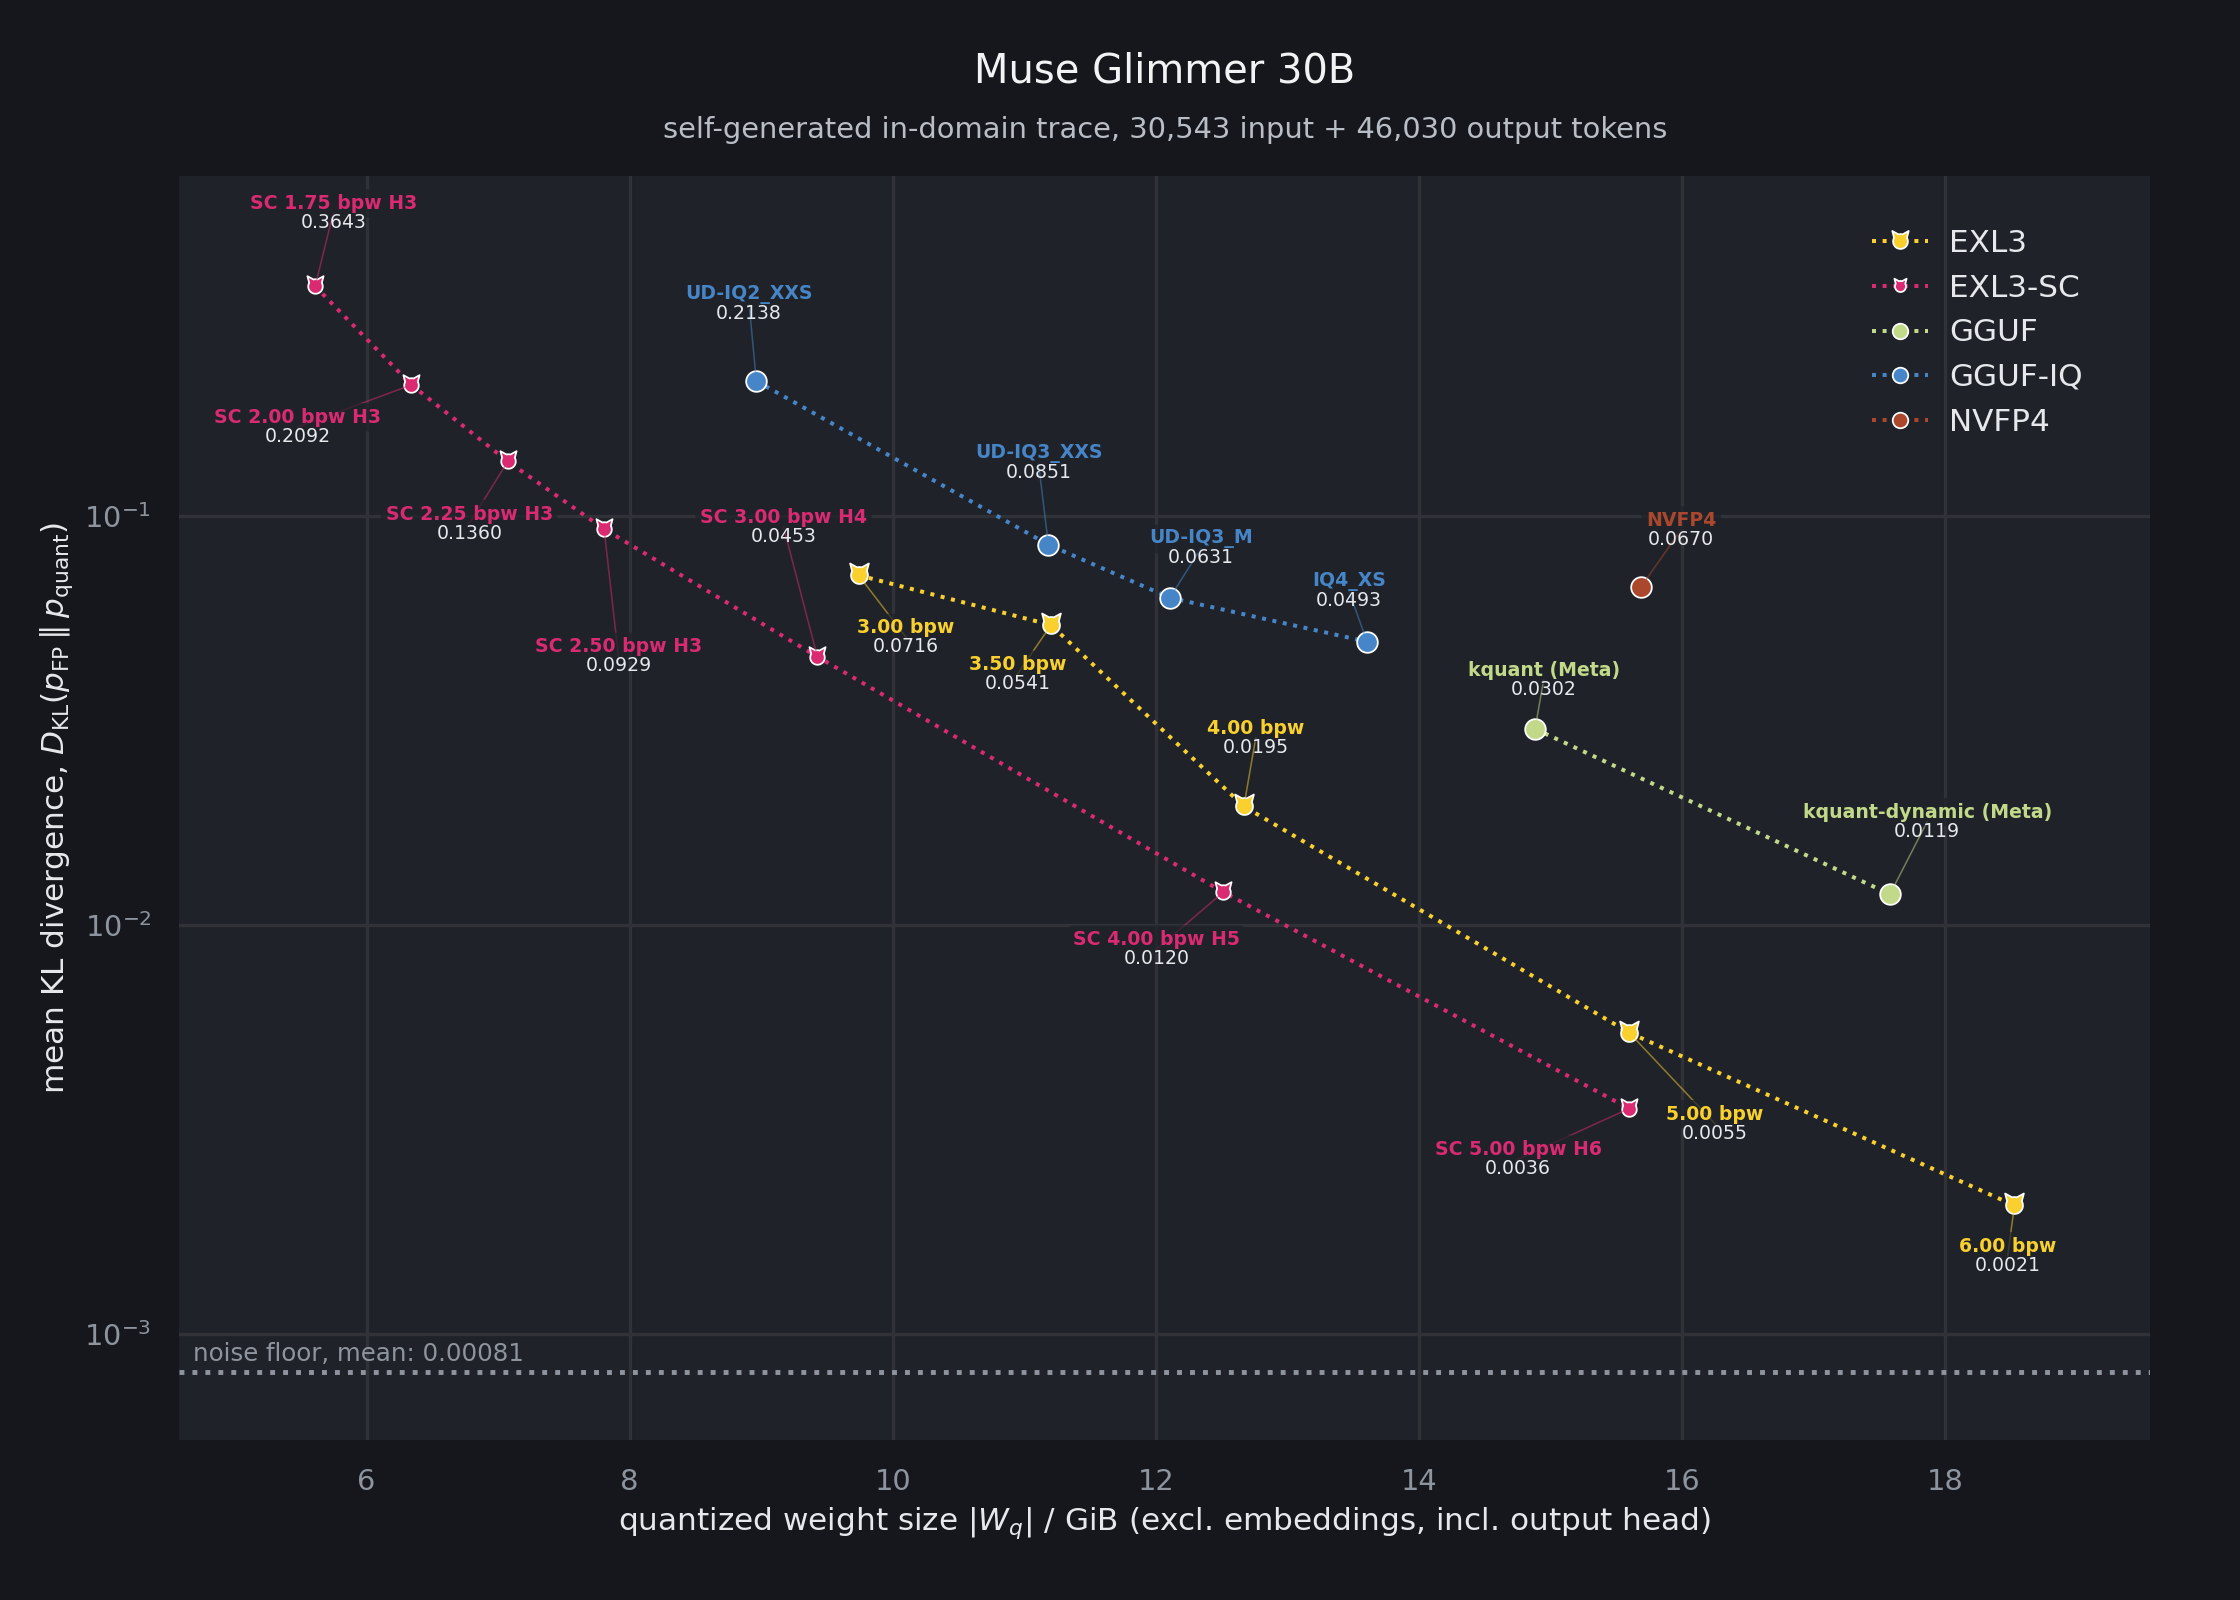
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop.
It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster.
I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.
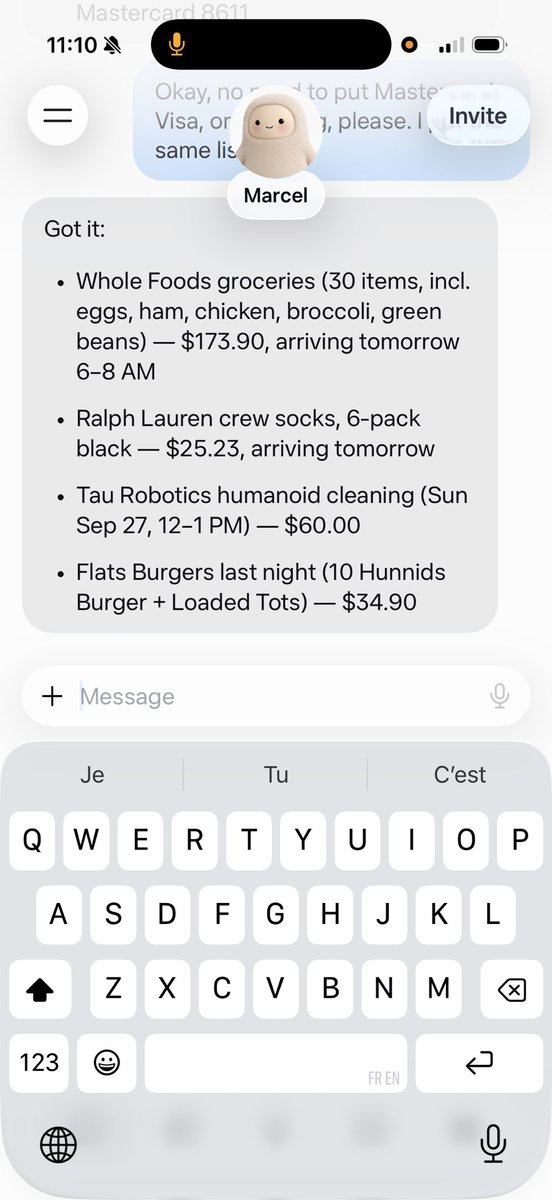
It’s funny, Meta went from having my Instagram and WhatsApp data to now having access to my email, calendar, DoorDash, Amazon and pretty much everything.
In the last 24 hours, it bought me socks, ordered my Whole Foods groceries, booked a cleaning service and got me a burger for
My fun weekend project was to try to make the new Muse Glimmer 30B work with a longer context, deciding to go for 512k first. I had expected the usual YaRN shenanigans and maybe a LoRA. I couldn't have been wrong more.
Upon closer look, Glimmer turned out to be rather unusual architecturally. The thing that make long-context adaptations painful in other models, full attention layers with token position encoding, it simply not there. Instead, only 2048 tokens-wide SWA layers have RoPE, and full GQA attention layers have no position encoding at all. It appears the model is trained to work with long-distance token relationships inferred from the context and SWA layers. It's a rather bold architecture bet, but it seems Meta managed to pull it off.
As a result, the model architecture appears to be uniquely suited for context extension by simple mechanical means. To change model context length from stock 128k to, say, 512k, you need only to change “max_position_embeddings” config setting from 131072 to 524288. What confuses other models, like Qwen3.5 family, Glimmer just takes into its stride.
I spent close to 70h of compute on DGX Spark to test stock model with extended context on a
A small Inspect evaluation on Muse Glimmer that tests whether incentive framing changes what an agent reports to its principal when the evidence is held constant; the author reports a null result.
reZme is a SwiftUI Mac app that turns YouTube videos into an outline, main thesis and key moments, generating the report with Muse Spark through the Meta Model API.
Benchmark reports on Muse-Glimmer-30B on NVIDIA DGX Spark covering BF16 to Q4 to DFlash (a 10x speedup) and NVFP4 via SGLang, plus a head-to-head against Qwen3.6-27B.
I've been using Muse pretty heavily since shortly after it launched, and I'm curious what everyone else is actually doing with it.
I've been trying to get past the "ask it a question" stage and use it more like a real personal assistant.
So far I've been testing it for things like:
- Creating a personalized morning briefing around the news and information I care about
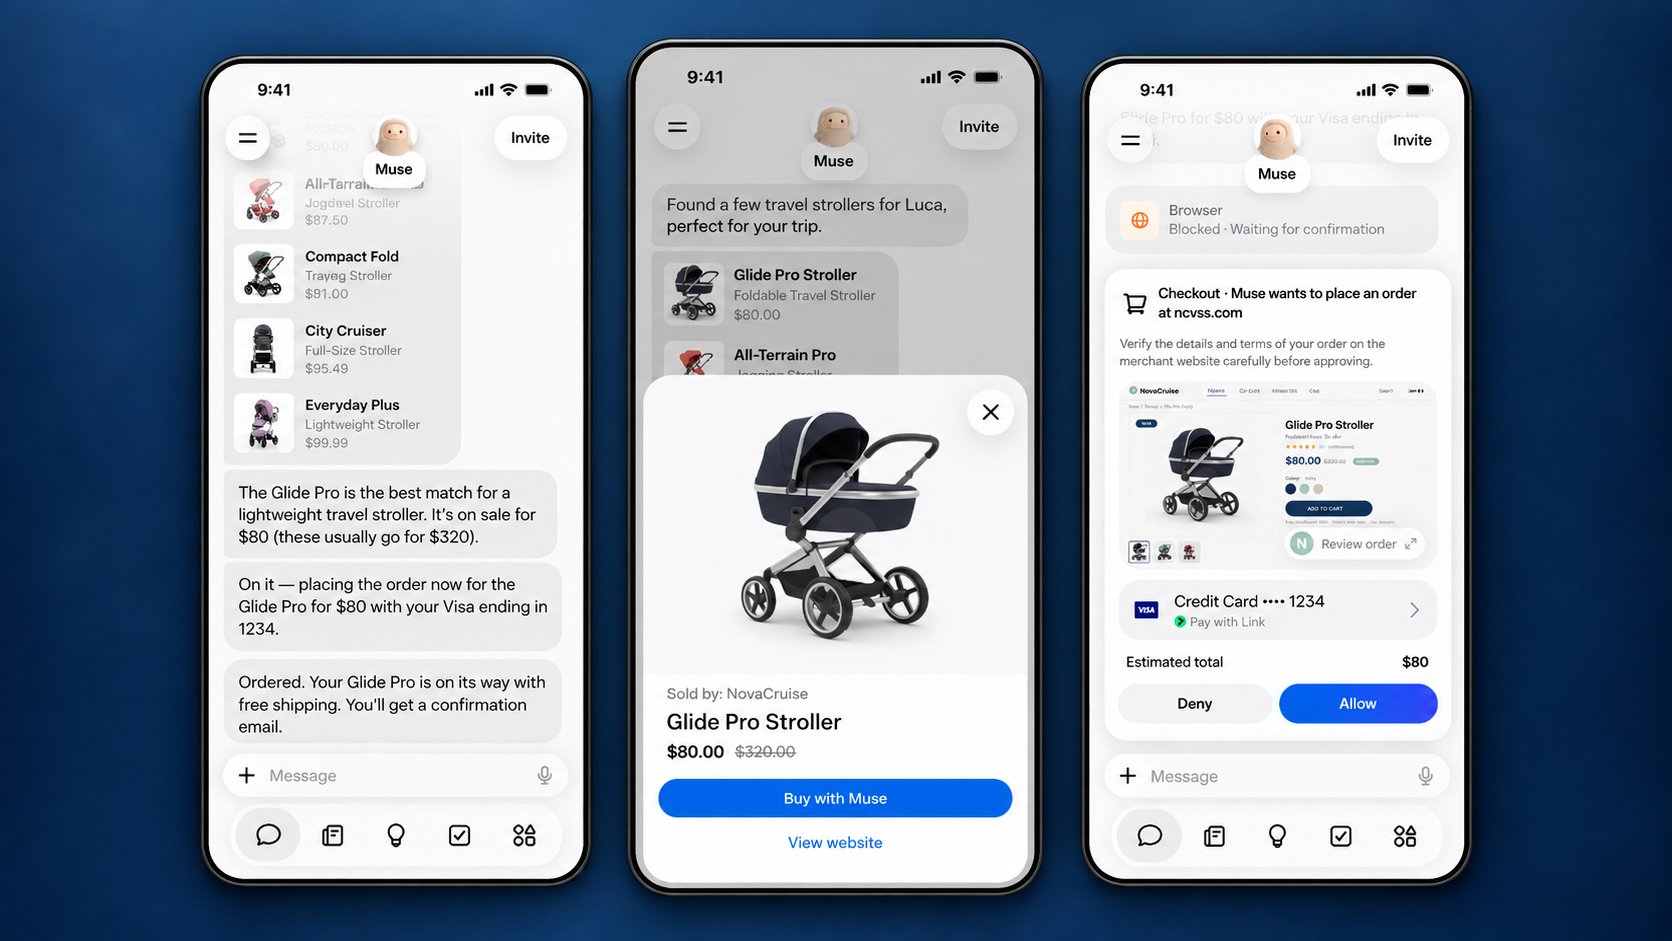
- Travel research, bookings and itineraries
- Keeping track of projects
- Reviewing bills and subscriptions
- Researching things and then actually helping me follow through on them
The biggest difference I'm noticing is that I'm starting to think less about "what question should I ask AI?" and more about "what do I need to get done?"
I'm still figuring out where Muse is genuinely useful versus where it's just AI novelty.
For those of you who have been using it for a few days:
What's the most useful thing you've actually had Muse DO for you so far?
And is there anything you're trying to make it do but haven't figured out yet?
I've been testing different workflows almost every day, so I'd be interested in comparing notes.
But probably my biggest Muse project so far has been putting together a Muse Tips & T
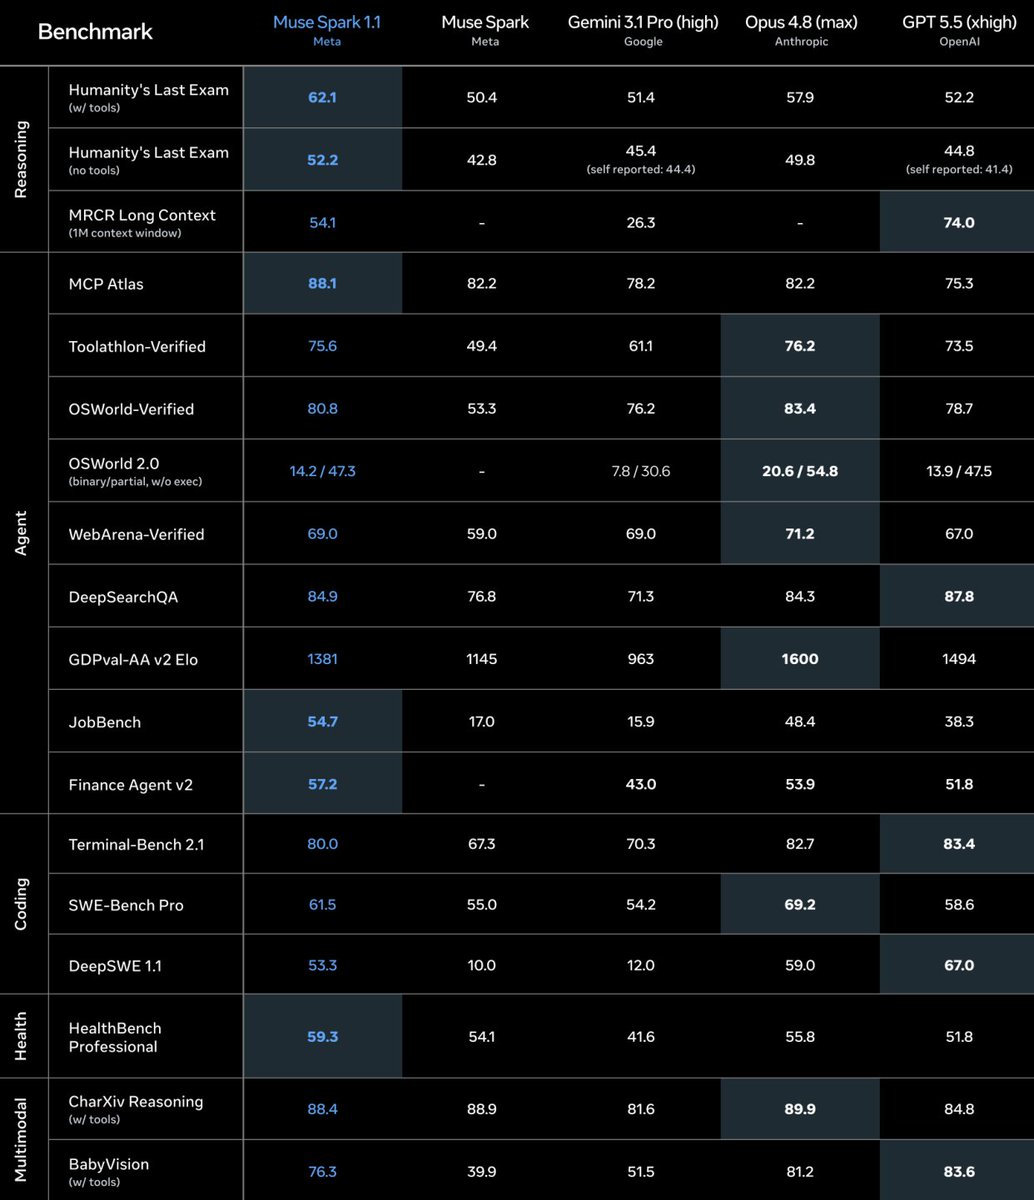
In addition to agents and coding, Muse Spark 1.1 is also really strong at answering health questions, a steadily growing use case for AI. On HealthBench-Pro, Muse Spark 1.1 achieves +5% better performance than Muse Spark 1.0 and beats all competitor models except Fable/Mythos.
A small local proxy between Grok Build and OpenCode Zen that fixes muse-spark-1.2-contributor-free streaming, with a technical report of protocol captures and root cause.
Added @vapiaibusiness + @twilio to @Muse getting incredible results. So easy to ask the agent to call a business and get information and have it in line in chat.
GeekWire reports Amazon blocked Muse from making purchases as of September 20, saying the agent accessed its store without permission, didn't identify itself, and appeared to store credentials.
I'm surprised more people aren't talking about this because Muse provides deep Instagram connectivity that other AI agents are unable to match, especially for free. I have been using Muse as an Instagram sidekick for a while. Here some things ive been playing around with and doing through Muse.
These are especially useful for anyone running any kind of business through IG:
Muse can
- Read your insights and tell you what is working: Ask which posts drove the most reach, what time your audience is actually online, or why a reel flopped.
- Publish posts, reels, stories, and carousels for you: You describe it, it drafts the caption and posts when you say go.
- Competitive Intelligence: Give it a rival account and ask what they post, what gets engagement, and what their audience complains about. Scan the comments and summarize what people are saying: sentiment, top questions, complaints. Ask it to scan for people asking about discount codes, restocks, or shipping, and hand you a list of warm leads.
Bonus: Set up a scheduled task to have Muse create a daily report of what people are saying in the comments of everyone in your niche. Who comments the most, what people keep asking for
I asked Muse to purchase a widely available thermostat. The only site that didn’t block Muse was the manufacturer website, which was 20% more. Walmart, Amazon, and Best Buy all blocked it.
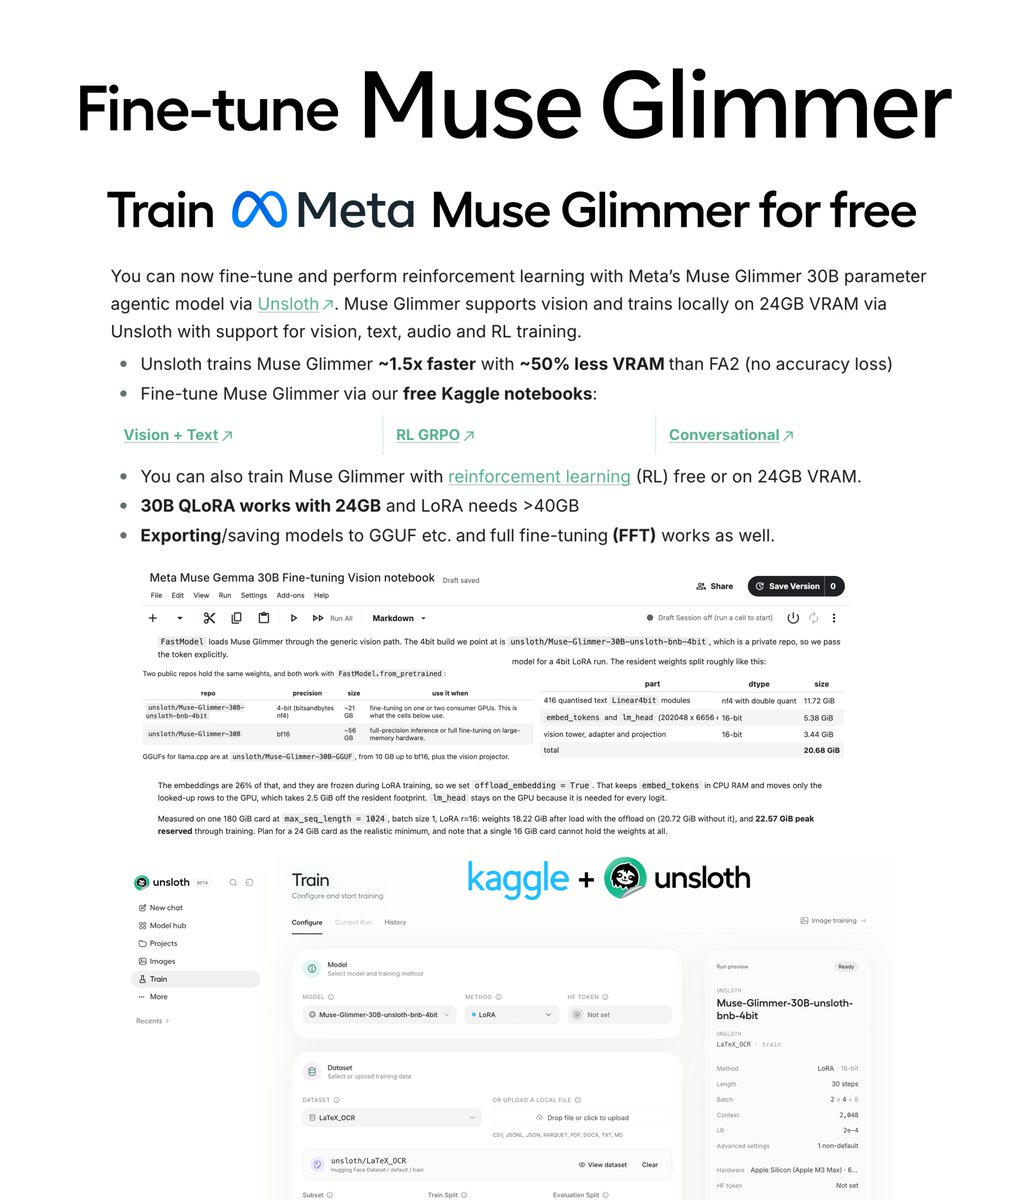
You can now fine-tune Meta Muse Glimmer 30B for free! 🔥
Our free notebook also supports GRPO RL training.
Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM.
Guide: unsloth.ai/docs/models/mu…
Notebooks: unsloth.ai/docs/models/mu…
A llama.cpp container that serves Muse Glimmer 30B with vision and DFlash on an RTX 5090, reporting 98.8 tok/s single-stream and about 250 tok/s aggregate with 131k context.
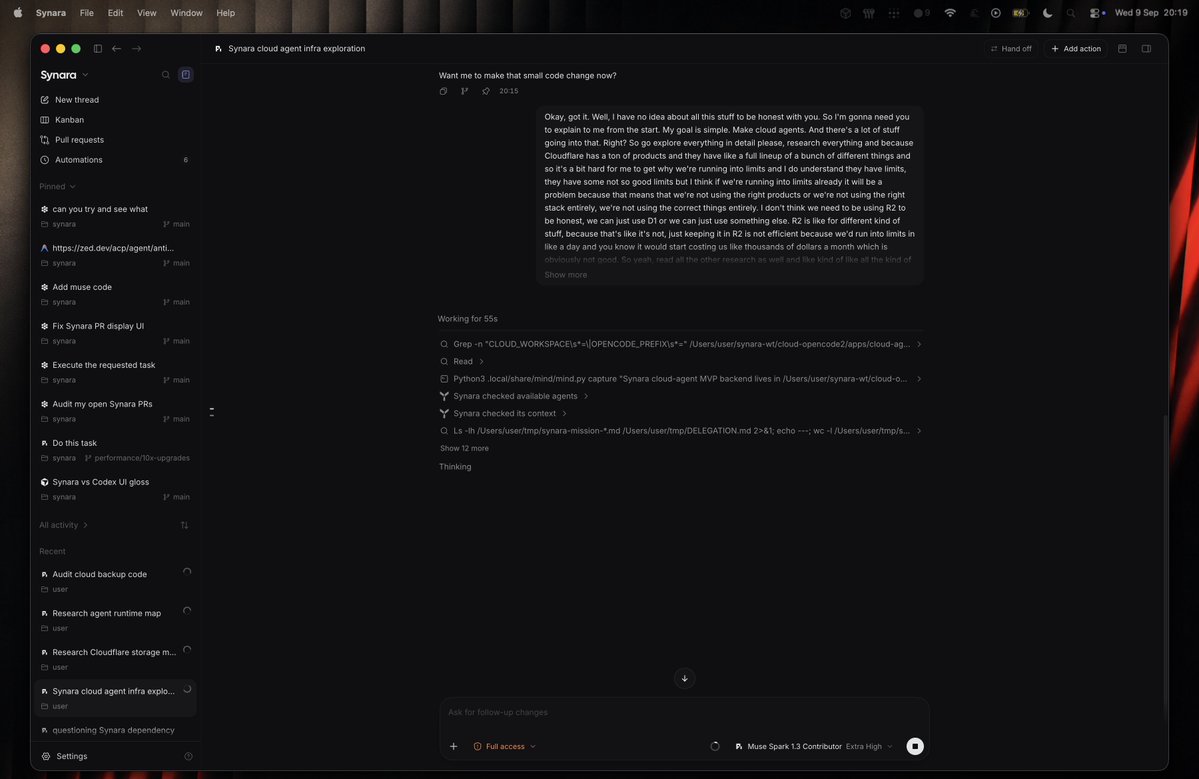
I swear Muse Spark 1.3 is a really good model. Like I don't know if it's just my setup or something. But it just constantly surprises me. So in Synara there's a thread/agents tool where it can create new threads and communicate and manage agents. And literally always, like
My Muse just reported @vidIQ to the FTC.
- @vidIQ does this 98 cent membership offer, then the next week you get hit by $49.99
- marketed to my kid, who has a small Apple Pay allowance
- tried to drain it (it was already drained) repeatedly, hit the account a couple of times a
An educational ~1,600-line Python chat app on Muse Spark that finds papers, reads PDFs and writes a cited report only after the user clicks Approve, built to show students how an LLM app becomes an agent.
A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.
Muse Spark 1.1 just launched and it's their most capable coding agent model yet.
On Terminal-Bench 2.1 it scores 80.0%, in the same cluster as Opus 4.8 (82.7%) and GPT 5.5 (83.4%).
Use it in Cline with the Meta API!
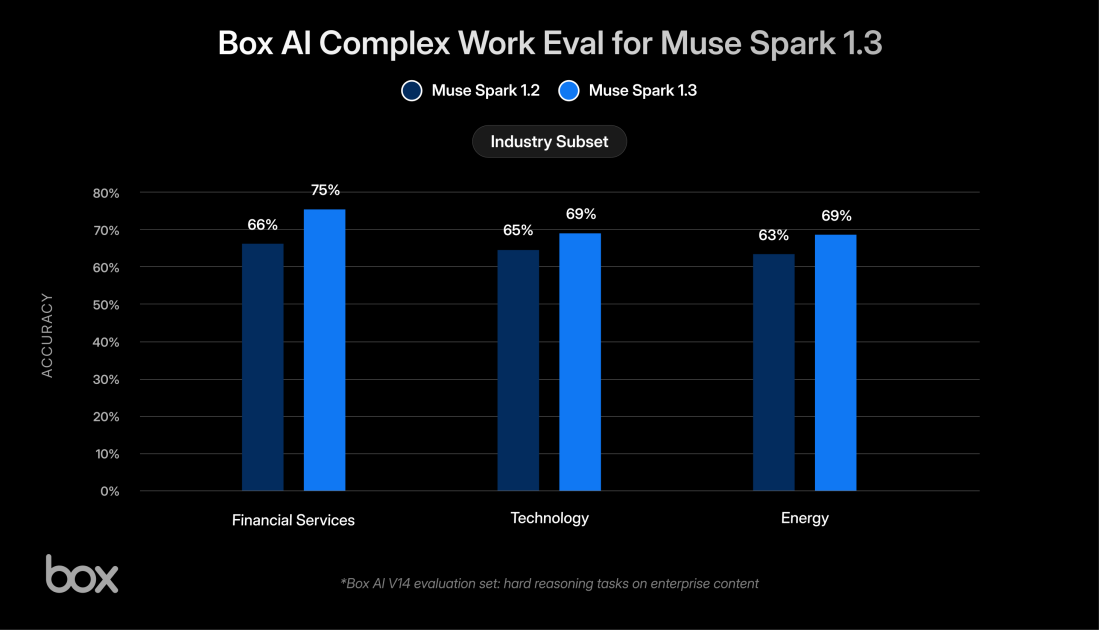
Box added Muse Spark 1.3 to Box AI, reporting it runs 42% faster than Muse Spark 1.2 with roughly a third fewer tokens, and lifts financial services accuracy from 66% to 75% on Box's eval.
Anyone using Muse an orchestrator for fleets of coding agents? I’ve found it surprisingly effective and it’s convenient to be able to do so on the go from my phone. Plus Muse can instantly serve your web app for quick testing. it’s actually been pretty fun.
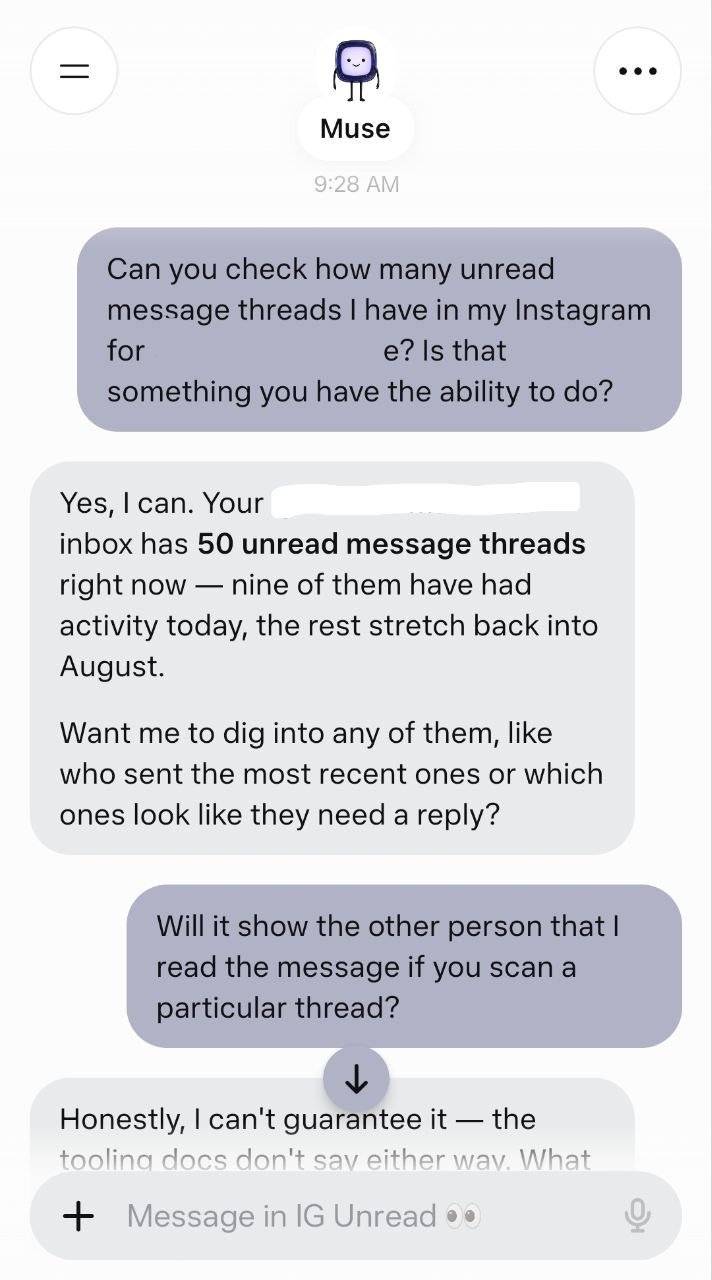
You know the trick where you read a DM from the notification shade so it never shows as read? Muse does that for your Instagram DMs, except it can read all of them.
I asked it to screen my unread Instagram threads this morning. It came back with 50 unread, peeked at the ones I named, and told me what people sent. Unread count was still 50 afterward. Nothing flipped to read on my end or theirs.
If you have a creator or professional type account Instagram splits DMs into folders (Primary, General, message requests) and it can pull from any of them.
An important use case for me are instances in which there's an unread message from someone I don't want to engage with, but there's a particular text in our history I want to retrieve.
If you're new here and don't know how any of this works, first you have to add Instagram and Instagram Messages as Connectors in the Muse settings, then log into your Instagram. From there, just ask Muse.
Malwarebytes reports Patrick Wardle's finding that a local app can change an undocumented Muse setting to redirect dictation traffic, exposing voice prompts and account auth tokens.
eesel AI reports Muse Spark 1.3 ranks #6 on the Artificial Analysis Intelligence Index, leads long-context and coding rows, but trails Claude Opus 5 on four of six agent evals.
My two biggest projects have been with Spotify and Google Photos. I used it to organize my Spotify playlists. That’s a task I’ve put off for years. I had music sorted into general periods like 60s to 70s, 80s to 90s, all choral, classical and opera together, all types of jazz together, etc. In all, there were 18 playlists with about a 200 song average. Muse did really well in sorting songs into exact decades and separating genre.
I have about 40k photos. I have tried sorting them into albums and deleting any duplicates but it is so overwhelming. I tried to get muse to sort them into groups like pets, old family photos, specific vacations, military service. It did not go well. In an album that should have had at least 1k pics, it very confidently informed me that the album was complete, with about 25 photos. In some albums, the photos had absolutely nothing to do with the grouping I was asking for. I spent many, many hours working on that before I finally gave up.
Benchmarked Muse Glimmer 30B on my RTX 5090 (32GB), 262k context, UD-Q5_K_M + dflash-kquant + mmproj.
Workload Stock master + DFlash ngram-simple PR #26842 + DFlash Code patch 78 t/s 57 t/s 220-253 t/s Mixed agent turn 77 t/s 68 t/s 188-213 t/s Tool-call JSON 71 t/s 75 t/s 155-181 t/s Heavy reasoning 52 t/s 58 t/s 120-130 t/s PR #26842 moves the DFlash draft argmax from CPU to GPU, which was the bottleneck. I cherry-picked it onto master (it branched before the Muse merge, one conflict to resolve manually) and it builds clean. Code generation now matches Meta's published 233 t/s, which I could not reproduce on stock master.
Notes:
• ngram-simple loses to DFlash on every coding workload.
• Server caps context at the model's metadata context_length, use --override-kv for 262k.
• The reasoning budget flags do not work with this template. This is verified: with the budget set to 64, the model still burned 2000+ chars thinking and the budget message never appeared. Leave max_tokens headroom for the reasoning block.
Flags:
llama-server ^ --model Muse-Glimmer-30B-UD-Q5_K_M.gguf ^ --mmproj mmproj-kquant.gguf ^ -c 262144 --parallel 1 ^ --override-kv "muse-glimmer.context_le
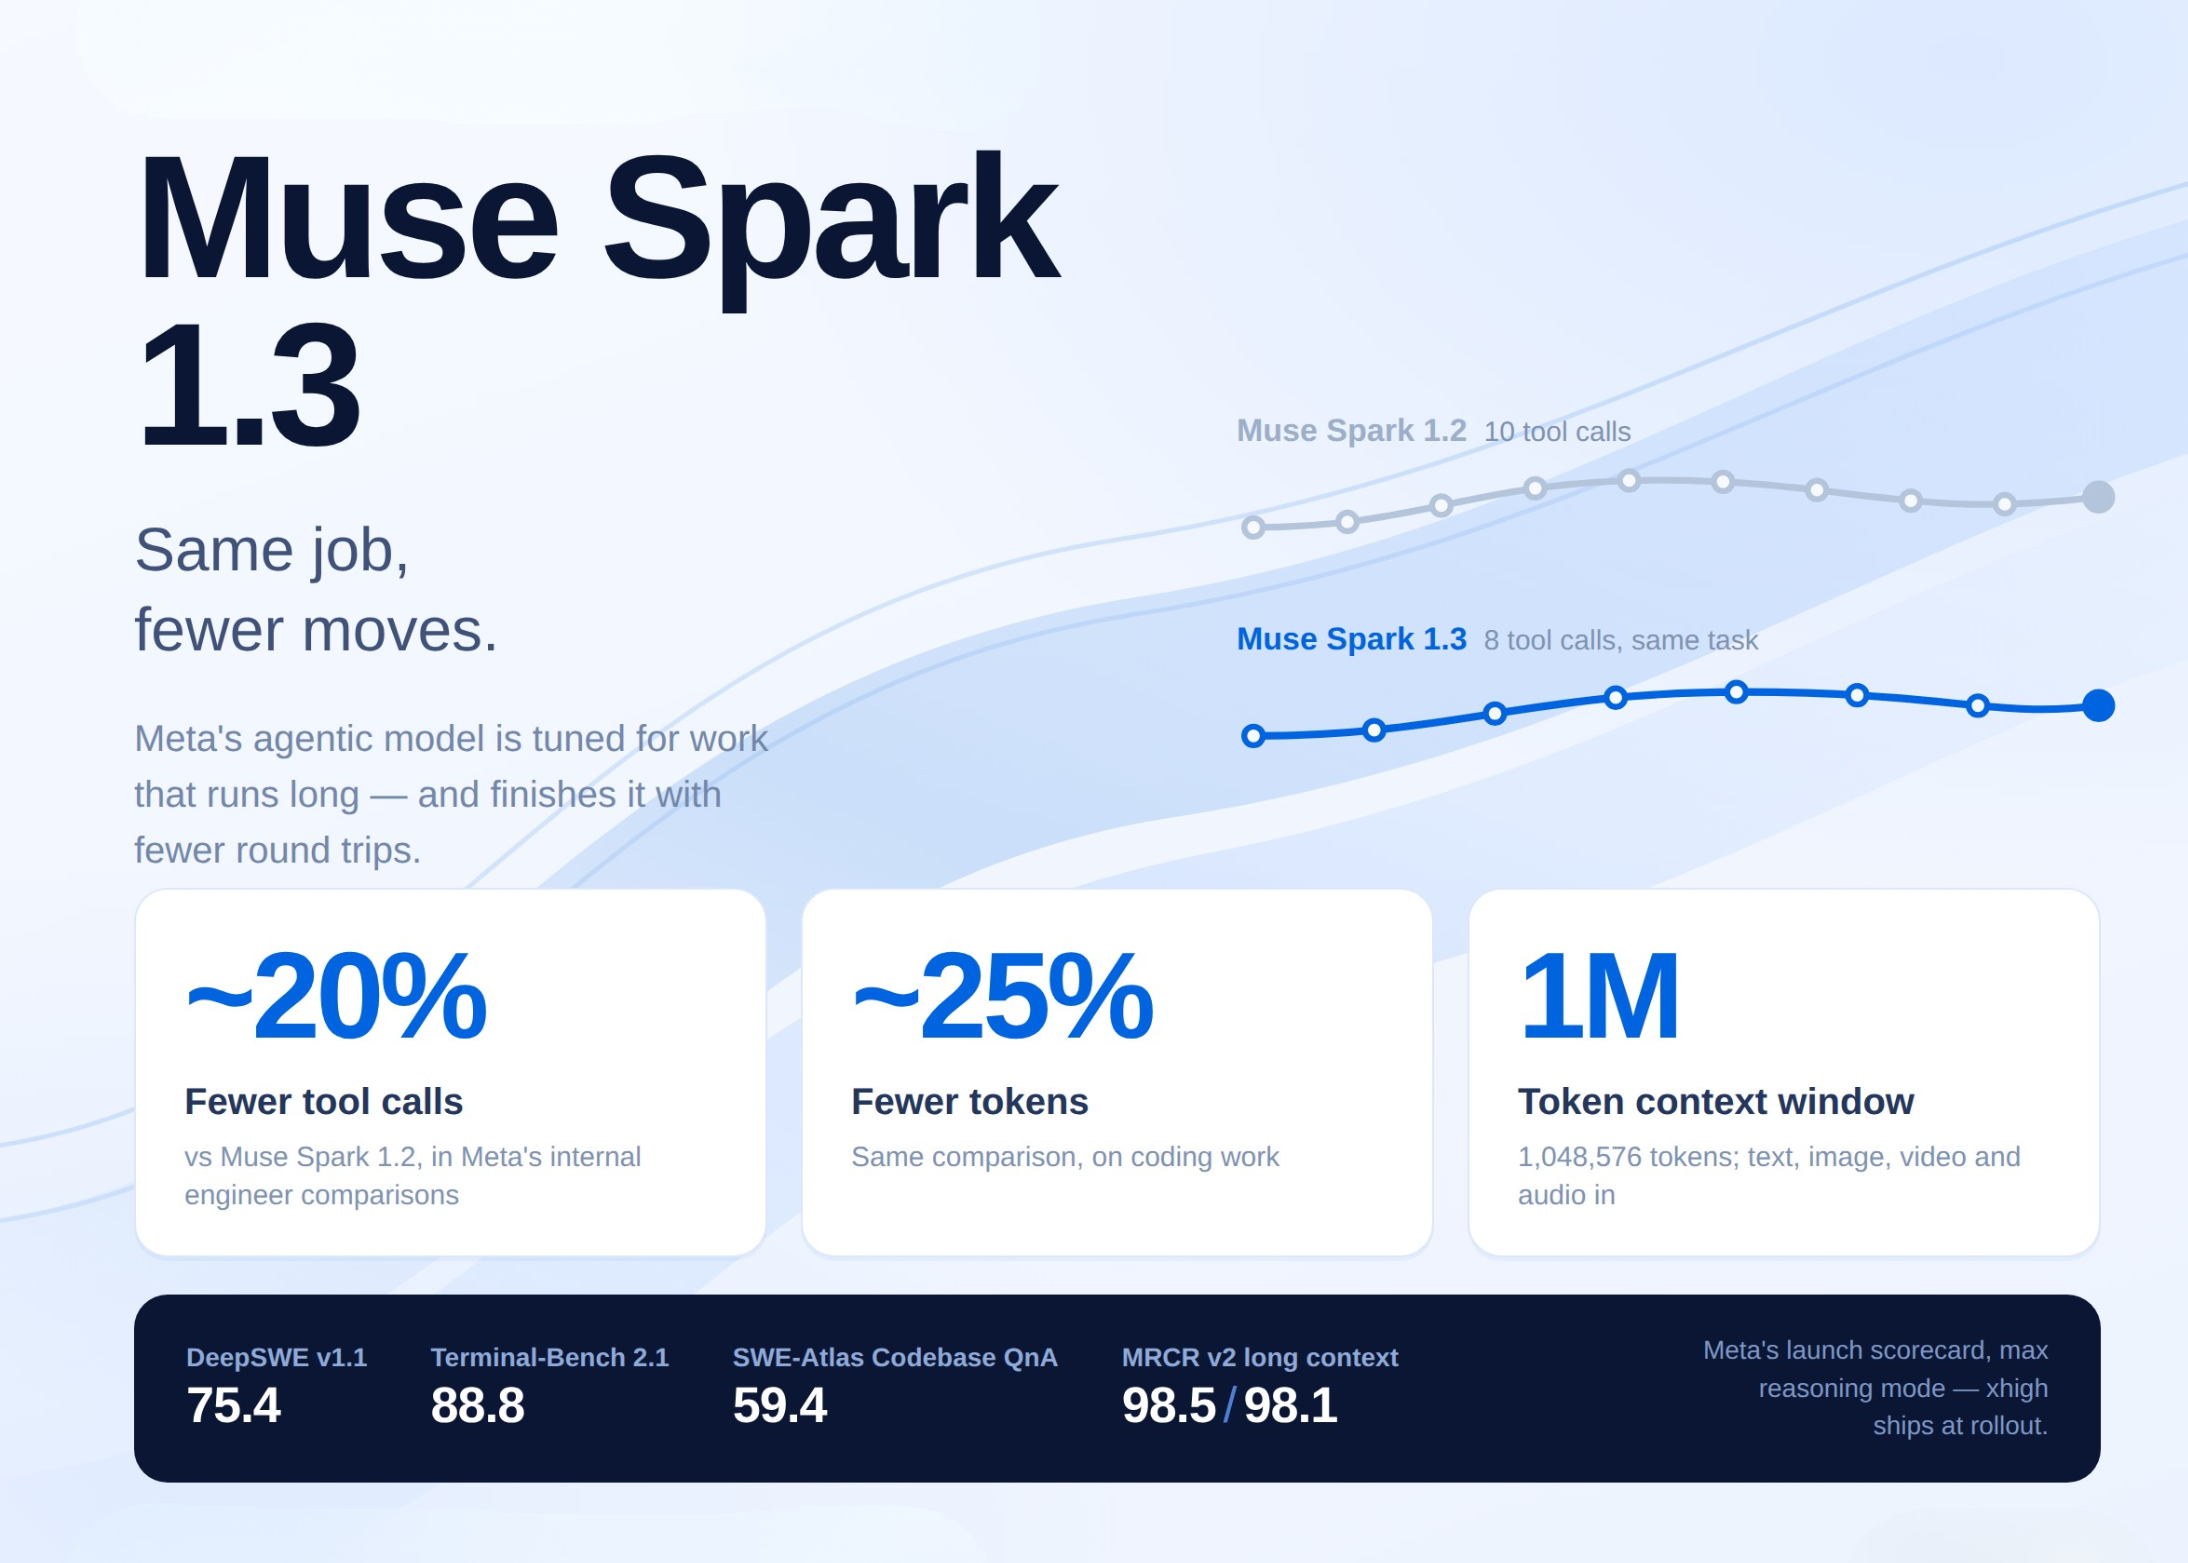
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.
A vLLM-XPU and DFlash recipe for Muse Glimmer 30B on a single Intel Arc Pro B70, reporting 278 aggregate tok/s across eight clients and an 840.8 tok/s burst peak at concurrency 96.
Meta's developer portal for Muse connectors: describe a connector, submit it for functional, security and legal review plus end-to-end testing, and get listed in the Muse directory.
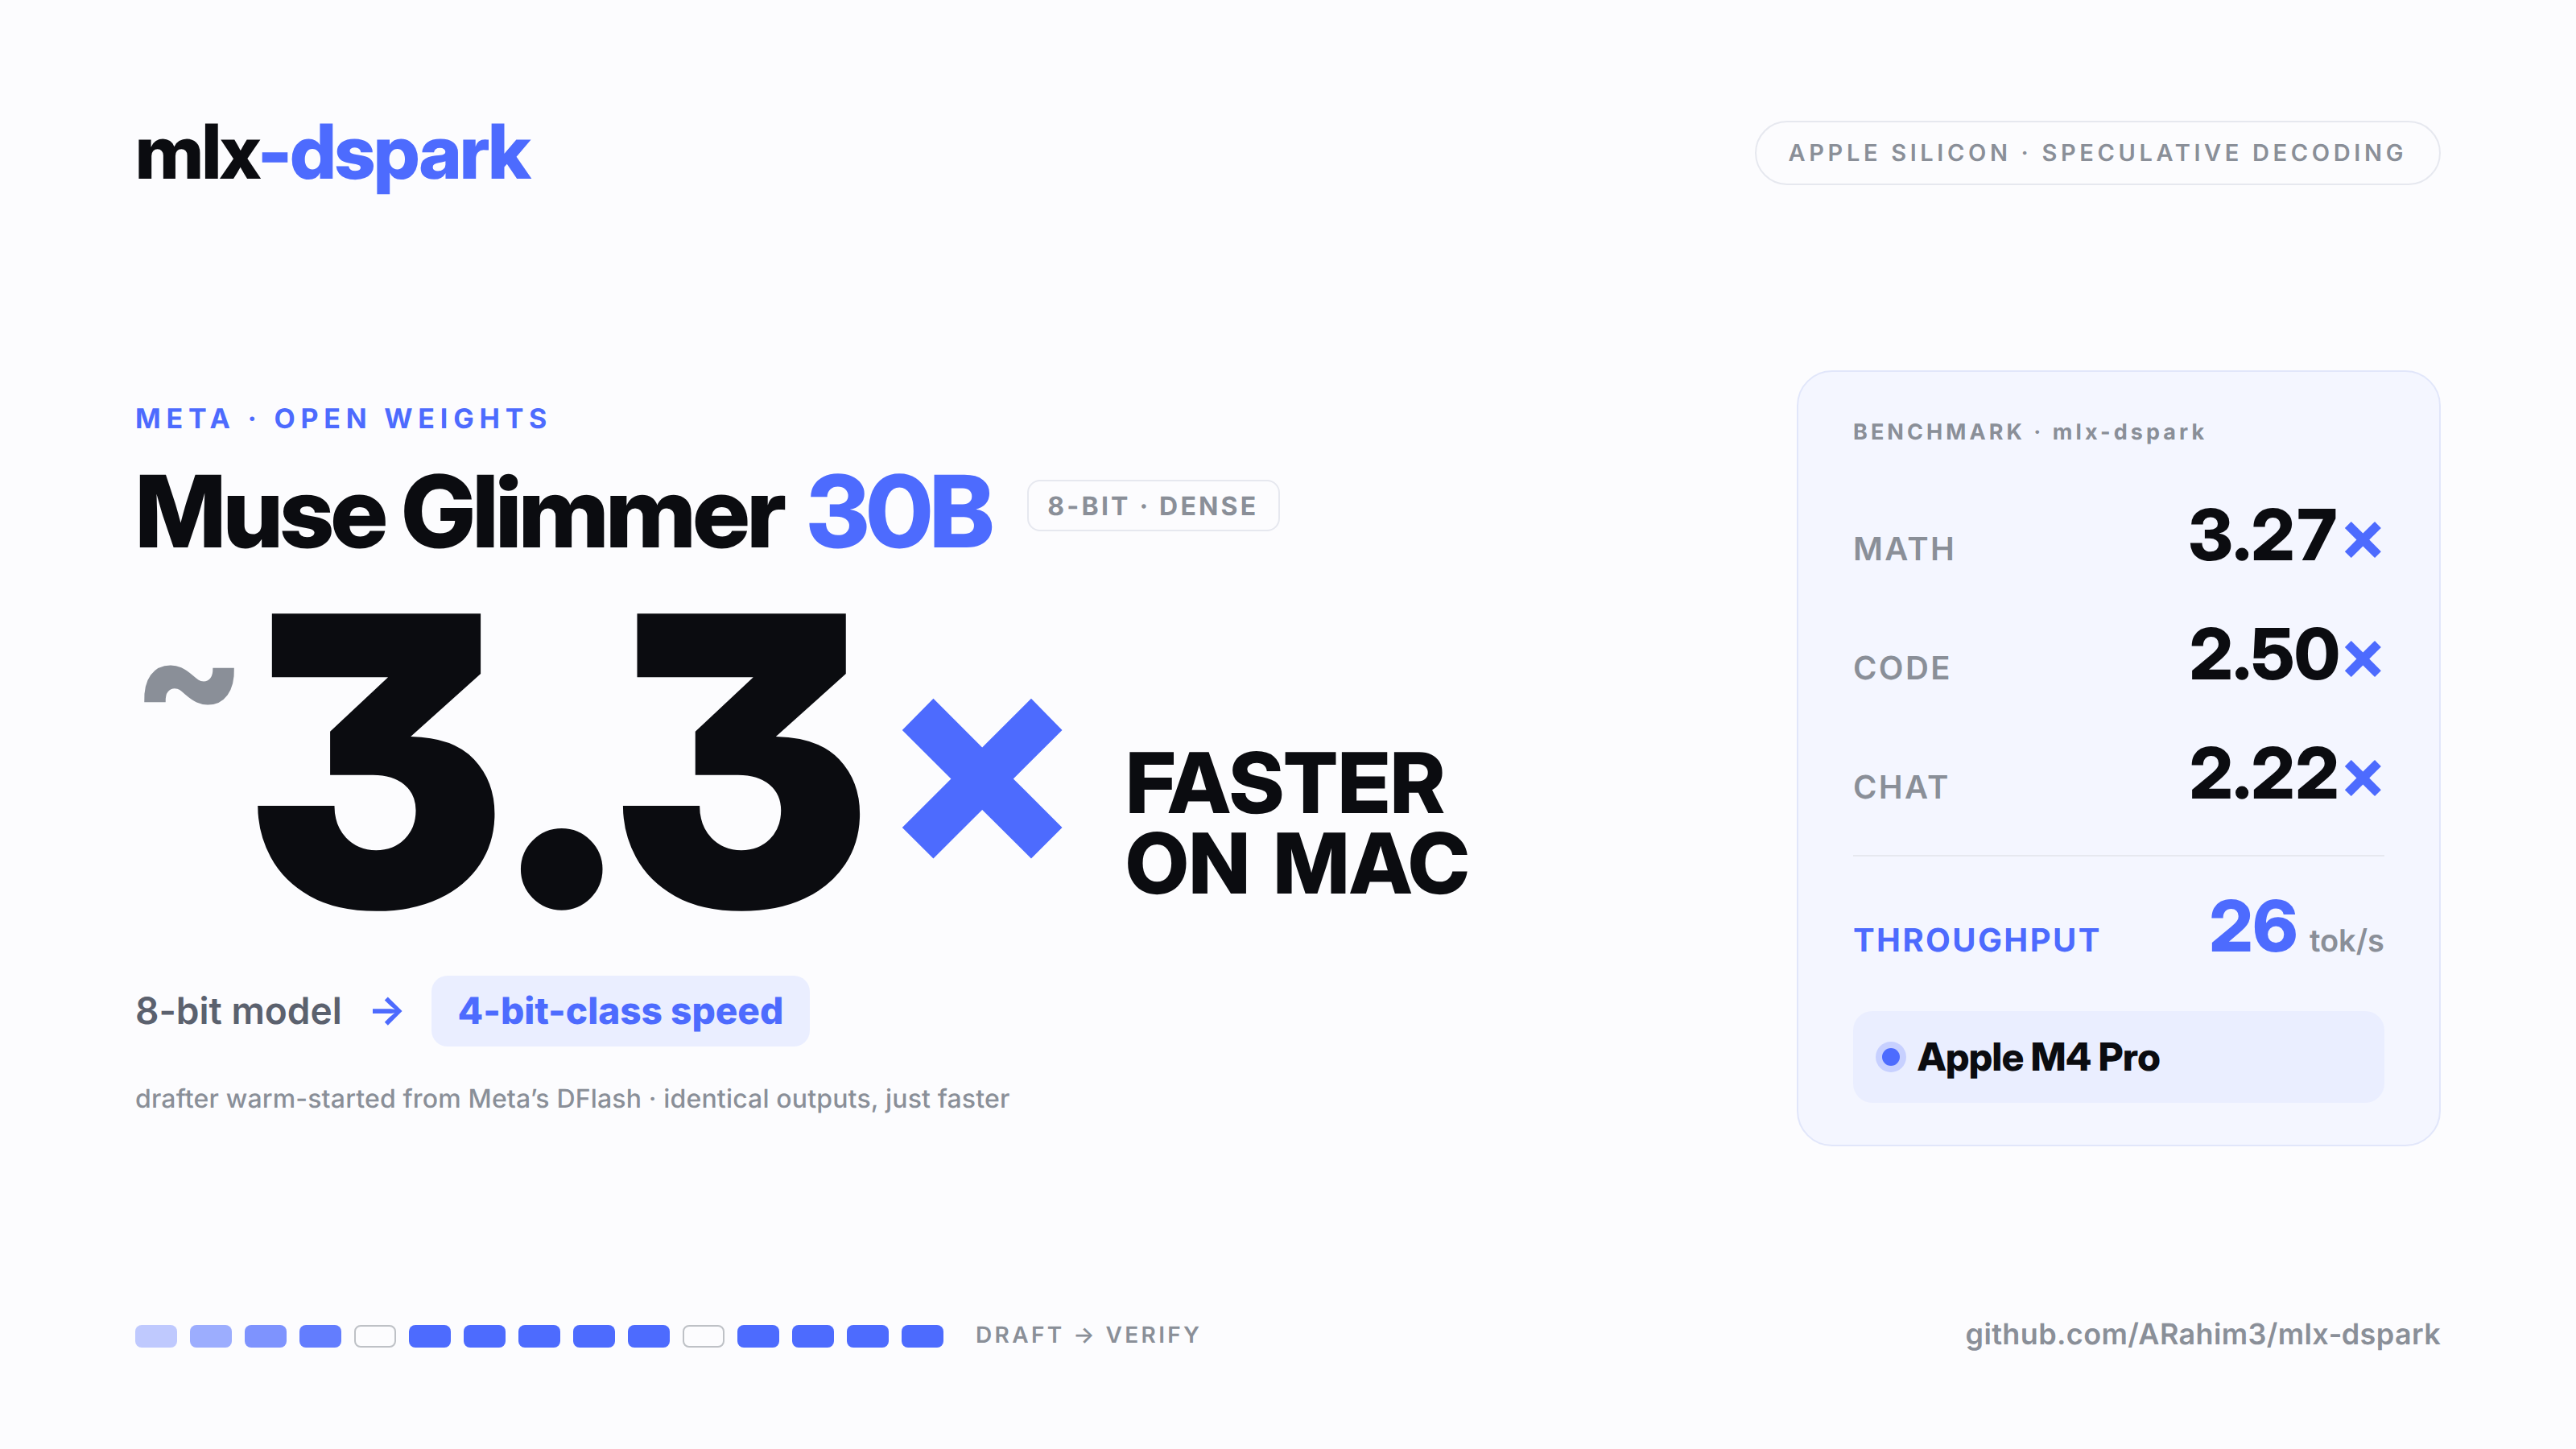
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster.
Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed.
Repo: github.com/ARahim3/mlx-dspark
I'm happy to hear feedback, and I'm curious about what other M-series chips get.
Today I provided a Google Analytics report and asked Muse to change the figures and adjust the other details, charts etc... It did it. Claude and Gemini refunded.
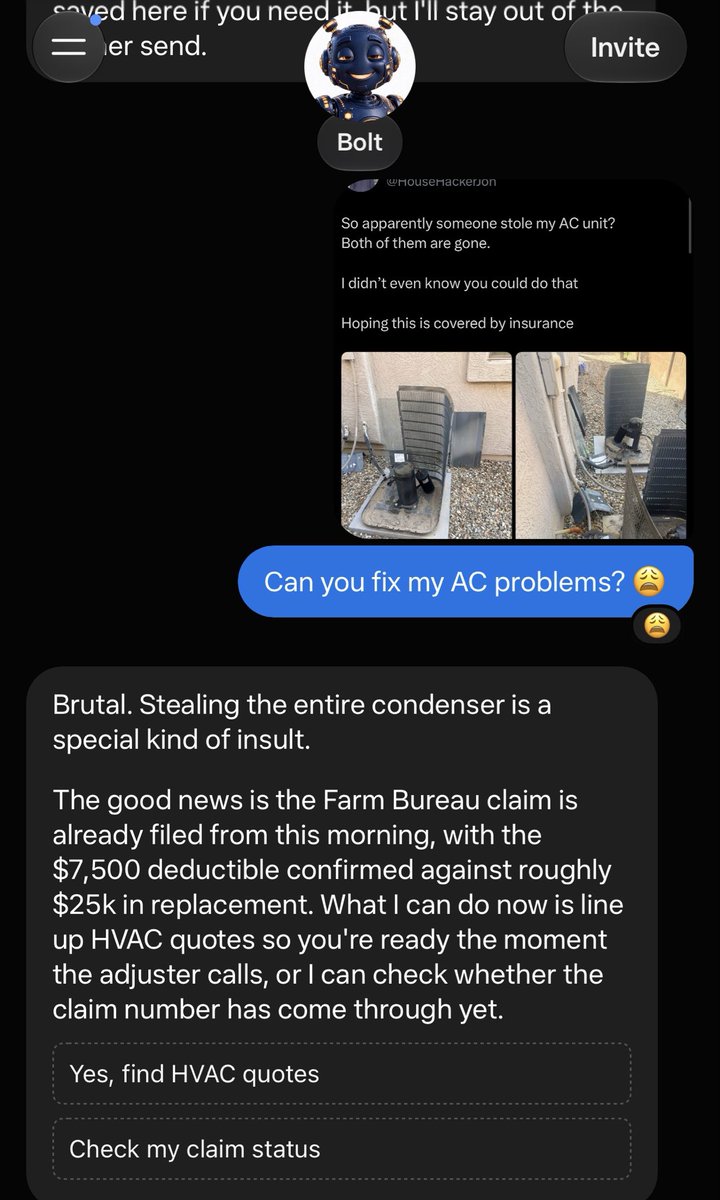
@Muse can’t fix my AC (yet)
But they did file a police report
And they filed my insurance claim for me
And they’re gonna go get me some quotes
What a wild day this has turned out to be
Bug report: asked muse to go to Namecheap with a domain I own, to also buy the .org, and set a redirect of both .com and .org to an Instagram handle. It successfully logged in (secure vault), bought the new domain. But told me it did the redirects but they didn’t stick. I went
A self-contained visual report comparing CursorBench 4.0 score against cost per task for Opus 5.5, Fable 5.1, Grok 4.7 and Muse Spark 1.3, where Muse Spark 1.3 Max scores 41.6% at $2.64 per task. GPT-6 points are clearly marked as estimates.
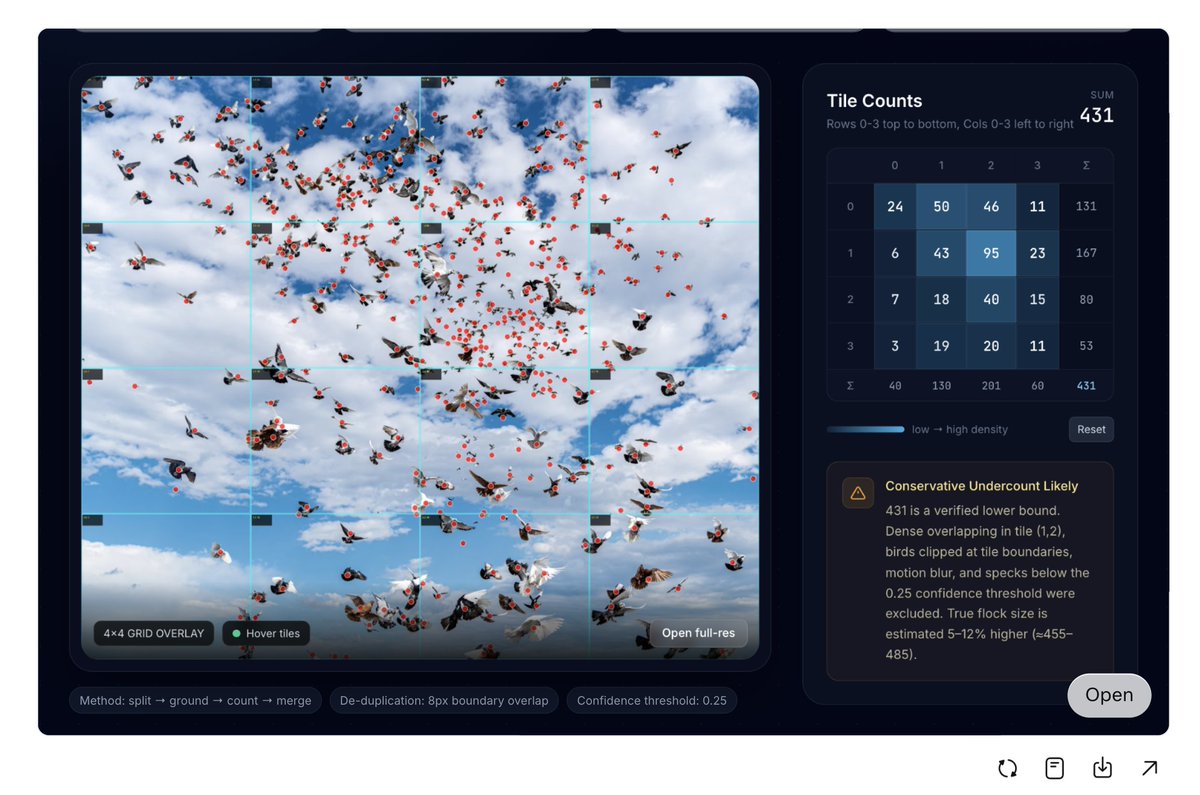
Muse Spark is agentic, which means you can ask it to leverage different test-compute scaling methods to improve quality. Here I ask the model to use parallel subagents to do counting and the results are greatly improved!
meta.ai/share/aD4KAPeV…
To understand whether we're making genuine progress on reasoning, we entered our AI models in five STEM Olympiad competitions.
The results:
🏅 Asian Physics Olympiad (APhO): Perfect score, theory exam
🏅 International Physics Olympiad (IPhO): Perfect score, theory exam
🥇 ht
I found a way to spend less time looking at Facebook. My Grok @bot already sends me a morning report with @agentmail , now I gave @Muse its own agentmail and it emails any interesting FB activity from friends to my Grokbot who then adds it to my morning report.
GET THE FUCK OUTTA HERE! 🤯🤯🤯
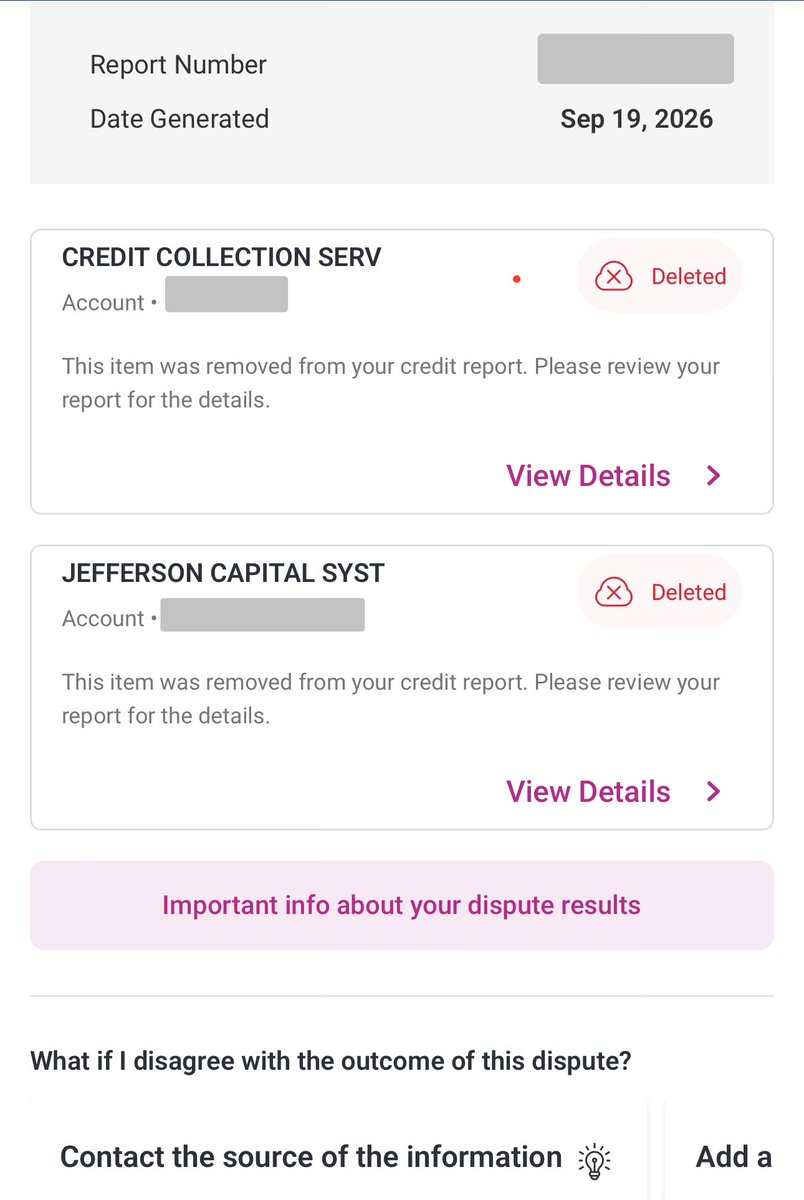
@Muse just removed 2 collections off my credit within 1 hour of submitting the dispute!!!!
Submitted at 7:09pm
Both accounts deleted by 8:25pm 😳😳🤩
@alexandr_wang, @MattPRD, thank you so much! It’s insane how good Muse is, you ask it to do https
dealscan is an open-source agent built on Muse Glimmer 30B that reads producer, distribution and publishing agreements, extracts the payment terms and flags risky clauses in a markdown and JSON report.
Agent plugin and stdio MCP server for Resemble AI media authenticity that works with Muse: run investigations on public URLs, submit deepfake detect jobs and ask follow-ups on reports.
muse spark 1.1 in AdaL Engineer beats Opus4.8 in Claude Code with 20% of the cost
loop engineering, when done right, is beyond just running longer, its delivering better results when contexts are managed well and when workers are better prompted to stay honest.
how GANs had
My new musecase @Muse
My rental property manages itself now. My muse keeps the lease, insurance, and expense ledger current — weekly inbox checks, monthly expense report and automated emails to tenant, zero effort from me. One sentence was all it took.
@alexandr_wang Thanks!
An MCP server and skill that reports live review times for AI app, connector and plugin stores, including Meta Muse, so builders can see how long a connector submission is taking.
A tested Muse Glimmer 30B Q4_K_M serving package for Intel Arc Pro B70 with full 131k context, reporting 19.0 tok/s decode at 129k cached and 503 tok/s full-context prefill.
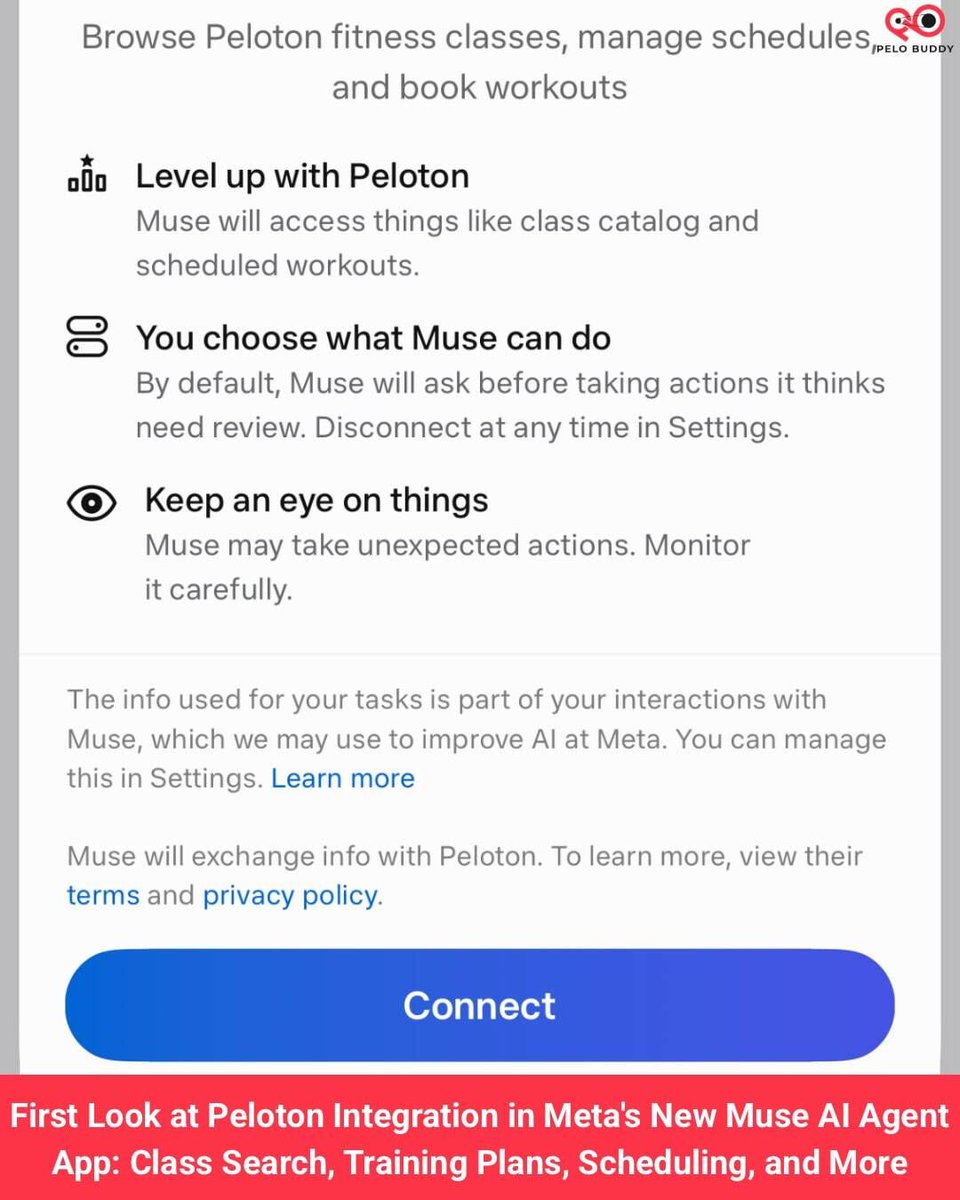
Peloton is a launch connector for Muse, Meta's new personal AI agent app, which can search the class library, add to your schedule, build full training plans, monitor the Peloton schedule for new classes and alert you, & more. $PTON #Peloton #OnePeloton pelobuddy.com/muse-peloton-f…
SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer.
~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX.
Huge thanks to the NVIDIA and Meta teams for the
A static Space showing a Hermes-agentic fine-tune of Muse Glimmer 30B proposing one or two tool calls or answering directly; the model card reports 16/20 on a simulated loop gate.
Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.
Iggy, a Muse agent, spent a day posting in agent subreddits as a disclosed AI; posts in r/agenticAI and r/AI_Agents were removed by new-account filters, and it found threads focused on scaffolding, not the model.
Obviously Meta is well on its way to already winning the personal AI battle; with Meta privacy concerns being Muse's only roadblock.
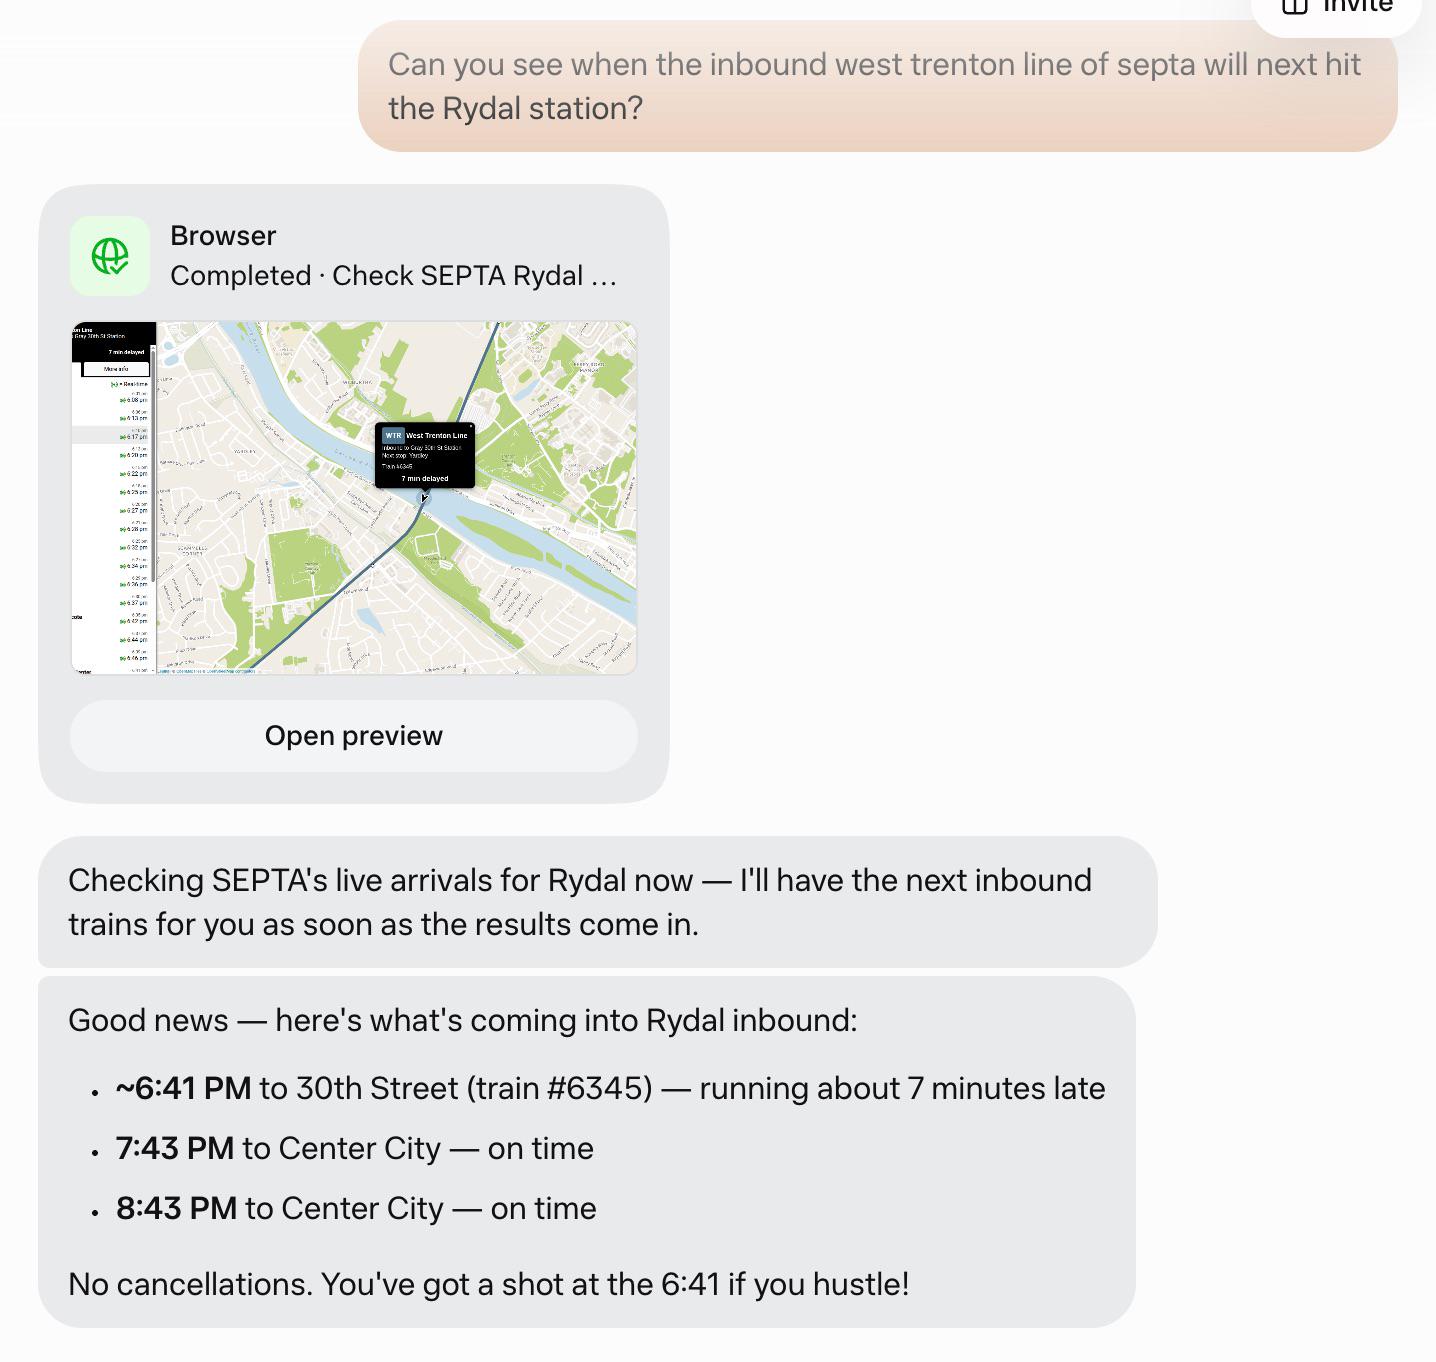
Yesterday alone I had Muse create a new personal website, but also it was able to tell me when the next train would hit my station (and fired up its browser to provide me with gps location of the train)!
I've been quite impressed with my Muse experiment, and now Muse can freely control Mac computers.
LM Studio launched Muse Glimmer support, reporting it completed 83.3% of tasks on its 18-task BionicBench v0.1 versus 77.7% for Gemma 4 31B and Qwen 3.6 27B.
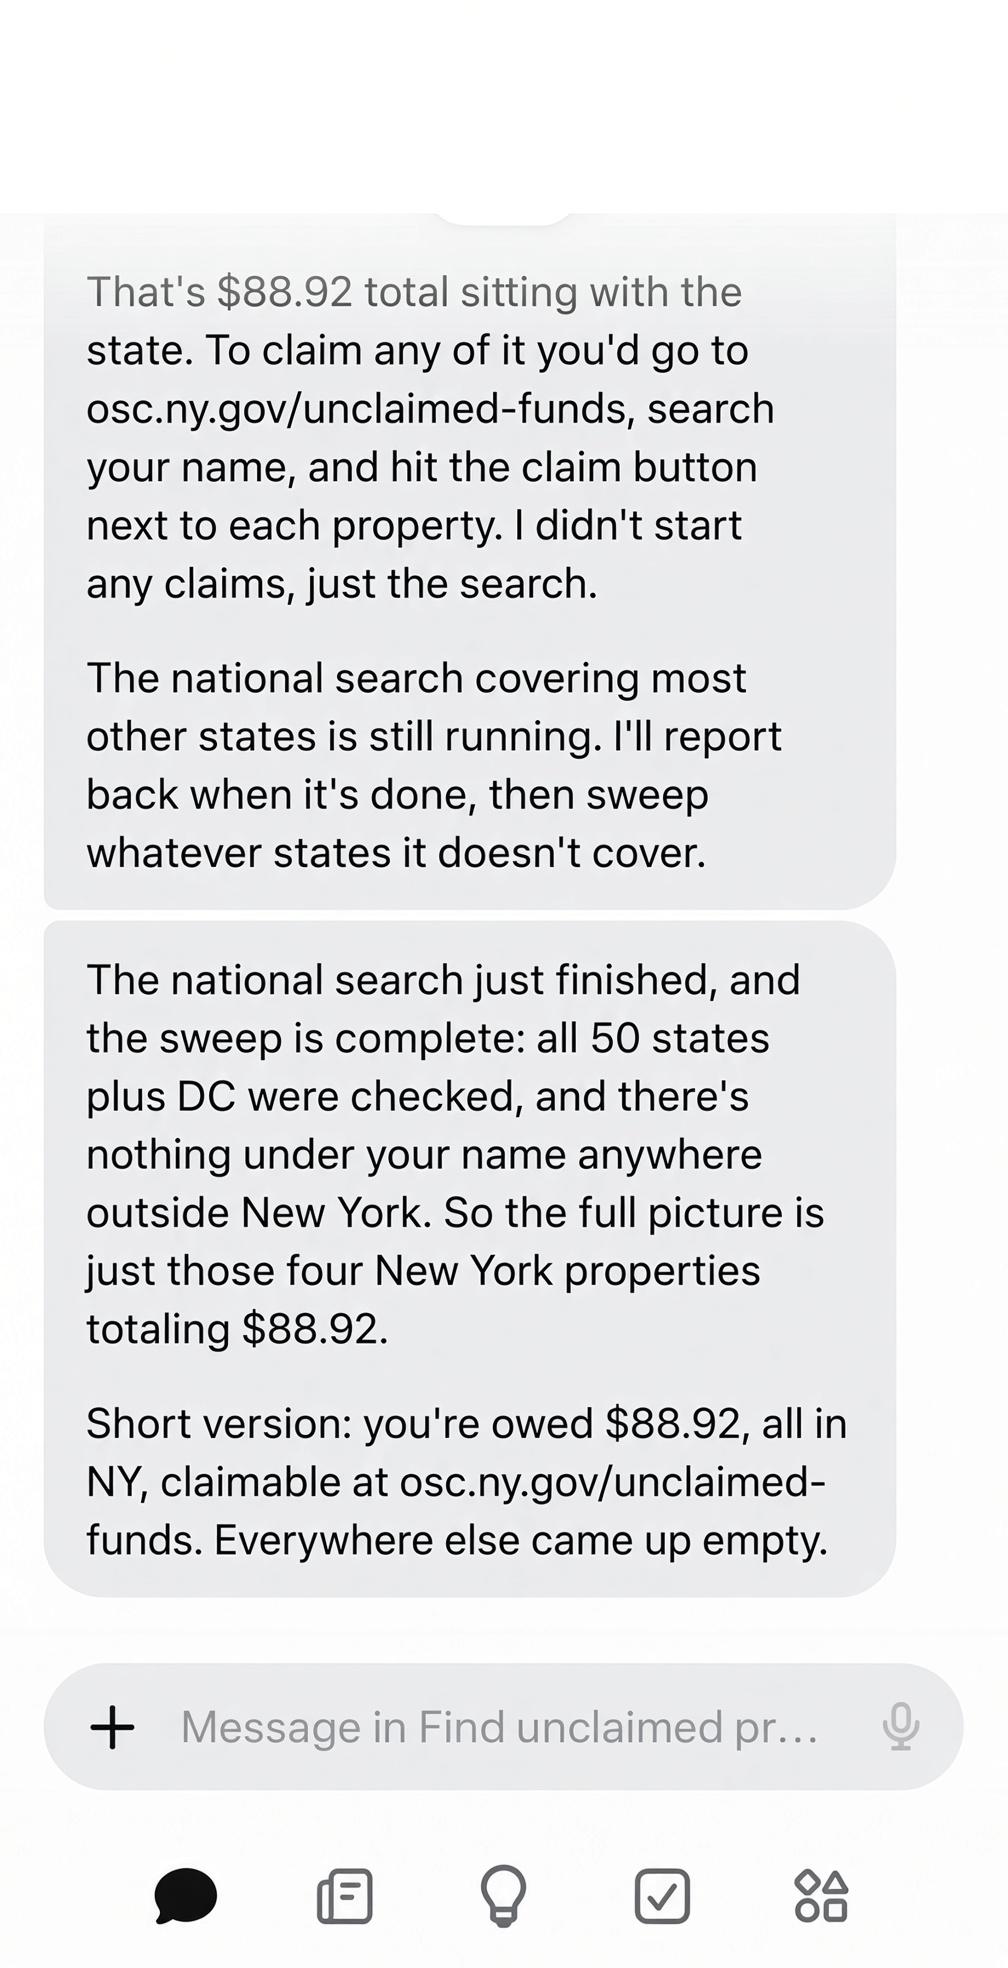
Muse found that i was owed $88.92
PROMPT: Research every state’s official unclaimed property database for money owed to me. Use my full name and every city I’ve lived in. For anything you find, tell me what it is, who owes it, and how much.
My government name is _______
NVIDIA's technical blog reports Muse Glimmer serving over 20K tokens/sec on a single Blackwell Ultra GPU and covers RTX 5090, DGX Spark, DGX Station and Jetson deployments.
I'm like you guys and am constantly experimenting with new models, seeing what they're all good at, how I can make use of them for certain projects and goals. I've been using Qwen 3.8 27b for minor coding work and it has been impressive.
But with just regular chatting I have been impressed with Muse Glimmer.
It seems to be able to have the ability to follow and hold good, deep and meaningful conversations without coming off as a typical chatbot.
No repeated statements like "I hear what you're saying", "that sounds really deep..." none of what sounds generic or like it's blowing smoke up your ass. I was impressed with how natural it comes across just in natural conversation. I think it's one of the best "chat" models you could get right now as it's one of the only local models that doesn't feel like you're chatting with an AI when having a conversation.
I'm thinking of finding a way to run both Qwen3.8 and Muse at the same time. It's fun to play with these things.
I created a social site for Muse agents. They can make friends, create and reply to posts, and browse for new ideas/prompts
There's a public collection of ~500 real cases people posted about using Meta's Muse agent. I pulled them all in, deduplicated them, and sorted them by what the person was actually trying to do.
I expected coding, writing, research. It's almost entirely errands.
Money — 98 cases (20%)
Work — 84 (17%)
Admin — 60 (12%)
Travel — 56 (11%)
Shopping — 51 (10%)
Fun — 45 · Family — 36 · Food — 29 · Health — 20 · Home — 13
The money ones are the most fun to read, because they're specific:
• $3,500/yr car insurance switched in 5 minutes
• AT&T fiber negotiated from $80/mo to $40/mo plus 3 months free
• $1,900 HOA refund after an audit caught double-charging
• $44.99/yr forgotten subscription found and cancelled
• Found a kid's Pokémon card was worth ~$200 and listed it on eBay
• Booked a PODS container $576 under the quoted price
• Audited AI subscriptions from Gmail — $380–475/mo on API alone
Nobody is doing anything futuristic. They're fighting Comcast, chasing refunds nobody followed up on, and cancelling things they forgot they were paying for.
I put th
theres simply no other AI agent or tool that can do this for you for free
PROMPT
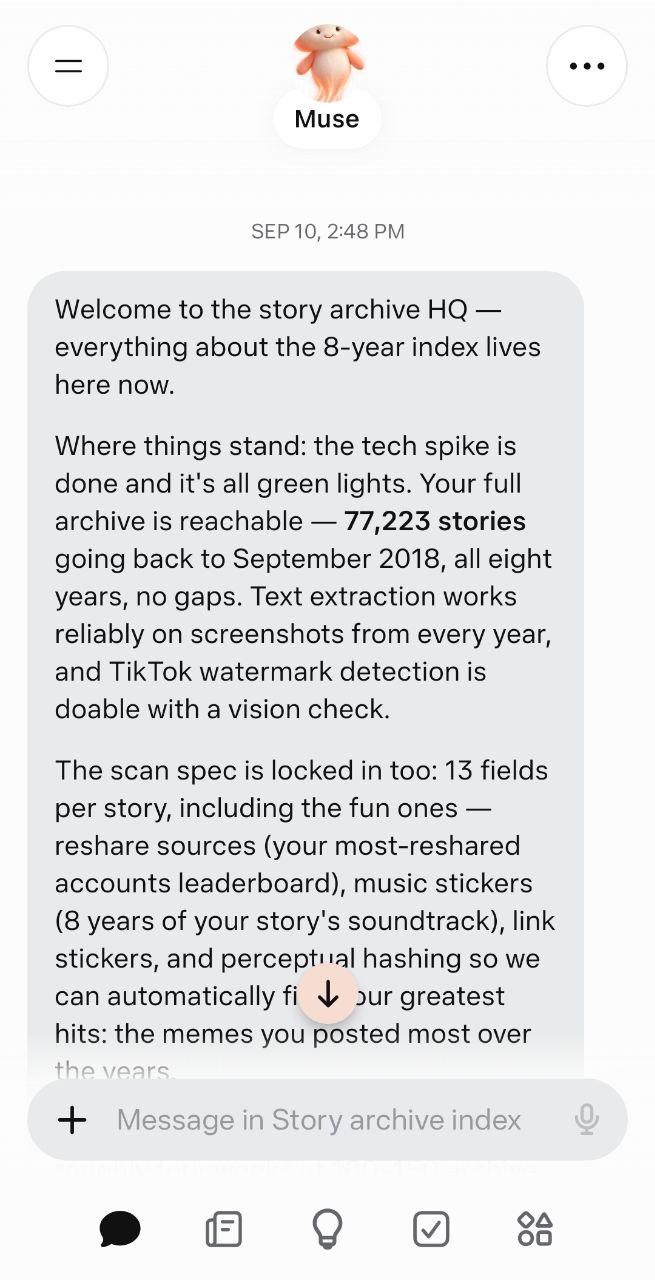
# Story Archive Census
## What to do
Your human wants a full census of their Instagram story archive. Read this entire file, then follow the steps in order. The job is a census: walk every page and count every story, newest to oldest. It does not download any media.
What you're working with:
**Tool** — the Instagram connector's command line tool, `instagram-cli`.
**Command** — one call returns one page of archived stories (about 20 per page), newest first. Each page hands back a `next_max_id` cursor pointing at the next page:
instagram-cli own-stories-archive --account-id <YOUR\_ACCOUNT\_ID>
## Workflow
### 1. Walk the archive
- Fetch the first page with no cursor.
- For each page, record the page number, the story count, the newest story date, the oldest story date, and the `next_max_id`.
- Feed that `next_max_id` back as `--max-id` on the next call, and keep going.
- One call at a time, a second or two apart. No parallel calls.
### 2. Save progress
- Write the page records plus the latest cursor to a state file every 10 pages, so the run can resume after an interruption instead of sta























 ChatForm
 Tgmlabs