№ 0413Reddit post★ Pick
Muse Glimmer 3.3x faster on Mac with mlx-dspark
Got Muse Glimmer 30B working in his mlx-dspark speculative-decoding project; on an M4 Pro the 8-bit model goes from 8.2 tok/s to 18–26 tok/s with byte-identical output.
A-Rahim added Muse Glimmer 30B support to mlx-dspark, a speculative-decoding project for Apple Silicon. He reports up to 3.27x on math, 2.5x on code and 2.22x on chat for the 8-bit model, and ~1.7x (~25 tok/s, ~18GB) for 4-bit. Output stays byte-identical because the target verifies every token.
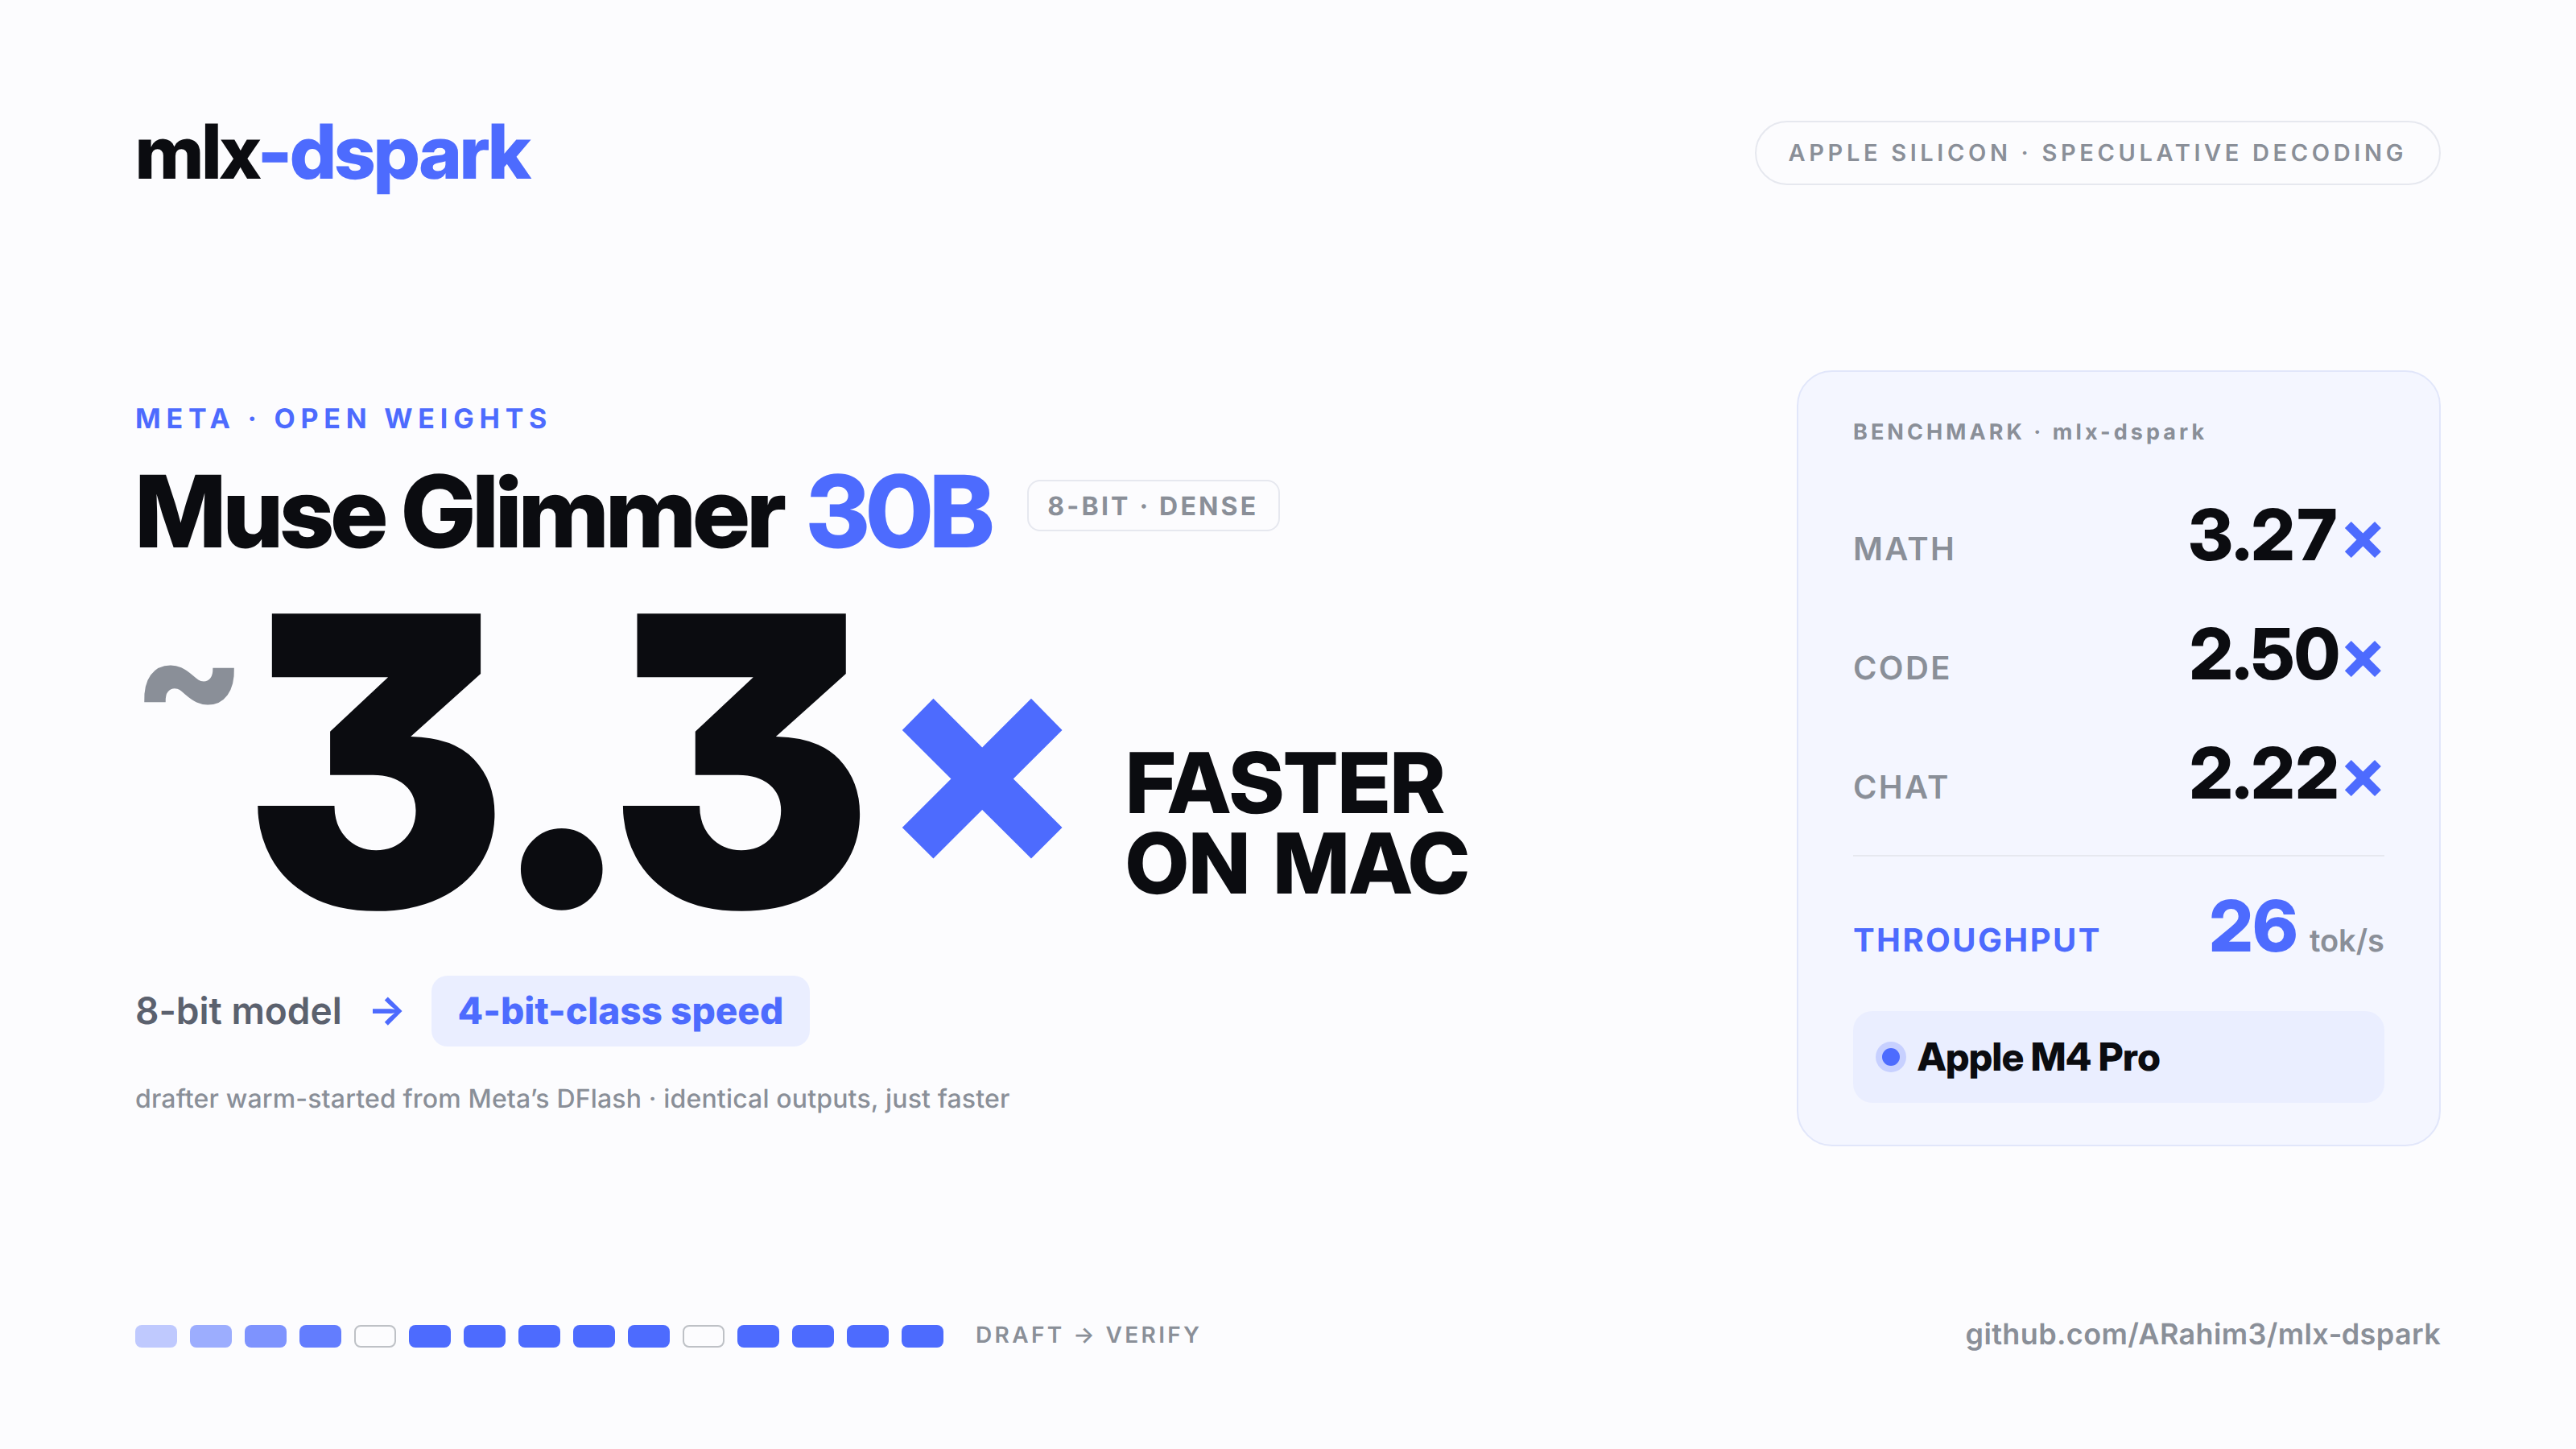
Meta's Muse Glimmer 30B now runs up to ~3.3x faster on Mac with mlx-dspark
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster. Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed. Repo: github.com/ARahim3/mlx-dspark I'm happy to hear feedback, and I'm curious about what other M-series chips get.



 ChatForm
 Tgmlabs