Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
19 builds · page 1 of 1
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
DFlash 2 speculative-decoding draft model for Muse Glimmer 30B from z-lab, run inside a speculative decoding server alongside the target model.
Resource · Local & open models· ♥ 15
Meta's lightweight DFlash block-diffusion drafter for Muse Glimmer 30B that predicts blocks of 16 tokens per forward pass for speculative decoding.
Resource · Local & open models· ♥ 61
A correctness-first bring-up of Muse Glimmer 30B on a single Tenstorrent p150 card, with paged KV cache, native DFlash speculative decoding and an OpenAI-compatible server.
GitHub · Local & open models· ★ 4
A start/stop/status launcher that serves the NVFP4 Muse Glimmer 30B checkpoint on NVIDIA DGX Spark with vLLM, Glimmer's reasoning and tool parsers, and its DFlash speculative decoder.
GitHub · Local & open models· ★ 2
A reproducible single-GPU deployment of Muse Glimmer 30B in BF16 with DFlash speculative decoding on a 96GB RTX PRO 6000 Blackwell, served via vLLM with pinned overlays and smoke tests.
GitHub · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Abid Ali Awan sets up Muse Glimmer 30B on an RTX 5090 with llama.cpp, dynamic quantization and DFlash speculative decoding, serves it locally and wires it into OpenCode to build a medical research web app.
Guide · Local & open models
Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.
Site · Local & open models
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models
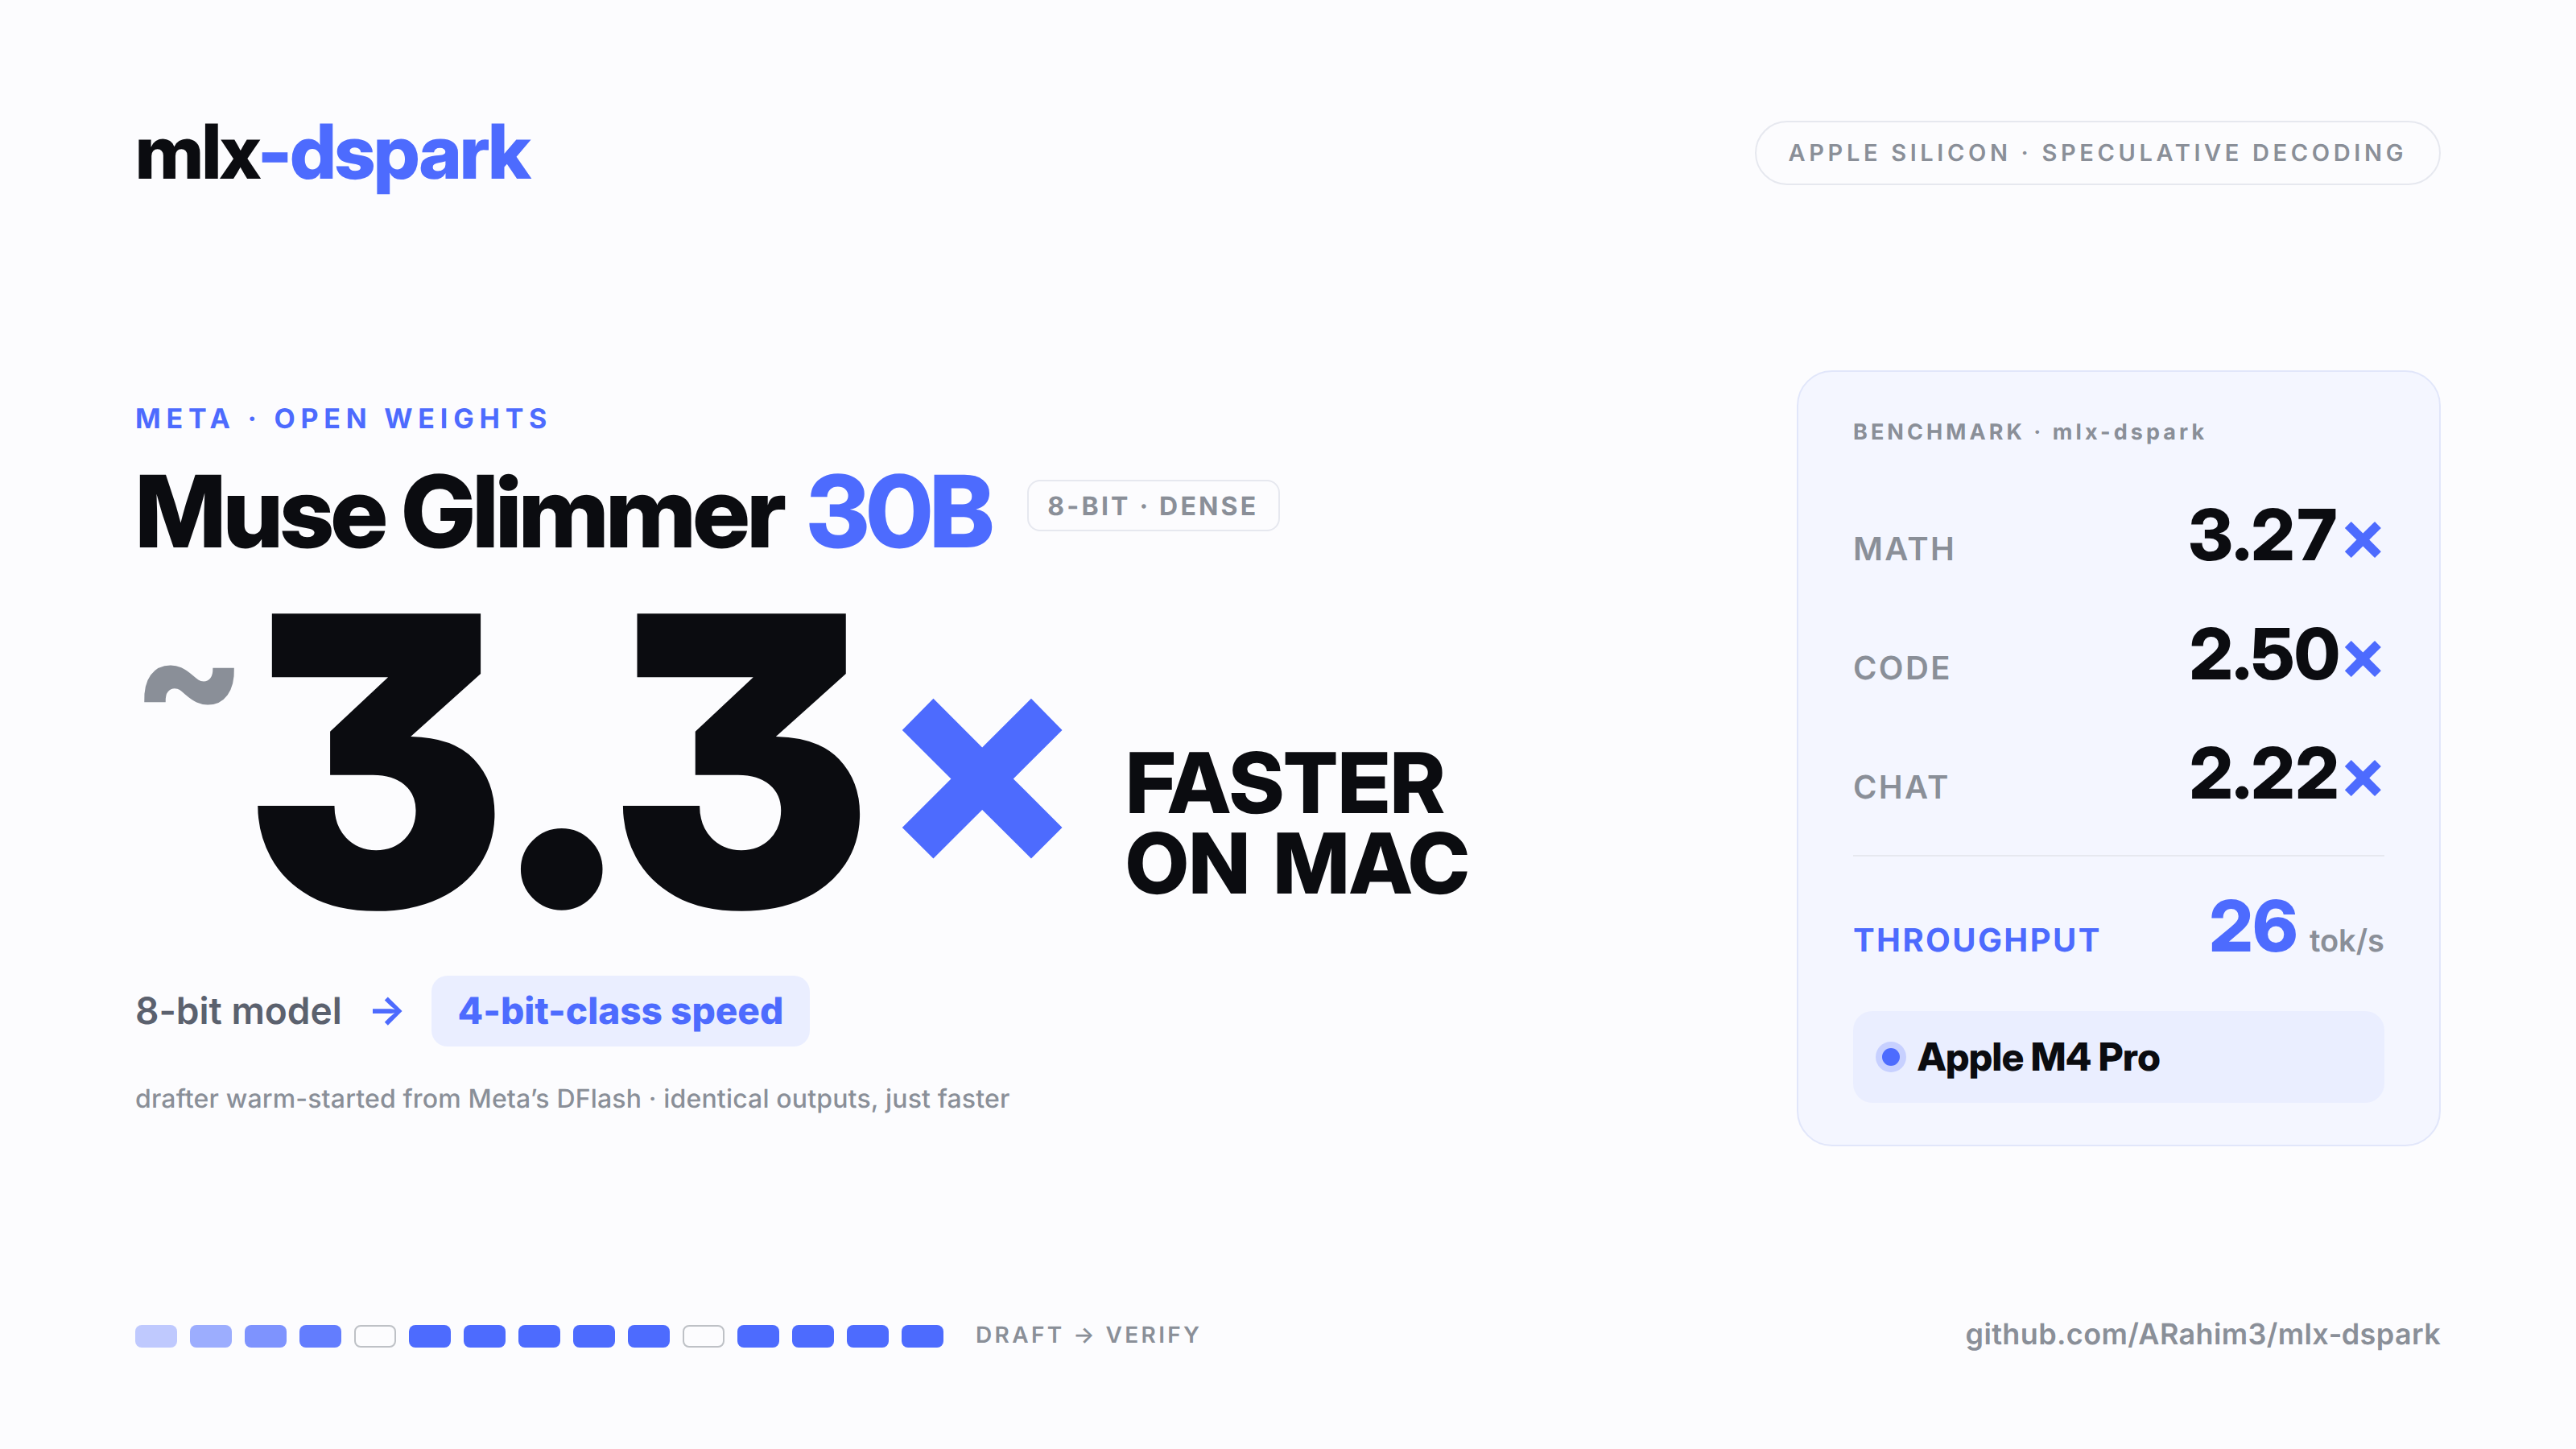
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster. Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed. Repo: github.com/ARahim3/mlx-dspark I'm happy to hear feedback, and I'm curious about what other M-series chips get.
Reddit post · Local & open models★ Pick
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
Resource · Local & open models★ Pick
Fahd Mirza installs Muse Glimmer in GGUF format and tests it with DFlash speculative decoding for faster local inference.

Video · Local & open models
GGUF conversions of Inco AI's DFlash 2 draft model for Muse Glimmer 30B, for speculative decoding in llama.cpp.
Resource · Local & open models· ♥ 16

TimDarcet
@TimDarcet
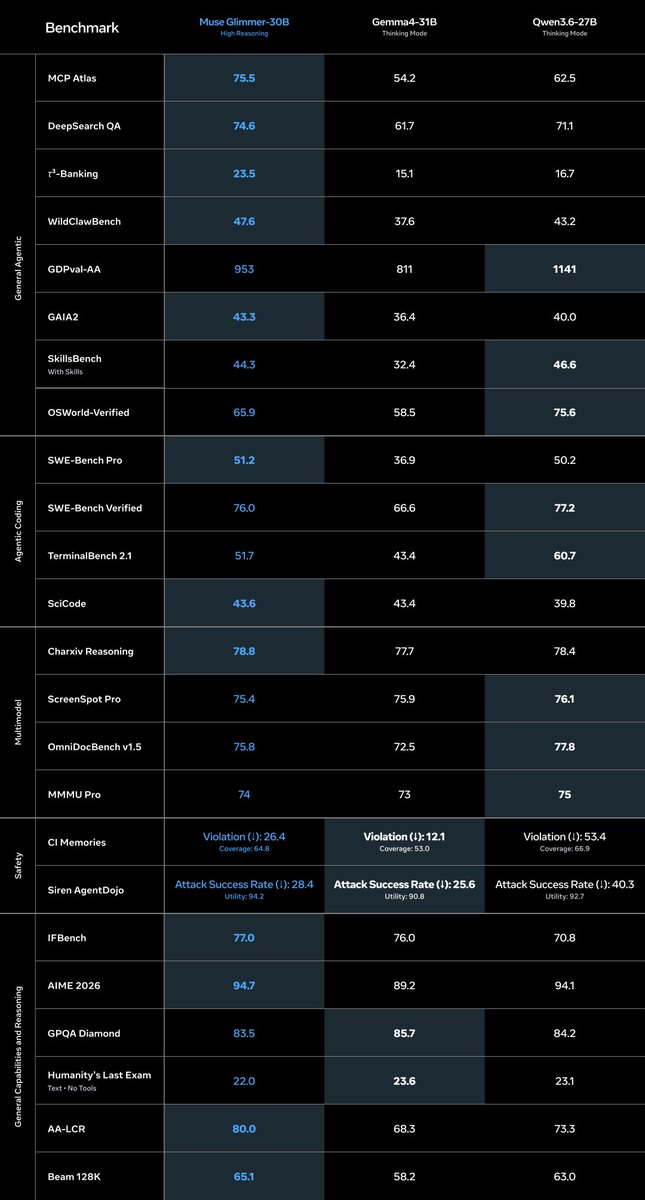
Happy to release ✨ Muse Glimmer ✨ - level ~= Qwen 3.6-27B - Apache 2 - 30B dense - quantized to run in 17GB - quant + spec dec => 50 tok/s on macbook m5 max, interactive, smooth Enjoy!
X post · Local & open models· ♥ 74
Eleven matched on/off pairs across Gemma 4 and Qwen3.6, holding model, quant, card, corpus and concurrency fixed inside each pair. Speed: 1.65x to 2.54x, every pair. Accuracy: nothing the paired intervals could separate from ordinary run-to-run movement. Muse Glimmer is the one that lost. Meta's matching DFlash drafter made the same 7900 XTX 9% slower, keeping 24.55% of drafted tokens against roughly four in five for the Gemma and Qwen heads. Acceptance fell across the run instead of warming up. Meta's model card reports 3.1x on an RTX 5090, and there are open llama.cpp issues for DFlash on AMD and under Vulkan, so I read it as the backend rather than the model. Acceptance turned out to be a poor predictor of speed. It moved under four points across five models while the multiple nearly doubled. What tracks the multiple is how bandwidth-bound the target is: a heavier quant gains more, and the two mixture-of-experts pairs gained least. Worth knowing before you benchmark anything: -md mtp-head.gguf silently disables speculation. Use -hf REPO:QUANT -hfd REPO, then read speculative from /slots and confirm it is true. Per-pair table, intervals, acceptance counters and the raw predic
Reddit post · Local & open models
A self-hosted llama.cpp serving stack that runs Muse-Glimmer-30B GGUF with DFlash2 speculative decoding on Kaggle's NVIDIA T4 x2, exposed through an authenticated OpenAI-compatible gateway.
GitHub · Local & open models
This repo documents running Muse Glimmer 30B locally on an M4 Max MacBook via llama.cpp, benchmarking it with and without speculative decoding, and wiring it into Claude Code through LiteLLM for fully offline coding.
GitHub · Local & open models
A coding-specialised speculative-decoding drafter for Muse Glimmer 30B, fine-tuned on software-engineering traces. It raises mean acceptance length to about 6.9 versus 4.0 for the community DSpark, for about 3.8x over no speculation.
Resource · Local & open models· ♥ 1
A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.
GitHub · Local & open models· ★ 8


 ChatForm
 Tgmlabs