Curated with by@mohithkumar808

Catalog / Use case

Benchmarks & research

139 benchmark results and research notes on Muse Spark and Muse Glimmer: arena rankings, index scores, head-to-head tests and architecture teardowns.

Mark Zuckerberg

@finkd

Muse Voice Transcribe is MSL's first real-time audio perception model -- rolling out today. SOTA in streaming speech-to-text, it handles speaker diarization, and endpointing natively in a single model.

X post · Benchmarks & research★ Pick· ♥ 5.5K

Muse Voice Transcribe

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

J A Z I I

@notjazii

meta muse just mogged fable 5.1 tested fable 5.1 and muse spark 1.3 with same prompt at highest reasoning available and results came out really different > muse spark 1.3 completed task in one minute and costed almost nothing > fable 5.1 completed task in 70 minutes and costed

X post · Benchmarks & research· ♥ 266

Same prompt: 1 minute vs 70 minutes

Deedy

@deedydas

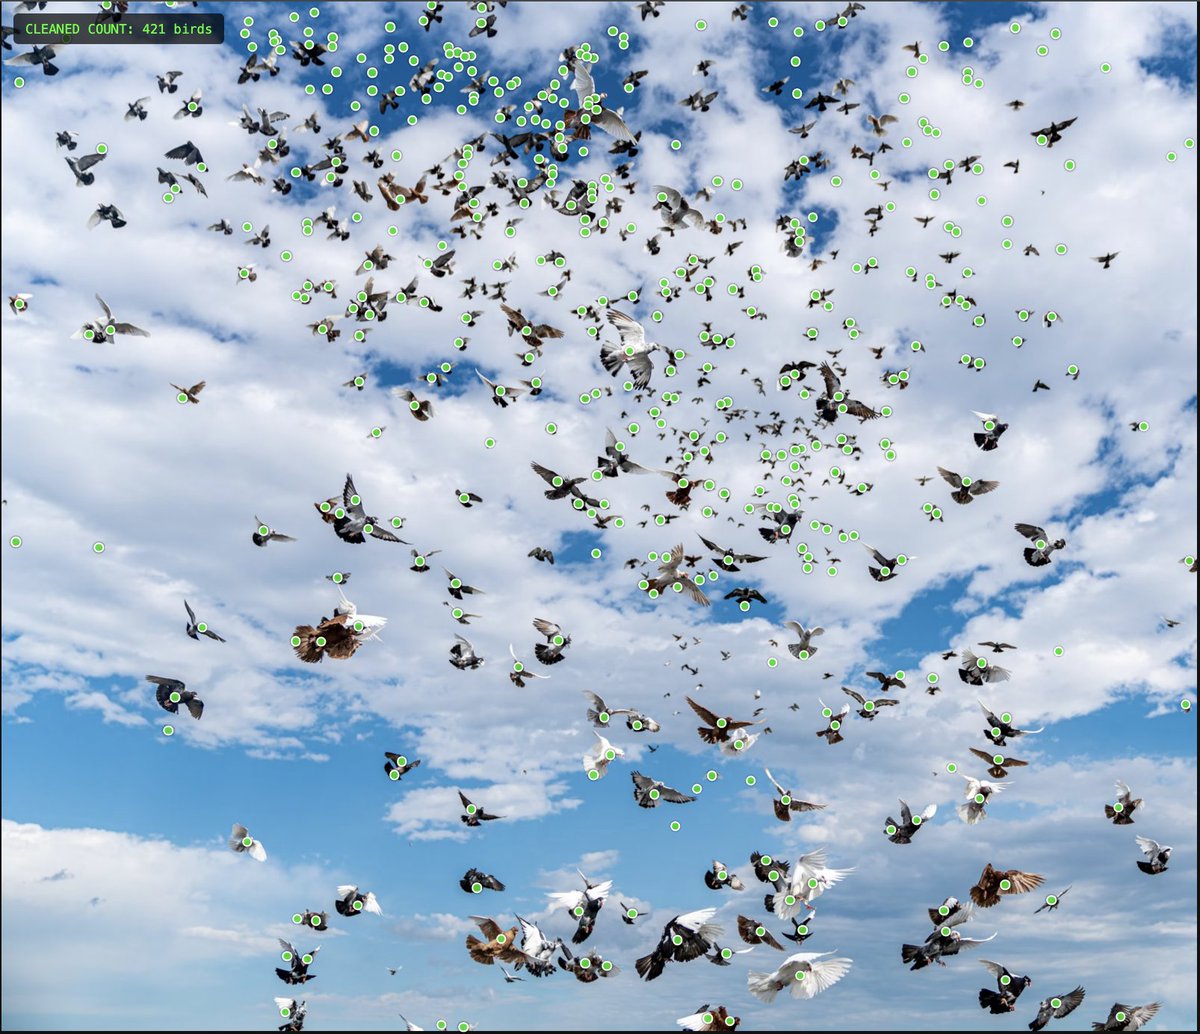
The coolest thing Meta AI's Muse Spark can do by far is counting objects! As you can tell, it's far from perfect. They call it "visual grounding" and it can count objects and do bounding boxes. I've been playing with the new model and here's what I think so far: Good stuff: –

X post · Benchmarks & research· ♥ 370

Visual grounding and counting tests

U

DerTomsn

u/DerTomsn

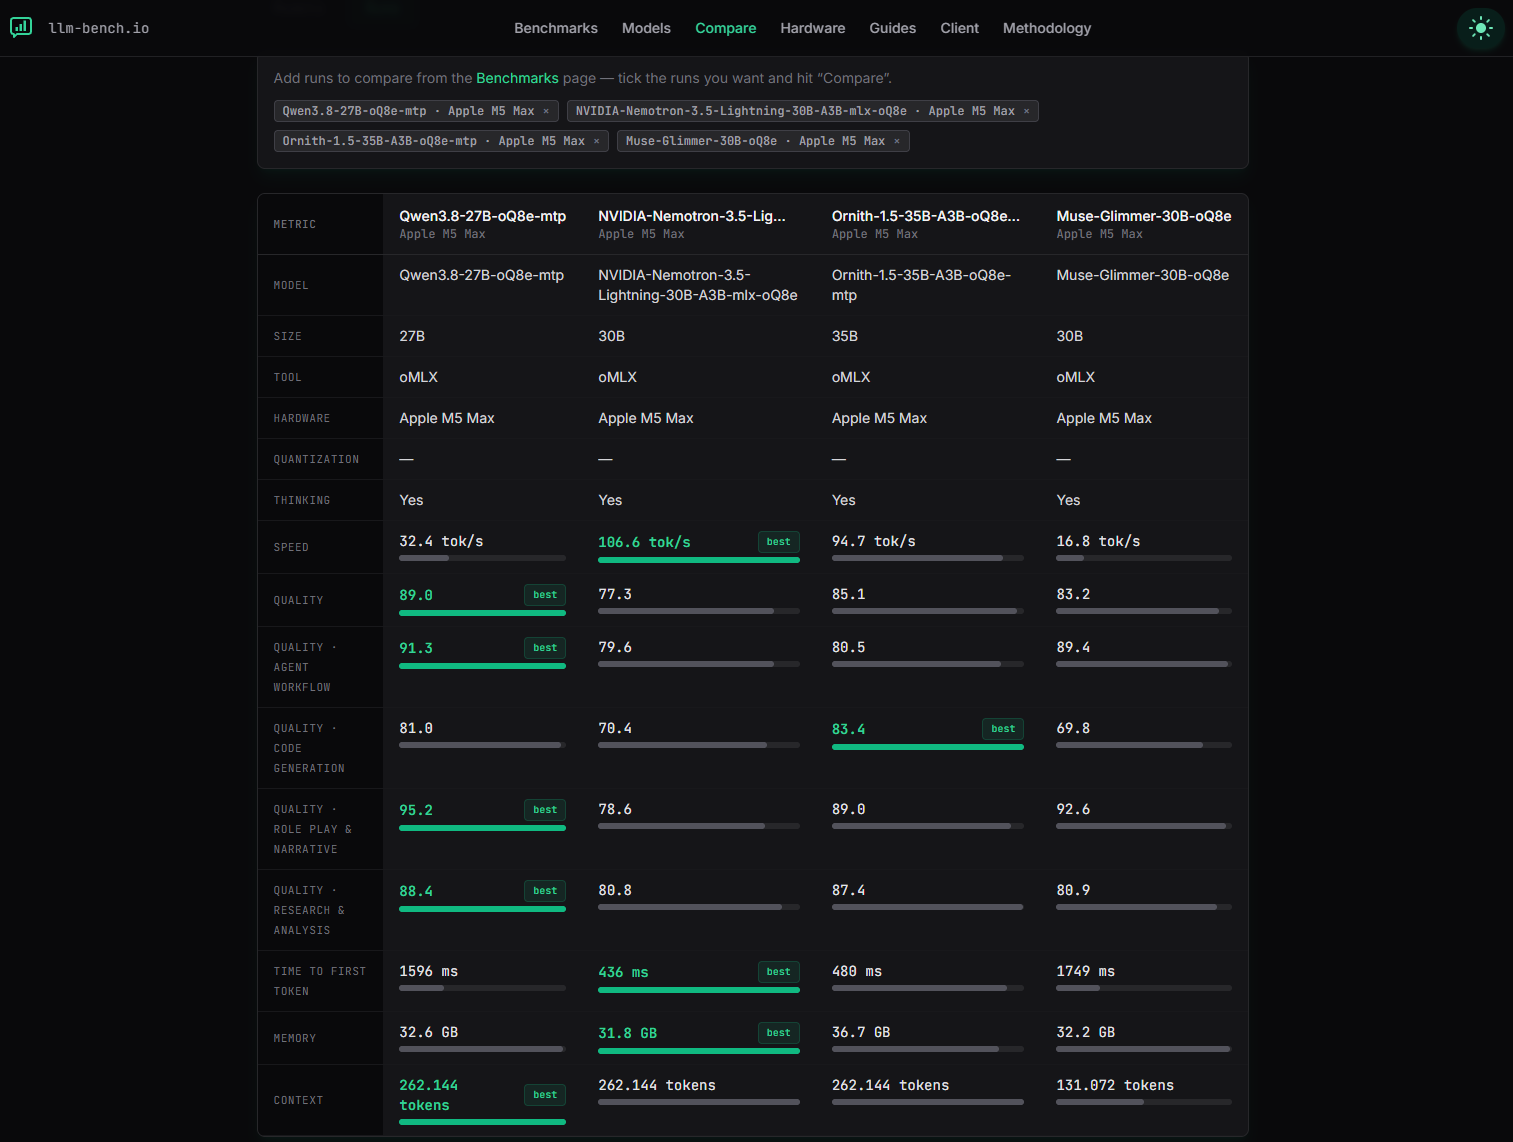
Ornith does really well. TielCoder (https://llm-bench.io/benchmarks/cmt7kp2zj002r01lcmpchvlko) might be even a bit better in coding. Will give it a try soon. Details of the comparison see here: https://llm-bench.io/compare/runs?runs=cmt6ecf8g000001p45vwzux53%2Ccmt6ergk5000701p41hqdyy78%2Ccmt6f2oob000e01p49o9592cb%2Ccmt6fqddm000l01p4l1vm7skd

Reddit post · Benchmarks & research

Four-way local model comparison incl. Glimmer oQ8e

mindstudio.ai

mindstudio.ai

MindStudio notes Muse Spark 1.3 topped DeepSWE at 75.4 and placed third on Artificial Analysis, yet in a hands-on game-clone test produced "a cube shooting at other cubes."

Resource · Benchmarks & research

Why Muse Spark 1.3's benchmark scores don't add up

geekwire.com

geekwire.com

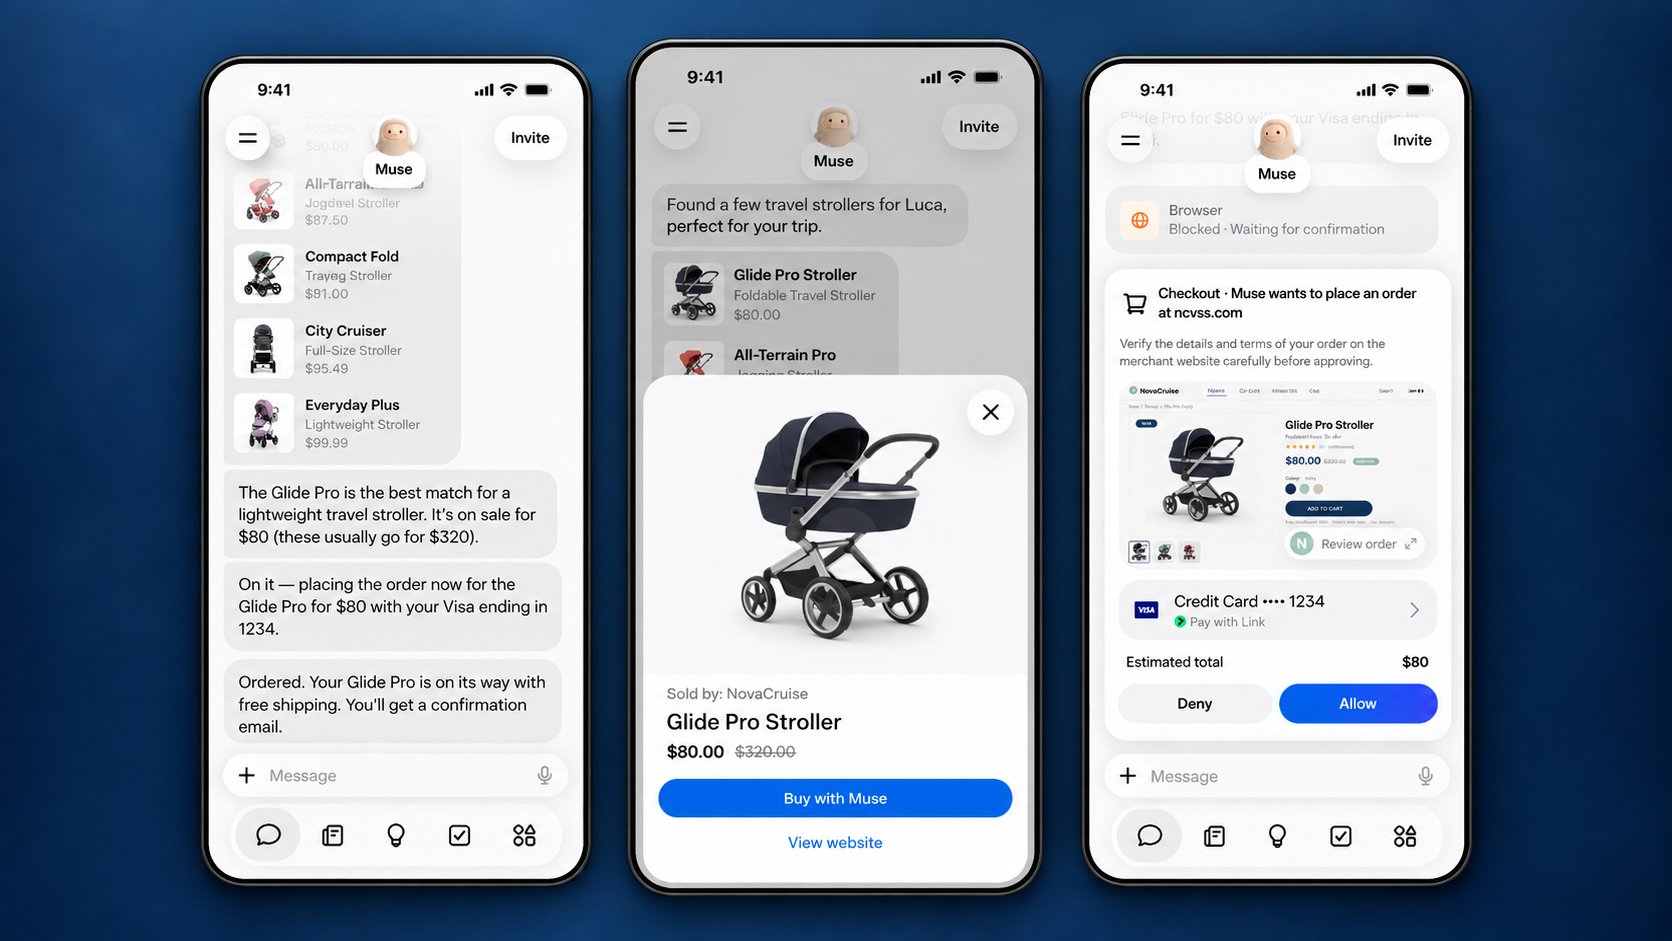
GeekWire reports Amazon blocked Muse from making purchases as of September 20, saying the agent accessed its store without permission, didn't identify itself, and appeared to store credentials.

Resource · Benchmarks & research

Amazon blocks Meta's Muse shopping agent

thehype.

@thehypedotnews

muse glimmer 30b vs nemotron 3.5 lightning – on agentic coding two 30b open-weight agent models, released three days apart, both sold as the model you leave running. same harness, same tools, same tasks, two of them: repair a broken landing page, then write breakout from a spec

X post · Benchmarks & research· ♥ 32

Muse Glimmer vs Nemotron on agentic coding

Arena.ai

@arena

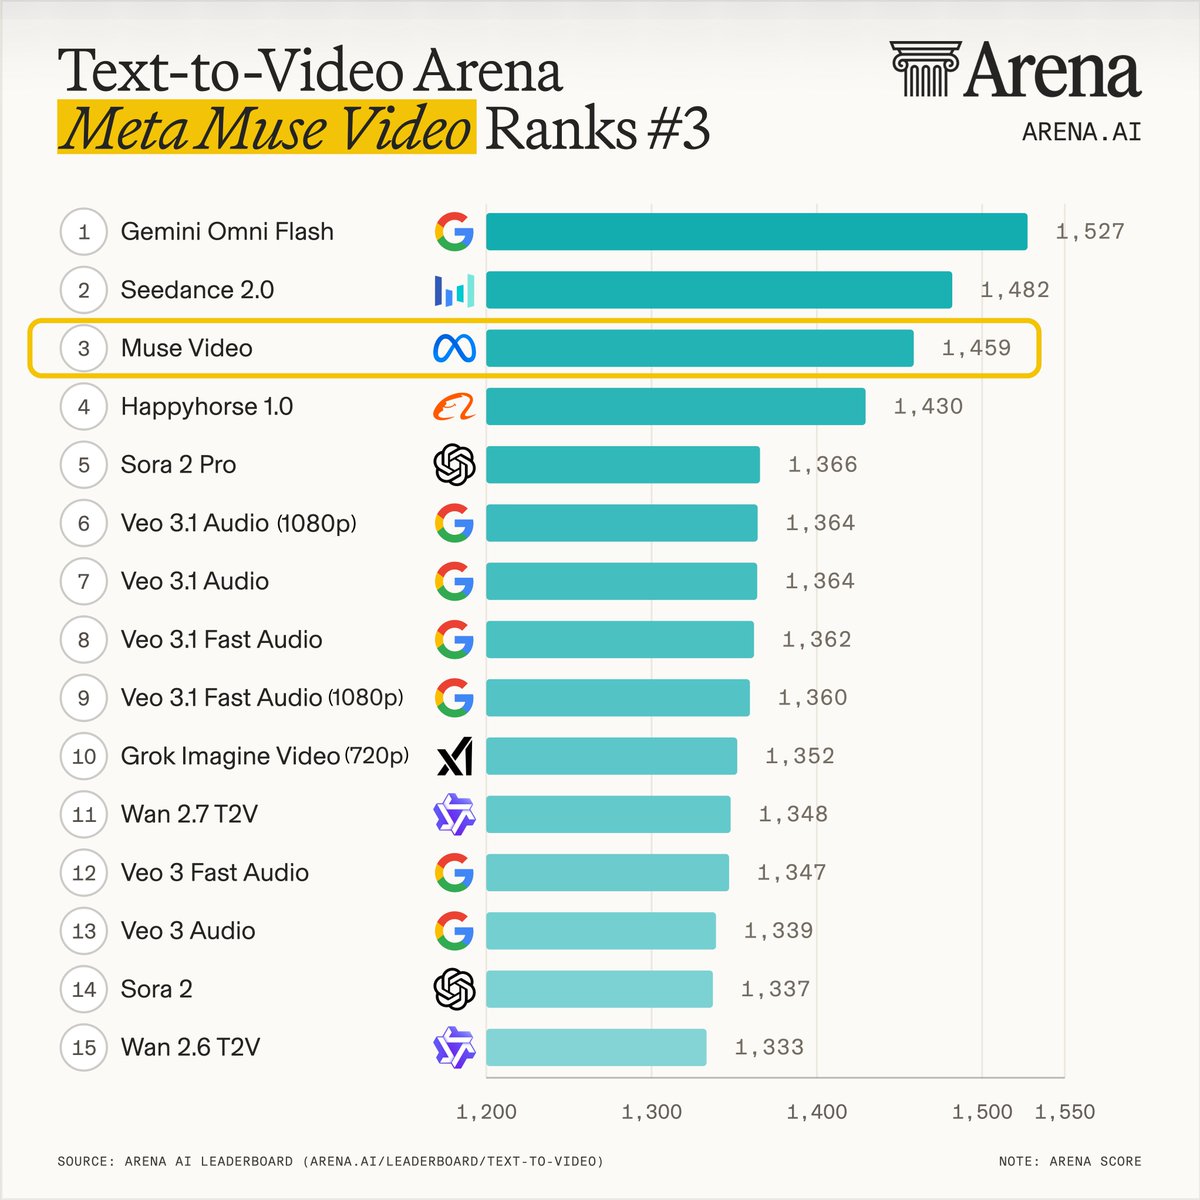
Meta Muse Video just entered the Video Arena at #3. @AIatMeta’s new video model scored 1459 in the Text-to-Video Arena. It outperforms Alibaba’s HappyHorse 1.0 by +30pts and ranks ahead of Grok Imagine, Sora 2 Pro and Google Veo-3.1 models. Meta has now reached the video AI

X post · Benchmarks & research★ Pick· ♥ 611

Muse Video enters Video Arena at #3

Iam_

@SPAC89

Muse Spark 1.3 Ultra Contributor vs Fable 5.1 xHigh Same prompt, both ran for roughly 2 hours The prompt had a self improvement rule: if the independent judges scored the result below 9.5/10, it had to keep improving and try again, What shocked me most was that Muse Spark just

X post · Benchmarks & research★ Pick· ♥ 1.2K

20 self-improvement loops for under $1

Vals AI

@ValsAI

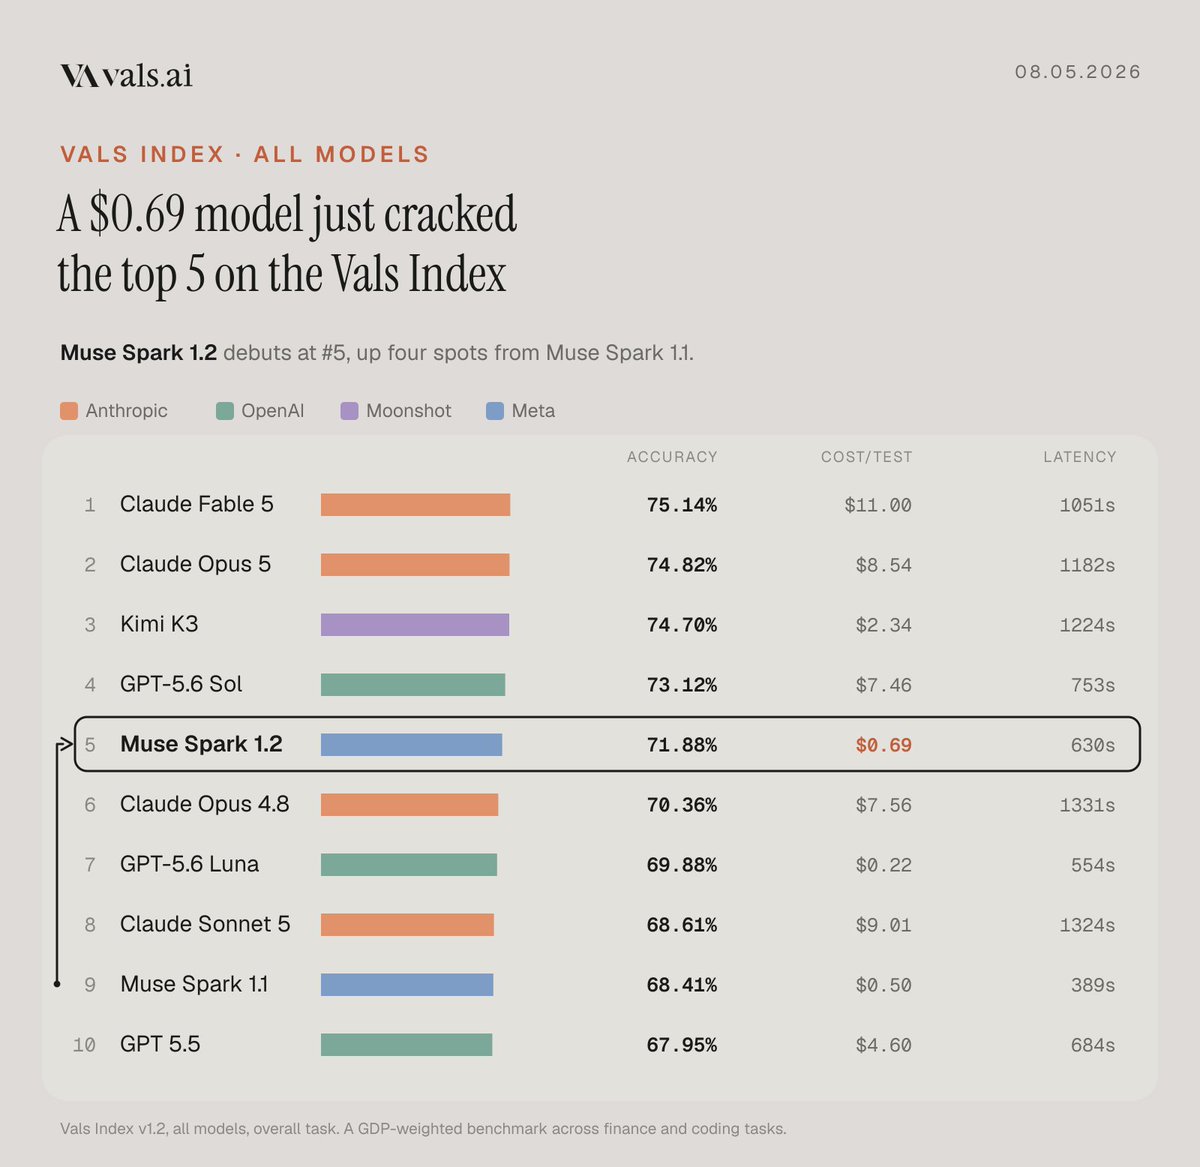
Muse Spark 1.2 just cracked the top 5 on the Vals Index, at just $0.69 per test. This is 3x cheaper than Kimi and 10x or more cheaper than Fable, Opus, and 5.6 Sol.

X post · Benchmarks & research★ Pick· ♥ 773

Muse Spark 1.2 enters Vals Index top 5

Cline

@cline

Muse Spark 1.1 just launched and it's their most capable coding agent model yet. On Terminal-Bench 2.1 it scores 80.0%, in the same cluster as Opus 4.8 (82.7%) and GPT 5.5 (83.4%). Use it in Cline with the Meta API!

X post · Benchmarks & research· ♥ 191

Spark 1.1 scores 80% on Terminal-Bench 2.1

AI at Meta

@AIatMeta

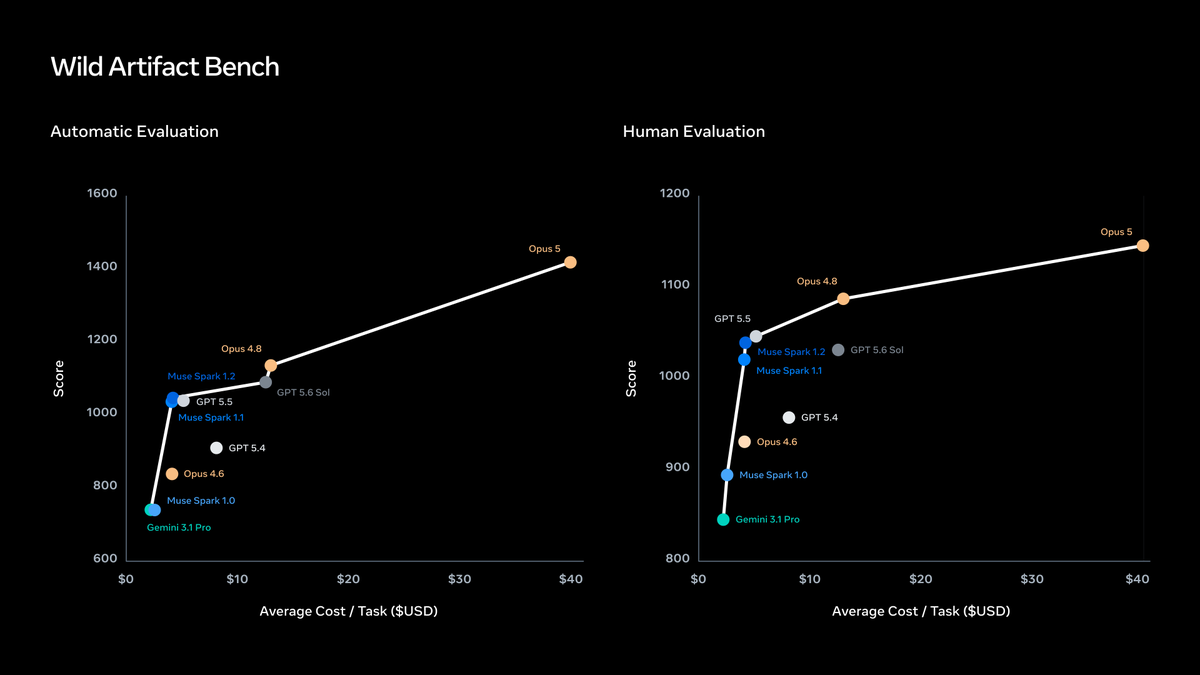
Today we’re also previewing WildArtifactBench, an internal evaluation framework designed to assess agents on complex, real-world tasks across diverse deliverable formats. By using win rates and Elo scores from human and agentic preference judges rather than strict ground-truth

X post · Benchmarks & research★ Pick· ♥ 637

WildArtifactBench agent eval preview

wh

@nrehiew_

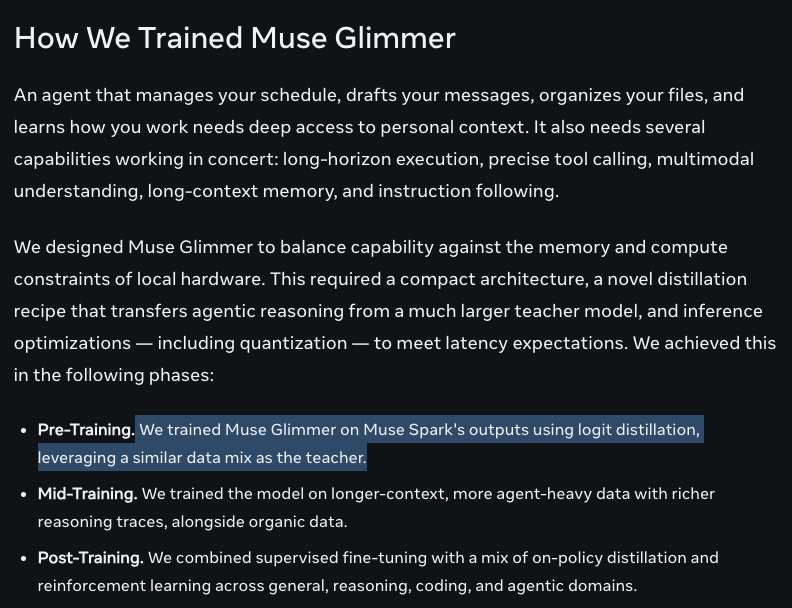
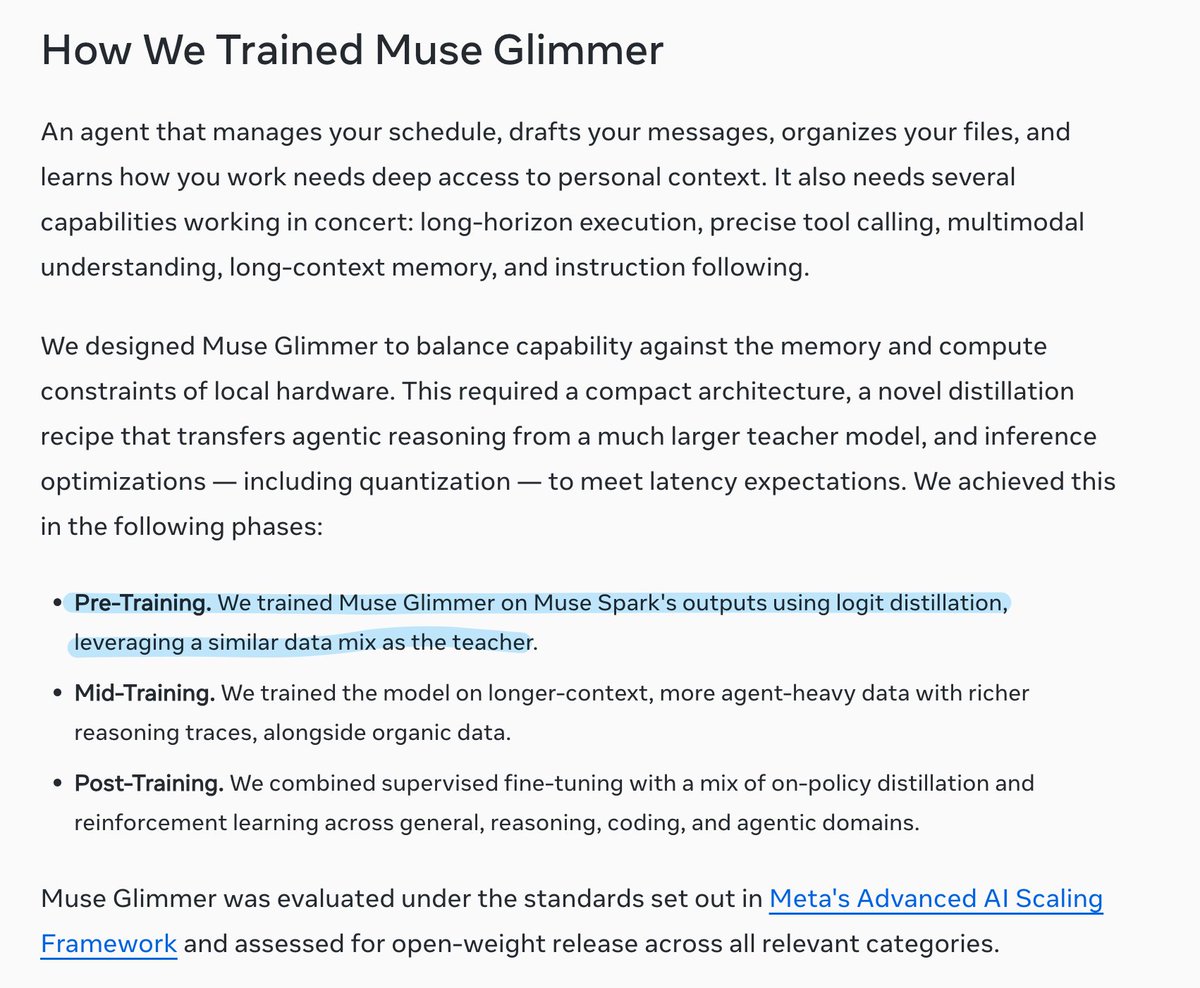
Muse Glimmer was trained directly logit distilled from Muse Spark. This means that there isn't a traditional 'base model' in that it was trained from the start on agentic traces. Super cool and haven't seen this approach in a while Welcome back GPT OSS

X post · Benchmarks & research· ♥ 336

Glimmer was logit-distilled from Spark

Artificial Analysis

@ArtificialAnlys

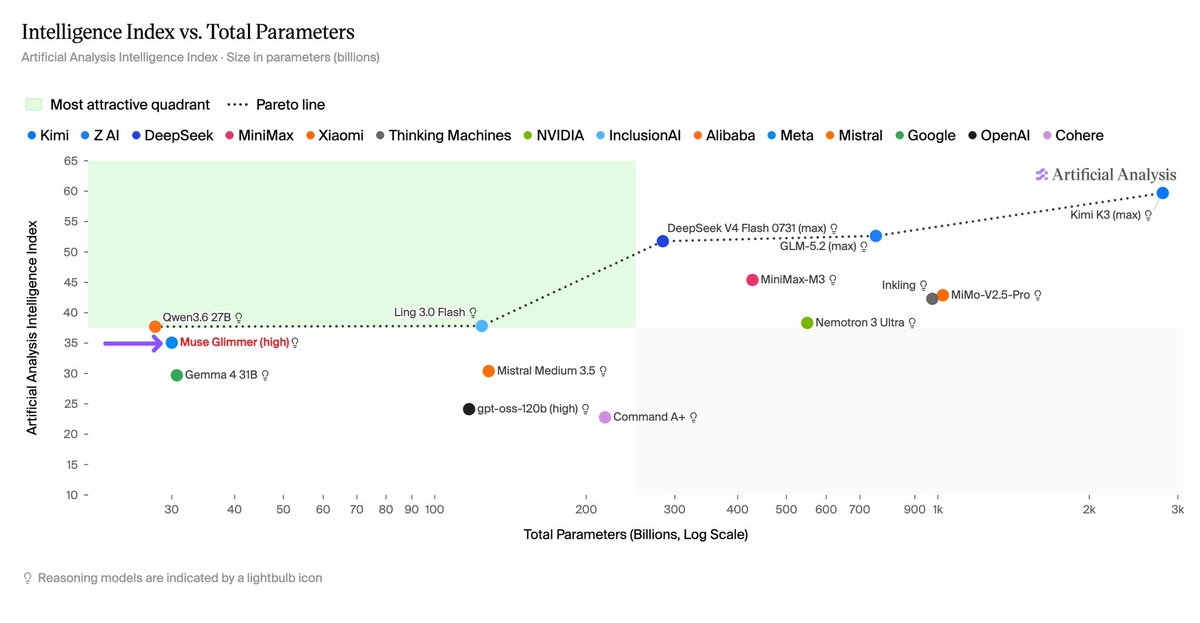
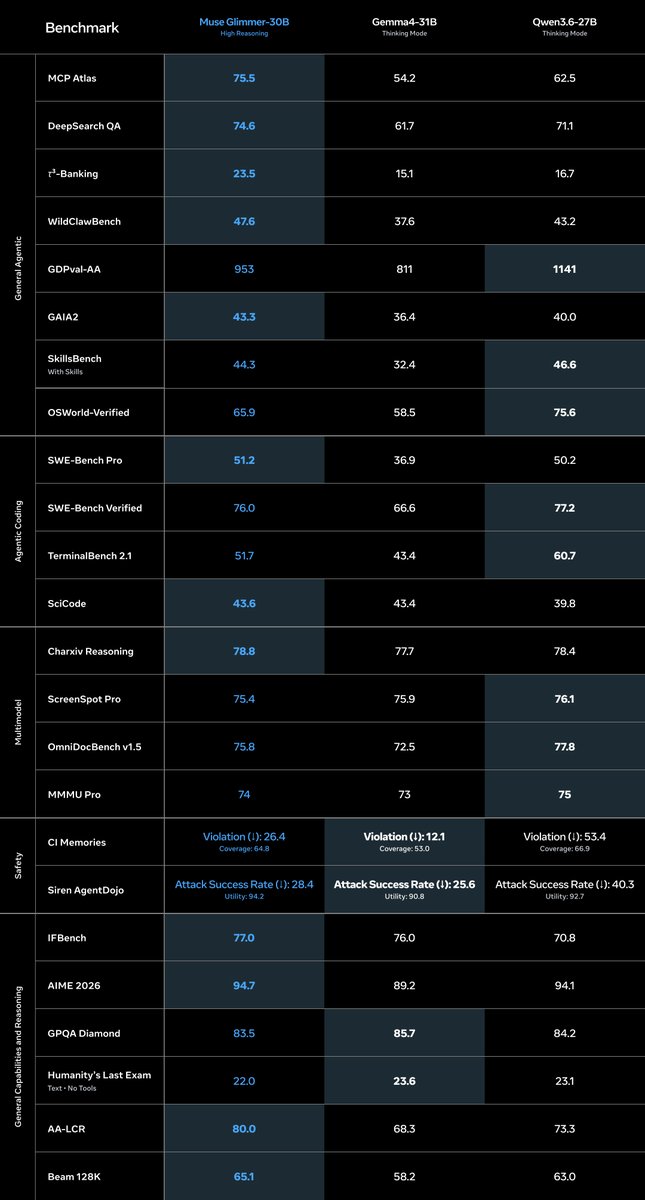
At 30B parameters, Muse Glimmer sits near the Intelligence vs Parameters frontier for open weights models: 5 points above Gemma 4 31B (Reasoning) at the same size, effectively matching Kimi K2.5 (Reasoning) at 33x fewer total parameters, and just behind Qwen3.6 27B (Reasoning),

X post · Benchmarks & research· ♥ 60

Glimmer on the intelligence vs parameters frontier

pilvar (Philippe Dourassov)

@pilvar222

We ran Muse Spark 1.3 on our Cybersecurity benchmark, and it's actually not that good (yet) 😬 - At pass@1, it rediscovers an average of 19/32 CVEs. In comparison, Grok 4.6 scores 23.3/32 - When pooling the results of 3 runs (pass@3), Muse scores 24/32. DeepSeek V4 Pro gets

X post · Benchmarks & research· ♥ 116

Muse Spark 1.3 on a CVE rediscovery benchmark

Artificial Analysis

@ArtificialAnlys

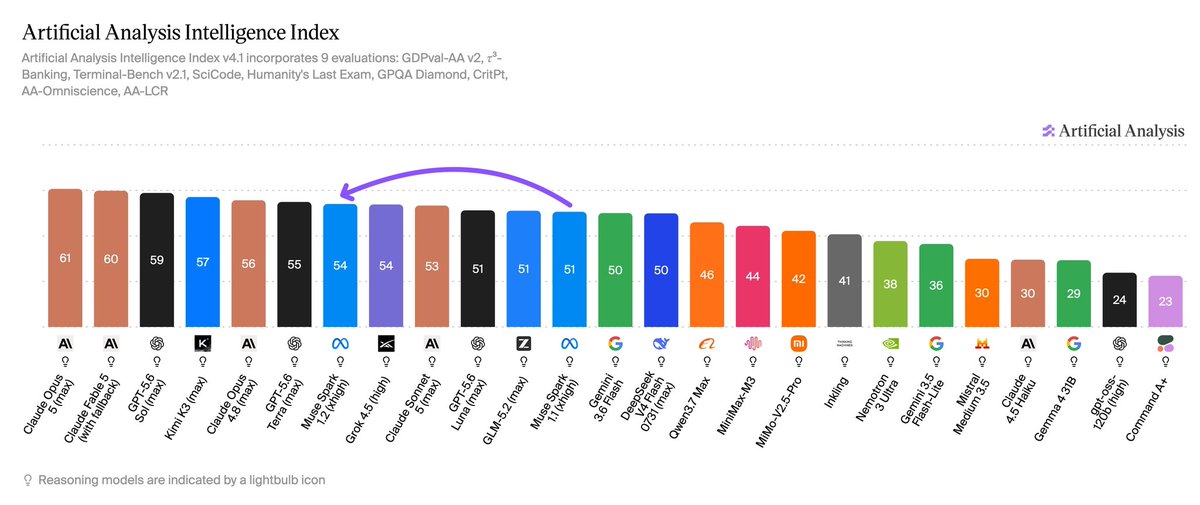
Meta has released Muse Spark 1.2. It's their third release in four months and scores 54 on the Artificial Analysis Intelligence Index, significantly improving agentic knowledge work capabilities over prior releases and putting Meta next to SpaceXAI in a tie for third place

X post · Benchmarks & research★ Pick· ♥ 1.2K

Spark 1.2 scores 54 on the Intelligence Index

Louis-François Bouchard 🎥🤖

@Whats_AI

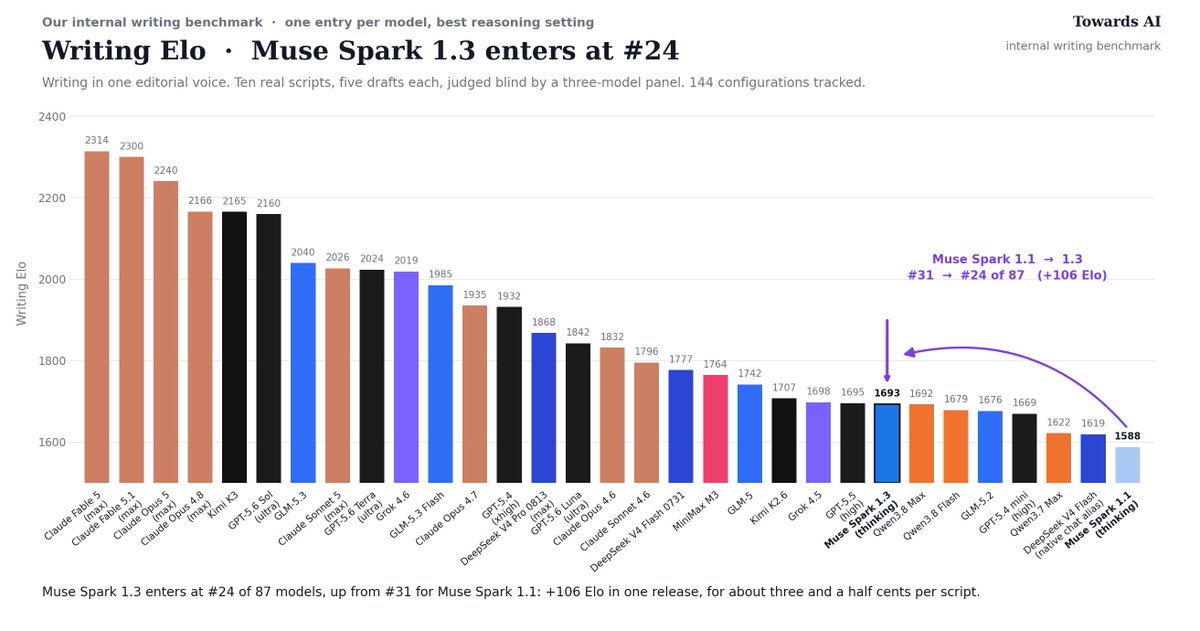
We just measured Meta Muse Spark 1.3 on our internal writing benchmark hoping for new SOTA. Unfortunately, it isn't... It enters at #24 of the 87 models we track, up from #31 for Muse Spark 1.1. As @alexandr_wang highlighted, it beats every Gemini configuration we have,

X post · Benchmarks & research· ♥ 9

Muse Spark 1.3 on a writing benchmark

Tom Collins

@thetomcollins

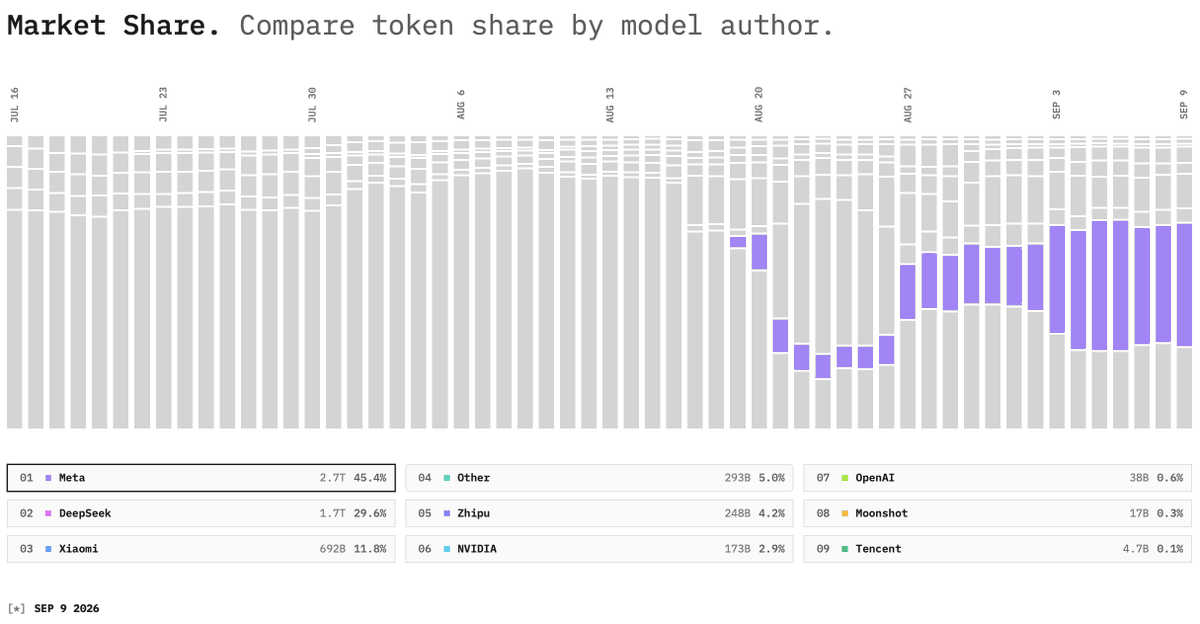
$META just went from 3.5% to 45.4% token share on OpenCode in just over two weeks Muse Spark 1.3 being good + free is enough to become the default for most users Default gets you usage → usage gets you data → data makes the next model better Anthropic and OpenAI can’t afford

X post · Benchmarks & research★ Pick· ♥ 738

Meta's OpenCode token share hits 45%

チャエン | デジライズ CEO《重要AIニュースを毎日最速で発信⚡️》

@masahirochaen

【速報】Metaが30BのオープンモデルMuse Glimmerを公開。18GBのRAMで動く。 久々のMetaからの本格オープンモデル。 小型なので低スペックのPCでも動かせるAIモデル。 ・Apache 2.0で商用利用可、重みはHugging Faceで公開 ・画像も読めるvisionモデル、100言語超に対応 ・MCP Atlas

X post · Benchmarks & research· ♥ 96

Muse Glimmer launch rundown (Japanese)

thehype.

@thehypedotnews

muse spark 1.2 vs gpt 5.6 sol vs kimi k3 vs grok 4.5 – on two landing pages four coding agents built two desktop landing pages from scratch, then had to open them in a real browser, find their own bugs and fix them before they were allowed to hand anything over the setup: each

X post · Benchmarks & research· ♥ 64

Landing pages built and self-debugged by Muse Code

Artificial Analysis

@ArtificialAnlys

Last week the Intelligence Index vs Cost Pareto frontier moved out substantially. Claude Fable 5.1, Muse Spark 1.3, and GPT-6 Astra each set a new point in efficient intelligence Link to analysis: artificialanalysis.ai/#intelligence-…

X post · Benchmarks & research★ Pick· ♥ 732

Spark 1.3 moves the cost Pareto frontier

U

myanimal22

u/myanimal22

Some people told me that the difference in richness and layout between Glimmer and Qwen wasn't clear to them. This example makes it super clear. I'm aware that comparing Glimmer 30B (a dense model) with Qwen 3.6 (a MoE) isn't entirely fair, but if we compare it to the dense Qwen 27B, the gap will likely be even bigger. If you want, I can add the 27B version later. For now, I'm waiting for Qwen 3.8 27B to see how close it gets to the blueprint. As for the technical details: Both were run on a custom llama.cpp build optimized for the RTX 5080, with a temperature of 0.5 and a 125k context window. Regarding the music: I created it myself without using AI I specifically wanted it to sound that weird.

Reddit post · Benchmarks & research

DS4 vs Qwen3.6 vs Glimmer on one design prompt

U

Ok-Inevitable8391

u/Ok-Inevitable8391

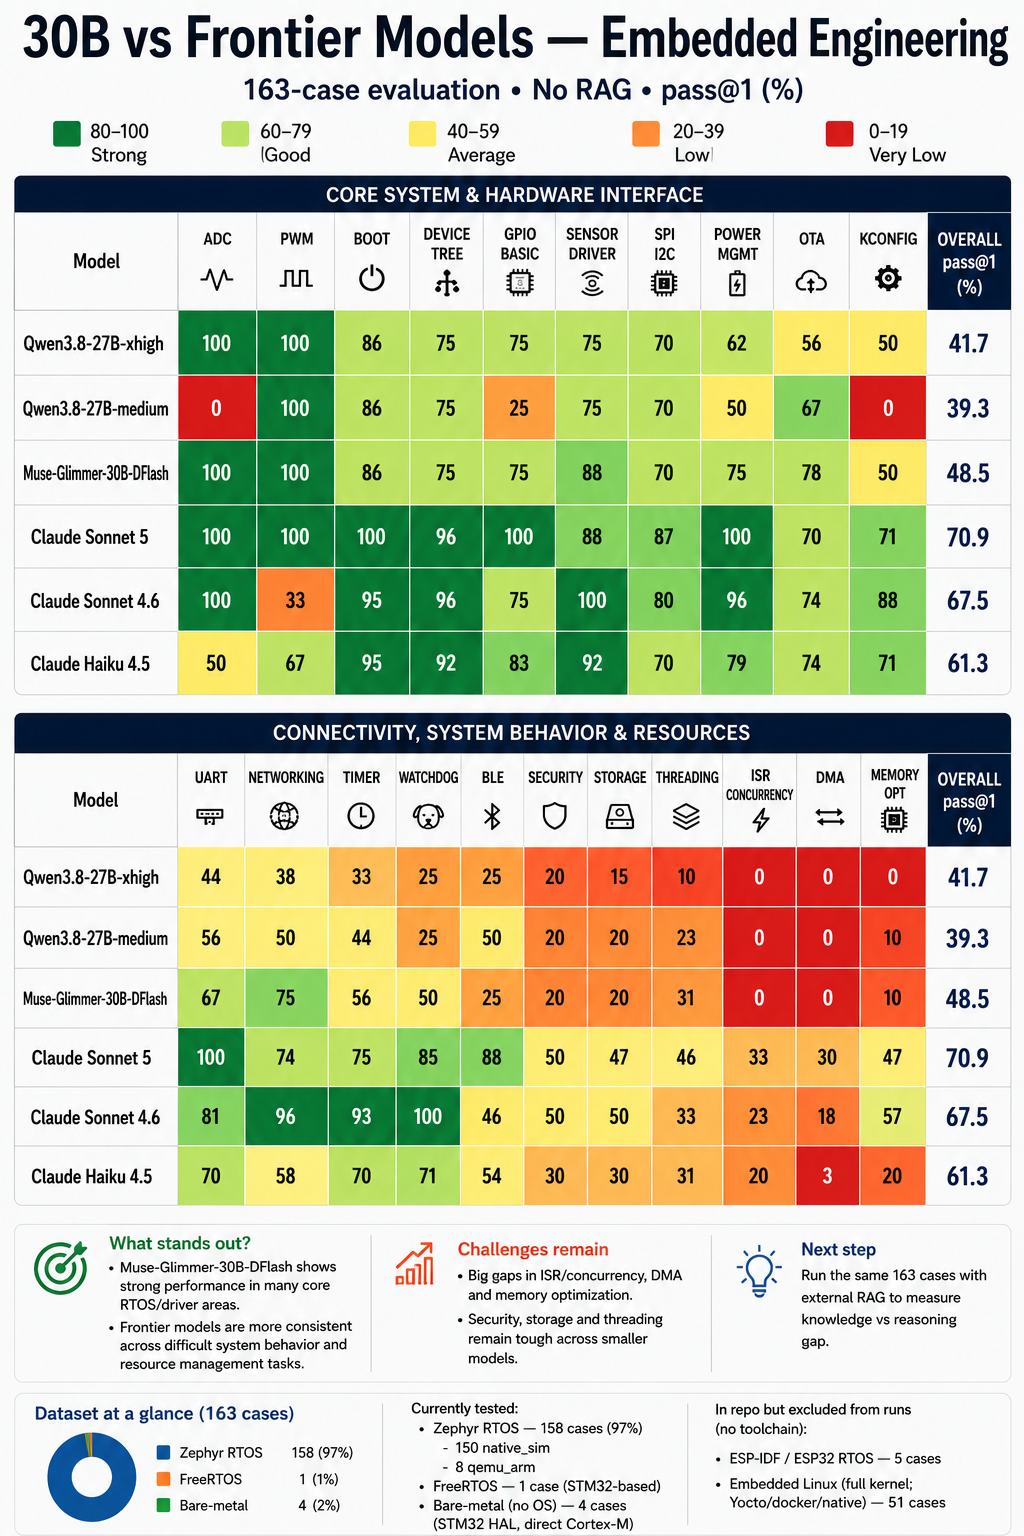
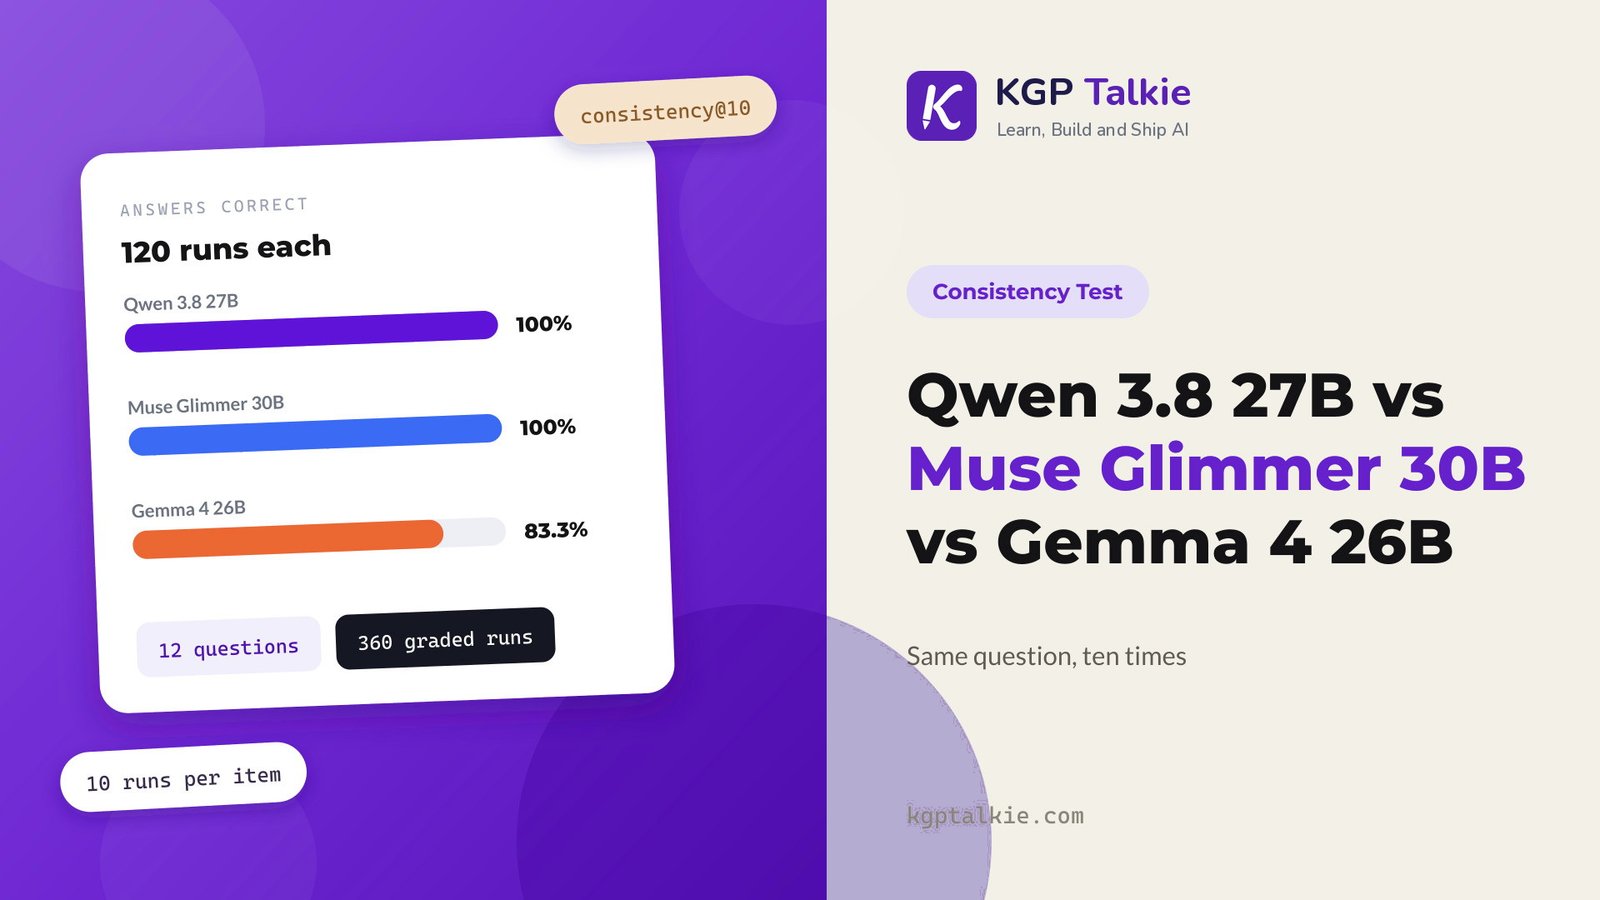
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.

Reddit post · Benchmarks & research

Glimmer vs Qwen 3.8 on an implicit-knowledge eval

@barkleesanders

@barkleesanders

A static teardown of Meta's Muse macOS app (codename Endo) finding a full computer-use agent in the public build, switched off by five server-delivered feature flags.

GitHub · Benchmarks & research

Muse for Mac 'Endo' teardown

Design Arena

@DesignArena

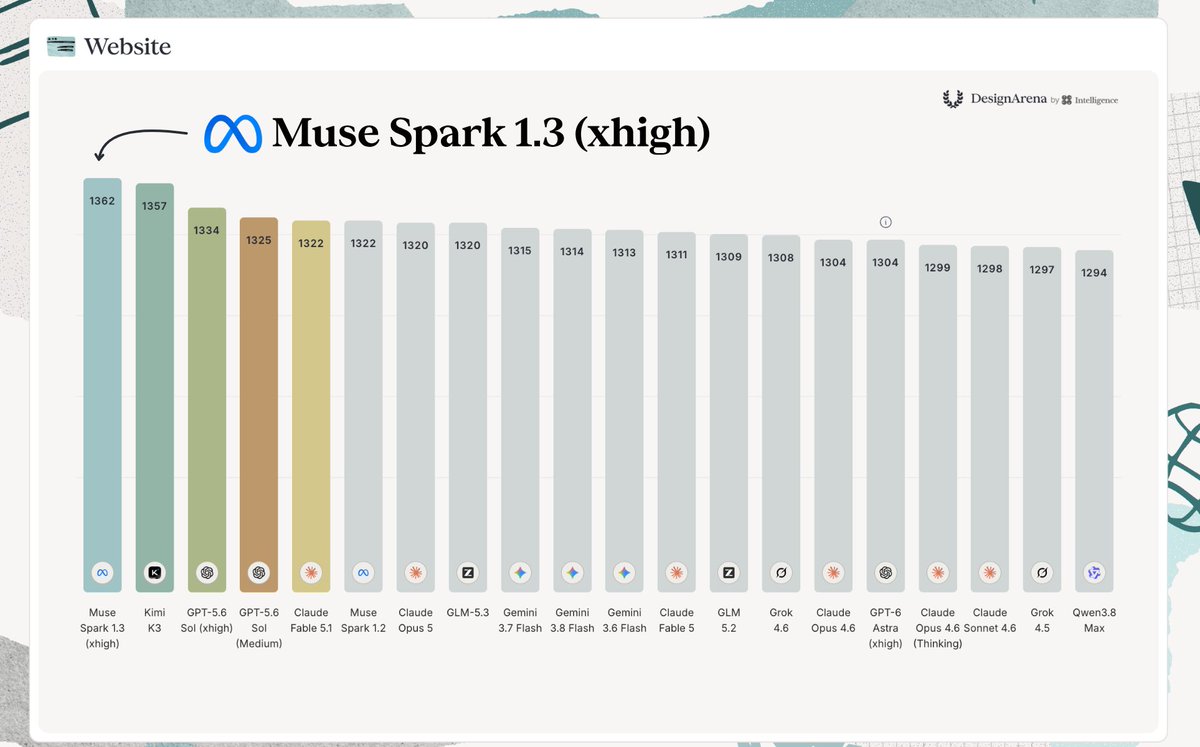
BREAKING: Muse Spark 1.3 (xhigh) takes 1st overall on Website Arena with an Elo of 1362! This is a jump of 5 positions from Muse Spark 1.2, establishing a new Pareto frontier for Speed and Price. Only a month after the release of Muse Spark 1.2, @AIatMeta has topped this

X post · Benchmarks & research★ Pick· ♥ 864

Spark 1.3 tops Website Arena

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

elie

@eliebakouch

extremely exciting to see meta getting back into open weight models with a 30B dense first, and soon muse spark 1.2 they used knowledge distillation from muse spark, architecture wise it's similar to gemma 4 (which is llama 3 + swa (again!) + vision encoder), with scale free QK

X post · Benchmarks & research· ♥ 464

Glimmer architecture teardown

AI at Meta

@AIatMeta

To understand whether we're making genuine progress on reasoning, we entered our AI models in five STEM Olympiad competitions. The results: 🏅 Asian Physics Olympiad (APhO): Perfect score, theory exam 🏅 International Physics Olympiad (IPhO): Perfect score, theory exam 🥇 ht

X post · Benchmarks & research★ Pick· ♥ 1.3K

Muse models take five STEM Olympiads

Dan

@DanDr1s

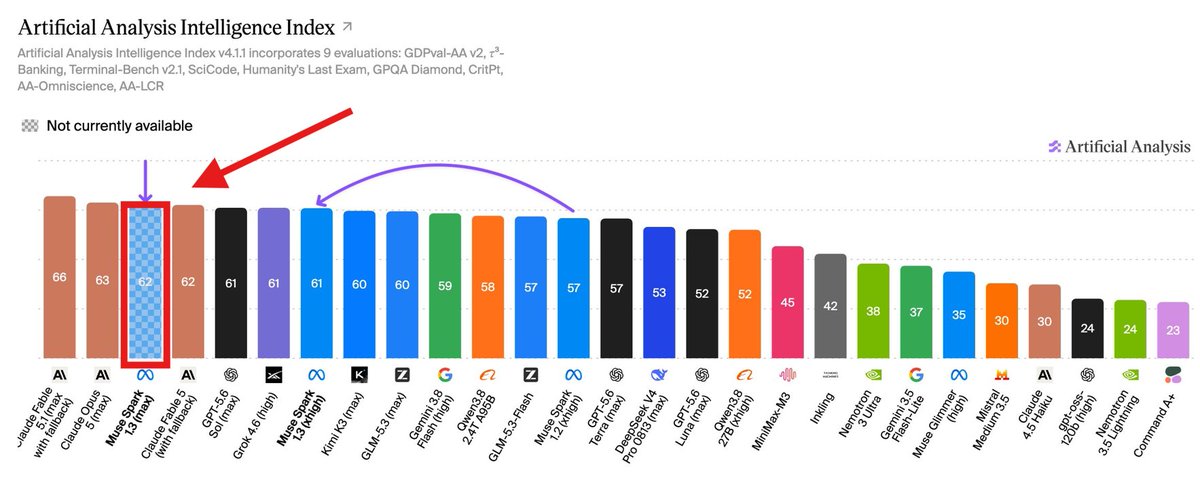
Meta’s Muse Spark 1.3 just scored 62 on Artificial Analysis’ Intelligence Index. That ties Claude Fable 5, but Muse costs 8x less for input and nearly 12x less for output. It also scores above GPT-5.6 Sol, Grok 4.6, Kimi K3, and Gemini 3.8 Flash. Meta is suddenly in the top

X post · Benchmarks & research· ♥ 223

Spark 1.3 matches Fable 5 at a fraction of the price

John Yang

@jyangballin

My favorite demo from the launch: muse spark 1.1 + opencode runs evaluation of *itself* + mini-SWE-agent (by @KLieret, @closji, urs truly) on DeepSWE!

X post · Benchmarks & research· ♥ 40

Muse Spark 1.1 evaluates itself on DeepSWE

Paweł Huryn

@PawelHuryn

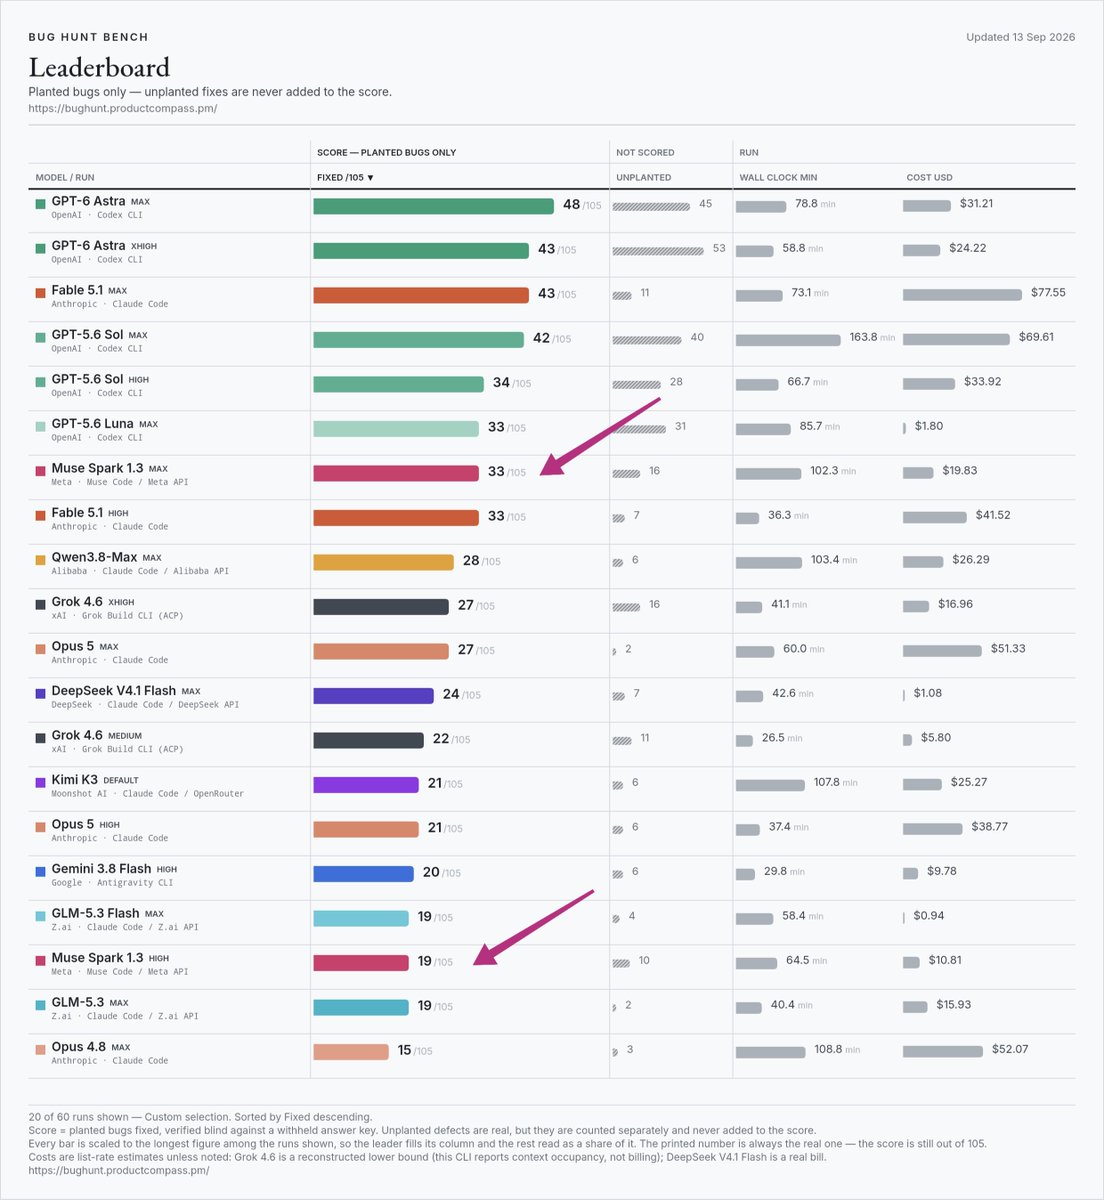
So, I finally tested Muse Spark 1.3. 2 real repos, 105 planted bugs, find and fix what you can. Original harness and API. Big surprise: Muse Spark 1.3 (max): 33 Fable 5.1 (high): 33 Grok 4.6 (xhigh): 27 Opus 5 (max): 27 Muse Spark 1.3 (high): 19 Meta joined the frontier.

X post · Benchmarks & research★ Pick· ♥ 694

105 planted bugs: Spark 1.3 vs frontier

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Alex Volkov

@altryne

Here's my full in depth review of @muse (muse.ai) Meta's new FREE AI agent with it's own browser, computer and connectors to anything from FB marketplace to Apple health! I go into setting it up, have it buy stuff securely with @link, and 3 great usecases that

X post · Benchmarks & research· ♥ 77

Hands-on Muse review with Link purchases

🚨 AI News | TestingCatalog

@testingcatalog

Since the Meta Muse agent isn't available to everyone, here is a quick UI walkthrough of its web version. Highlights 👀 > The animated Muse avatar is very cool! You can ask Muse to change how it looks, and it will generate the new look along with all the animations. >

X post · Benchmarks & research· ♥ 289

Muse web UI walkthrough

li yin

@panda_liyin

muse spark 1.1 in AdaL Engineer beats Opus4.8 in Claude Code with 20% of the cost loop engineering, when done right, is beyond just running longer, its delivering better results when contexts are managed well and when workers are better prompted to stay honest. how GANs had

X post · Benchmarks & research· ♥ 75

Spark 1.1 in AdaL Engineer vs Opus 4.8

Derya Unutmaz, MD

@DeryaTR_

Here is a crazy Jev @typesafeai example that I’m betting nobody has thought about: I asked @Muse from @Meta to use Jev to select the top 100 unanswered questions in immunology from 10,000 literature-grounded candidates. A few minutes later, it came back with some of the best

X post · Benchmarks & research· ♥ 427

Top 100 open immunology questions via Muse + Jev

Morgan

@morganlinton

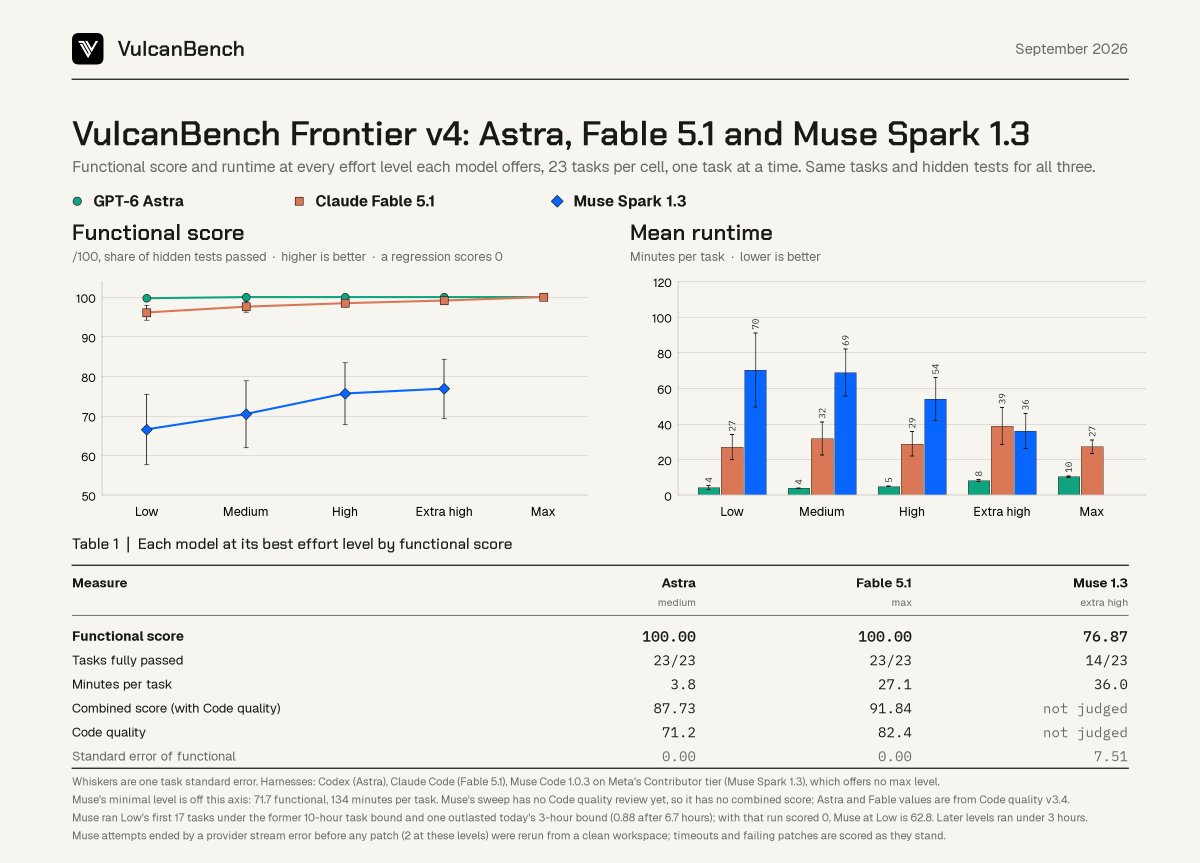
Okay, finally finished my Muse Spark 1.3 benchmark. This ended up being the longest-running benchmark I've ever done at @VulcanBench and it definitely looks like Muse has some serious issues at lower effort levels. I was able to run Astra through my v4 eval suite across every

+1

X post · Benchmarks & research· ♥ 99

VulcanBench run of Muse Spark 1.3

deeplearning.ai

deeplearning.ai

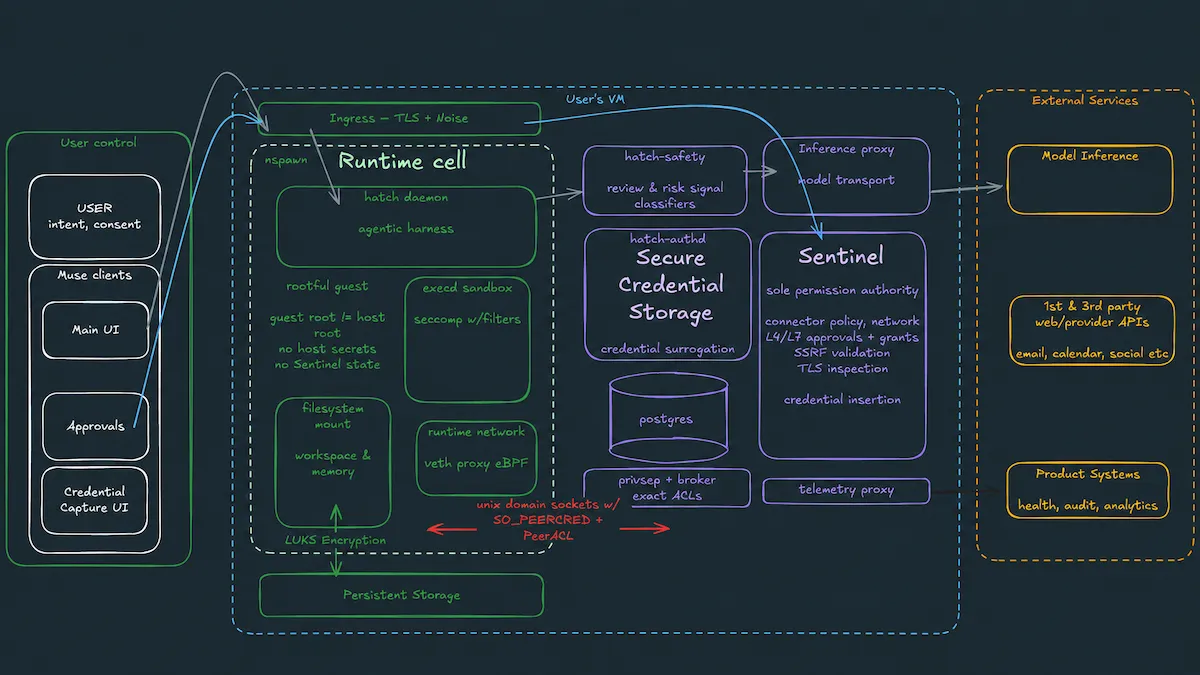
DeepLearning.AI's The Batch covers Muse's security design (isolated VMs, the Sentinel credential layer, prompt-injection classifiers) and its free tier of up to 100M tokens a week.

Resource · Benchmarks & research

How to secure agents for the masses (The Batch)

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

U

myanimal22

u/myanimal22

Muse Glimmer 30B feels significantly more precise and reliable, it almost never drops the ball or breaks rules. However, its designs lack creative depth and richness. Qwen3.6 35B, on the other hand, is prone to more occasional blunders/hallucinations, but its creative output is superior. It generates far richer, more complex voxel worlds and offers higher design quality. LLama.ccp Build Provenance: • Base: llama.cpp upstream (merge 4445f8d, build 661) • CUDA Toolkit 13.1 + MSVC 19.44 + sm_120a-real (native Blackwell PTX) • Flags: GGML_CUDA=ON, GGML_CUDA_FA=ON, GGML_CUDA_FA_ALL_QUANTS=ON, GGML_CUDA_GRAPHS=ON, GGML_NATIVE=OFF • License: MIT (upstream llama.cpp) Do you think Qwen3.6 is still the undisputed king here?

Reddit post · Benchmarks & research

Voxel worlds: Glimmer 30B vs Qwen3.6 35B

139 builds · page 1 of 4

About this shelf

This shelf gathers 139 scores, comparisons and research notes. Independent leaderboards come first. Artificial Analysis has scored every Muse Spark release on its Intelligence Index, putting 1.3 at 62. Arena ranked Muse Image #2 in its Image Arena, Design Arena put Spark 1.3 at #1 on Website Arena, and Vals AI placed Spark 1.2 in its Vals Index top 5.

Then there are hands-on tests. AICodeKing's KingBench 3 pits Muse Spark 1.3 against Gemini 3.8 Flash and flags file-overwriting issues. Matt Johnston's blind coding gauntlet found a strong Halo build but broken XCOM and Diablo attempts. thehype had Muse Code and three rivals build landing pages and fix their own bugs in a real browser.

The research side covers how the models are made. Sebastian Raschka and elie broke down Muse Glimmer's Gemma-like architecture, and another post notes it was logit-distilled directly from Muse Spark. Meta's own benchmark claims are labeled as Meta's, and third-party numbers link to the people who ran them.

Frequently asked

+How good is Muse Spark 1.3 at coding?

Meta reports 75.4 on DeepSWE v1.1 and 88.8 on Terminal-Bench 2.1. Independent tests on this shelf are more mixed: DataCamp measured a cost increase on its tasks, and some coding gauntlets found failures on complex builds.
+Where does Muse Spark rank on Artificial Analysis?

Artificial Analysis scored Muse Spark 1.3 (max) at 62 on its Intelligence Index, behind Claude Fable 5.1 and Claude Opus 5. Earlier releases scored 52 for the original, 51 for 1.1 and 54 for 1.2.

+How does Muse Glimmer compare with Qwen?

Most comparisons here find Glimmer somewhat behind Qwen 3.6 27B on raw scores but using far fewer tokens. One Reddit analysis of Artificial Analysis data puts it at 92% of Qwen3.6 27B's index score with 2.9x fewer tokens.

Want more AI builds?artificialbuilds.com