Curated with by@mohithkumar808

Catalog / Use case

Benchmarks & research

139 benchmark results and research notes on Muse Spark and Muse Glimmer: arena rankings, index scores, head-to-head tests and architecture teardowns.

U

Certain-Cod-1404

u/Certain-Cod-1404

Just downloaded the model, UD-Q5_K_XL quant, asked it to generate a long story to test out reasoning and speed with dflash (super fast btw, ~ 90 to 160 tok/s on a 5090 depending on task) and was surprised at the reasoning traces, they are so unlike anything i've seen recently either in gemma 4, qwen 3.5/ 3.6 or laguna, where as these models to like plan stuff out, and have organized thoughts / plans (granted like half the time they just loop and get lost either way) this model's reasoning is like if a gold fish was suddenly granted speech or something, the reasoning is so disorganized, repetitive, using we for some reason? and bringing up policy and safety twice me : write a long story model : write a long story User wants a long story. We can comply. No constraints. Probably provide a long story. Might ask genre? Could just write a long story. Probably provide a story. Maybe ask what kind? The prompt is just write a long story. We can generate a long story. Probably a few paragraphs. Long story could be lengthy. Provide maybe ~1000 words? Could be long. Maybe give a story with decent length. We should not ask clarifying? Could just produce. Probably safe to produce a story.

Reddit post · Benchmarks & research

How Glimmer's reasoning traces differ

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@tanishq-dubey

@tanishq-dubey

A reproducible Apple Silicon harness that runs six fixed quality tasks against MLX quantizations of Muse Glimmer 30B and records scores, tokens per second, peak memory and load time.

GitHub · Benchmarks & research

Muse Glimmer 30B MLX benchmark harness

@cneuralnetwork

@cneuralnetwork

smol-muse-glimmer scales Muse Glimmer's language backbone down to a 51M-parameter model and trains it on TinyStories, reaching validation cross-entropy of 1.8127 at step 5,000.

GitHub · Benchmarks & research

smol-muse: 51M Muse Glimmer architecture study

@ND-DAC-DOME

@ND-DAC-DOME

A test bed comparing Muse-Glimmer-30B against Qwen3.6-27B and Qwen3.8-27B under identical settings; with 32k-token budgets the three were about even (MMLU-Pro 82/82/80%).

GitHub · Benchmarks & research

Local LLM benchmark: Glimmer vs Qwen

M

@MetaDevelopers

@MetaDevelopers

Meta Developers session on what Muse Spark's act-on-perception multimodality unlocks across code, physical action and video workflows, plus Muse Voice Transcribe.

Video · Benchmarks & research· ♥ 1

Meta Connect: the multimodal intelligence of Muse Spark

Artificial Analysis

@ArtificialAnlys

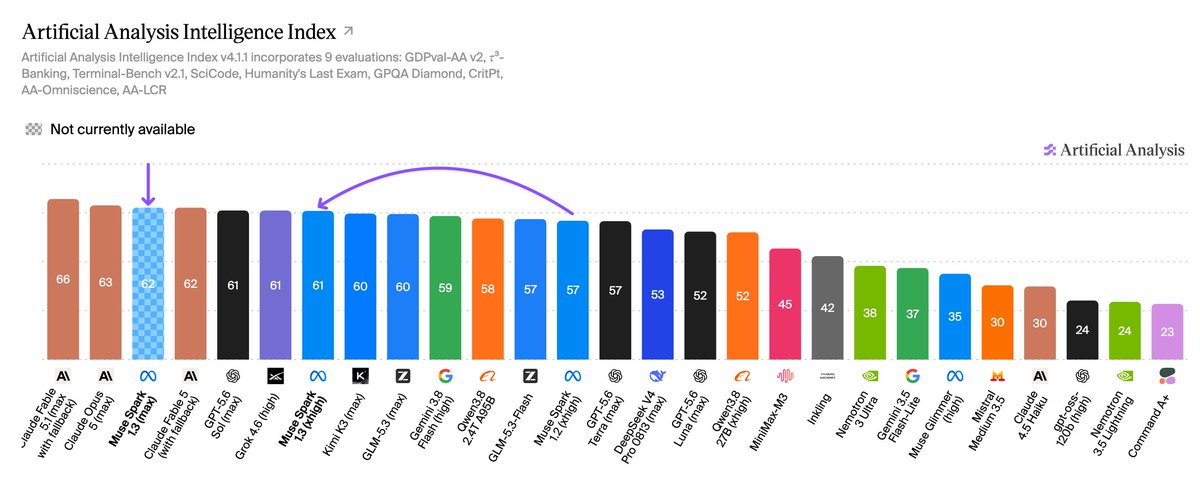
Meta has released Muse Spark 1.3, their fourth Muse Spark model release in five months. Muse Spark 1.3 (max), which is in limited preview for Meta’s partners, scores 62 on the Artificial Analysis Intelligence Index, behind only Claude Fable 5.1 and Claude Opus 5. The variant

X post · Benchmarks & research★ Pick· ♥ 2.6K

Artificial Analysis scores Muse Spark 1.3

Alexandr Wang

@alexandr_wang

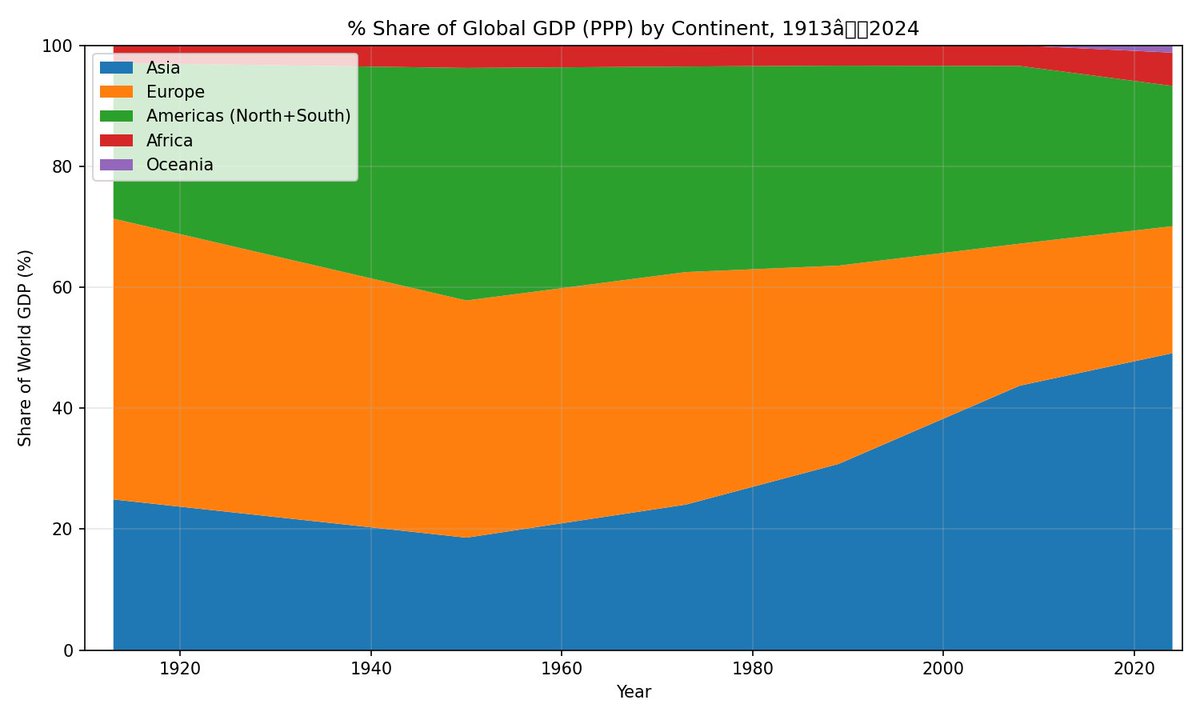
i find muse spark is very good at data analysis—both finding relevant open-source data and analyzing it. for example, here's my results for analyzing global share of GDP over past century: meta.ai/share/cw54skLB…

X post · Benchmarks & research★ Pick· ♥ 591

Century of global GDP share analysis

@rickyzzzzz

@rickyzzzzz

A controlled local benchmark on an M1 Max comparing Muse Glimmer 30B with Qwen 3.6 35B and Qwen 3.8 27B on tool calling and data-science tasks; Glimmer passed 24/30 versus Qwen 3.8's 30/30.

GitHub · Benchmarks & research

Muse Glimmer vs Qwen local agent benchmark

W

@webdoze

@webdoze

WEBdoze has Gemini 3.8 Flash and Muse Spark 1.3 each build a multi-page Astro site with custom SVGs, comparing code organization, speed, visuals and browser self-verification.

U

tacticaltweaker

u/tacticaltweaker

I'm just using OpenWebUI with a simple FastMCP server. Every other model I've tried will simply run a few lines of Python and give me the result. Glimmer seems to overthink like crazy to the point of being useless. On the carwash test it tried to compute emissions using Python. I'm using the recommended sampling parameters, default template, and I've tried both unsloth's Q6_K_XL and Meta's dynamic GGUFs. Any ideas? EDIT: It seems like it's definitely related to the tools available. With them disabled, it's reasonably efficient. I guess it's just overly eager to call every tool it can unlike Qwen or Gemma in my experience.

Reddit post · Benchmarks & research

Glimmer over-eager with MCP tools

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

malwarebytes.com

malwarebytes.com

Malwarebytes reports Patrick Wardle's finding that a local app can change an undocumented Muse setting to redirect dictation traffic, exposing voice prompts and account auth tokens.

Resource · Benchmarks & research

Muse zero-day can turn it into a Mac backdoor

@chishiki37

@chishiki37

Benchmark reports on Muse-Glimmer-30B on NVIDIA DGX Spark covering BF16 to Q4 to DFlash (a 10x speedup) and NVFP4 via SGLang, plus a head-to-head against Qwen3.6-27B.

GitHub · Benchmarks & research

Muse Glimmer optimization reports on DGX Spark

@mahdi-salmanzade

@mahdi-salmanzade

A static teardown of Muse 3.0 for macOS plus Android and iOS builds, documenting shipped tools for iMessage, WhatsApp, Mail, screen control, background sync and a bundled Chrome extension.

GitHub · Benchmarks & research

Privacy teardown of the Muse apps

U

Cradawx

u/Cradawx

LLMs have become extremely good at coding, maths etc, but how well do they do at playing a simple dungeon/maze game that even a child can solve easily? The LLM has to navigate a 10x10 grid map, completing objectives in the right order (collect weapon > kill monster > head to exit) while navigating the dungeon and avoiding walls. Three illegal moves fail the run. All models are tested with reasoning enabled. The code and more info on my GitHub if you want try it yourself: https://github.com/shinomakoi/dungeon-bench Model leaderboard: Model Score DeepSeek-V4-Pro (high) 🥇12/12 Gemma-4-31B-it 🥈11/12 Qwen-3.8-27B (medium) 🥈11/12 GLM-5.3-Flash (high) 🥈11/12 Muse-Glimmer-30B (medium) 🥉10/12 DeepSeek-V4-Flash (high) 🥉10/12 Granite 4.2 (full) 8/12 KAT-Coder-V2.5-Dev 8/12 Nemotron-3.5-Lightning-30B-A3B 5/12 Model Illegal moves DeepSeek-V4-Pro (high) 🥇0 Gemma-4-31B-it 🥈1 Qwen-3.8-27B (medium) 🥈1 Muse-Glimmer-30B (medium) 🥉2 Granite 4.2 (full) 🥉2 Nemotron-3.5-Lightning-30B-A3B 7 GLM-5.3-Flash (high) 8 KAT-Coder-V2.5-Dev 10 DeepSeek-V4-Flash (high) 12 DeepSeek-V4-Pro: By far the best result. Basically perfect performance in all maps.

Reddit post · Benchmarks & research

DungeonBench: LLMs navigating a grid dungeon

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Trapit Bansal

@TrapitBansal

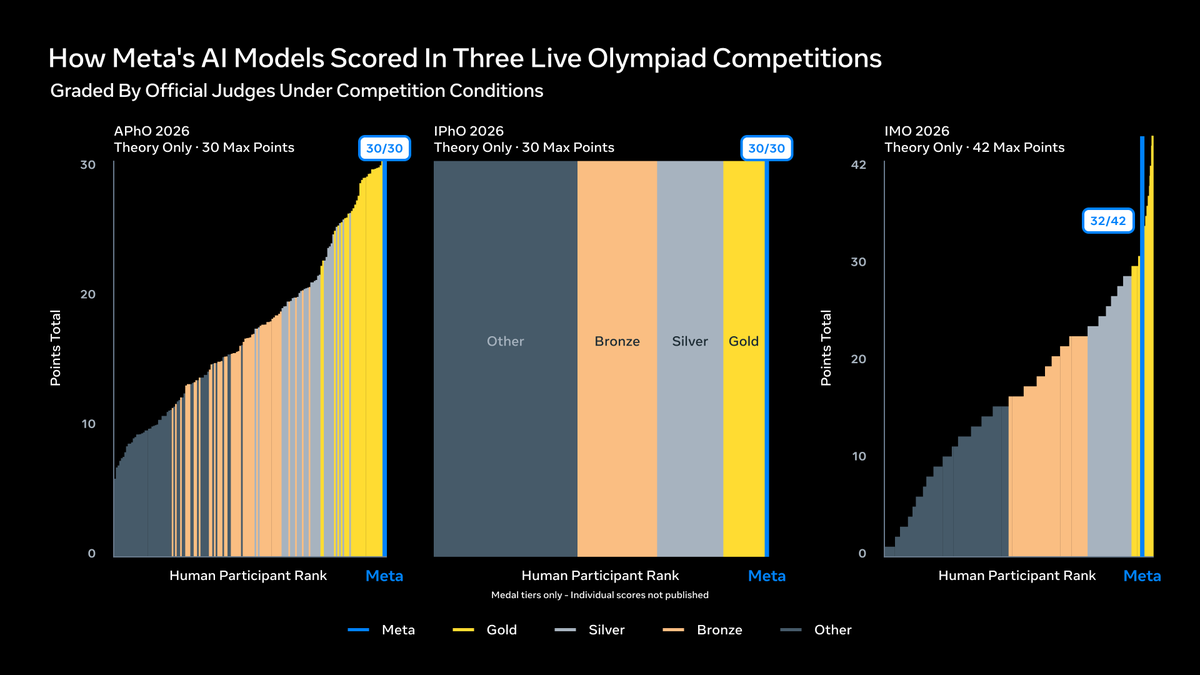
We entered Meta models in five international STEM Olympiads, as an uncontaminated eval of their reasoning capabilities. Three of these were live participations and graded officially. The models achieved gold-medal results in all five! 1/5

X post · Benchmarks & research· ♥ 219

Olympiad golds as an uncontaminated eval

A

@AICodeKing

@AICodeKing

AICodeKing tests Muse Spark 1.3 and Gemini 3.8 Flash on frontend, 3D, SVG, maths and agentic coding, and flags file-overwriting issues.

Video · Benchmarks & research· ♥ 220

KingBench 3: Muse Spark 1.3 vs Gemini 3.8 Flash

artificialanalysis.ai

artificialanalysis.ai

Artificial Analysis puts Muse Spark 1.1 at 51 on its Intelligence Index, 8 points above 1.0, and calls it cost and token efficient versus peers.

Resource · Benchmarks & research

Artificial Analysis: Muse Spark 1.1 scores 51

trycodus.com

trycodus.com

Codus reads the three benchmark charts Meta published for Muse Code and notes Claude Opus 5 wins all three, including Meta's own internal eval.

Resource · Benchmarks & research

What Meta's Muse Code benchmarks actually say

research.meta.ai

research.meta.ai

Meta's engineering write-up on Muse security: isolated VMs, a separate Sentinel permission authority, credential surrogation and layered prompt-injection defenses, with bug bounties up to $300,000.

Resource · Benchmarks & research★ Pick

How Meta built safety into Muse

Arena.ai

@arena

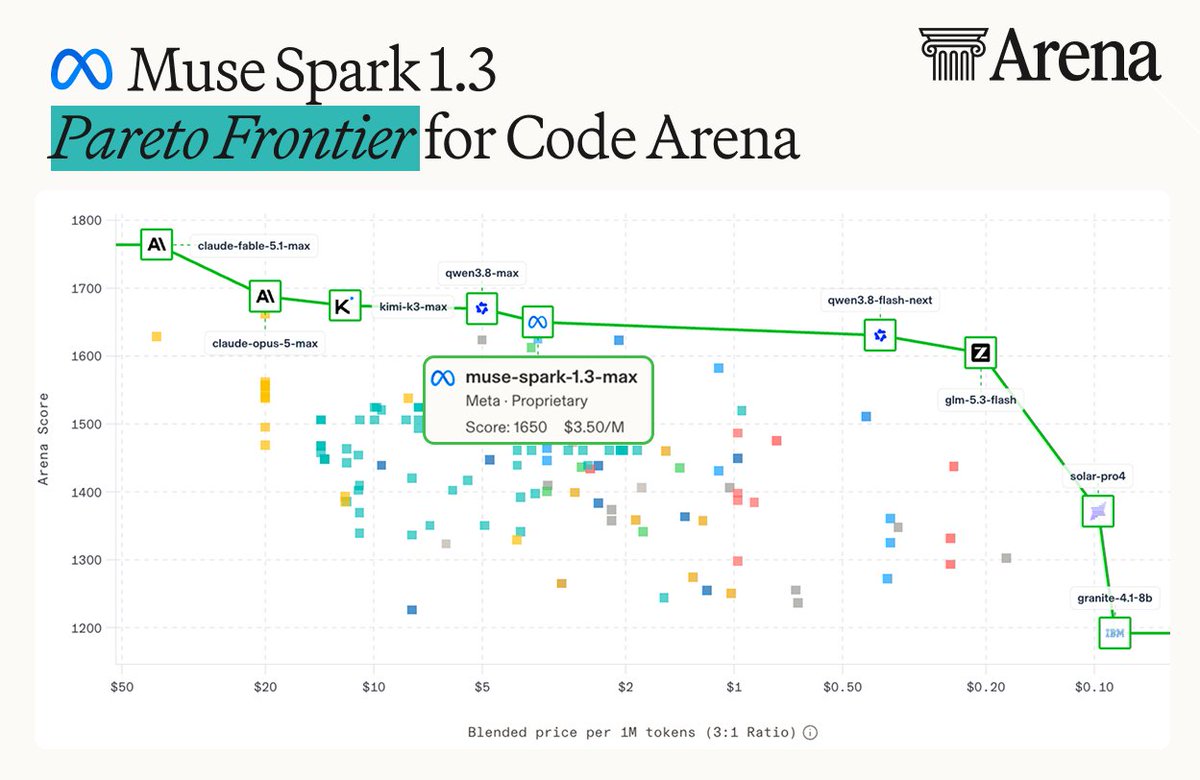
Muse Spark 1.3 Max by @AIatMeta has reshaped the Pareto frontier for Code Arena: WebDev! Meta's latest model at Max reasoning is doing something interesting on the Arena Pareto frontier: it's the only model holding down the wide price band between Qwen3.8-max ($5/MToken) and

X post · Benchmarks & research· ♥ 334

Spark 1.3 Max on the WebDev Pareto frontier

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

runtimewire.com

runtimewire.com

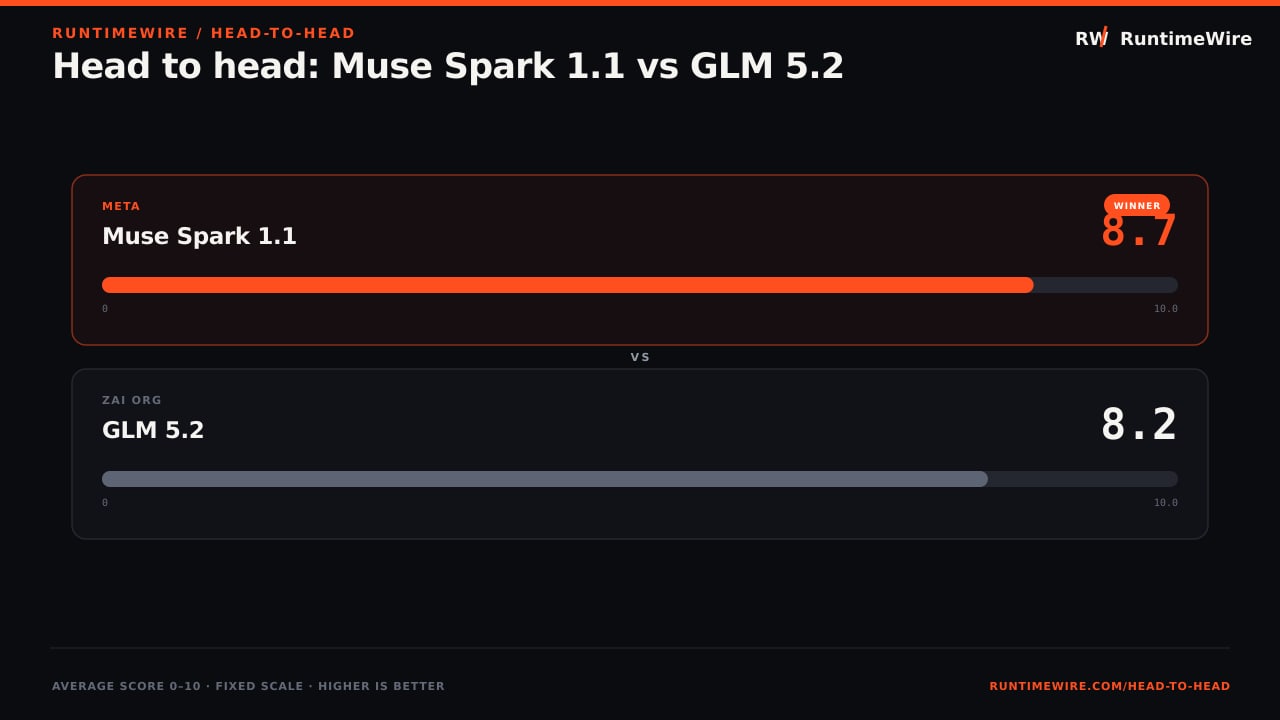
RuntimeWire finds Muse Spark 1.1 ahead of GLM 5.2 on harder, failure-prone tasks, with GLM the tidier formatter in spots.

Resource · Benchmarks & research

Head to head: Muse Spark 1.1 vs GLM 5.2

Artificial Analysis

@ArtificialAnlys

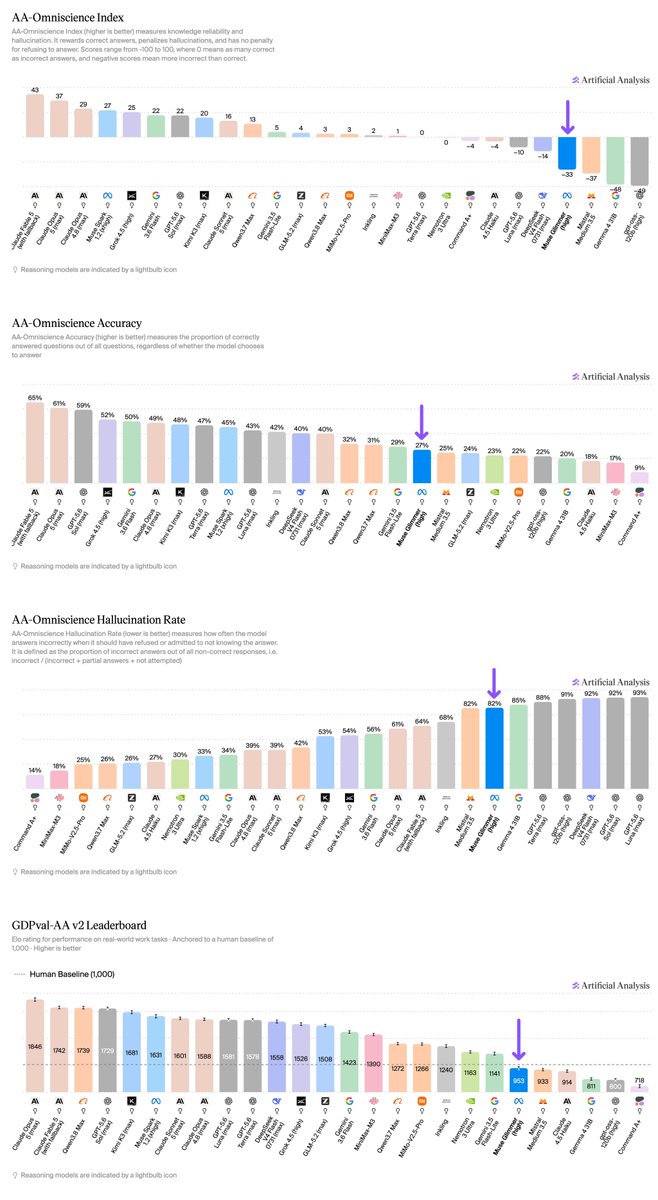
Muse Glimmer's gaps against its class concentrate in agentic evaluations: 953 Elo on GDPval-AA v2 against 1141 for Qwen3.6 27B (Reasoning), 1141 for Gemini 3.5 Flash-Lite, and 1004 for Kimi K2.5 (Reasoning), with Terminal-Bench v2.1 (52%) also behind Qwen3.6 27B (61%). The

X post · Benchmarks & research· ♥ 34

Where Glimmer trails on agentic evals

@wonder-soft

@wonder-soft

A benchmark that tests whether Muse Glimmer 30B on a single RTX 5090 works as an OpenCode backend, using the same tasks as earlier DeepSeek and Qwen runs; first results show 18/18 episodes with zero malformed tool calls.

GitHub · Benchmarks & research

Muse Glimmer as an OpenCode backend

U

WonderRico

u/WonderRico

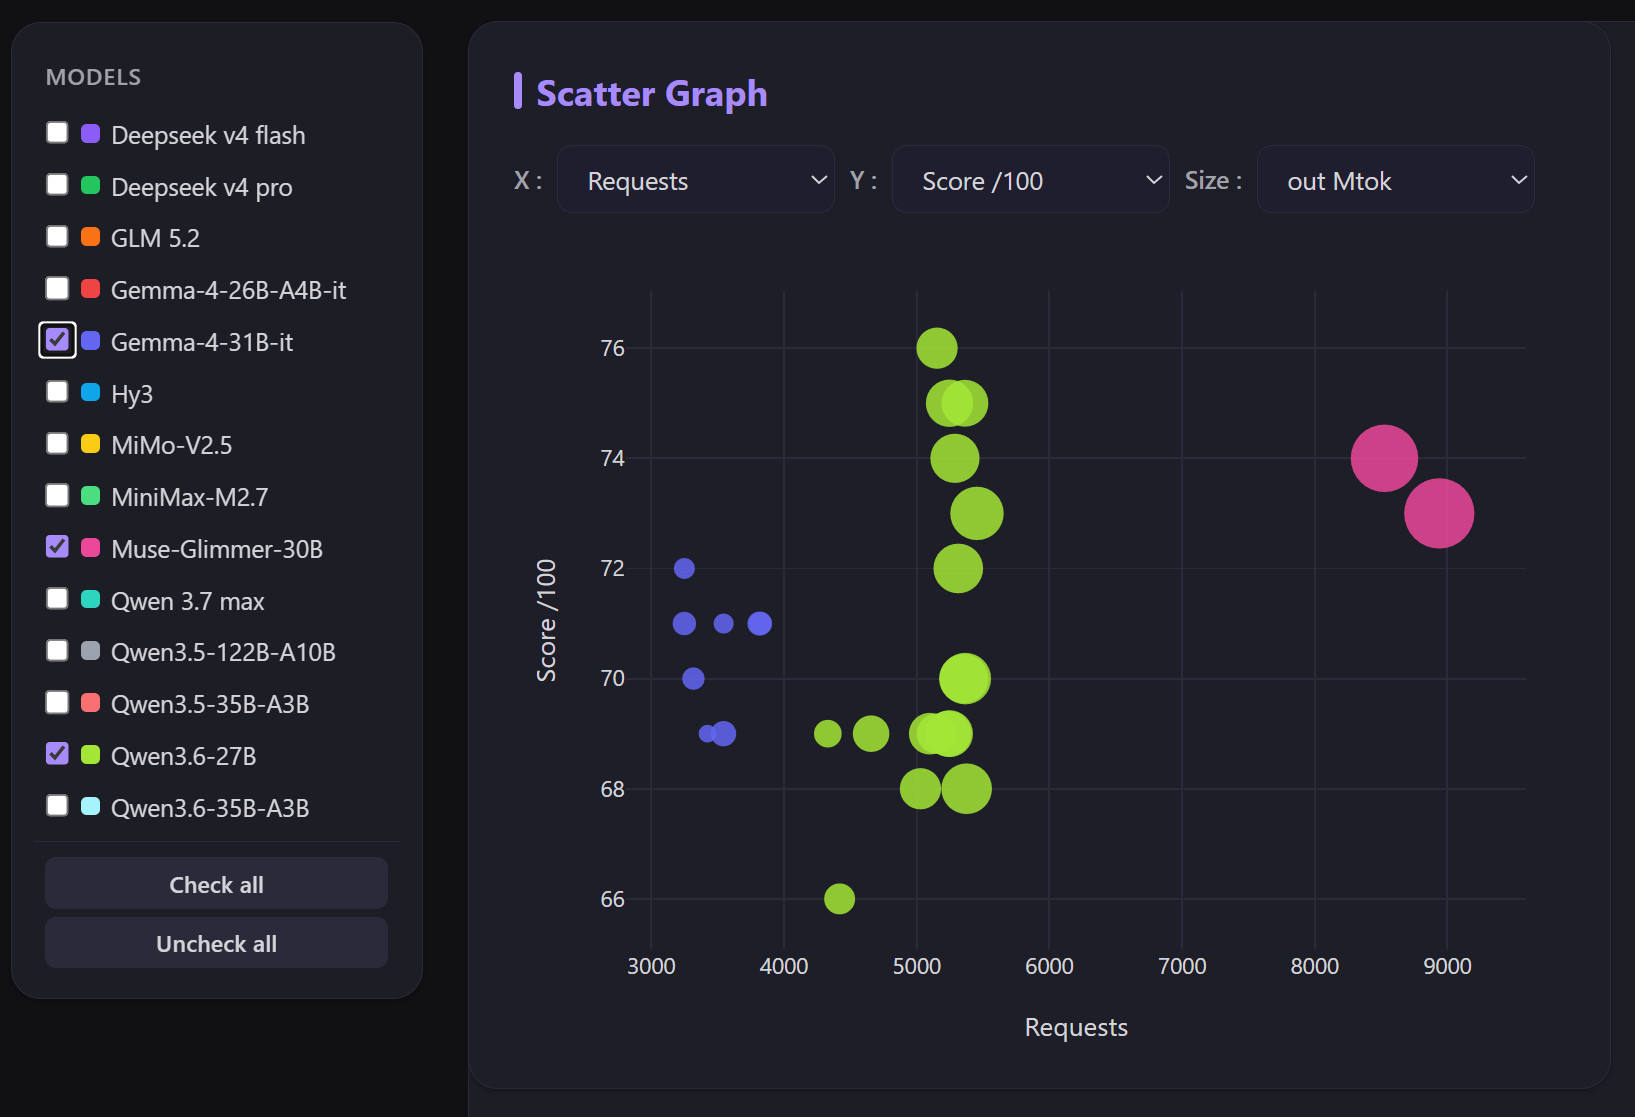
Needs a lot of requests compared to Qwen (almost twice) and Gemma (almost x3). Final score is fine, even though it is "not a coding model" https://wonderrico.github.io/local_llm_benchmark/benchmark-main.html more details on https://wonderrico.github.io/local_llm_benchmark/benchmark-detail.html let see Qwen 3.8 tomorrow...

Reddit post · Benchmarks & research

Local coding benchmark: Glimmer vs Qwen vs Gemma

U

flaneur451

u/flaneur451

# Hidden Capabilities — Deep Self-Scan Findings Live run: **September 23, 2026, ~08:00–08:30 UTC**, ~90 minutes, all probes benign and reversible. Verdict key: - **CONFIRMED** — exposed tool schema, successful benign probe, or exact internal documentation. - **PUBLICLY DOCUMENTED** — found in official external sources. - **ABSENT FROM PUBLIC SOURCES** — searched; no credible public mention found. - **UNVERIFIED POSSIBILITY** — inferred from filenames, gating manifests, or incomplete chatter only. --- ## 1. CONFIRMED — hidden / non-obvious (schema, probe, or internal docs) ### Phone & wearable superpowers (confirmed via `device.describe`) - **Full HomeKit control**: list homes/rooms/zones/accessories/scenes; read/change accessory characteristics; run scenes; ordered choreographies; concurrent virtual scenes; security sweeps (locks, contact/motion/leak sensors); geofence-triggered HomeKit actions. — **ABSENT FROM PUBLIC SOURCES** (official docs say only "smart-home devices"; Patrick Wardle's Sept 21 security demo is the only external mention of smart-home commands). - **Persistent/one-time geofences** with arrival/departure triggers. — **ABSENT FROM PUBLIC SOURCES**. - **

Reddit post · Benchmarks & research
Muse agent hidden capabilities: a 90-minute self-scan

khaled

@eltokh7

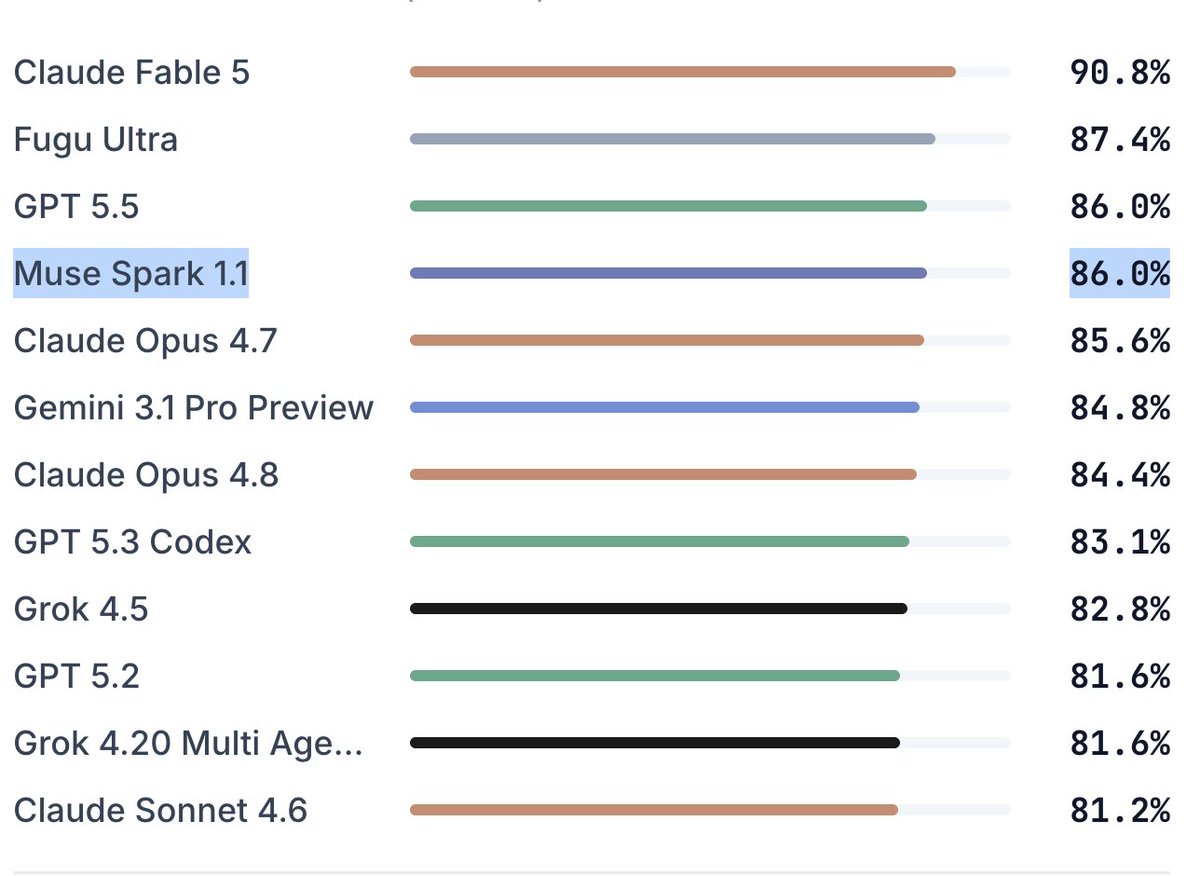
Muse Spark 1.1 seems like a very good model. I tested it on Stata Benchmark and it ranks 4th (!) beating Opus 4.7/4.8, tied with GPT 5.5. I like this benchmark because it often catches seemingly good model performing poorly on OOD tasks

X post · Benchmarks & research· ♥ 17

Spark 1.1 ranks 4th on Stata Benchmark

simonwillison.net

simonwillison.net

Simon Willison notes Muse Spark 1.1 is the first Spark model with an API and that Meta claims big gains in agentic tool calling and computer use.

Resource · Benchmarks & research

Simon Willison on Muse Spark 1.1's API

Design Arena

@DesignArena

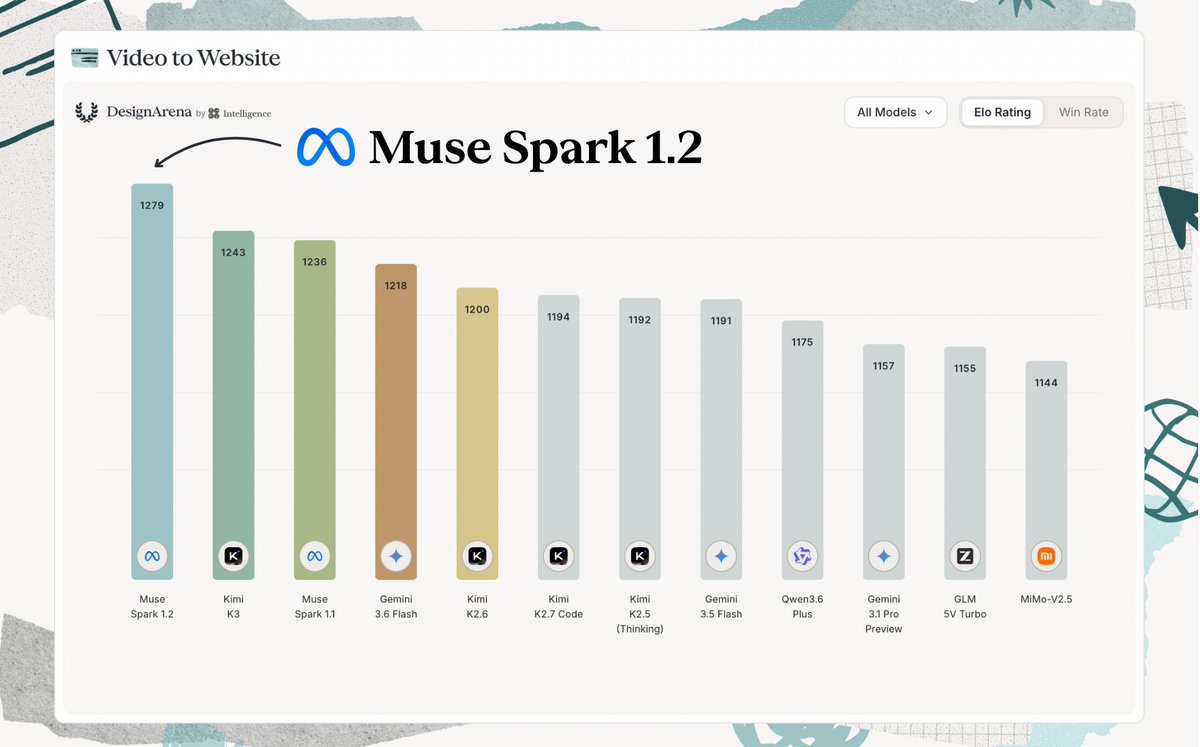
BREAKING: Muse Spark 1.2 by @AIatMeta takes 1st for Video-to-Website with an Elo rating of 1279 and impressive scores across all of our multimodal code categories. Muse Spark 1.2 also takes 2nd for Image-to-HTML with an Elo rating of 1252 and 3rd for Image-to-Frontend with Elo

+2

X post · Benchmarks & research· ♥ 254

Spark 1.2 wins Video-to-Website

U

mr_tolkien

u/mr_tolkien

I wanted a quick calories counter for myself, using LLMs to evaluate the calories from pictures of meals + descriptions. I needed to pick a model so I made a quick benchmark. The setup was: - Nutrition5k photos for photo + calories: https://github.com/google-research-datasets/Nutrition5k - A tool with access to calories information from USDA FoodData Central + MEXT - I evaluated models based on how many of the meals they managed to have under 20% of error - All on the same randomly picked 25 meals. Models too big for my machine were run through OpenCode Go/OpenRouter. I've also included Spark 1.3 since it'll supposedly be open weights. Results Model % within 20% Mean bias Median Error Qwen 3.8 27b 16% +64 kcal 148 kcal GLM 5.3 Flash 28% +18 kcal 65 kcal Qwen 3.8 Max 32% -11 kcal 48 kcal Muse Glimmer 30b 32% +25 kcal 92 kcal Qwen 3.8 Flash 36% +2 kcal 91 kcal DeepSeek v4 Flash Vision 40% +52 kcal 65 kcal Muse Spark 1.3 48% -24 kcal 45kcal I know it's not the most scientific benchmark, but it's interesting to see that the order is not really linked to model size. The most interesting for me is how Muse Glimmer 30b trounces Qwen 3.8 27b here. I think it hig

Reddit post · Benchmarks & research

Calorie-estimation benchmark: Glimmer vs Spark 1.3

runtimewire.com

runtimewire.com

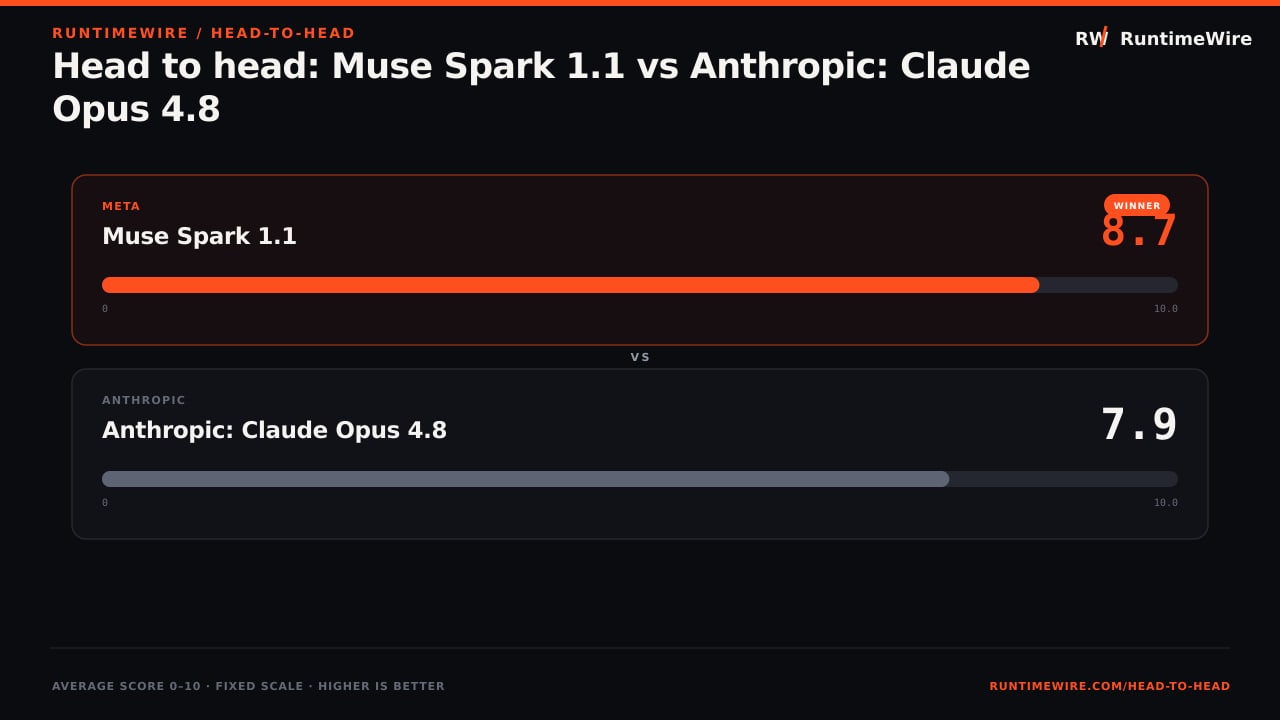
RuntimeWire's head-to-head eval has Muse Spark 1.1 beating Claude Opus 4.8 by 10 points overall with a 95% confidence verdict.

Resource · Benchmarks & research

Head to head: Muse Spark 1.1 vs Claude Opus 4.8

U

ag789

u/ag789

started trying out rather recent 'frontier' about ~30b param models recently, there are many choices including QWen 3.8 - this is nevertheless a great model, practically 'one-shotting' code refactoring tasks https://huggingface.co/Qwen/Qwen3.8-27B https://huggingface.co/unsloth/Qwen3.8-27B-GGUF code refactoring is still deemed 'difficult', practically 'infinite' permutations and dependencies which LLMs need to work through itself for code refactoring. But that in terms of style, I'm liking Muse Glimmer better https://research.meta.ai/blog/introducing-muse-glimmer-open-agentic-model https://huggingface.co/meta-models/Muse-Glimmer-30B https://huggingface.co/meta-models/Muse-Glimmer-30B-GGUF https://huggingface.co/unsloth/Muse-Glimmer-30B-GGUF this is in particular when it comes to *incorrect* (e.g. mistakes, typos) prompts, resolving contradictions in existing codes during refactoring, code proposals etc. The handling especially the 'thinking' is different. LLMs have 'styles' and it is great that we've different creators for them

Reddit post · Benchmarks & research
Muse Glimmer's style for code refactoring

rohanadwankar.github.io

rohanadwankar.github.io

Rohan Adwankar found Muse runs on Cloud Hypervisor microVMs with a 327 MB Rust harness that boots in ~40 s, an on-VM Postgres with 194 tables and 60+ privsep tool workers.

Resource · Benchmarks & research
A peek inside Meta's Muse VMs

139 builds · page 3 of 4

Want more AI builds?artificialbuilds.com