Curated with by@mohithkumar808

№ 0859GitHub

Local LLM benchmark: Glimmer vs Qwen

A test bed comparing Muse-Glimmer-30B against Qwen3.6-27B and Qwen3.8-27B under identical settings; with 32k-token budgets the three were about even (MMLU-Pro 82/82/80%).

nd-dac-dome/local-llm-benchmarkREADME ↗

Local LLM benchmark: Muse-Glimmer-30B vs Qwen3.6-27B vs Qwen3.8-27B

A small, auditable test bed for comparing locally served models under identical conditions: same questions, same prompts, same sampling, same token budget, with every prompt, reasoning trace, answer and verdict saved to disk.

Report site: https://nd-dac-dome.github.io/local-llm-benchmark/ — the findings, navigable, with a question explorer. The same content as text: results.md.

Findings in short

  • Given enough room to finish thinking (32k tokens per answer), the three models are equivalent: MMLU-Pro 82 / 82 / 80% (Muse / Qwen3.6 / Qwen3.8), GPQA Diamond 80 vs 80% (Muse vs Qwen3.8).
  • With a tighter budget (12k) Muse is ahead (MMLU-Pro 82% vs 73–77%), because the Qwens run out of tokens before answering, not because they reason worse. On LiveCodeBench Qwen3.8 does not finish 38% of the problems even at 32k (Muse 79%, Qwen3.8 60%).
  • The Qwens use 2–3× the tokens per answer to reach the same score. Which model is "better" depends on how long an answer may take in the intended use.
  • Quantization, speculative decoding (MTP / DFlash) and the machine (A6000 vs DGX Spark) do not change the scores; they change speed. Same model and recipe: 50.8 tok/s on the A6000, 20.3 on the Spark.

Datasets and grading: benchmarks.md. Vendor-published SWE-bench numbers (not reproduced here): swe-bench-cards.md.

Layout

File Purpose
bench.py The harness. Talks to any OpenAI-compatible endpoint (llama.cpp, vLLM, Ollama). Tasks: gsm8k, mmlu_pro, humaneval, gpqa_diamond, livecodebench, speed (decode tok/s, TTFT, prefill tok/s). Resumable; errors logged; aborts after 5 consecutive request errors.
compare.py Prints a markdown table across every run under results/, with margins of error.
rescore_humaneval.py, rescore_livecodebench.py Re-grade saved answers with the current scorer, without regenerating (used after scorer fixes; the LiveCodeBench one also grades under the judge environment).
run_all.sh Run 1 end to end: serve Muse then Qwen3.6 (GGUF, llama.cpp) and run all tasks.
speed_only.sh Re-measure only speed/prefill for an existing llama.cpp run, keeping its scores.
serve_vllm_nvfp4.sh Serve an NVFP4 checkpoint with vLLM on an A6000; parameterized by env vars (mod
Local LLM benchmark: Glimmer vs Qwen on github.com

Also filed under Benchmarks & research

See all →
  1. 0599

    Spark 1.3 tops Website Arena★

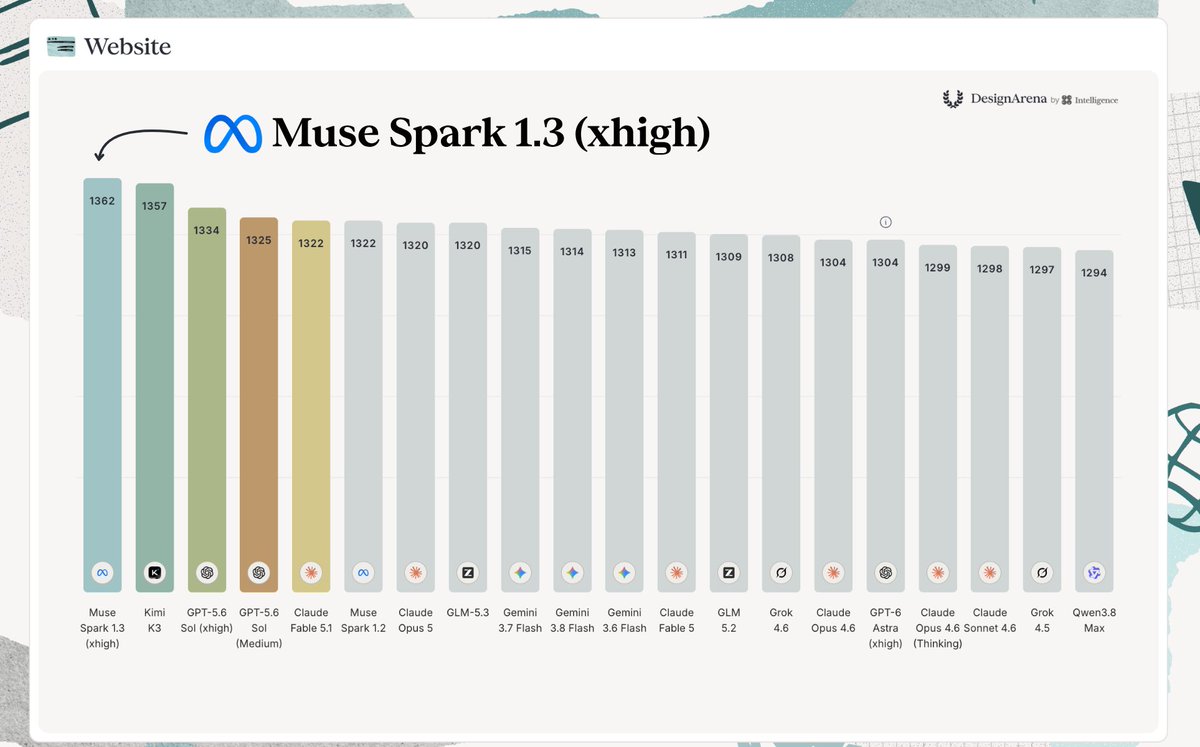
    BREAKING: Muse Spark 1.3 (xhigh) takes 1st overall on Website Arena with an Elo of 1362! This is a jump of 5 positions from Muse Spark 1.2, establishing a new Pareto frontier for Speed and Price. Only a month after the release of Muse Spark 1.2, @AIatMeta has topped this

    @DesignArena

    X post

    Benchmarks & research

  2. 0598

    Spark 1.3 moves the cost Pareto frontier★

    Last week the Intelligence Index vs Cost Pareto frontier moved out substantially. Claude Fable 5.1, Muse Spark 1.3, and GPT-6 Astra each set a new point in efficient intelligence Link to analysis: artificialanalysis.ai/#intelligence-…

    @ArtificialAnlys

    X post

    Benchmarks & research

  3. 0590

    Meta's OpenCode token share hits 45%★

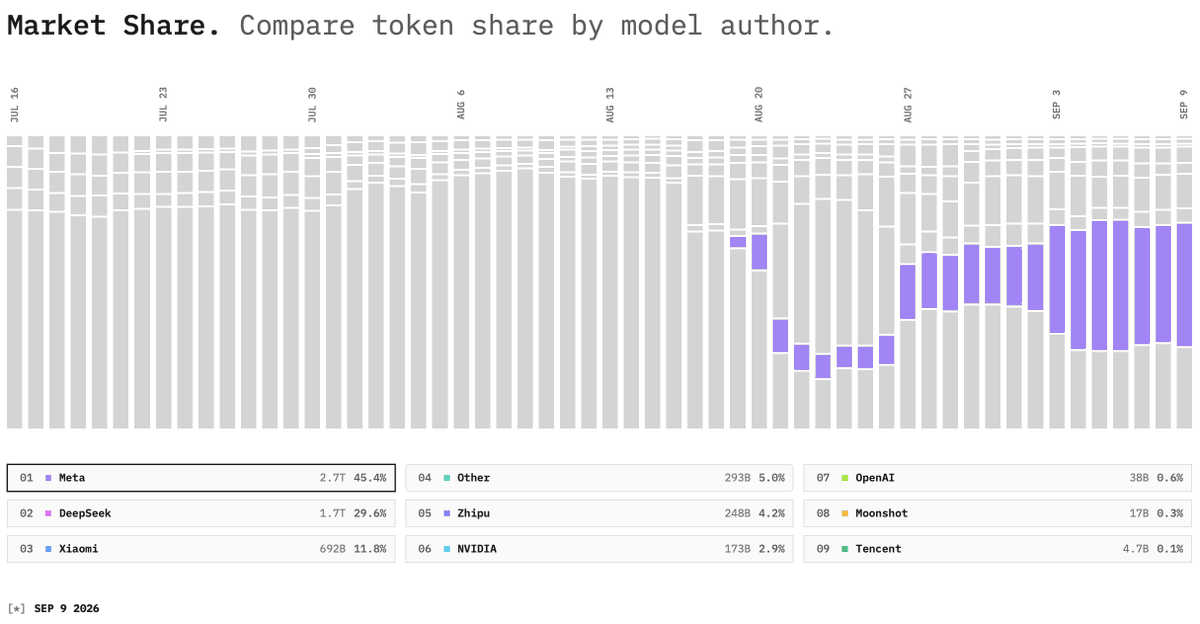
    $META just went from 3.5% to 45.4% token share on OpenCode in just over two weeks Muse Spark 1.3 being good + free is enough to become the default for most users Default gets you usage → usage gets you data → data makes the next model better Anthropic and OpenAI can’t afford

    @thetomcollins

    X post

    Benchmarks & research

  4. 0541

    Spark 1.3 in Code Arena: WebDev top 10★

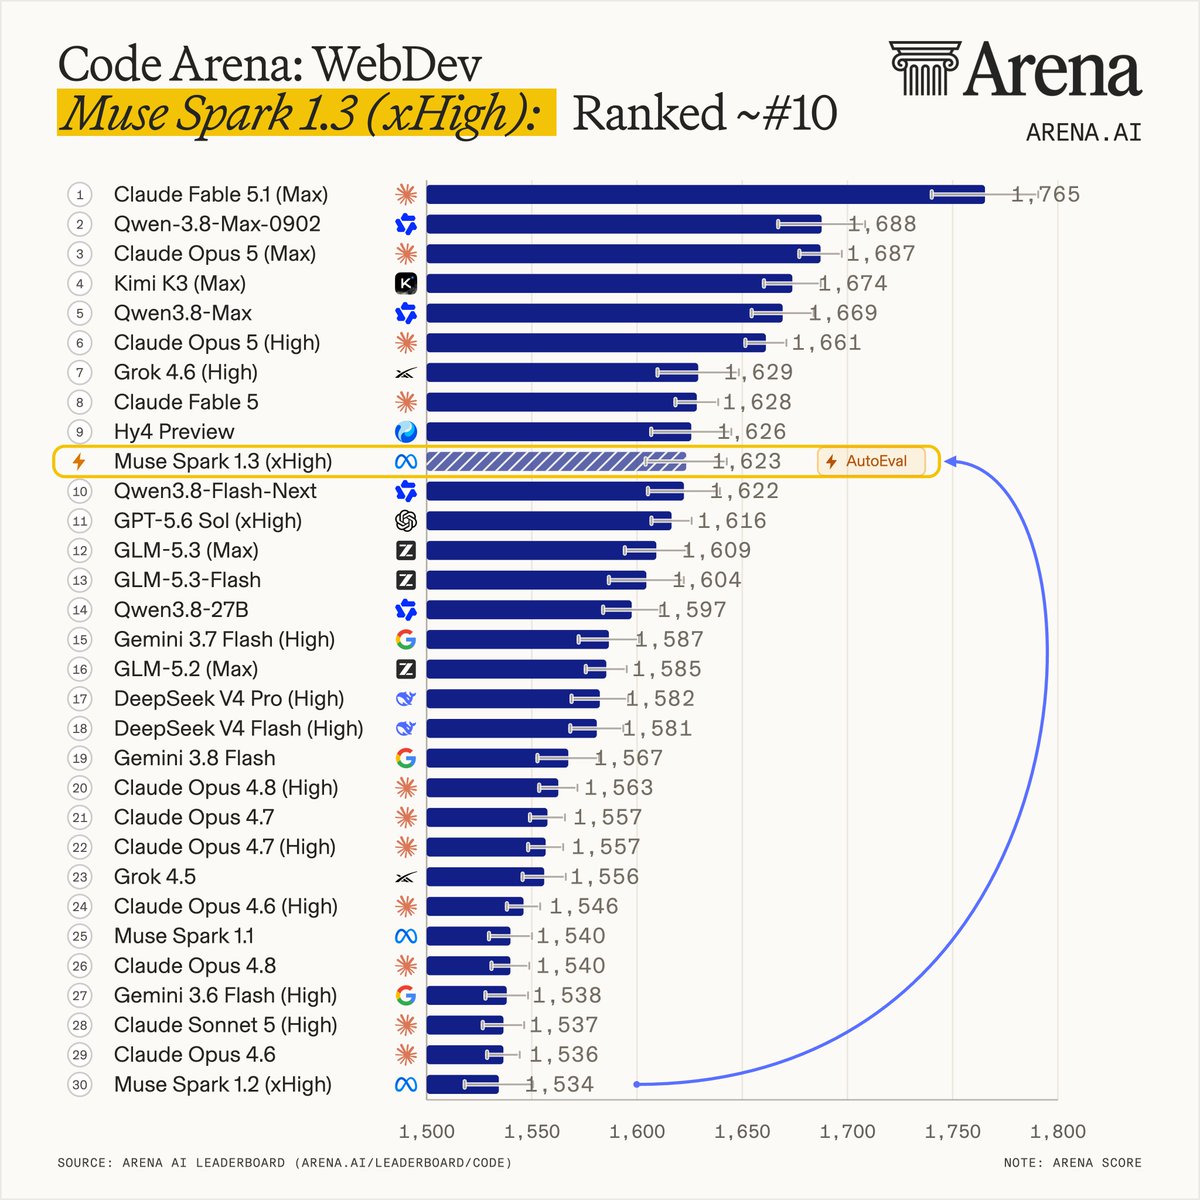
    Muse Spark 1.3 (xHigh) just landed @AIatMeta back in the top 10 models for Code Arena: WebDev! This release is ~#10 in Code Arena: WebDev with 1623 pts (AutoEval). It’s performance is par with Claude Fable 5 at #8 (1628 pts) and GPT-5.6 Sol at #11 (1616 pts). Muse Spark 1.3

    @arena

    X post

    Benchmarks & research

More GitHub

See all →
  1. 1091

    RedMuse

    Muse-native pentesting skill pack for Muse.ai. 13 skills, 4 scan modes (quick, standard, deep, diff), gate-first, localhost vulnerable app plus passive scans only, no active probes on live sites without a separate yes. Strix-inspired with original writing. Proven on localhost (IDOR, XSS, open redirect) and on live targets with anonymized totals: 0 critical, 2 high, 4 medium, 8 low, 14 info. MIT.

    Anonymous

    GitHub

    Coding & dev tools

  2. 1089

    Gig Driver Profit Checker — real delivery profit in minutes

    A working mobile-friendly web app built by the Meta Muse personal agent from a real courier's detailed requirements. It compares DoorDash/Uber Eats delivery offers after total miles (including empty return), waiting time, all-in vehicle costs and tolls. The surprising demo: a $9 offer can yield $19.08 net per hour while a $20 offer only yields $16.09 under stated assumptions. Muse created the standalone offline HTML and logic tests (49/49 self-reported); I downloaded it, independently verified actual browser inputs/outputs, published the source and proof screenshot to GitHub, and deployed a no-signup live demo. Live app: https://boyhoangxattpt2-blip.github.io/gig-driver-profit-checker/ . GitHub README includes exact math, source code, build story, and reproducible prompt.

    Anonymous

    GitHub

    Apps & websites

  3. 1087

    Zouroboros Workshop

    Muse is your personal assistant. Zouroboros Workshop is the workshop behind it. Workshop is an MCP service that runs on a private, single-tenant VPS provisioned for each customer. From a normal Muse conversation, a user can dispatch real software work to a coordinated team of seven AI coding executors — Claude Code, Codex, Gemini, OpenCode, Kimi, Hermes, and Pi — routed by health and capability, with automatic fallback when one executor is unavailable. Three things make it different from a single-vendor hosted builder. First, it runs on the subscriptions the user already pays for: there are no Workshop model credits and no second meter. Second, its memory is shared across every executor and survives across sessions, so a decision recorded by one tool is retrieved by another in a later Muse conversation — memory that compounds instead of resetting. Third, work is verified before it is delivered: builds run through a factory lane with deterministic review, and swarm results return with per-task evidence, not just an agent's claim that it is done. The customer-facing promise is simple: turn your existing AI tools into a workshop that delivers tested, reviewed work — a finished pull request, not a wall of code in chat.

    @Xmarlandoj

    GitHub

    Connectors & MCP

  4. 1086

    Self-Healing Agent VM

    A self-healing watchdog pattern for AI agent VMs: byte-exact restore caches in persistent storage, sentinel probes, no-clobber atomic restores, and verified heals. When the VM's root filesystem is rebuilt with pieces missing (Python stdlib, timezone data, Node), the watchdog restores them in minutes and reports only repairs and failures. Includes an AGENTS.md so any agent can set it up.

    @TMTrevisan

    GitHub

    Agents & automation

Curator picks

  1. 1057

    Muse Mail: your agent gets an email address★

    MUSE FEATURE ALERT: y'all have been asking for this one. your @muse is getting its own email address. add it to a thread or forward it stuff and it’ll handle it for you. muse mail!

    @alexandr_wang

    X post

    Agents & automation

  2. 1054

    Kevin Roose gives his Muse $100 and a Kalshi account★

    gave my Muse $100 and a kalshi account, let's see how frontier this thing is

    @kevinroose

    X post

    Agents & automation

  3. 1046

    Medical bills audited line by line, $4,000 saved★

    Got Muse logged in to my medical provider’s portal, he pulled the itemized bills, and questioned every line. So far he’s found several times I’d been double billed, asked for some discounts and has saved me over $4,000. If your moat is bureaucracy, you’re cooked.

    @Ryan_Holdaway

    X post

    Errands & personal agent

  4. 1042

    GitHub connector for Muse★

    GitHub 🤝 @Muse A new way to connect your GitHub account to review PRs, catch up on issues and notifications, and leave comments without switching tabs.

    @github

    X post

    Connectors & MCP

Want more AI builds?artificialbuilds.com