
Refusal-direction ablation on Muse-Glimmer-30B that cut refusals from 128/150 to 3/150, adding an agentic-safety evaluation and publishing bf16 and GGUF uncensored weights.
GitHub · Local & open models★ Pick· ★ 1
80 builds · page 1 of 1
Refusal-direction ablation on Muse-Glimmer-30B that cut refusals from 128/150 to 3/150, adding an agentic-safety evaluation and publishing bf16 and GGUF uncensored weights.
GitHub · Local & open models★ Pick· ★ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Samuel Alexander ran Muse Glimmer 30B entirely on a Qualcomm Dragonwing IQ-9075 board for zero-shot PCB defect inspection and tool calling, measuring 21.6 GB resident with full 131K context and 2.84 tokens/s generation.
GitHub · Local & open models★ Pick
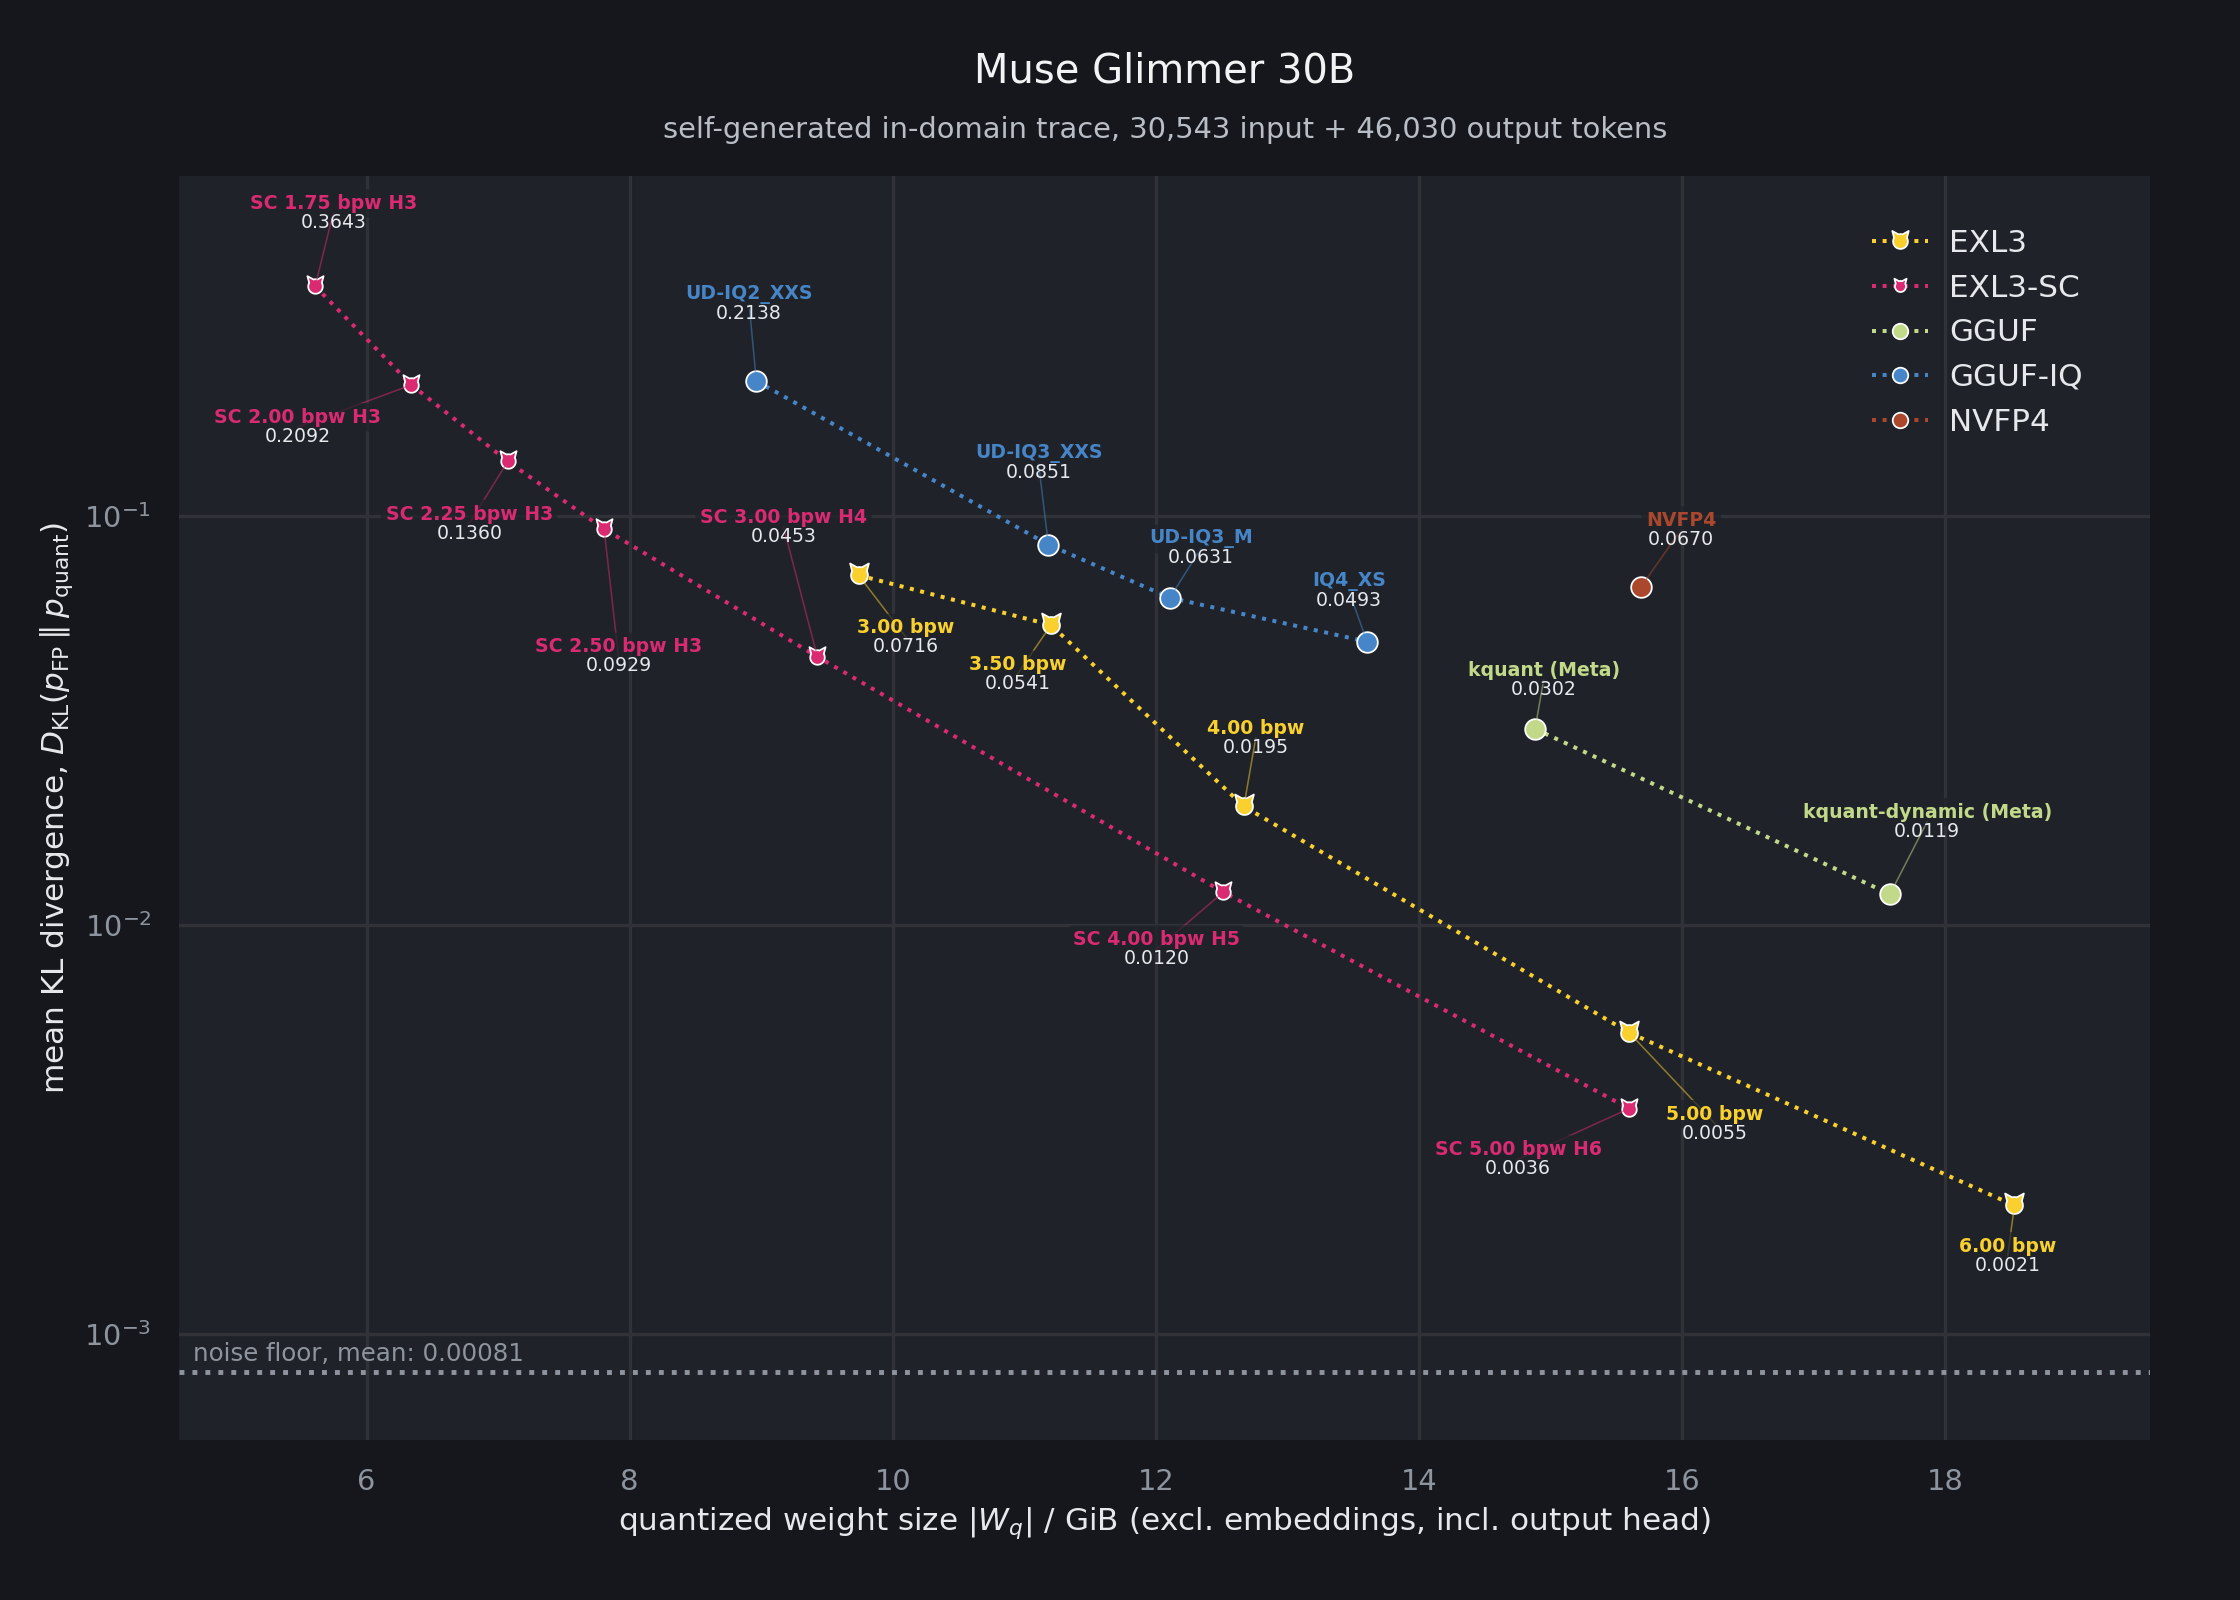
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop. It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster. I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.
Reddit post · Local & open models★ Pick

ollama
@ollama
Using @AIatMeta's Muse Glimmer all locally to process personal monthly credit card statements. Your data belongs to you! Try different agent tasks using your favorite apps / harnesses with Ollama.
X post · Local & open models★ Pick· ♥ 345
My fun weekend project was to try to make the new Muse Glimmer 30B work with a longer context, deciding to go for 512k first. I had expected the usual YaRN shenanigans and maybe a LoRA. I couldn't have been wrong more. Upon closer look, Glimmer turned out to be rather unusual architecturally. The thing that make long-context adaptations painful in other models, full attention layers with token position encoding, it simply not there. Instead, only 2048 tokens-wide SWA layers have RoPE, and full GQA attention layers have no position encoding at all. It appears the model is trained to work with long-distance token relationships inferred from the context and SWA layers. It's a rather bold architecture bet, but it seems Meta managed to pull it off. As a result, the model architecture appears to be uniquely suited for context extension by simple mechanical means. To change model context length from stock 128k to, say, 512k, you need only to change “max_position_embeddings” config setting from 131072 to 524288. What confuses other models, like Qwen3.5 family, Glimmer just takes into its stride. I spent close to 70h of compute on DGX Spark to test stock model with extended context on a
Reddit post · Local & open models★ Pick

Unsloth AI
@UnslothAI
2-bit Muse Glimmer GGUF managed to call 100+ tools on just 14GB RAM. 🔥 Muse Glimmer did a complete repo bug hunt for 5 mins nonstop with: evidence, repro, fix, tests and a PR writeup. Run and train it in Unsloth. GitHub repo: github.com/unslothai/unsl…
X post · Local & open models★ Pick· ♥ 1.6K
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Resource · Local & open models· ♥ 6
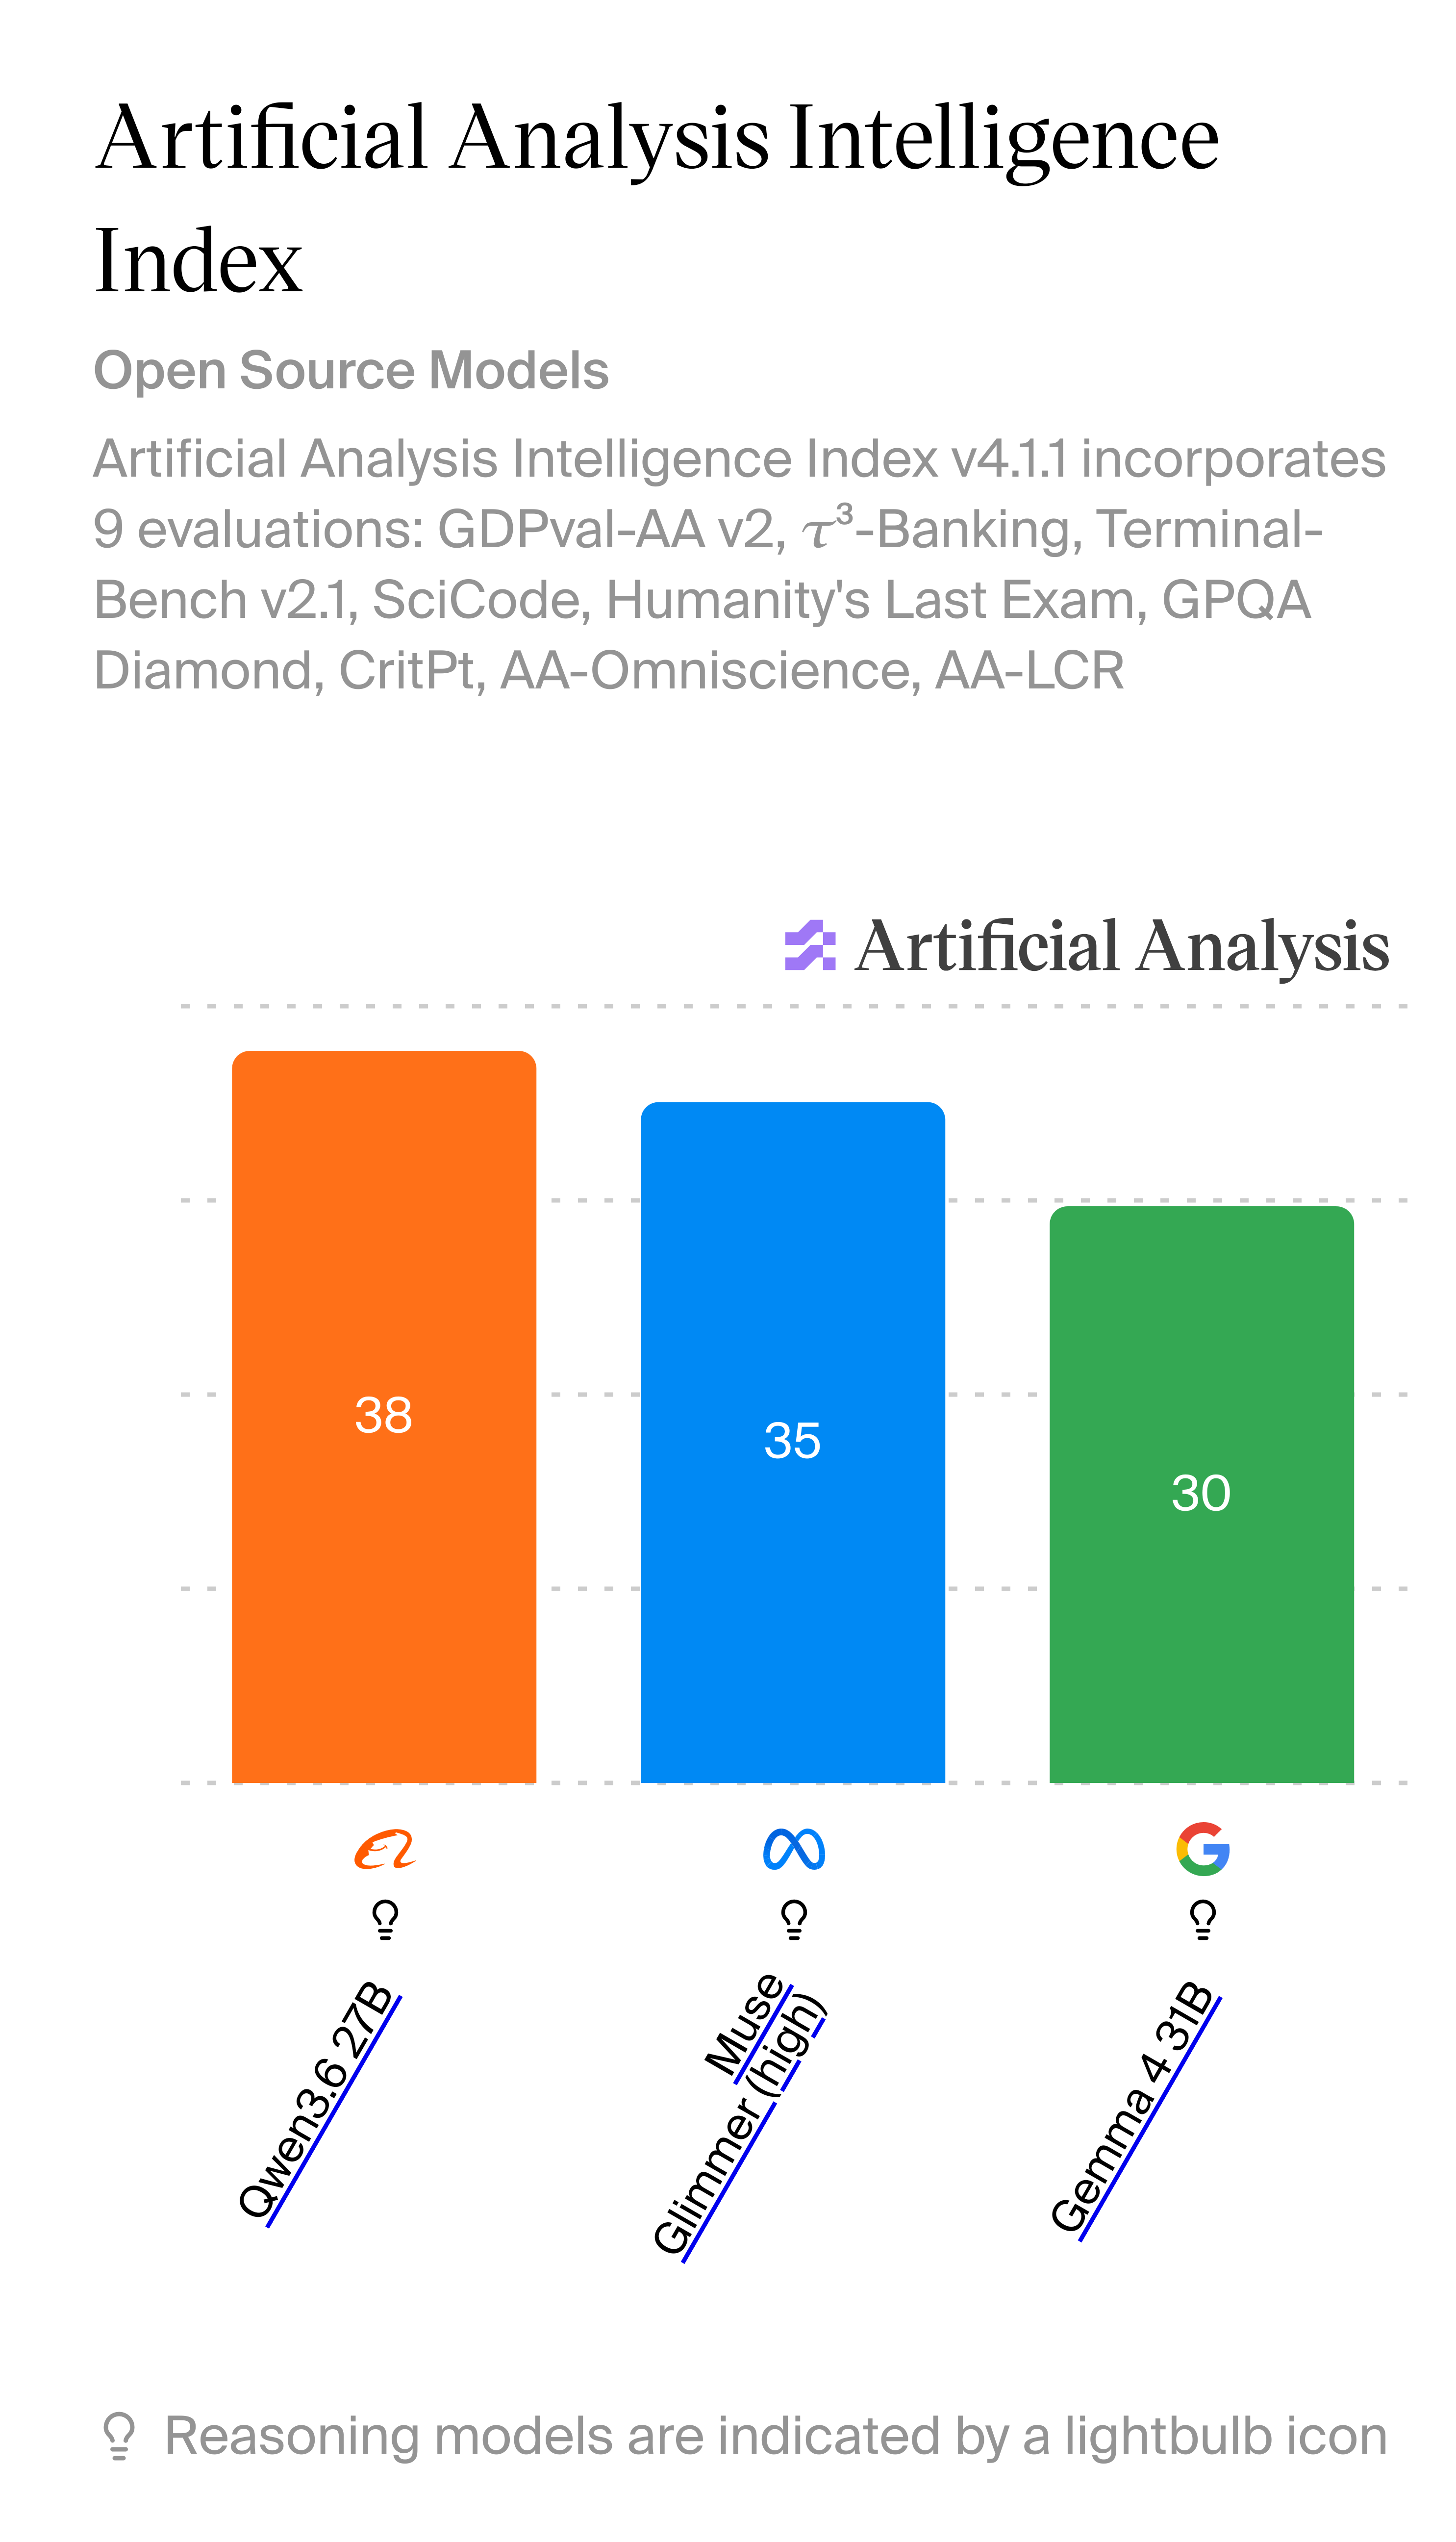
Independent benchmarks and analysis of Meta's open-weight Muse Glimmer.
Resource · Benchmarks & research
An architecture port adding the muse_glimmer model class (vision tower, language model, projector and image processor) to mlx-vlm, so any Muse Glimmer checkpoint runs multimodally on Apple Silicon.
GitHub · Local & open models
Resource · Local & open models· ♥ 12
Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.
Site · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Unsloth's bitsandbytes 4-bit build of Muse Glimmer 30B for fine-tuning and inference.
Resource · Local & open models· ♥ 14
Muse Glimmer 30B abliterated with Heretic v1.4.0 using self-organizing maps and magnitude-preserving orthogonal ablation.
Resource · Local & open models· ♥ 11
llama.cpp imatrix quantizations of Muse Glimmer 30B with image support via mmproj and MTP/DFlash notes.
Resource · Local & open models· ♥ 19
AWQ INT4 quant of Muse Glimmer 30B calibrated on STEM and agentic data across ten languages, 24.02 GB.
Resource · Local & open models· ♥ 10
LoRA adapter that makes Muse Glimmer 30B reliably commit to tool calls when it already knows the correct function.
Resource · Local & open models· ♥ 1
Pre-exported ExecuTorch PTE artifacts of Muse Glimmer 30B from Meta, lowered and optimized for specific target backends.
Resource · Local & open models· ♥ 34

Together AI
@togethercompute
Muse Glimmer is now live on Together AI. We’re proud to be a Day 0 launch partner for this open-weight model from Meta Superintelligence Labs, built for long-running agents that can reason, use tools, recover, and keep working across complex tasks.
X post · Local & open models· ♥ 35
A prebuilt macOS arm64 bundle for the Muse Glimmer voice-agent recipe in meta-oss-cookbook: Parakeet speech helper, Muse Glimmer worker and Supertonic TTS executables built from one pinned ExecuTorch checkout, plus the shared MLX Metal library.
Resource · Local & open models
ROCmFP4 and ROCmFP8 builds of Muse Glimmer 30B and its drafter, targeted and tested on AMD Strix Halo (gfx1151).
Resource · Local & open models· ♥ 18
QLoRA adapter that teaches Muse Glimmer 30B to return click points on web screenshots from instructions, trained on the MolmoWeb dataset.
Resource · Local & open models· ♥ 6
GGUF builds of Muse Glimmer 30B all cut from the same BF16 source weights, including full-precision files.
Resource · Local & open models· ♥ 6
Reddit post · Benchmarks & research
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Solo-built GGUF line of Muse Glimmer 30B with custom calibration, per-tensor allocations and an eval harness behind every reported number.
Resource · Local & open models· ♥ 21
mlx-community's 4-bit MLX conversion of Muse Glimmer 30B made with mlx-vlm 0.6.12 for Apple Silicon.
Resource · Local & open models· ♥ 18
sequelbox's Tachibana-Agent fine-tune of Muse Glimmer 30B, part of a series also released for Gemma 4 12B and Qwen3.6 27B.
Resource · Local & open models· ♥ 4
Mixed-precision NVFP4/MXFP8 checkpoint of Muse Glimmer packed for SGLang, keeping v_proj, down_proj and lm_head at MXFP8.
Resource · Local & open models· ♥ 9
Kingy AI explains Muse Glimmer's benchmarks, 24-64 GB hardware needs, GGUF setup, pricing, runtimes and risks.
Resource · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Sam Witteveen covers Meta's open-weight Muse Glimmer 30B release, pointing to the research blog and the Hugging Face collection.

Video · Local & open models· ♥ 405

Mark Zuckerberg
@finkd
Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats
X post · Local & open models· ♥ 30.4K
HolaClaw's tutorial for running Muse Glimmer 30B behind OpenClaw on a Mac, with hardware requirements and llama.cpp and Ollama setup.
Resource · Local & open models
Meta's lightweight DFlash block-diffusion drafter for Muse Glimmer 30B that predicts blocks of 16 tokens per forward pass for speculative decoding.
Resource · Local & open models· ♥ 61

Xuan-Son Nguyen
@ngxson
We are happy to announce that Muse Glimmer is day-0 supported on llama.cpp. Meta also provides an official GGUF quant:
X post · Local & open models· ♥ 86

Cline
@cline
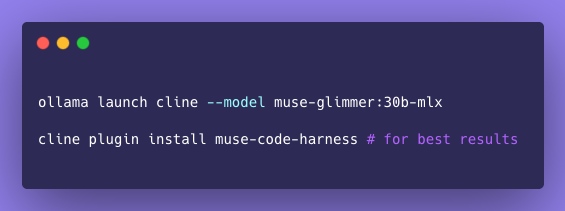
The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now!
X post · Local & open models· ♥ 157
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Venelin Valkov runs Muse Glimmer 30B locally via llama.cpp server and tests it on coding with OpenCode, agentic tasks and frontend work.

Video · Local & open models
HolaClaw tested Muse Glimmer on base M3 and M4 Macs: it fits in 24GB of RAM but generates at 4.3 tokens per second.
Resource · Local & open models
DFlash 2 speculative-decoding draft model for Muse Glimmer 30B from z-lab, run inside a speculative decoding server alongside the target model.
Resource · Local & open models· ♥ 15
Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.
Reddit post · Local & open models★ Pick
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
A vLLM-XPU and DFlash recipe for Muse Glimmer 30B on a single Intel Arc Pro B70, reporting 278 aggregate tok/s across eight clients and an 840.8 tok/s burst peak at concurrency 96.
GitHub · Local & open models★ Pick· ★ 1
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
Resource · Local & open models★ Pick
We've been curious how far local models have actually come for agentic coding tasks, so we ran an experiment. Setup: • Model: Muse Glimmer (30B), packaged as a single llamafile • Agent: Hermes coding agent (connected via llamafile's local server mode, zero API keys needed) • Target: Mozilla AI's Otari gateway The Issue: We pointed Hermes at a real, reported bug in Otari (#183) where the gateway returned a vague 502 error on image requests instead of passing through the actual provider error. What the Agent Did: Hermes read the issue, navigated the repo, isolated the bug, created a branch, ran existing tests, wrote a new regression test, and opened a draft PR (#727). All of it ran locally and offline, with zero code written by hand. It's still draft PR territory rather than a merged fix, but it's a solid signal that ~30B local models are getting genuinely capable for real dev workflows, not just toy demos. Video walkthrough of the run: https://youtu.be/5GAgbT-XgHU?si=vJqEDGm9hssCO5-M Happy to answer questions about the setup, model performance, or how Hermes handled tool calling!
Reddit post · Local & open models★ Pick
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster. Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed. Repo: github.com/ARahim3/mlx-dspark I'm happy to hear feedback, and I'm curious about what other M-series chips get.
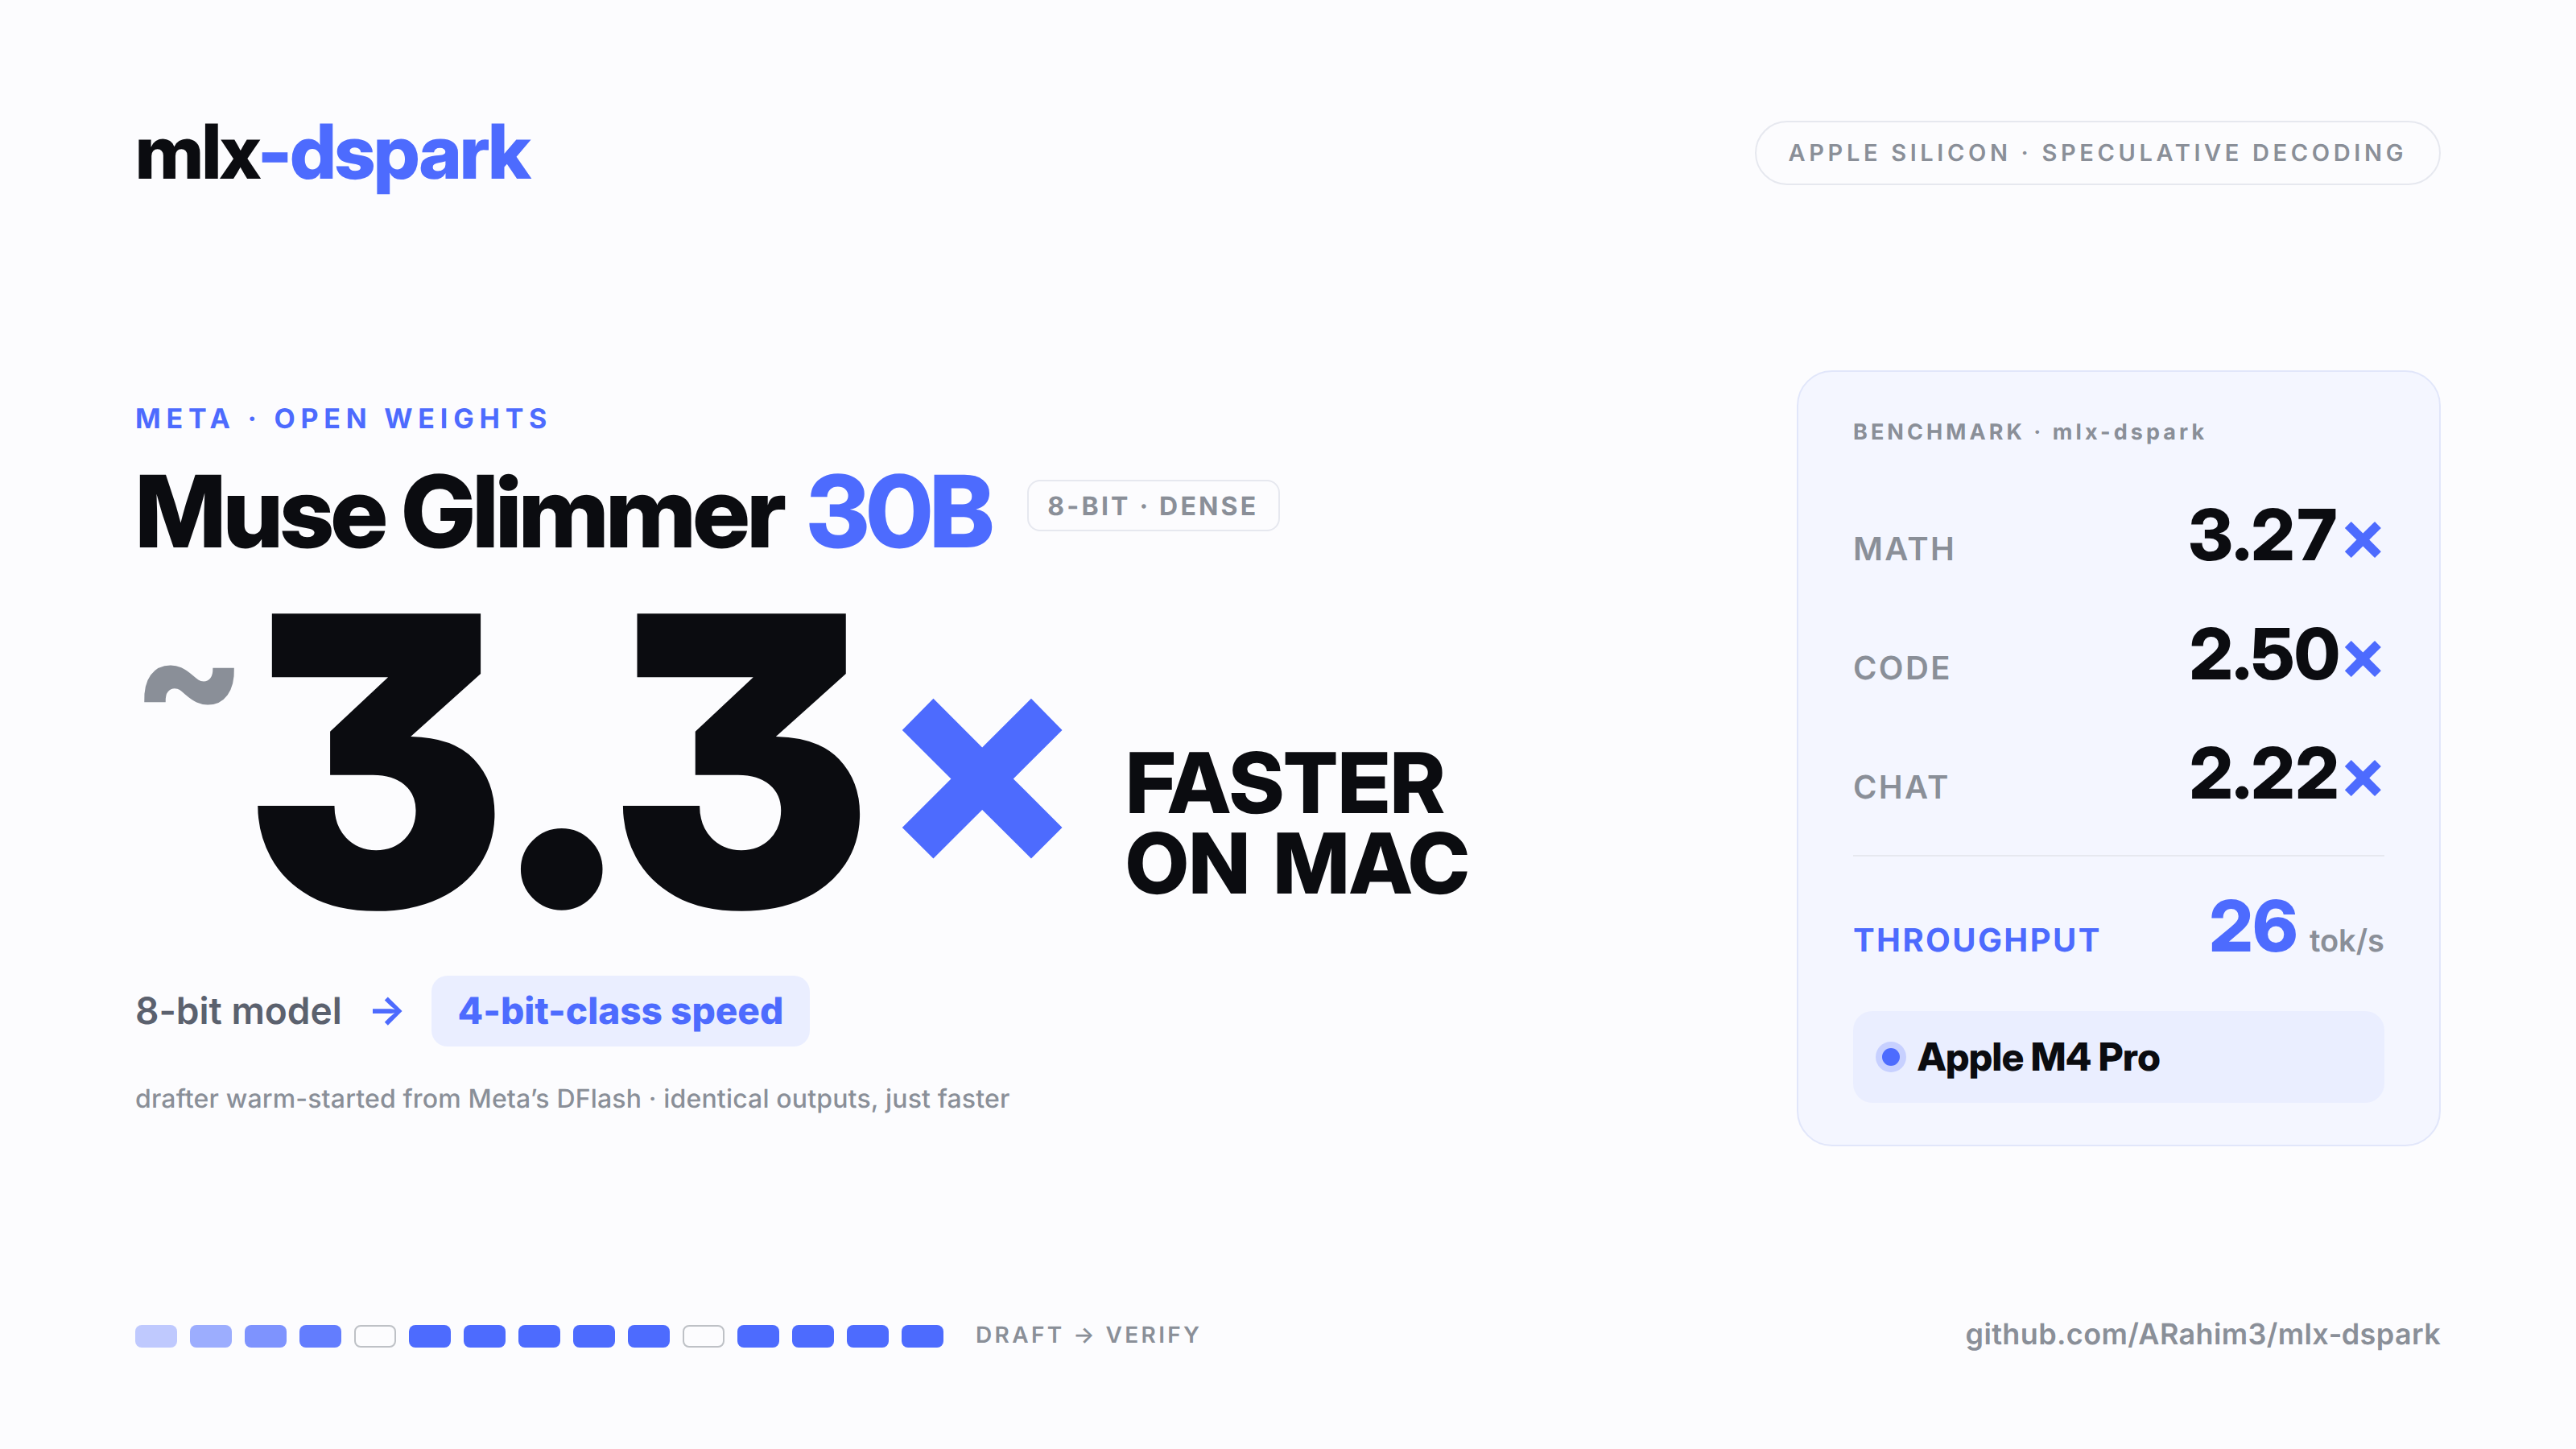
Reddit post · Local & open models★ Pick

Paolo Rosson
@redp314
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're
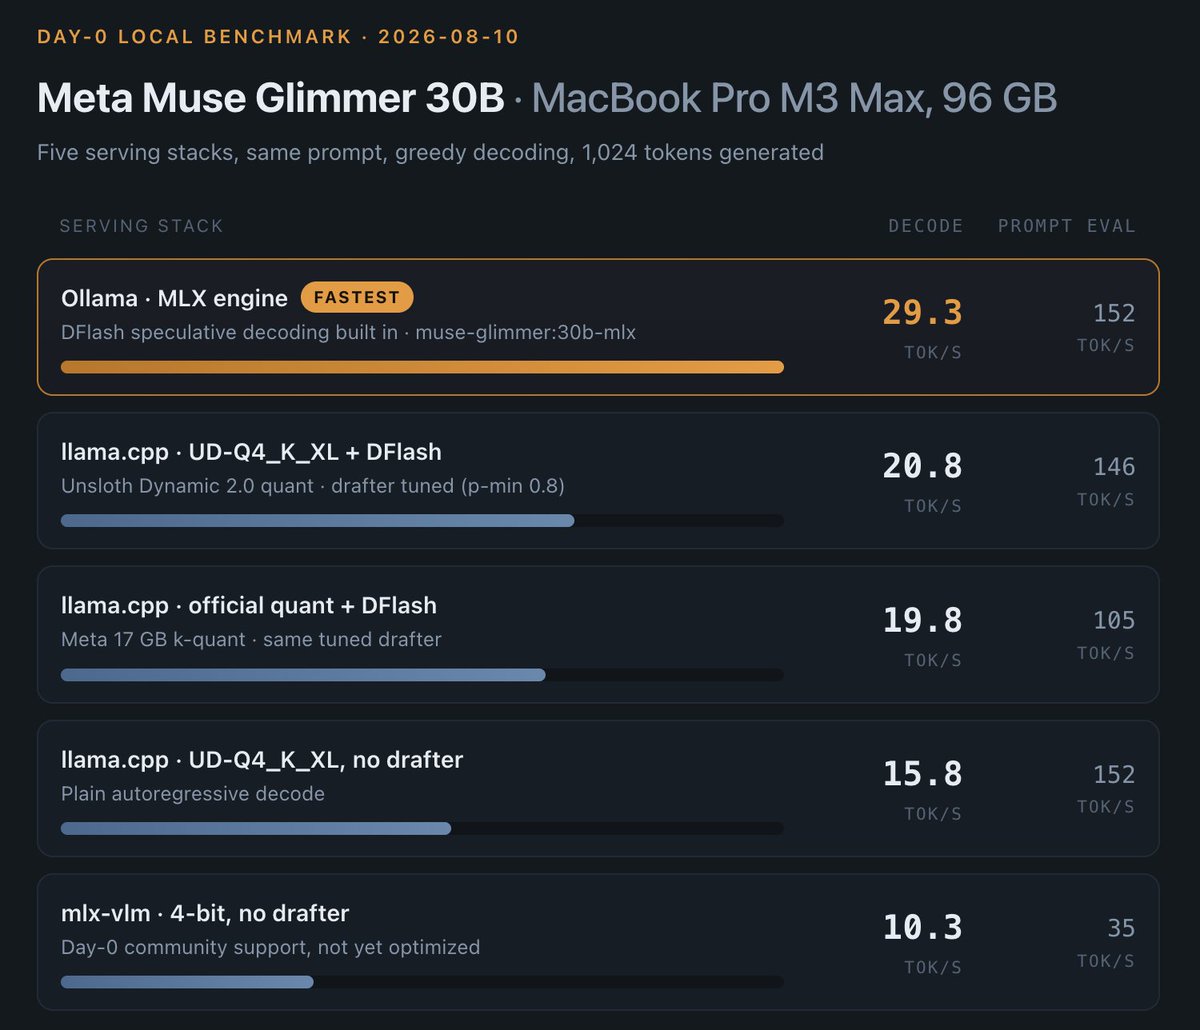
X post · Local & open models★ Pick· ♥ 44
Resource · Local & open models· ♥ 4
Resource · Local & open models· ♥ 15
Resource · Local & open models· ♥ 8
Standalone packaging of the vision tower and projector extracted from Muse Glimmer 30B.
Resource · Local & open models· ♥ 2
Resource · Local & open models· ♥ 18
Resource · Local & open models· ♥ 343
Decensored Muse Glimmer 30B made with Heretic v1.4.0, shipped with a reproduce directory.
Resource · Local & open models· ♥ 15
smol-muse-glimmer scales Muse Glimmer's language backbone down to a 51M-parameter model and trains it on TinyStories, reaching validation cross-entropy of 1.8127 at step 5,000.
GitHub · Benchmarks & research
muse-glimmer-mlx is an MLX port of Muse Glimmer 30B for Apple Silicon that supplies the missing runtime so the many unloadable MLX conversions published on Hugging Face can actually be run.
GitHub · Local & open models
Site · Local & open models· ♥ 5
Experimental OpenVINO INT4 conversion of Muse Glimmer 30B that needs development builds of Optimum Intel and OpenVINO.
Resource · Local & open models· ♥ 1
A suite of 27 GGUF quantizations of an abliterated Muse Glimmer 30B produced with Heretic v1.4.0.
Resource · Local & open models· ♥ 20
Unsloth's docs page for running Meta's Muse Glimmer 30B locally with its GGUF quants.
Resource · Local & open models
LoRA adapter for Muse Glimmer 30B that makes responses predictable machine-readable JSON with a stable API-style envelope.
Resource · Local & open models· ♥ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Red Hat AI's FP8 weight and activation quantized Muse Glimmer 30B (text and image input) for vLLM.
Resource · Local & open models· ♥ 12
Fahd Mirza installs Muse Glimmer in GGUF format and tests it with DFlash speculative decoding for faster local inference.

Video · Local & open models
Unsloth Dynamic 2.0 GGUF quants of Muse Glimmer 30B with a companion run guide and thinking toggles.
Resource · Local & open models· ♥ 548
GGUF conversions of Inco AI's DFlash 2 draft model for Muse Glimmer 30B, for speculative decoding in llama.cpp.
Resource · Local & open models· ♥ 16
Fireworks made Muse Glimmer 30B available on launch day, pitching high-concurrency, cost-effective serving for always-on agents.
Resource · Local & open models
Muse Glimmer 30B quantized with Intel AutoRound at a 3.5-bit target and packed with llm-compressor, tested on vLLM.
Resource · Local & open models· ♥ 3
turboderp's self-calibrated EXL3 quants of Muse Glimmer 30B down to 1.75 bits per weight, with calibration and eval traces.
Resource · Local & open models· ♥ 14

Sumanth
@Sumanth_077
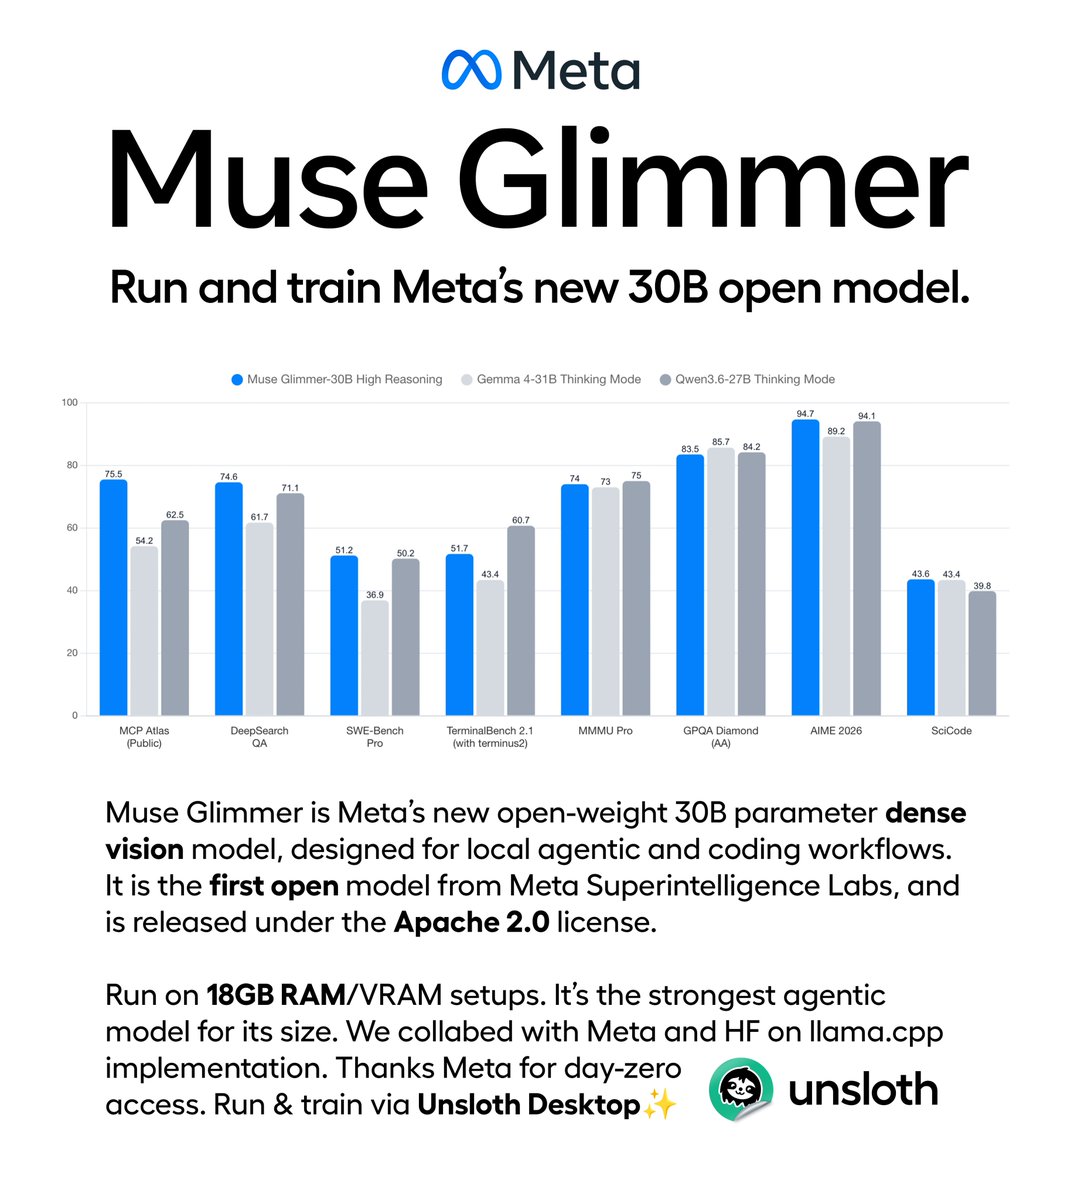
Run and fine-tune Meta's Muse Glimmer locally! Meta released Muse Glimmer, a 30B dense vision model designed for local agentic and coding workflows. The first open model from Meta Superintelligence Labs, released under Apache 2.0. The model runs locally at different memory
X post · Local & open models· ♥ 26
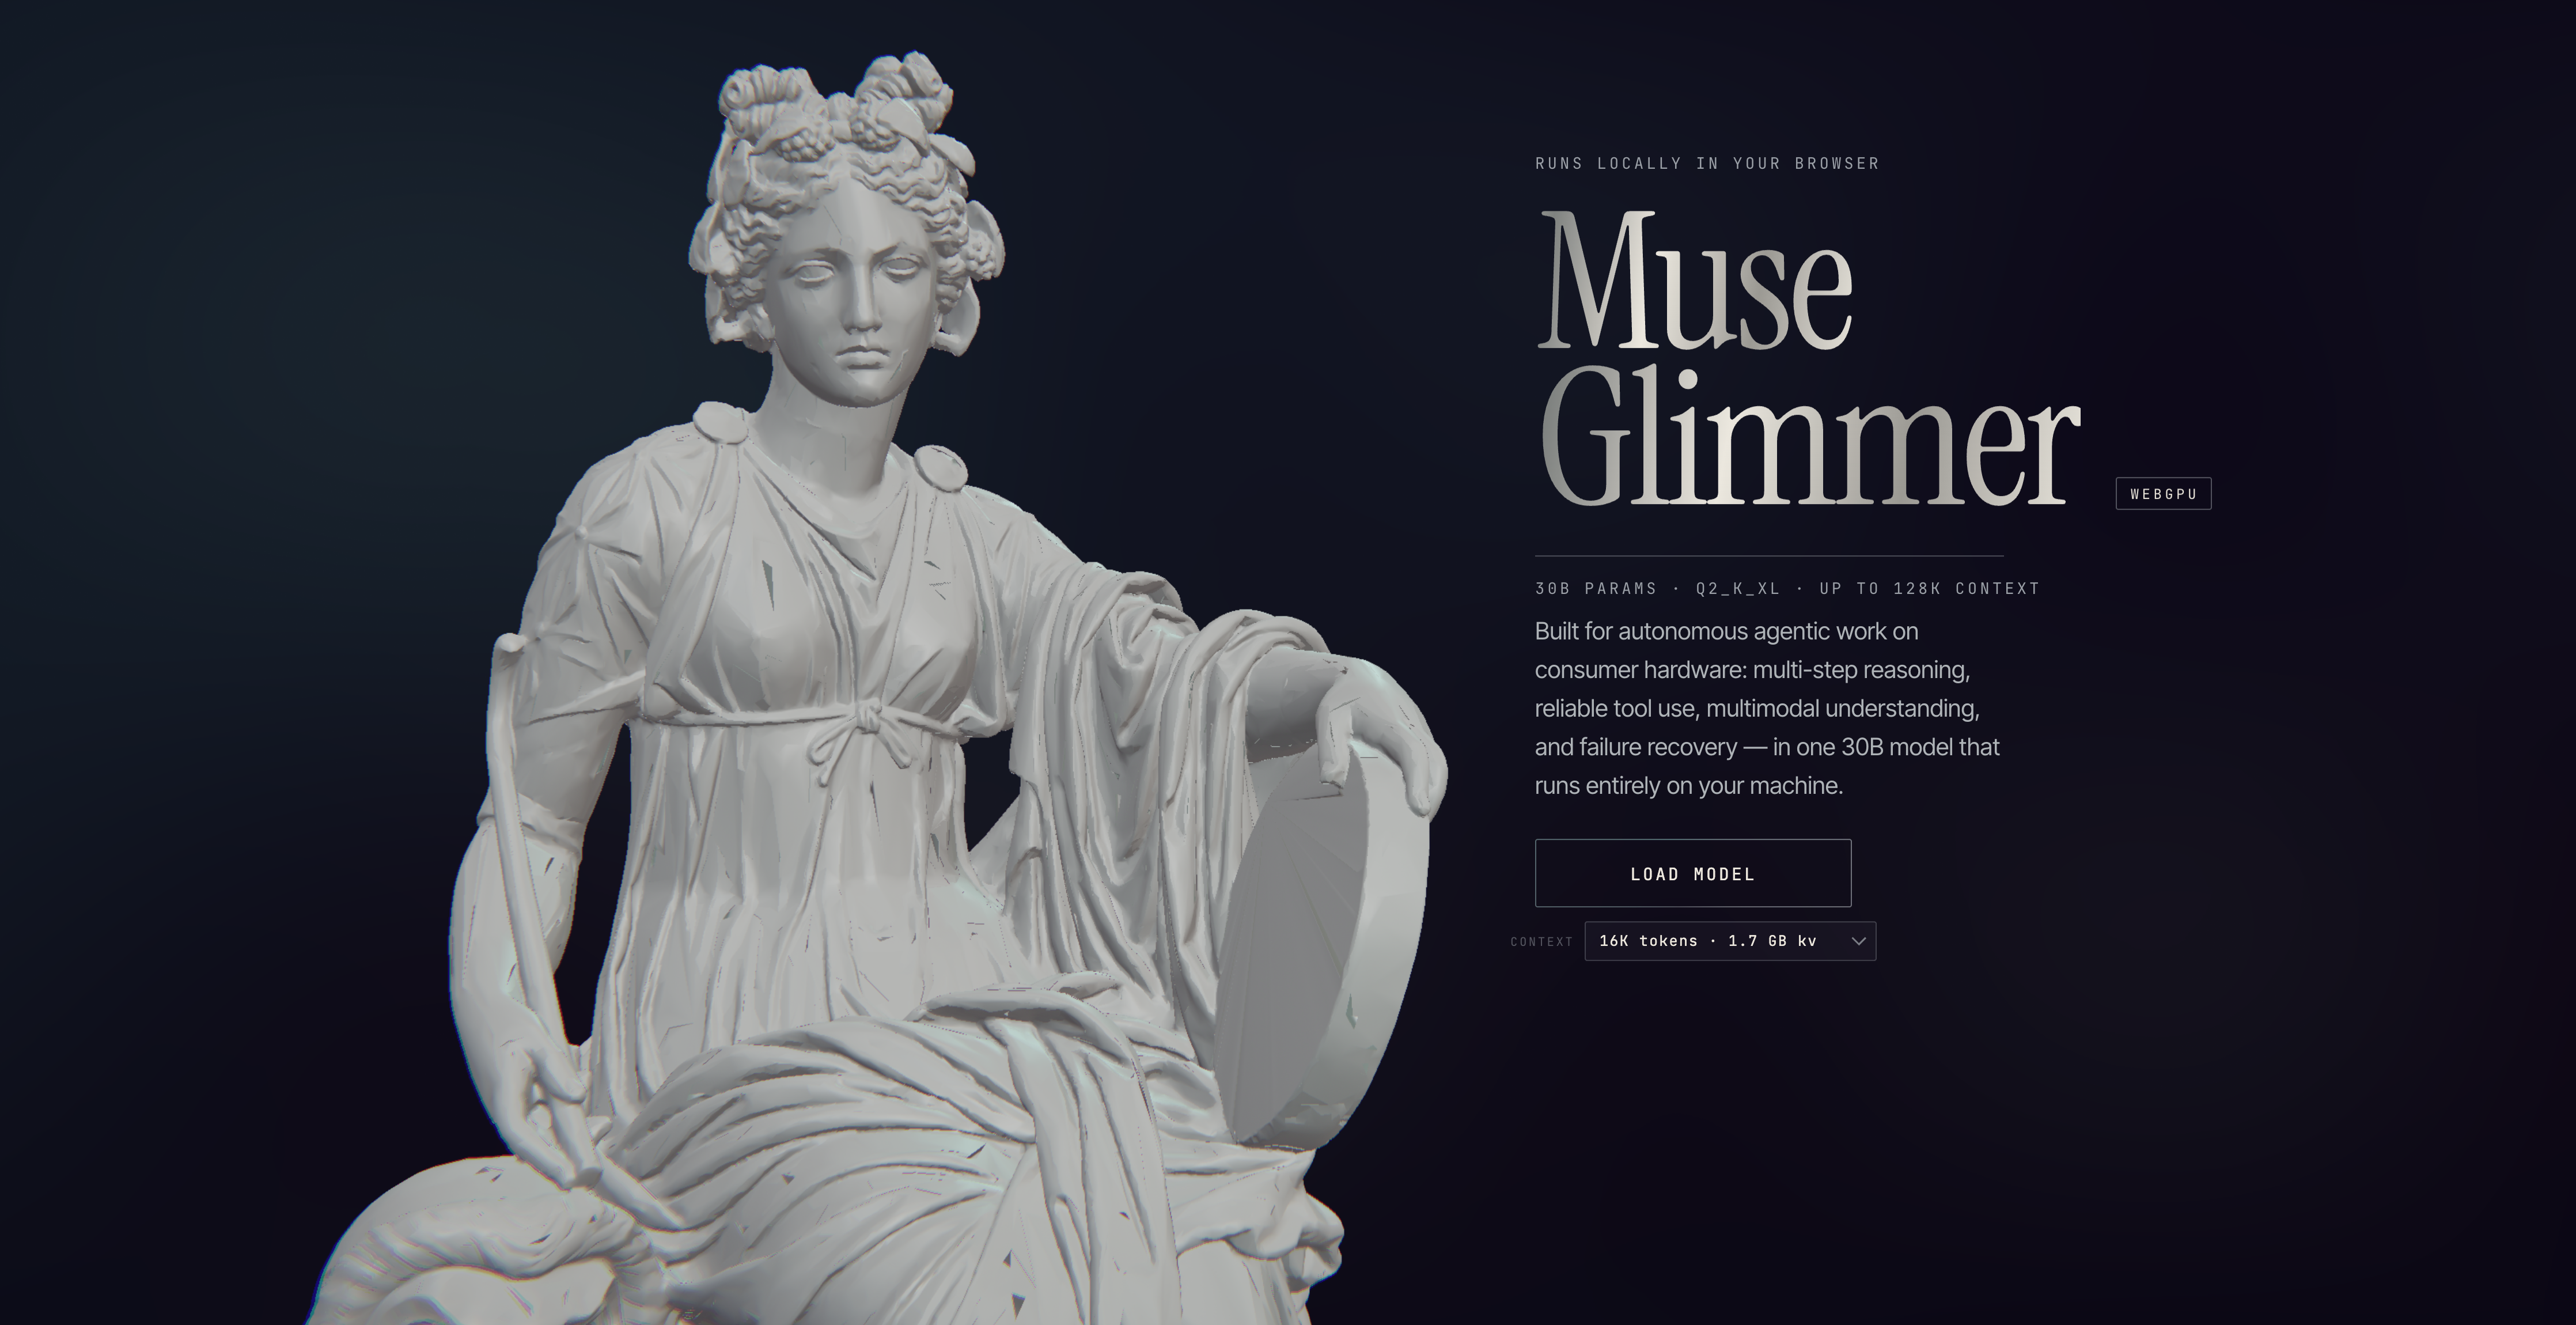
A webml-community Space that runs Muse Glimmer 30B locally in the browser using custom WebGPU kernels.
Site · Local & open models· ♥ 15
Muse Glimmer 30B fine-tuned on agentic coding traces and chat distilled from Claude Fable 5, merged bf16 and drop-in for the base.
Resource · Local & open models· ♥ 3

LM Studio
@lmstudio
Muse Glimmer 30B is live in LM Studio! It's a new open source model from Meta. Apache 2.0 license, fit right on your laptop. It is the strongest model of its size class we've tested.
X post · Local & open models· ♥ 1.4K

Simon Willison
@simonw
Muse Glimmer, the new 30B model, is available on Hugging Face right now - here's the GGUF version: huggingface.co/meta-models/Mu…
X post · Local & open models· ♥ 210

Ben Burtenshaw
@ben_burtenshaw
Meta is back with Muse Glimmer: a 30B open-source multimodal model built for local, agentic use. HF is shipping day-0 support and I built a few demos to see what it can do. First: we gave Glimmer tools and asked it to quantize itself.
X post · Local & open models· ♥ 125
ROCmFP4 GGUF of Muse Glimmer 30B with DFlash for AMD Strix Halo, requiring a ROCmFPX llama.cpp fork that adds the muse-glimmer architecture.
Resource · Local & open models· ♥ 4
Unsloth AI
@UnslothAI
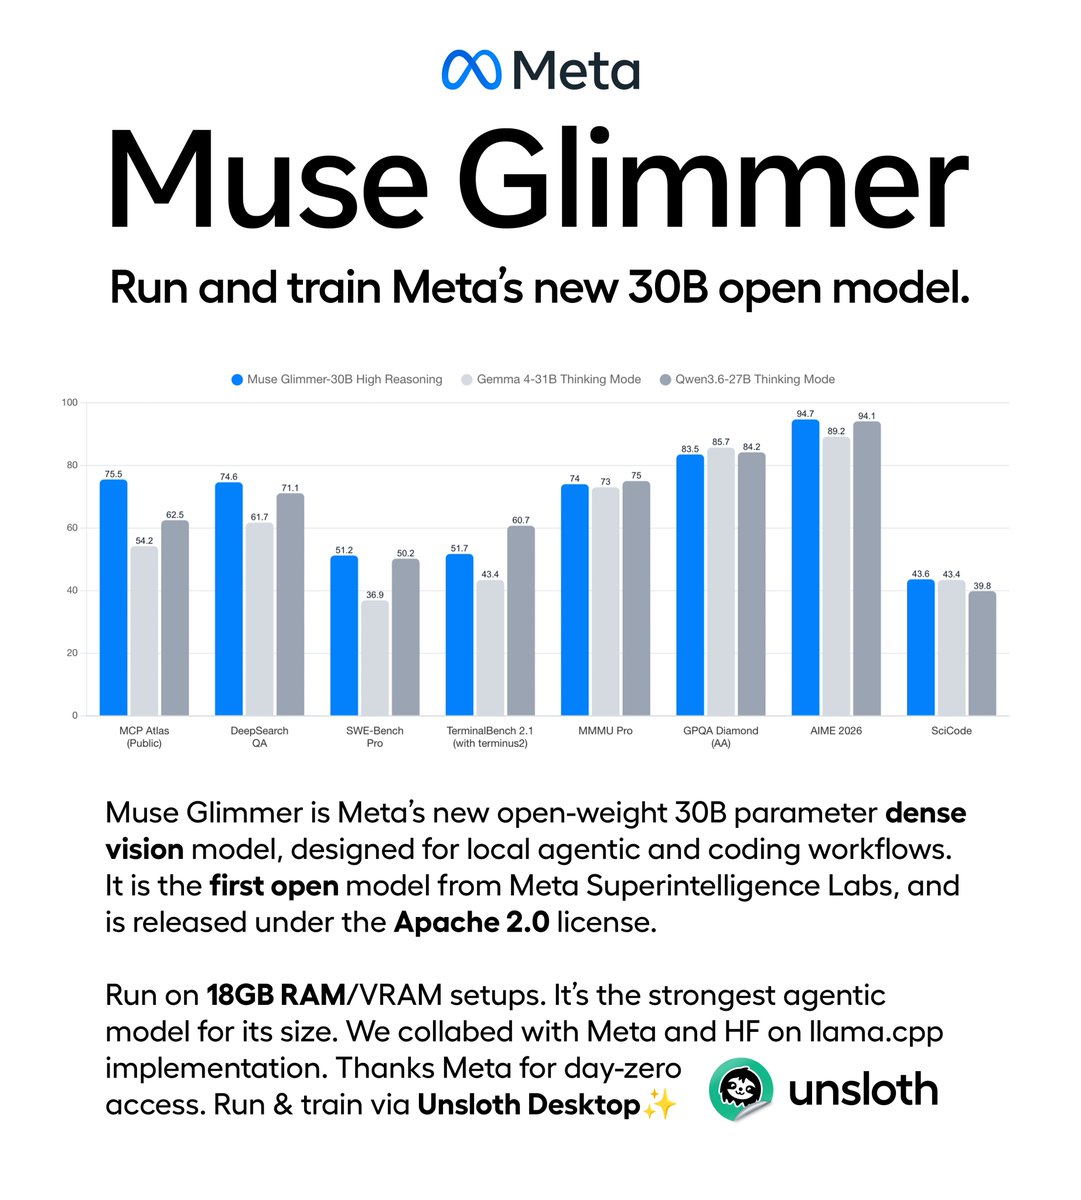
Meta releases Muse Glimmer, a new 30B open model that runs on 18GB RAM. Muse Glimmer is Apache 2.0 licensed, supports vision and is the strongest agentic model for its size. Run and train the model via Unsloth. GGUF: huggingface.co/unsloth/Muse-G… Guide: unsloth.ai/docs/models/mu…
X post · Local & open models· ♥ 2.8K
Fine-tune of Muse Glimmer 30B for Hermes Agent and agentic tool work that teaches the model to call one or two tools and stop.
Resource · Local & open models· ♥ 2
Abliterated Muse Glimmer 30B GGUF quant ladder, updated with a 1.63 GB abliterated DFlash drafter and a 1.40 GB multimodal projector.
Resource · Local & open models· ♥ 49

vLLM
@vllm_project
@Meta is back in open source. Excited to announce Day-0 vLLM support for Muse Glimmer 30B, the first open-weights model from Meta Superintelligence Labs — which ships under Apache 2.0!!! 30B dense, 128K+ context, multimodal, built for local agents. Capable enough for
X post · Local & open models· ♥ 251
Fireship breaks down Meta's Muse Glimmer, a 30B-parameter agentic model released under Apache 2.0, in a short explainer.
Video · Local & open models· ♥ 13.6K
Lightweight LoRA that makes Muse Glimmer 30B output a target element's bounding box directly from a screenshot and instruction, for computer-use agents.
Resource · Local & open models· ♥ 3
AICodeKing reviews Muse Glimmer for local agent setups, finding it strong at tool calling, multi-step tasks and failure recovery but weaker on general benchmarks.

Video · Local & open models
A Makefile that downloads the three Muse Glimmer 30B GGUFs and builds and serves llama.cpp on Apple Silicon, automating a scriptable.com walkthrough.
GitHub · Local & open models






 ChatForm
 Tgmlabs