№ 0076Reddit post★ Pick
Muse Glimmer 30B on a 12GB laptop GPU
Runs Muse Glimmer 30B as an EXL3 3.00bpw quant fully in 12GB VRAM at 100K context, reporting ~30 tok/s for a Hermes Agent workload.
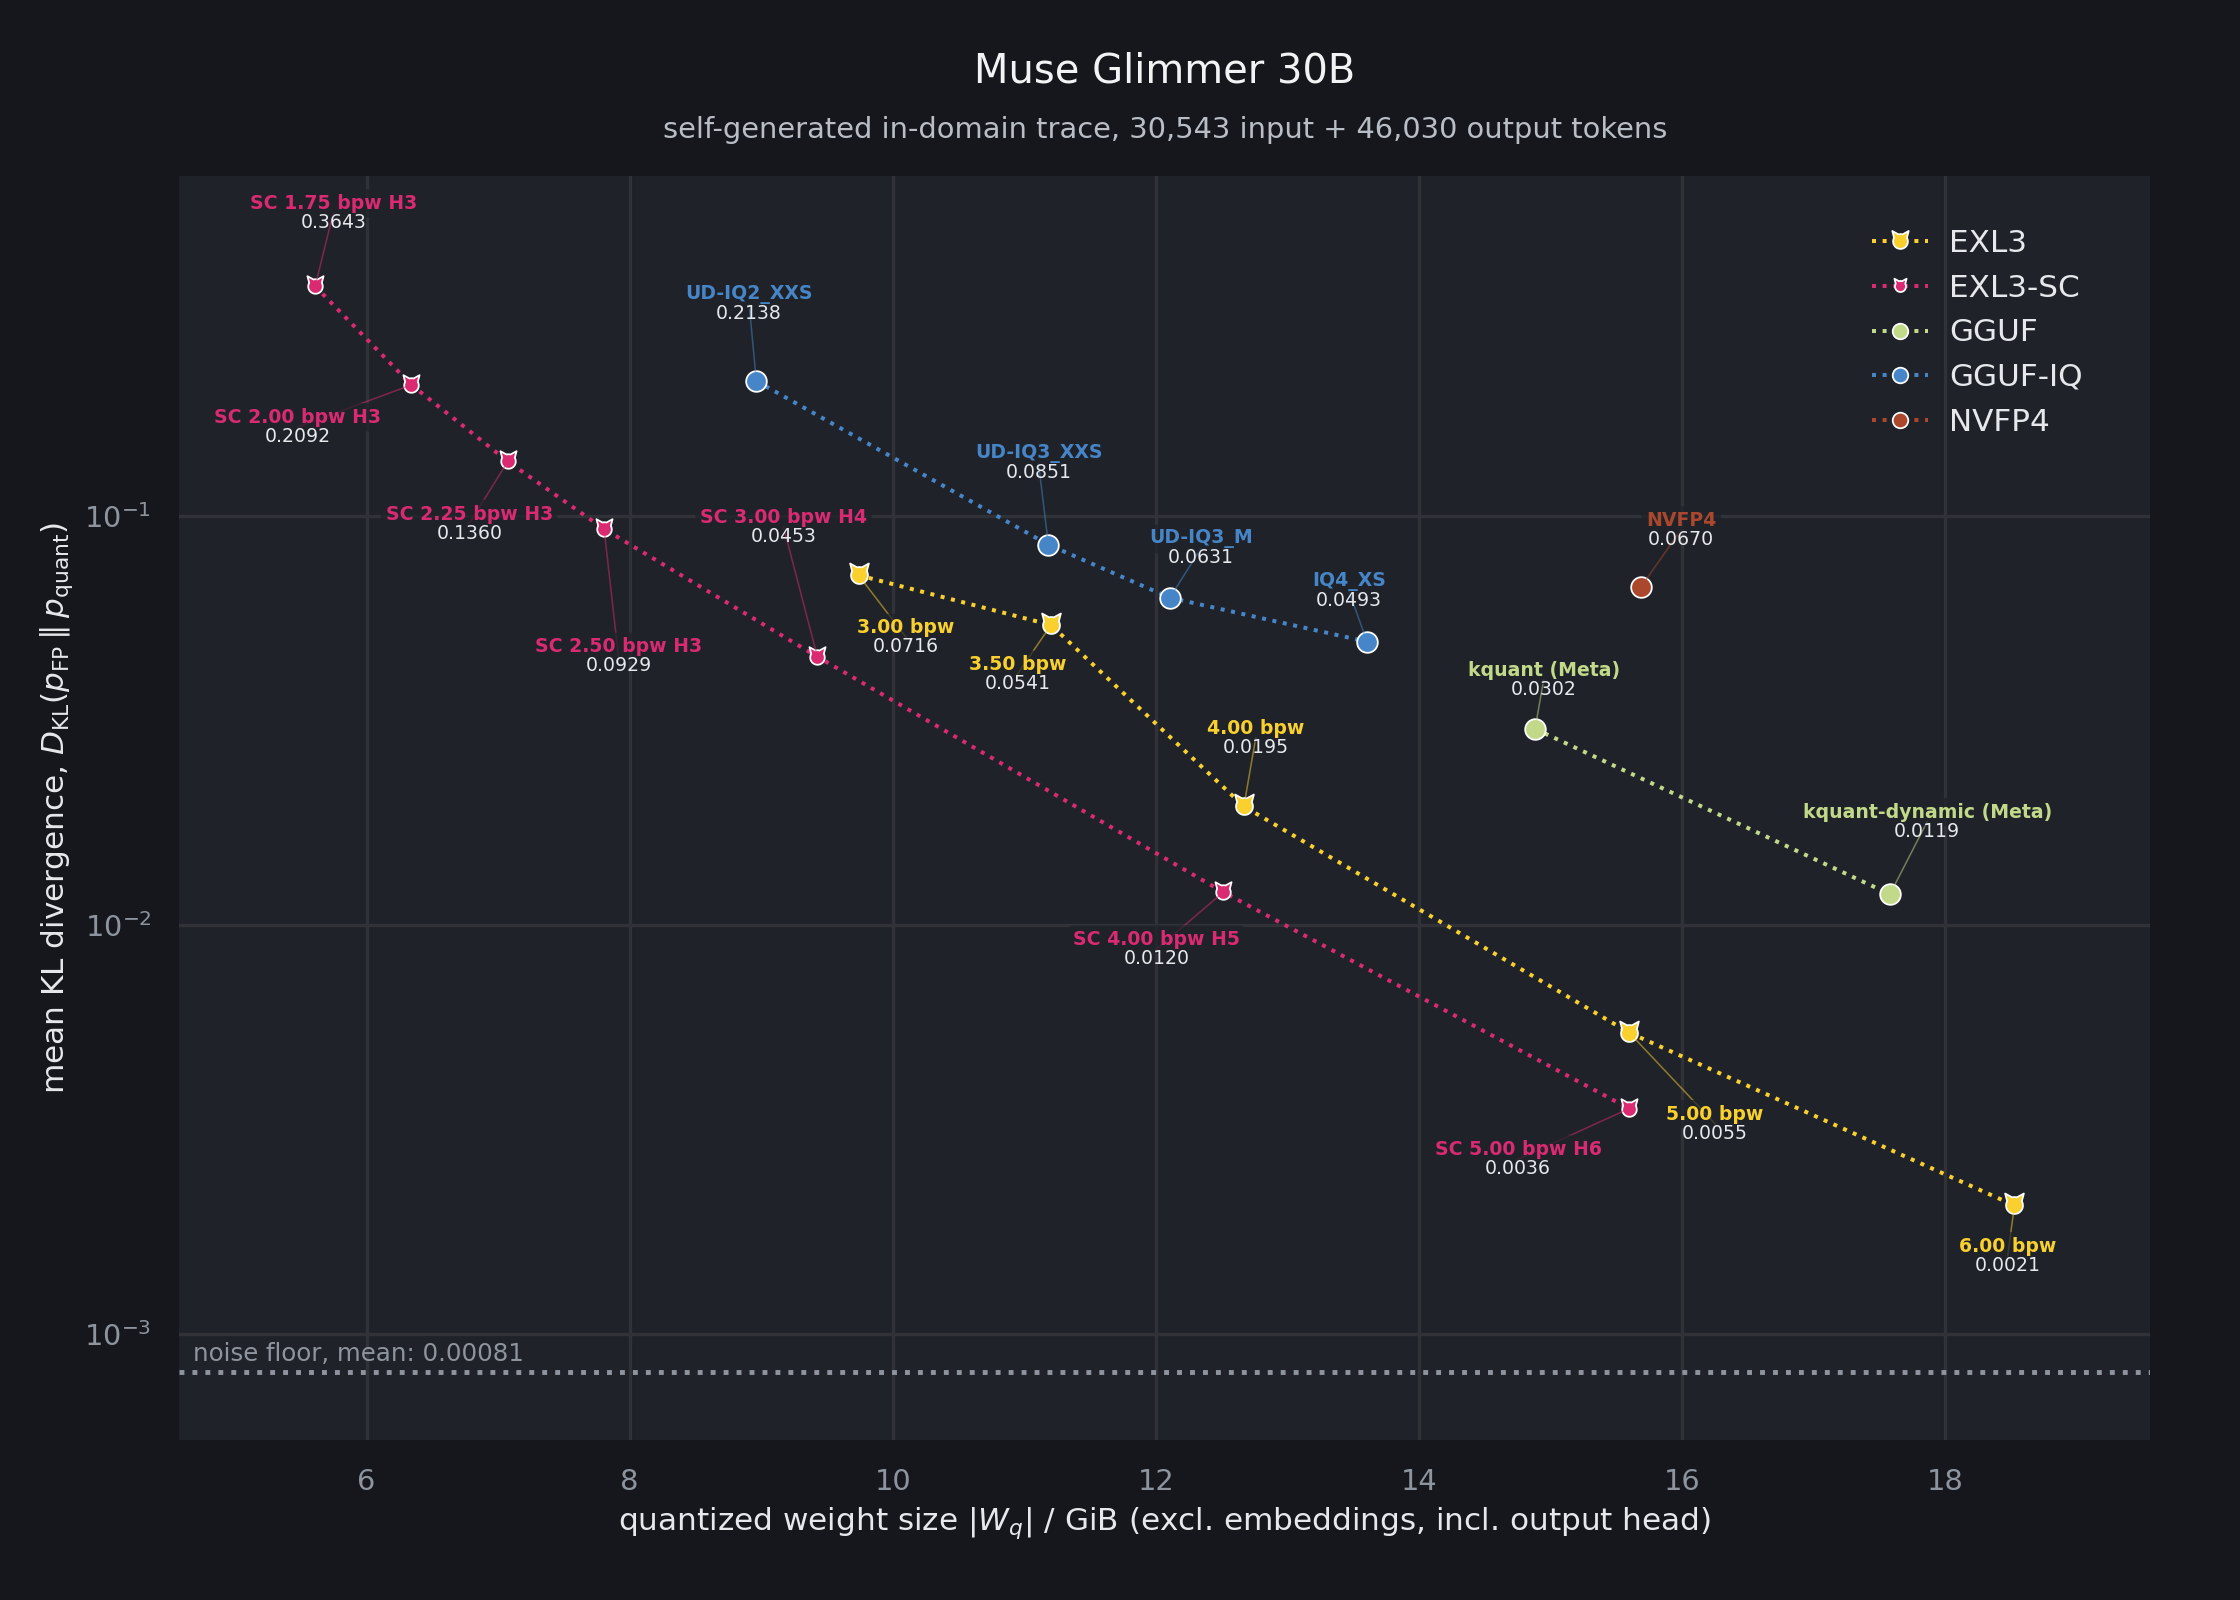
u/PyaesoneP runs Muse Glimmer 30B EXL3-SC 3.00bpw H4 fully resident on a 12GB VRAM laptop GPU with 100K context and Q8 KV cache. They report ~30 tok/s and say they notice no quality difference versus the official 17GB K-quant for their Hermes Agent use case.
Don't Sleep on EXL3 Quants
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop. It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster. I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.



 ChatForm
 Tgmlabs