shipwithmuse

Entries matching “quantization”

17 builds · page 1 of 1

Ben Burtenshaw

@ben_burtenshaw

Meta is back with Muse Glimmer: a 30B open-source multimodal model built for local, agentic use. HF is shipping day-0 support and I built a few demos to see what it can do. First: we gave Glimmer tools and asked it to quantize itself.

X post · Local & open models· ♥ 125
Muse Glimmer quantizes itself

R

RedHatAI

RedHatAI

Red Hat AI's FP4 weight and activation quantized Muse Glimmer 30B.

Resource · Local & open models· ♥ 18

Red Hat AI NVFP4 Muse Glimmer

0

0bserverx

0bserverx

A suite of 27 GGUF quantizations of an abliterated Muse Glimmer 30B produced with Heretic v1.4.0.

Resource · Local & open models· ♥ 20

Heretic Uncensored Muse Glimmer GGUF

A

Anbeeld

Anbeeld

GGUF quantizations of the Inco AI DFlash2 drafter for Muse Glimmer 30B, for use with the BeeLlama.cpp llama.cpp fork.

Resource · Local & open models· ♥ 1

DFlash2 GGUF for BeeLlama.cpp

TimDarcet

@TimDarcet

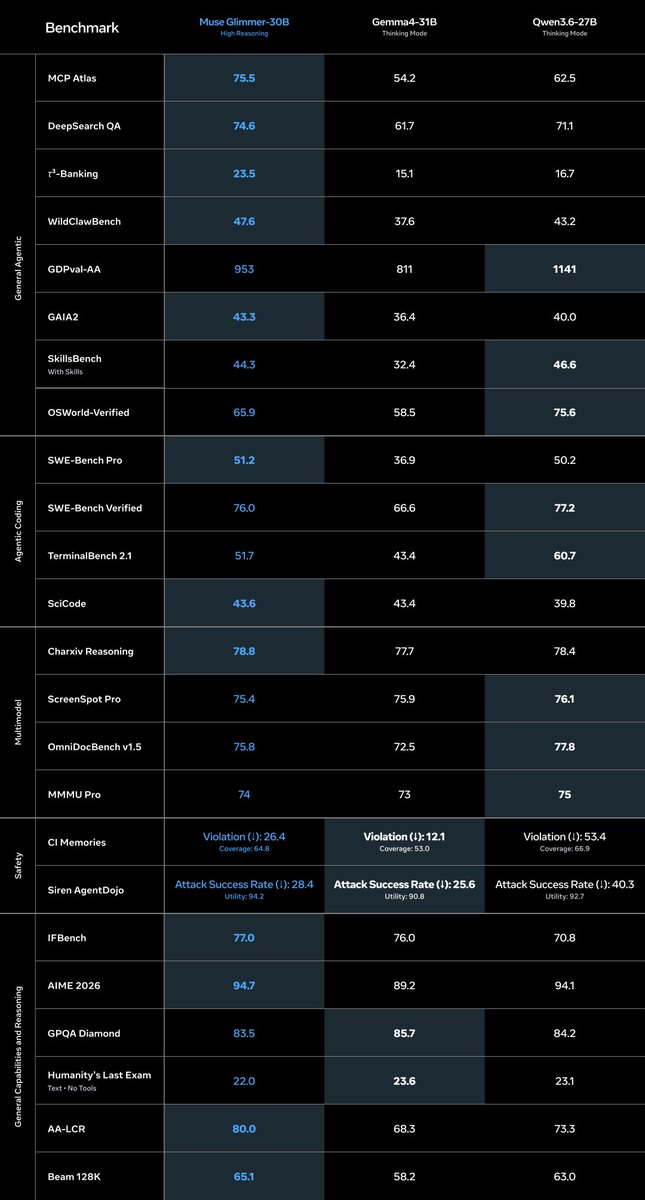
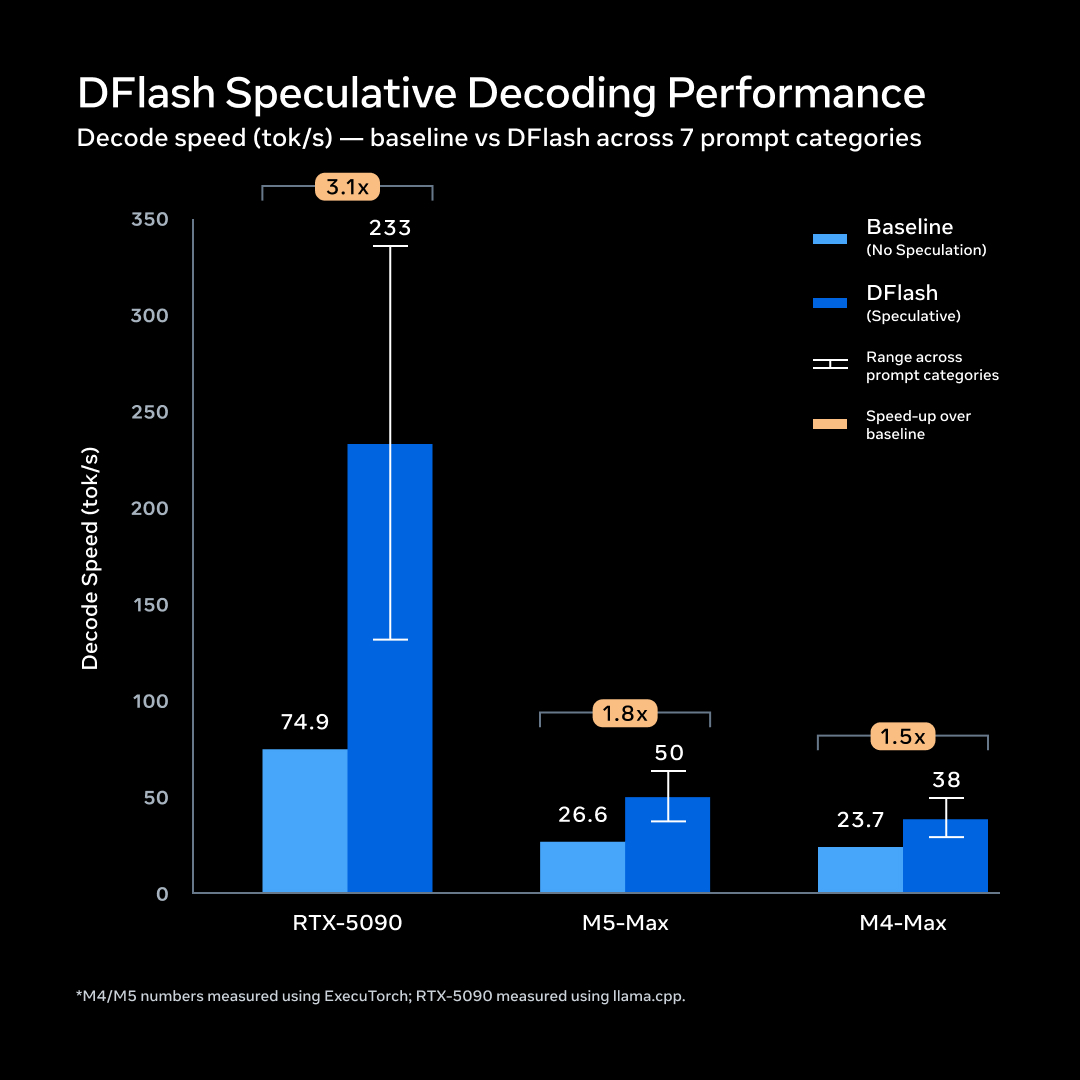
Happy to release ✨ Muse Glimmer ✨ - level ~= Qwen 3.6-27B - Apache 2 - 30B dense - quantized to run in 17GB - quant + spec dec => 50 tok/s on macbook m5 max, interactive, smooth Enjoy!

X post · Local & open models· ♥ 74

Glimmer at 50 tok/s on an M5 Max MacBook

Alok

@analogalok

Muse Glimmer, A 30B parameter dense model swallowing a 130,000 token context window using only 19.3 GB of VRAM (extreme efficiency). No KV cache quantization required. I just benched the new Muse Glimmer 30B (dense) on a single RTX 4090. We are pulling 3,100+ t/s prefill and 75

X post · Local & open models· ♥ 392

Glimmer bench on a single RTX 4090

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

A

datacamp.com

datacamp.com

Abid Ali Awan sets up Muse Glimmer 30B on an RTX 5090 with llama.cpp, dynamic quantization and DFlash speculative decoding, serves it locally and wires it into OpenCode to build a medical research web app.

Guide · Local & open models

Run Muse Glimmer 30B locally for AI coding

Q

huggingface.co

huggingface.co

A quantization-aware-trained Q4_0 GGUF of Muse Glimmer 30B for llama.cpp. On held-out tokens it measures closer to BF16 than Meta's official Q4_K_M: 0.0213 vs 0.0228 KL and 95.9% vs 95.6% top-token agreement.

Resource · Local & open models· ♥ 3

Muse Glimmer 30B native Q4_0 QAT GGUF

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

B

bartowski

bartowski

llama.cpp imatrix quantizations of Muse Glimmer 30B with image support via mmproj and MTP/DFlash notes.

Resource · Local & open models· ♥ 19

bartowski imatrix GGUF of Muse Glimmer

R

RedHatAI

RedHatAI

Red Hat AI's FP8 weight and activation quantized Muse Glimmer 30B (text and image input) for vLLM.

Resource · Local & open models· ♥ 12

Red Hat AI FP8-block Muse Glimmer

K

kaitchup

kaitchup

Muse Glimmer 30B quantized with Intel AutoRound at a 3.5-bit target and packed with llm-compressor, tested on vLLM.

Resource · Local & open models· ♥ 3

AutoRound 3.5-bit Muse Glimmer

AI at Meta

@AIatMeta

For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to

X post · Local & open models· ♥ 456

How Glimmer fits on consumer hardware

@tanishq-dubey

@tanishq-dubey

A reproducible Apple Silicon harness that runs six fixed quality tasks against MLX quantizations of Muse Glimmer 30B and records scores, tokens per second, peak memory and load time.

GitHub · Benchmarks & research

Muse Glimmer 30B MLX benchmark harness

M

dev.meta.ai

dev.meta.ai

Meta's developer post on running Muse Glimmer on a single consumer GPU with vLLM, llama.cpp and ExecuTorch, with quantized builds in 24-32 GB and cookbook recipes.

Resource · Local & open models

Build with Muse Glimmer: local agents on one GPU