№ 0338GitHub
Muse Glimmer 30B MLX benchmark harness
A reproducible Apple Silicon harness that runs six fixed quality tasks against MLX quantizations of Muse Glimmer 30B and records scores, tokens per second, peak memory and load time.
Muse Glimmer 30B MLX benchmark
A reproducible Apple Silicon benchmark harness for Meta's Muse Glimmer 30B, ported from the Laguna S 2.1 harness. It runs the same six fixed quality tasks against MLX quantizations and records task scores, token throughput, peak MLX memory, load time, package versions, model revision, and machine metadata.
The harness loads Muse Glimmer through mlx-lm's custom-architecture path: the model ships a reviewed muse_glimmer_mlx.py loader (the same file the SGLang MLX backend maintains), loaded in-process. No server is required.
This work is sponsored by DWS LLC.
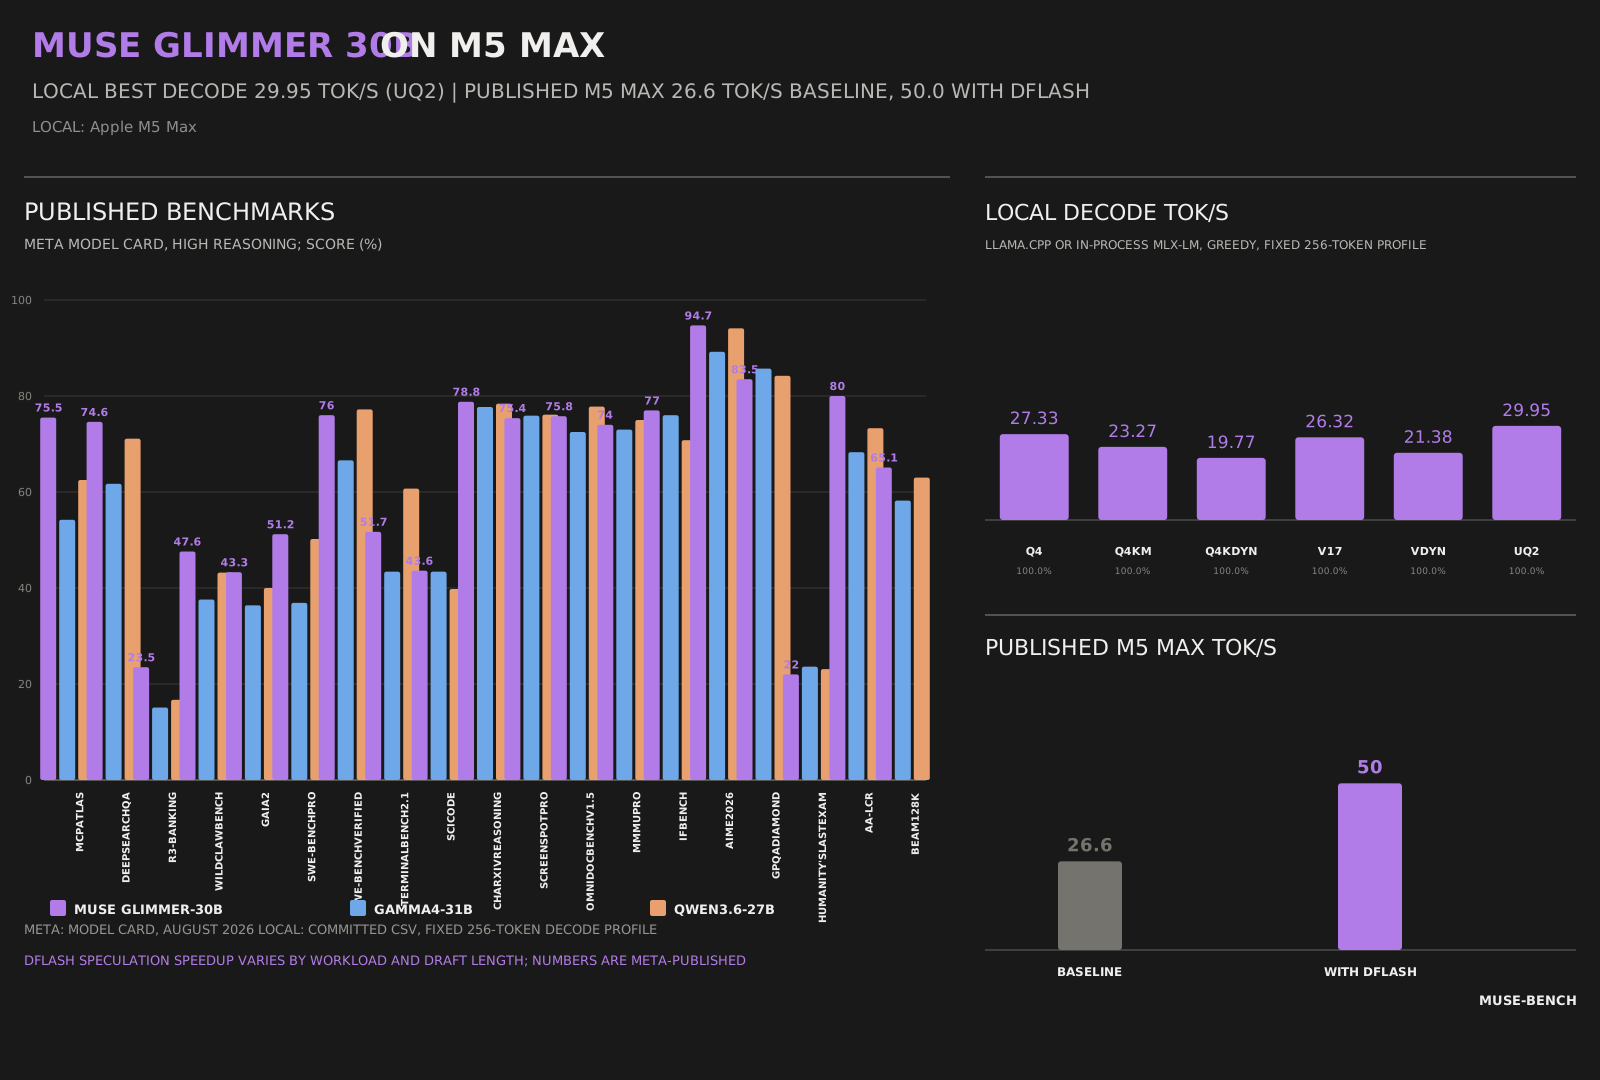
The left panel reproduces Muse Glimmer's published benchmark scores from Meta's model card. The right panels show locally measured in-process MLX decode throughput versus Meta's published M5 Max speeds with and without DFlash speculative decoding. Regenerate the SVG with:
uv run --frozen muse-bench chart
Results at a glance
Measured on a 128 GB Apple M5 Max (macOS 27.0, Python 3.13, MLX 0.32.0, MLX-LM 0.31.3) at --reasoning-strength low. Every tested quantization passed all 38 assertions; the table ranks by speed and memory.
| Quant | Runtime | Profile decode tok/s | Peak GB |
|---|---|---|---|
unsloth/Muse-Glimmer-30B-GGUF:UD-Q2_K_XL |
llama.cpp | 29.95 | 12.1 |
RadixArk/Muse-Glimmer-q4-MLX |
mlx-lm | 27.33 | 16.4 |
meta-models/Muse-Glimmer-30B-GGUF kquant-17gb |
llama.cpp | 26.32 | 16.1 |
RadixArk/Muse-Glimmer-q4km-gs128-MLX |
mlx-lm | 23.27 | 19.0 |
meta-models/Muse-Glimmer-30B-GGUF kquant-dynamic |
llama.cpp | 21.38 | 18.8 |
RadixArk/Muse-Glimmer-q4k-dynamic-MLX |
mlx-lm | 19.77 | 22.4 |
All six decode rates are close to Meta's published M5 Max baseline (26.6 tok/s, ExecuTorch); Meta's 50.2 tok/s with DFlash speculation needs a drafter-enabled runtime, which none of these bundles expose yet.
Reasoning-strength comparison on the q4 MLX build: low/medium/high all score 1.000 (38/38); high reasoning roughly triples agentic wall time. Details in BENCHMARK_RESULTS.md.
Clone and run
git clone git@github.com:tanishq-dubey/macos-muse-spark.git muse-bench
cd muse-bench
uv sync --extra dev --pyt