shipwithmuse

Entries matching “mlx”

19 builds · page 1 of 1

Paolo Rosson

@redp314

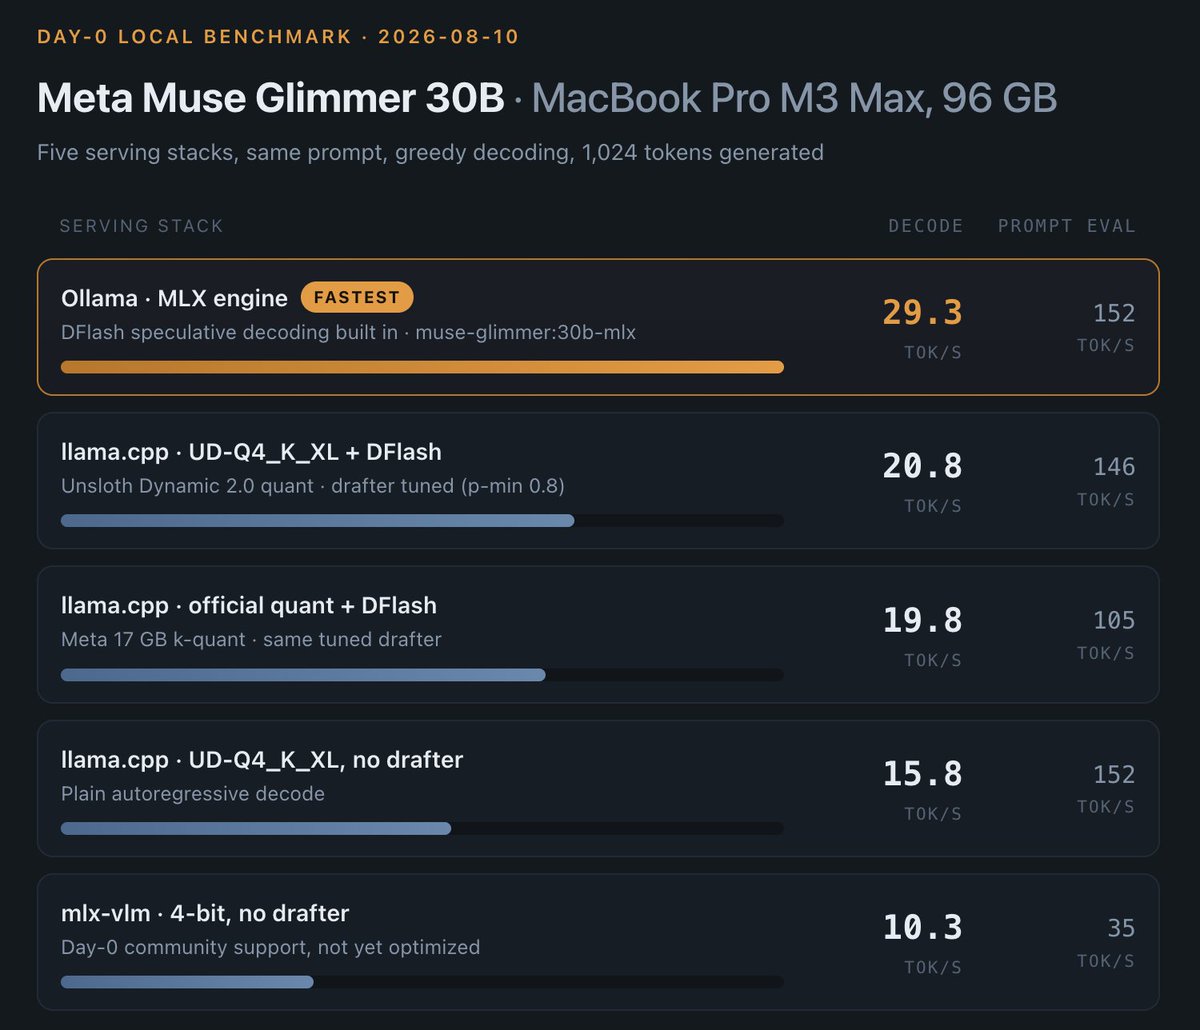
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're

X post · Local & open models★ Pick· ♥ 44

Glimmer serving shootout on an M3 Max

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

R

RadixArk

RadixArk

The smallest and fastest MLX 4-bit (group size 64) Muse Glimmer checkpoint, served with SGLang's MLX backend on Macs with 48 GB+ unified memory.

Resource · Local & open models· ♥ 11

Muse Glimmer MLX q4 for SGLang

@GordonWei

@GordonWei

An OpenAI-compatible /v1/chat/completions server that runs Muse Glimmer on Apple Silicon through mlx_vlm while LM Studio's bundled MLX runtime can't yet load the architecture.

GitHub · Local & open models

museglimmer-shim

ollama

@ollama

Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and

X post · Local & open models· ♥ 1.3K

Muse Glimmer on Ollama's MLX engine

@nicedreamzapp

@nicedreamzapp

An architecture port adding the muse_glimmer model class (vision tower, language model, projector and image processor) to mlx-vlm, so any Muse Glimmer checkpoint runs multimodally on Apple Silicon.

GitHub · Local & open models

mlx-vlm support for Muse Glimmer

U

divinetribe1

u/divinetribe1

muse glimmer dropped yesterday and mlx-lm couldn't load it yet, so i wrote the text model port and opened a PR. i checked it against meta's own transformers reference before posting, 5 out of 5 next token matches and 0.9965 logit cosine, so it's not just coherent it actually matches the reference. if you want to run glimmer on apple silicon right now the model file is in the PR. https://github.com/ml-explore/mlx-lm/pull/1710

Reddit post · Local & open models

Day-1 mlx-lm port for Muse Glimmer 30B

SGLang

@sgl_project

SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer. ~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX. Huge thanks to the NVIDIA and Meta teams for the

X post · Local & open models· ♥ 95

SGLang day-0 serving for Glimmer

LMSYS Org

@lmsysorg

@AIatMeta's Muse Glimmer (30B dense, open-weights) launches with SGLang day-0 support. We got ~230 tok/s on a single RTX 5090, with NVFP4 + DFlash on. It also works out of the box on @NVIDIAAIDev RTX Pro 6000, DGX Spark, and MLX for Mac. Speed and reliability have always been

X post · Local & open models· ♥ 129

SGLang serves Glimmer at ~230 tok/s on one RTX 5090

M

research.meta.ai

research.meta.ai

Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Introducing Muse Glimmer

U

A-Rahim

u/A-Rahim

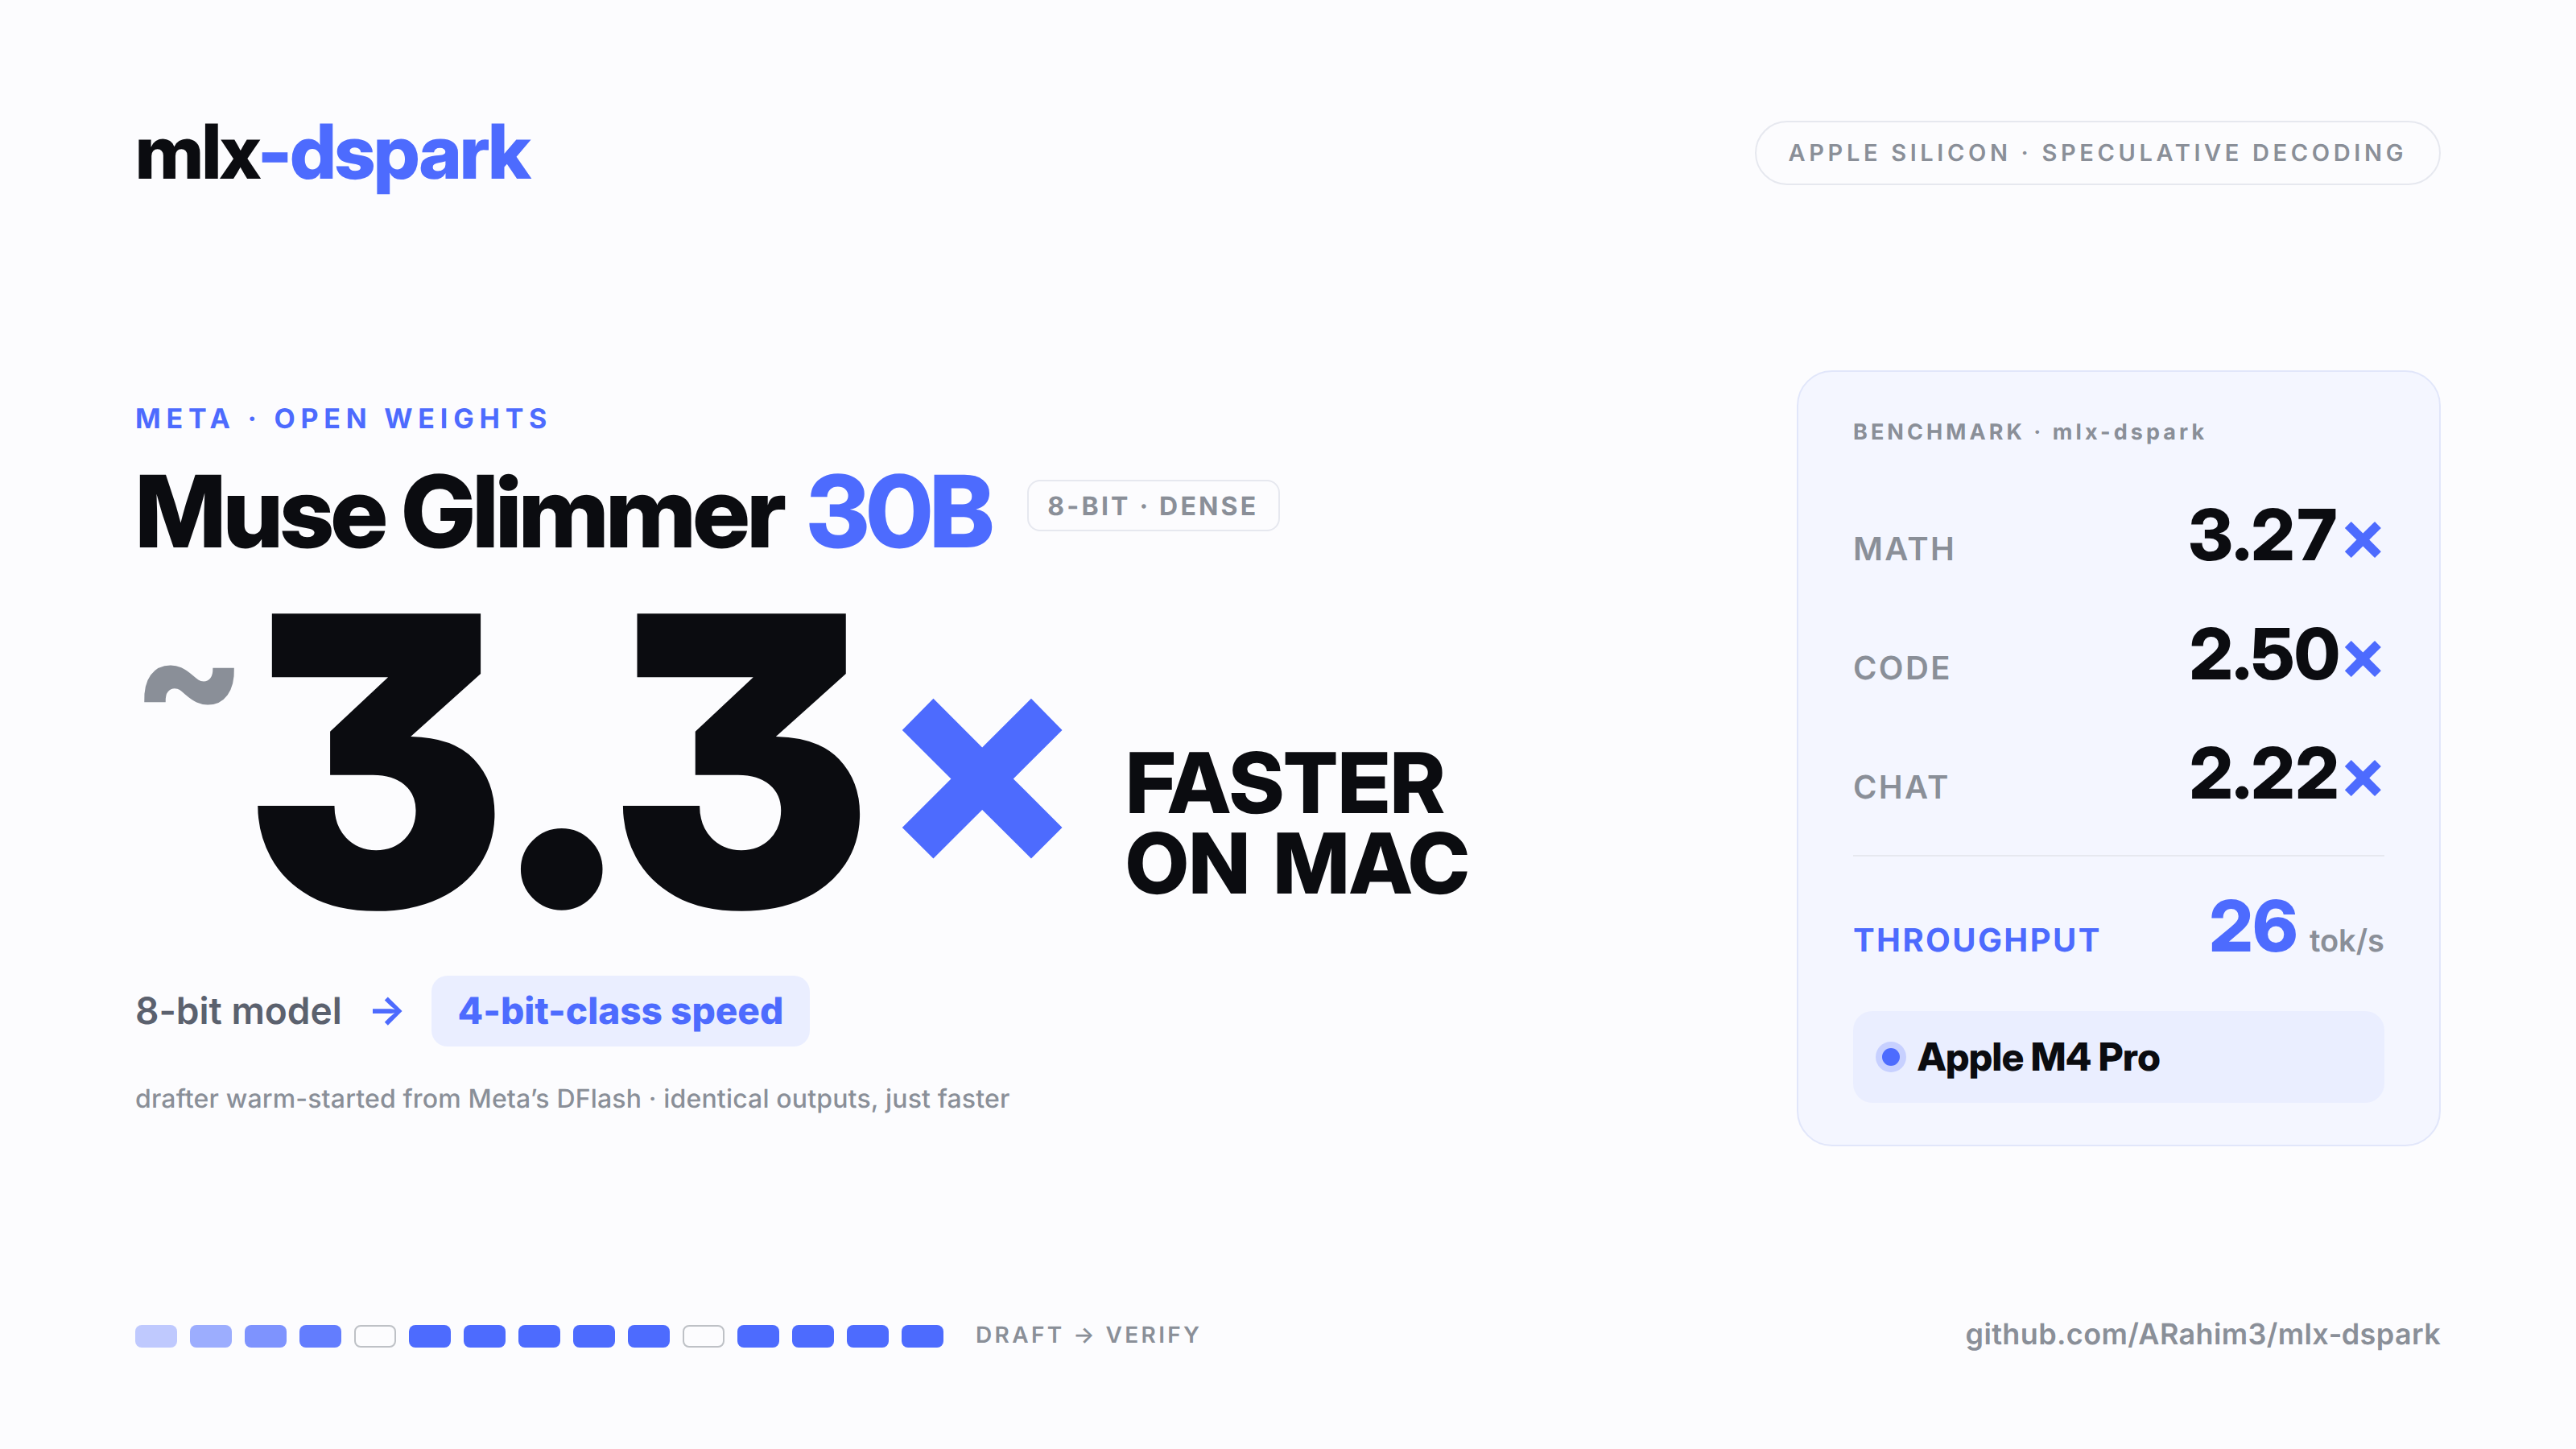
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster. Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed. Repo: github.com/ARahim3/mlx-dspark I'm happy to hear feedback, and I'm curious about what other M-series chips get.

Reddit post · Local & open models★ Pick

Muse Glimmer 3.3x faster on Mac with mlx-dspark

M

mlx-community

mlx-community

mlx-community's 4-bit MLX conversion of Muse Glimmer 30B made with mlx-vlm 0.6.12 for Apple Silicon.

Resource · Local & open models· ♥ 18

MLX 4-bit Muse Glimmer

@PipeNetwork

@PipeNetwork

muse-glimmer-mlx is an MLX port of Muse Glimmer 30B for Apple Silicon that supplies the missing runtime so the many unloadable MLX conversions published on Hugging Face can actually be run.

GitHub · Local & open models

MLX runtime for Muse Glimmer 30B

B

brenden7158

brenden7158

An unofficial parody MLX-VLM QLoRA adapter for Muse Glimmer 30B on Apple Silicon.

Resource · Local & open models· ♥ 1

ZuckLM parody MLX LoRA

@mapleroyal

@mapleroyal

A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.

GitHub · Local & open models

Muse Glimmer MLX playground

@tanishq-dubey

@tanishq-dubey

A reproducible Apple Silicon harness that runs six fixed quality tasks against MLX quantizations of Muse Glimmer 30B and records scores, tokens per second, peak memory and load time.

GitHub · Benchmarks & research

Muse Glimmer 30B MLX benchmark harness

@brn715

@brn715

A deliberately overengineered parody that 'gives you the Zuck', with a deterministic Oracle edition, a prompted Muse Glimmer edition and an MLX QLoRA fine-tune of Muse Glimmer 30B for Apple Silicon.

GitHub · Content & creative

ZuckLM

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Y

huggingface.co

huggingface.co

A prebuilt macOS arm64 bundle for the Muse Glimmer voice-agent recipe in meta-oss-cookbook: Parakeet speech helper, Muse Glimmer worker and Supertonic TTS executables built from one pinned ExecuTorch checkout, plus the shared MLX Metal library.

Resource · Local & open models

Muse Glimmer voice agent ExecuTorch runtime

O

ollama.com

ollama.com

Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.

Site · Local & open models

Muse Glimmer in the Ollama library