№ 0053GitHub
Muse Glimmer MLX playground
A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.
Muse Glimmer Playground
A local Muse Glimmer 30B vision-and-reasoning chat app tuned for a 128 GB Apple M5 Max. Inference runs through ExecuTorch, MLX/Metal, and DFlash on this Mac; the server listens only on 127.0.0.1, and conversations are not persisted to disk.
Quick start
Requirements:
- An Apple silicon Mac. This preset is sized for a high-memory M5 Max; other Macs are not tested.
- Xcode, Node.js 20.19+ or 22.12+, npm, an internet connection, and at least 30 GB of free disk space.
Download and unzip the repository, then run this from the project folder:
./setup.sh
Setup prepares a project-local Python environment, builds the pinned ExecuTorch MLX worker, downloads the approximately 21 GB model and vision data, builds the browser app, and creates Muse Glimmer.command locally. Downloads and completed build work are reused later.
After setup, double-click Muse Glimmer.command in Finder and keep its Terminal window open. The launcher starts the server at http://127.0.0.1:3939 and opens the app in the default browser. Press Control-C in that Terminal window to stop the server and release the model.
To preserve setup errors or launch without Finder, run:
./Muse\ Glimmer.command
Playground
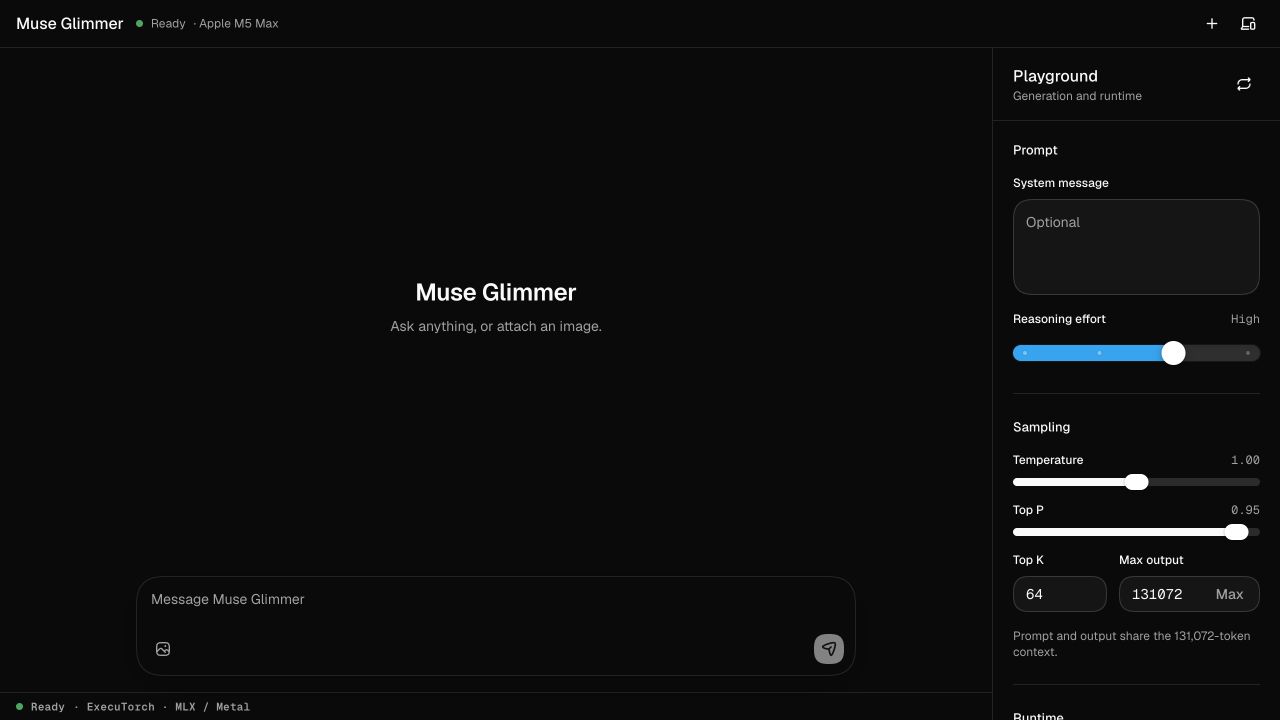
- Live answer streaming with Muse Glimmer's thinking shown separately in an automatic collapsible disclosure
- Text and vision chat; attach one PNG or JPEG of up to 20 MB per conversation
- Edit or copy any prompt or response, regenerate responses, and stop active generation
- Markdown, tables, task lists, code, and links in responses
- A four-stop reasoning-effort slider for Low, Medium, High, or XHigh
- Temperature, Top P, Top K, and maximum-output-token controls
- Light, system, and dark themes with desktop and mobile layouts
- Time to first token, duration, throughput, thinking/output/input token usage, context usage, and runtime details
The recommended defaults are temperature 1.0, Top P 0.95, Top K 64, High reasoning effort, and the full 131,072-token output ceiling. Prompt and output share that context window: before generation, the server subtracts the rendered prompt and gives the model the exact remaining room. The Max shortcut restores the full ceiling. Editing an earlier turn replaces that point in the conversation and remove




