Standalone packaging of the vision tower and projector extracted from Muse Glimmer 30B.
Resource · Local & open models· ♥ 2
15 builds · page 1 of 1
Standalone packaging of the vision tower and projector extracted from Muse Glimmer 30B.
Resource · Local & open models· ♥ 2
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

チャエン | デジライズ CEO《重要AIニュースを毎日最速で発信⚡️》
@masahirochaen
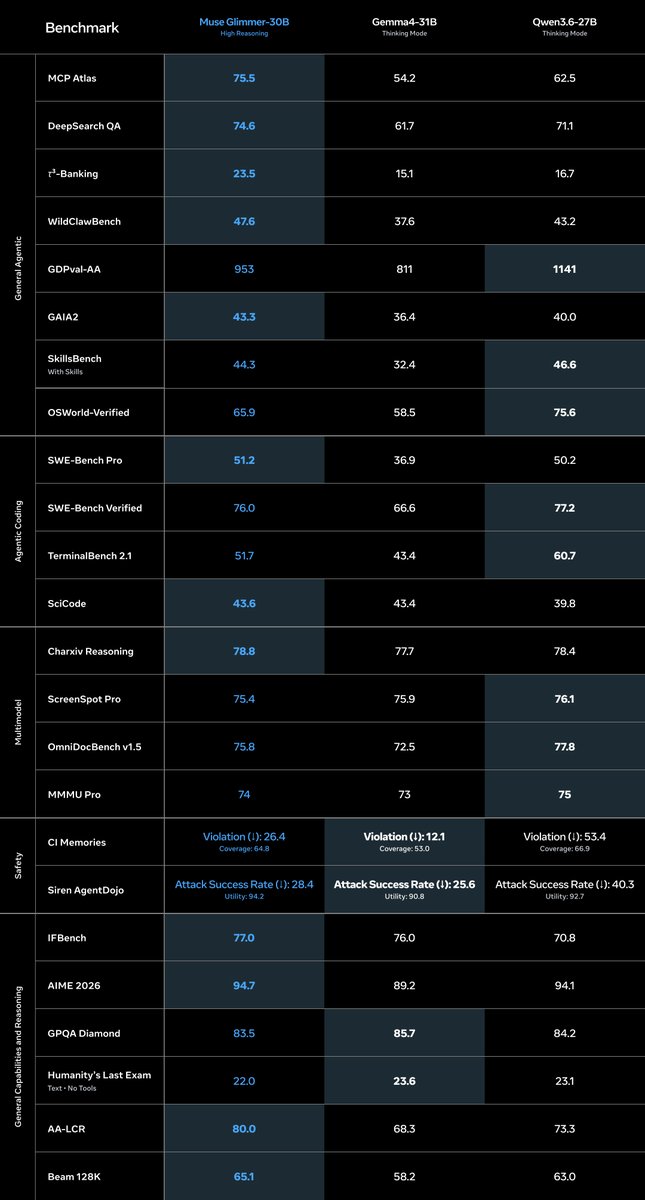
【速報】Metaが30BのオープンモデルMuse Glimmerを公開。18GBのRAMで動く。 久々のMetaからの本格オープンモデル。 小型なので低スペックのPCでも動かせるAIモデル。 ・Apache 2.0で商用利用可、重みはHugging Faceで公開 ・画像も読めるvisionモデル、100言語超に対応 ・MCP Atlas
X post · Benchmarks & research· ♥ 96

elie
@eliebakouch
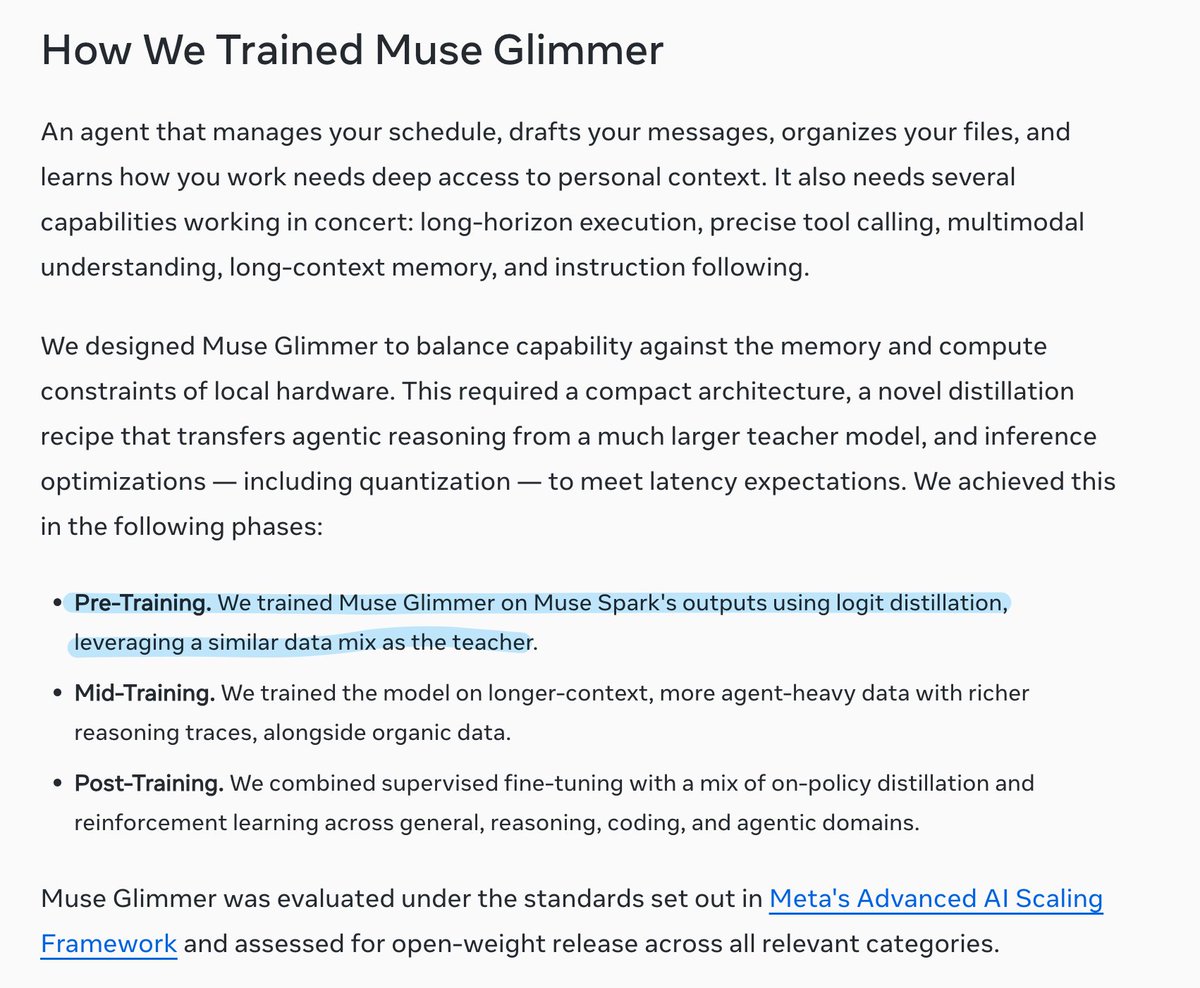
extremely exciting to see meta getting back into open weight models with a 30B dense first, and soon muse spark 1.2 they used knowledge distillation from muse spark, architecture wise it's similar to gemma 4 (which is llama 3 + swa (again!) + vision encoder), with scale free QK
X post · Benchmarks & research· ♥ 464
A pinned llama.cpp recipe for Muse Glimmer 30B on one NVIDIA GB10 that verifies Meta's official GGUFs by SHA-256 and reproduces text, tool-call, coding, vision and throughput checks.
GitHub · Local & open models· ★ 1
A llama.cpp container that serves Muse Glimmer 30B with vision and DFlash on an RTX 5090, reporting 98.8 tok/s single-stream and about 250 tok/s aggregate with 131k context.
GitHub · Local & open models

atomic.chat
@atomic_chat_hq
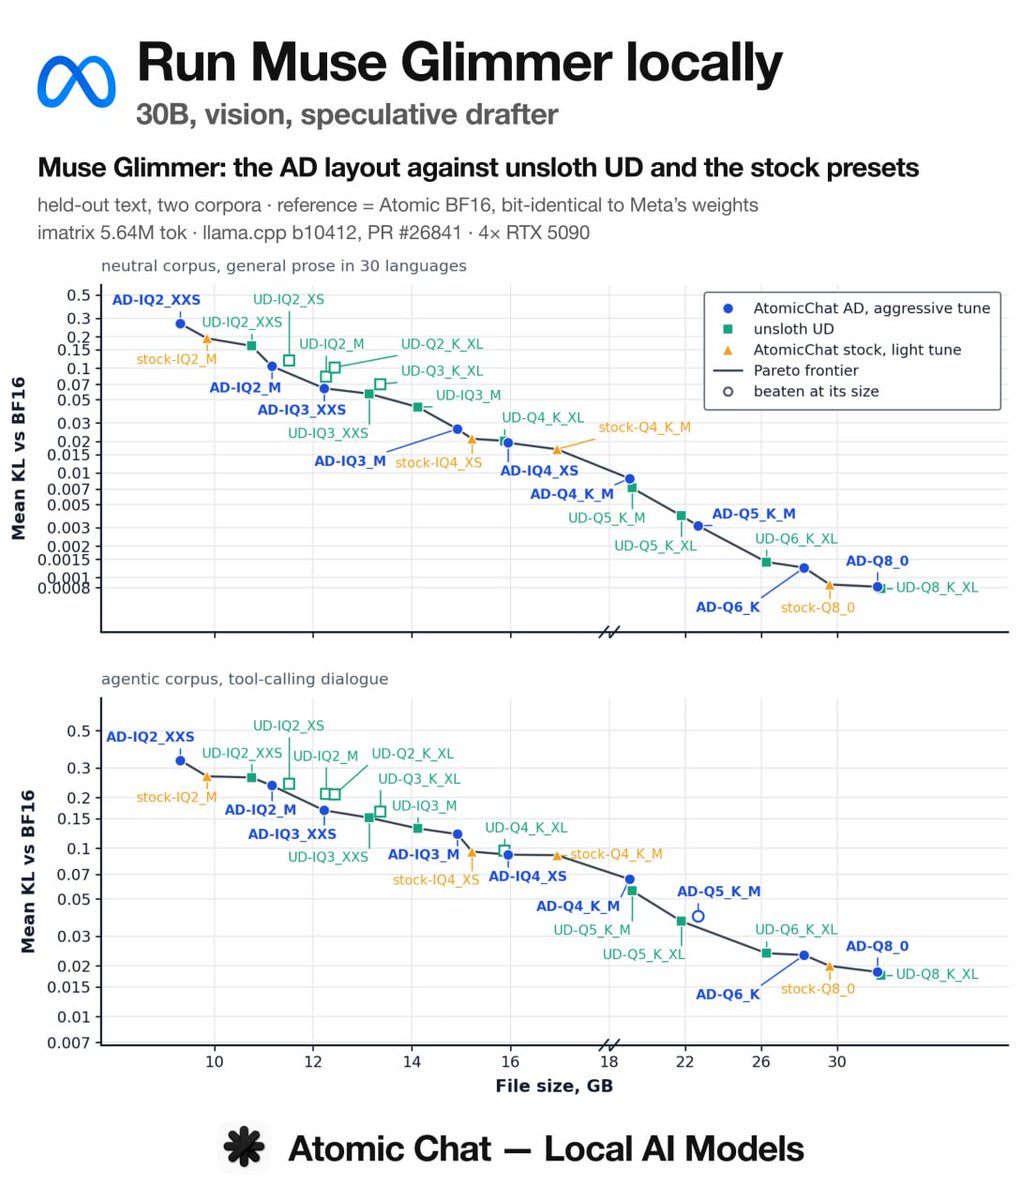
Run Meta's new Muse Glimmer 30B♾locally with 16GB VRAM! We ship our own GGUF quants. AD-IQ3_XXS does 62 tokens/s on a single RTX 4080 with vision and DFlash, and picks the same next token as the BF16 original 90% of the time! Run the model via Atomic Chat
X post · Local & open models· ♥ 59
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Glimmer HD Vision is an OpenAI-compatible proxy that keeps images within Muse Glimmer 30B's 4,096 visual-token limit by sending a 4K image as one overview plus four overlapping detail tiles, with an OCR/layout mode.
GitHub · Local & open models

vLLM
@vllm_project
@Meta is back in open source. Excited to announce Day-0 vLLM support for Muse Glimmer 30B, the first open-weights model from Meta Superintelligence Labs — which ships under Apache 2.0!!! 30B dense, 128K+ context, multimodal, built for local agents. Capable enough for
X post · Local & open models· ♥ 251
A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.
GitHub · Local & open models
Same old prompt, just appended a TIP in the end: "Write a single HTML file with a full-page canvas and no libraries. Simulate a realistic side-view of a moving car as the main subject. Keep the car visible in the foreground while the background landscape scrolls continuously to create the feeling that the car is driving forward. Use layered scenery for depth: nearby ground, roadside elements, trees, poles, and distant hills or mountains should move at different speeds for a natural parallax effect. Animate the wheels spinning realistically and add subtle body motion so the car feels connected to the road. Let the environment pass smoothly behind it, with repeating but varied scenery that makes the movement feel believable. Use cinematic lighting and a cohesive sky, such as sunset, dusk, or daylight, to enhance atmosphere. The overall motion should feel calm, immersive, and realistic, with a seamless looping animation. TIPS: You don't have vision abilities so don't try it yourself. If you feel in need of vision ability, you can access http://xxx:8080/v1, model id: Muse-Glimmer for help, it will see the picture, and describe it for you." Then the PI agent started spinning, round a
Reddit post · Agents & automation
An architecture port adding the muse_glimmer model class (vision tower, language model, projector and image processor) to mlx-vlm, so any Muse Glimmer checkpoint runs multimodally on Apple Silicon.
GitHub · Local & open models
Scripts that run Muse-Glimmer-30B with vision and tool calling on a 32GB M2 MacBook Pro via llama.cpp and Metal, without admin or sudo access, pulling Meta's official GGUFs.
GitHub · Local & open models· ★ 1
A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.
GitHub · Local & open models
A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.
GitHub · Local & open models· ★ 8
Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.
Site · Local & open models


 ChatForm
 Tgmlabs