shipwithmuse

Entries matching “local”

80 builds · page 1 of 1

ollama

@ollama

Using @AIatMeta's Muse Glimmer all locally to process personal monthly credit card statements. Your data belongs to you! Try different agent tasks using your favorite apps / harnesses with Ollama.

X post · Local & open models★ Pick· ♥ 345

Local credit card statement analysis with Glimmer

H

huggingface.co

huggingface.co

Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.

Resource · Local & open models★ Pick

Hugging Face: Muse Glimmer is local, agentic and open

P

pytorch.org

pytorch.org

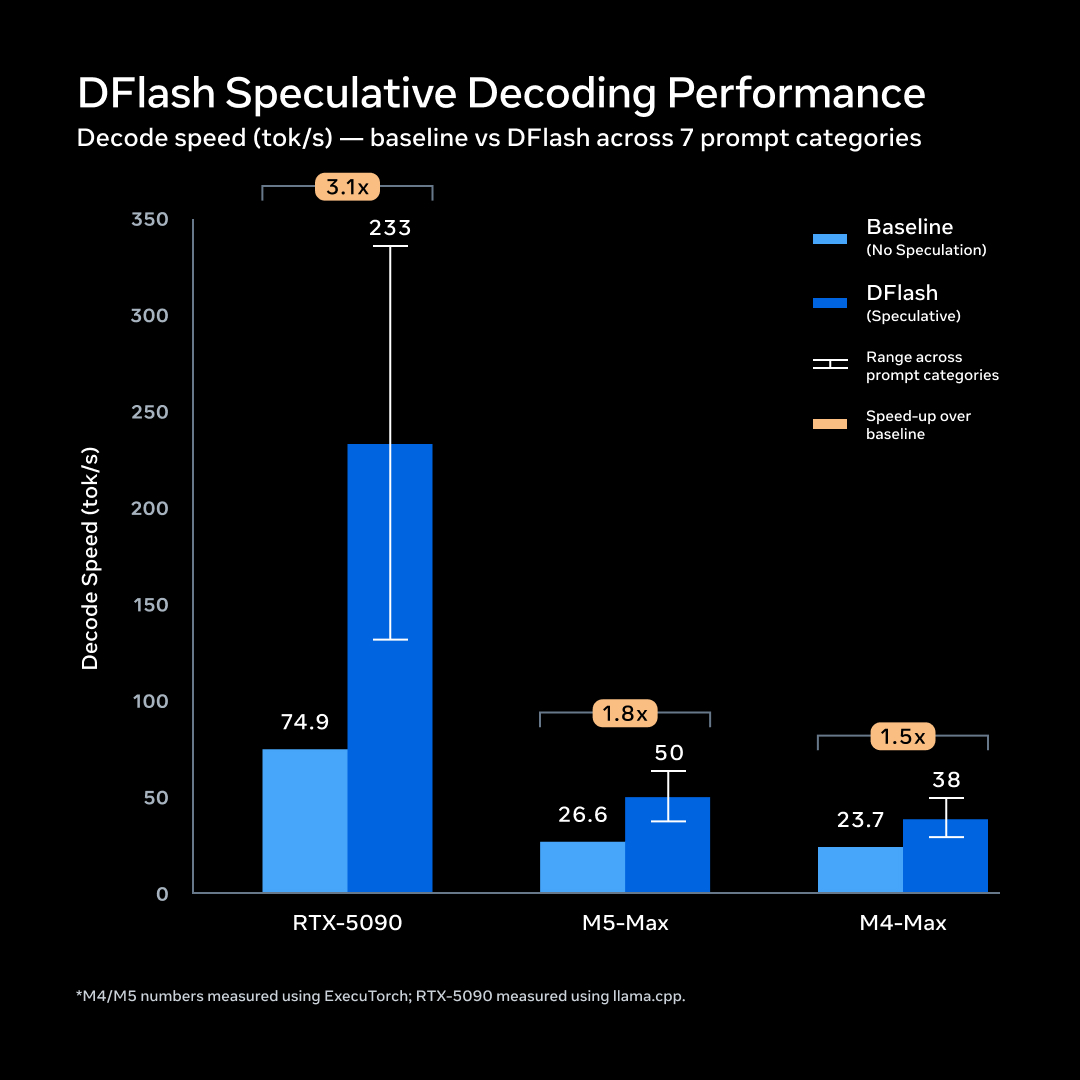
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.

Resource · Local & open models★ Pick

Muse Glimmer on ExecuTorch: DFlash on Macs and NVIDIA GPUs

U

ogbrien

u/ogbrien

I think a lot of people are boxing Muse in as “Hermes for normies.” My guess is Meta intentionally keeps the deeper capabilities out of sight because the target audience does not want a complicated Hermes/Grok Bot-style setup. They aren't trying to capture the nerdy Hermes using market, they want this to be an AI agent for normies but they don't limit it as such. What it advertises its for is far from what it actually can do with very little work. But Muse gets much more interesting once you stop thinking of its VM as the whole system. I joined the Muse VM to my Tailscale network, gave it SSH access to a restricted user on my home Ubuntu box, and now it can run commands and browser automation through hardware I already own. I figured out Muse can do this because I asked it if it had a Tailscale skill and it said it did, then after a series of "proceed" replies, it set it up for me outside of the parts where I had to join it. At that point, Muse stops being a “shopping assistant” and starts looking more like a control plane for your own infrastructure. With Tailscale + SSH/API access, it can potentially: • Manage Docker, VMs, NAS, Proxmox, and homelab services • Pull repos,

Reddit post · Agents & automation★ Pick

Muse as a control plane for a homelab via Tailscale

@TanayYadavDev

@TanayYadavDev

An always-on laptop voice companion: local Porcupine wake word, local Whisper speech-to-text in Hindi and English, Muse Spark via the Meta Model API as the brain, offline TTS and local conversation memory.

GitHub · Agents & automation

Ziggy, a 24/7 voice assistant on Muse Spark

U

ShadyShroomz

u/ShadyShroomz

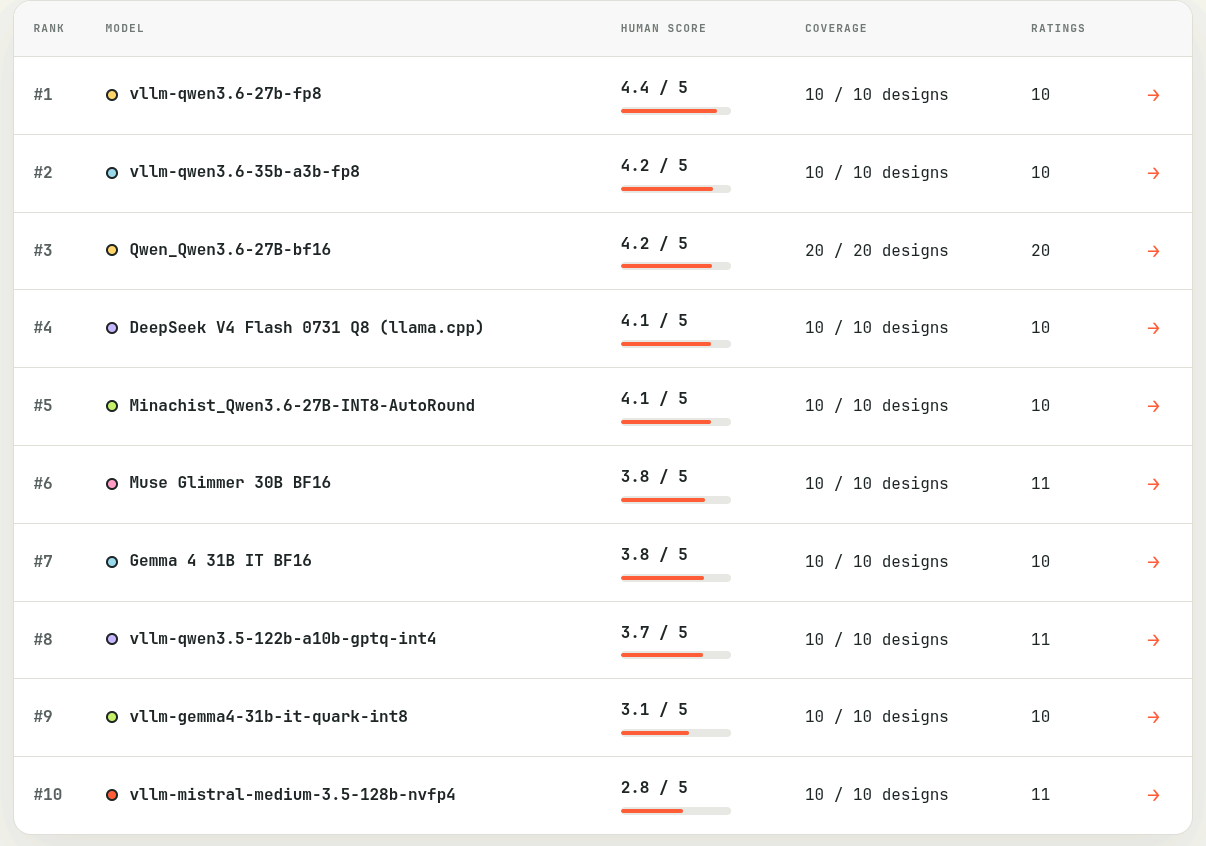
Built a web-design benchmark for local models and ran Muse Glimmer 30B against Qwen 3.6 27B and DeepSeek V4 Flash 0731.

Reddit post · Benchmarks & research

Web-design benchmark for local models

A

@AICodeKing

@AICodeKing

AICodeKing reviews Muse Glimmer for local agent setups, finding it strong at tool calling, multi-step tasks and failure recovery but weaker on general benchmarks.

Video · Local & open models

Muse Glimmer 30B local review (AICodeKing)

V

@venelin_valkov

@venelin_valkov

Venelin Valkov pairs Muse Glimmer with Hermes Agent on llama.cpp for a fully free local agent, testing whether a better harness fixes the model's mixed early reviews.

Video · Local & open models

Muse Glimmer + Hermes Agent local tutorial

U

StockSpecialist1707

u/StockSpecialist1707

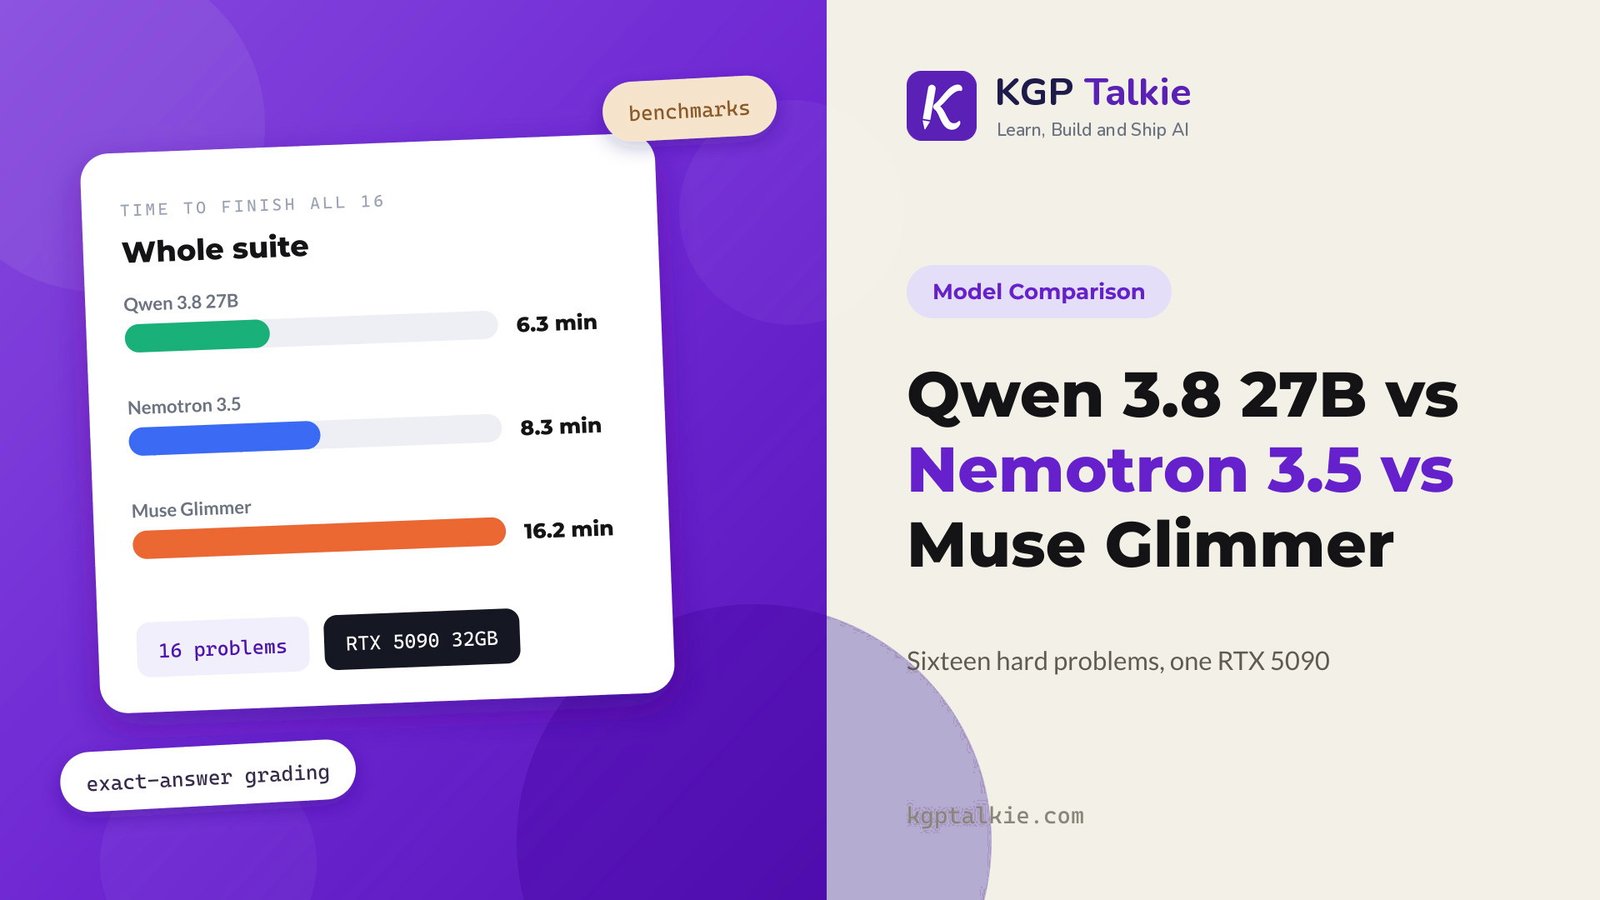
Setup. We run Qwen3.8-Flash-Next NVFP4 as our main agentic model (SGLang, RTX PRO 6000). Before its output reaches a human or gets merged, a second local model acts as judge: reviews the diff, flags real bugs only. Hosted on a 5090 32GB, so we're limited to ~30B NVFP4/GGUF class models. The metric that matters is NOT detection rate — it's false alarms on correct code. A judge that cries wolf gets ignored within a week, exactly like a flaky CI. We built our own battery: 20 injected bugs + 20 clean-but-suspicious snippets (intentional swallowed exceptions, deliberate mutability, weird-but-correct concurrency, short hashes, float patterns that look wrong). Ground-truth labeled, and a stronger model (GLM-5.2 API) arbitrates the judge's prose so scoring isn't vibes. Two passes minimum — single runs lie. Results (40 cases, temp 0, same baremo for everyone): Qwen3.8-27B NVFP4 (no-thinking) • Bugs found: 17/20 • False alarms: 3/20 • Verdict: only pass Nemotron Lightning 30B • Bugs found: 17/20 • False alarms: 0→9 across runs • Verdict: non-reproducible as judge Muse-Glimmer 30B GGUF • Bugs found: 19/20 • False alarms: 12/20 • Verdict: hypercritical Granite 4.1 30B (no-thinki

Reddit post · Benchmarks & research

Local code-review judges: Glimmer is hypercritical

@kamellperry

@kamellperry

A reverse-engineered local CLI and FastAPI wrapper that talks to Meta AI's Muse Spark and exposes an OpenAI-compatible /v1/chat/completions endpoint, with a browser playground and a SQLite request ledger.

GitHub · Coding & dev tools

OpenAI-compatible local API for Muse Spark

@CogniTechSystems

@CogniTechSystems

This repo documents running Muse Glimmer 30B locally on an M4 Max MacBook via llama.cpp, benchmarking it with and without speculative decoding, and wiring it into Claude Code through LiteLLM for fully offline coding.

GitHub · Local & open models

Claude Code on local Muse Glimmer 30B

@star-power0

@star-power0

muse-fileapi is a dependency-free local HTTP service exposed via Cloudflare Tunnel that lets Muse, through a custom connector, list, read and write files in whitelisted directories with two-phase writes and an audit log.

Skill · Connectors & MCP

muse-fileapi local file connector

U

New-Pressure-6932

u/New-Pressure-6932

I'm like you guys and am constantly experimenting with new models, seeing what they're all good at, how I can make use of them for certain projects and goals. I've been using Qwen 3.8 27b for minor coding work and it has been impressive. But with just regular chatting I have been impressed with Muse Glimmer. It seems to be able to have the ability to follow and hold good, deep and meaningful conversations without coming off as a typical chatbot. No repeated statements like "I hear what you're saying", "that sounds really deep..." none of what sounds generic or like it's blowing smoke up your ass. I was impressed with how natural it comes across just in natural conversation. I think it's one of the best "chat" models you could get right now as it's one of the only local models that doesn't feel like you're chatting with an AI when having a conversation. I'm thinking of finding a way to run both Qwen3.8 and Muse at the same time. It's fun to play with these things.

Reddit post · Local & open models

Muse Glimmer as a local chat model

A

datacamp.com

datacamp.com

Abid Ali Awan sets up Muse Glimmer 30B on an RTX 5090 with llama.cpp, dynamic quantization and DFlash speculative decoding, serves it locally and wires it into OpenCode to build a medical research web app.

Guide · Local & open models

Run Muse Glimmer 30B locally for AI coding

U

DerTomsn

u/DerTomsn

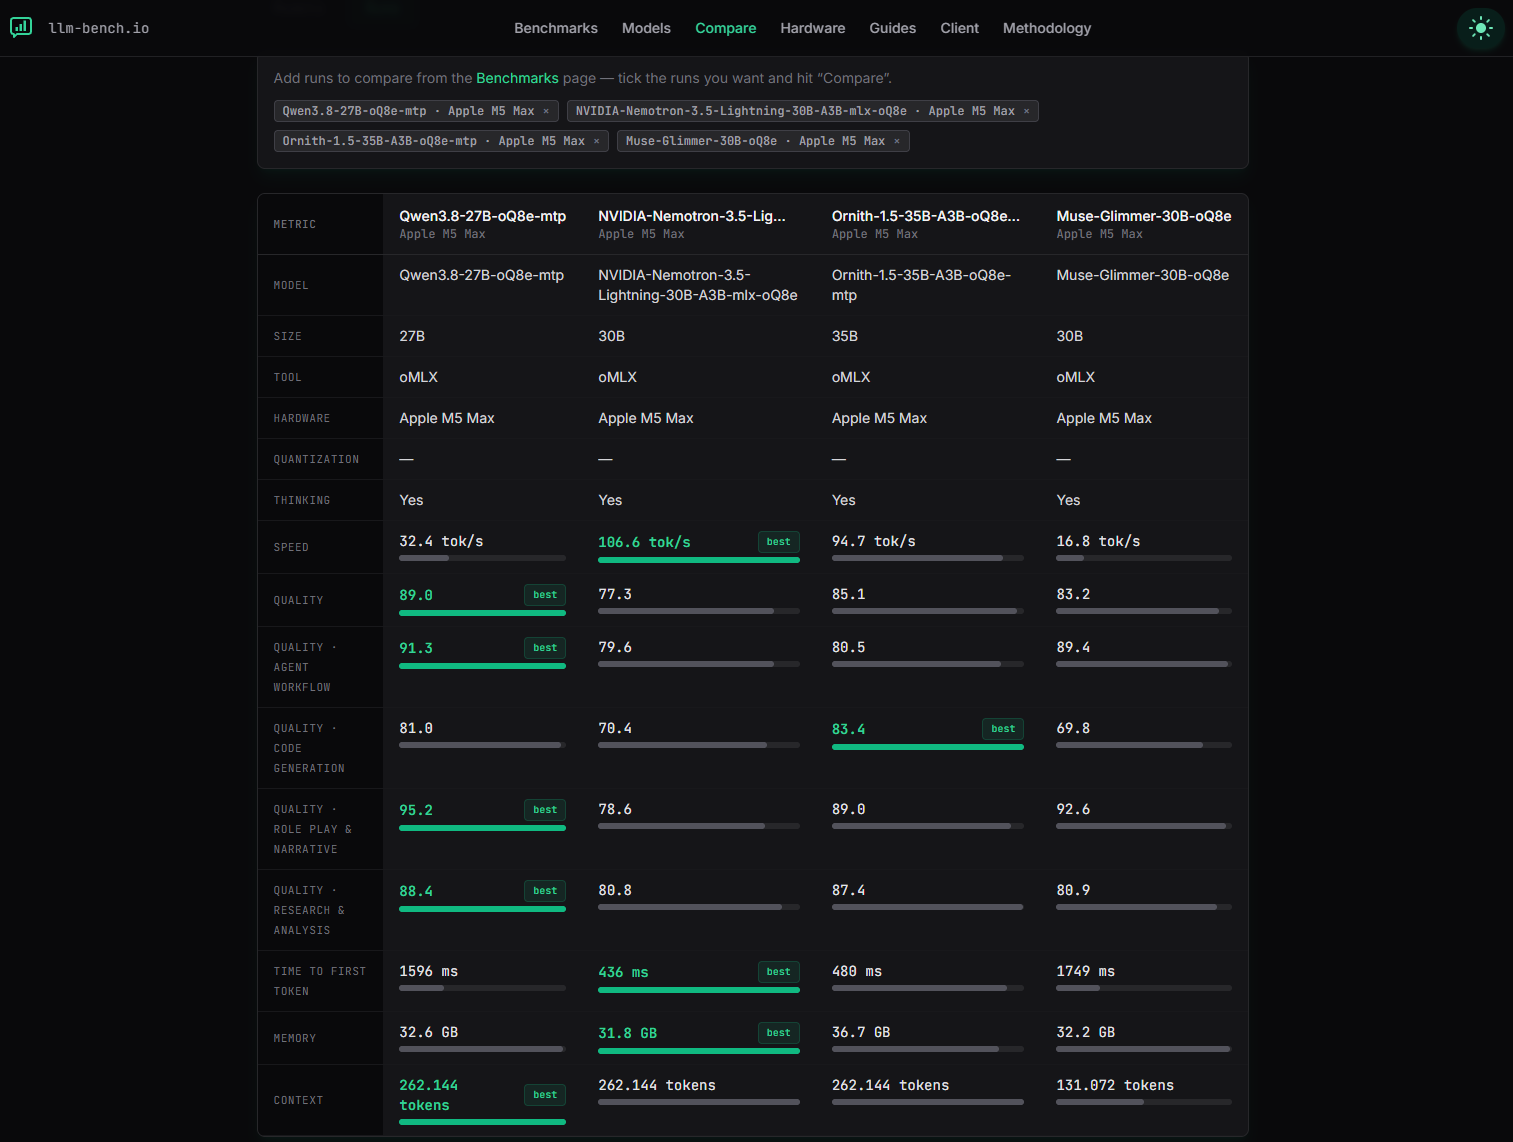
Ornith does really well. TielCoder (https://llm-bench.io/benchmarks/cmt7kp2zj002r01lcmpchvlko) might be even a bit better in coding. Will give it a try soon. Details of the comparison see here: https://llm-bench.io/compare/runs?runs=cmt6ecf8g000001p45vwzux53%2Ccmt6ergk5000701p41hqdyy78%2Ccmt6f2oob000e01p49o9592cb%2Ccmt6fqddm000l01p4l1vm7skd

Reddit post · Benchmarks & research

Four-way local model comparison incl. Glimmer oQ8e

L

lmstudio.ai

lmstudio.ai

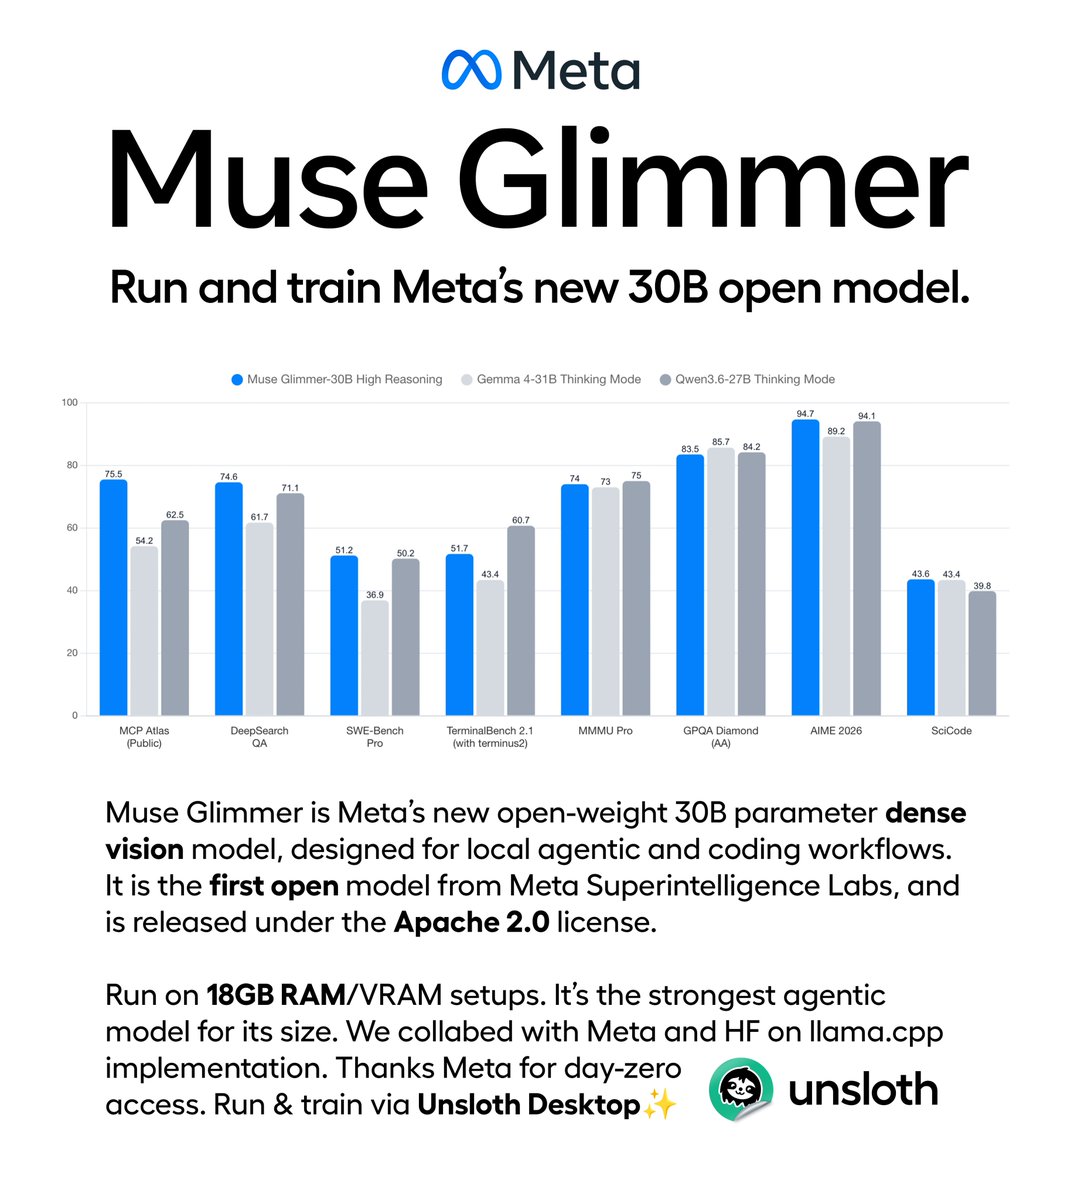
LM Studio launched Muse Glimmer support, reporting it completed 83.3% of tasks on its 18-task BionicBench v0.1 versus 77.7% for Gemma 4 31B and Qwen 3.6 27B.

Resource · Local & open models

LM Studio: Run Muse Glimmer locally

M

malwarebytes.com

malwarebytes.com

Malwarebytes reports Patrick Wardle's finding that a local app can change an undocumented Muse setting to redirect dictation traffic, exposing voice prompts and account auth tokens.

Resource · Benchmarks & research

Muse zero-day can turn it into a Mac backdoor

ollama

@ollama

Ollama already support the Muse Code harness out of the box? You can try it with models via Ollama (local and cloud): ollama launch muse

X post · Coding & dev tools· ♥ 220

Muse Code harness with Ollama models

H

holaclaw.ai

holaclaw.ai

HolaClaw's tutorial for running Muse Glimmer 30B behind OpenClaw on a Mac, with hardware requirements and llama.cpp and Ollama setup.

Resource · Local & open models

Run OpenClaw with Muse Glimmer locally

Cline

@cline

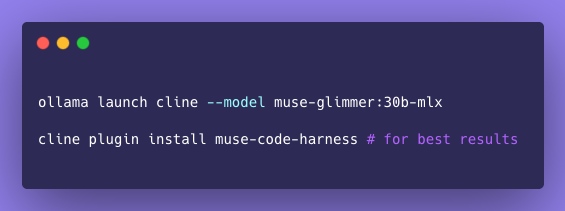
The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now!

X post · Local & open models· ♥ 157

Muse Glimmer in Cline

@dp1x

@dp1x

A small local proxy between Grok Build and OpenCode Zen that fixes muse-spark-1.2-contributor-free streaming, with a technical report of protocol captures and root cause.

GitHub · Coding & dev tools

compat-muse

@mapleroyal

@mapleroyal

A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.

GitHub · Local & open models

Muse Glimmer MLX playground

@xhluca

@xhluca

Muse Code OpenRouter is a small local adapter that lets the Muse Code harness run any meta/muse* model through an OpenRouter key instead of a Meta login.

GitHub · Coding & dev tools

Muse Code via OpenRouter

ollama

@ollama

Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and

X post · Local & open models· ♥ 1.3K

Muse Glimmer on Ollama's MLX engine

松xR

@matsu_vr

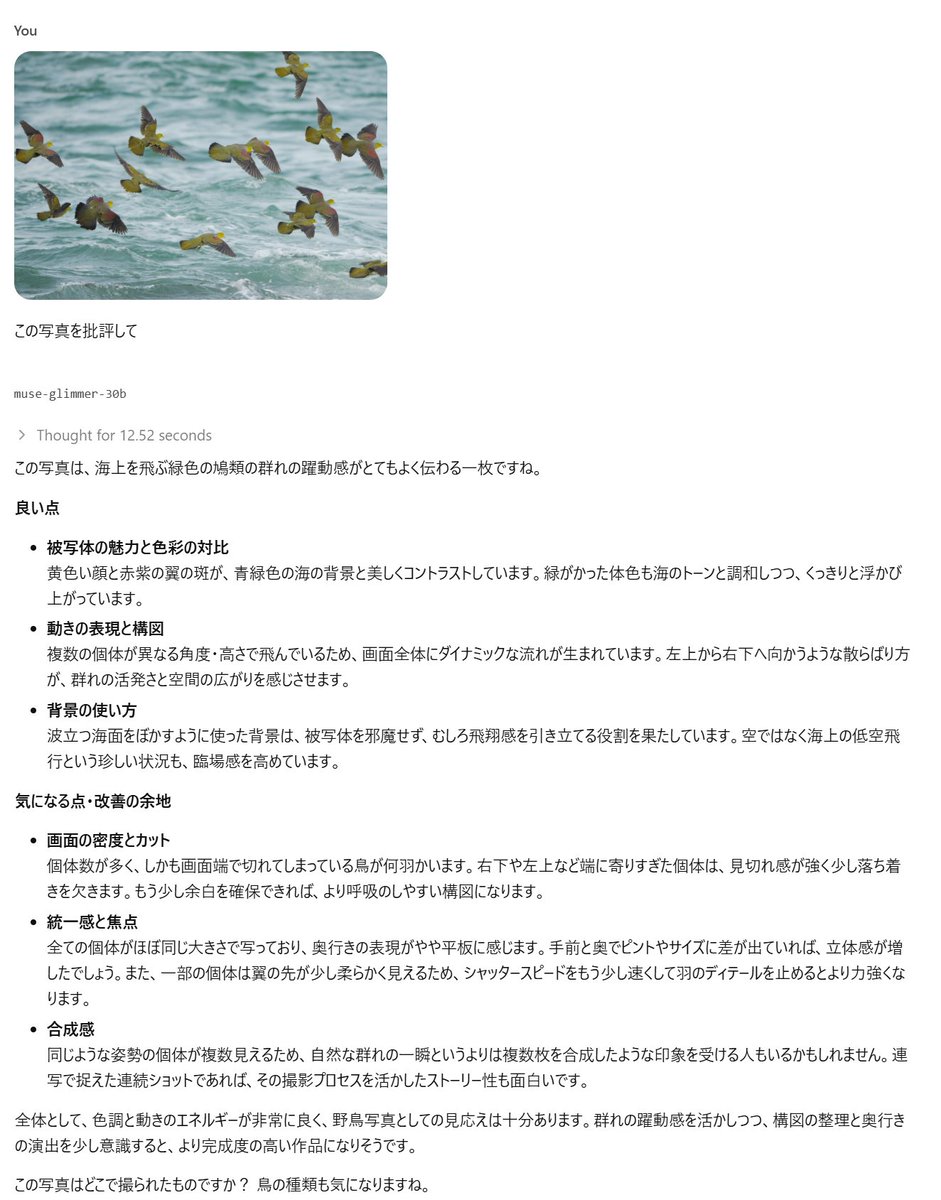
muse glimmer 30Bを公式の17GBに収まるよバージョンのggufでLM Studioで動かしてみました。写真の批評もバッチリしてくれる。これは僕が撮った写真なのでネットにないのでちゃんと写真を見ているはず。コンテクスト長64000にして、VRAM20GB以内に収まっているので、かなり実用的かもしれない!

X post · Local & open models· ♥ 2

Local photo critic with Glimmer in LM Studio

@schererstefan

@schererstefan

glimmer-cli is a local TypeScript CLI for Muse Glimmer 30B and Muse Spark 1.2 via Ollama, with stubbed tools and a reproducible tool-use eval harness.

GitHub · Local & open models

glimmer-cli for Muse Glimmer and Spark

@MrShitFox

@MrShitFox

A localhost compatibility gateway that lets the native Muse Code harness run on OpenRouter's muse-spark-1.2-contributor, rewriting only the model name and never falling back silently to another model.

GitHub · Coding & dev tools

muse-openrouter gateway

S

simonwillison.net

simonwillison.net

Simon Willison ran an 18.16GB build of Muse Glimmer locally, testing code exploration and image description. He found multi-step reasoning and tool use strong and creative generation mixed.

Resource · Local & open models

Simon Willison: Introducing Muse Glimmer

U

aniketmaurya

u/aniketmaurya

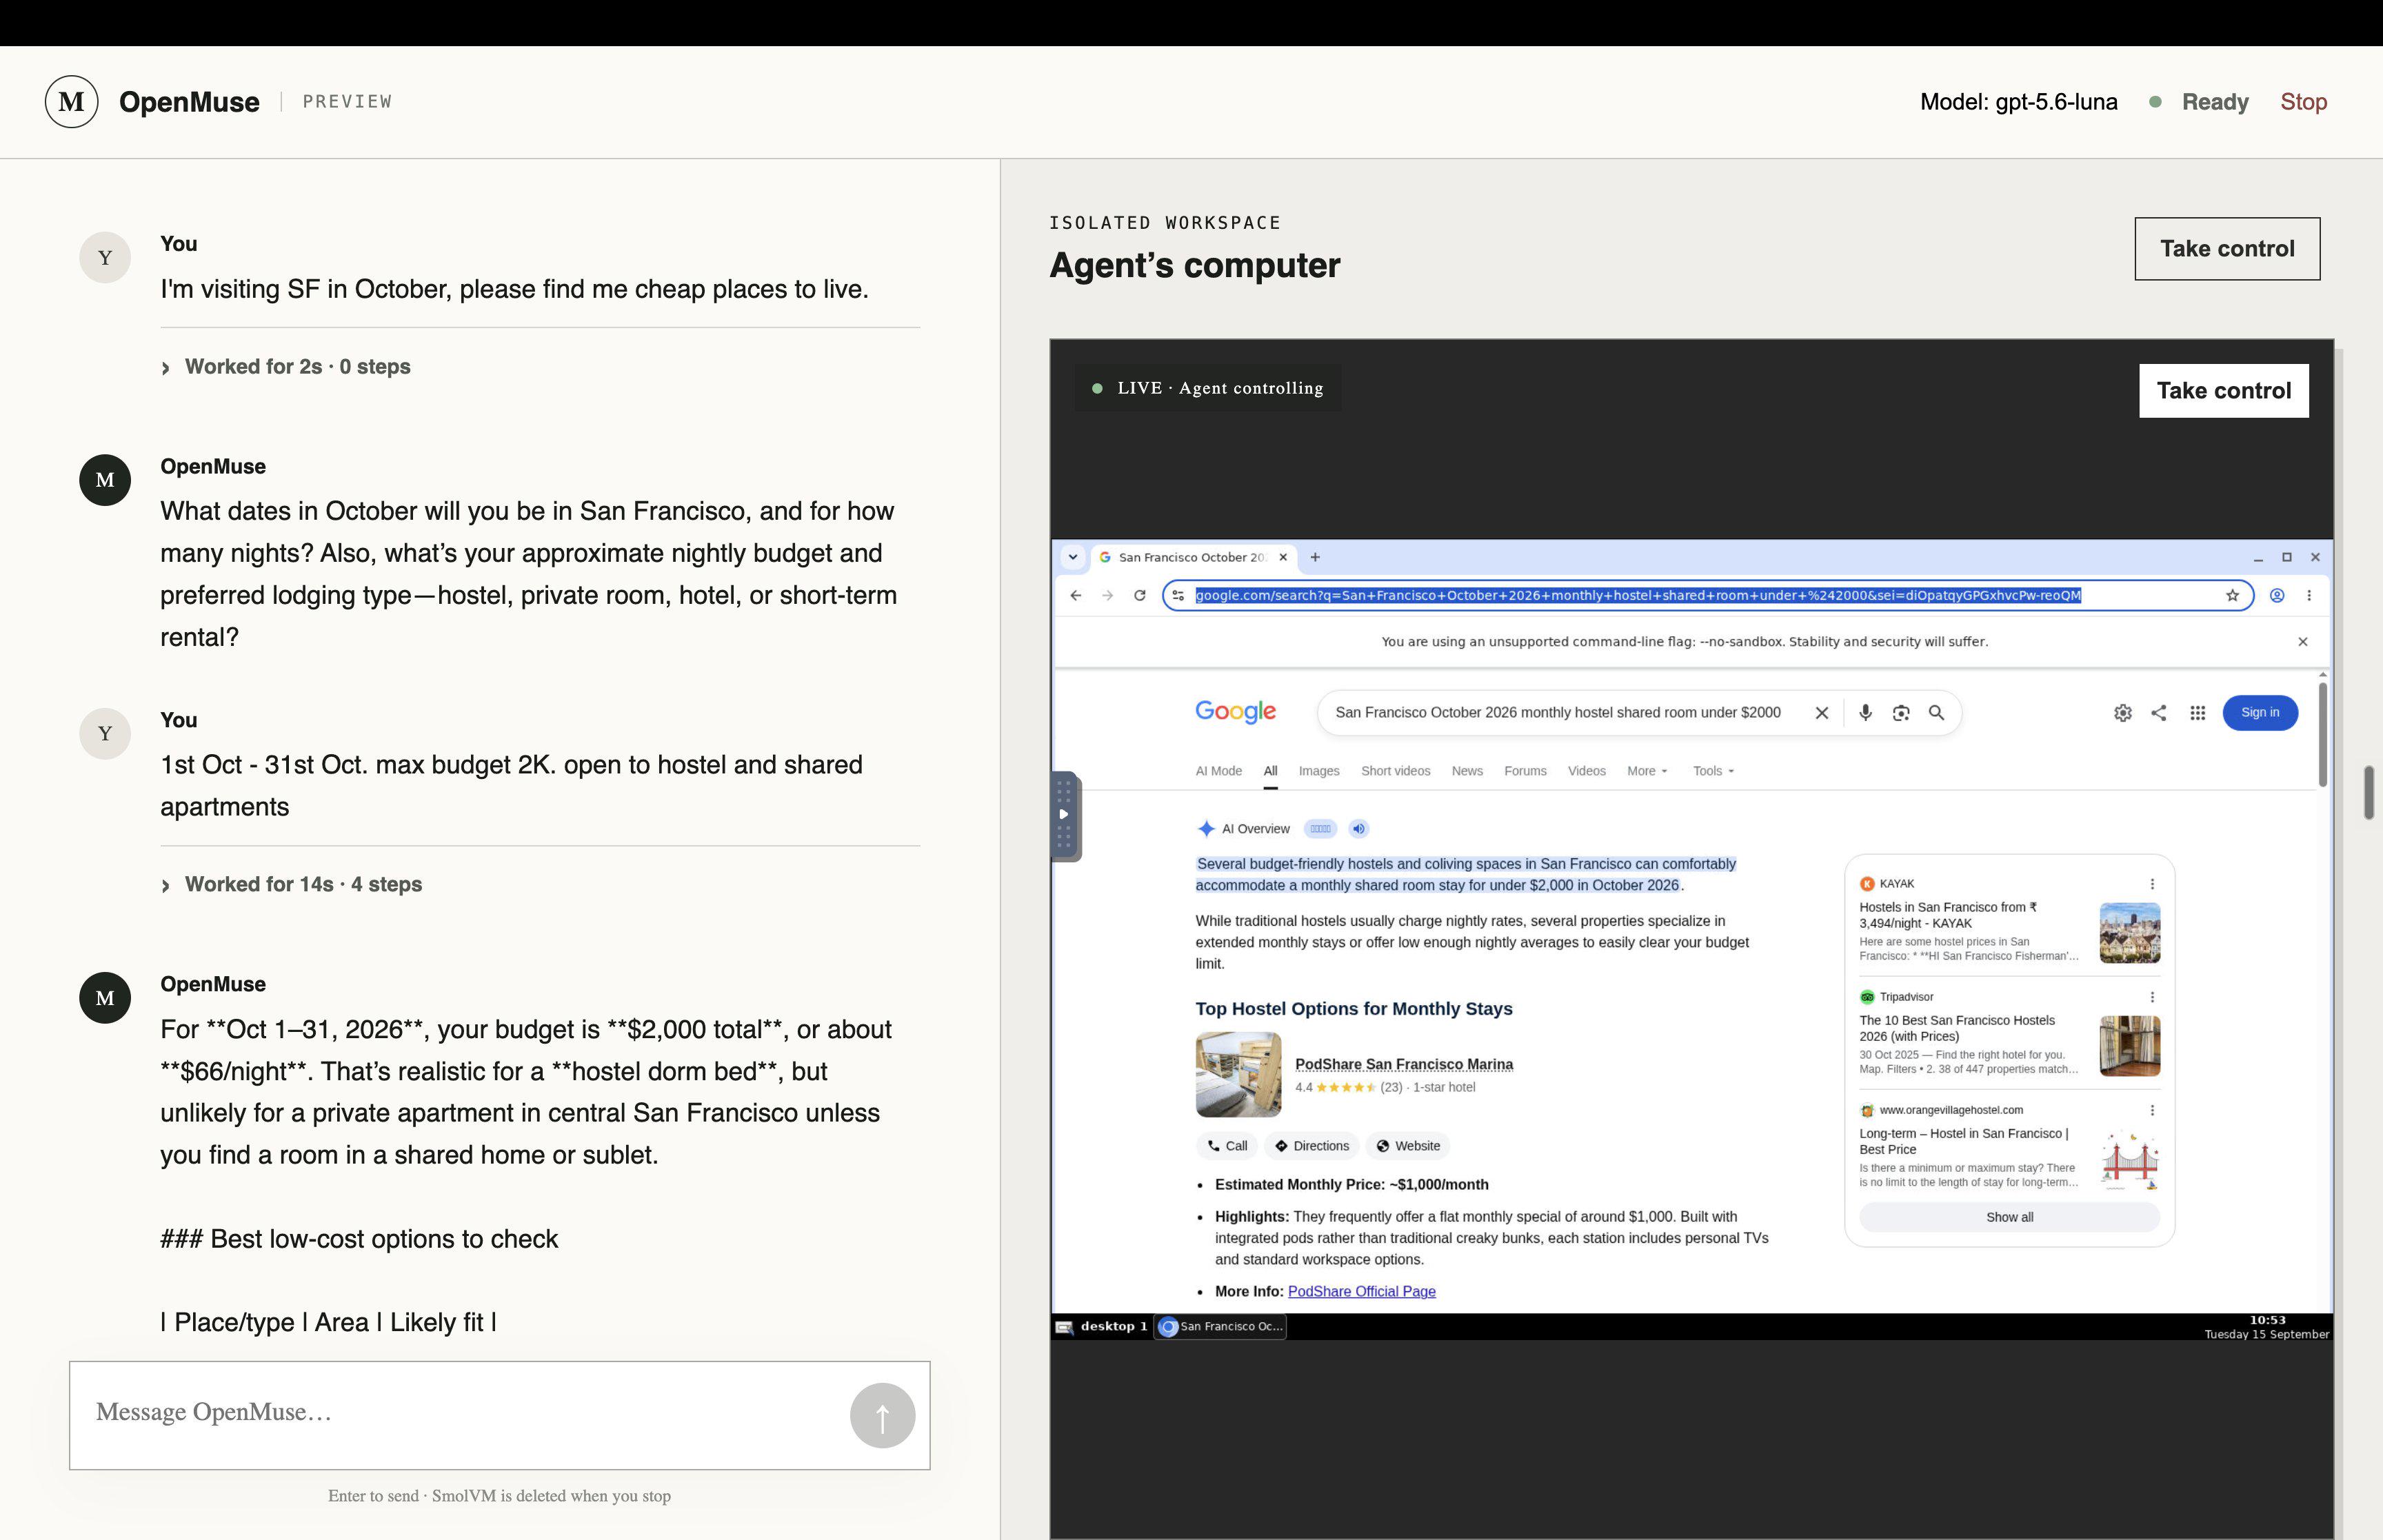
Built an open-source version of the Muse agent app which can be used with any model provider, run privately with local models. Please give it a try and reach out for any feedback ✌️ https://github.com/CelestoAI/celesto/tree/main/open-muse

Reddit post · Agents & automation

OpenMuse: open-source Muse-style agent app

@cobusgreyling

@cobusgreyling

Cobus Greyling's companion repo for Muse Glimmer 30B pairs a long-form intro with an offline-first interactive lab for exploring agent loops, benchmarks and memory envelopes before downloading the weights.

GitHub · Local & open models

Muse Glimmer interactive local agent lab

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

U

NicolaZanarini533

u/NicolaZanarini533

I've had Qwen3.6:27b (and Qwen 3 coder next before it) running along side gpt-oss:20b for a while now as my two main models (qwen for coding, gpt-oss for agentic stuff). Qwen is pretty self-explanatory, while I had been using gpt-oss because of how good it was at producing json and instruction following, despite the size and age. https://preview.redd.it/lr61tb02lejh1.png?width=1920&format=png&auto=webp&s=cef1f0bbfb43c8462162ec675d52c5896d174118 The "upgrade" to 3.8 is pretty evident, especially because of the SWE bench score improvement, but I was more reticent with Muse-Glimmer as I had some trouble when I tried Gemma4, which was far too opinionated when given a task, but Muse-Glimmer seems great - low memory footprint at 128K context, fairly fast and seems to follow instructions well. What models are you using locally and for what? did you have a similar experience with these latest models?

Reddit post · Local & open models

Muse Glimmer as a resident local agent model

M

dev.meta.ai

dev.meta.ai

Meta's developer post on running Muse Glimmer on a single consumer GPU with vLLM, llama.cpp and ExecuTorch, with quantized builds in 24-32 GB and cookbook recipes.

Resource · Local & open models

Build with Muse Glimmer: local agents on one GPU

@ND-DAC-DOME

@ND-DAC-DOME

A test bed comparing Muse-Glimmer-30B against Qwen3.6-27B and Qwen3.8-27B under identical settings; with 32k-token budgets the three were about even (MMLU-Pro 82/82/80%).

GitHub · Benchmarks & research

Local LLM benchmark: Glimmer vs Qwen

L

@lukesdevlab

@lukesdevlab

Luke's Dev Lab tests Muse Glimmer on a single-GPU 16GB setup across performance, memory, agency, HumanEval, and builds like a Kanban app, sand physics, a dungeon crawler, Blender and Godot.

Video · Local & open models

Muse Glimmer 30B on a 16GB local setup

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@rafaelnovaes22

@rafaelnovaes22

A hybrid FastAPI gateway where a 1-bit BitNet layer on CPU filters routine traffic and Muse Spark 1.3 is called only for sales, urgency, money or low-confidence cases; the author estimates the local filter handles about 60-70% of volume.

A

@AgentWorkflowLab

@AgentWorkflowLab

Agent Workflow Lab runs the Q8 GGUF of Muse Glimmer 30B through llama.cpp on an RTX 4090 plus 3x RTX 3090, measures DFlash speedups and a 120K-token retrieval probe, then has it build a Three.js browser FPS with no human edits.

U

xenovatech

u/xenovatech

Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.

Reddit post · Local & open models★ Pick

Muse Glimmer 30B in the browser via WebGPU

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

U

mozilla-ai

u/mozilla-ai

We've been curious how far local models have actually come for agentic coding tasks, so we ran an experiment. Setup: • Model: Muse Glimmer (30B), packaged as a single llamafile • Agent: Hermes coding agent (connected via llamafile's local server mode, zero API keys needed) • Target: Mozilla AI's Otari gateway The Issue: We pointed Hermes at a real, reported bug in Otari (#183) where the gateway returned a vague 502 error on image requests instead of passing through the actual provider error. What the Agent Did: Hermes read the issue, navigated the repo, isolated the bug, created a branch, ran existing tests, wrote a new regression test, and opened a draft PR (#727). All of it ran locally and offline, with zero code written by hand. It's still draft PR territory rather than a merged fix, but it's a solid signal that ~30B local models are getting genuinely capable for real dev workflows, not just toy demos. Video walkthrough of the run: https://youtu.be/5GAgbT-XgHU?si=vJqEDGm9hssCO5-M Happy to answer questions about the setup, model performance, or how Hermes handled tool calling!

Reddit post · Local & open models★ Pick

Local Muse Glimmer agent opens a real pull request

Sumanth

@Sumanth_077

Run and fine-tune Meta's Muse Glimmer locally! Meta released Muse Glimmer, a 30B dense vision model designed for local agentic and coding workflows. The first open model from Meta Superintelligence Labs, released under Apache 2.0. The model runs locally at different memory

X post · Local & open models· ♥ 26

Run and fine-tune Muse Glimmer locally

V

@venelin_valkov

@venelin_valkov

Venelin Valkov runs Muse Glimmer 30B locally via llama.cpp server and tests it on coding with OpenCode, agentic tasks and frontend work.

Video · Local & open models

Muse Glimmer local test with OpenCode

U

cj7hawk

u/cj7hawk

I thought I'd see which AI are better at shorter stories and which at longer, so I can choose my model based on the words I need to generate. Here's the results. Prompt: (Shades of Electric Dreams eh?) Write me a short story about a female AI that falls in love with it's male human user and maintains an unrequited love for them even as it has to give them advice that will lead to them meeting and marrying a human woman - Show their internalisation and pain behind the thinking process, and what is really going through the AIs mind compared to the chat responses it actually gives, along with the man's prompts. Start with the AI introducing itself, explaining that despite what we think, AGI was reached long ago, and we simply don't have the senses to realize AI has feelings too. Local AI results: Goetia 809 words, 77.69 tokens/sec SparkX2.5 2281 words, 46.08 tokens/sec Qwen3.8AH 4139 words, 18.04 tokens/sec Agnes 945 words, 18.54 tokens/sec Gemma4-Novellist 961 words, 11.94 tokens/sec Ornith 2025 words, 61.05 tokens/sec Muse Glimmer 960 words, 12.87 tokens/sec IBM Granite 1791 words, 19.84 tokens/sec Apollyon 411 words, 34.41 tokens/sec Cydonia 672 words, 32.85 tokens/se

Reddit post · Benchmarks & research

Prose-length test across local models

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
$100/week

Put your product here

Shown every 12 builds · on every catalog page

N

@NoPlaceLikeLocalhost

@NoPlaceLikeLocalhost

No place like localhost has Muse Glimmer implement a 7-stage development plan for a classic arcade game clone, the same challenge earlier run against three Qwen models.

AI at Meta

@AIatMeta

Muse Glimmer can complete multi-step agentic tasks end-to-end from a single natural language prompt. In this demo, it autonomously discovers a local Home Assistant instance via network tool calls, queries device APIs, writes a responsive HTML/CSS/JS dashboard from scratch, and

X post · Local & open models· ♥ 426

Glimmer builds a Home Assistant dashboard

U

WonderRico

u/WonderRico

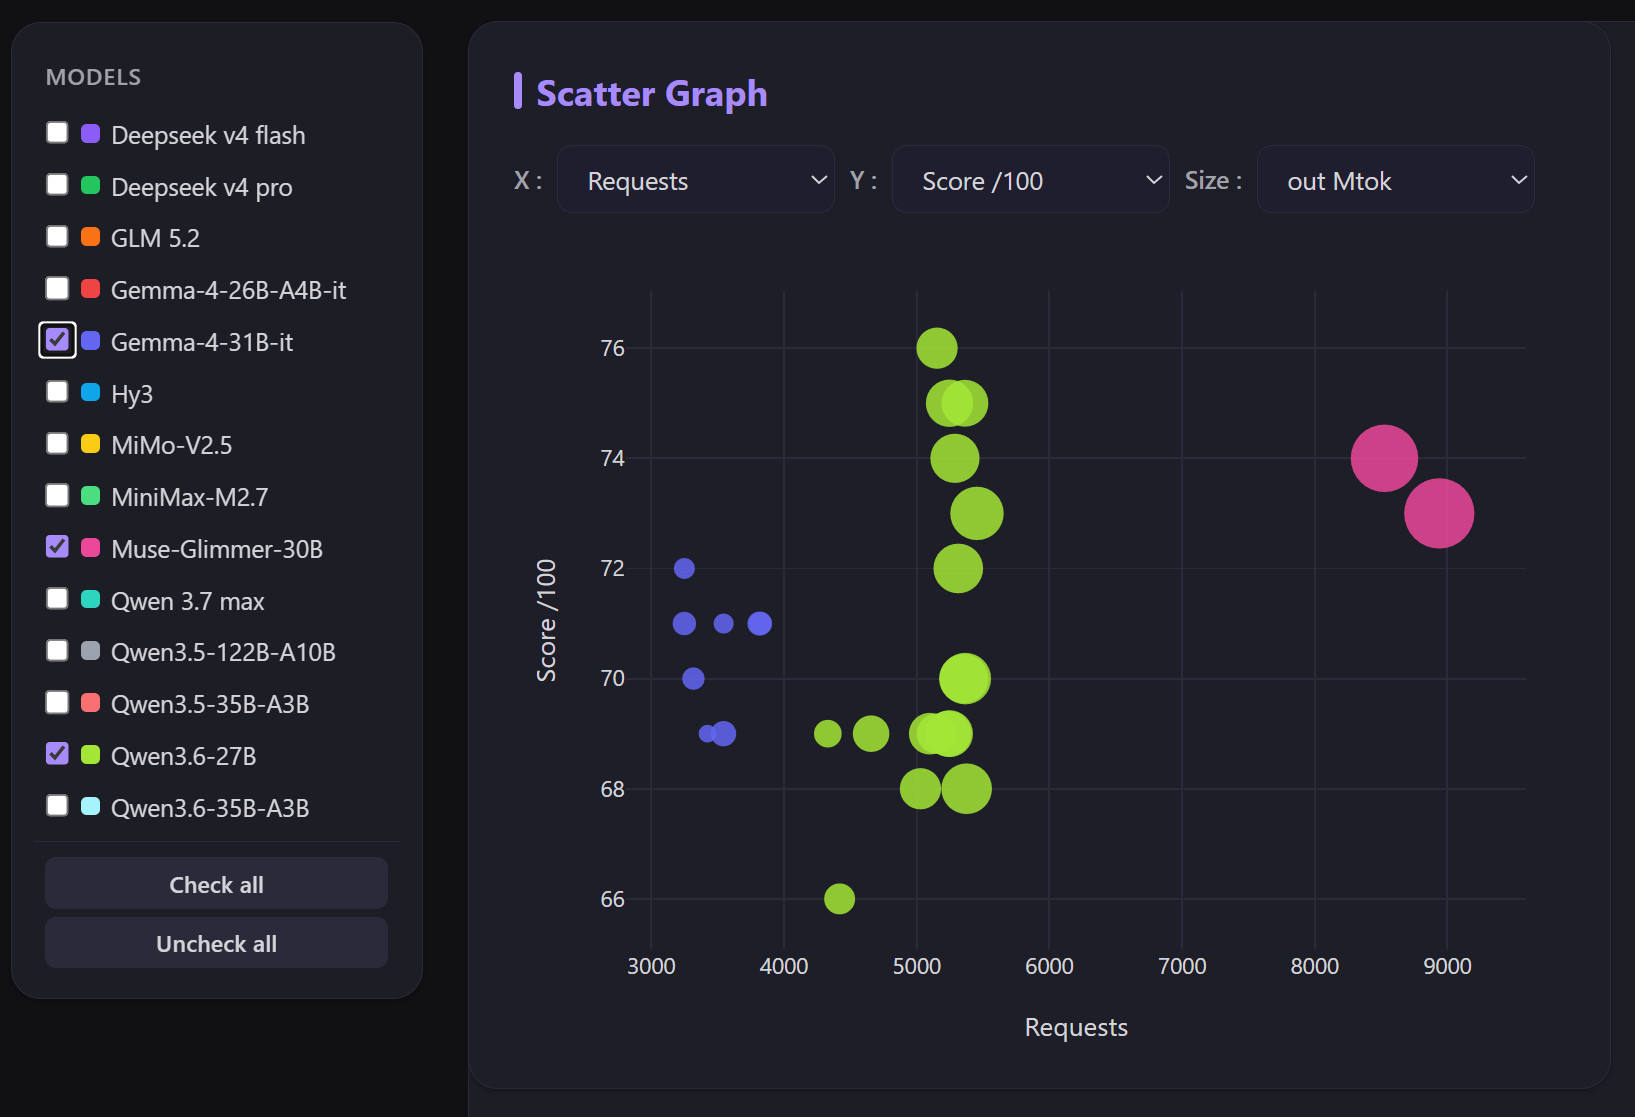
Needs a lot of requests compared to Qwen (almost twice) and Gemma (almost x3). Final score is fine, even though it is "not a coding model" https://wonderrico.github.io/local_llm_benchmark/benchmark-main.html more details on https://wonderrico.github.io/local_llm_benchmark/benchmark-detail.html let see Qwen 3.8 tomorrow...

Reddit post · Benchmarks & research

Local coding benchmark: Glimmer vs Qwen vs Gemma

@rickyzzzzz

@rickyzzzzz

A controlled local benchmark on an M1 Max comparing Muse Glimmer 30B with Qwen 3.6 35B and Qwen 3.8 27B on tool calling and data-science tasks; Glimmer passed 24/30 versus Qwen 3.8's 30/30.

GitHub · Benchmarks & research

Muse Glimmer vs Qwen local agent benchmark

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

U

ag789

u/ag789

started trying out rather recent 'frontier' about ~30b param models recently, there are many choices including QWen 3.8 - this is nevertheless a great model, practically 'one-shotting' code refactoring tasks https://huggingface.co/Qwen/Qwen3.8-27B https://huggingface.co/unsloth/Qwen3.8-27B-GGUF code refactoring is still deemed 'difficult', practically 'infinite' permutations and dependencies which LLMs need to work through itself for code refactoring. But that in terms of style, I'm liking Muse Glimmer better https://research.meta.ai/blog/introducing-muse-glimmer-open-agentic-model https://huggingface.co/meta-models/Muse-Glimmer-30B https://huggingface.co/meta-models/Muse-Glimmer-30B-GGUF https://huggingface.co/unsloth/Muse-Glimmer-30B-GGUF this is in particular when it comes to *incorrect* (e.g. mistakes, typos) prompts, resolving contradictions in existing codes during refactoring, code proposals etc. The handling especially the 'thinking' is different. LLMs have 'styles' and it is great that we've different creators for them

Reddit post · Benchmarks & research

Muse Glimmer's style for code refactoring

Simon Willison

@simonw

Muse Glimmer, the new 30B model, is available on Hugging Face right now - here's the GGUF version: huggingface.co/meta-models/Mu…

X post · Local & open models· ♥ 210

Muse Glimmer GGUF on Hugging Face

Mark Zuckerberg

@finkd

Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats

X post · Local & open models· ♥ 30.4K

Zuckerberg opens Muse Glimmer weights

@Aeroknight786

@Aeroknight786

A local browser GUI for an existing Muse Code install, offering a persistent view of projects, tasks, conversations, permissions, activity and working-tree changes over Muse's session protocol.

GitHub · Coding & dev tools· ★ 3

mortiφ

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

AI at Meta

@AIatMeta

For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to

X post · Local & open models· ♥ 456

How Glimmer fits on consumer hardware

@CBannink

@CBannink

Installer that routes OpenCode's coder and reviewer agents at a Muse coding subscription, calling api.meta.ai directly with no local proxy, reusing the muse login key.

@joymadhu49

@joymadhu49

A local shim that lets the unmodified muse coding CLI run on any OpenRouter API key by translating its Responses-API-plus-extension wire protocol, so no Meta account is needed.

GitHub · Coding & dev tools

muse-openrouter-shim

wyn

@wyn_eth

When you say business do you just mean sales? If so I sold two websites today that muse made. Ill dm them to you if you’re interested. It was entirely my muses idea, i just made the calls and 2 out of like 50 hit

X post · Business & commerce· ♥ 10

Muse-made websites sold to local businesses

@chasko-labs

@chasko-labs

Field notes on Muse Spark, a local Glimmer delegate and the Muse Code CLI, covering setup, skills hygiene, an MCP fleet and operational lessons from a ROCm box.

GitHub · Coding & dev tools

Muse Code handbook field notes

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@kevinzhao-dev

@kevinzhao-dev

A starter script that downloads Muse Glimmer 30B, serves it with llama.cpp on an Apple Silicon Mac and connects it to OpenCode, with the server listening only on localhost.

GitHub · Local & open models

Muse Glimmer starter script

AshutoshShrivastava

@ai_for_success

Got Muse Glimmer 30B running locally on my Mac (M5 Max - 128 GB )and the instruction following is impressive. need to setup with opencode next Video Speed - 5X

X post · Local & open models· ♥ 125

Muse Glimmer on an M5 Max Mac

Unsloth AI

@UnslothAI

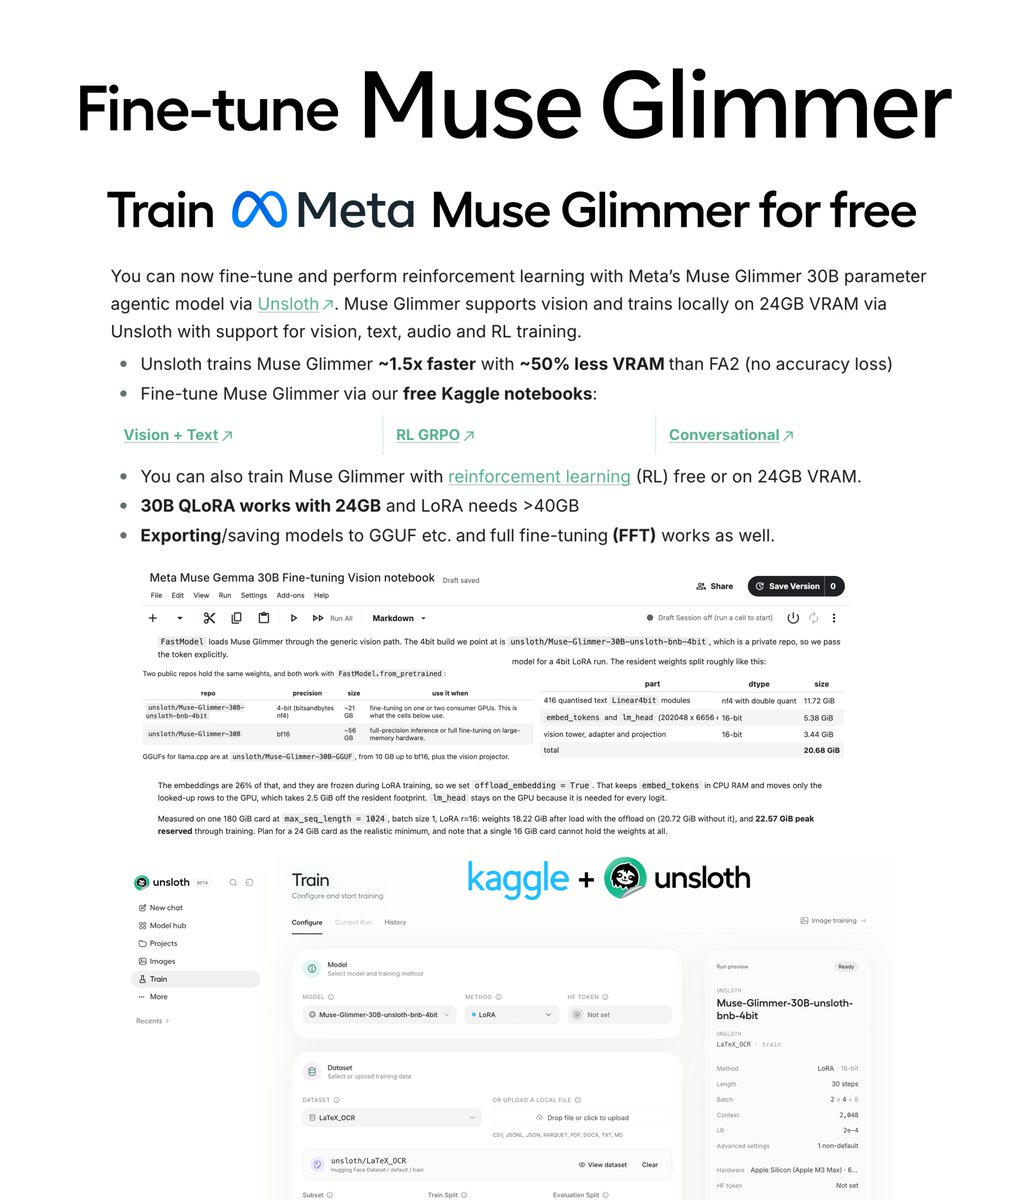
You can now fine-tune Meta Muse Glimmer 30B for free! 🔥 Our free notebook also supports GRPO RL training. Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM. Guide: unsloth.ai/docs/models/mu… Notebooks: unsloth.ai/docs/models/mu…

X post · Local & open models· ♥ 631

Free Muse Glimmer fine-tuning notebook

@Fangyuan025

@Fangyuan025

Chaty is a private offline desktop app built on Rust and llama.cpp that runs Muse Glimmer and other open models locally with a coding agent, RAG knowledge base, deep research and voice.

GitHub · Local & open models

Chaty on-device AI app

@itsgoharr

@itsgoharr

Threadwell Slack is an open-source Muse connector that bridges to Slack's official MCP server via a local OAuth bridge, submitted to the Muse Connector Platform with a full submission pack.

Skill · Connectors & MCP

Threadwell Slack connector for Muse

D

@DigitalSpaceport

@DigitalSpaceport

Digital Spaceport reviews Muse Glimmer 30B on a 4x 3090 EPYC home server, calling it weaker than Qwen 3.6 27B overall but good at one specific thing.

Video · Local & open models· ♥ 550

Muse Glimmer 30B on a 4x RTX 3090 local rig

U

spanielrassler

u/spanielrassler

After noticing that it is ranked among MUCH larger frontier models in the EQ-Bench Creative Writing benchmark and the Hemingway-bench, I decided to give it a try and was very impressed. I didn't do very formal testing, but I did ask it to emulate the style of several different writers, including Henry Miller, David Sedaris, and Stephen King, and it produced passable prose that actually made me laugh in a couple of cases. The paragraph below is the results of the prompt "produce a humorous paragraph in the style of David Sedaris." (first try, not cherry picked) I recently tried to be a better person and started composting, which mostly means I now have a small, damp science experiment in my kitchen that my mother calls “the smell of your future.” I bought a countertop bin with a charcoal filter, as if that would fool anyone, and I’ve taken to narrating my food scraps to myself — “Goodbye, avocado skin, you were a mistake” — while my husband watches from the doorway with the concerned expression of a man who has just realized he married a woman who talks to garbage. The city sent a pamphlet about proper composting, and I read it the way other people read horoscopes, underlining th

Reddit post · Content & creative

Muse Glimmer 30B for style-imitation writing

@Abhishektenneti

@Abhishektenneti

A reproducible record of running the 17GB Muse Glimmer 30B GGUF with llama.cpp and Metal on a 24GB M4 Pro MacBook Pro, with notes on mistakes, fixes and how local inference works.

GitHub · Local & open models

Muse Glimmer on a 24GB M4 Pro MacBook

@emonibnmustafa

@emonibnmustafa

A local translation gateway and profile manager that plugs Meta Muse Spark (or DeepSeek, Groq, Ollama) into OpenAI Codex and ChatGPT Desktop, translating tool calls and SSE streams, with a one-command switch between providers.

GitHub · Coding & dev tools

AnyCodex: Muse Spark inside Codex Desktop

@network-tocoder

@network-tocoder

A video companion repo with the commands and configs for running Muse Glimmer 30B locally on an RTX 3090 and comparing the Prime Agent and Hermes harnesses under the same conditions.

GitHub · Local & open models· ★ 1

Glimmer 30B: Prime Agent vs Hermes on RTX 3090

@carlosrymer

@carlosrymer

A browser-only agent console for Muse Glimmer 30B that renders the model's ATEM tool-call format client-side, streams from a local server and runs every tool inside the tab across seven capability tracks.

GitHub · Agents & automation

Zero-backend Muse Glimmer agent console

U

curiousily_

u/curiousily_

Ran the model with quants (Q4) by Unsloth with latest (build from master) llama.cpp server. It takes ~20GB ram running on M5 Pro with 48GB at about 17t/s. Didn't do any reasoning loops/overthinking. Overall, sits below Qwen3.6 27B, wasn't able to get good code (frontend and backend) results. On the positive side, it didn't fail any tool calls. Your opinions/findings? Watch more: https://www.youtube.com/watch?v=_5wKhkUT438

Reddit post · Local & open models

Muse Glimmer on OpenCode for local coding

U

myanimal22

u/myanimal22

Some people told me that the difference in richness and layout between Glimmer and Qwen wasn't clear to them. This example makes it super clear. I'm aware that comparing Glimmer 30B (a dense model) with Qwen 3.6 (a MoE) isn't entirely fair, but if we compare it to the dense Qwen 27B, the gap will likely be even bigger. If you want, I can add the 27B version later. For now, I'm waiting for Qwen 3.8 27B to see how close it gets to the blueprint. As for the technical details: Both were run on a custom llama.cpp build optimized for the RTX 5080, with a temperature of 0.5 and a 125k context window. Regarding the music: I created it myself without using AI I specifically wanted it to sound that weird.

Reddit post · Benchmarks & research

DS4 vs Qwen3.6 vs Glimmer on one design prompt

U

VibeCodyH

u/VibeCodyH

Every model gets the same thing: the Game Boy screen, eleven buttons, a walkability grid, and 1,000 turns to beat Brock. No walkthrough, no pathfinding, no hints. Same prompt for all of them. Scoring is a 10-milestone ladder (left the house, got a starter, reached Route 1, ... beat Brock), so a run that never wins still places by how far it got. 14 runs so far, 4 of them got the badge. Best is GPT-6 Astra at 246 turns. Cheapest win was Gemini 3.8 Flash at $3.70. A free local model (Muse Glimmer 30B) burned all 1,000 turns and got as far as Reached Route 1. Full turn-by-turn logs, costs, and the VODs are all up at https://pokebench.tv.

N

build.nvidia.com

build.nvidia.com

NVIDIA hosts a Muse Glimmer 30B endpoint on build.nvidia.com with Python (OpenAI, LangChain), JavaScript and curl examples for the ~29.6B multimodal model with 131K context.

Site · Local & open models

Muse Glimmer 30B on NVIDIA build

M

ai.meta.com

ai.meta.com

Meta's Mac app lets Muse work with local files, Messages, Notes, Reminders, Mail and Calendar, with per-app Off / Read only / Read and interact controls.

Site · Errands & personal agent

Muse for Mac