№ 1067Reddit post
Muse Voice Transcribe tested on clinical diarization
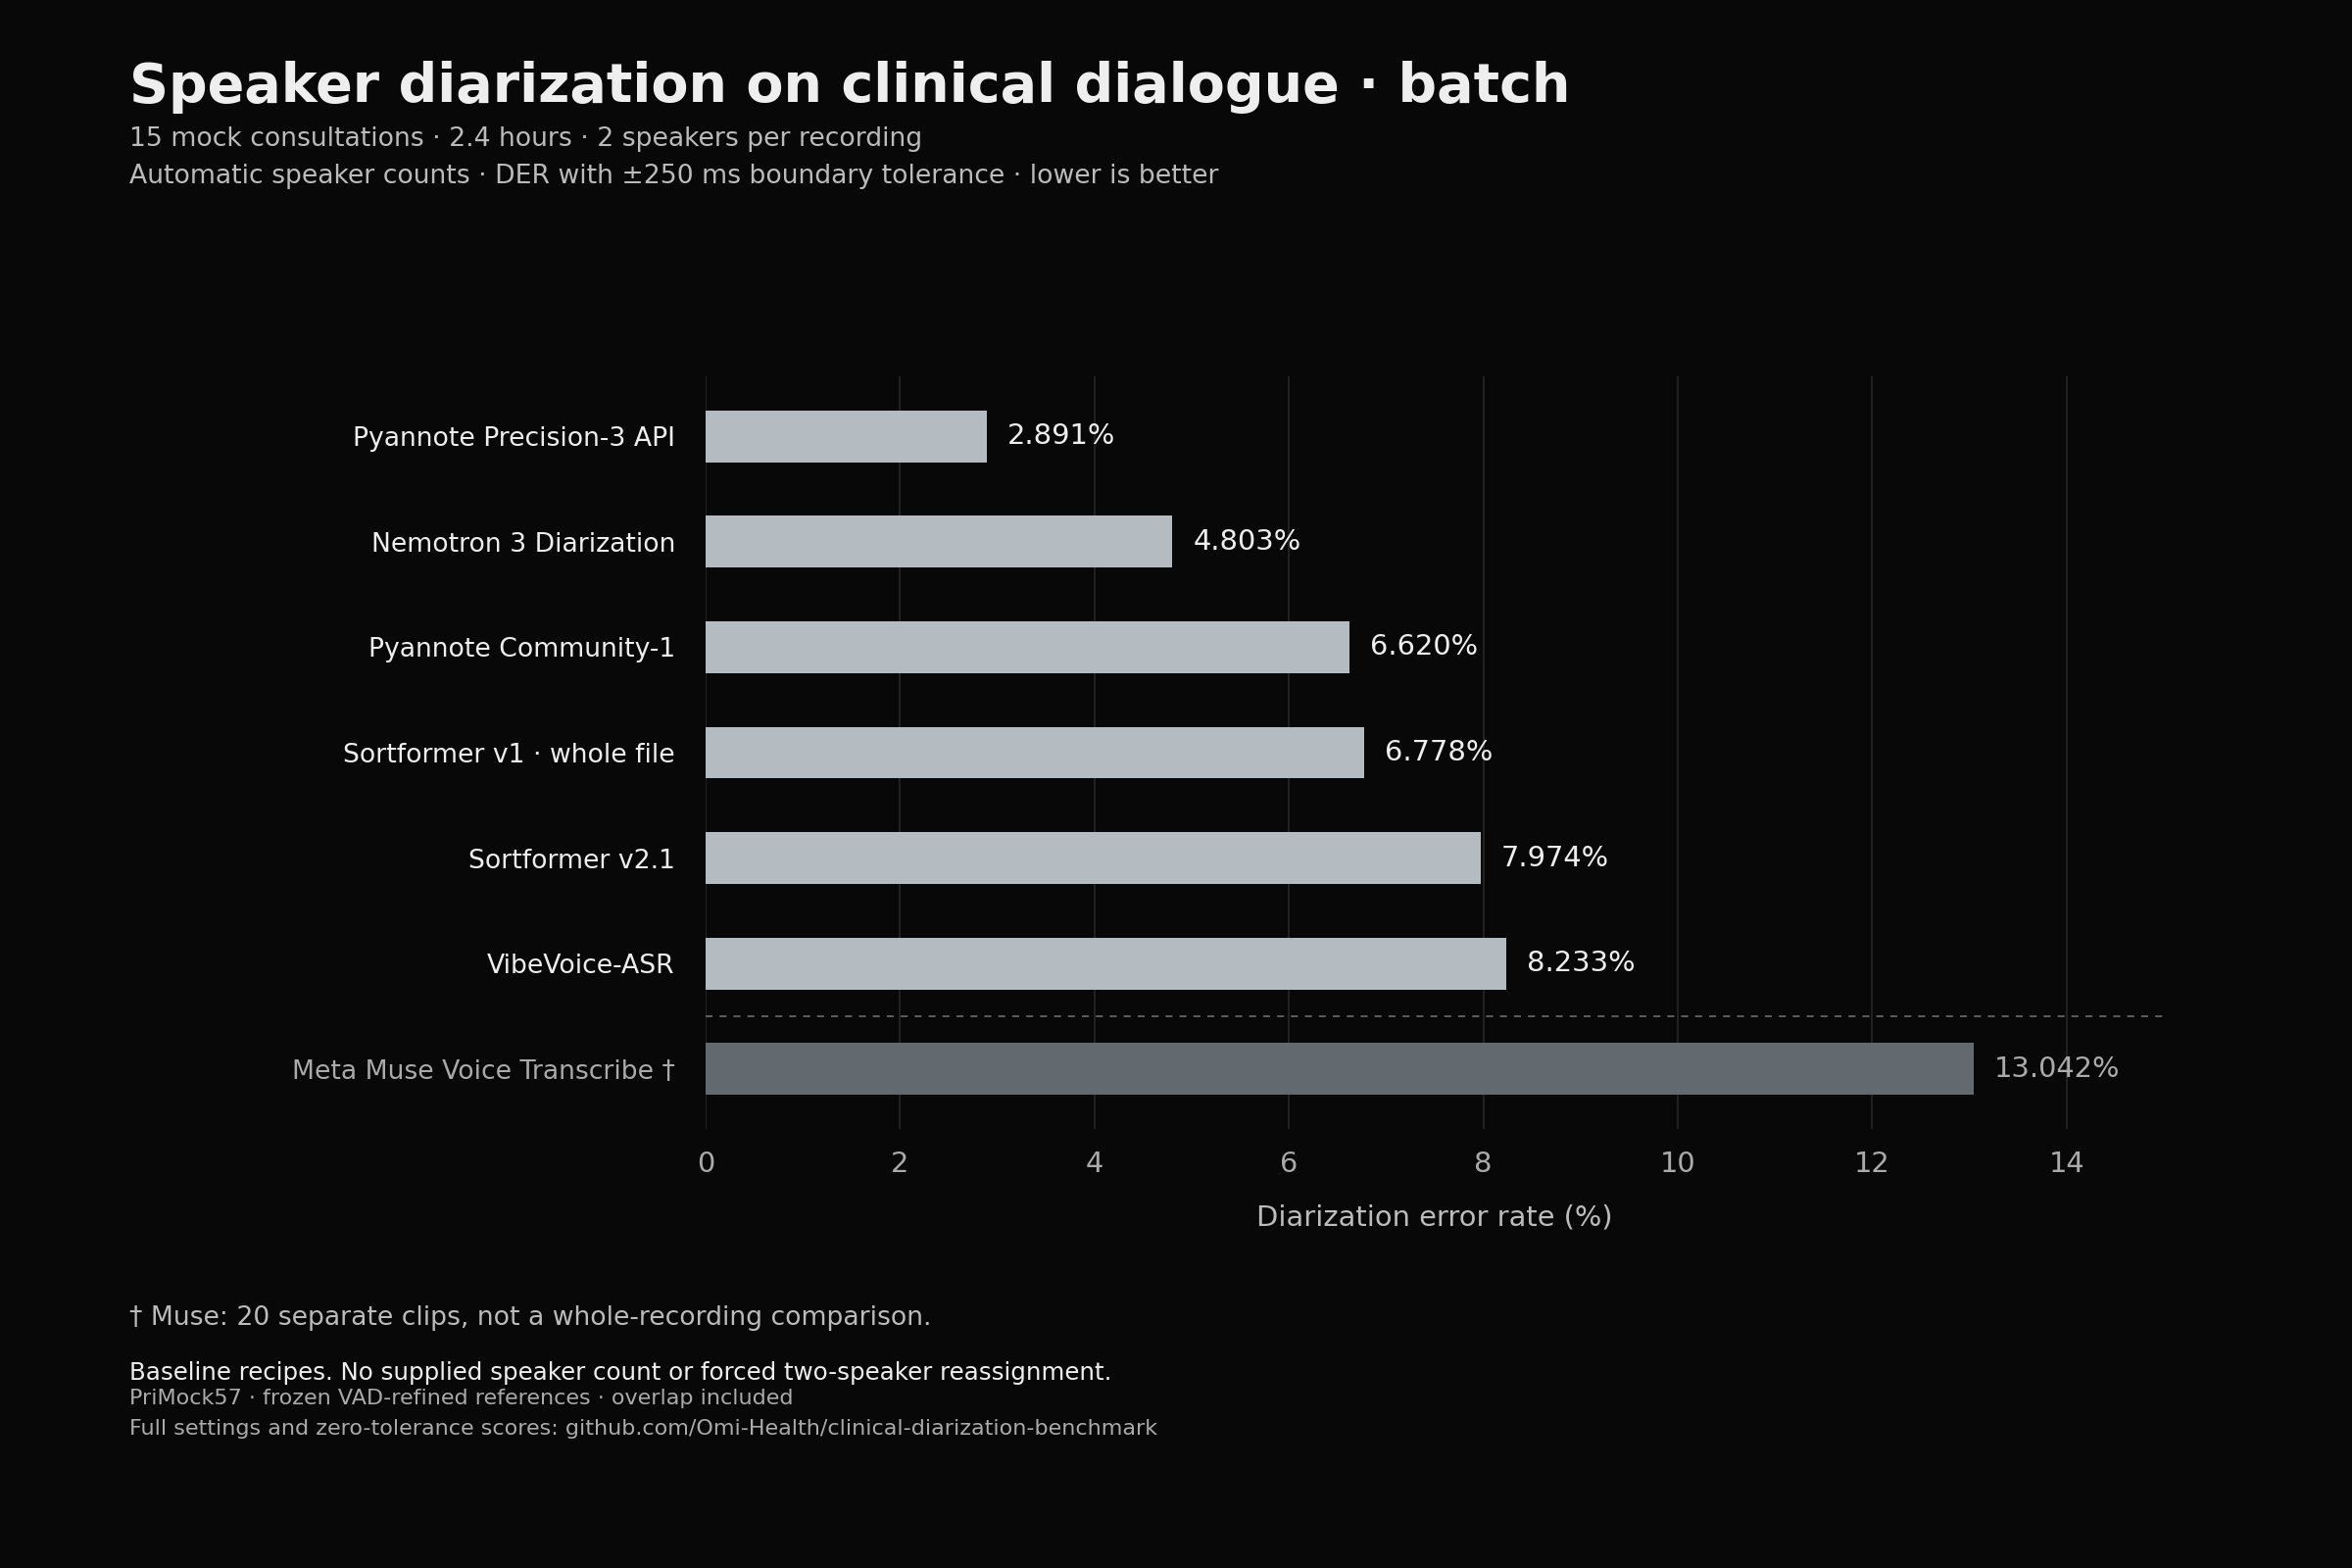
Compared diarization models on 15 mock doctor-patient consultations (~2.4 h): Meta Muse Voice Transcribe scored 13.04% DER at ~92 s per request via API, behind Pyannote (2.89%) and Nemotron 3 (4.80%).
MajesticAd2862, who works on clinical speaker attribution at Omi, used PriMock57 with a ±250 ms boundary tolerance and automatic speaker counts. Muse had to be run on 20 separate clips because of its 10-minute request limit, so its number is not a whole-recording comparison, and it was not evaluated for streaming.
I compared diarization models on 15 clinical conversations: Nemotron 3, Pyannote, Sortformer, VibeVoice and Muse
I've been working on clinical speaker attribution at Omi and wanted to compare the current diarization models on the same audio. I used 15 mock doctor–patient consultations from PriMock57, about 2.4 hours. Full recordings, automatic speaker counts, without telling the models there are two people. Batch Diarization error rate (DER), with ±250 ms boundary tolerance. Lower is better. Model DER Median processing time Pyannote Precision-3 2.891% 18.9 s / recording (API) Nemotron 3 4.803% 0.688 s / recording Pyannote Community-1 6.620% 18.691 s / recording Sortformer v1 6.778% 3.869 s / recording Sortformer v2.1 7.974% 1.077 s / recording VibeVoice-ASR 8.233% 123 s / recording Meta Muse Voice Transcribe † 13.042% 92 s / request (API) Local models ran on one NVIDIA L4. API times include round-trip overhead; VibeVoice-ASR also performs transcription. † Muse used 20 separate clips because of its 10-minute request limit, so its result isn't a whole-recording comparison. Pyannote Precision-3 had the lowest error. Nemotron came next and was the fastest local model. Streaming Model DER Pyannote live API 3.959% Nemotron 3 † 4.971% Sortformer v2.1 † 6.958% VibeVo