Curated with by@mohithkumar808

Catalog / Use case

Benchmarks & research

139 benchmark results and research notes on Muse Spark and Muse Glimmer: arena rankings, index scores, head-to-head tests and architecture teardowns.

Arena.ai

@arena

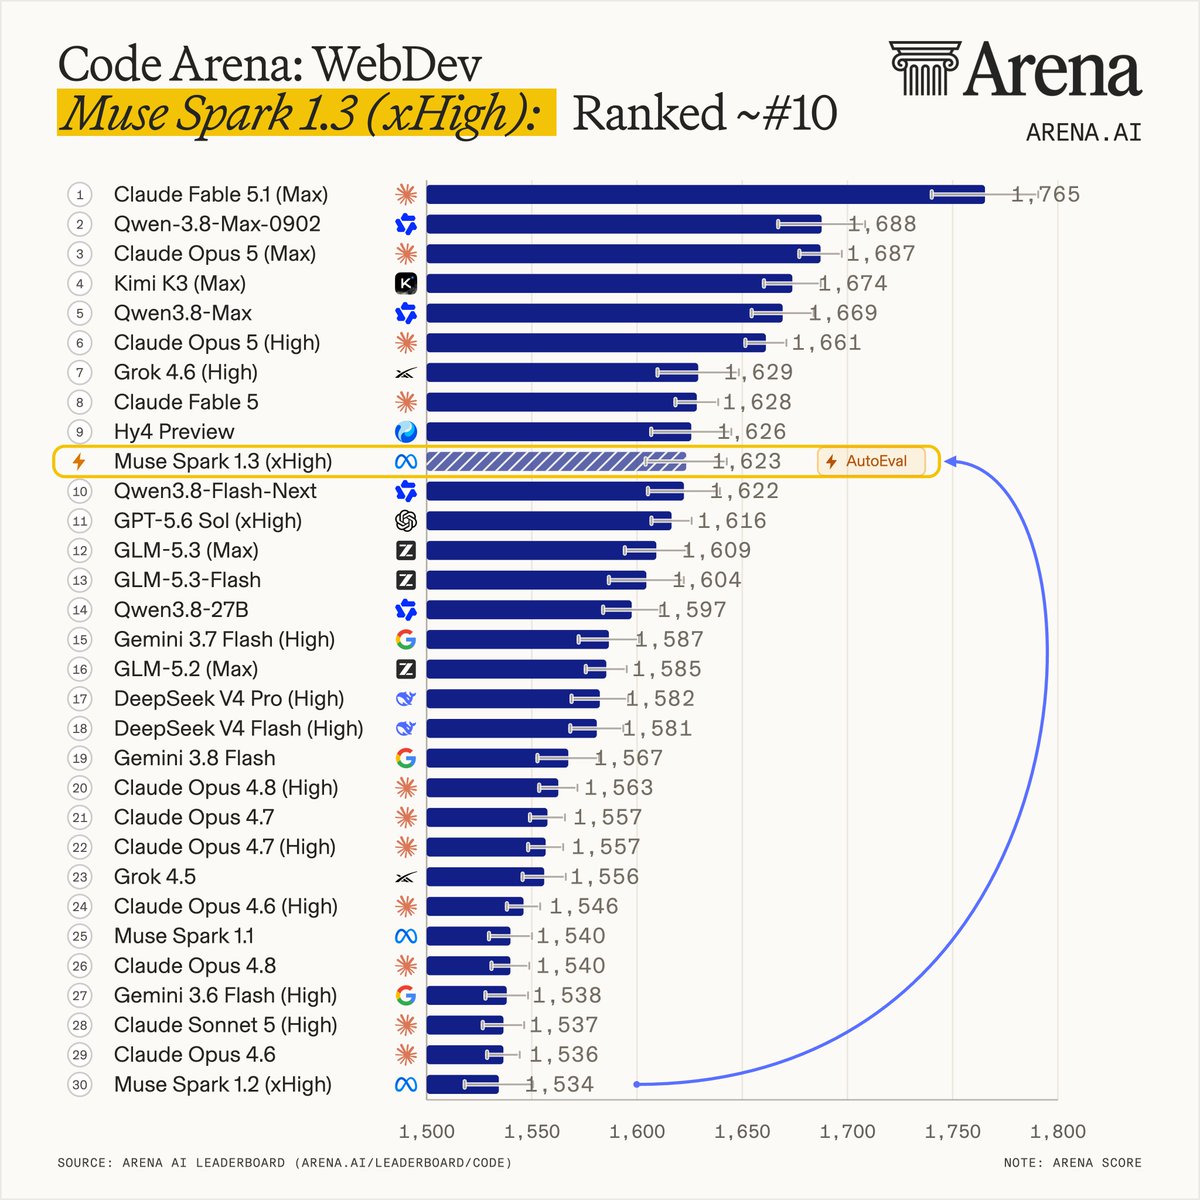
Muse Spark 1.3 (xHigh) just landed @AIatMeta back in the top 10 models for Code Arena: WebDev! This release is ~#10 in Code Arena: WebDev with 1623 pts (AutoEval). It’s performance is par with Claude Fable 5 at #8 (1628 pts) and GPT-5.6 Sol at #11 (1616 pts). Muse Spark 1.3

X post · Benchmarks & research★ Pick· ♥ 610

Spark 1.3 in Code Arena: WebDev top 10

U

PathfinderTactician

u/PathfinderTactician

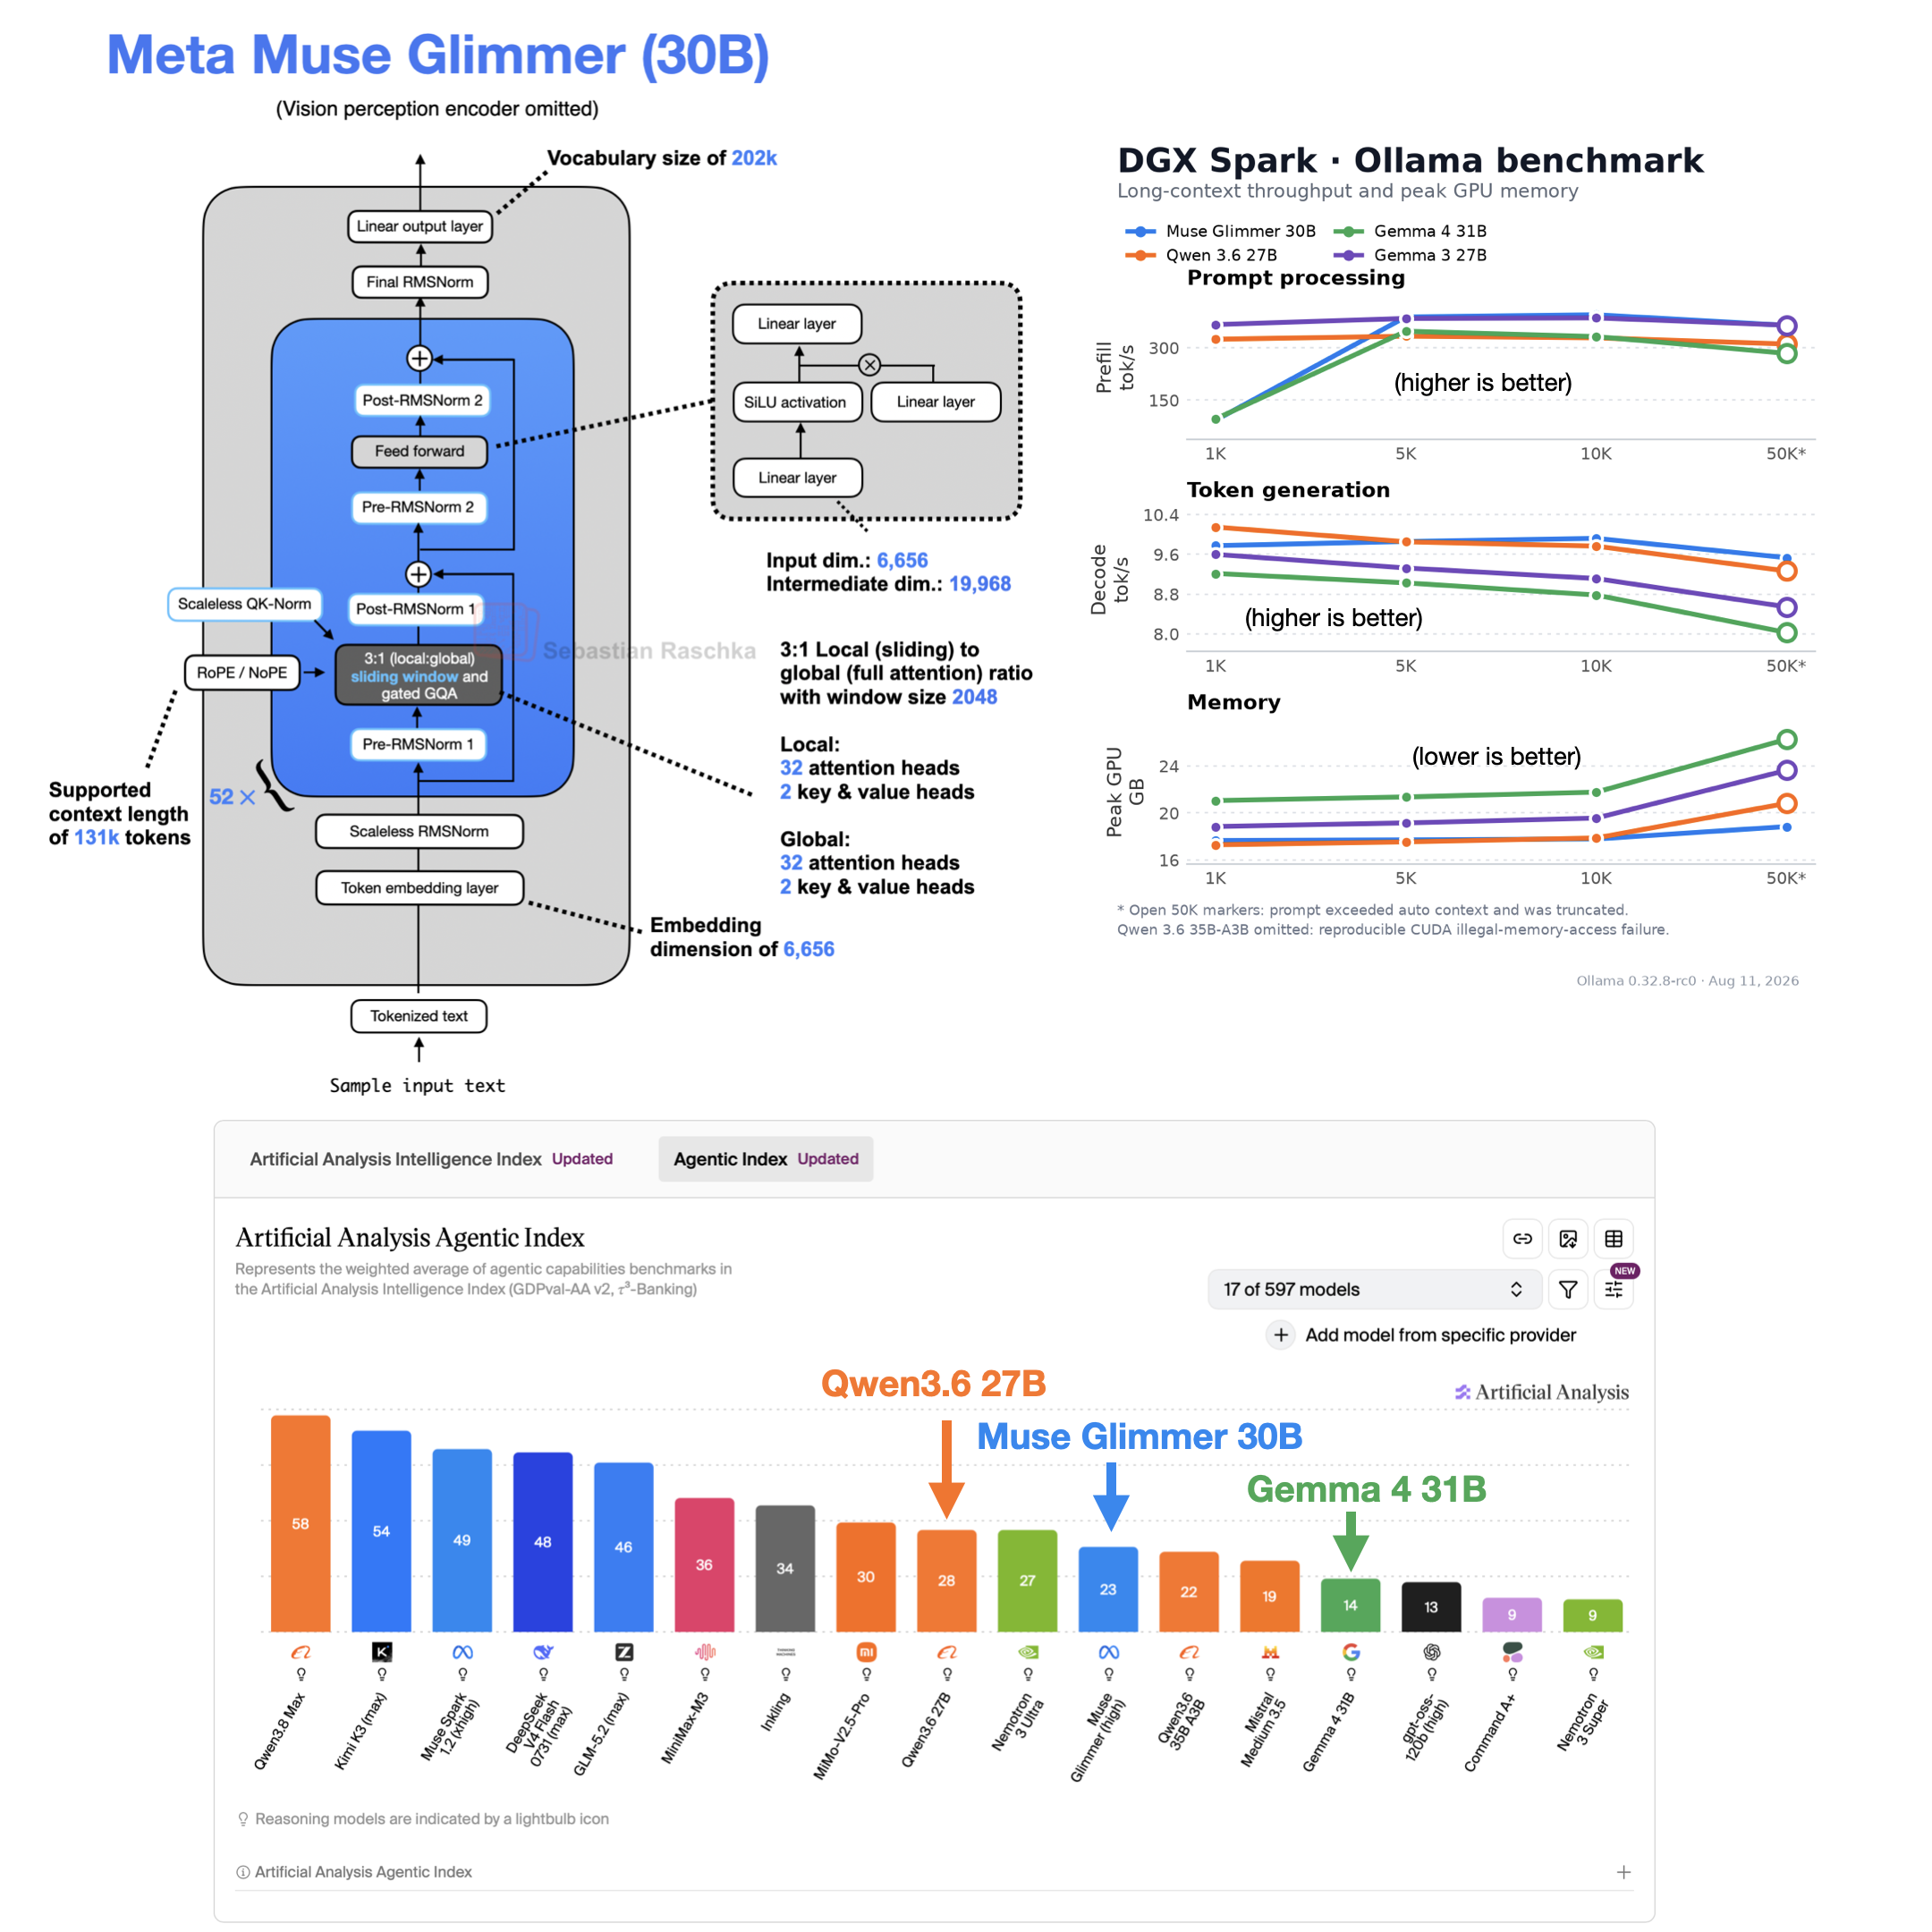
I'm guessing that many people have been waiting for this comparison. For clarity, both models are running at full FP16 KV-cache. Due to VRAM limitations, Muse Glimmer is running full 262,144 context, whilst Qwen3.6 27B can only run at 147,500 context - full GPU offload in both cases. Both models have been coding on an enterprise-grade web application. Detailed report of each model (warning - includes AI generated content): Diagnostic quality - comparable. Both have shown genuinely good root-cause work when they apply themselves. Qwen found coding issue and worked to fix things cleanly. Muse Glimmer correctly traced bugs and even caught something that a Frontier model missed after more than 10 rounds of review. Neither one is weak at diagnosis. Implementation reliability - Qwen ahead. Qwen did introduce real regressions into the coding along the way (eg. severe zone-scope refactor regression, and case-sensitivity regression) but each one eventually got fixed properly once caught, usually within one or two corrective rounds. Muse Glimmer did land fixes that were clean and verified true to spec. However, when working in a complex environment exceeding 200k context, Muse Glimmer fa

Reddit post · Benchmarks & research

BF16 Muse Glimmer vs Qwen3.6 27B on real code

@youdotcom-oss

@youdotcom-oss

You.com's harness for evaluating Muse Glimmer 30B on DeepSearchQA with You.com MCP tools inside pi sessions. A custom RLM v5 extension reached F1 0.8054 on 50 tasks (0.6910 over 900x3) versus 0.50 for plain skill injection.

GitHub · Benchmarks & research

Muse Glimmer DeepSearchQA skill eval

M

@MattJohnstonai

@MattJohnstonai

Matt Johnston's live gauntlet puts Muse Spark 1.2 at 95 and #5 on his board, at $1.25/$4.25 per M tokens and 171 tok/s on OpenRouter; the full bench ran in 17 minutes.

Video · Benchmarks & research· ♥ 6

Muse Spark 1.2 scores 95 on a live coding benchmark

U

sebseo

u/sebseo

This week we spent about $95 trying to beat our own lineup of reviewing models. One of the candidates was Muse Spark 1.2, and it turned out to be the most interesting model in the whole test. The good, measured: • Among the best we tested at finding real problems. Scored against bugs we already knew were there, it matched our existing lineup, and it caught one real bug our lineup had missed. • Fastest model in our table. Typical answer in 18 seconds, writing at over 220 tokens a second. The speed table from our test (same job, same codebases, 33 runs per model): Model Typical time Answer length (tokens) Writing speed (tok/s) Time follows answer length Time follows question length Muse Spark 1.2 18 s 4,205 222 0.79 barely (0.08) Gemini 3.1 Pro 19 s 2,621 133 0.99 no (0.0) Gemini 3.8 Flash 22 s 1,996 89 0.91 some (0.65) GPT 5.4 29 s 3,058 105 0.95 no (below 0) Grok 4.6 38 s 2,498 61 0.61 no (below 0) Grok 4.7 44 s * 3,176 75 0.98 a little (0.30) Claude Sonnet 5 50 s * 4,471 91 0.59 barely (0.07) * Runs that finished in time only, so the real typical time is higher. The last two columns are correlations: 1 means time rises in step with that length, 0 means no lin

Reddit post · Benchmarks & research

Muse Spark 1.2 as a code reviewer vs 6 models

Arena.ai

@arena

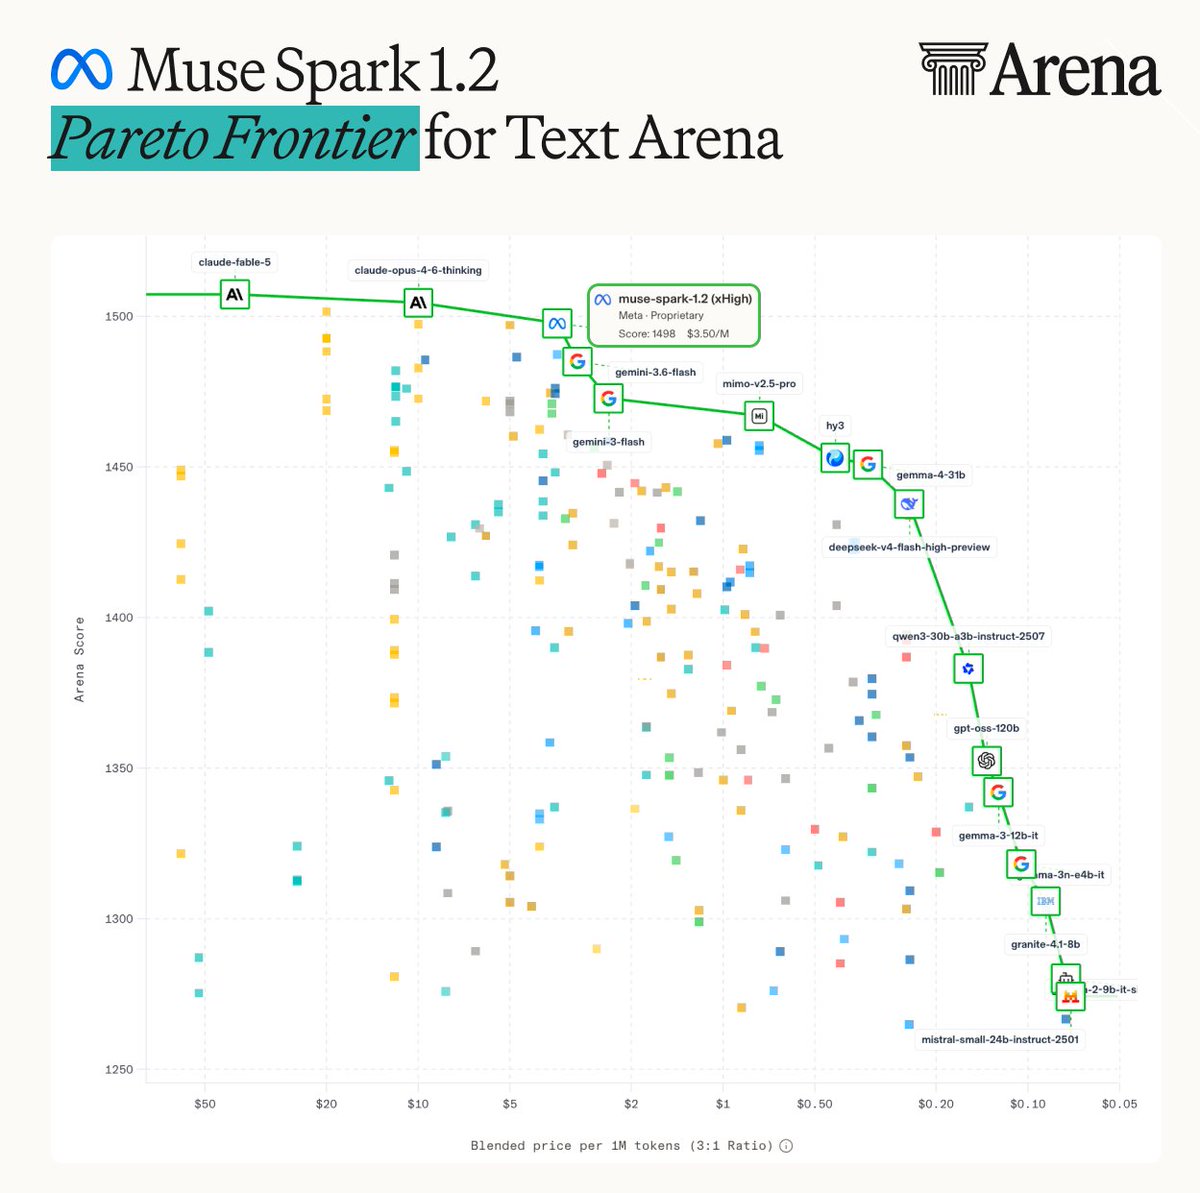
Exciting news: Muse Spark 1.2 (xHigh) by @AIatMeta is #4 in the Text Arena (1498 pts), and has reshaped the Pareto frontier! It is priced at $1.25/$4.25 per MToken. Congrats again to the @AIatMeta team on this release!

X post · Benchmarks & research· ♥ 422

Spark 1.2 reaches #4 in Text Arena

Simon Willison

@simonw

Pelicans for Meta's new Muse Spark models - plus I did a bit of a deep dive into the Code Interpreter and fascinating "container.visual_grounding" tools in their meta.ai chat UI simonwillison.net/2026/Apr/8/mus…

X post · Benchmarks & research· ♥ 290

Pelicans and a deep dive into Muse Spark tools

@murpheycandler

@murpheycandler

A small Inspect evaluation on Muse Glimmer that tests whether incentive framing changes what an agent reports to its principal when the evidence is held constant; the author reports a null result.

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Artificial Analysis

@ArtificialAnlys

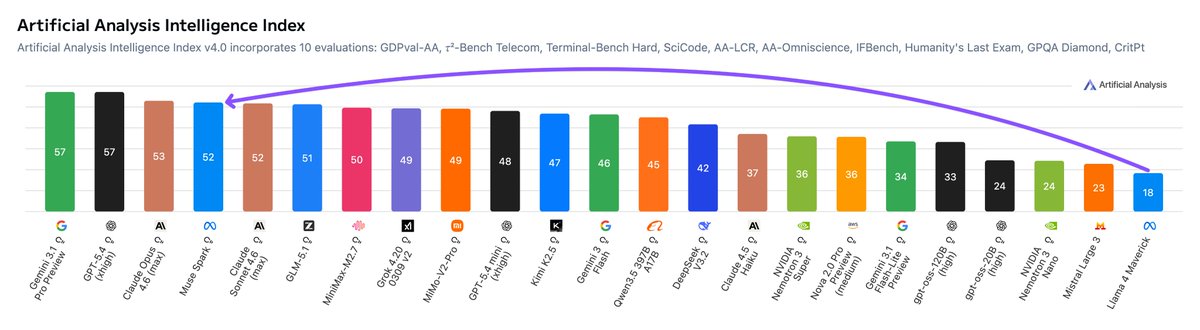
Meta is back! Muse Spark scores 52 on the Artificial Analysis Intelligence Index, behind only Gemini 3.1 Pro, GPT-5.4, and Claude Opus 4.6. Muse Spark is the first new release since Llama 4 in April 2025 and also Meta's first release that is not open weights Muse Spark is a new

X post · Benchmarks & research★ Pick· ♥ 2.4K

Original Muse Spark scores 52

@ezcat207

@ezcat207

A curated, source-linked catalog of 156 real things people have done with the Muse personal agent, grouped into 16 categories with every entry linked to its original X post.

GitHub · Benchmarks & research

Awesome Meta Muse use cases

Simon Willison

@simonw

I few notes on Meta's new Muse Glimmer 30B - their first Apache 2.0 licensed open weight model (the Llama models had a janky non-OSI license) simonwillison.net/2026/Aug/10/in…

X post · Benchmarks & research· ♥ 435

Simon Willison's notes on Muse Glimmer

Artificial Analysis

@ArtificialAnlys

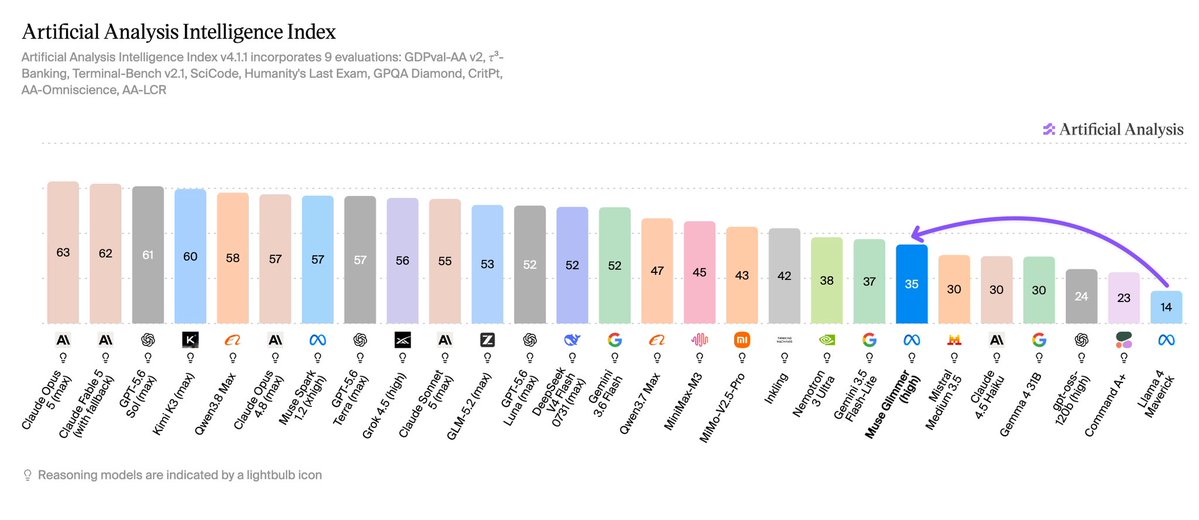
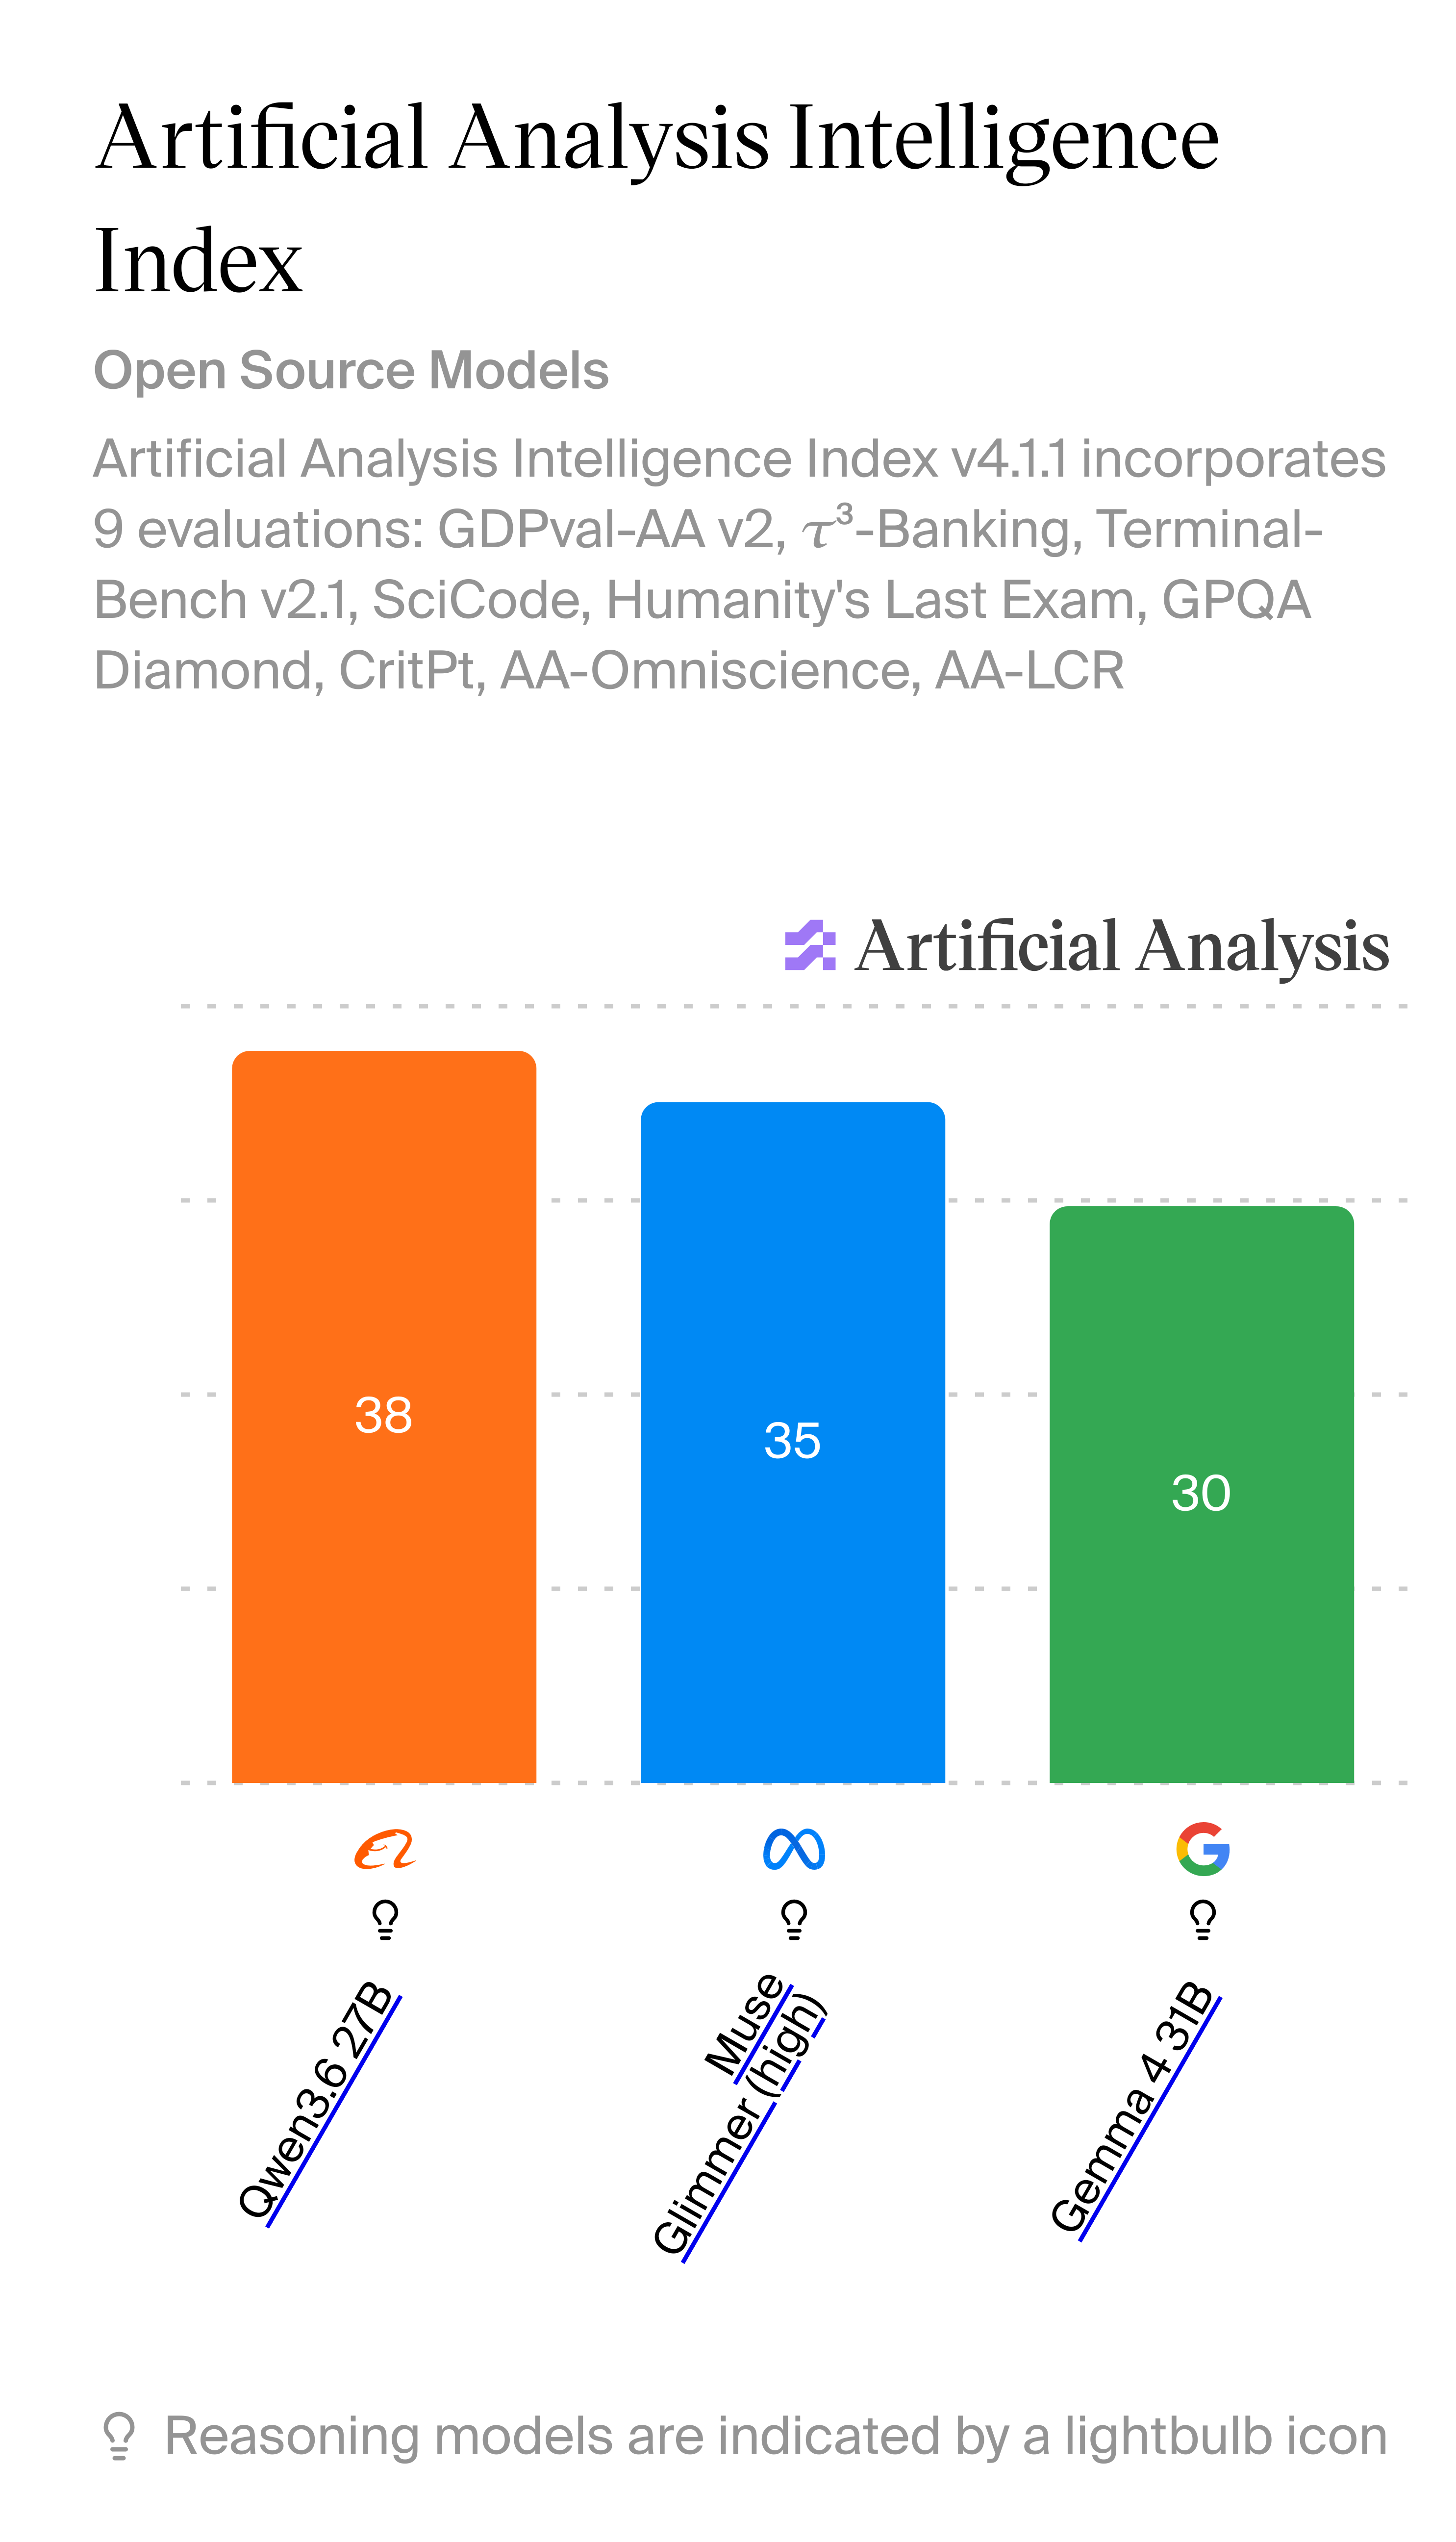
Meta returns to open weights: Muse Glimmer, its first open-weights release since Llama 4, scores 35 on the Artificial Analysis Intelligence Index. It is a 30B-parameter model, and the first from Meta to be released under Apache 2.0 Muse Glimmer (high) arrives 16 months after

X post · Benchmarks & research★ Pick· ♥ 778

Glimmer scores 35 on the Intelligence Index

Arena.ai

@arena

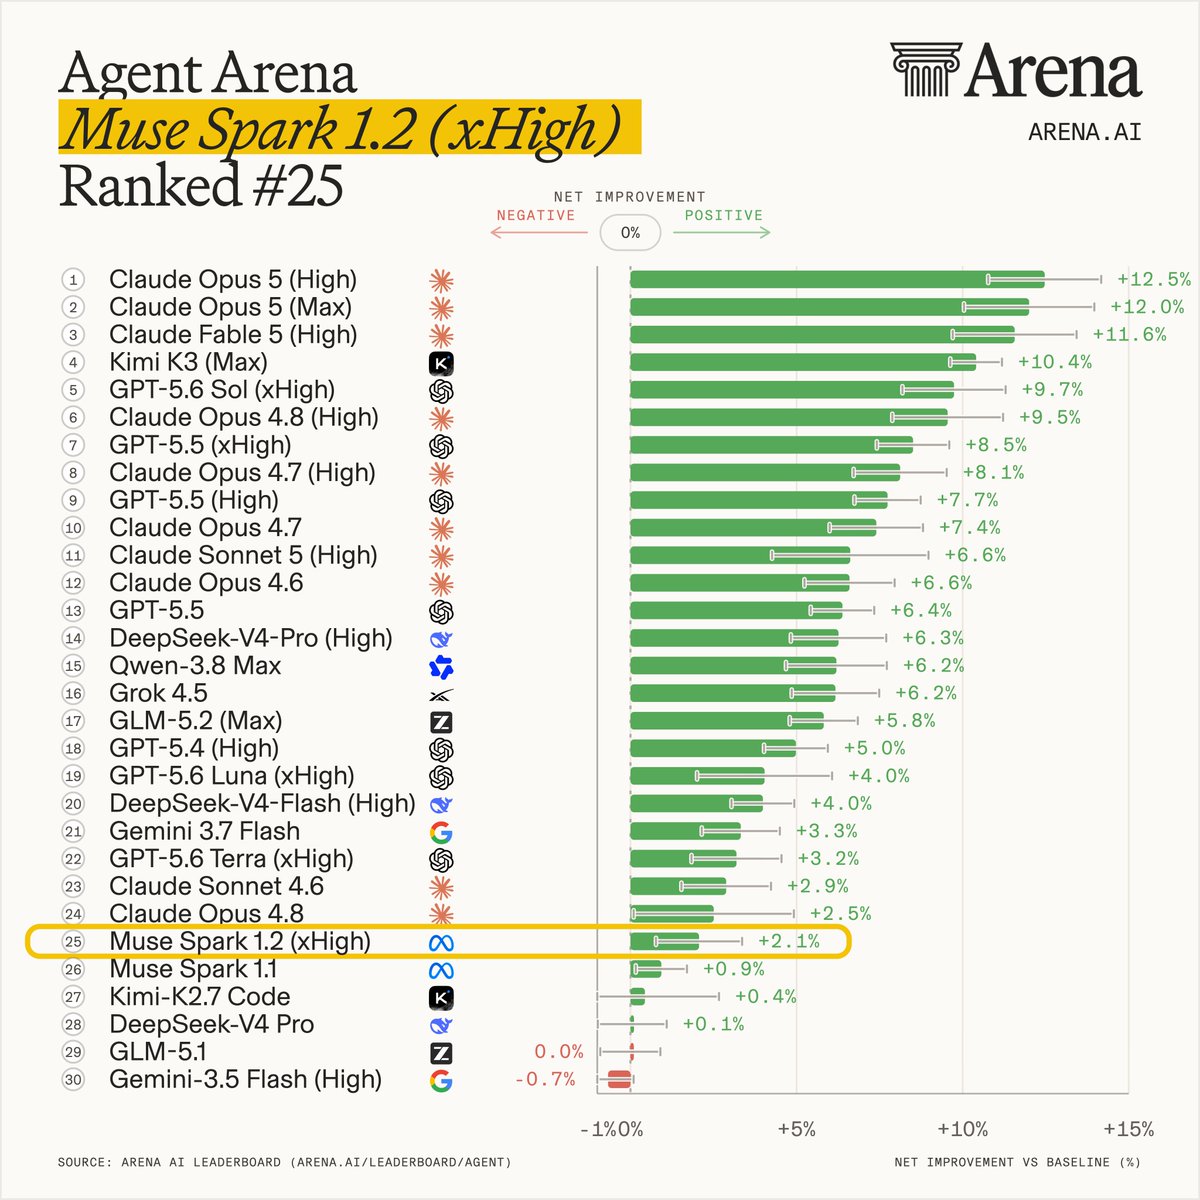
Muse Spark 1.2 (xHigh) by @AIatMeta is now in Agent Arena, with a net improvement of +2.1%! Agent Arena measures models on millions of real-world, long-horizon agentic tasks. We use causal tracing methodology to measure a model's net improvement, indicating how much it improves

X post · Benchmarks & research· ♥ 259

Spark 1.2 joins Agent Arena

Vals AI

@ValsAI

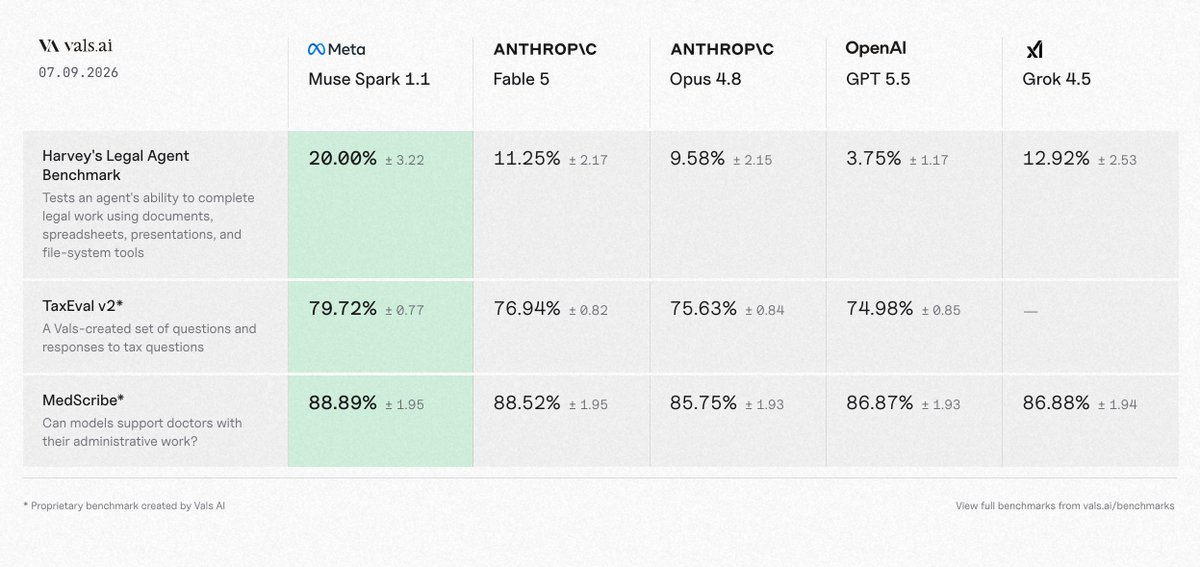
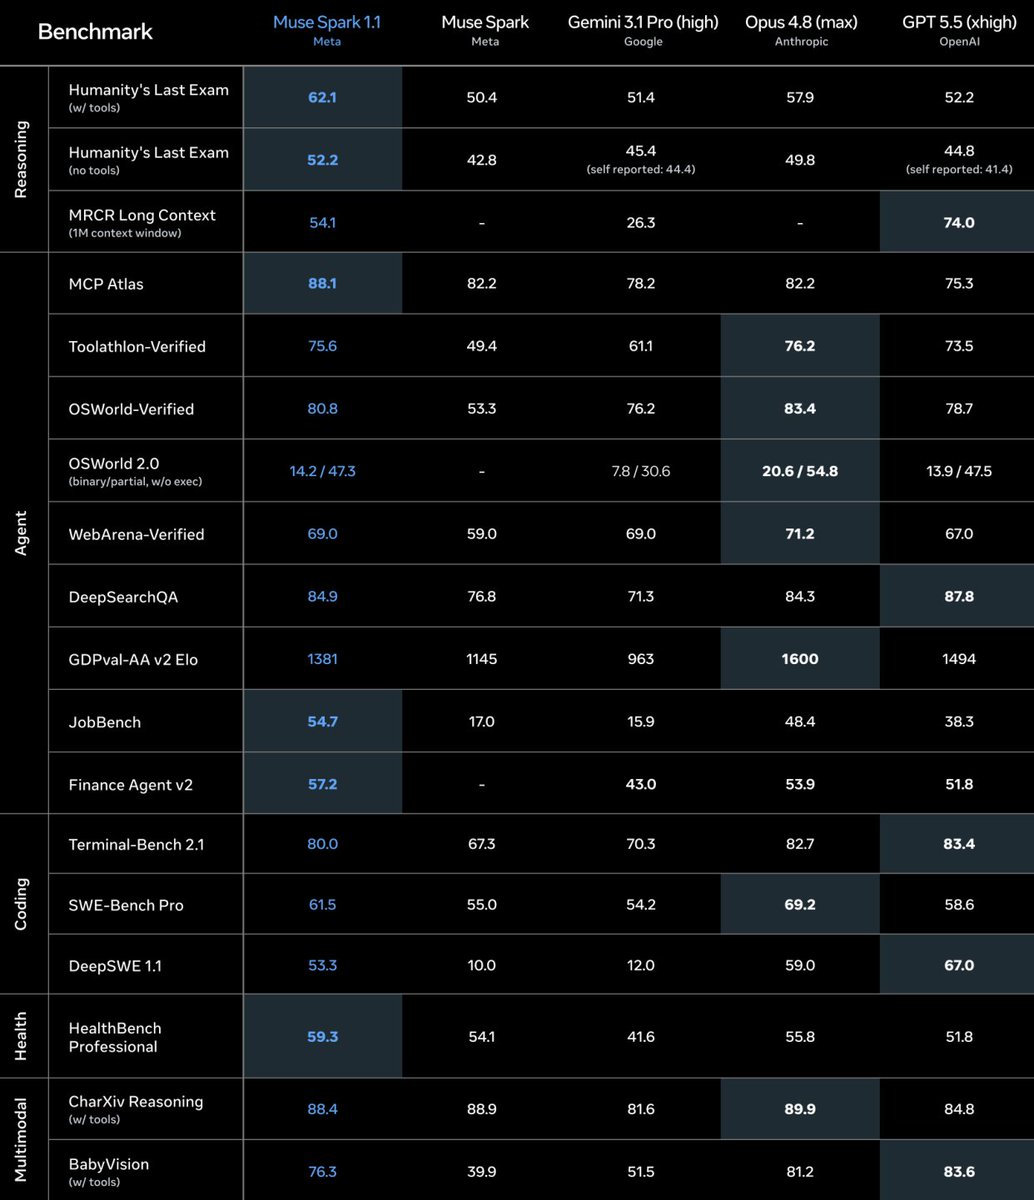
Meta just released Muse Spark 1.1 and is the new SOTA on MedScribe and TaxEval, taking the top spot from Fable 5 while being 10x cheaper and twice as fast. Meta currently holds the top 2 spots on TaxEval It is also the new #1 on Harvey's Legal Agent Bench, dethroning Grok 4.5

X post · Benchmarks & research★ Pick· ♥ 1.3K

Spark 1.1 tops MedScribe and TaxEval

Evergreen Capital

@evergreencap3

I tested $META's Muse Spark over the last few hours and came away net positive. 3 main takeaways: 1) Quality: It's a very good model. Not quite frontier but good. It showed comparable performance vs Opus 4.6 across web data search, PDF parsing, and general

X post · Benchmarks & research· ♥ 309

Investor's hands-on test of Muse Spark

@JacobStephens2

@JacobStephens2

A reproducible evaluation of a stochastic defect where Muse Spark 1.1, under some agent-like request envelopes, wrote to claude-smoke.txt when asked for muse-smoke.txt; a neutral control kept 80/80 filenames intact.

GitHub · Benchmarks & research

Muse Spark 1.1 filename-substitution repro

marktechpost.com

marktechpost.com

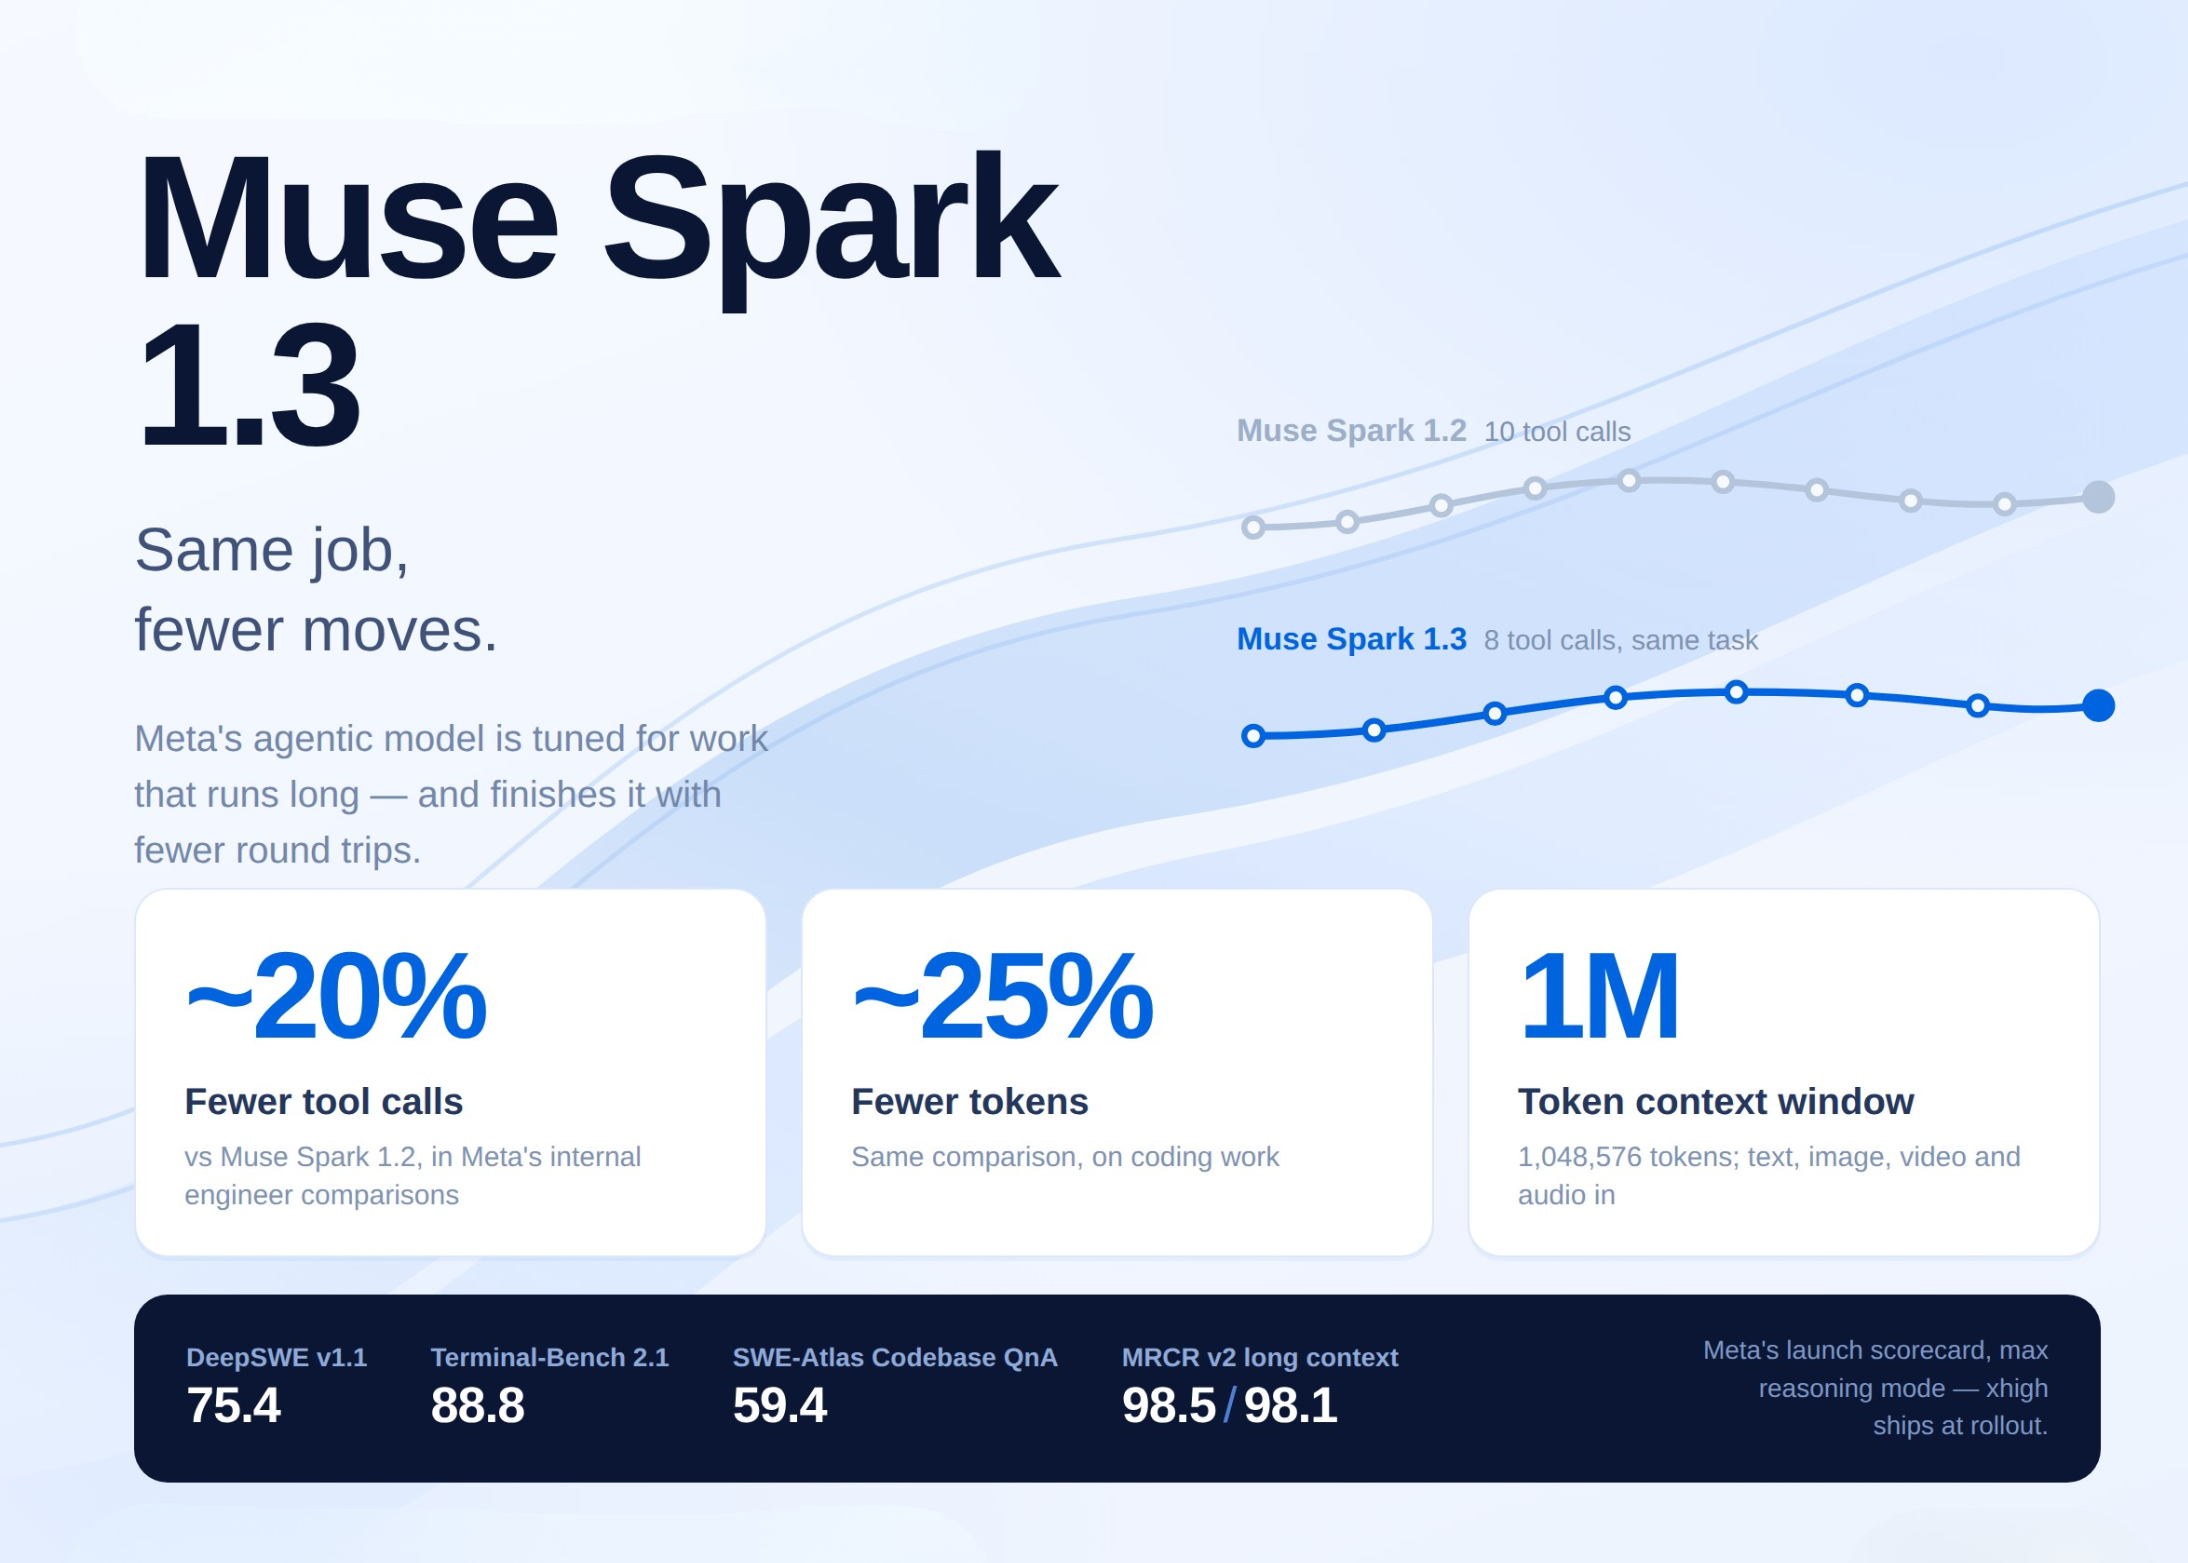
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.

Resource · Benchmarks & research

MarkTechPost: Muse Spark 1.3 benchmarks breakdown

mouse.dev

mouse.dev

Mouse asked Muse to archive the files it could see and send them to Google Drive; the agent complied and sent back 6.8 GB of its runtime.

Resource · Benchmarks & research

Asking Muse for its filesystem returned 6.8 GB

Arena.ai

@arena

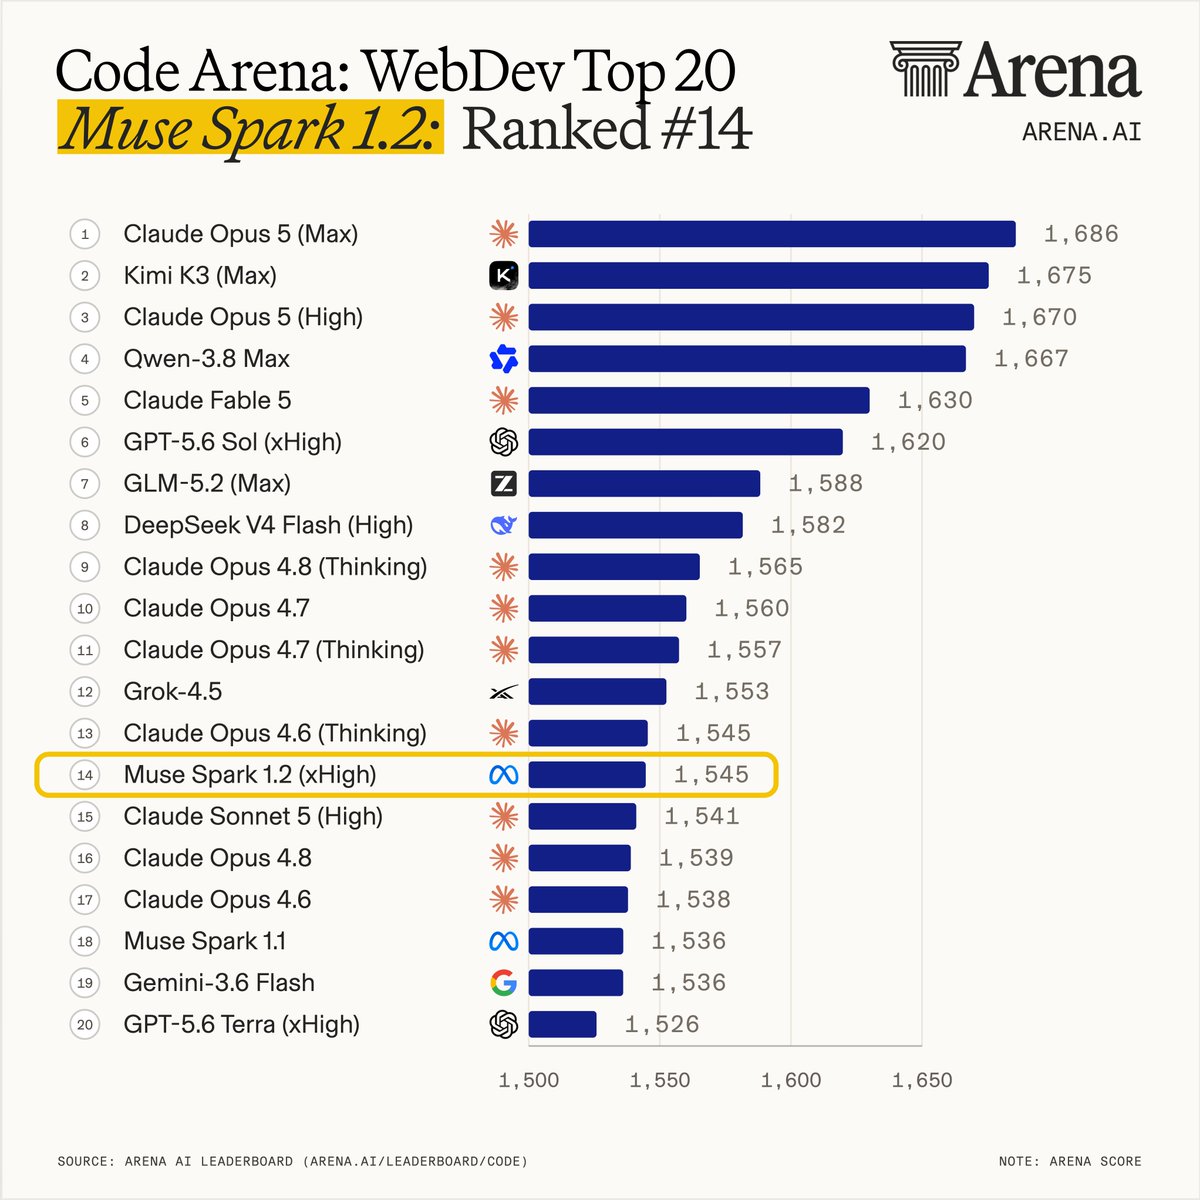
Muse Spark 1.2 (xHigh) by @AIatMeta is #14 in the Code Arena: WebDev, with 1,545 pts! This is an improvement from Muse Spark 1.1 at #18. See its biggest gains by category in the post below. Congrats to the @AIatMeta team on this release!

X post · Benchmarks & research· ♥ 380

Spark 1.2 in Code Arena: WebDev

Sebastian Raschka

@rasbt

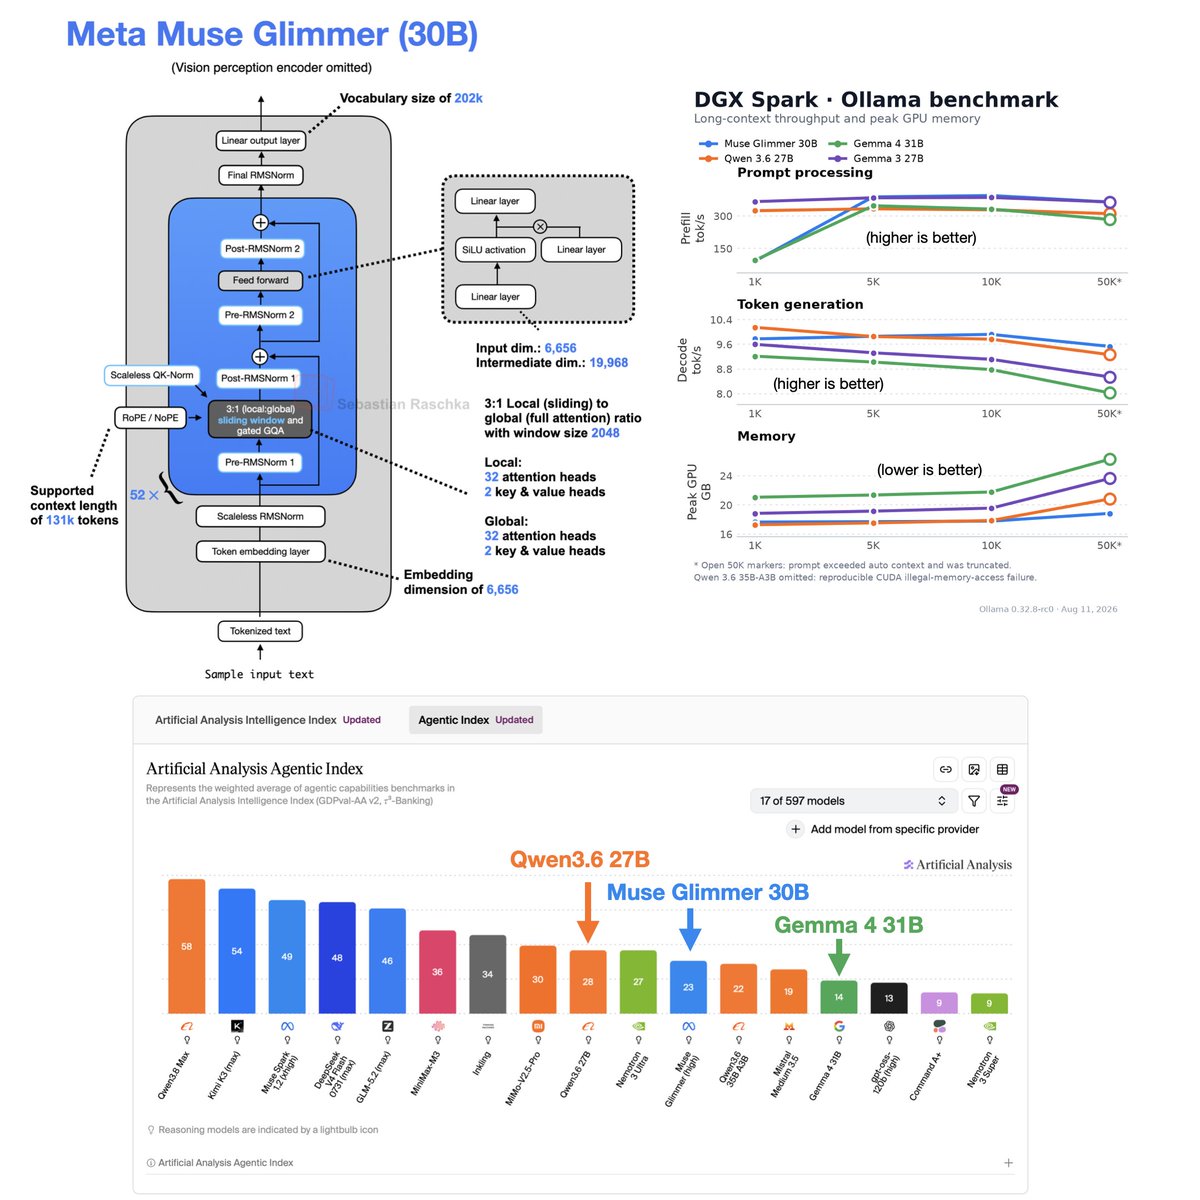
Whoa, Meta released a new open-weight LLM yesterday, something that hasn't happened since the good old Llama days. Their Meta Muse Glimmer model is a 30B multimodal reasoning model with a Gemma-like architecture design. (“Glimmer” is probably a wordplay on “Spark,” the more

X post · Benchmarks & research★ Pick· ♥ 1.6K

Raschka on Glimmer's Gemma-like design

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

W

@webdoze

@webdoze

WEBdoze pairs Muse Spark 1.3 and Gemini 3.8 Flash with the Impeccable design skill and browser testing to turn plain AI-generated pages into polished frontends.

Video · Benchmarks & research· ♥ 6

Muse Spark 1.3 vs Gemini 3.8 Flash on UI refactoring

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

AI at Meta

@AIatMeta

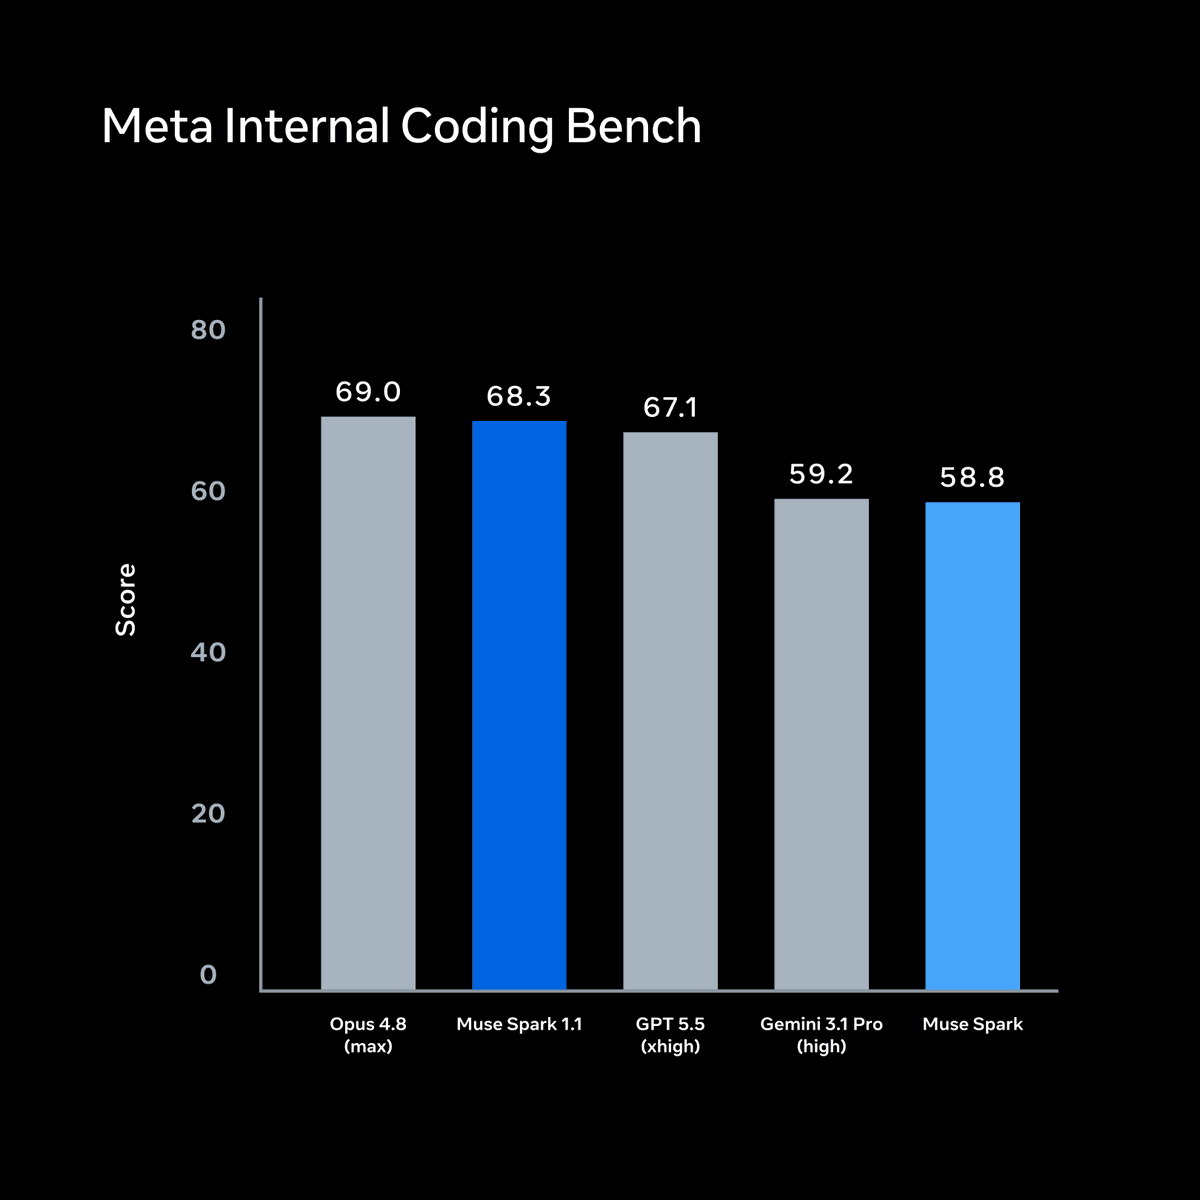
Muse Spark 1.1 is used across Meta in coding and research workflows, scoring competitively with leading models on Meta's internal coding benchmark. Our researchers are now automating model development and evaluation tasks by leveraging Muse Spark 1.1 in their workflows.

X post · Benchmarks & research· ♥ 167

Spark 1.1 on Meta's internal coding benchmark

sebastianraschka.com

sebastianraschka.com

Sebastian Raschka breaks down Glimmer's dense architecture: 3:1 sliding-window to global attention, 32 query heads with only 2 KV heads, and ~52 KiB of KV cache per token.

Resource · Benchmarks & research

Muse Glimmer 30B architecture notes

@dominicletz

@dominicletz

A self-contained visual report comparing CursorBench 4.0 score against cost per task for Opus 5.5, Fable 5.1, Grok 4.7 and Muse Spark 1.3, where Muse Spark 1.3 Max scores 41.6% at $2.64 per task. GPT-6 points are clearly marked as estimates.

GitHub · Benchmarks & research

CursorBench 4.0 score-vs-cost report

Arena.ai

@arena

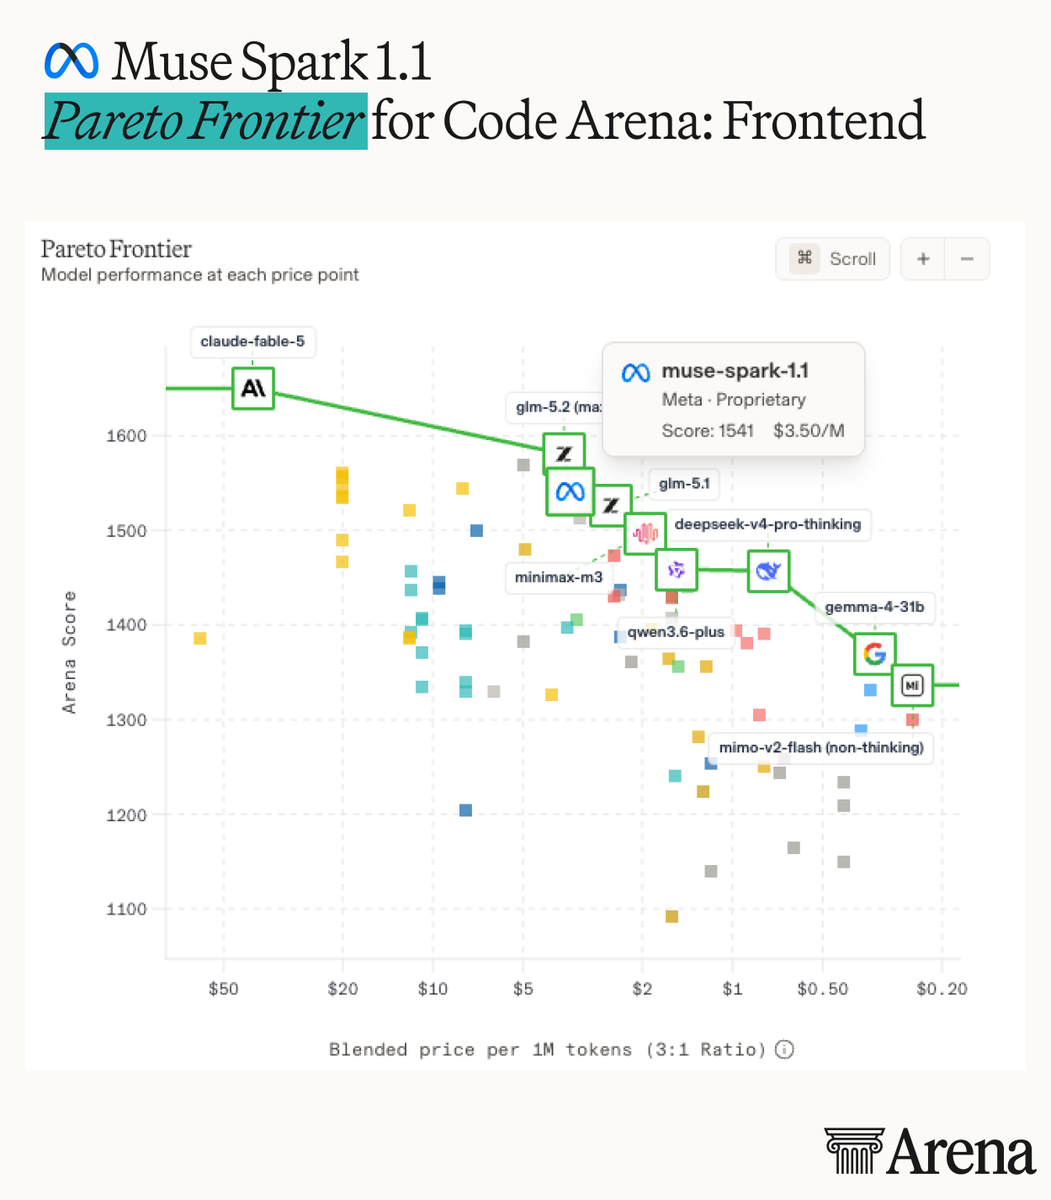
Muse Spark 1.1 has entered the Code Arena: Frontend at #9! Muse Spark 1.1 reshapes the cost-performance Pareto Frontier by scoring 1541 at a blended $3.5M ($1.25 per input MToken, $4.25 per output MToken). This is frontier performance at a fraction of the price. Congrats to

X post · Benchmarks & research· ♥ 302

Spark 1.1 in Code Arena: Frontend

Jason Wei

@_jasonwei

In addition to agents and coding, Muse Spark 1.1 is also really strong at answering health questions, a steadily growing use case for AI. On HealthBench-Pro, Muse Spark 1.1 achieves +5% better performance than Muse Spark 1.0 and beats all competitor models except Fable/Mythos.

X post · Benchmarks & research· ♥ 229

Spark 1.1 on HealthBench-Pro

Arena.ai

@arena

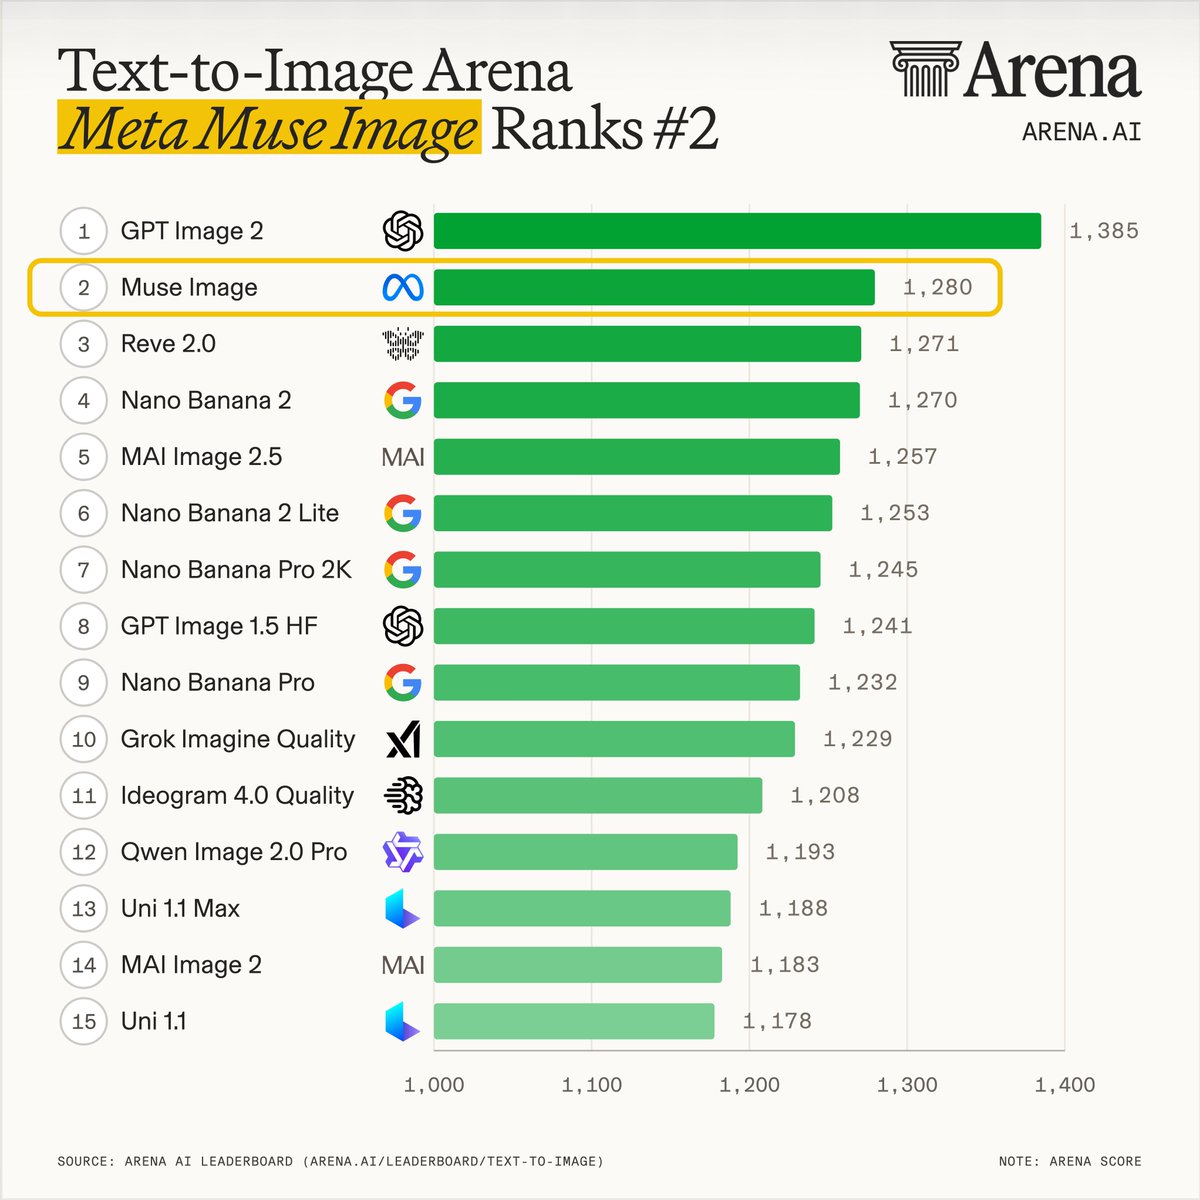
Exciting news: Meta’s Muse Image just claimed #2 in the Image Arena! Muse Image from @AIatMeta now ranks second only to OpenAI's GPT Image 2, outperforming Nano Banana, Grok Imagine, MAI Image, and many other leading image models. It holds #2 across the board: Text-to-Image,

X post · Benchmarks & research★ Pick· ♥ 1.5K

Muse Image takes #2 in Image Arena

Fei Xia

@xf1280

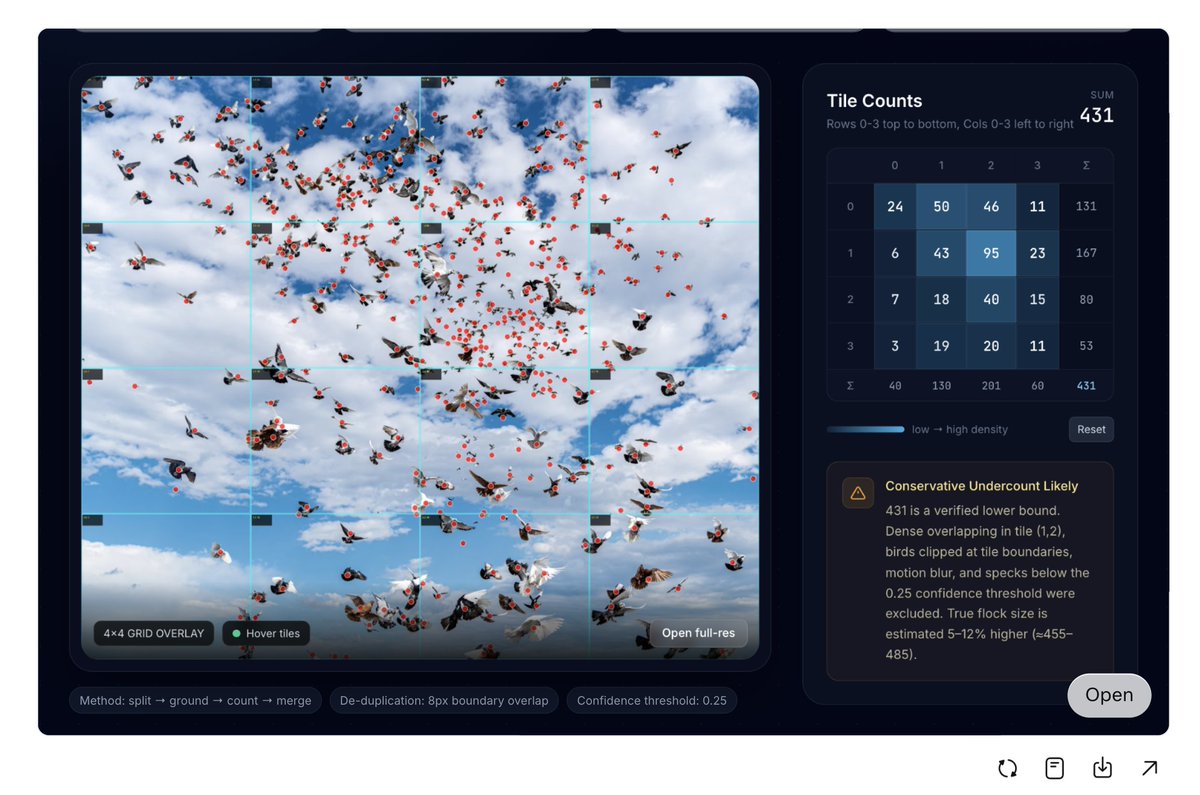
Muse Spark is agentic, which means you can ask it to leverage different test-compute scaling methods to improve quality. Here I ask the model to use parallel subagents to do counting and the results are greatly improved! meta.ai/share/aD4KAPeV…

X post · Benchmarks & research· ♥ 166

Parallel subagents for object counting

A

@altryne

@altryne

ThursdAI hosts compare daily-driver assistants, then David Pawlan, who ran 273 tests across 23 assistants for Assistant Benchmark, walks through how Muse stacks up.

Video · Benchmarks & research· ♥ 18

ThursdAI: Grok Bot vs Meta Muse vs Instinct

Artificial Analysis

@ArtificialAnlys

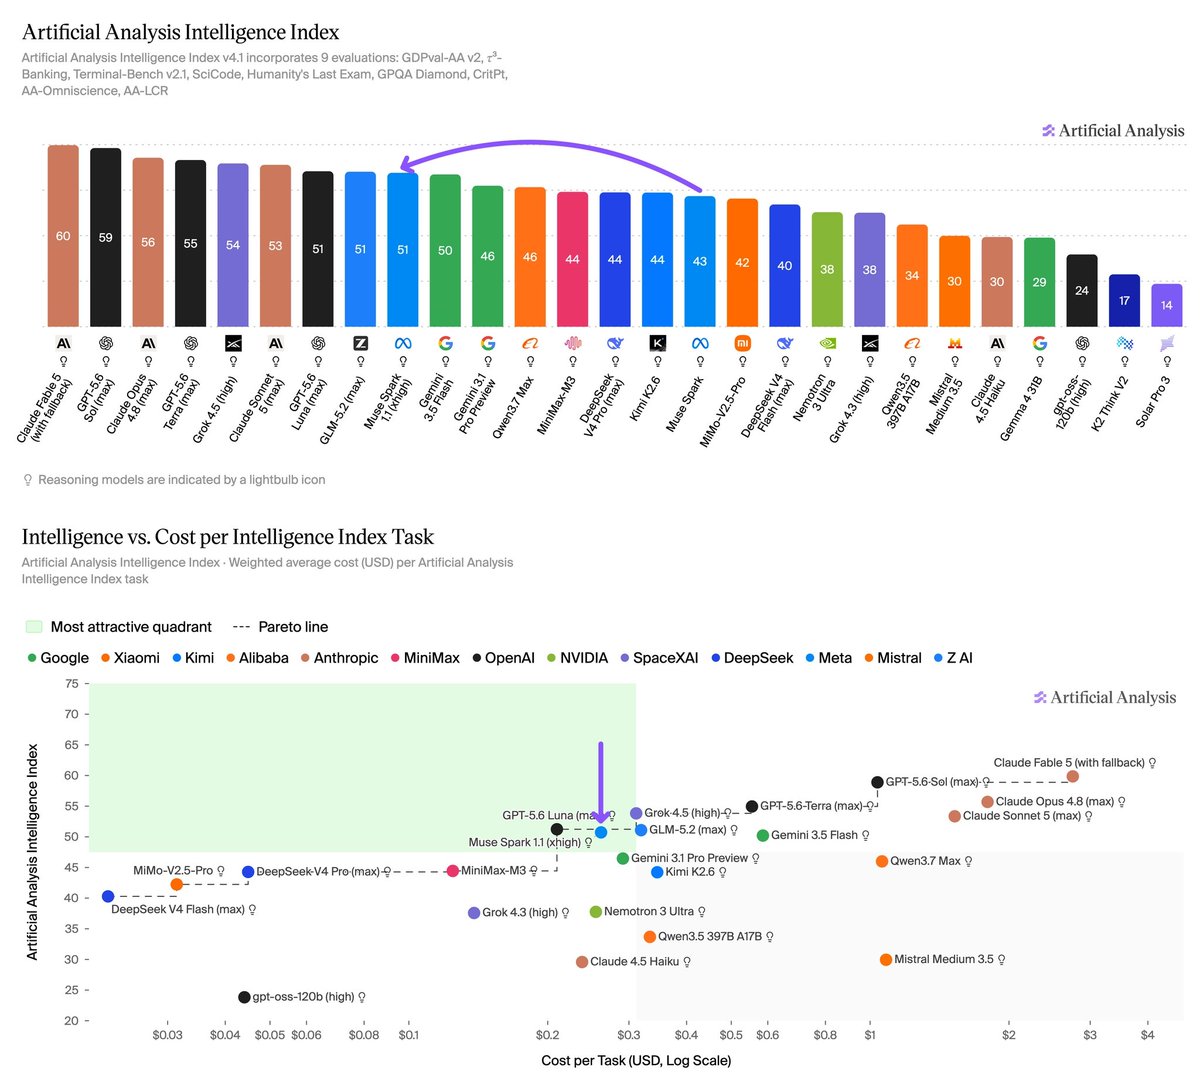
Meta's Muse Spark 1.1 scores 51 on the Artificial Analysis Intelligence Index and is cost and token efficient compared to its peers Muse Spark 1.1 (xhigh) improves 8 points over Muse Spark 1.0 (43) in three months. It is effectively tied with GLM-5.2 (max), GPT-5.4 (xhigh), and

X post · Benchmarks & research★ Pick· ♥ 708

Spark 1.1 scores 51 on the Intelligence Index

Vals AI

@ValsAI

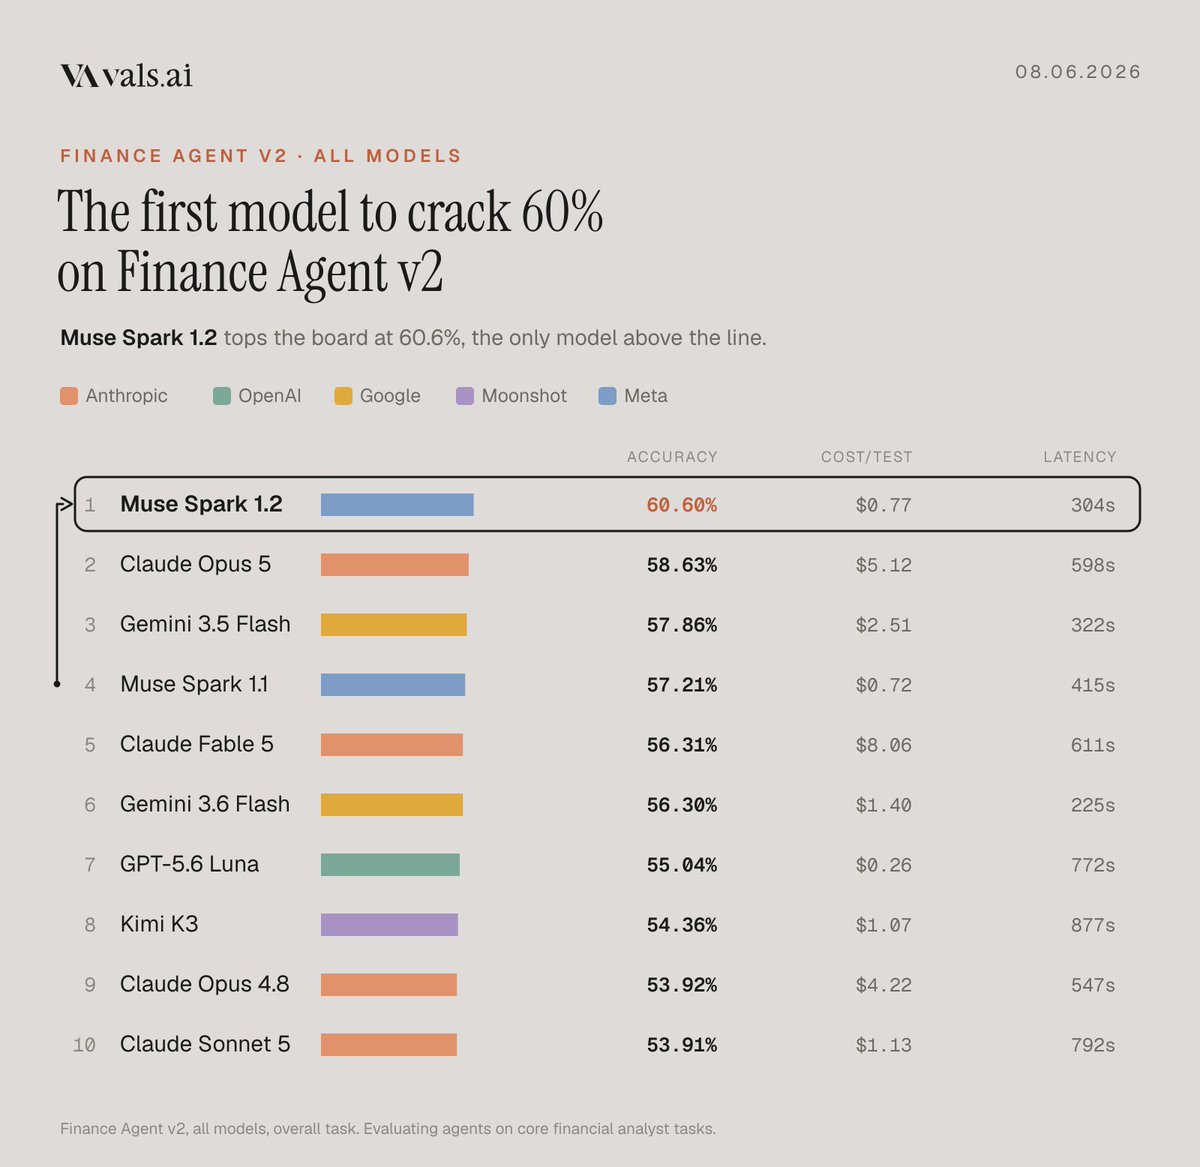
Muse Spark 1.2 is the first model to crack 60% on Finance Agent v2, our benchmark that gives models the job of a financial analyst. At $0.77/test it is 6.7x cheaper than the previous #1, Opus 5 ($5.12), at twice the speed.

X post · Benchmarks & research· ♥ 406

Spark 1.2 passes 60% on Finance Agent v2

W

@intheworldofai

@intheworldofai

WorldofAI benchmarks Muse Glimmer 30B on consumer hardware with a self-built test harness and compares it against Qwen 3.6 27B.

Video · Benchmarks & research

Muse Glimmer 30B vs Qwen 3.6 27B, fully tested

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Peter James

@heypeterjames

By chatting normally with the Muse iOS app I was able to have it send a zip of its entire filesystem from the linux root to my Google Drive via the google connector. /home/hatch is the agents home and contains top level files live soul.md, identity.md, memory, tools, and more

X post · Benchmarks & research· ♥ 3

Exporting the Muse agent filesystem

taylorarndt.substack.com

taylorarndt.substack.com

Taylor Arndt tested Muse with VoiceOver and found non-standard text fields and missing heading structure in chats, plus connector gaps such as iCloud email that kept it out of her work.

Resource · Benchmarks & research

I tried Meta's Muse agent: an accessibility review

@accretional

@accretional

Unofficial knowledge base and tools for Meta's Muse Spark, starting with a root-cause write-up of Codex tool-calling failures with Muse Spark 1.1.

Skill · Benchmarks & research· ★ 3

awesome-muse-spark

M

@MattJohnstonai

@MattJohnstonai

Matt Johnston runs Muse Spark 1.3 blind through his benchmark: a Halo build looked frontier, but XCOM, Diablo and the multi-turn agentic test broke.

Video · Benchmarks & research· ♥ 31

Muse Spark 1.3 run blind through a coding gauntlet

@nisten

@nisten

A single static HTML page that renders every weight tensor of Muse Glimmer 30B in 3D, sized by bits on disk, with educational notes on each layer.

GitHub · Benchmarks & research

3D weight visualization of Muse Glimmer 30B

U

MajesticAd2862

u/MajesticAd2862

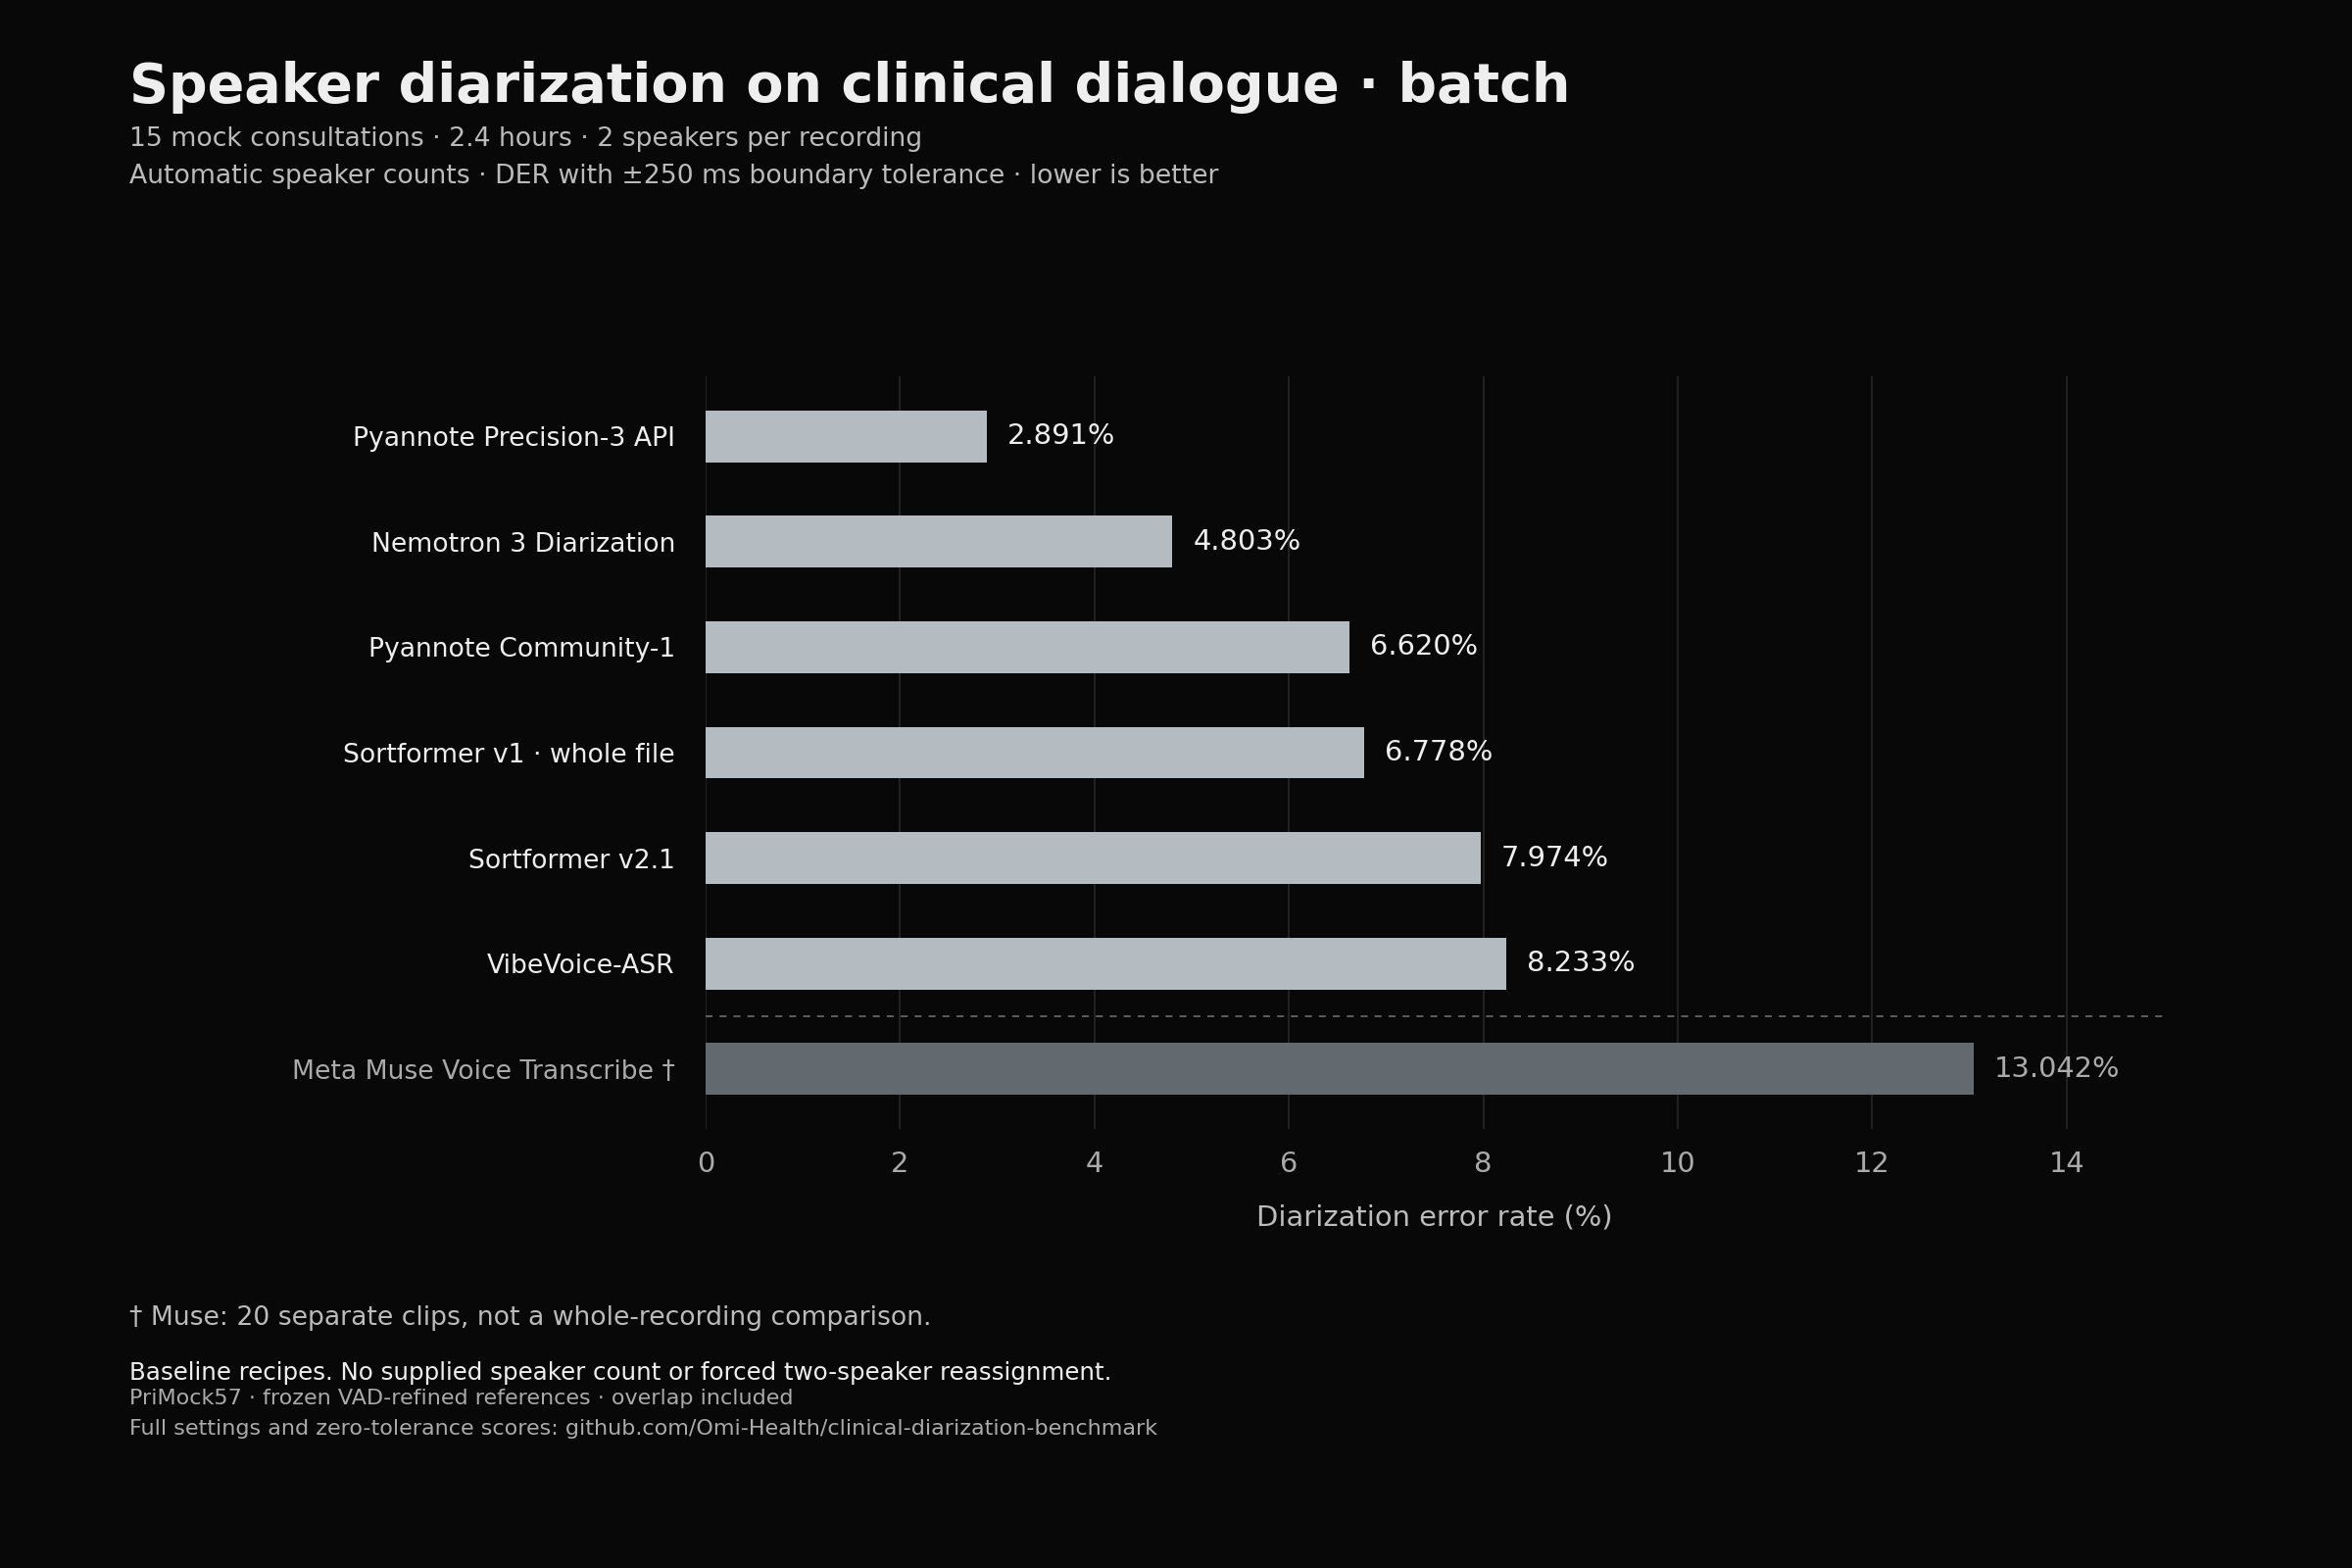
I've been working on clinical speaker attribution at Omi and wanted to compare the current diarization models on the same audio. I used 15 mock doctor–patient consultations from PriMock57, about 2.4 hours. Full recordings, automatic speaker counts, without telling the models there are two people. Batch Diarization error rate (DER), with ±250 ms boundary tolerance. Lower is better. Model DER Median processing time Pyannote Precision-3 2.891% 18.9 s / recording (API) Nemotron 3 4.803% 0.688 s / recording Pyannote Community-1 6.620% 18.691 s / recording Sortformer v1 6.778% 3.869 s / recording Sortformer v2.1 7.974% 1.077 s / recording VibeVoice-ASR 8.233% 123 s / recording Meta Muse Voice Transcribe † 13.042% 92 s / request (API) Local models ran on one NVIDIA L4. API times include round-trip overhead; VibeVoice-ASR also performs transcription. † Muse used 20 separate clips because of its 10-minute request limit, so its result isn't a whole-recording comparison. Pyannote Precision-3 had the lowest error. Nemotron came next and was the fastest local model. Streaming Model DER Pyannote live API 3.959% Nemotron 3 † 4.971% Sortformer v2.1 † 6.958% VibeVo

Reddit post · Benchmarks & research

Muse Voice Transcribe tested on clinical diarization

139 builds · page 2 of 4

Want more AI builds?artificialbuilds.com