№ 0048Resource
Muse Glimmer 30B architecture notes
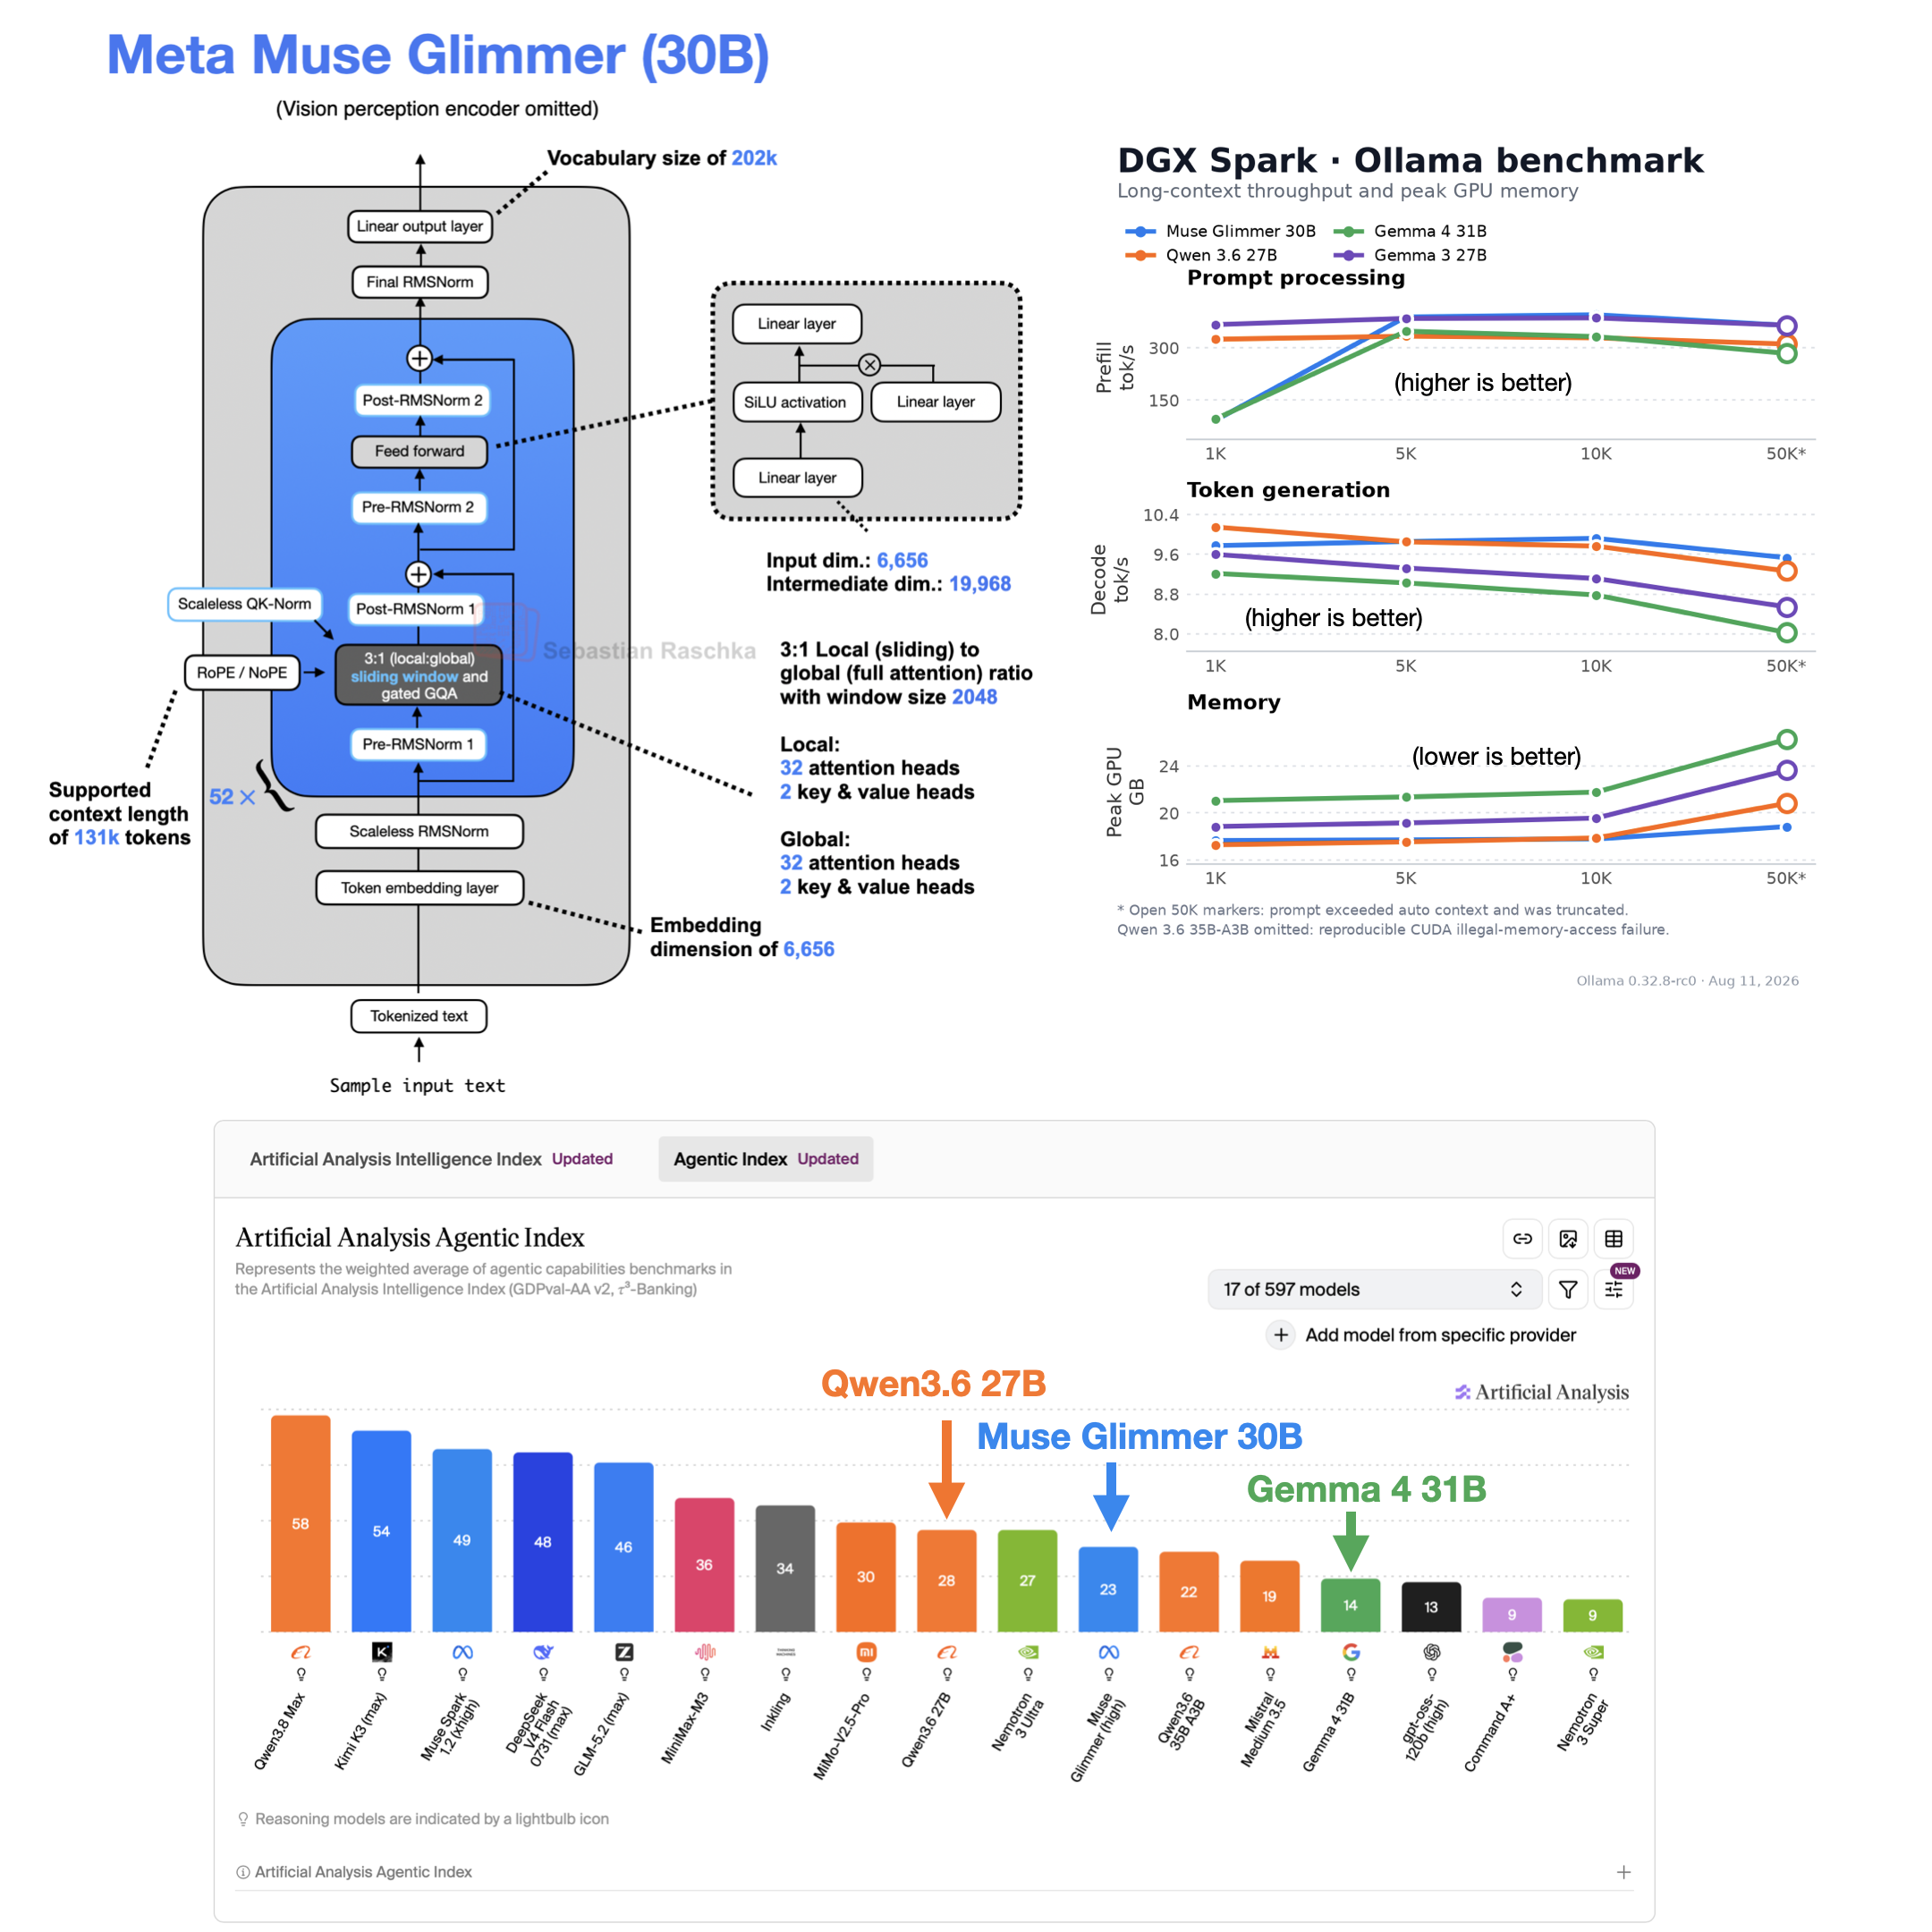
Sebastian Raschka breaks down Glimmer's dense architecture: 3:1 sliding-window to global attention, 32 query heads with only 2 KV heads, and ~52 KiB of KV cache per token.
He notes the model has a 131K context window and no mixture-of-experts, and that it lands slightly behind Qwen3.6 on composite indexes while being more KV-cache efficient.



 ChatForm
 Tgmlabs