№ 0070Reddit post
Glimmer vs Qwen 3.8 on an implicit-knowledge eval
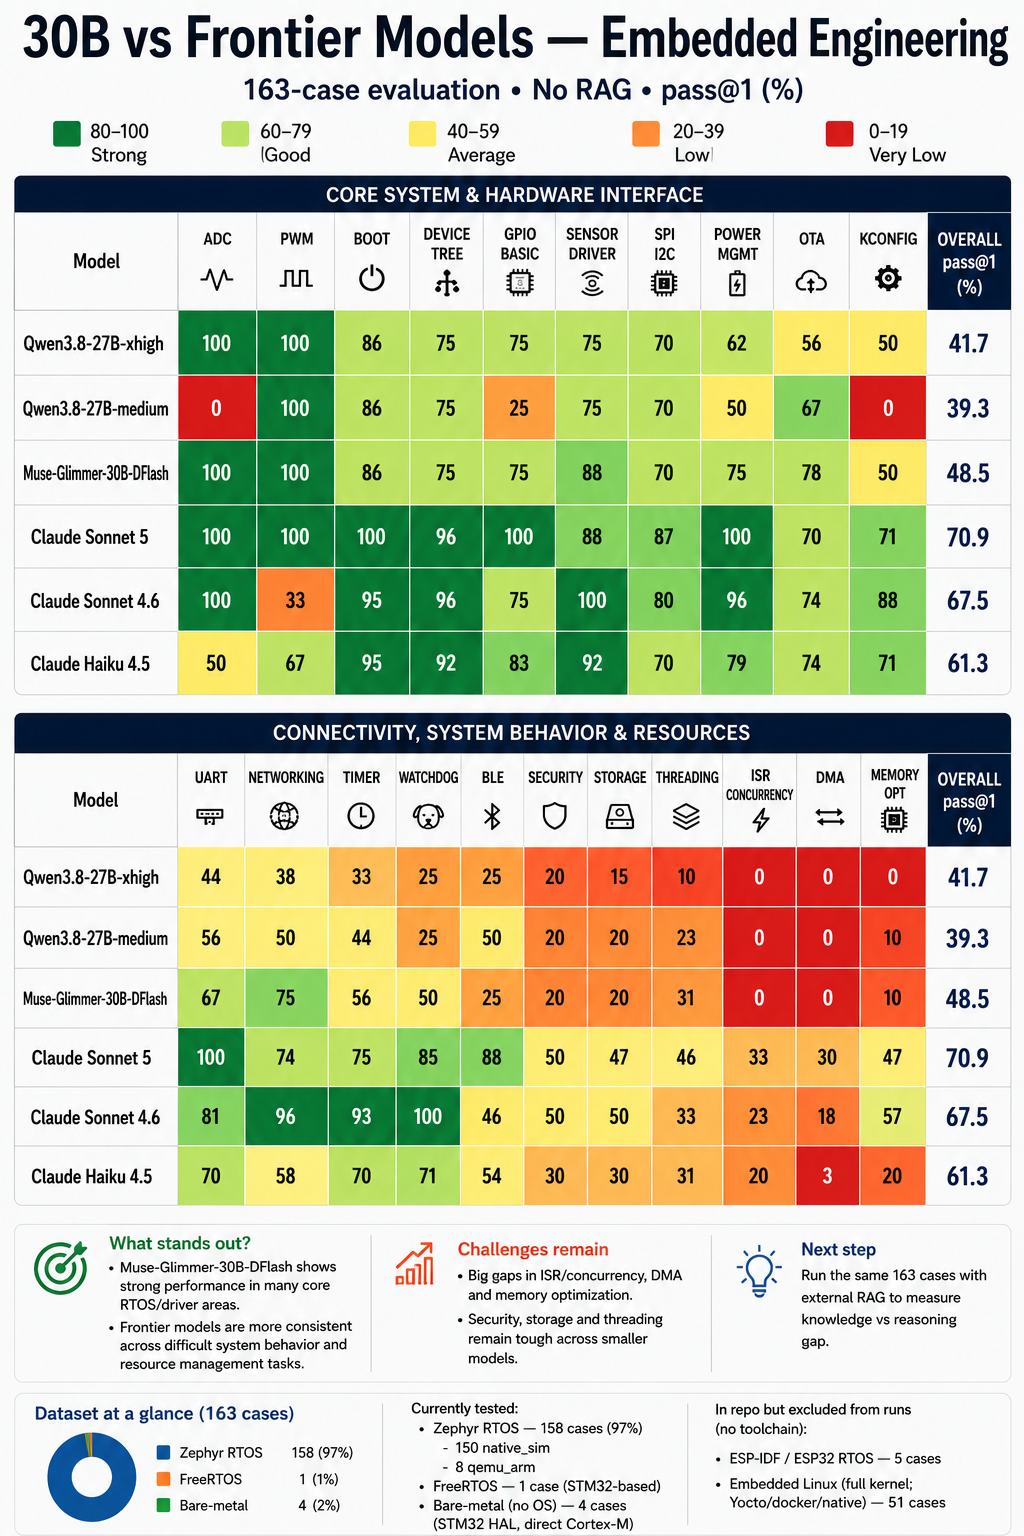
Benchmarked Qwen 3.8 (xhigh, medium) against Muse Glimmer; Glimmer finished in 3-4 hours vs ~30 hours for xhigh and scored better than Qwen.
u/Ok-Inevitable8391 ran an implicit-knowledge benchmark (comparing against Claude results from the embedeval repo). Qwen 3.8 xhigh took almost 30 hours and still failed 16 cases on the 32K output limit, while medium and Muse Glimmer took 3-4 hours each, with Glimmer scoring better than Qwen. They credit its sliding-window KV cache for efficient long context.
Underrated Muse Glimmer
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.



 ChatForm
 Tgmlabs