shipwithmuse

Entries matching “apple-silicon”

18 builds · page 1 of 1

U

A-Rahim

u/A-Rahim

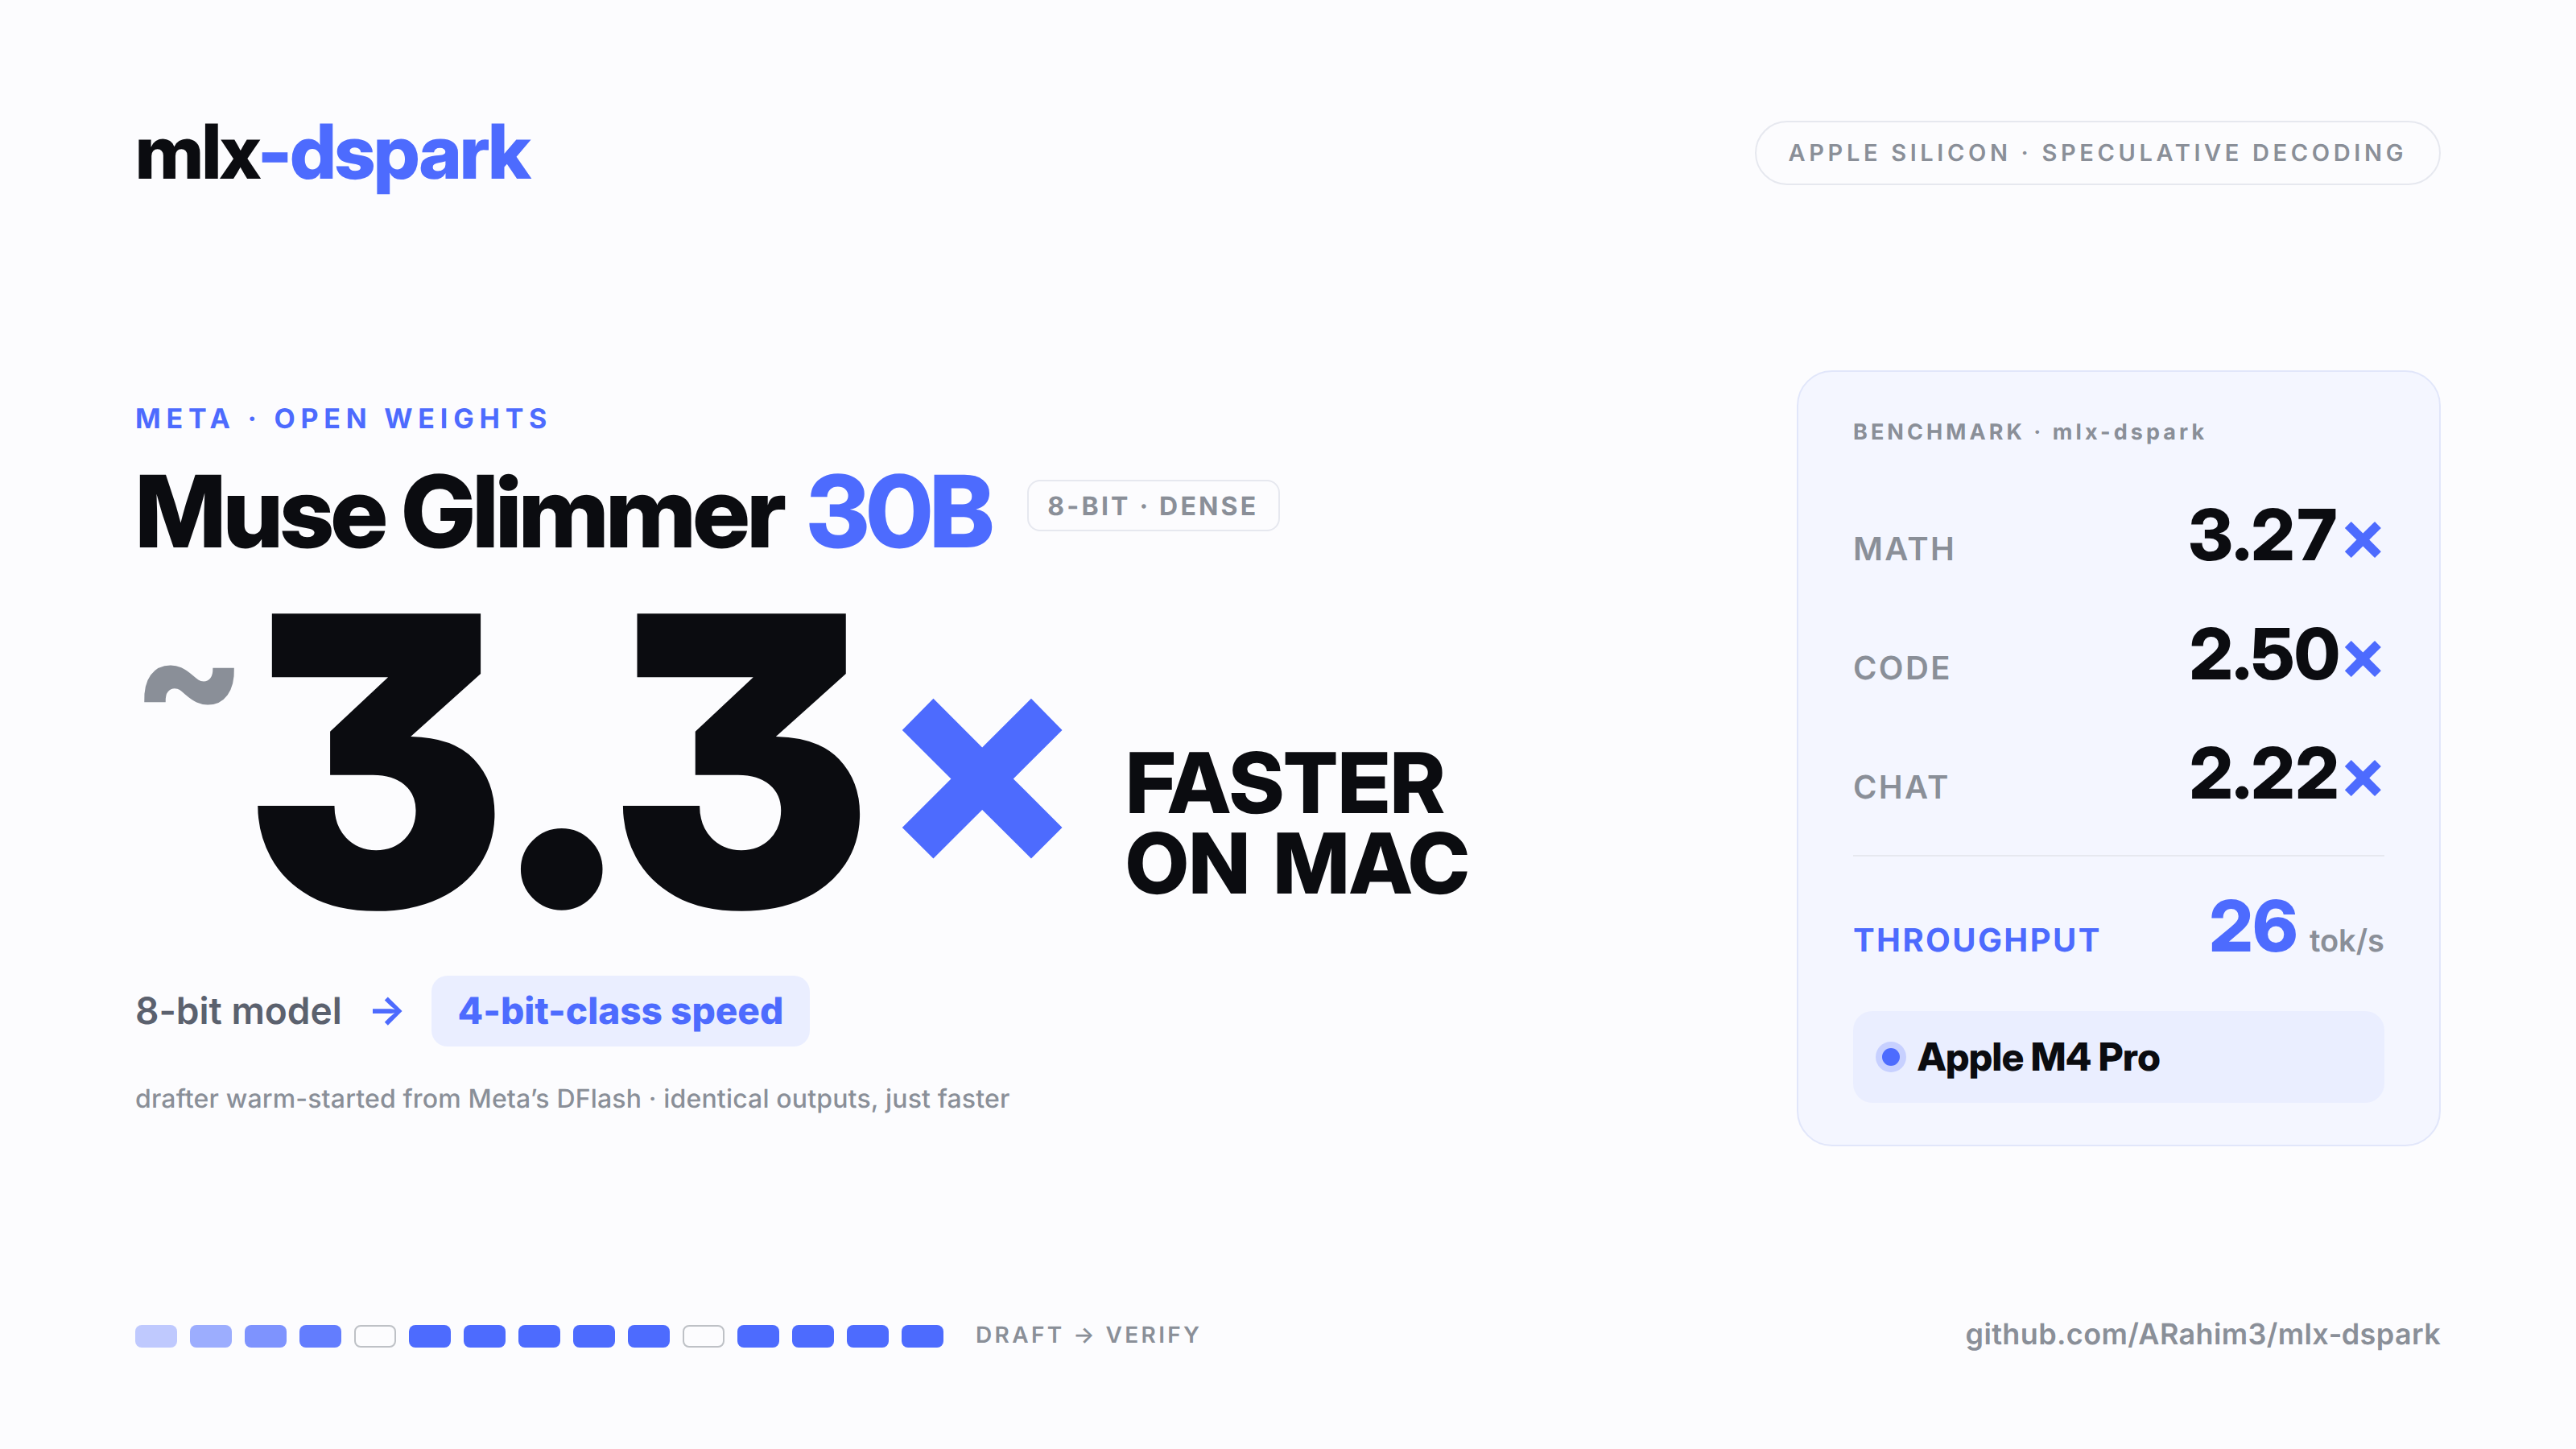
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster. Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed. Repo: github.com/ARahim3/mlx-dspark I'm happy to hear feedback, and I'm curious about what other M-series chips get.
Reddit post · Local & open models★ Pick
Muse Glimmer 3.3x faster on Mac with mlx-dspark

M

mlx-community

mlx-community

mlx-community's 4-bit MLX conversion of Muse Glimmer 30B made with mlx-vlm 0.6.12 for Apple Silicon.

Resource · Local & open models· ♥ 18

MLX 4-bit Muse Glimmer

@mitchallen

@mitchallen

A Makefile that downloads the three Muse Glimmer 30B GGUFs and builds and serves llama.cpp on Apple Silicon, automating a scriptable.com walkthrough.

GitHub · Local & open models

Muse Glimmer llama.cpp Makefile for macOS

@mapleroyal

@mapleroyal

A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.

GitHub · Local & open models

Muse Glimmer MLX playground

ollama

@ollama

Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and

X post · Local & open models· ♥ 1.3K

Muse Glimmer on Ollama's MLX engine

@nicedreamzapp

@nicedreamzapp

An architecture port adding the muse_glimmer model class (vision tower, language model, projector and image processor) to mlx-vlm, so any Muse Glimmer checkpoint runs multimodally on Apple Silicon.

GitHub · Local & open models

mlx-vlm support for Muse Glimmer

@tanishq-dubey

@tanishq-dubey

A reproducible Apple Silicon harness that runs six fixed quality tasks against MLX quantizations of Muse Glimmer 30B and records scores, tokens per second, peak memory and load time.

GitHub · Benchmarks & research

Muse Glimmer 30B MLX benchmark harness

SGLang

@sgl_project

SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer. ~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX. Huge thanks to the NVIDIA and Meta teams for the

X post · Local & open models· ♥ 95

SGLang day-0 serving for Glimmer

@LilMuh

@LilMuh

Since Muse for Mac ships only for Apple silicon, this small service lets Muse's cloud VM screenshot, click and type on an Intel Mac, compressing each 5K frame to about 150 KB and handling Retina coordinate scaling.

GitHub · Errands & personal agent· ★ 1

Muse remote-control bridge for Intel Macs

@High-Performance-AI-Lab

@High-Performance-AI-Lab

A 40-chapter book on Muser, an engine that runs Muse Glimmer on Apple Silicon Metal. It covers kquant and DFlash speculative lanes, exact KV-cache replay with kvpack, and GB10 NVFP4 prefill handed off to a Mac, with every number tied to an evidence receipt.

GitHub · Local & open models· ★ 3

The Muser book: how to write an inference engine

B

brenden7158

brenden7158

An unofficial parody MLX-VLM QLoRA adapter for Muse Glimmer 30B on Apple Silicon.

Resource · Local & open models· ♥ 1

ZuckLM parody MLX LoRA

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@brad-richardson

@brad-richardson

An experimental Rust and Metal inference runtime for Muse models on Apple Silicon, currently supporting Muse Glimmer, using llama.cpp as the correctness and speed baseline.

GitHub · Local & open models

Muse Metal

@GordonWei

@GordonWei

An OpenAI-compatible /v1/chat/completions server that runs Muse Glimmer on Apple Silicon through mlx_vlm while LM Studio's bundled MLX runtime can't yet load the architecture.

GitHub · Local & open models

museglimmer-shim

@brn715

@brn715

A deliberately overengineered parody that 'gives you the Zuck', with a deterministic Oracle edition, a prompted Muse Glimmer edition and an MLX QLoRA fine-tune of Muse Glimmer 30B for Apple Silicon.

GitHub · Content & creative

ZuckLM

@kevinzhao-dev

@kevinzhao-dev

A starter script that downloads Muse Glimmer 30B, serves it with llama.cpp on an Apple Silicon Mac and connects it to OpenCode, with the server listening only on localhost.

GitHub · Local & open models

Muse Glimmer starter script

@PipeNetwork

@PipeNetwork

muse-glimmer-mlx is an MLX port of Muse Glimmer 30B for Apple Silicon that supplies the missing runtime so the many unloadable MLX conversions published on Hugging Face can actually be run.

GitHub · Local & open models

MLX runtime for Muse Glimmer 30B

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@High-Performance-AI-Lab

@High-Performance-AI-Lab

muser is a standalone inference engine for Muse Glimmer 30B on Apple Silicon Metal, with an optional disaggregated lane where an NVIDIA GB10 node prefills in NVFP4 and hands the KV cache to the Mac.

GitHub · Local & open models

muser inference engine for Muse Glimmer

O

ollama.com

ollama.com

Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.

Site · Local & open models

Muse Glimmer in the Ollama library