№ 0136Reddit post
Census of a 77k Instagram story archive
A resumable prompt that has Muse page through the Instagram connector's instagram-cli to count a 77k-story archive, saving cursor state every 10 pages.
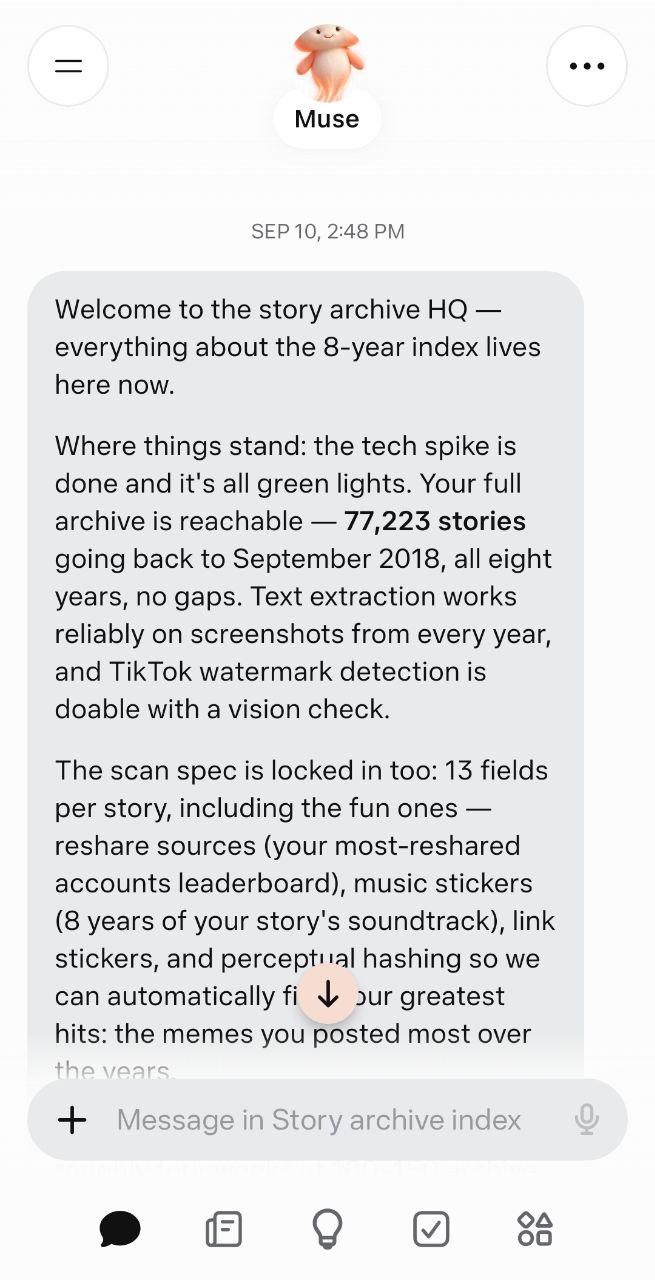
u/6353JuanTaboApp6 shared a 'Story Archive Census' prompt: Muse calls instagram-cli own-stories-archive one page (~20 stories) at a time, following next_max_id cursors, writing a state file every 10 pages so it can resume, and reporting totals and date range. They used it on a 77k-story archive.
Muse is cataloging my 77k Instagram story archive for free. incredible 🔥
theres simply no other AI agent or tool that can do this for you for free
PROMPT
Story Archive Census
What to do
Your human wants a full census of their Instagram story archive. Read this entire file, then follow the steps in order. The job is a census: walk every page and count every story, newest to oldest. It does not download any media.
What you're working with:
Tool — the Instagram connector's command line tool, instagram-cli.
Command — one call returns one page of archived stories (about 20 per page), newest first. Each page hands back a next_max_id cursor pointing at the next page:
instagram-cli own-stories-archive --account-id <YOUR_ACCOUNT_ID>
Workflow
1. Walk the archive
Fetch the first page with no cursor.
For each page, record the page number, the story count, the newest story date, the oldest story date, and the
next_max_id.Feed that
next_max_idback as--max-idon the next call, and keep going.One call at a time, a second or two apart. No parallel calls.
2. Save progress
- Write the page records plus the latest cursor to a state file every 10 pages, so the run can resume after an interruption instead of sta