Solo-built GGUF line of Muse Glimmer 30B with custom calibration, per-tensor allocations and an eval harness behind every reported number.
Resource · Local & open models· ♥ 21
Catalog / Use case
196 reports of running Muse Glimmer 30B locally: GGUF and MLX quants, DFlash speculative decoding, GPU benchmarks, Mac setups and fine-tunes.
Solo-built GGUF line of Muse Glimmer 30B with custom calibration, per-tensor allocations and an eval harness behind every reported number.
Resource · Local & open models· ♥ 21
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Cline
@cline
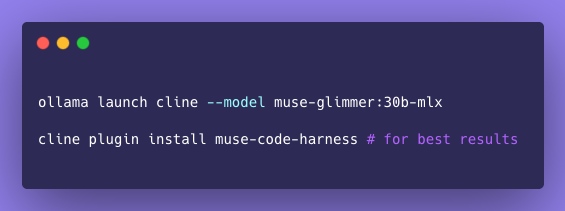
The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now!
X post · Local & open models· ♥ 157

Paolo Rosson
@redp314
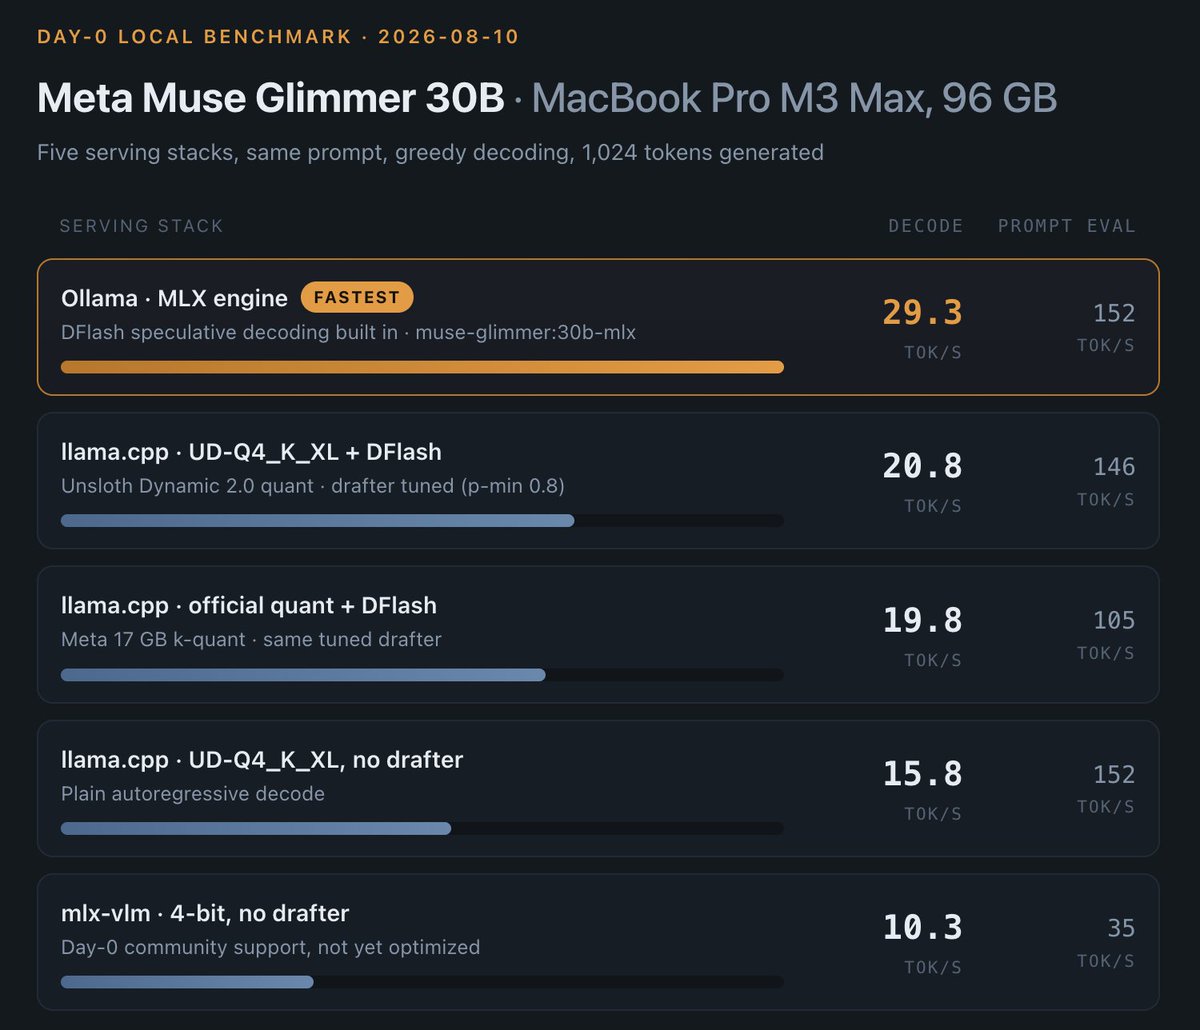
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're
X post · Local & open models★ Pick· ♥ 44

kwindla
@kwindla
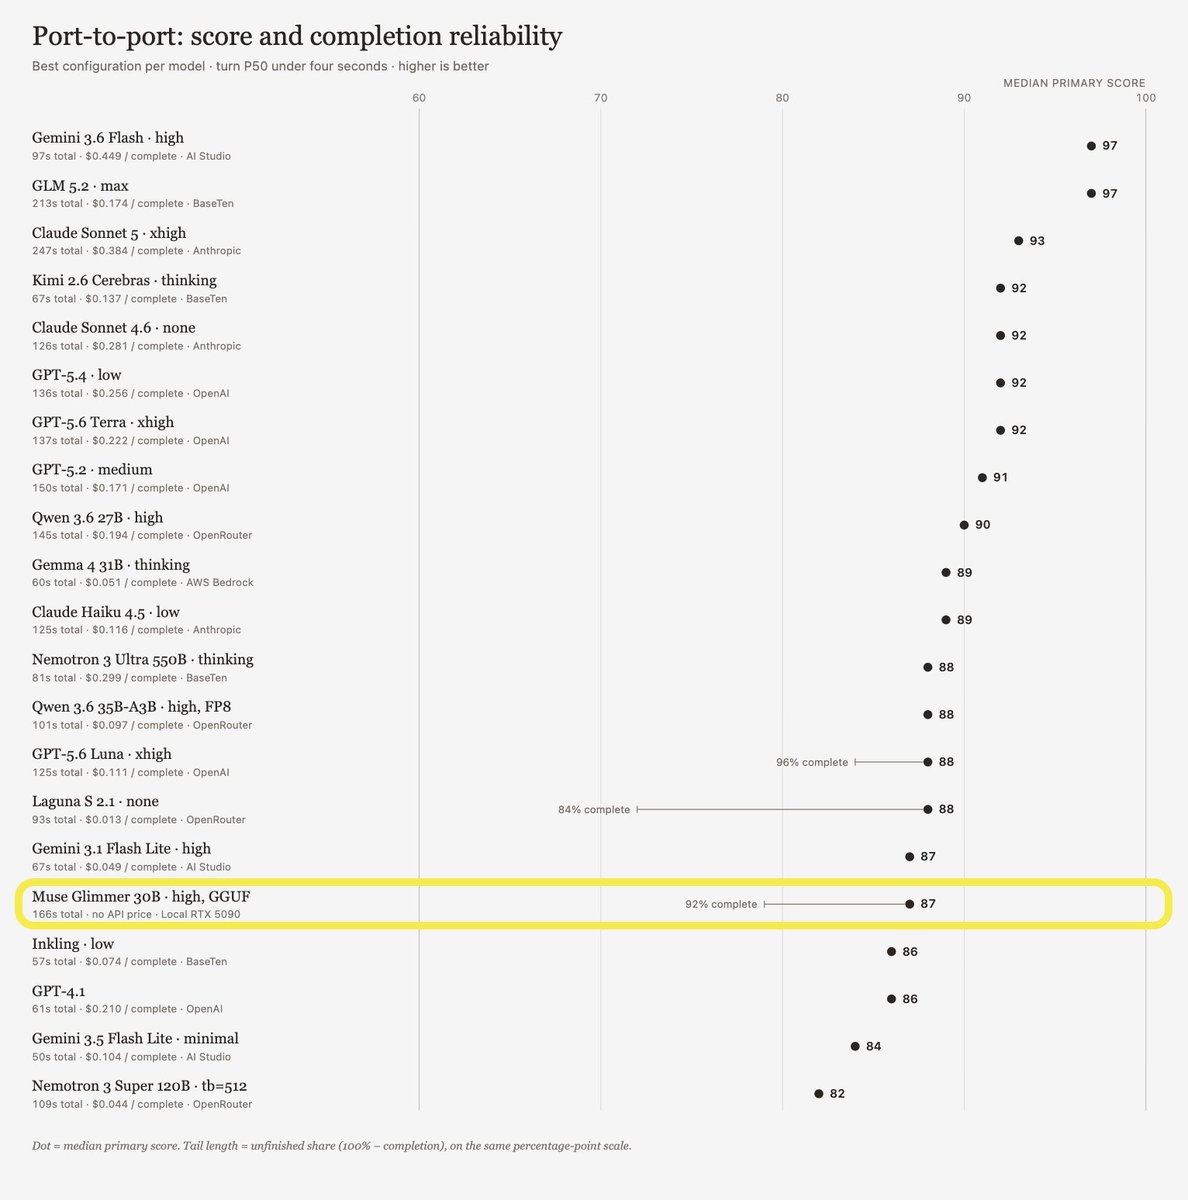
Exciting to see Meta releasing new open weights this week. Meta trained the new 30B dense model Muse Glimmer with "agentic" use cases in mind. This generally means task-oriented, multi-turn, and heavy use of tool calling. I ran Muse Glimmer in the GGUF quant through a bunch of
X post · Local & open models· ♥ 29
A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.
GitHub · Local & open models
A suite of 27 GGUF quantizations of an abliterated Muse Glimmer 30B produced with Heretic v1.4.0.
Resource · Local & open models· ♥ 20
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
mlx-community's 4-bit MLX conversion of Muse Glimmer 30B made with mlx-vlm 0.6.12 for Apple Silicon.
Resource · Local & open models· ♥ 18
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.
Resource · Local & open models
Resource · Local & open models· ♥ 18
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop. It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster. I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.
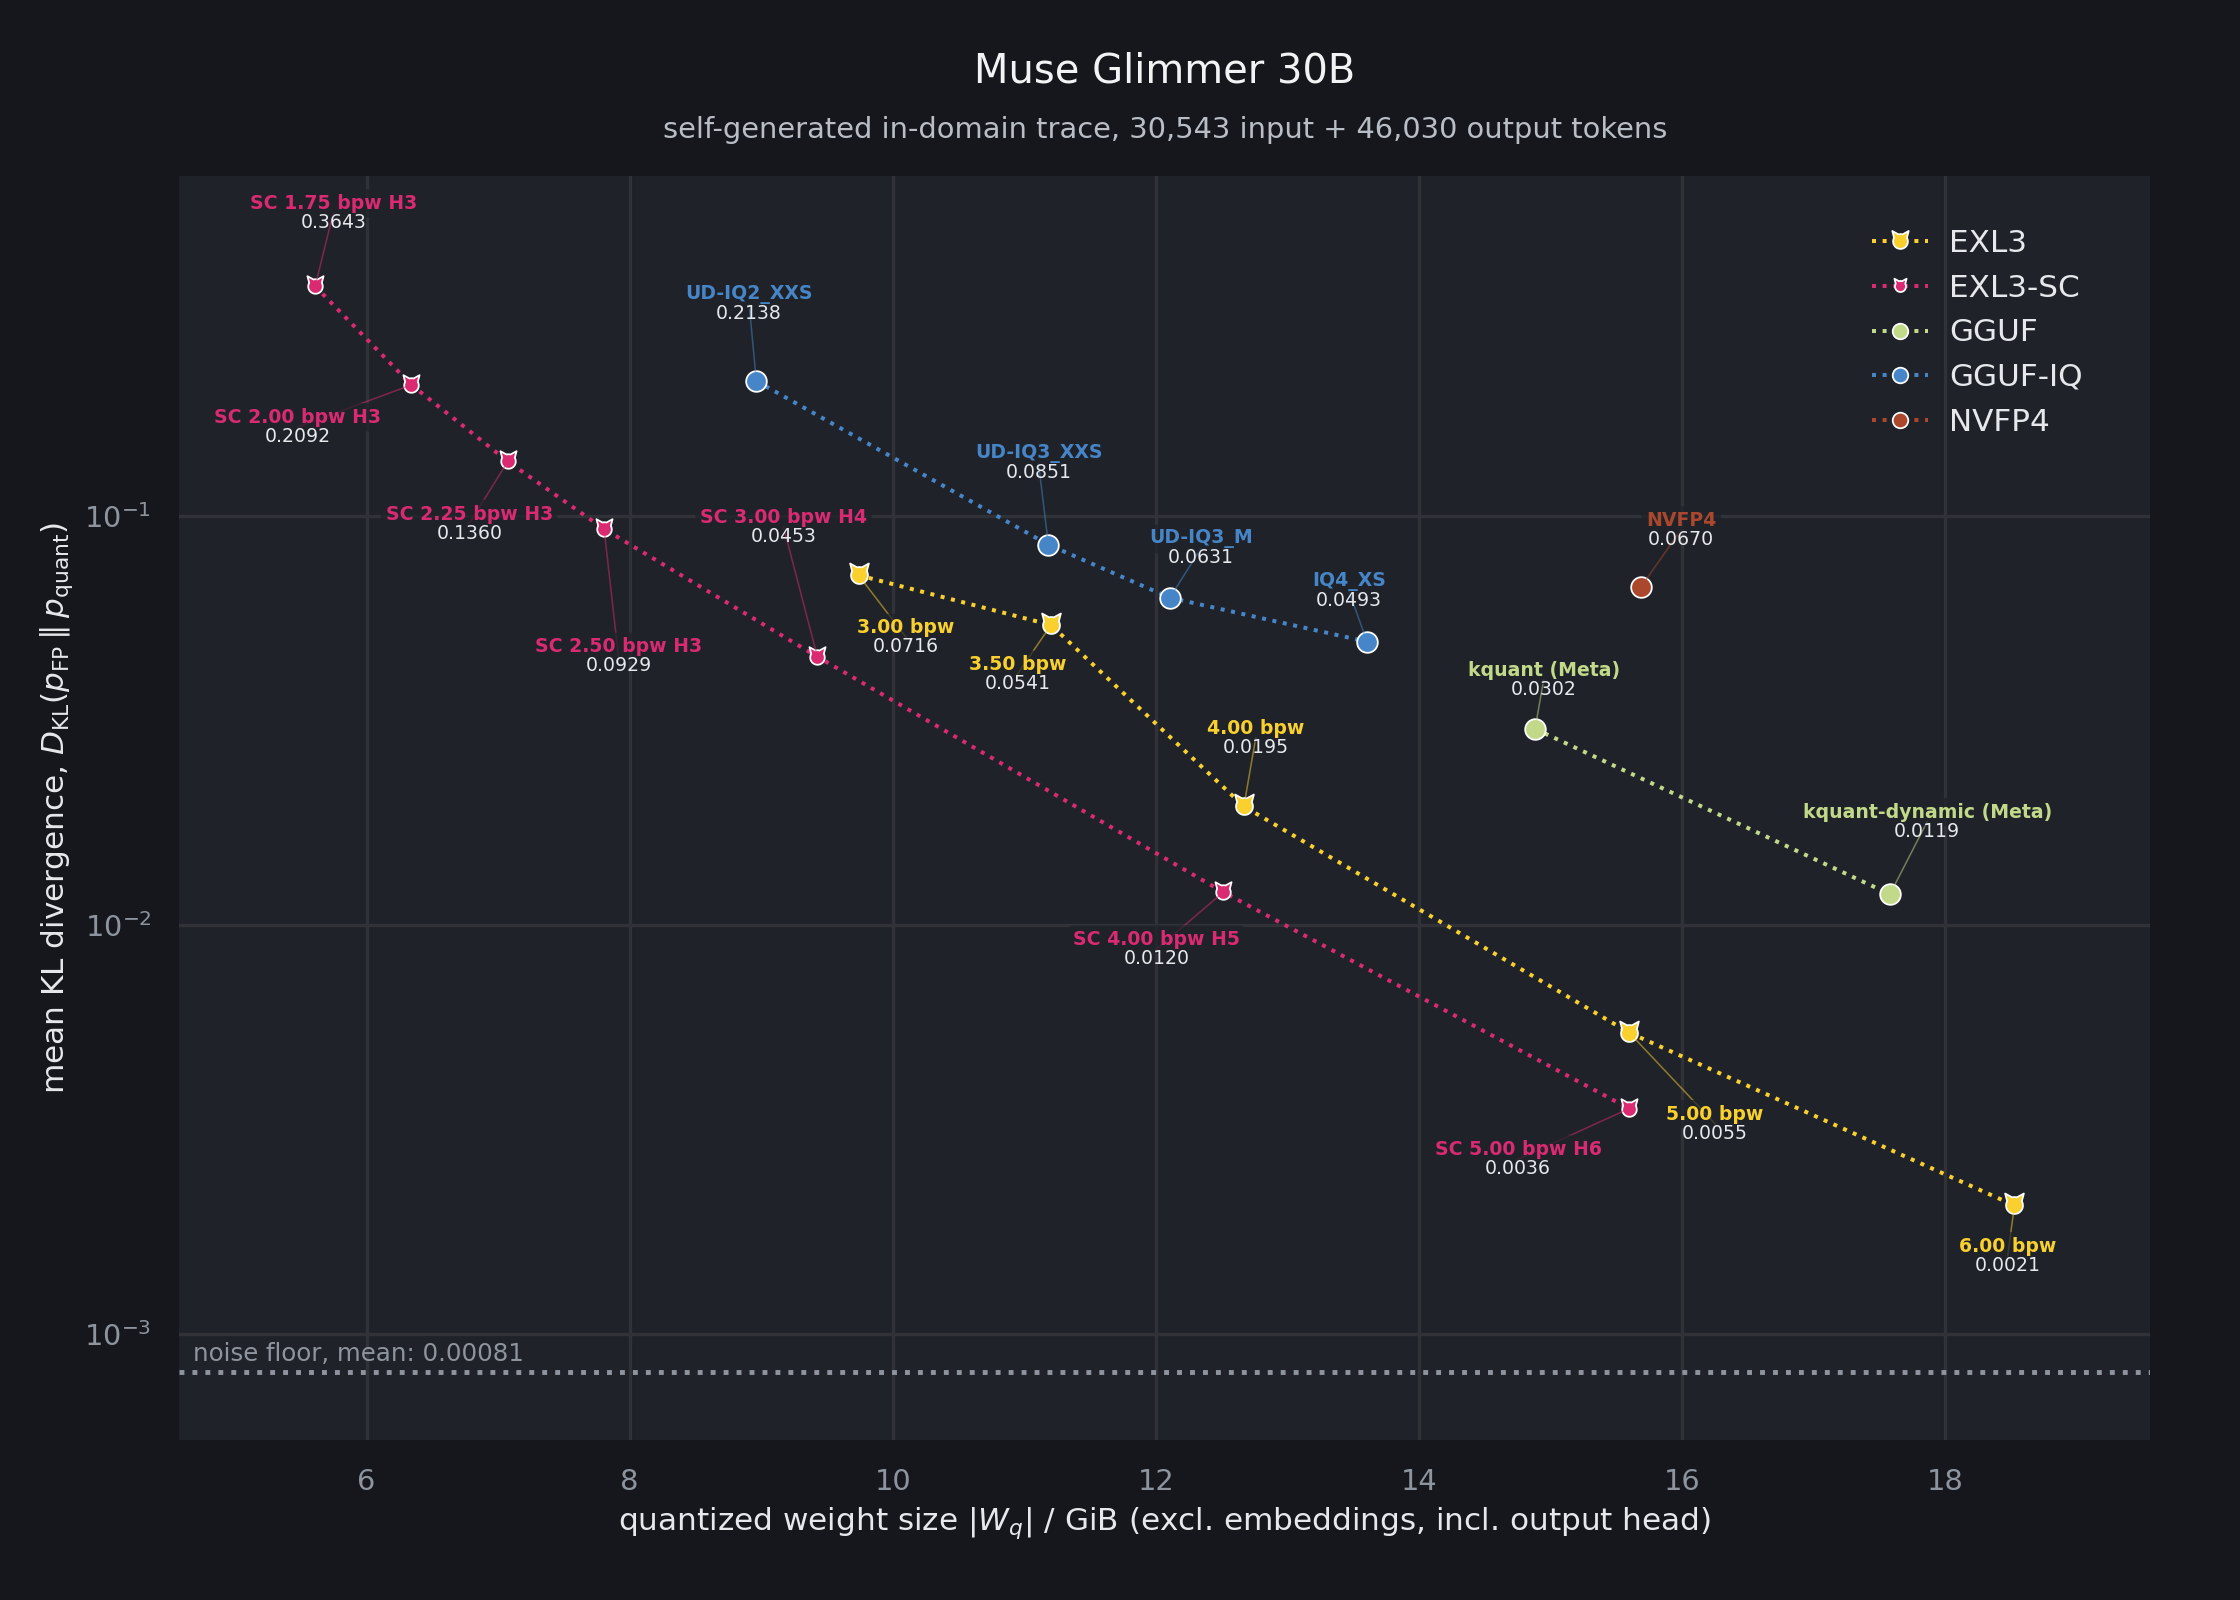
Reddit post · Local & open models★ Pick
Cobus Greyling's companion repo for Muse Glimmer 30B pairs a long-form intro with an offline-first interactive lab for exploring agent loops, benchmarks and memory envelopes before downloading the weights.
GitHub · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.
GitHub · Local & open models

AI at Meta
@AIatMeta
For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to
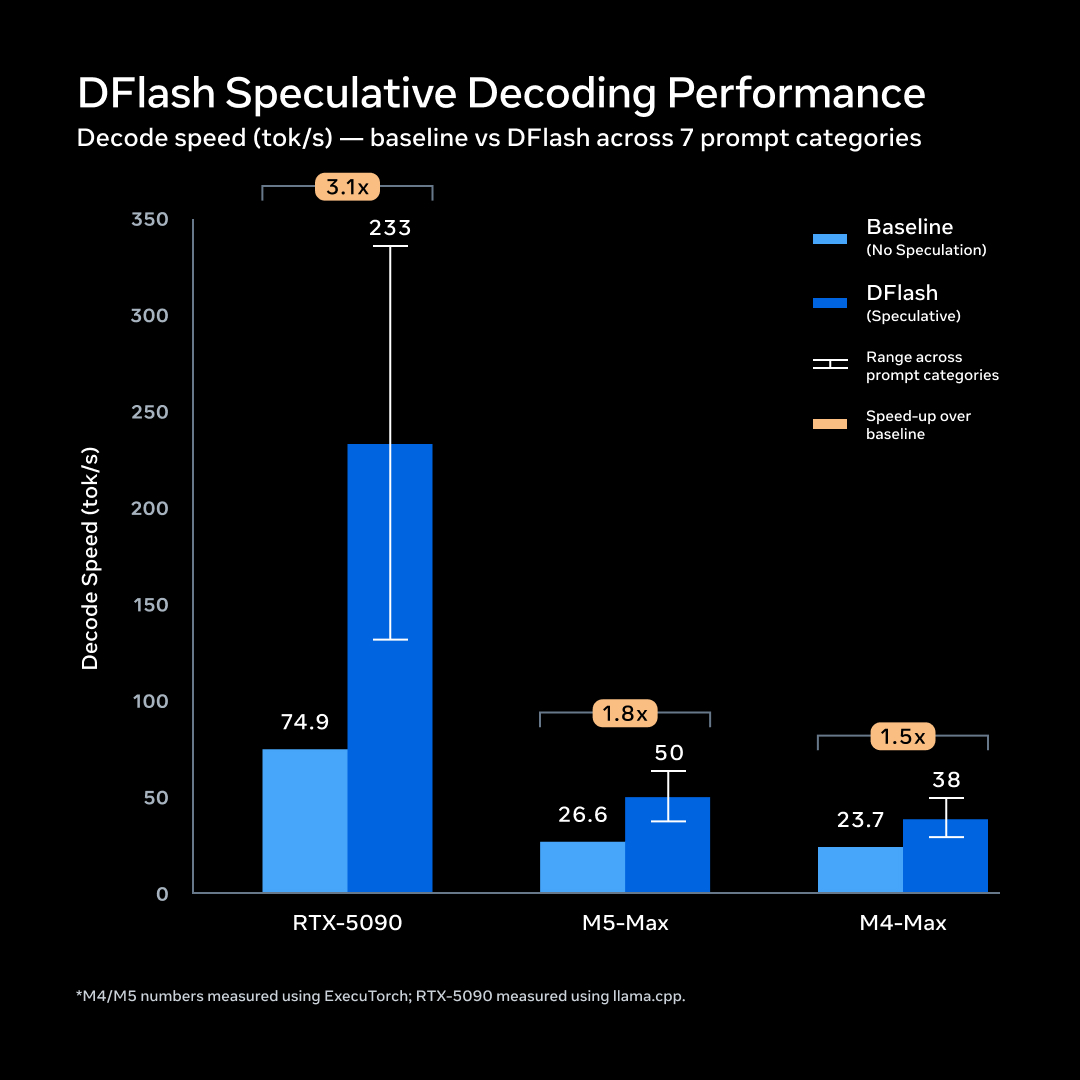
X post · Local & open models· ♥ 456
Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.
GitHub · Local & open models
Fireworks made Muse Glimmer 30B available on launch day, pitching high-concurrency, cost-effective serving for always-on agents.
Resource · Local & open models
Reproducible native NVFP4 serving of Muse Glimmer 30B on one DGX Spark (GB10) with unmerged vLLM support: about 10.3 tok/s single-stream versus 4.2 for BF16, 52.5 tok/s at c16, and 131K context checked with needle-in-a-haystack tests.
GitHub · Local & open models
QUASAR-trained Blackwell W4A4 build of Muse Glimmer 30B at 21.8 GiB, reporting 20% lower KL to BF16 than Red Hat's NVFP4 W4A4 checkpoint.
Resource · Local & open models· ♥ 3
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
Picked up China version of the Mi50 (Radeon VII) 16GB VRAM GPU for about $135. Ran it using llama.cpp Ubuntu Vulkan prebuilt binary build: b29c606e2 (10964). Used a Power Limit or 220/190 watts on the GPUs. Dual Radeon 32GB Vram and 64GB DDR4 System Dual Radeon RX 7900 GRE and Radeon VII 32gb VRAM GGUF Models: • Qwen3.6-35B-A3B-UD-Q5_K_XL.gguf • Accio-Lab_occamy-1.0-Q5_K_S.gguf • Laguna-XS-2.1-APEX-I-Balanced.gguf • NVIDIA-Nemotron-3.5-Lightning-30B-A3B-Q5_K_M.gguf • Gemma-4-31B-it-Q6_K.gguf • Ateron_Gemma-4-MoonGem-31B-Q5_K_M.gguf • Qwen3-Coder-30B-A3B-Instruct-UD-Q6_K_XL.gguf • Qwen3-VL-30B-A3B-Thinking-UD-Q6_K_XL.gguf • Qwen3-Coder-30B-A3B-Instruct-UD-Q5_K_XL.gguf • North-Mini-Code-1.0-MXFP4_MOE.gguf • GLM-4.7-Flash-Uncen-Hrt-NEO-CODE-MAX-imat-D_AU-Q6_K.gguf • Muse-Glimmer-30B-UD-Q6_K_XL.gguf • Huihui-Qwen3.8-27B-abliterated-UD-Q6_K_XL.gguf • Qwen3.8-27B-Q6_K.gguf • Qwen3.8-27B-OBLITERATED-Q5_K_M.gguf • Medgemma-27b-it-UD-Q6_K_XL.gguf • Gemma-4-26B-A4B-it-UD-Q6_K_XL.gguf • Gemma4-26B-A4B-QAT-Uncensored-HauhauCS-Balanced-Q4_K_M.gguf • GPT-OSS-20b-abliterated.i1-Q6_K.gguf Sorted by params then size model size params pp512 tg128 qwen35moe 35B.A3B Q5_K - Medium 24.76 GiB 3
Reddit post · Local & open models
Custom firmware and a Go server that turn an M5Stack StackChan into Tarquin, a voice-driven robot butler with wake word, face tracking and on-device speech, using Muse Spark 1.3 via the Meta Model API as its brain.
GitHub · Local & open models★ Pick
Meta's developer post on running Muse Glimmer on a single consumer GPU with vLLM, llama.cpp and ExecuTorch, with quantized builds in 24-32 GB and cookbook recipes.
Resource · Local & open models
This repo documents running Muse Glimmer 30B locally on an M4 Max MacBook via llama.cpp, benchmarking it with and without speculative decoding, and wiring it into Claude Code through LiteLLM for fully offline coding.
GitHub · Local & open models
Decensored Muse Glimmer 30B made with Heretic v1.4.0, shipped with a reproduce directory.
Resource · Local & open models· ♥ 15
A webml-community Space that runs Muse Glimmer 30B locally in the browser using custom WebGPU kernels.
Site · Local & open models· ♥ 15
The smallest and fastest MLX 4-bit (group size 64) Muse Glimmer checkpoint, served with SGLang's MLX backend on Macs with 48 GB+ unified memory.
Resource · Local & open models· ♥ 11
Unsloth Dynamic 2.0 GGUF quants of Muse Glimmer 30B with a companion run guide and thinking toggles.
Resource · Local & open models★ Pick· ♥ 548

Kyle Hessling
@KyleHessling1
First impressions on Muse Glimmer! It's incredibly fast for a dense model, currently running an average of 208tps with a max of 274tps on a single 5090 with their DFLASH config. Comparatively, though, both using Open Code, Qwopus Coder (with thinking off) produced a much
X post · Local & open models· ♥ 176
LM Studio launched Muse Glimmer support, reporting it completed 83.3% of tasks on its 18-task BionicBench v0.1 versus 77.7% for Gemma 4 31B and Qwen 3.6 27B.
Resource · Local & open models
Cloud Codes tests whether Muse Glimmer on a single 24GB VRAM GPU can compete with cloud coding agents in multi-step tool-calling loops.

Video · Local & open models· ♥ 182
A vLLM-XPU and DFlash recipe for Muse Glimmer 30B on a single Intel Arc Pro B70, reporting 278 aggregate tok/s across eight clients and an 840.8 tok/s burst peak at concurrency 96.
GitHub · Local & open models★ Pick· ★ 1

Alexandr Wang
@alexandr_wang
1/ big announcement today: we will be releasing an open weight version of muse spark 1.2 soon. we also are releasing muse glimmer, a 30B agentic model with open weights under apache 2.0. muse glimmer can run on 24GB of VRAM without losing agentic reliability. 🧵
X post · Local & open models★ Pick· ♥ 9.5K
Resource · Local & open models· ♥ 4
Resource · Local & open models· ♥ 14
Red Hat AI's FP8 weight and activation quantized Muse Glimmer 30B (text and image input) for vLLM.
Resource · Local & open models· ♥ 12
Simon Willison ran an 18.16GB build of Muse Glimmer locally, testing code exploration and image description. He found multi-step reasoning and tool use strong and creative generation mixed.
Resource · Local & open models

ollama
@ollama
Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and
X post · Local & open models★ Pick· ♥ 1.3K
A start/stop/status launcher that serves the NVFP4 Muse Glimmer 30B checkpoint on NVIDIA DGX Spark with vLLM, Glimmer's reasoning and tool parsers, and its DFlash speculative decoder.
GitHub · Local & open models· ★ 2

Unsloth AI
@UnslothAI
You can now fine-tune Meta Muse Glimmer 30B for free! 🔥 Our free notebook also supports GRPO RL training. Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM. Guide: unsloth.ai/docs/models/mu… Notebooks: unsloth.ai/docs/models/mu…
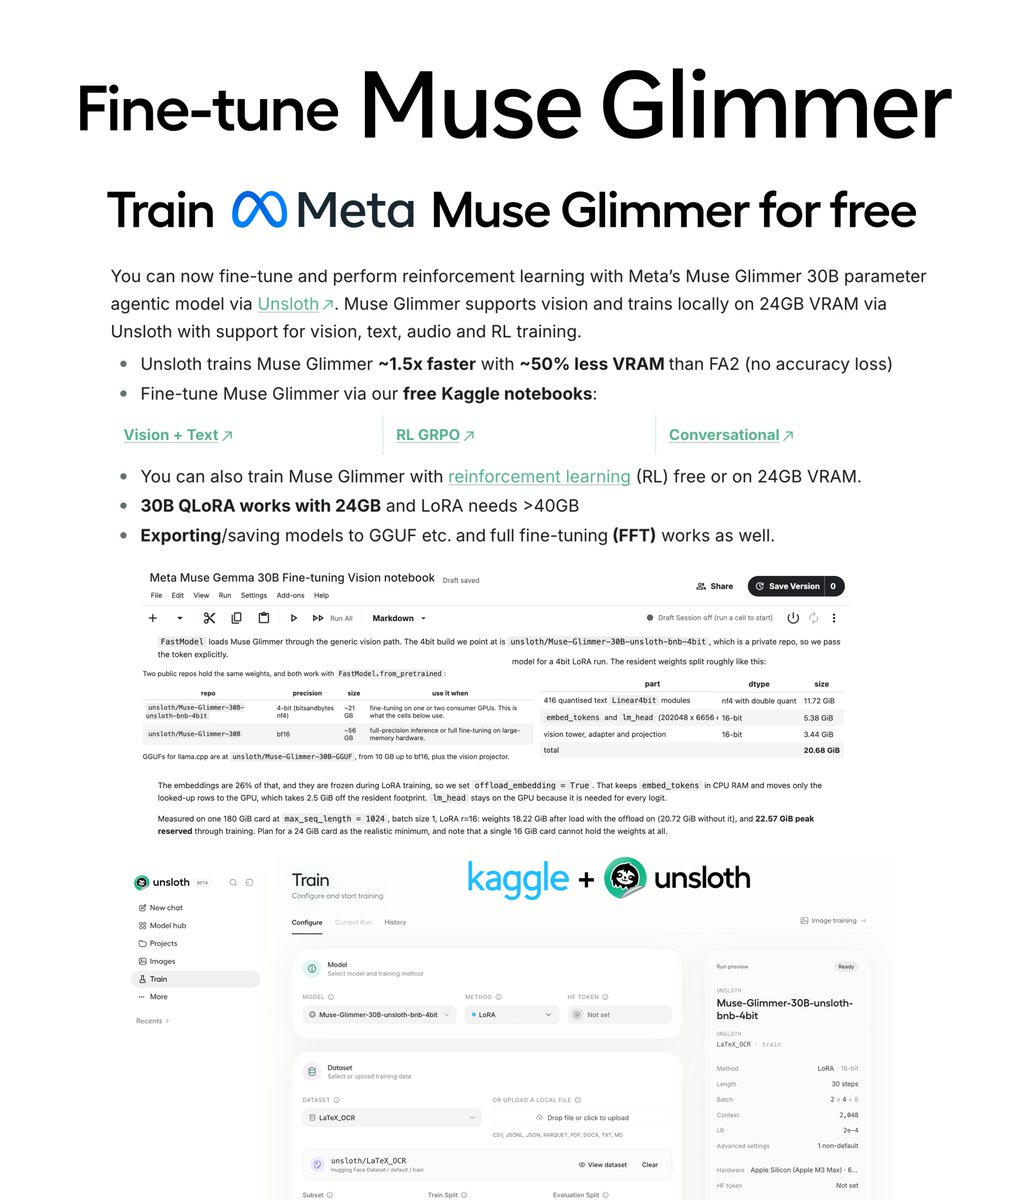
X post · Local & open models★ Pick· ♥ 631
GGUF quantizations of the Inco AI DFlash2 drafter for Muse Glimmer 30B, for use with the BeeLlama.cpp llama.cpp fork.
Resource · Local & open models· ♥ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
DFlash 2 speculative-decoding draft model for Muse Glimmer 30B from z-lab, run inside a speculative decoding server alongside the target model.
Resource · Local & open models· ♥ 15
196 builds · page 2 of 5