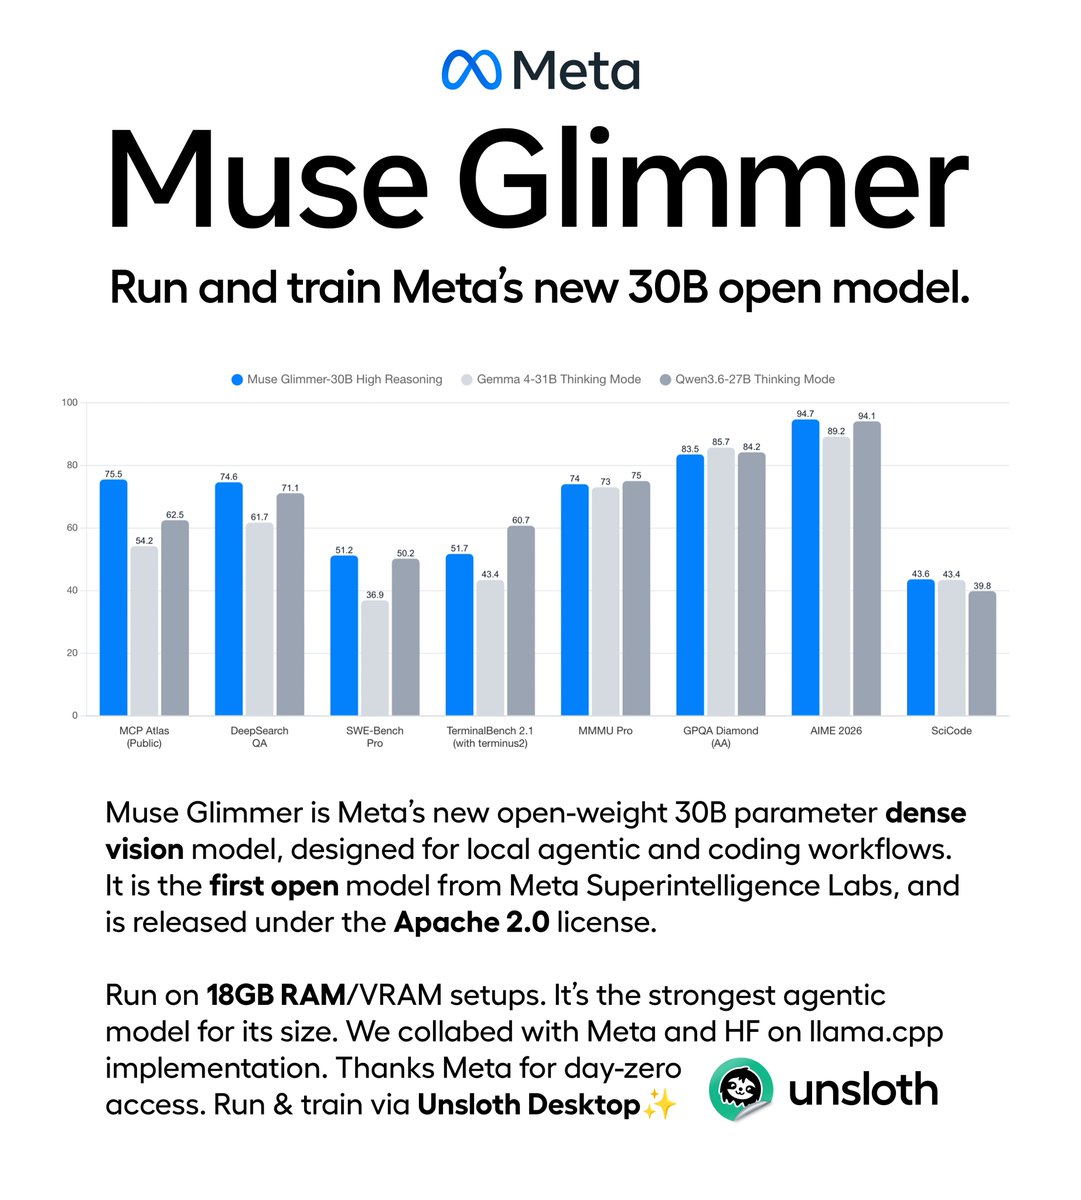
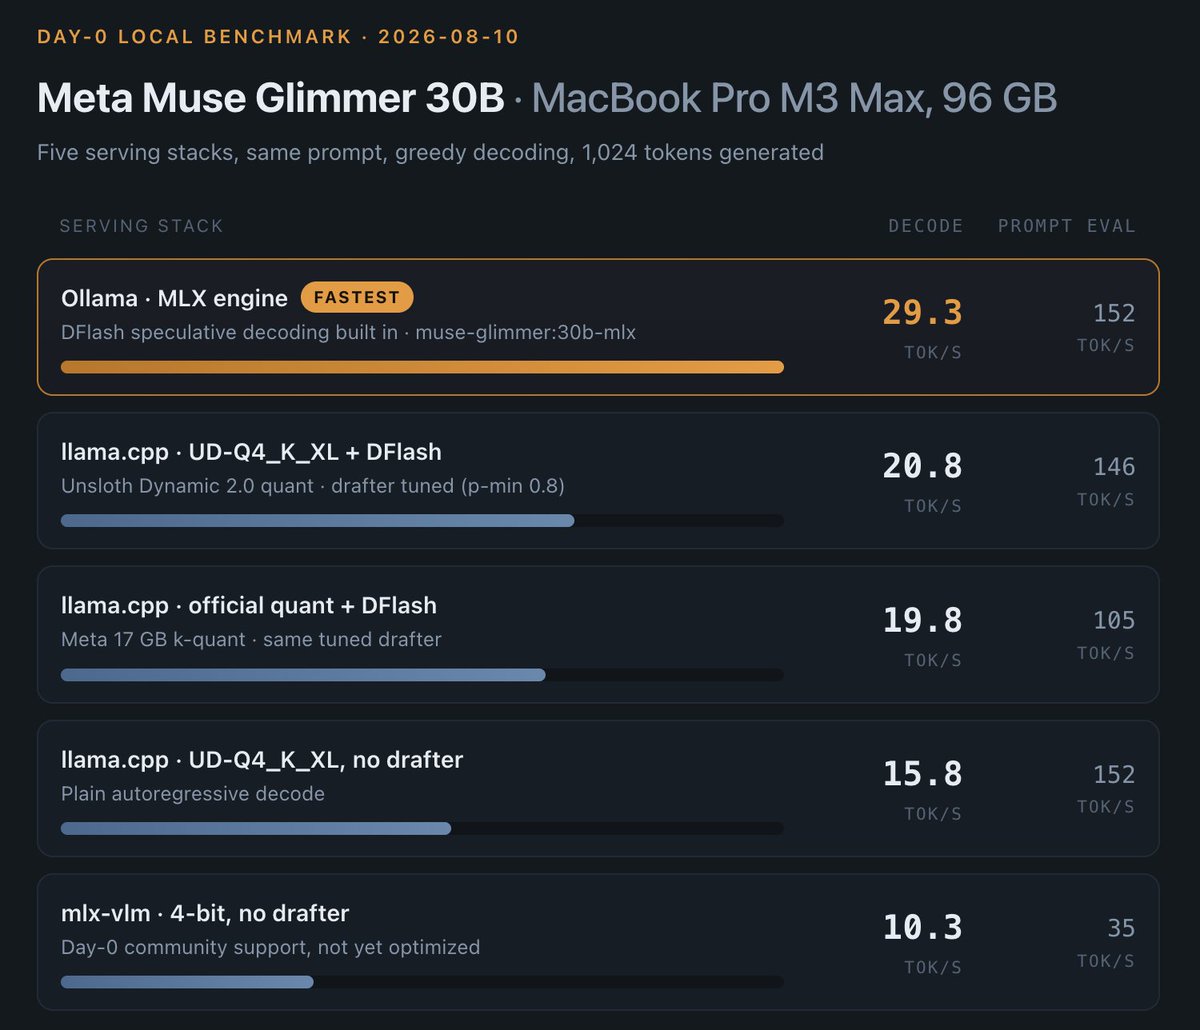
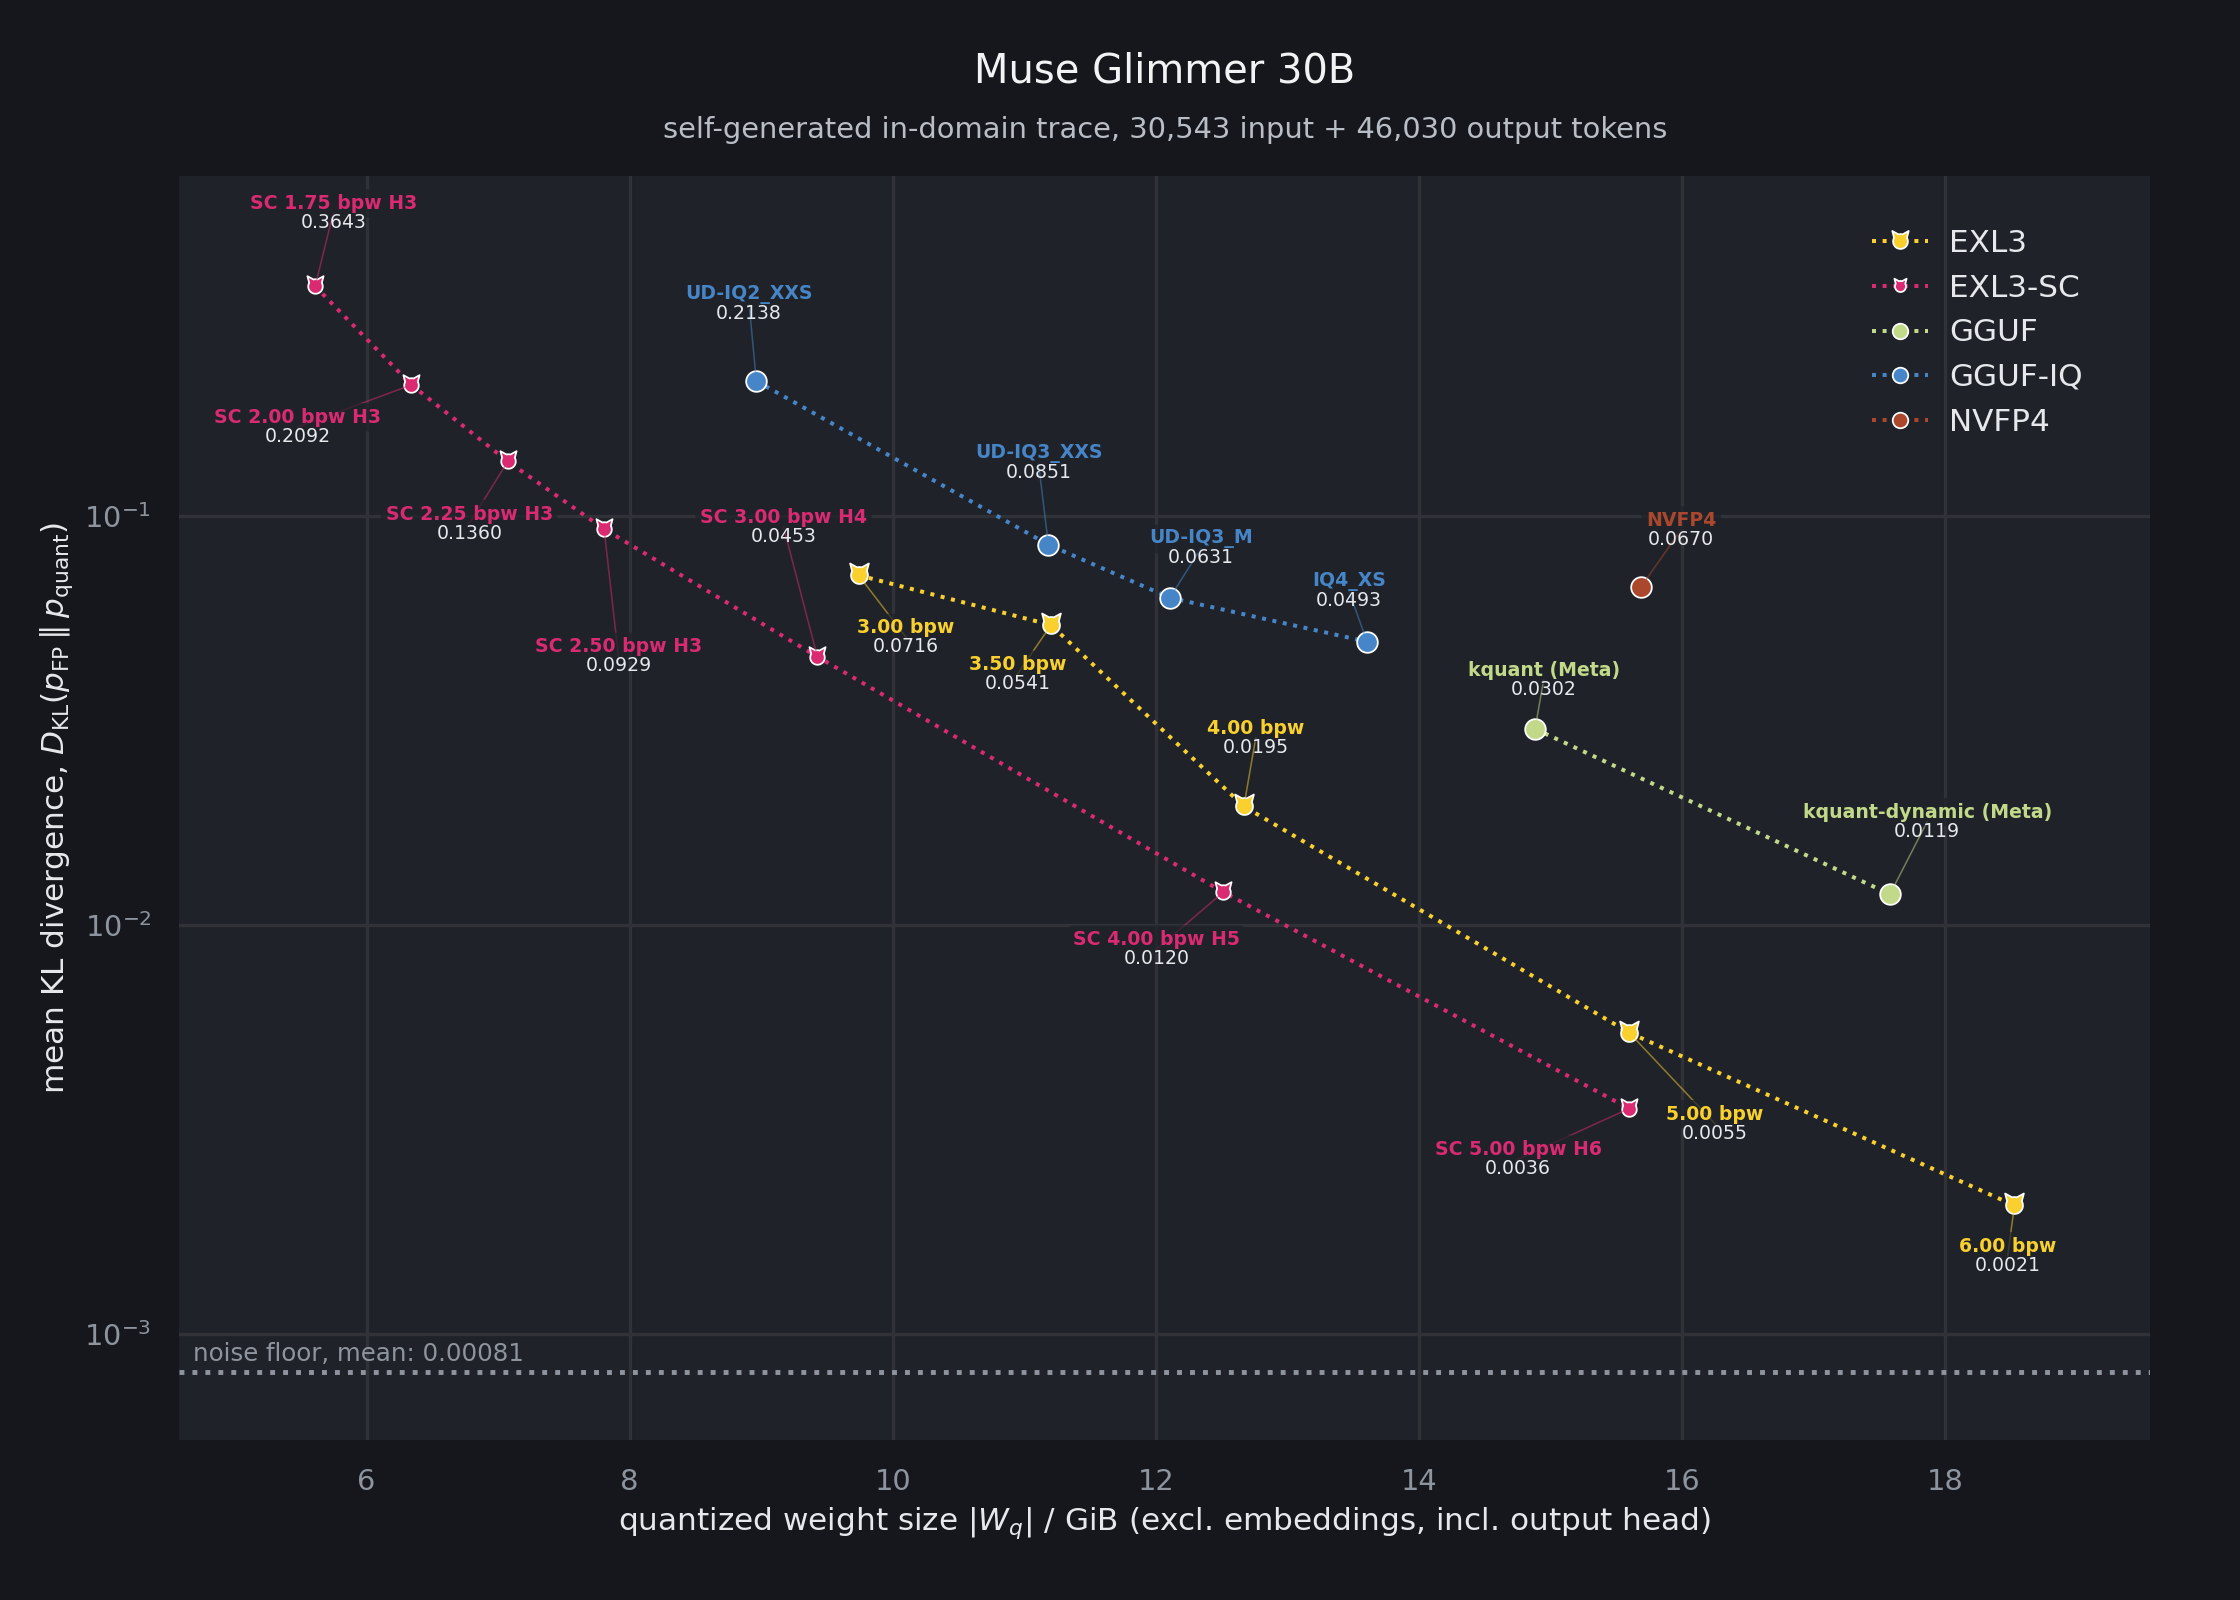
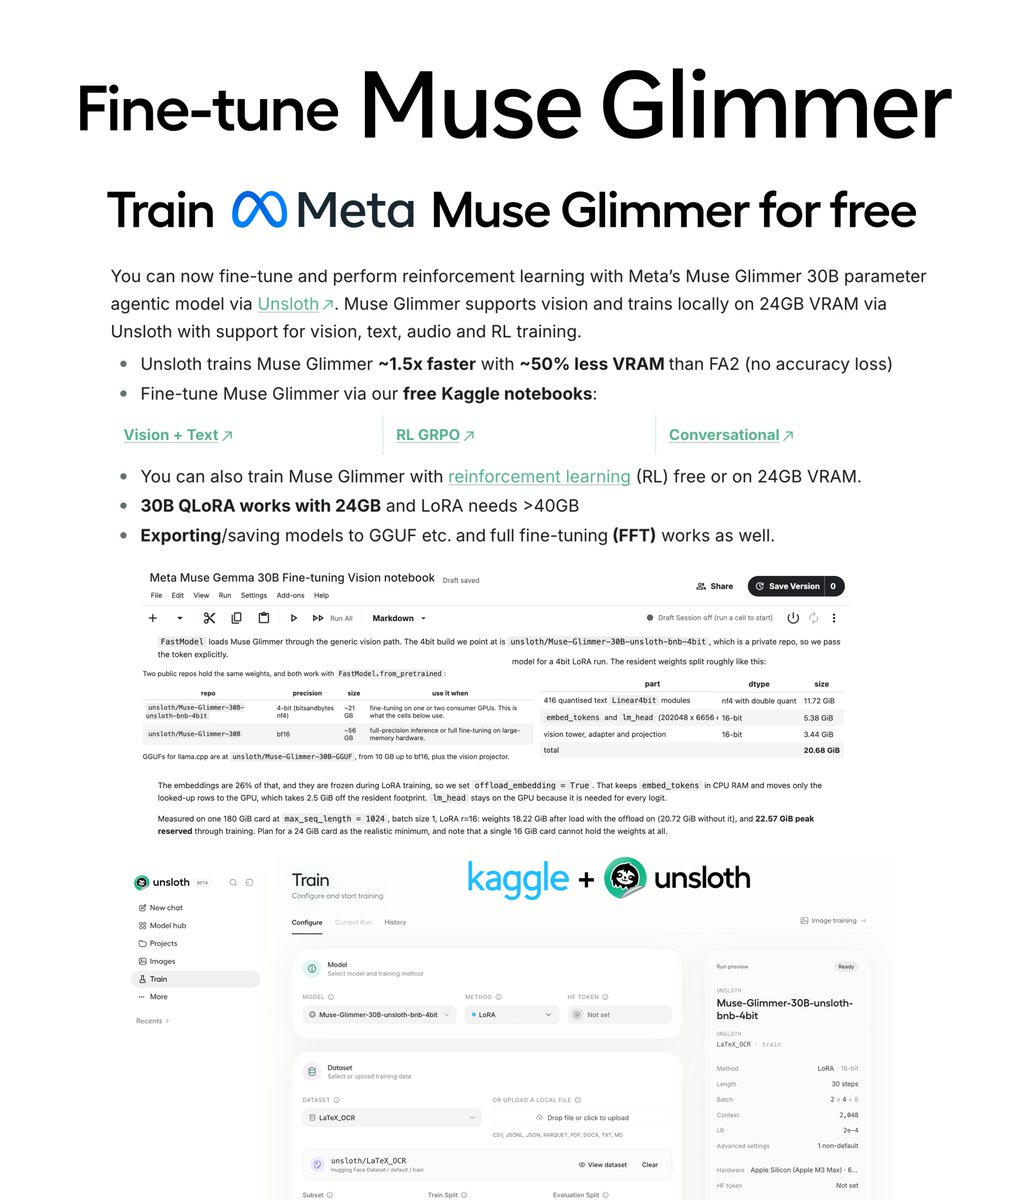
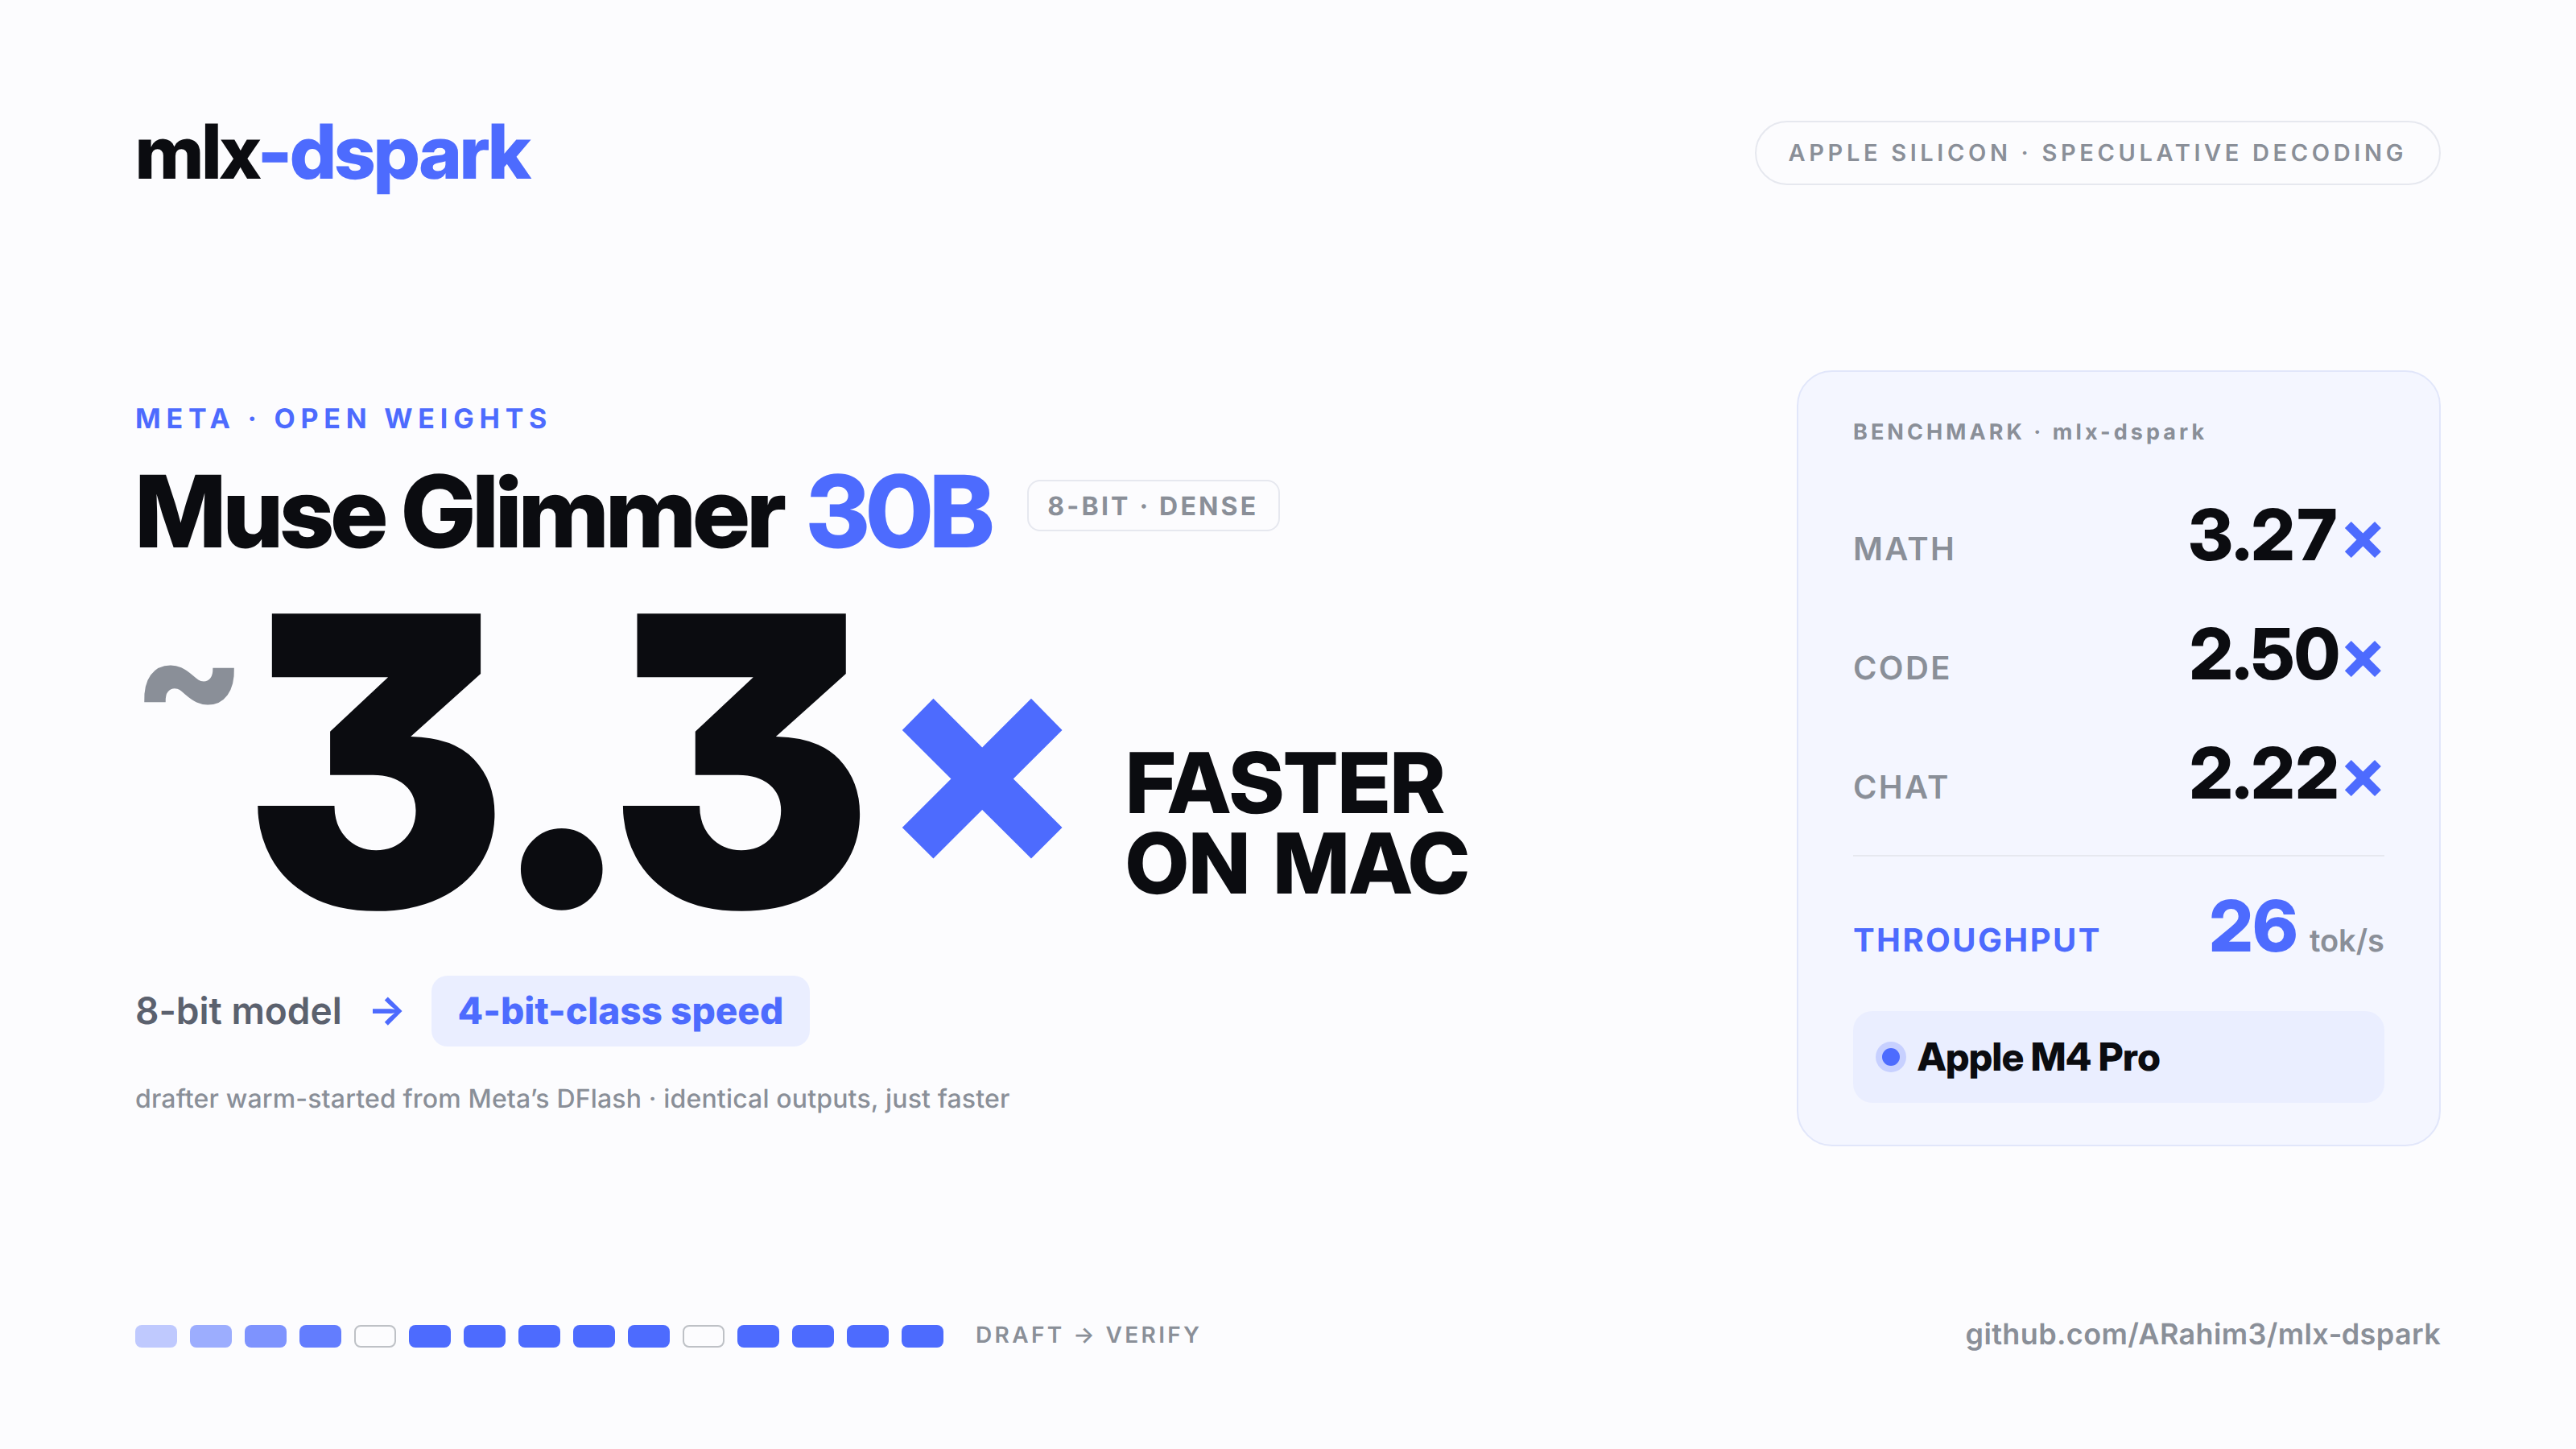
This is the largest shelf, with about 190 entries on Muse Glimmer 30B, Meta's open-weight model released under Apache 2.0. Much of it is quants: Meta's own GGUF, Unsloth's Dynamic 2.0 builds, bartowski's imatrix GGUF, mlx-community's 4-bit MLX, and FP8, INT4 and NVFP4 builds from Red Hat AI and NVIDIA. Meta's DFlash drafter and community DFlash 2 drafters speed up decoding.
The hardware reports are the practical part. Alok ran Glimmer with 130K context on Kaggle's free dual T4s. Cloud Codes ran Unsloth's 2-bit quant in about 14GB of laptop memory and logged 100+ tool calls. Reddit users report speeds on RTX 5090s, AMD V620s and an RX 7600 XT, and one got it running in the browser over WebGPU.
There are honest reviews too. Digital Spaceport found it weaker than Qwen 3.6 27B overall on a 4x 3090 rig, and one Reddit post documents a max_tokens setting that made it look dumb. Speed numbers are as reported by each author and depend heavily on quant and runtime.








 ChatForm
 Tgmlabs