GGUF builds of Muse Glimmer 30B all cut from the same BF16 source weights, including full-precision files.
Resource · Local & open models· ♥ 6
Catalog / Use case
196 reports of running Muse Glimmer 30B locally: GGUF and MLX quants, DFlash speculative decoding, GPU benchmarks, Mac setups and fine-tunes.
GGUF builds of Muse Glimmer 30B all cut from the same BF16 source weights, including full-precision files.
Resource · Local & open models· ♥ 6
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

merve
@mervenoyann
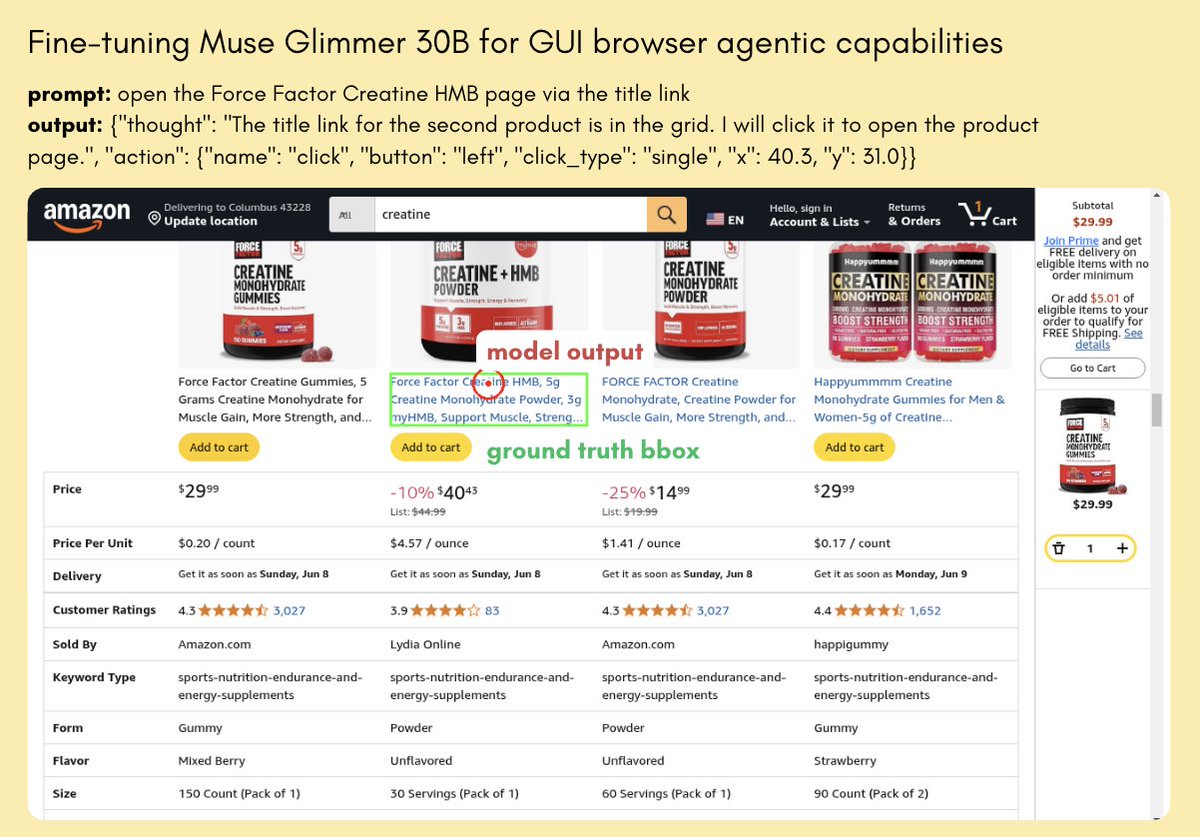
I shipped a fine-tuning tutorial for Muse Glimmer 30B on AI2's MolmoWeb dataset with TRL github.com/merveenoyan/sm… > but merve, this model is sota on ScreenSpot-Pro? yes, but it doesn't work well with ambiguous prompts of MolmoWeb that are close to how you interact with computer,
X post · Local & open models· ♥ 109
sequelbox's Tachibana-Agent fine-tune of Muse Glimmer 30B, part of a series also released for Gemma 4 12B and Qwen3.6 27B.
Resource · Local & open models· ♥ 4
An experimental Rust and Metal inference runtime for Muse models on Apple Silicon, currently supporting Muse Glimmer, using llama.cpp as the correctness and speed baseline.
GitHub · Local & open models
A reproducible single-GPU deployment of Muse Glimmer 30B in BF16 with DFlash speculative decoding on a 96GB RTX PRO 6000 Blackwell, served via vLLM with pinned overlays and smoke tests.
GitHub · Local & open models
Refusal-removed Muse Glimmer 30B; the card reports refusals falling from 128/150 (85.3%) to 3/150 (2.0%) on harmful prompts with 0/75 over-refusals.
Resource · Local & open models· ♥ 6
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Fahd Mirza installs Muse Glimmer in GGUF format and tests it with DFlash speculative decoding for faster local inference.

Video · Local & open models
GGUF conversions of Inco AI's DFlash 2 draft model for Muse Glimmer 30B, for speculative decoding in llama.cpp.
Resource · Local & open models· ♥ 16
A reproducible setup serving Muse Glimmer 30B on one AMD MI300X with a custom 11 GB vLLM 0.28.0 ROCm image, exposed as an authenticated OpenAI-compatible endpoint and driven from the pi CLI.
GitHub · Local & open models
A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.
GitHub · Local & open models· ★ 8
xCreate runs a Q9 MLX build of Muse Glimmer against Qwen 3.6 on a 512 GiB M3 Ultra using the Inferencer app.

Video · Local & open models· ♥ 129
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Abstract Extraordinary digs into the architecture behind Meta's pitch of an autonomous, multimodal agent that runs on-device with no cloud.
Resource · Local & open models
Resource · Local & open models· ♥ 8
Resource · Local & open models· ♥ 12

Mark Zuckerberg
@finkd
Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats
X post · Local & open models★ Pick· ♥ 30.4K
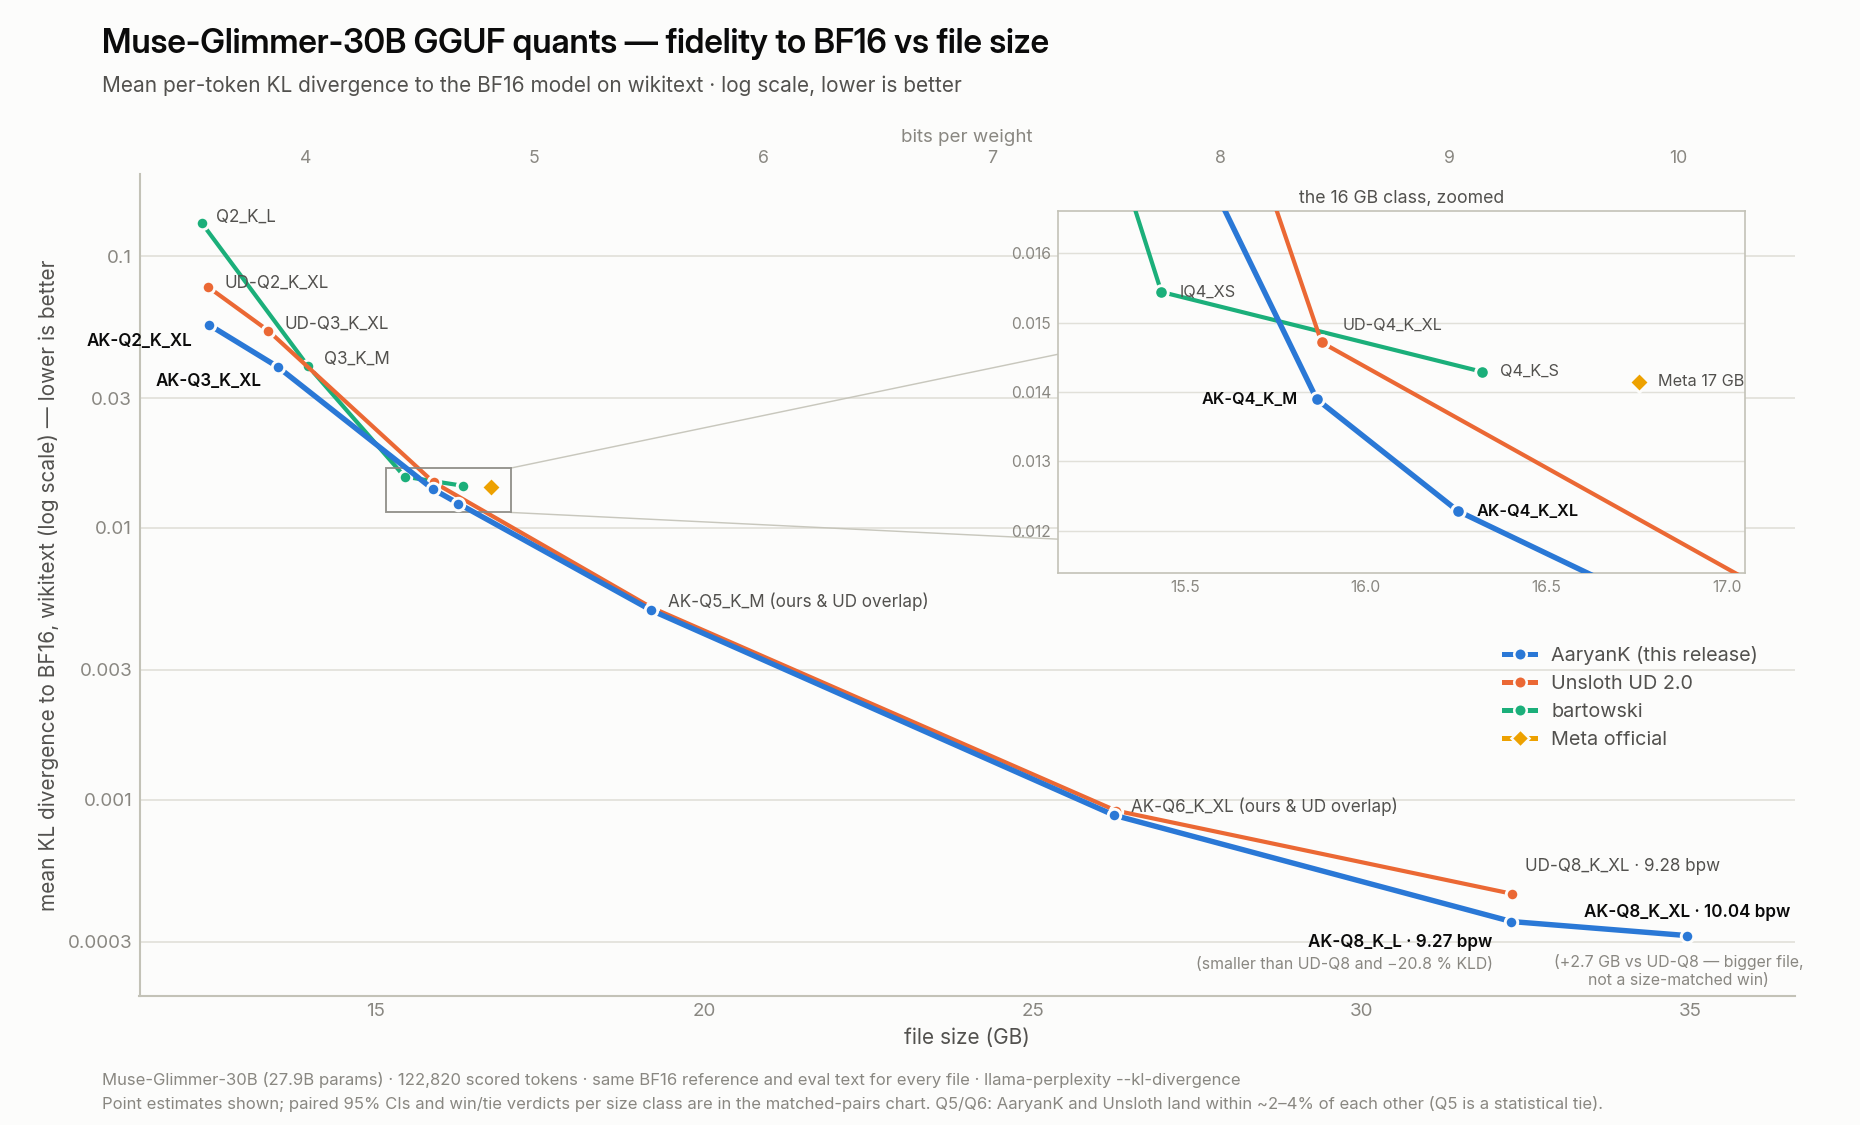
Hey Folks, I've been making quants for a while - recently I took a short break to get into hardcore research (submitted my first EMNLP paper during it!). Along the way, I built up a little arsenal of quant-optim techniques: everything from novel, paper-pending tricks to some genuinely sick tensor-mapping algos. I threw some of the secret sauce into the newly released Muse Glimmer 30B (META IS BACK!) and compared it to several OGs. I'm honestly shocked by how it never loses to any quant out there in every single VRAM class! One of the coolest ones is my Q8 quant, it is smaller than UD-Q8_K_XL and 21% closer to BF16. Full methodology is on the card - eval setup, CIs, held-out slices, the lot. Happy to answer questions in the comments. Model: https://huggingface.co/AaryanK/Muse-Glimmer-30B-GGUF I still had headroom left but ran out of compute credits :( Being a solo undergrad sophomore, I can't exactly spend H100 money that often, which is why the "hopefully" in the title :) I'm looking for internships in AI agent orchestration and model inference. If this work looks relevant to your team: linkedin.com/in/theaaryankapoor I plan on doing a write-up soon to describe some of the
Reddit post · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.
Site · Local & open models
An effort to make Muse Glimmer 30B actually use a 512k-token context (4x native) as a ~17GB GGUF in 32GB VRAM, trained on DGX Spark and evaluated with RULER-style retrieval tests.
GitHub · Local & open models· ★ 1
Tested SGLang and vLLM launch recipes for an NVFP4 export of a Hermes-agentic fine-tune of Muse-Glimmer-30B on NVIDIA DGX Spark (GB10).
GitHub · Local & open models

filipe
@filicroval
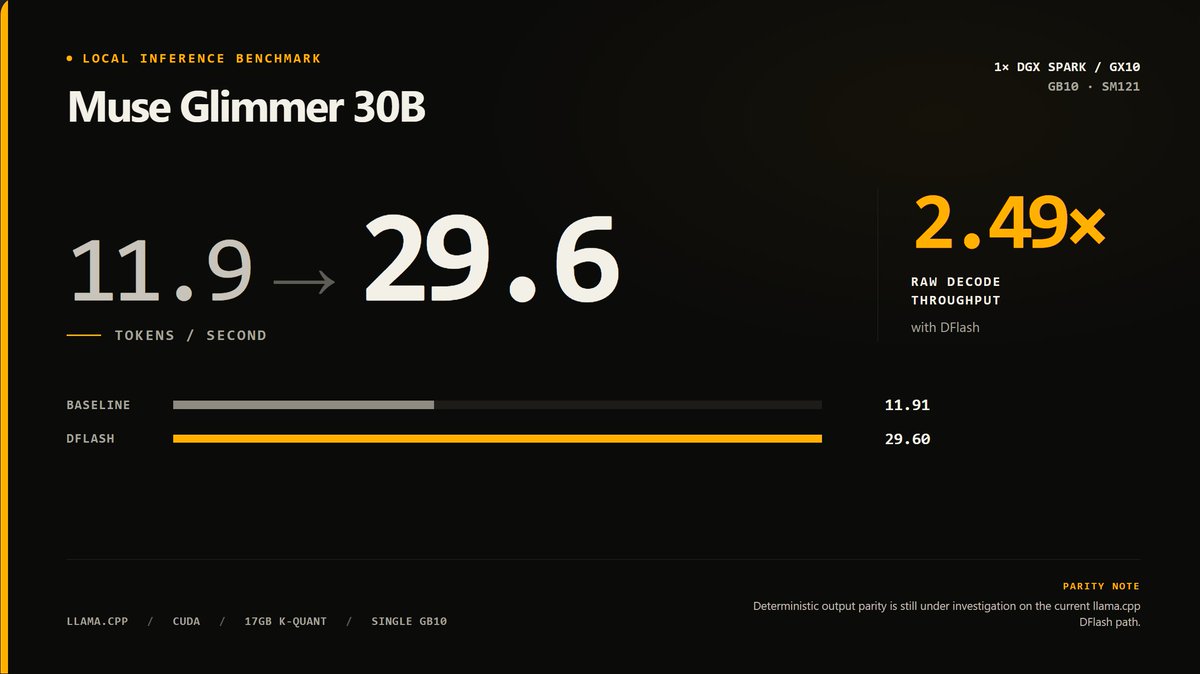
got Muse Glimmer 30B running on a single DGX Spark / GX10 at 29.6 tok/s with DFlash, up from 11.9 tok/s baseline, 2.49× raw decode throughput. packaged the whole thing into a reproducible GB10 recipe: - pinned weights + SHA-256s - llama.cpp compiled for GB10 / SM121 - baseline
X post · Local & open models· ♥ 5
AWQ INT4 quant of Muse Glimmer 30B calibrated on STEM and agentic data across ten languages, 24.02 GB.
Resource · Local & open models· ♥ 10
A project that fine-tunes a DSpark speculator for Muse Glimmer 30B on on-policy coding and agentic traces to raise acceptance length on agentic workloads, evaluated with Terminal-Bench.
GitHub · Local & open models
NVIDIA's technical blog reports Muse Glimmer serving over 20K tokens/sec on a single Blackwell Ultra GPU and covers RTX 5090, DGX Spark, DGX Station and Jetson deployments.
Resource · Local & open models
Hey Guys, I've got 4 x v100's in a Dell C4140 (NVlink) and I have been working on a fork of llama.cpp that is targeted at the v100's. Looking for testers to give it a go and provide feedback. WyvernTKC/llama.cpp-4xV100: Fork of llama.cpp Nvida Volta V100 (tensor parallelism 4 x v100 GPU) model arch type size (GB) pp layer pp tensor change tg layer tg tensor change glm4 9B Q8_0 glm4 dense 9.3 1187.9 2924.3 +146 % 67.6 123.0 +82 % qwen35 27B Q8_K_P qwen35 dense 29.3 640.4 1717.6 +168 % 22.2 52.4 +137 % gemma4 31B Q8_0 gemma4 dense 30.4 679.8 1621.2 ±322 noisy 20.6 46.7 +127 % muse-glimmer 30B F16 muse-glimmer dense 51.9 1048.4 2395.6 +128 % 15.1 40.4 +168 % llama 70B Q8_0 llama dense 69.8 302.5 950.5 +214 % 9.8 28.6 +192 % qwen35moe 35B-A3B Q8_0 qwen35moe MoE 256×8 34.4 1602.6 3143.7 +96 % 93.6 113.7 +21 % qwen3next 80B-A3B Q4_K_M qwen3next MoE 512×10 45.9 889.8 1647.0 +85 % 76.6 86.8 +13 % deepseek4 284B Q2_K deepseek4 MoE 256×6 90.9 188.8 616.1 +226 % 27.3 37.7 +38 % Thanks!
Reddit post · Local & open models
merve
@mervenoyann
Meta released Muse Glimmer 30B: multimodal model for your Claw/Pi setups 🔥 we tested and fine-tuned the model for you, and shipped day-0 support in transformers and llama.cpp, including DFlash for 2-4x speed-ups 🥵 read our blog huggingface.co/blog/muse-glim…
X post · Local & open models· ♥ 398
A reproducible RDNA reference that adapts MI-series ROCm recipes to run Muse-Glimmer-30B on Ryzen AI (Radeon 8060S) hardware, measuring 2.2–2.5x single-stream speedups from DFlash.
GitHub · Local & open models· ★ 3
A reproducible record of running the 17GB Muse Glimmer 30B GGUF with llama.cpp and Metal on a 24GB M4 Pro MacBook Pro, with notes on mistakes, fixes and how local inference works.
GitHub · Local & open models

vLLM
@vllm_project
@Meta is back in open source. Excited to announce Day-0 vLLM support for Muse Glimmer 30B, the first open-weights model from Meta Superintelligence Labs — which ships under Apache 2.0!!! 30B dense, 128K+ context, multimodal, built for local agents. Capable enough for
X post · Local & open models· ♥ 251
We've been curious how far local models have actually come for agentic coding tasks, so we ran an experiment. Setup: • Model: Muse Glimmer (30B), packaged as a single llamafile • Agent: Hermes coding agent (connected via llamafile's local server mode, zero API keys needed) • Target: Mozilla AI's Otari gateway The Issue: We pointed Hermes at a real, reported bug in Otari (#183) where the gateway returned a vague 502 error on image requests instead of passing through the actual provider error. What the Agent Did: Hermes read the issue, navigated the repo, isolated the bug, created a branch, ran existing tests, wrote a new regression test, and opened a draft PR (#727). All of it ran locally and offline, with zero code written by hand. It's still draft PR territory rather than a merged fix, but it's a solid signal that ~30B local models are getting genuinely capable for real dev workflows, not just toy demos. Video walkthrough of the run: https://youtu.be/5GAgbT-XgHU?si=vJqEDGm9hssCO5-M Happy to answer questions about the setup, model performance, or how Hermes handled tool calling!
Reddit post · Local & open models★ Pick
Lightweight LoRA that makes Muse Glimmer 30B output a target element's bounding box directly from a screenshot and instruction, for computer-use agents.
Resource · Local & open models· ♥ 3

LM Studio
@lmstudio
Muse Glimmer 30B is live in LM Studio! It's a new open source model from Meta. Apache 2.0 license, fit right on your laptop. It is the strongest model of its size class we've tested.
X post · Local & open models★ Pick· ♥ 1.4K
A Makefile that downloads the three Muse Glimmer 30B GGUFs and builds and serves llama.cpp on Apple Silicon, automating a scriptable.com walkthrough.
GitHub · Local & open models

Simon Willison
@simonw
Muse Glimmer, the new 30B model, is available on Hugging Face right now - here's the GGUF version: huggingface.co/meta-models/Mu…
X post · Local & open models· ♥ 210
An OpenAI-compatible /v1/chat/completions server that runs Muse Glimmer on Apple Silicon through mlx_vlm while LM Studio's bundled MLX runtime can't yet load the architecture.
GitHub · Local & open models
A fork of DeepSeek's DeepSpec that trains a fresh DSpark speculative drafter for Muse-Glimmer-30B in place of the shipped DFlash drafter, with the full data-to-eval pipeline working on GPU.
GitHub · Local & open models
NetworkCoder runs Muse Glimmer 30B on an RTX 3090, measures speed and VRAM, and gives two agent harnesses the same model, endpoint, project and prompt to compare results.

Video · Local & open models
Scripts that run Muse-Glimmer-30B with vision and tool calling on a 32GB M2 MacBook Pro via llama.cpp and Metal, without admin or sudo access, pulling Meta's official GGUFs.
GitHub · Local & open models· ★ 1
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
Resource · Local & open models★ Pick
Chaty is a private offline desktop app built on Rust and llama.cpp that runs Muse Glimmer and other open models locally with a coding agent, RAG knowledge base, deep research and voice.
GitHub · Local & open models
Muse Glimmer 30B fine-tuned on agentic coding traces and chat distilled from Claude Fable 5, merged bf16 and drop-in for the base.
Resource · Local & open models· ♥ 3
196 builds · page 3 of 5