№ 0427Reddit post
SoTA GGUF quants of Muse Glimmer 30B
Released custom Muse Glimmer 30B GGUF quants that he says never lose to other quants in any VRAM class; his Q8 is smaller than UD-Q8_K_XL and 21% closer to BF16.
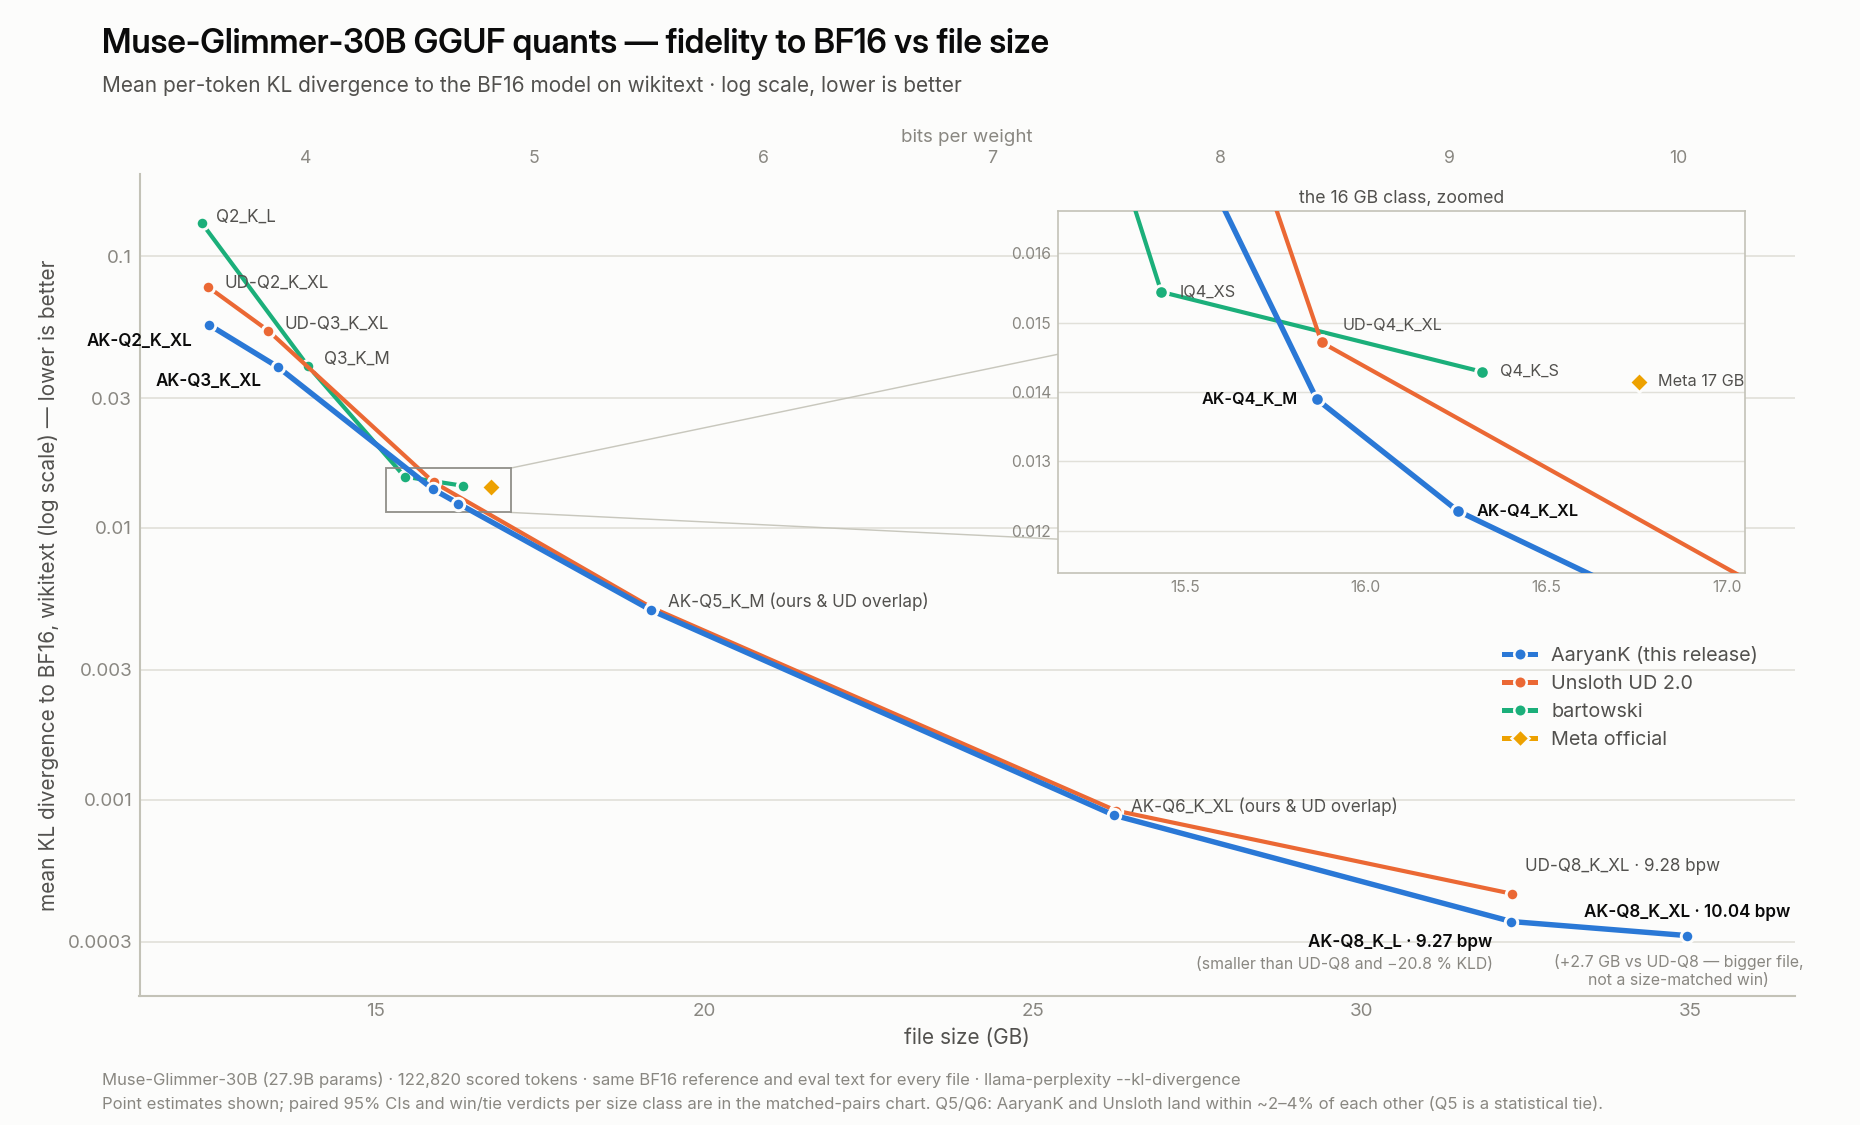
New Muse-Glimmer-30B SoTA Quants - hopefully a new lineup :)
Hey Folks, I've been making quants for a while - recently I took a short break to get into hardcore research (submitted my first EMNLP paper during it!). Along the way, I built up a little arsenal of quant-optim techniques: everything from novel, paper-pending tricks to some genuinely sick tensor-mapping algos. I threw some of the secret sauce into the newly released Muse Glimmer 30B (META IS BACK!) and compared it to several OGs. I'm honestly shocked by how it never loses to any quant out there in every single VRAM class! One of the coolest ones is my Q8 quant, it is smaller than UD-Q8_K_XL and 21% closer to BF16. Full methodology is on the card - eval setup, CIs, held-out slices, the lot. Happy to answer questions in the comments. Model: https://huggingface.co/AaryanK/Muse-Glimmer-30B-GGUF I still had headroom left but ran out of compute credits :( Being a solo undergrad sophomore, I can't exactly spend H100 money that often, which is why the "hopefully" in the title :) I'm looking for internships in AI agent orchestration and model inference. If this work looks relevant to your team: linkedin.com/in/theaaryankapoor I plan on doing a write-up soon to describe some of the



 ChatForm
 Tgmlabs