№ 0436GitHub
Muse Glimmer 30B on Ryzen AI and Radeon
A reproducible RDNA reference that adapts MI-series ROCm recipes to run Muse-Glimmer-30B on Ryzen AI (Radeon 8060S) hardware, measuring 2.2–2.5x single-stream speedups from DFlash.
Muse-Glimmer-30B-ROCm


The reproducible RDNA reference for Meta Muse-Glimmer-30B — from
MI-series recipes to Ryzen AI and Radeon.
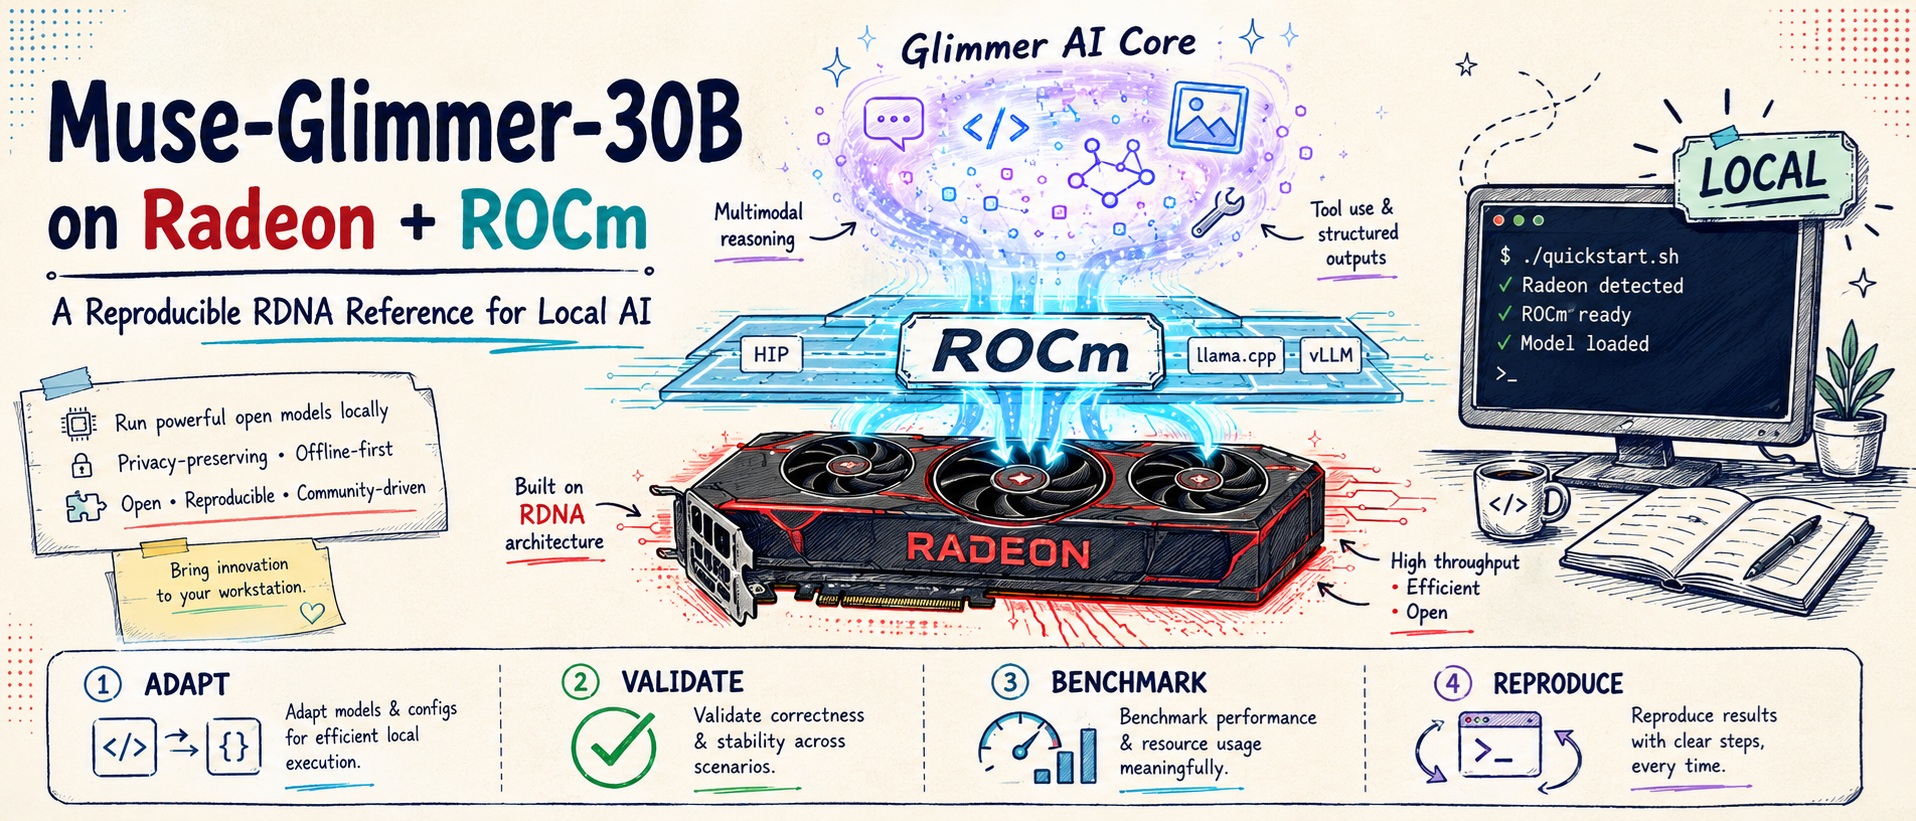
What you get:
- Run a ~30B multimodal reasoning/tool-use model locally on validated Ryzen
AI-class hardware (Radeon 8060S,gfx1151) with a one-command quickstart. - Measured, not guessed, speedups — DFlash speculative decoding delivers
2.2–2.5× single-stream; concurrency tradeoffs are benchmarked, including
the pitfalls (see known good and known bad). - A reviewed CDNA → RDNA adaptation map — reuse the
engineering delta instead of rediscovering it. - Evidence-first claims: every number links to raw cells with exact flags,
hashes and manifests. Failures are preserved as findings, not hidden. - A protocol to contribute Radeon evidence that is comparable rather than
anecdotal (hardware validation).
Method: Adapt → Validate → Benchmark → Explain → Reproduce.
Actually validated here: AMD Ryzen AI MAX+ PRO 395 / Radeon 8060S,gfx1151 (RDNA 3.5). Every additional platform remains evidence-gated by the matrix below.
Performance highlights
gfx1151 rows validated on ROCm 7.14.0 via the GGUF/llama.cpp matrix
(docs/results/matrix-714/). The W7900
(gfx1100) rows are community-validated and independently reproduced on
ROCm 7.14.0 (recommended default) and 7.2.1
(W7900 results).
Single-stream (Study 1, greedy, Meta-aligned DFlash anchor):
| Configuration | Baseline | DFlash | Speedup |
|---|---|---|---|
| gfx1151, K-Quant-17GB | 10.42 tok/s | 23.08 tok/s | 2.22× |
| gfx1151, dynamic K-Quant | 9.11 tok/s | 22.49 tok/s | 2.47× |
W7900 (gfx1100), K-Quant-17GB |
33.21 tok/s | 61.45 tok/s | 1.85× |
W7900 rows: ROCm 7.14.0, draft acceptance ~0.24 — raw cells:
[cells-rocm-7.14.0](docs/results/hardware-validation/w7900-gfx1100/cell




