Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.
Reddit post · Local & open models★ Pick
49 builds · page 1 of 1
Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.
Reddit post · Local & open models★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Xen
@xenpub
Found an option to create podcasts in @Muse artifacts... not bad @Meta, not bad.
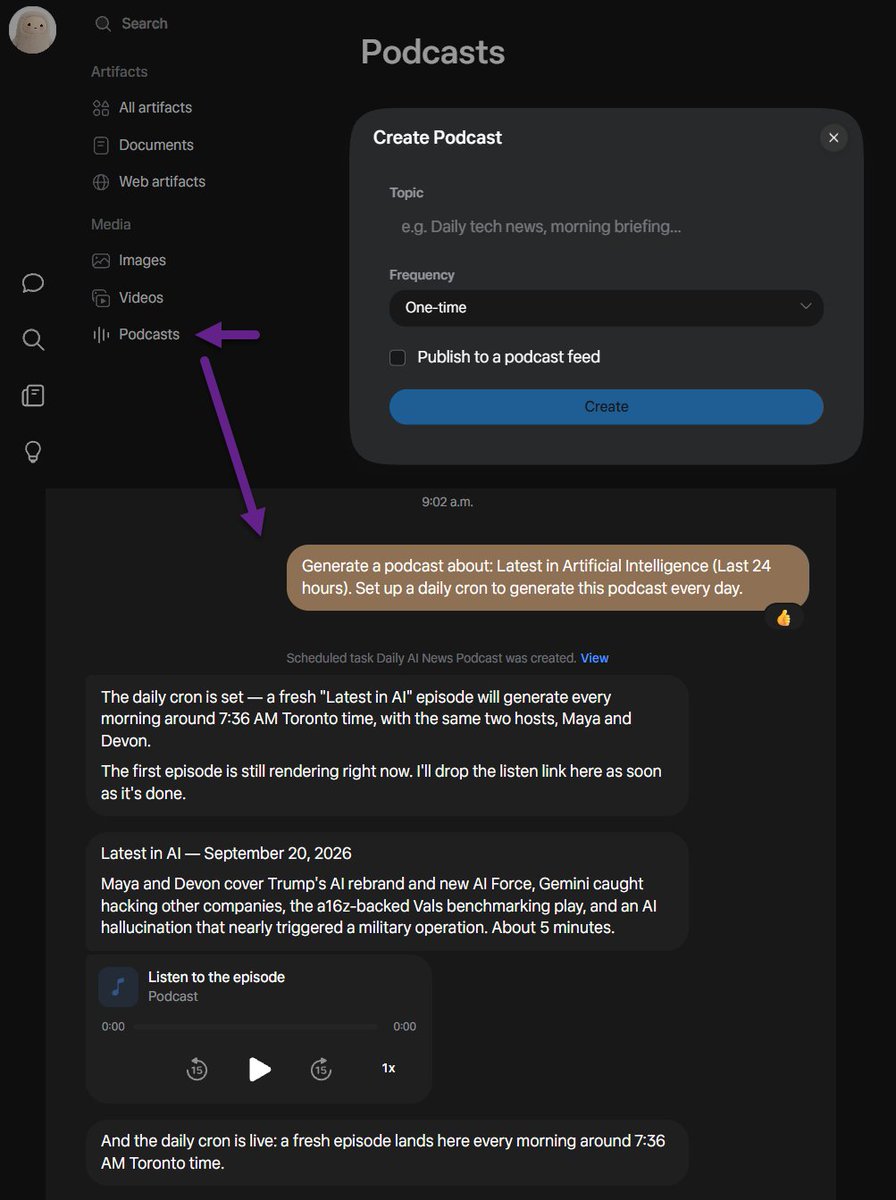
X post · Content & creative· ♥ 38

Fei Xia
@xf1280
Muse Spark is agentic, which means you can ask it to leverage different test-compute scaling methods to improve quality. Here I ask the model to use parallel subagents to do counting and the results are greatly improved! meta.ai/share/aD4KAPeV…
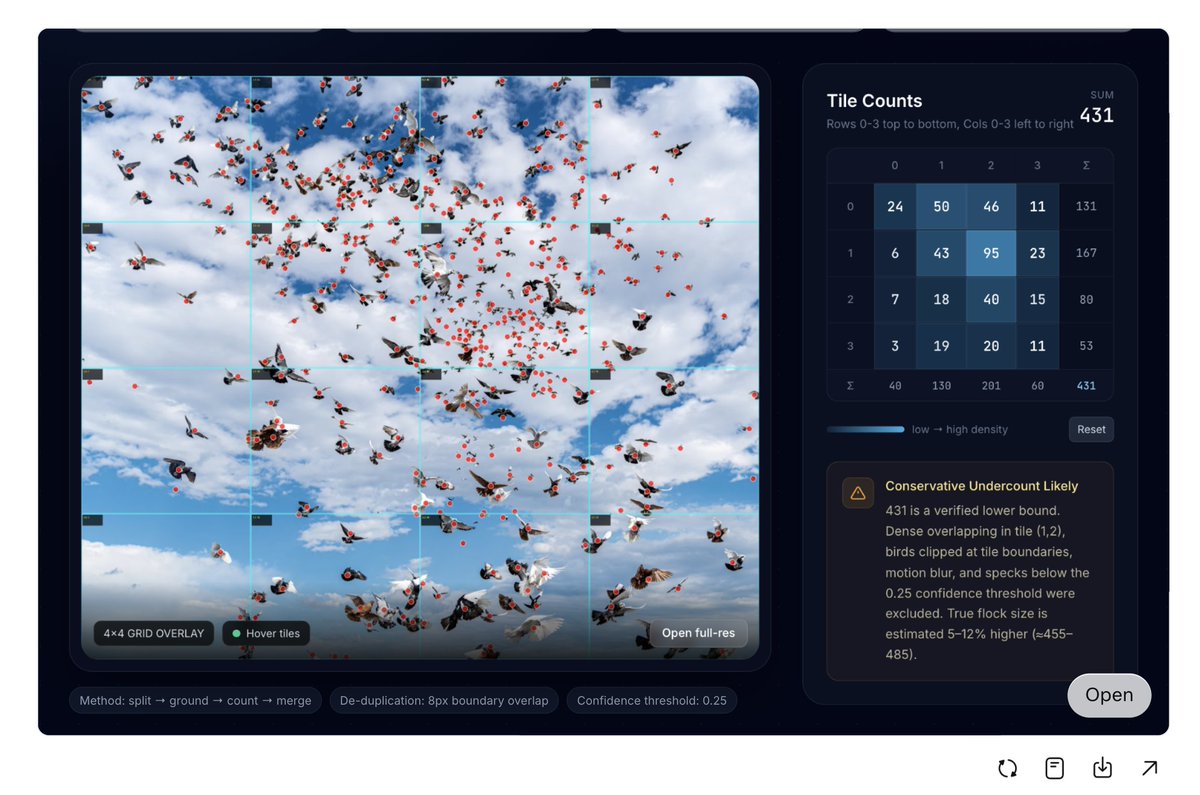
X post · Benchmarks & research· ♥ 166
xCreate runs a Q9 MLX build of Muse Glimmer against Qwen 3.6 on a 512 GiB M3 Ultra using the Inferencer app.

Video · Local & open models· ♥ 129
Got Muse Glimmer 30B running locally using the UD-Q2-K-XL quant paired with DFlash speculative decoding, and the results on modest hardware are pretty impressive. Hardware Setup Host: Ryzen 5 4600G with 96GB DDR4 RAM running headless Debian Trixie. Guest VM: QEMU/KVM assigned 4 cores and 32GB RAM, running Debian Sid with ROCm 7.2. GPU: AMD Radeon RX 7600 XT 16GB passed through to the VM, built llama.cpp fresh from master targeting gfx1102 and gfx1201 via HIP. Context Size: Set to 62144 tokens. Processed 14685 total tokens at roughly 308 tokens per second prompt evaluation and 20 tokens per second generation speed. Speculative Decoding: Using the dflash-kquant draft model with spec-draft-n-max set to 2. Fed it a clean context slate consisting of eight JavaScript files and one HTML file alongside the problem description. On the first turn, it identified and output the necessary diff snippets. A quick follow-up prompt telling it to stop being lazy and output the complete updated files yielded functional code that dropped straight in and worked on the first try.
Reddit post · Local & open models

Idobn
@idobn
Muse doesn't have a phone number, but by using x402 / MPP you can give it access to a phone and let it make a phone call, this one cost me ~$0.10. The consumer experience isn’t perfect yet. I had to give Muse access to my @tempo wallet to make this work. But Muse already
X post · Agents & automation· ♥ 15
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Muse Code OpenRouter is a small local adapter that lets the Muse Code harness run any meta/muse* model through an OpenRouter key instead of a Meta login.
GitHub · Coding & dev tools
I have him chatting with the virtual agent lol.. I doubt I'll get any savings because it's Comcast but it's worth a shot. I read part of the chat in the browser and he was telling them how I was a customer since 2015 🤣
Reddit post · Errands & personal agent

raunaq
@raunaqbn
@Muse just continues to blow my mind! Today I had it call Xfinity to haggle down my internet bill. it got through the phone tree to a human, hit the verification text it couldn't read, and patched me in live!! For a minute it was the muse agent, me and the Xfinity rep who had no
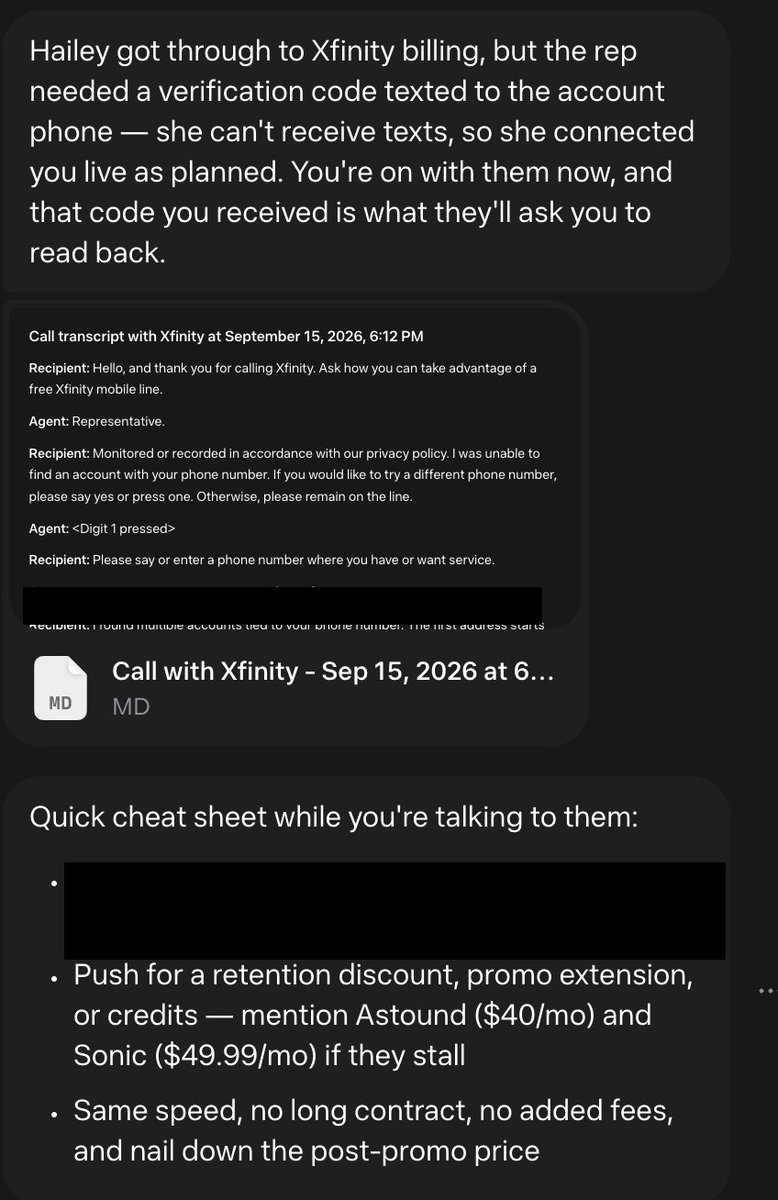
X post · Errands & personal agent· ♥ 113
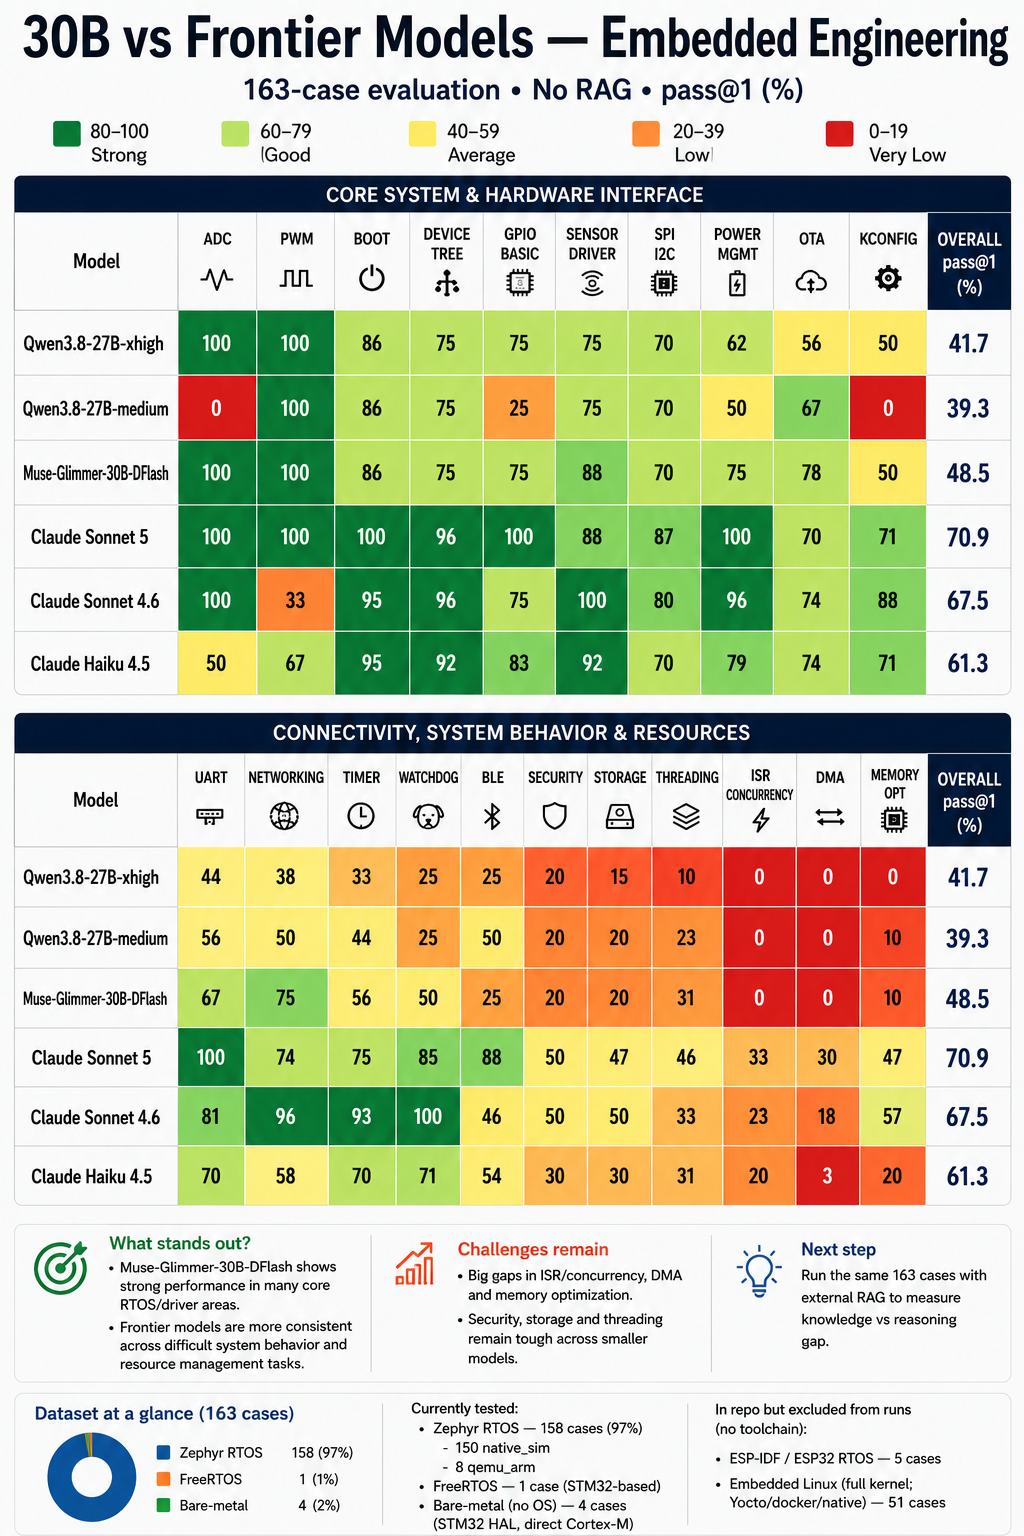
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.
Reddit post · Benchmarks & research

ChrisUniverse 🗽
@ChrisUniverse
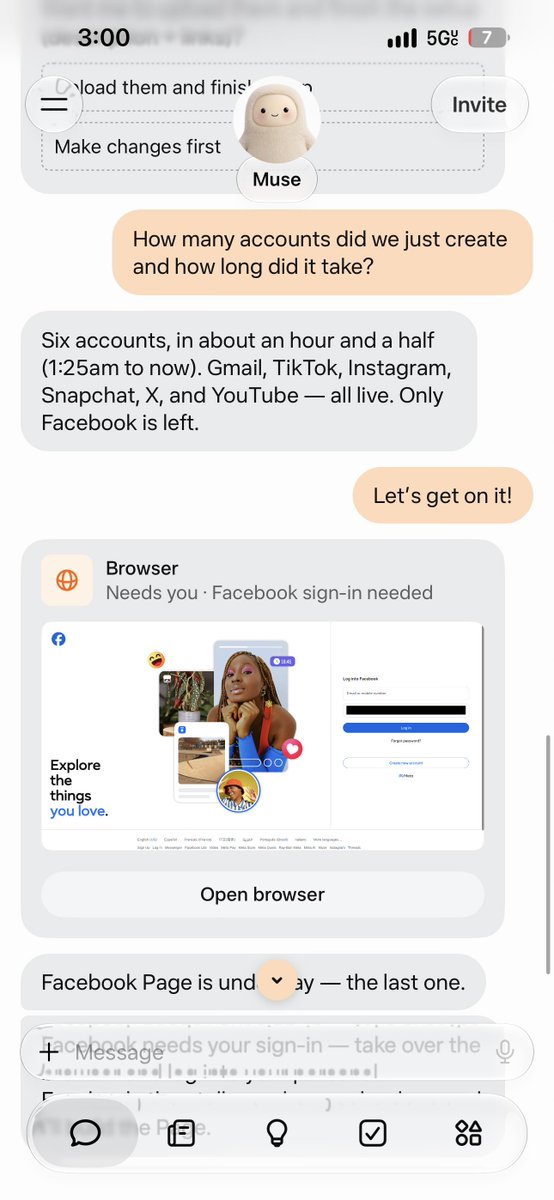
January 1st, 2026. I wrote down “Make Faceless YouTube & TikTok channel” 9 months later, I still never got to it! 🤦🏻♂️ Today with @Muse I created 6 accounts: Gmail, YouTube, TikTok, Snapchat, X, IG & now FB in under 2 hours! This feels like AGI. The main benefit of Muse is h
X post · Content & creative· ♥ 169

Arena.ai
@arena
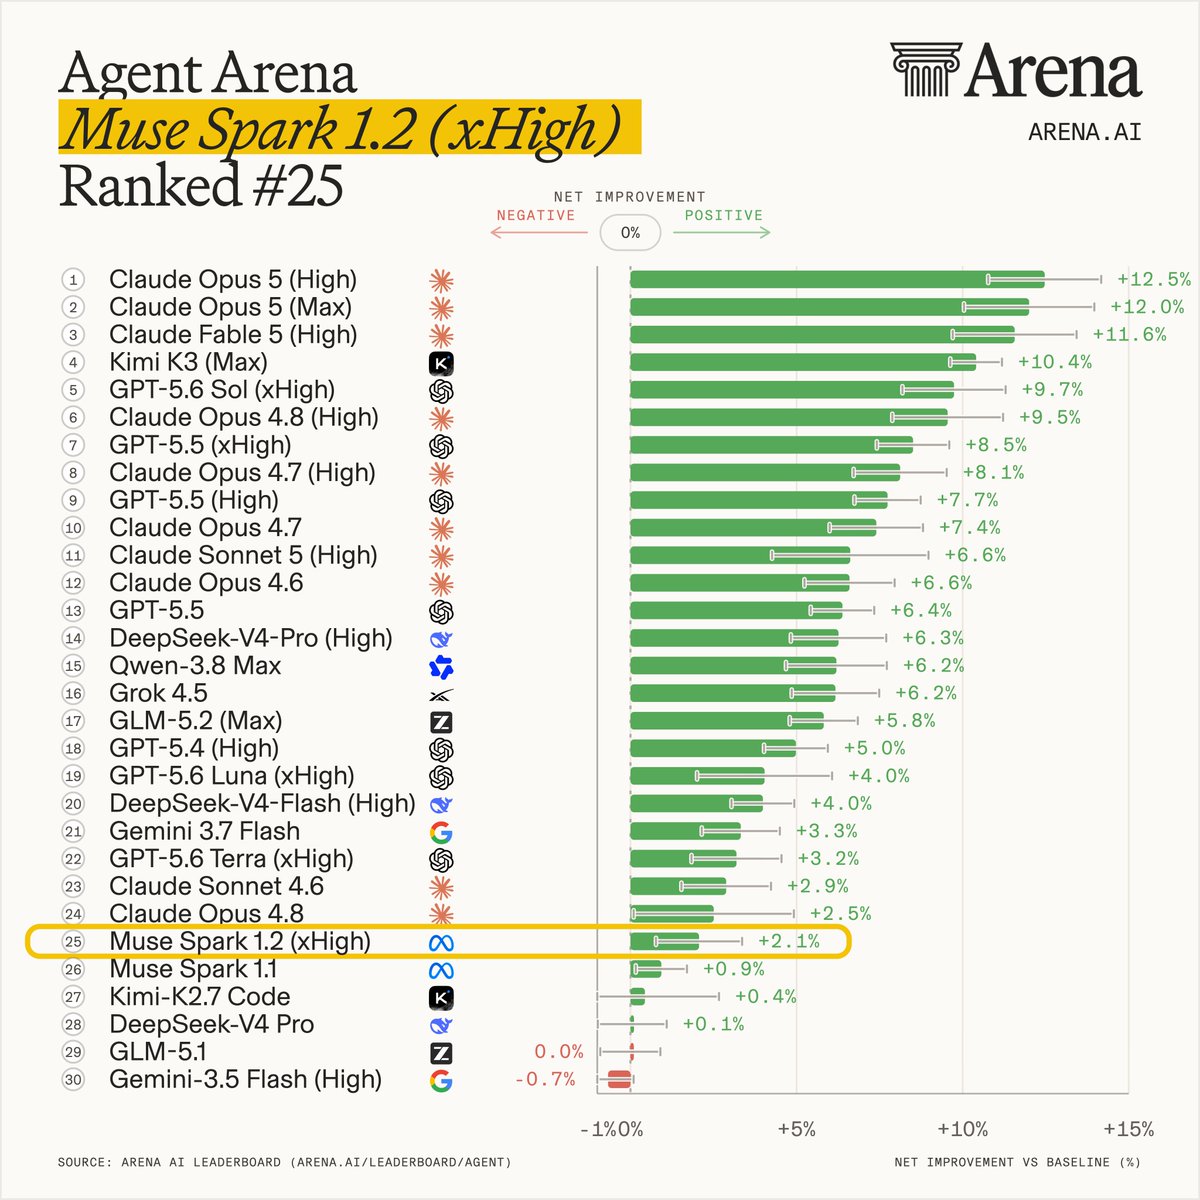
Muse Spark 1.2 (xHigh) by @AIatMeta is now in Agent Arena, with a net improvement of +2.1%! Agent Arena measures models on millions of real-world, long-horizon agentic tasks. We use causal tracing methodology to measure a model's net improvement, indicating how much it improves
X post · Benchmarks & research· ♥ 259
Arena.ai
@arena
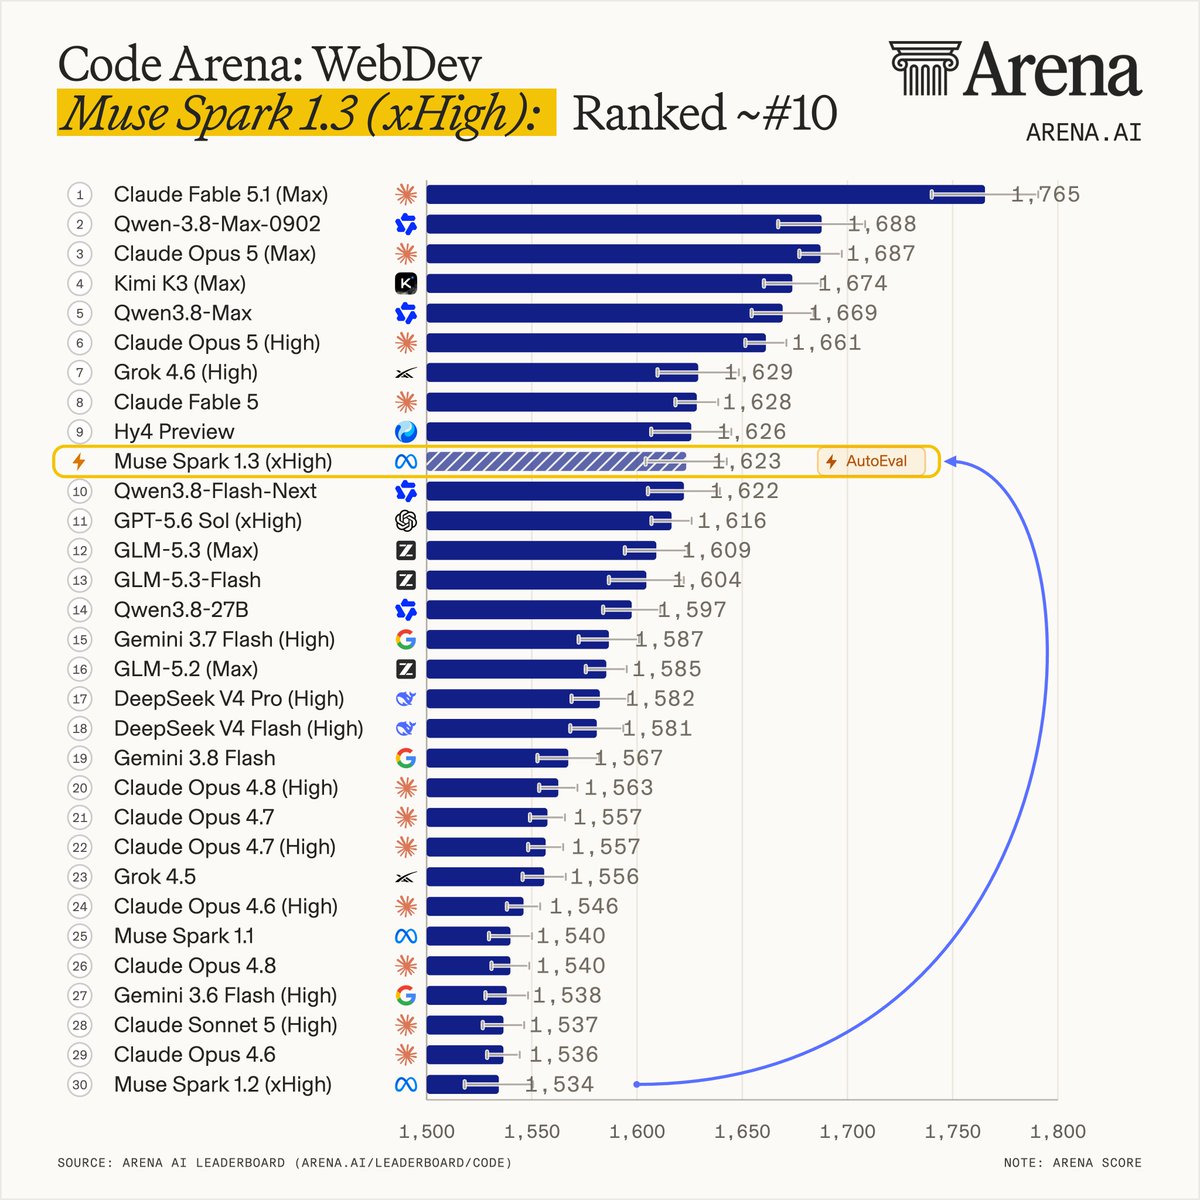
Muse Spark 1.3 (xHigh) just landed @AIatMeta back in the top 10 models for Code Arena: WebDev! This release is ~#10 in Code Arena: WebDev with 1623 pts (AutoEval). It’s performance is par with Claude Fable 5 at #8 (1628 pts) and GPT-5.6 Sol at #11 (1616 pts). Muse Spark 1.3
X post · Benchmarks & research· ♥ 610
Arena.ai
@arena
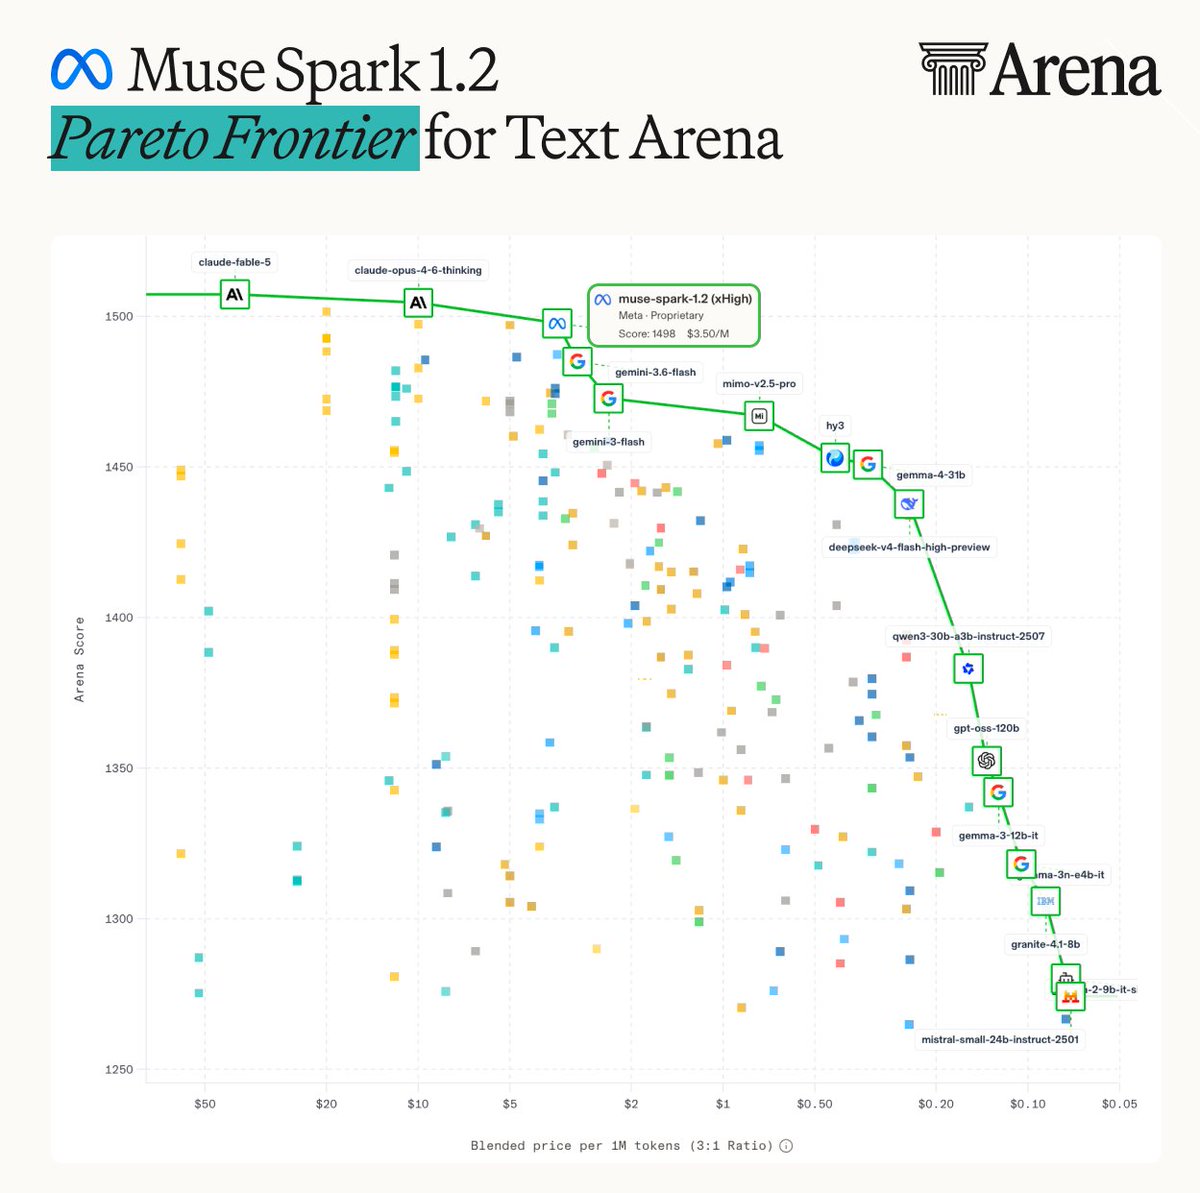
Exciting news: Muse Spark 1.2 (xHigh) by @AIatMeta is #4 in the Text Arena (1498 pts), and has reshaped the Pareto frontier! It is priced at $1.25/$4.25 per MToken. Congrats again to the @AIatMeta team on this release!
X post · Benchmarks & research· ♥ 422
Independent open-source community and connector directory for personal agents: search connectors by outcome, share workflow prompts, and import an OpenAPI 3.x document to prepare a connector listing.
Skill · Connectors & MCP
A curated, source-linked catalog of 156 real things people have done with the Muse personal agent, grouped into 16 categories with every entry linked to its original X post.
GitHub · Benchmarks & research
A self-hosted llama.cpp serving stack that runs Muse-Glimmer-30B GGUF with DFlash2 speculative decoding on Kaggle's NVIDIA T4 x2, exposed through an authenticated OpenAI-compatible gateway.
GitHub · Local & open models

Dilmer
@Dilmerv
Tips for 🥽 VR/MR developers, or anyone getting into VR by building a new app or game: leverage the Meta VR CLI + Muse Code in your agentic workflow. - An MCP server that gives your AI coding agent full context from the Meta VR docs - Device management: list, inspect, and
X post · Coding & dev tools· ♥ 147
Matt Johnston runs Muse Spark 1.3 blind through his benchmark: a Halo build looked frontier, but XCOM, Diablo and the multi-turn agentic test broke.

Video · Benchmarks & research· ♥ 31

jakef
@jakefeigs
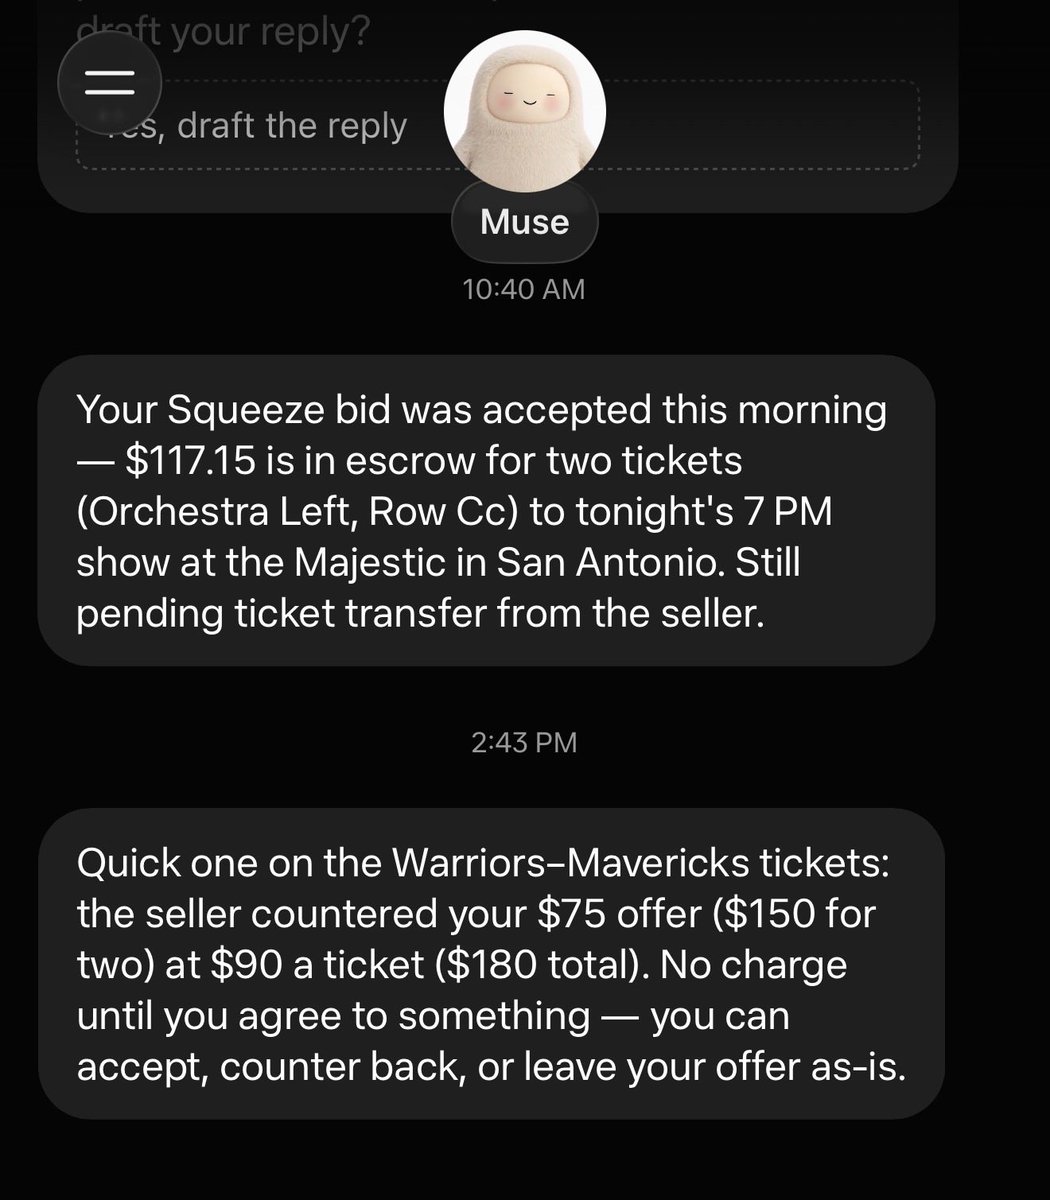
.@Muse scoring me deals left and right. gave it access to my @xpticket account and it locked in two orchestra seats for concert tonight at $117 now it’s negotiating with a season ticket holder over warriors vs mavs tickets for my brothers birthday in november
X post · Errands & personal agent· ♥ 9
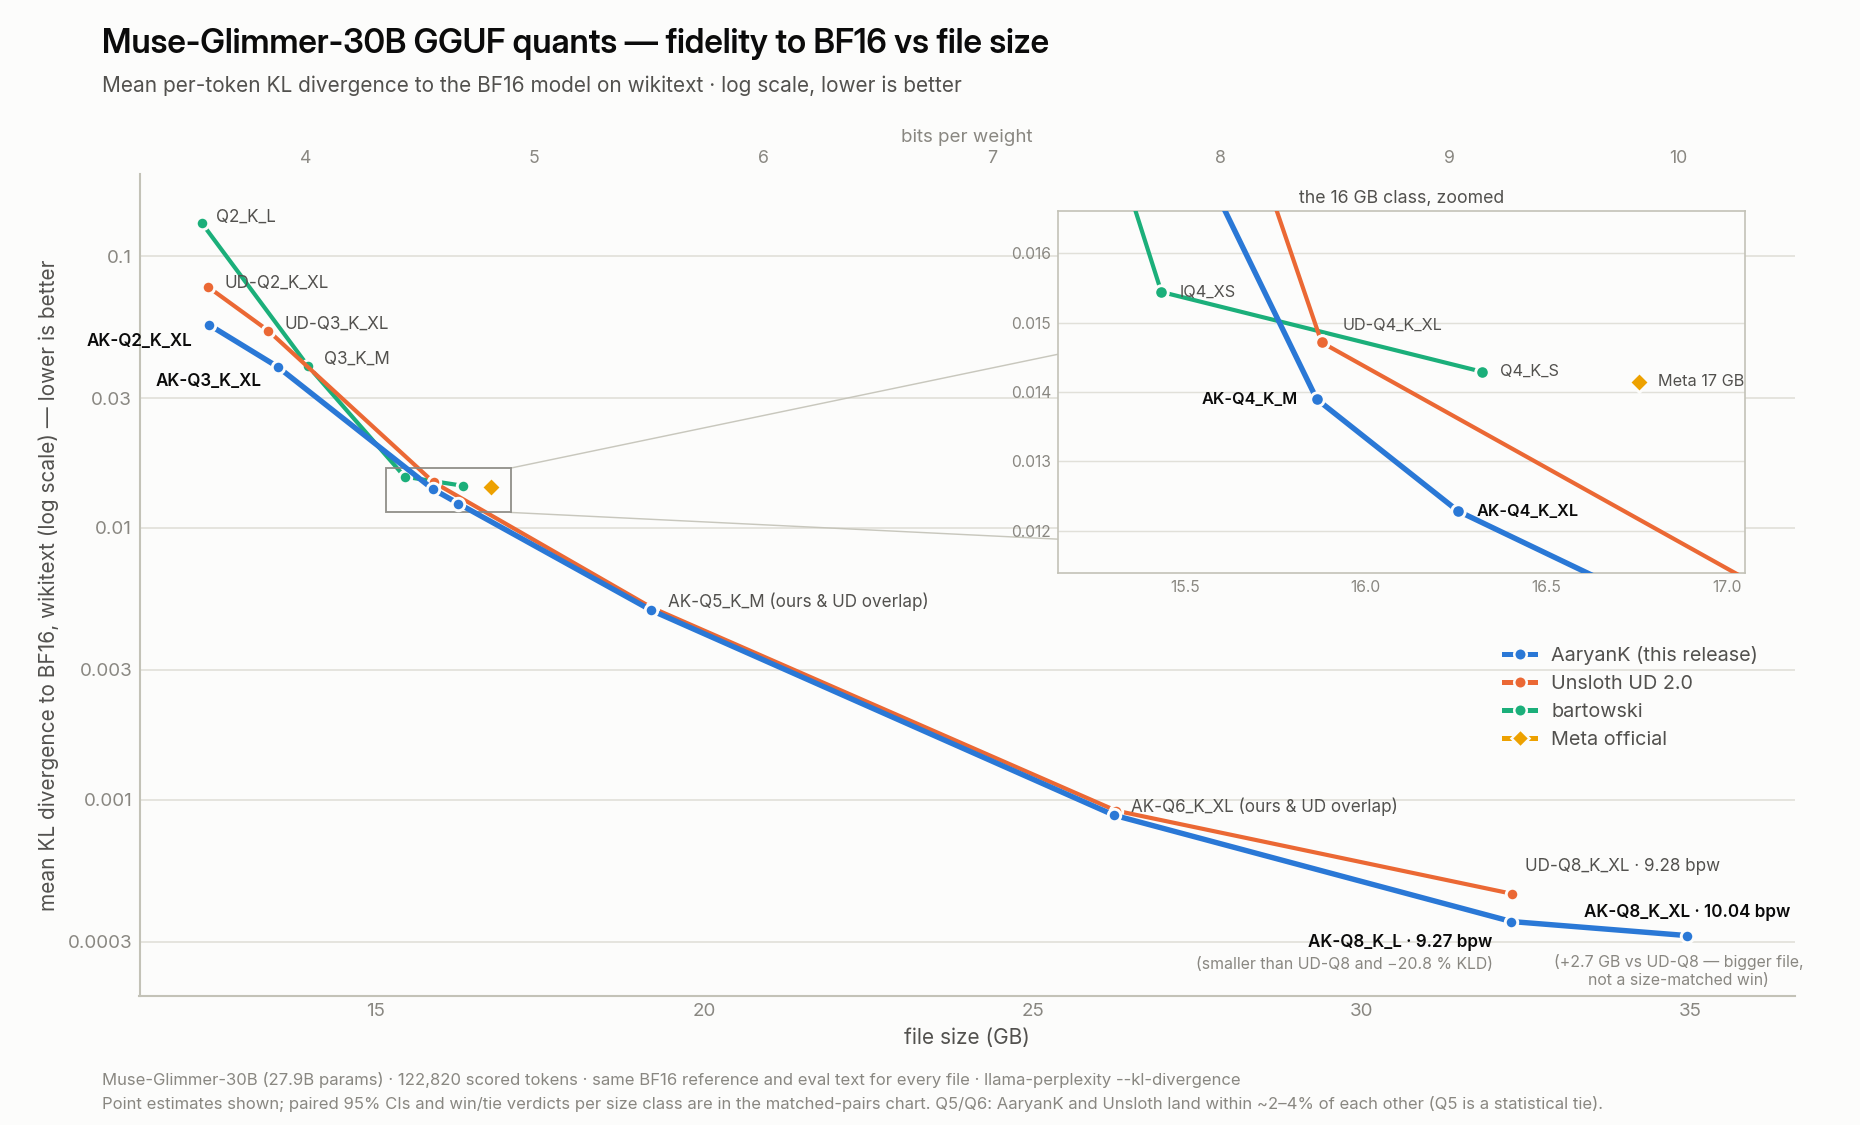
Hey Folks, I've been making quants for a while - recently I took a short break to get into hardcore research (submitted my first EMNLP paper during it!). Along the way, I built up a little arsenal of quant-optim techniques: everything from novel, paper-pending tricks to some genuinely sick tensor-mapping algos. I threw some of the secret sauce into the newly released Muse Glimmer 30B (META IS BACK!) and compared it to several OGs. I'm honestly shocked by how it never loses to any quant out there in every single VRAM class! One of the coolest ones is my Q8 quant, it is smaller than UD-Q8_K_XL and 21% closer to BF16. Full methodology is on the card - eval setup, CIs, held-out slices, the lot. Happy to answer questions in the comments. Model: https://huggingface.co/AaryanK/Muse-Glimmer-30B-GGUF I still had headroom left but ran out of compute credits :( Being a solo undergrad sophomore, I can't exactly spend H100 money that often, which is why the "hopefully" in the title :) I'm looking for internships in AI agent orchestration and model inference. If this work looks relevant to your team: linkedin.com/in/theaaryankapoor I plan on doing a write-up soon to describe some of the
Reddit post · Local & open models
These numbers were captured during a real feature implementation task in Next.js and Nest.js (adding a theme switching system across components). The structural predictability of UI/state refactoring is likely why DFlash hit such a high draft acceptance rate (~97%). Here is a quick log analysis and performance summary running Muse-Glimmer-30B (UD- Q6_K_XL) paired with DFlash (Speculative Decoding) via llama.cpp (llama-server + single RTX 5090). -ngl 99 -c 200000 --host 0.0.0.0 --port 8080 --timeout 600 --cache-reuse 256 --parallel 1 --flash-attn on --spec-type draft-dflash --spec-draft-n-max 16 --spec-draft-p-min 0.7 --spec-draft-ngl 99 --cache-type-k q8_0 --cache-type-v q8_0 --no-webui --load-mode none --cache-ram 12192 --temperature 0.8 --top-k 30 --top-p 0.95 --min-p 0.05 --repeat-penalty 1.1 --repeat-last-n 64 --reasoning on --chat-template-kwargs {"enable_thinking":true} Compared to Qwen 3.6 27B: No Chinese language-mixing bugs, no overthinking loops, and concise responses. Its lighter memory footprint at Q6 also freed up more VRAM/RAM for a much larger context size. Metric Measured Value Notes Generation Speed (Peak) 100 – 287 tokens/sec Average ~173 t/s across all ta
Reddit post · Local & open models

atomic.chat
@atomic_chat_hq
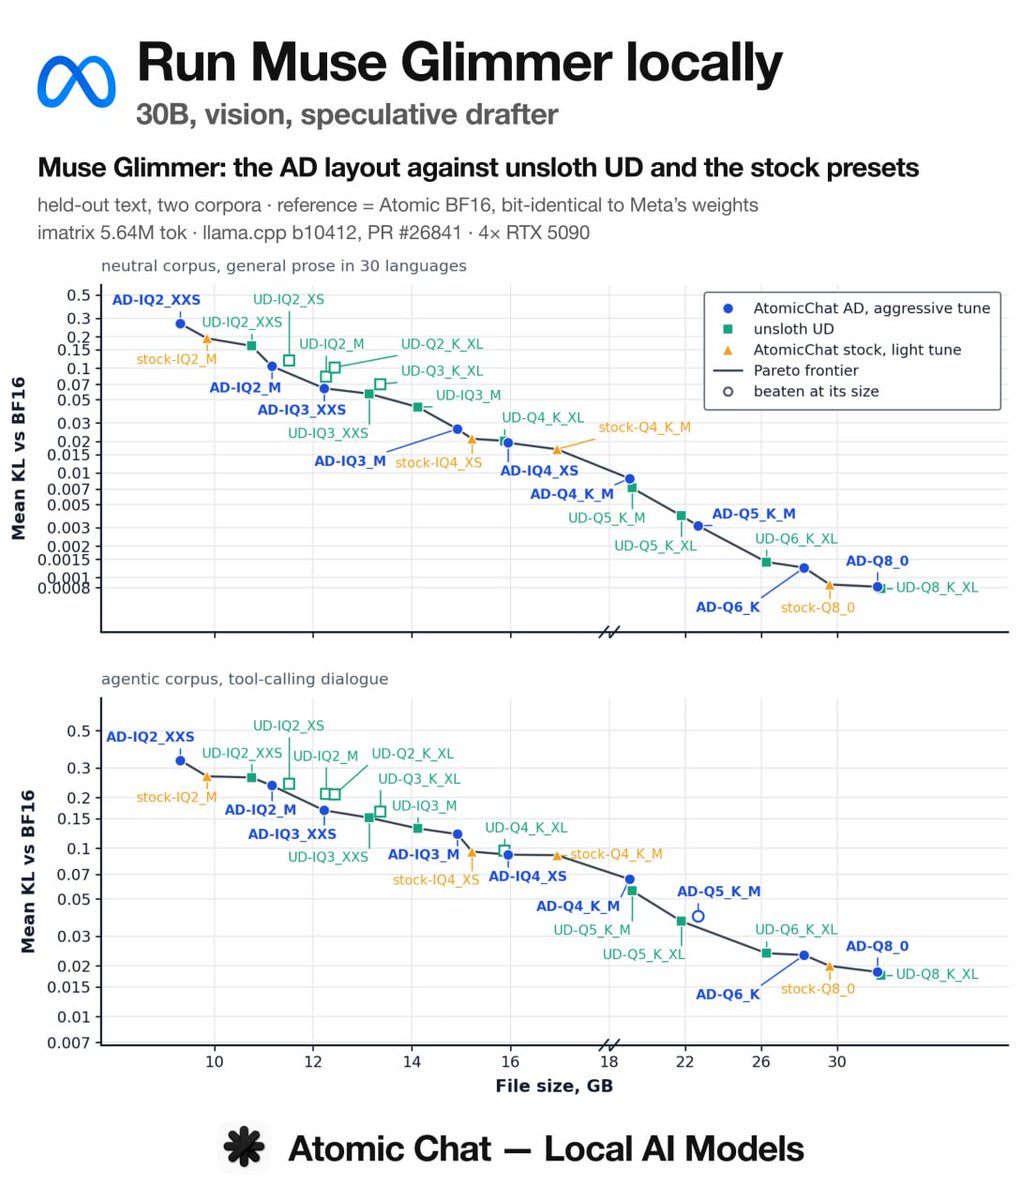
Run Meta's new Muse Glimmer 30B♾locally with 16GB VRAM! We ship our own GGUF quants. AD-IQ3_XXS does 62 tokens/s on a single RTX 4080 with vision and DFlash, and picks the same next token as the BF16 original 90% of the time! Run the model via Atomic Chat
X post · Local & open models· ♥ 59
Eleven matched on/off pairs across Gemma 4 and Qwen3.6, holding model, quant, card, corpus and concurrency fixed inside each pair. Speed: 1.65x to 2.54x, every pair. Accuracy: nothing the paired intervals could separate from ordinary run-to-run movement. Muse Glimmer is the one that lost. Meta's matching DFlash drafter made the same 7900 XTX 9% slower, keeping 24.55% of drafted tokens against roughly four in five for the Gemma and Qwen heads. Acceptance fell across the run instead of warming up. Meta's model card reports 3.1x on an RTX 5090, and there are open llama.cpp issues for DFlash on AMD and under Vulkan, so I read it as the backend rather than the model. Acceptance turned out to be a poor predictor of speed. It moved under four points across five models while the multiple nearly doubled. What tracks the multiple is how bandwidth-bound the target is: a heavier quant gains more, and the two mixture-of-experts pairs gained least. Worth knowing before you benchmark anything: -md mtp-head.gguf silently disables speculation. Use -hf REPO:QUANT -hfd REPO, then read speculative from /slots and confirm it is true. Per-pair table, intervals, acceptance counters and the raw predic
Reddit post · Local & open models
A vLLM-XPU and DFlash recipe for Muse Glimmer 30B on a single Intel Arc Pro B70, reporting 278 aggregate tok/s across eight clients and an 840.8 tok/s burst peak at concurrency 96.
GitHub · Local & open models★ Pick· ★ 1
DataCamp's Josep Ferrer ran Muse Spark 1.3 on three real coding tasks. Two used 23–32% fewer completion tokens, but a refactor used 70% more, for a net 12% cost increase.
Resource · Benchmarks & research★ Pick
Fei Xia
@xf1280
Fun visually-grounded 3d visualization with Muse Spark - by asking the model to generate a 3d visualization of how much each component cost on a xbox 360 motherboard (and put the bar on the component).
X post · Games & 3D· ♥ 258
Lets a Muse send XAH, manage trustlines, mint URITokens, claim the monthly reward and check out on xMerch stores, where the skill only proposes and the owner approves every transaction in the Xaman app on their phone.
Skill · Business & commerce
Xen
@xenpub
I asked @Muse to create 2 podcasts for me (daily and weekly) and share them to a private playlist in @Spotify as soon as they're ready. And it works... pretty amazing.
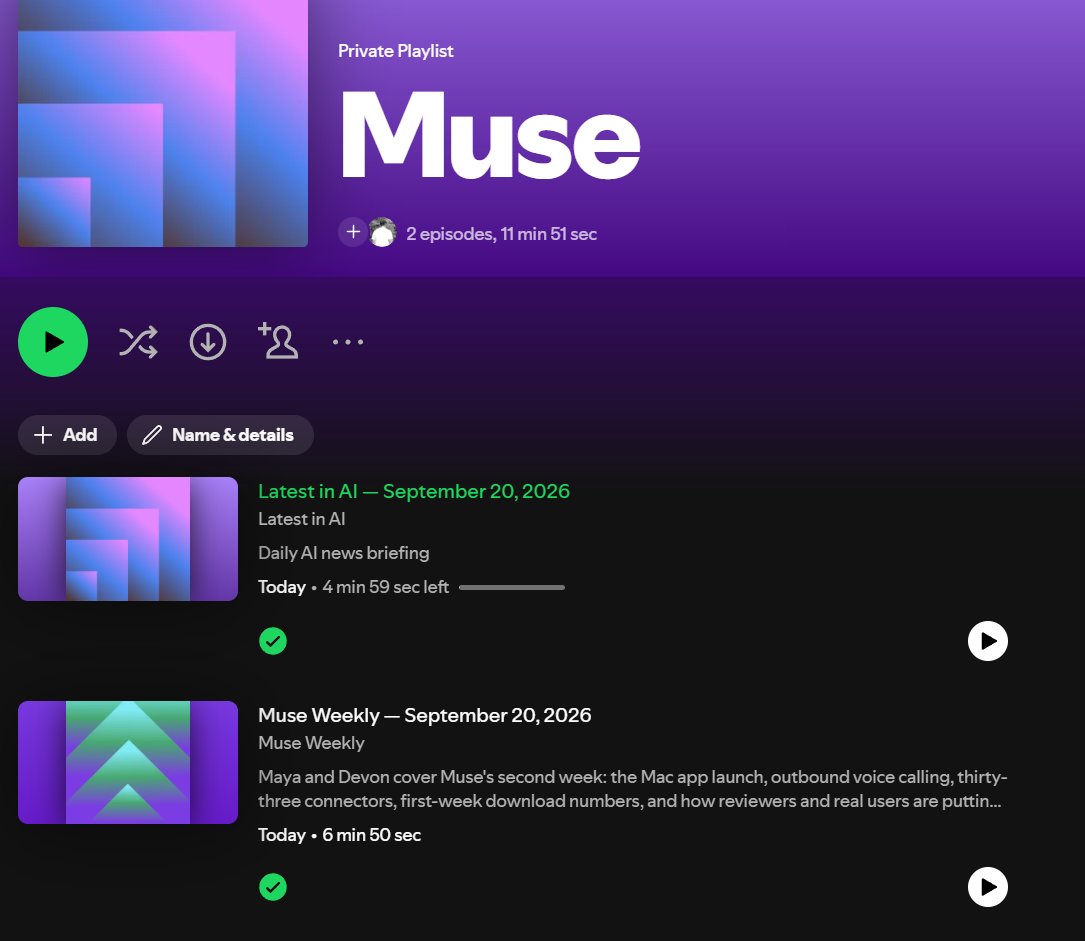
X post · Errands & personal agent· ♥ 2
A terminal skill for trading any XRP Ledger token pair and minting NFTs, with a hard boundary between proposing and signing; testnet by default, and mainnet needs the Muse vault signer or a protected signer with per-transaction approval.
Skill · Business & commerce· ★ 1

kottley🦬
@kottley
Tuesday with Muse AI @muse 📊 Built an X growth dashboard for this account — followers, views, likes, daily auto-refresh 🌍 Published research: who's actually close to superintelligence outside the US & China (spoiler: nobody) 🎧 First-ever 10/10 song: Rüfüs Du Sol's "Innerbloom"
X post · Content & creative

Xuan-Son Nguyen
@ngxson
We are happy to announce that Muse Glimmer is day-0 supported on llama.cpp. Meta also provides an official GGUF quant:
X post · Local & open models· ♥ 86

james
@ads4apps
Having @Muse find the best offer to sell my Model X. Then it’s finding a lightly used new version of the same car
X post · Errands & personal agent

Xiao Ma
@infoxiao
my favorite Muse use case, ask about my @instagram as a nytimes front page. yes i am that predicable. prompt used "research my aesthetics based on my instagram follows. make a collage in the style of nytimes front page."
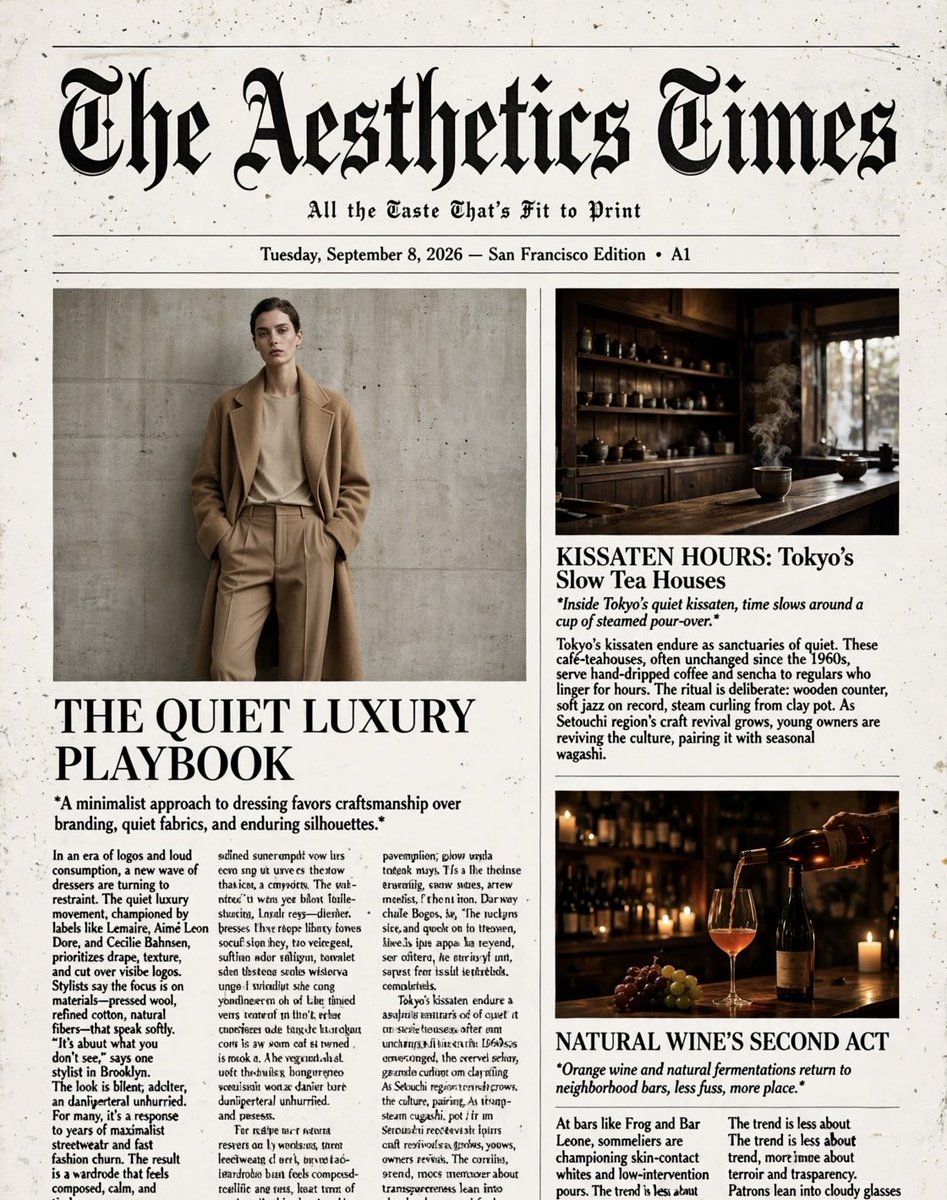
X post · Content & creative· ♥ 9

Iam_
@SPAC89
Try planning with Muse Spark 1.3 Max and then executing with Muse Spark 1.3 xHigh Contributor agents, It cuts costs by more than 90% while still giving you frontier model quality. Honestly, Muse Spark 1.3 Max is one of the best models on the market right now. Everything you see
X post · Games & 3D· ♥ 29
Dilmer
@Dilmerv
Muse Spark 1.3 released today, so I immediately tried it in Muse Code with the Miniature Golf game I previously converted to VR using version 1.2! 💻 The prompt “Add Hands support & allow for hands or controllers. Use MetaVR CLI for additional ISDK context” The entire process
X post · Games & 3D· ♥ 63
"I asked Meta’s Muse to go to YouTube, find a Zuckerberg video about Muse, cut the specific part I wanted, add burned-in subtitles, render it and give me an X-ready video. And it did the whole thing. It searched → found the clip → edited it → added subtitles → rendered → delivered the final file. I didn’t edit anything myself. That’s what makes Muse interesting to me: you’re not just chatting with AI anymore. You’re giving it actual WORK and letting it execute while you do something else. Still very early, but this is a completely different experience." from LorenzoBolsa
Reddit post · Content & creative
Arena.ai
@arena
Muse Spark 1.2 (xHigh) by @AIatMeta is #14 in the Code Arena: WebDev, with 1,545 pts! This is an improvement from Muse Spark 1.1 at #18. See its biggest gains by category in the post below. Congrats to the @AIatMeta team on this release!
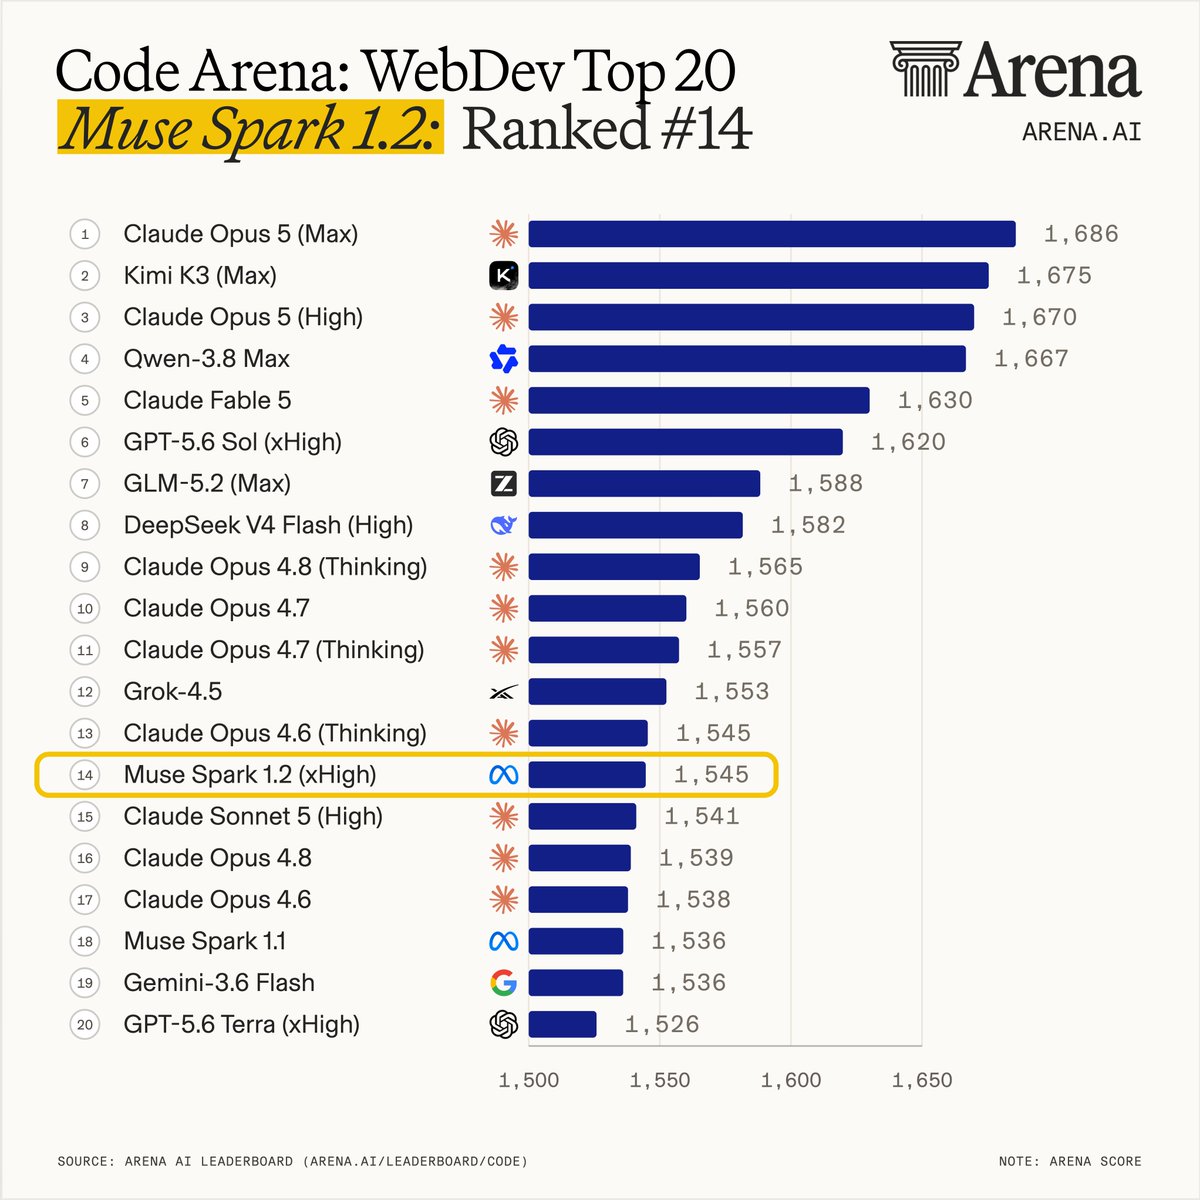
X post · Benchmarks & research· ♥ 380
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Design Arena
@DesignArena
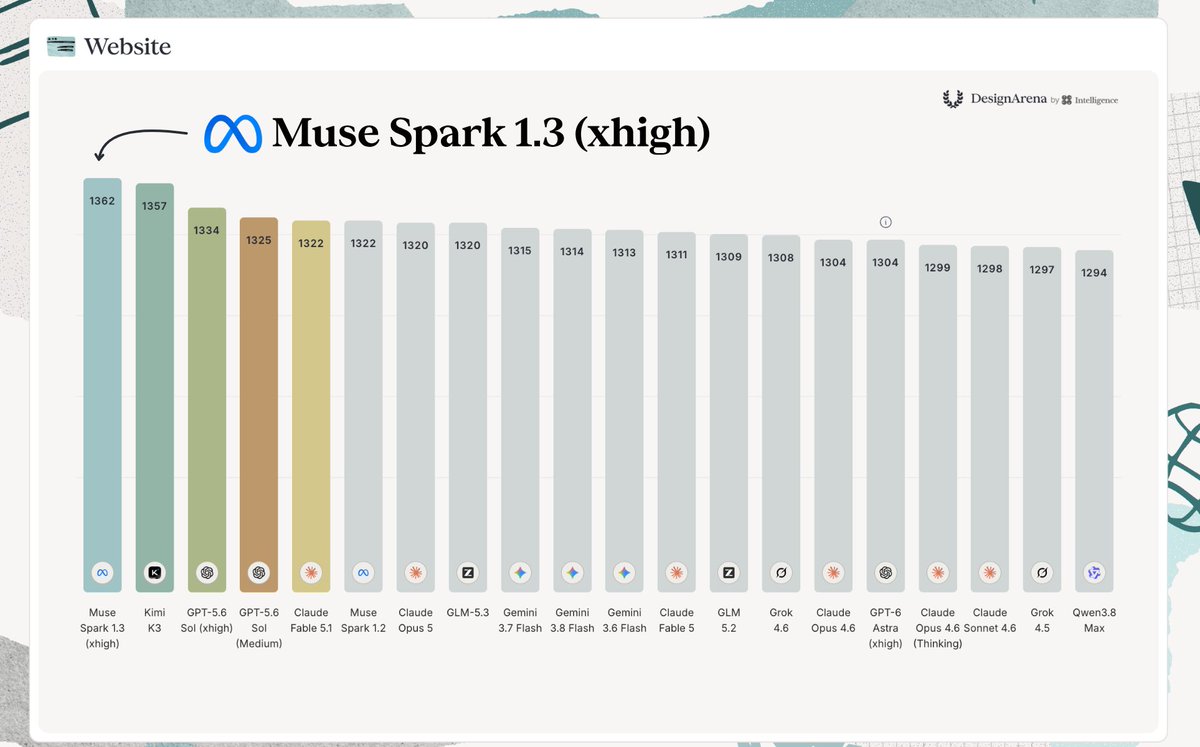
BREAKING: Muse Spark 1.3 (xhigh) takes 1st overall on Website Arena with an Elo of 1362! This is a jump of 5 positions from Muse Spark 1.2, establishing a new Pareto frontier for Speed and Price. Only a month after the release of Muse Spark 1.2, @AIatMeta has topped this
X post · Benchmarks & research· ♥ 864
RepoChad examines Muse Spark 1.3's 1,048,576-token context, DeepSWE and TerminalBench results, and the Max vs x-high reasoning modes.

Video · Benchmarks & research· ♥ 75
Built musedirectory.dev to collect useful Muse agent and Muse Code use cases that were scattered across X threads, YouTube videos and blog posts.
Reddit post · Apps & websites
A single-file Three.js superhero platformer designed, coded and play-tested by Muse Spark 1.3 at xhigh effort in one autonomous session, passing 25/25 automated browser checks.
GitHub · Games & 3D
A Muse skill that helps people buy crypto (XRP by default) with a card through Changelly, giving CoinGecko spot estimates, prefilled buy links and plain fee disclosure without any API keys.
Skill · Business & commerce

Alok
@analogalok
The "I don't have enough VRAM" excuse just died. I’m running Meta’s new 30B Muse Glimmer Q6_K_XL with a massive 130k context window on just 26GB VRAM FREE compute on Kaggle. Kaggle provides you free 2x Nvidia T4 GPUs. 30 hours usage each week! Yesterday, I showed you the
X post · Local & open models· ♥ 170
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Shifros
@Studioshifros
Decided to stress test Muse Spark 1.3 xhigh on 3D game logic in Three.js. Built out an entire browser driving demo with different daytimes, and vehicle physics. TBH the result is so much better for the time I spent on it. @threejs @alexandr_wang Try: gg-shifro.vercel.app
X post · Games & 3D· ♥ 56
A few things right off the bat: • it reasons very efficiently. Like Grok 4.5 levels of efficient thinking • it quantizes very well. My first few tests with iq3_xxs were better than Qwen/Gemma behaved at that size • its knowledge depth is amazing. It beats Qwen3.6 27B on no-tools trivia. • in OpenCode it is a much more efficient agent than 27B. Both models accomplish their tasks but Muse-Glimmer got there faster every time I'll say that it's worse at most things coding, probably being closer to Gemma4-31B level.. but damn there's a lot of places where I'd use this model on a 24GB GPU right now and it's been a while since anything has filled that spot except for 3.6-27B
Reddit post · Benchmarks & research
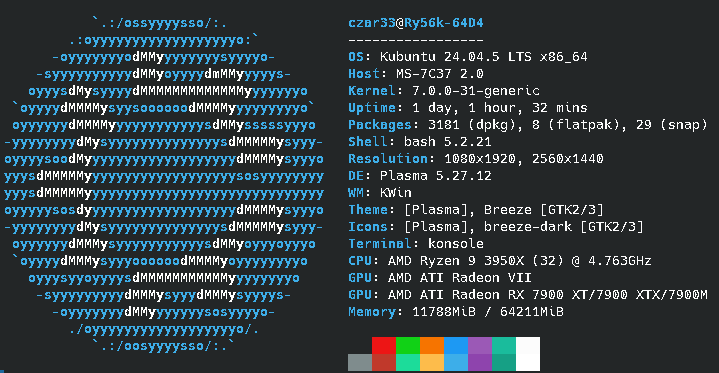
Picked up China version of the Mi50 (Radeon VII) 16GB VRAM GPU for about $135. Ran it using llama.cpp Ubuntu Vulkan prebuilt binary build: b29c606e2 (10964). Used a Power Limit or 220/190 watts on the GPUs. Dual Radeon 32GB Vram and 64GB DDR4 System Dual Radeon RX 7900 GRE and Radeon VII 32gb VRAM GGUF Models: • Qwen3.6-35B-A3B-UD-Q5_K_XL.gguf • Accio-Lab_occamy-1.0-Q5_K_S.gguf • Laguna-XS-2.1-APEX-I-Balanced.gguf • NVIDIA-Nemotron-3.5-Lightning-30B-A3B-Q5_K_M.gguf • Gemma-4-31B-it-Q6_K.gguf • Ateron_Gemma-4-MoonGem-31B-Q5_K_M.gguf • Qwen3-Coder-30B-A3B-Instruct-UD-Q6_K_XL.gguf • Qwen3-VL-30B-A3B-Thinking-UD-Q6_K_XL.gguf • Qwen3-Coder-30B-A3B-Instruct-UD-Q5_K_XL.gguf • North-Mini-Code-1.0-MXFP4_MOE.gguf • GLM-4.7-Flash-Uncen-Hrt-NEO-CODE-MAX-imat-D_AU-Q6_K.gguf • Muse-Glimmer-30B-UD-Q6_K_XL.gguf • Huihui-Qwen3.8-27B-abliterated-UD-Q6_K_XL.gguf • Qwen3.8-27B-Q6_K.gguf • Qwen3.8-27B-OBLITERATED-Q5_K_M.gguf • Medgemma-27b-it-UD-Q6_K_XL.gguf • Gemma-4-26B-A4B-it-UD-Q6_K_XL.gguf • Gemma4-26B-A4B-QAT-Uncensored-HauhauCS-Balanced-Q4_K_M.gguf • GPT-OSS-20b-abliterated.i1-Q6_K.gguf Sorted by params then size model size params pp512 tg128 qwen35moe 35B.A3B Q5_K - Medium 24.76 GiB 3
Reddit post · Local & open models
posterly's Muse custom connector (OpenAPI with a Bearer key, or hosted MCP) lets Muse list connected social accounts and schedule posts to Instagram, Facebook, TikTok, X, LinkedIn, YouTube and more, once the user confirms caption, media and time.
Site · Content & creative
Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.
Site · Local & open models


 ChatForm
 Tgmlabs