№ 0466Reddit post
Profile v2.2: 421 tok/s Glimmer on one RTX 5090
Used his open-source inference optimizer Profile to tune a vLLM server running Muse Glimmer 30B for SWE-Bench agents: 81 → 421 tok/s at 25K context and $3.41 → $0.65 per 1M output tokens in 4 iterations.
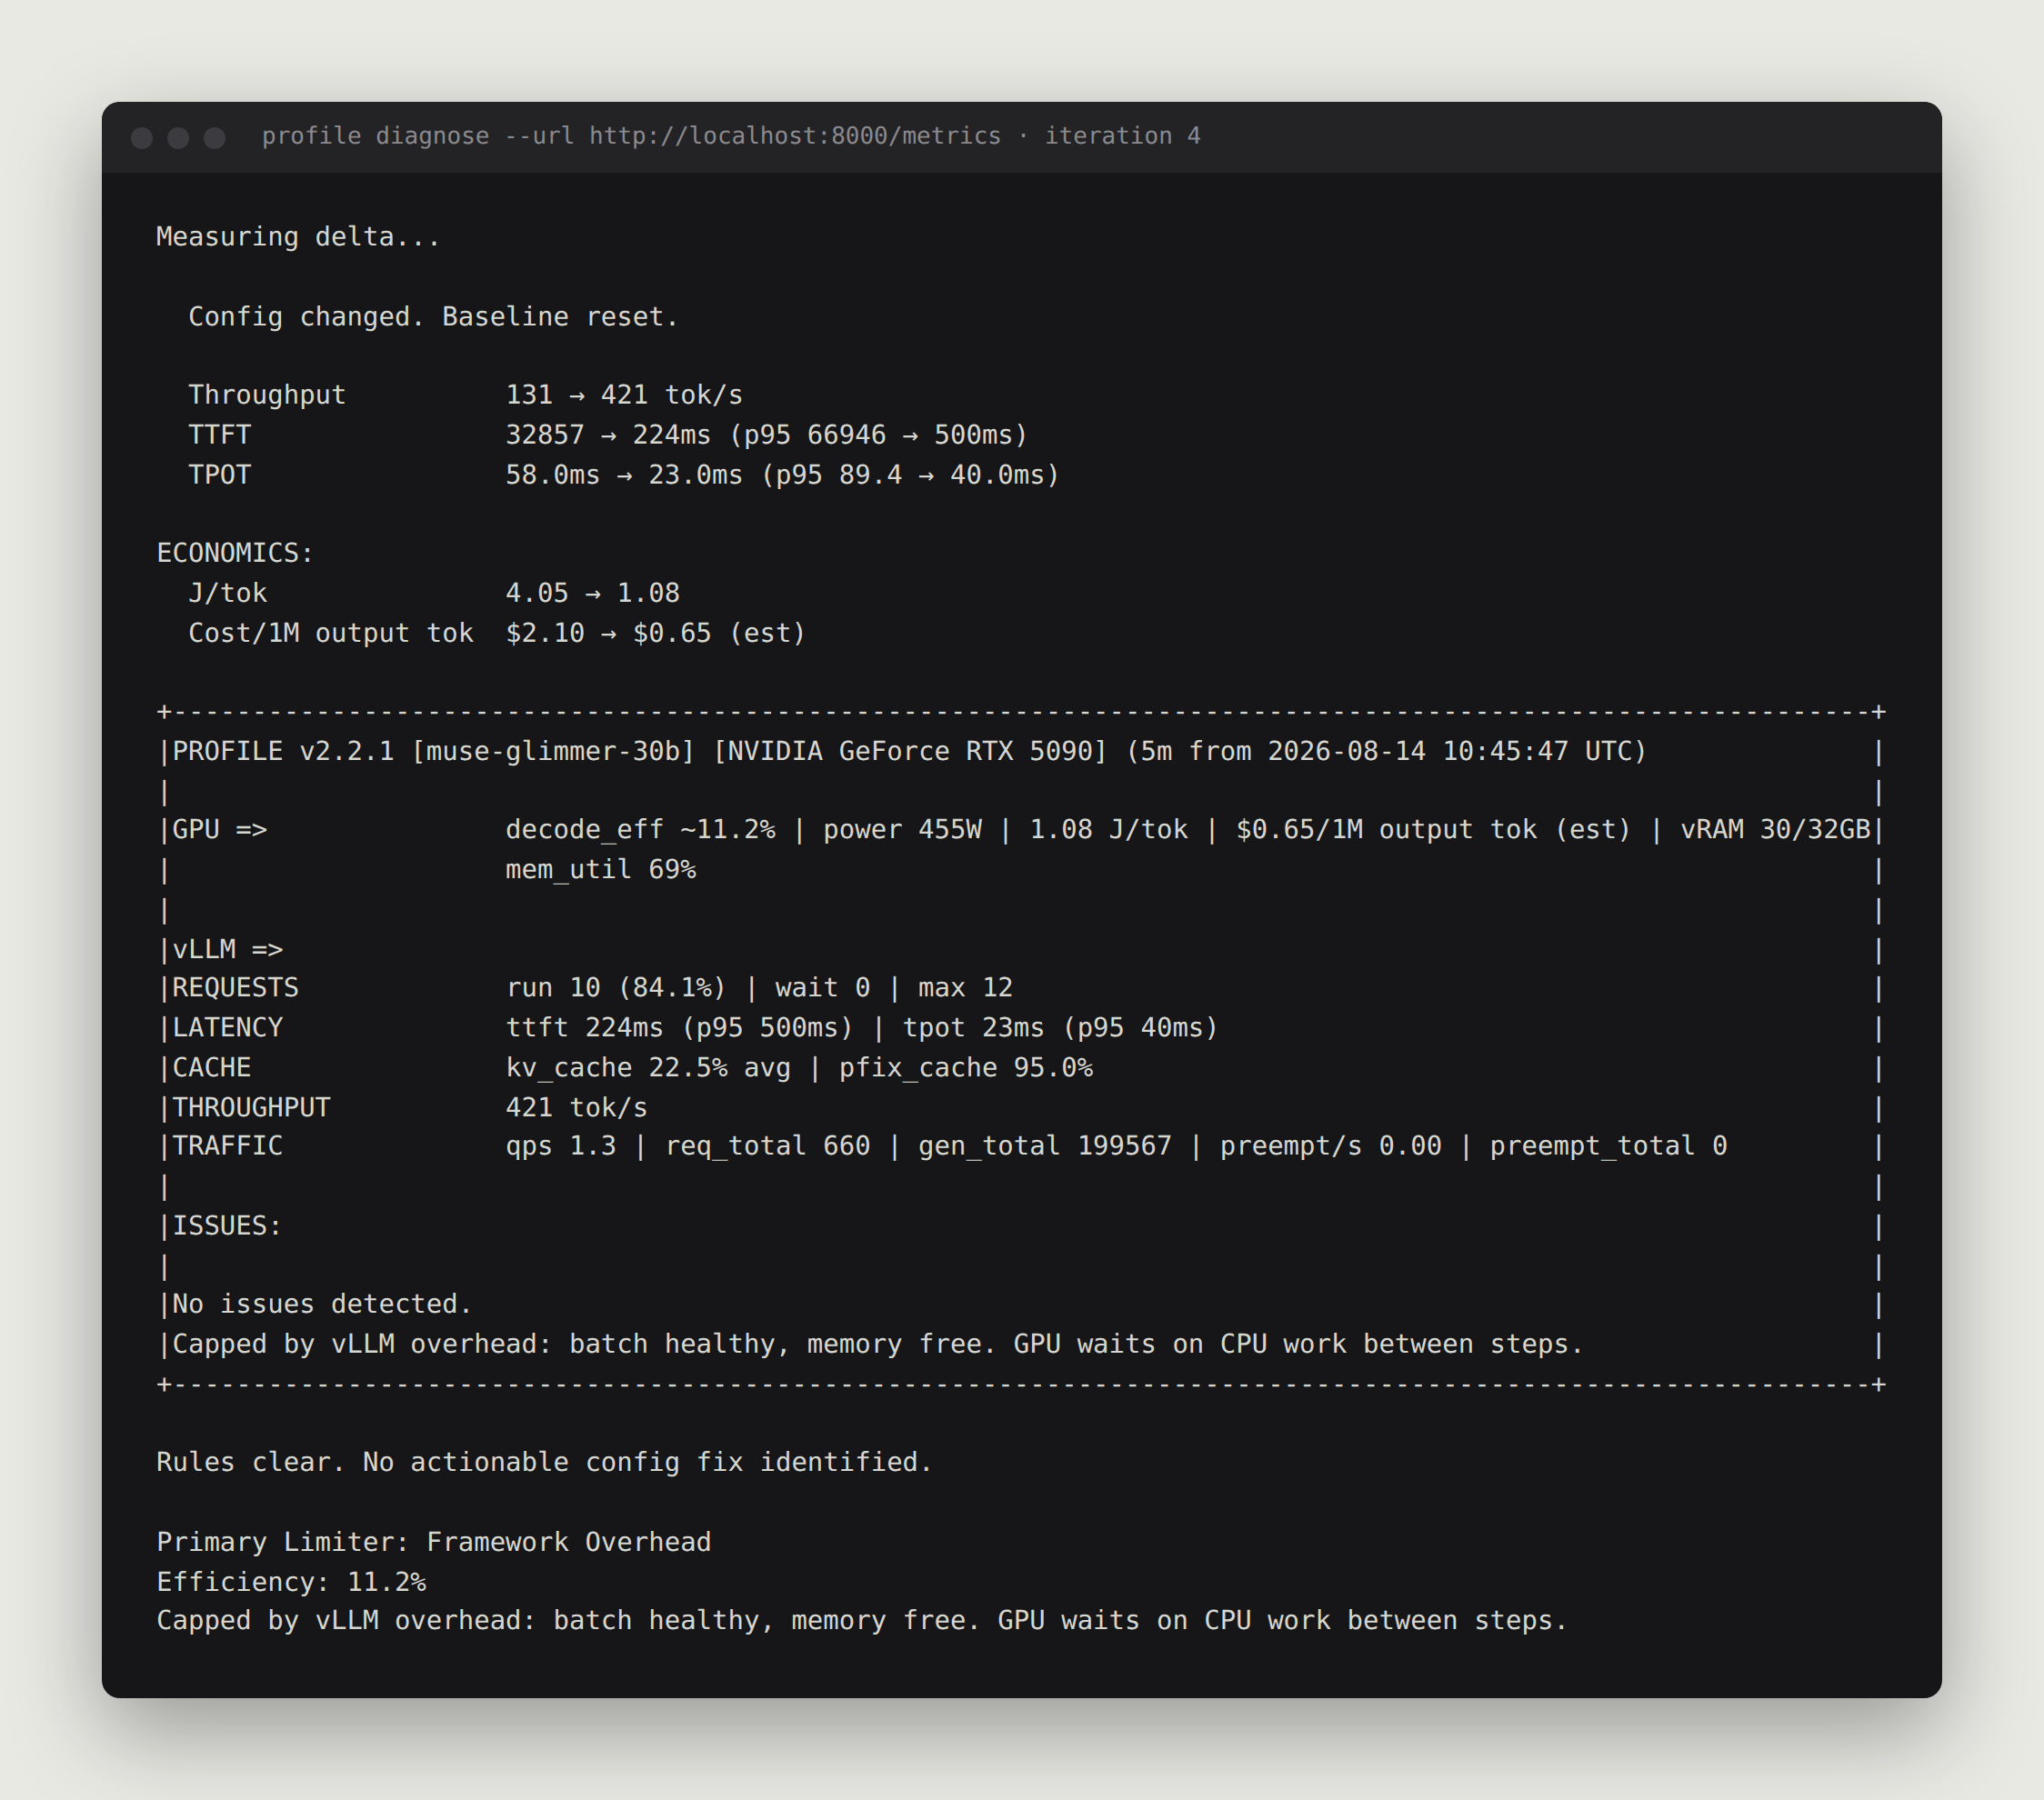
Profile v2.2: 421 tok/s with 25k ctx on a single RTX 5090 with muse-glimmer, no DFlash spec decoding
Hi all, Profile v2.2 is out. It's an open-source optimizer for inference servers. It computes your GPU's roofline ceiling, measures your live server against it, names the bottleneck, gives the flag. You apply. It re-measures. Every fix answers to a number. vLLM only today. More engines next. This release: core rule engine rewritten. Eight rules on a priority DAG with mutual exclusivity. Five alarms fire, four echoes are silenced, one true cause survives. Deterministic. AMD cards are now supported too. Tuning today is chaos: try a flag, wait, squint at a dashboard, repeat for days. Profile turns it into deterministic engineering: measure, fix, verify. Results in a few iterations. Mine took 4, ~30 minutes. My setup: RTX 5090, muse-glimmer 30B, SWE-Bench agents, no DFlash spec decoding. • 81 → 421 tok/s at 25k ctx • $3.41 → $0.65 per 1M output tok • TTFT 224ms (p95 500ms), TPOT 23ms at end of run • 4.72 → 1.08 J/tok https://preview.redd.it/4vazyxkcq6kh1.png?width=2248&format=png&auto=webp&s=77923a489b6f725240d23a7953150b5779260734 One iteration regressed hard: KV thrashing, TTFT 32.8s. Profile labeled it worse. Next fix recovered it. Regressions stay in the record. Watc



 ChatForm
 Tgmlabs