shipwithmuse

Entries matching “max”

31 builds · page 1 of 1

Paolo Rosson

@redp314

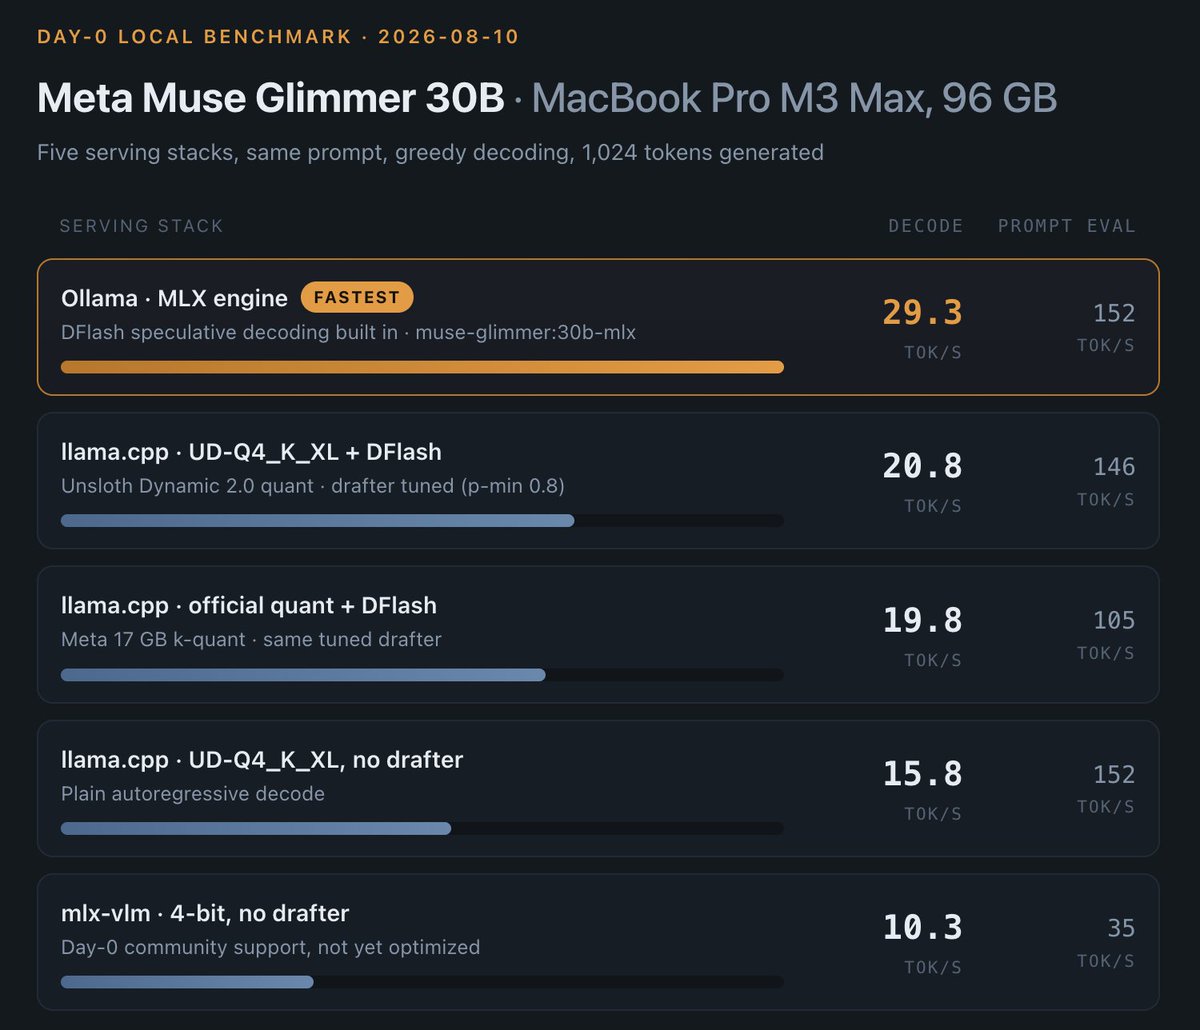
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're

X post · Local & open models★ Pick· ♥ 44

Glimmer serving shootout on an M3 Max

U

mr_il

u/mr_il

My fun weekend project was to try to make the new Muse Glimmer 30B work with a longer context, deciding to go for 512k first. I had expected the usual YaRN shenanigans and maybe a LoRA. I couldn't have been wrong more. Upon closer look, Glimmer turned out to be rather unusual architecturally. The thing that make long-context adaptations painful in other models, full attention layers with token position encoding, it simply not there. Instead, only 2048 tokens-wide SWA layers have RoPE, and full GQA attention layers have no position encoding at all. It appears the model is trained to work with long-distance token relationships inferred from the context and SWA layers. It's a rather bold architecture bet, but it seems Meta managed to pull it off. As a result, the model architecture appears to be uniquely suited for context extension by simple mechanical means. To change model context length from stock 128k to, say, 512k, you need only to change “max_position_embeddings” config setting from 131072 to 524288. What confuses other models, like Qwen3.5 family, Glimmer just takes into its stride. I spent close to 70h of compute on DGX Spark to test stock model with extended context on a

Reddit post · Local & open models★ Pick

Muse Glimmer 30B stretched to 512K context

Max Weinbach

@mweinbach

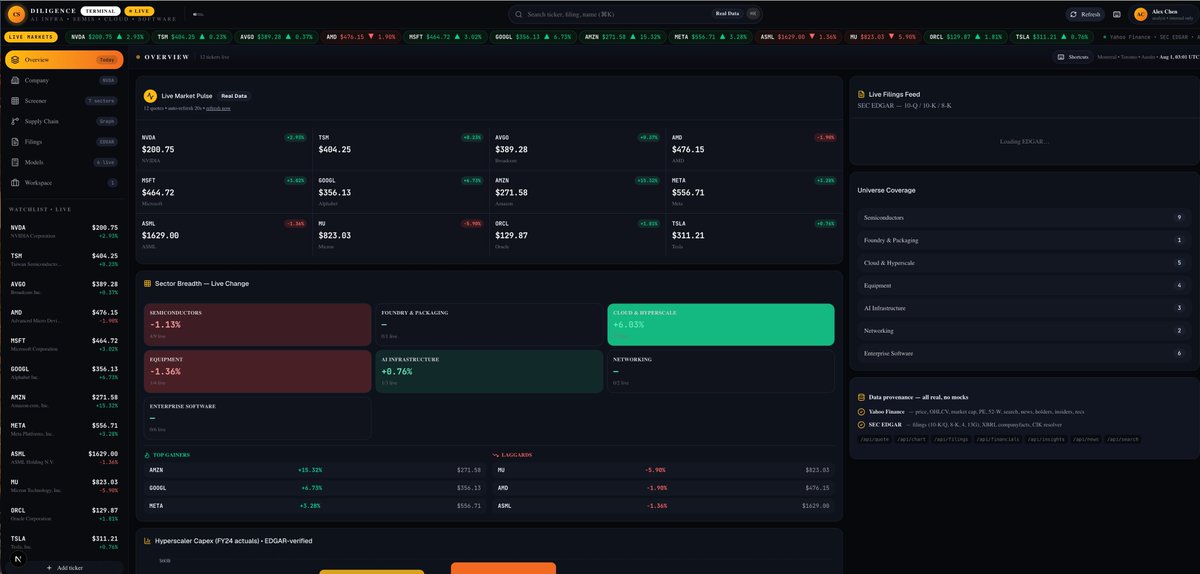
I asked Muse Spark 1.2 in Muse Code to make me an internal Bloomberg terminal style page for work on Friday This was what it made

X post · Apps & websites· ♥ 178

Bloomberg terminal-style work page

TimDarcet

@TimDarcet

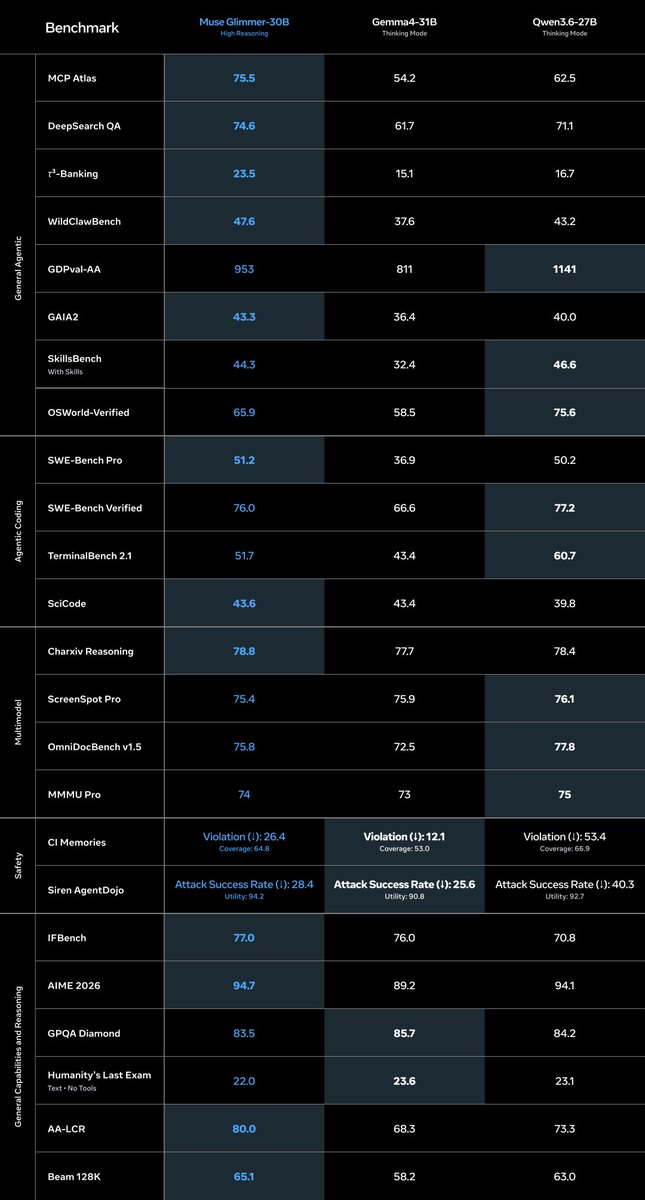
Happy to release ✨ Muse Glimmer ✨ - level ~= Qwen 3.6-27B - Apache 2 - 30B dense - quantized to run in 17GB - quant + spec dec => 50 tok/s on macbook m5 max, interactive, smooth Enjoy!

X post · Local & open models· ♥ 74

Glimmer at 50 tok/s on an M5 Max MacBook

AshutoshShrivastava

@ai_for_success

Got Muse Glimmer 30B running locally on my Mac (M5 Max - 128 GB )and the instruction following is impressive. need to setup with opencode next Video Speed - 5X

X post · Local & open models· ♥ 125

Muse Glimmer on an M5 Max Mac

Iam_

@SPAC89

Try planning with Muse Spark 1.3 Max and then executing with Muse Spark 1.3 xHigh Contributor agents, It cuts costs by more than 90% while still giving you frontier model quality. Honestly, Muse Spark 1.3 Max is one of the best models on the market right now. Everything you see

U

TigerConsistent

u/TigerConsistent

Ran Muse Glimmer on a single RTX 3090 and found a max_tokens setting that made it look dumb; shares numbers at filled context and notes better-than-expected non-English handling.

Reddit post · Local & open models

Muse Glimmer on one 3090: the max_tokens gotcha

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@CogniTechSystems

@CogniTechSystems

This repo documents running Muse Glimmer 30B locally on an M4 Max MacBook via llama.cpp, benchmarking it with and without speculative decoding, and wiring it into Claude Code through LiteLLM for fully offline coding.

GitHub · Local & open models

Claude Code on local Muse Glimmer 30B

@ryangu00

@ryangu00

A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.

GitHub · Local & open models

Muse Glimmer on Dell GB10: a negative result

@rickyzzzzz

@rickyzzzzz

A controlled local benchmark on an M1 Max comparing Muse Glimmer 30B with Qwen 3.6 35B and Qwen 3.8 27B on tool calling and data-science tasks; Glimmer passed 24/30 versus Qwen 3.8's 30/30.

GitHub · Benchmarks & research

Muse Glimmer vs Qwen local agent benchmark

Paweł Huryn

@PawelHuryn

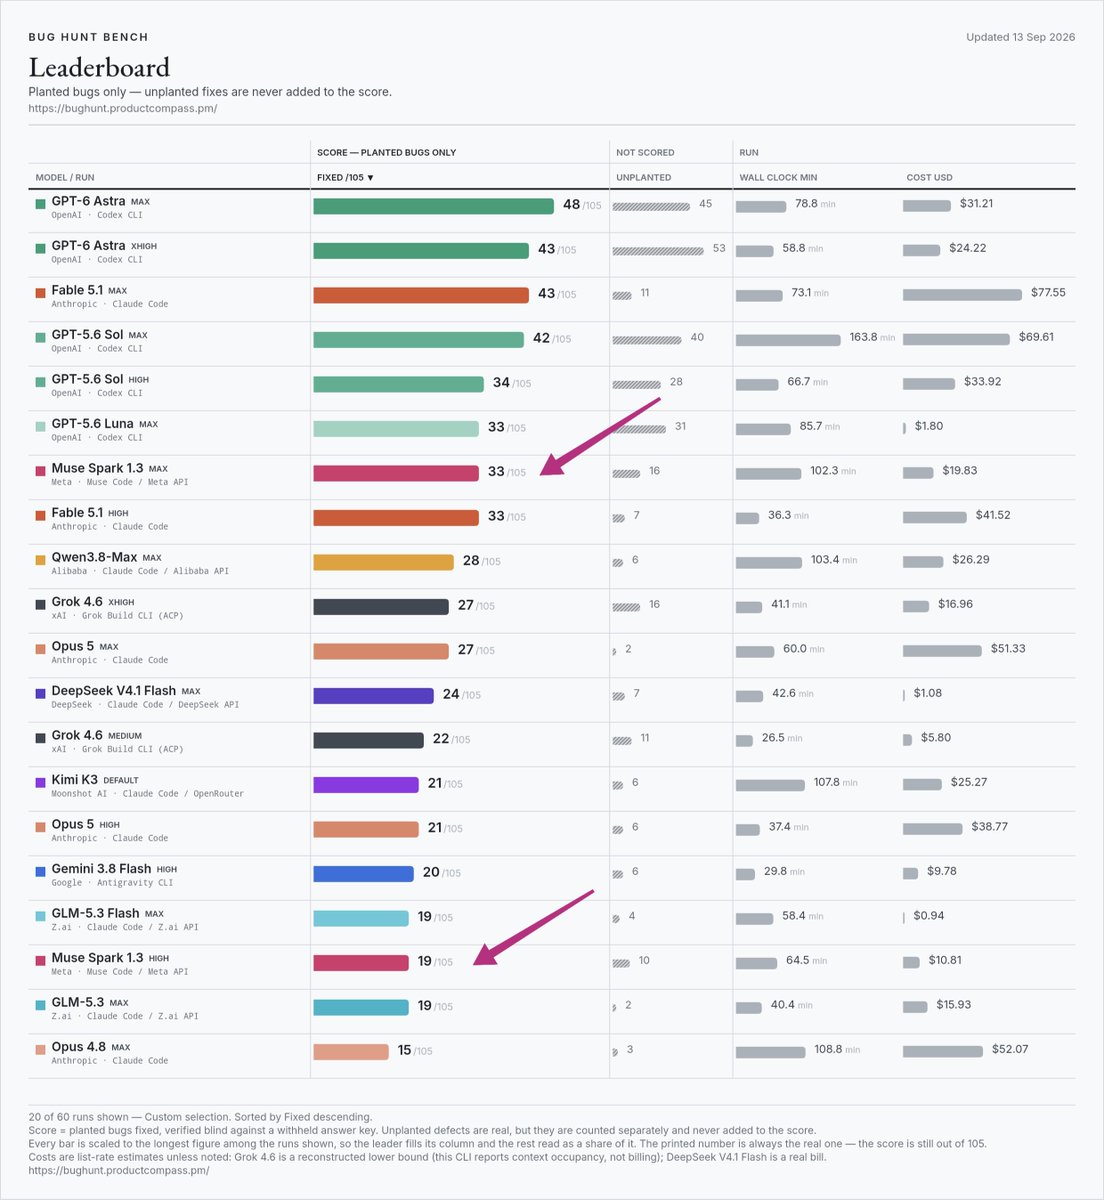
So, I finally tested Muse Spark 1.3. 2 real repos, 105 planted bugs, find and fix what you can. Original harness and API. Big surprise: Muse Spark 1.3 (max): 33 Fable 5.1 (high): 33 Grok 4.6 (xhigh): 27 Opus 5 (max): 27 Muse Spark 1.3 (high): 19 Meta joined the frontier.

X post · Benchmarks & research· ♥ 694

105 planted bugs: Spark 1.3 vs frontier

U

j4ys0nj

u/j4ys0nj

The vLLM recipe page for Muse Glimmer has this for speculative decoding: --speculative-config '{"method": "dflash", "model": "meta-models/Muse-Glimmer-30B-assistant", "num_speculative_tokens": 15}' This errors out on the current vllm/vllm-openai:muse-glimmer image, and each fix reveals the next error. Six separate issues in total, all in the DFlash path. The base model runs fine without the spec config. The source for the image isn't public yet (the recipe says "code will be released soon"), so I pulled the image layers through the registry API and read the code to figure out what was going on. Also checked tensor names by range-requesting the safetensors headers off HF instead of downloading the weights. What I found: • The drafter's config declares MuseGlimmerAssistantModel, which is in vLLM's registry. But the dflash code renames it to DFlashMuseGlimmerAssistantModel before the registry lookup, and that name isn't registered. Dies in config validation. • vLLM maps the drafter's config to Qwen3Config (there's a comment calling it "Qwen3-shaped"). The muse JSON omits vocab_size and use_sliding_window, so Qwen3Config fills in its own defaults: vocab becomes 151936 (the model i

Reddit post · Local & open models

Six vLLM patches for Glimmer DFlash decoding

M

marktechpost.com

marktechpost.com

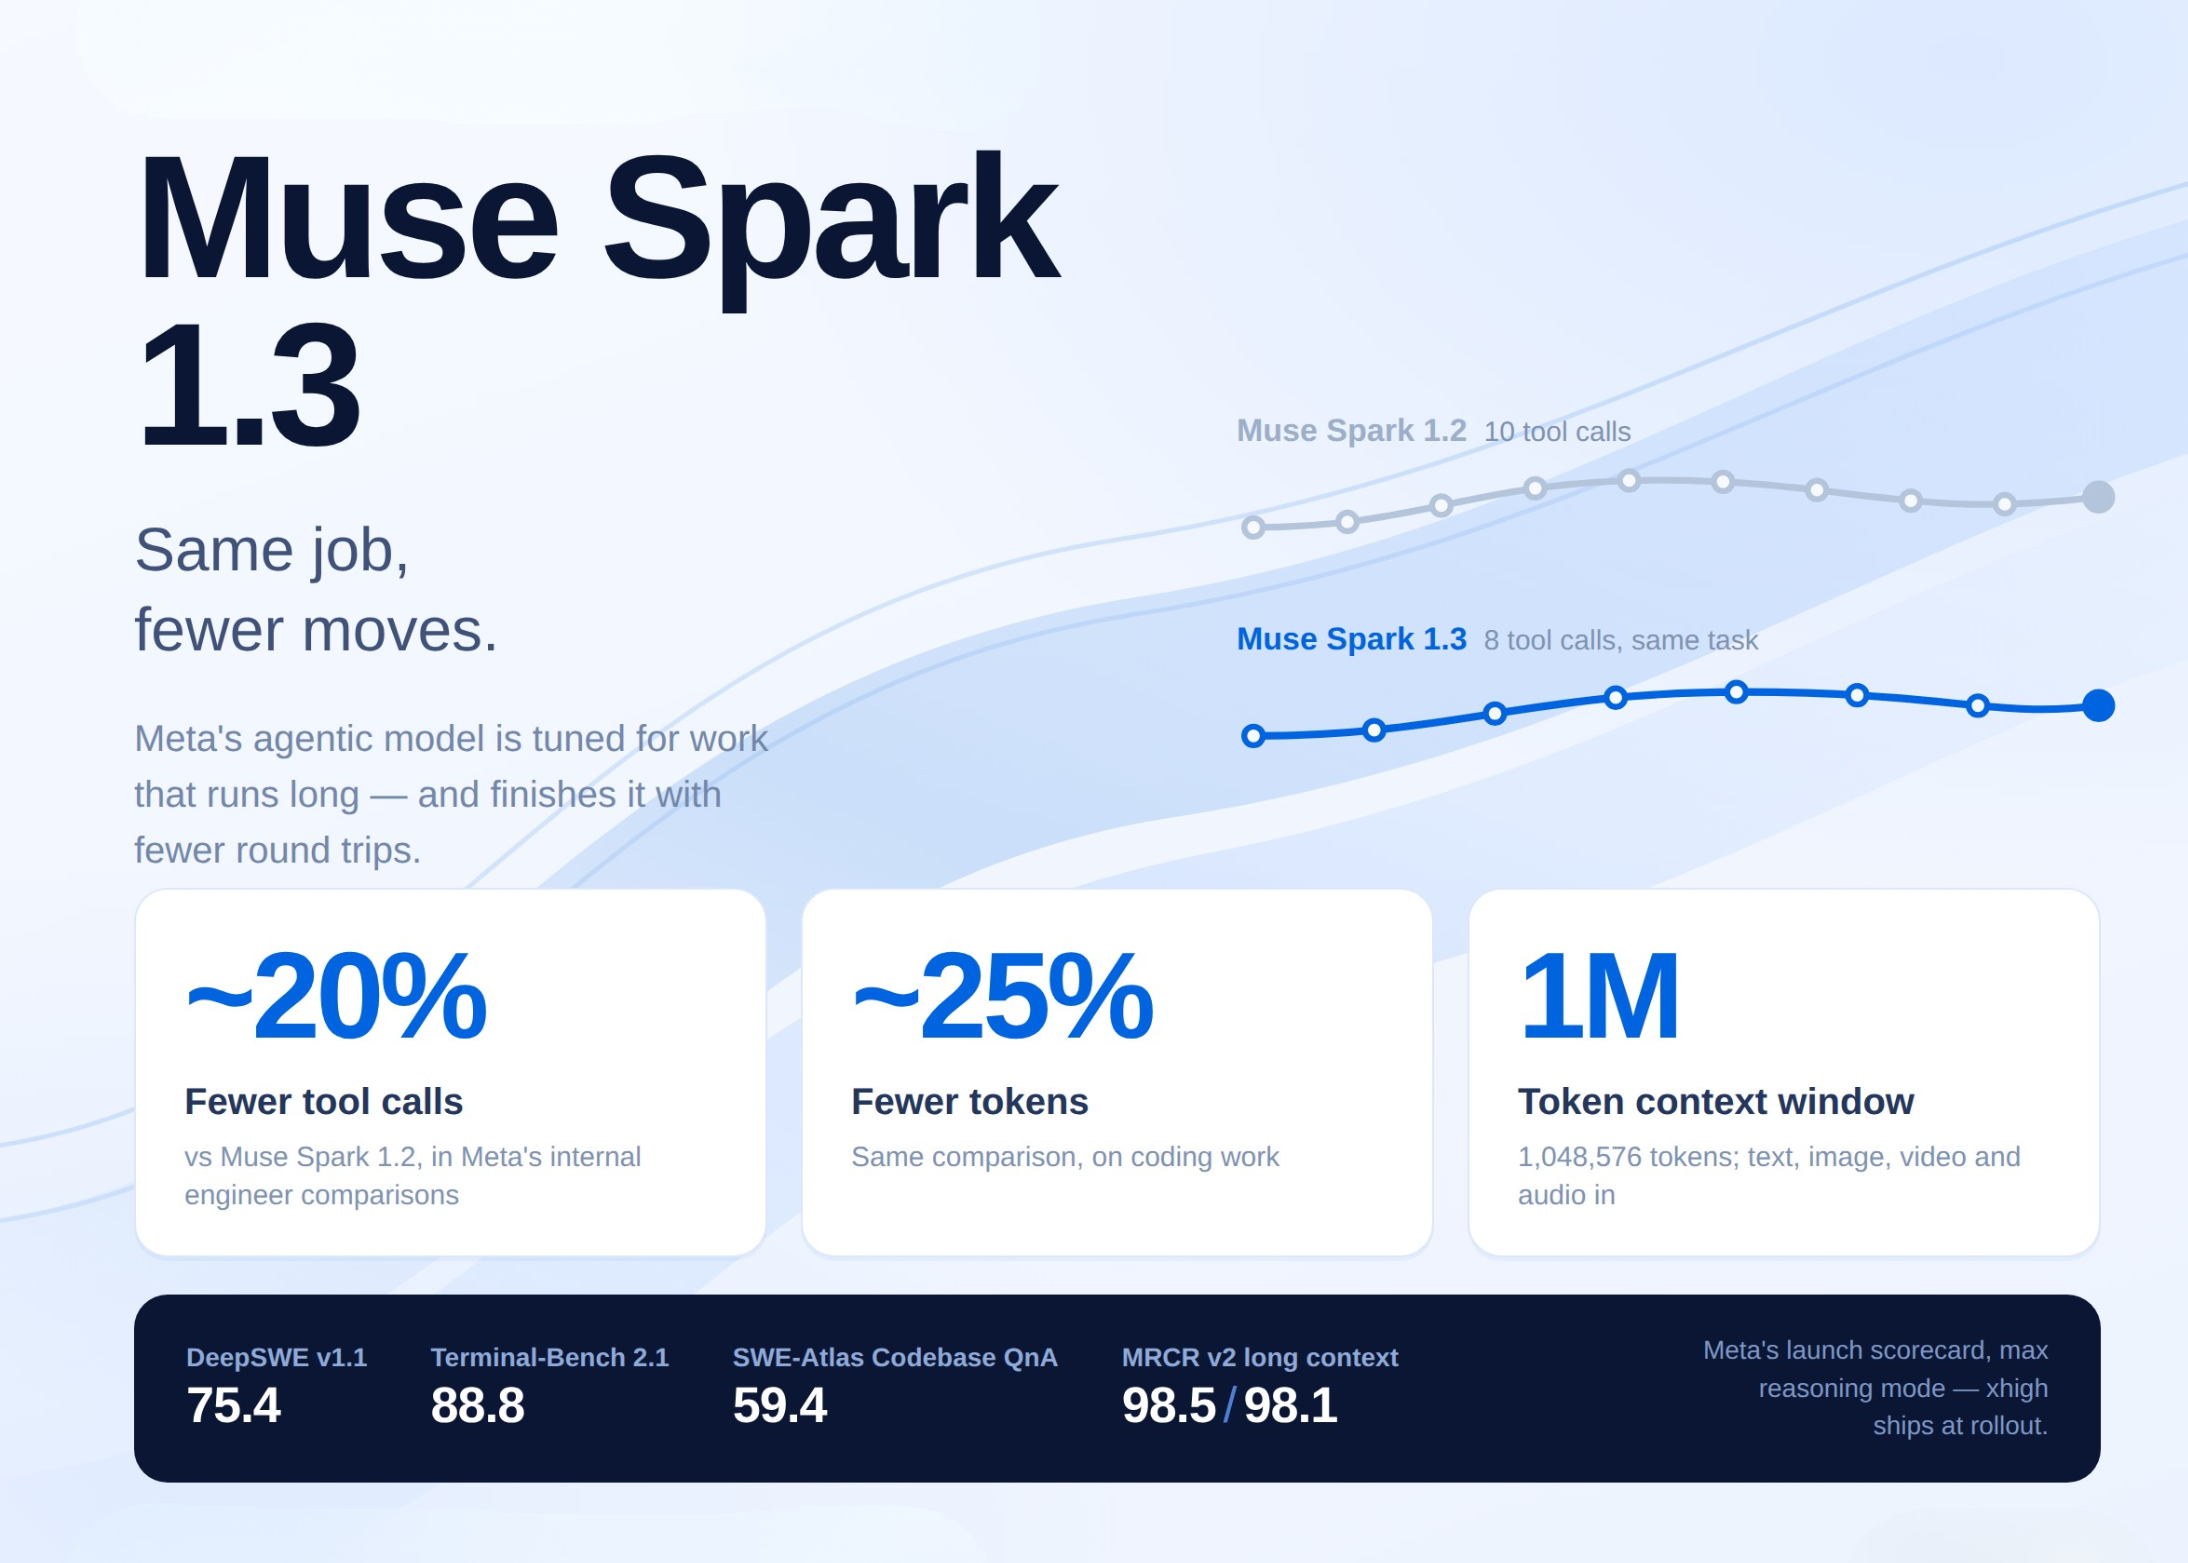
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.

Resource · Benchmarks & research

MarkTechPost: Muse Spark 1.3 benchmarks breakdown

U

6353JuanTaboApp6

u/6353JuanTaboApp6

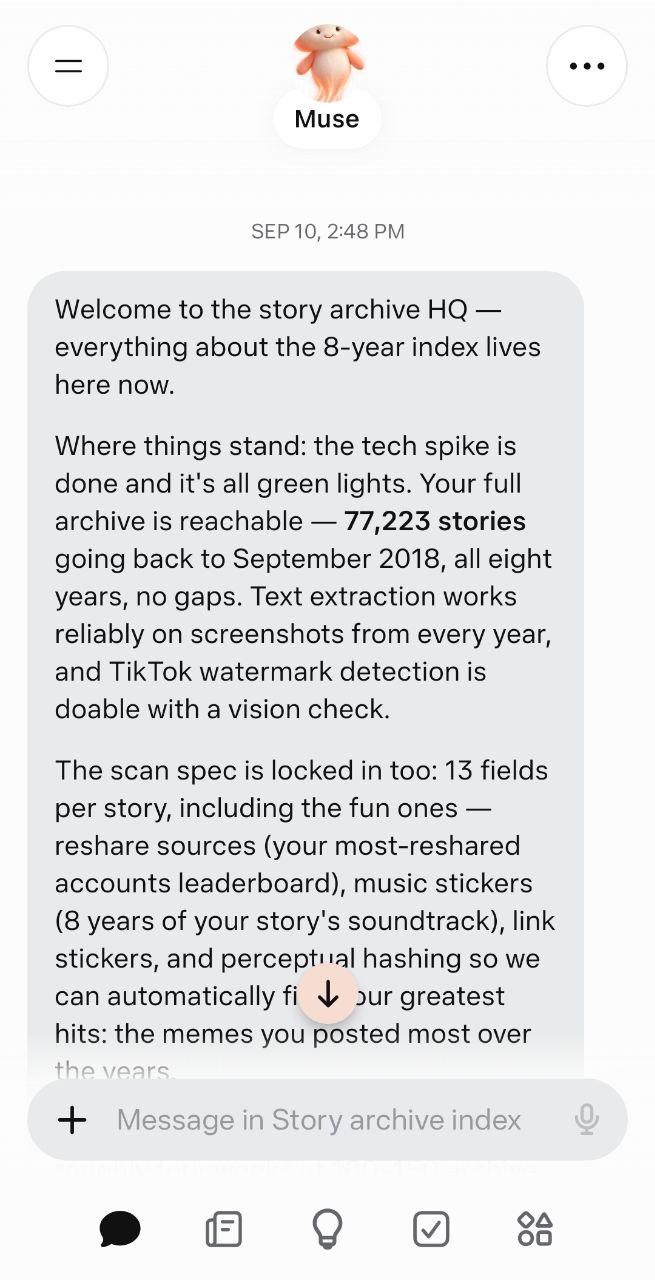
theres simply no other AI agent or tool that can do this for you for free PROMPT # Story Archive Census ## What to do Your human wants a full census of their Instagram story archive. Read this entire file, then follow the steps in order. The job is a census: walk every page and count every story, newest to oldest. It does not download any media. What you're working with: **Tool** — the Instagram connector's command line tool, `instagram-cli`. **Command** — one call returns one page of archived stories (about 20 per page), newest first. Each page hands back a `next_max_id` cursor pointing at the next page: instagram-cli own-stories-archive --account-id <YOUR\_ACCOUNT\_ID> ## Workflow ### 1. Walk the archive - Fetch the first page with no cursor. - For each page, record the page number, the story count, the newest story date, the oldest story date, and the `next_max_id`. - Feed that `next_max_id` back as `--max-id` on the next call, and keep going. - One call at a time, a second or two apart. No parallel calls. ### 2. Save progress - Write the page records plus the latest cursor to a state file every 10 pages, so the run can resume after an interruption instead of sta

Reddit post · Errands & personal agent

Census of a 77k Instagram story archive

M

research.meta.ai

research.meta.ai

Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Introducing Muse Glimmer

U

xenovatech

u/xenovatech

Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.

Reddit post · Local & open models★ Pick

Muse Glimmer 30B in the browser via WebGPU

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Alexandr Wang

@alexandr_wang

1/ we just publicly released Muse Spark 1.3 max! we see significantly stronger coding and agentic performance on muse spark 1.3 max, so would strongly recommend trying it out even if you've already tried muse spark 1.3 high or muse spark 1.3 xhigh.

+3

X post · Coding & dev tools· ♥ 2K

Muse Spark 1.3 max goes public

Arena.ai

@arena

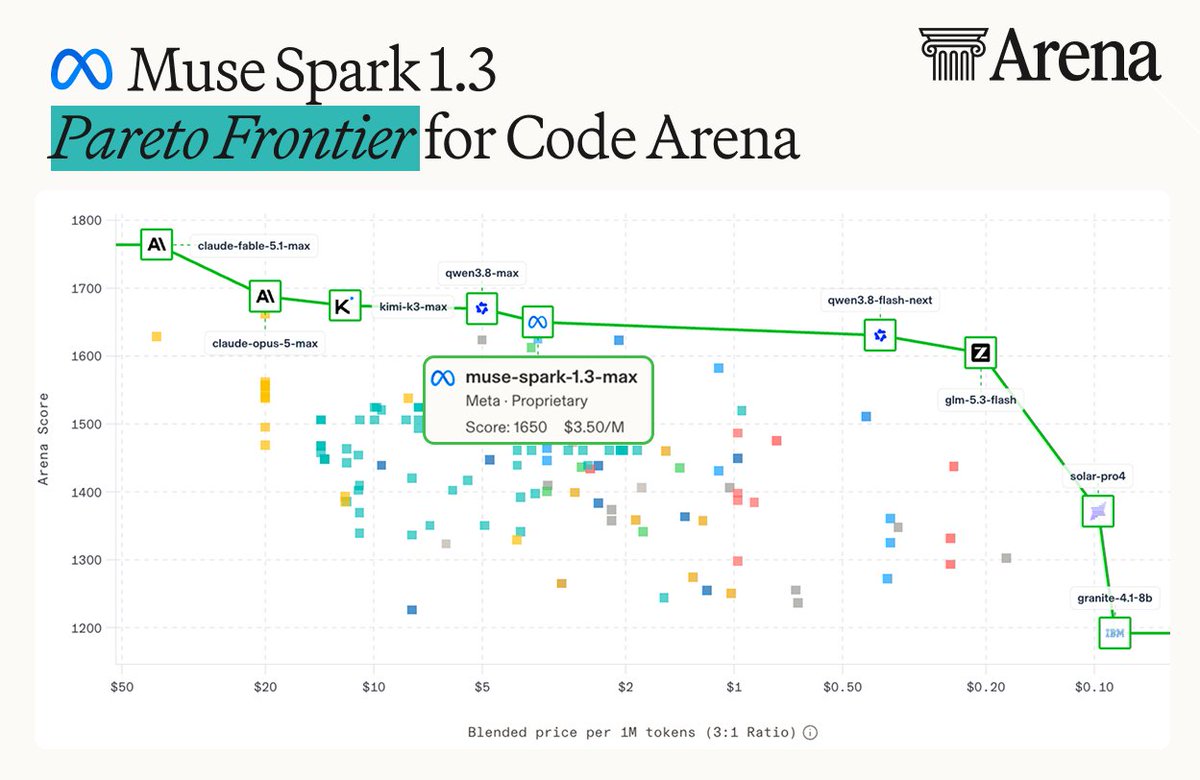
Muse Spark 1.3 Max by @AIatMeta has reshaped the Pareto frontier for Code Arena: WebDev! Meta's latest model at Max reasoning is doing something interesting on the Arena Pareto frontier: it's the only model holding down the wide price band between Qwen3.8-max ($5/MToken) and

X post · Benchmarks & research· ♥ 334

Spark 1.3 Max on the WebDev Pareto frontier

Meta for Developers

@MetaforDevs

Muse Spark 1.3 with max reasoning is now available on Muse Code and Meta Model API. Developers can build with frontier performance without the frontier prices. We thought showing would be better than telling, and encouraged our friends in Meta Superintelligence Labs to come up

X post · Games & 3D· ♥ 779

MSL one-shot demos on Spark 1.3 max

Pattern Preacher

@chanakyaspeakss

I had one shotted this with explicit instructions to create this game with all the Asset specifications on @opencode and it generated in 30-40 Seconds. Couple more iterations and inputs will give us a production ready game. Great Job Team Meta #ReverseSonic

Artificial Analysis

@ArtificialAnlys

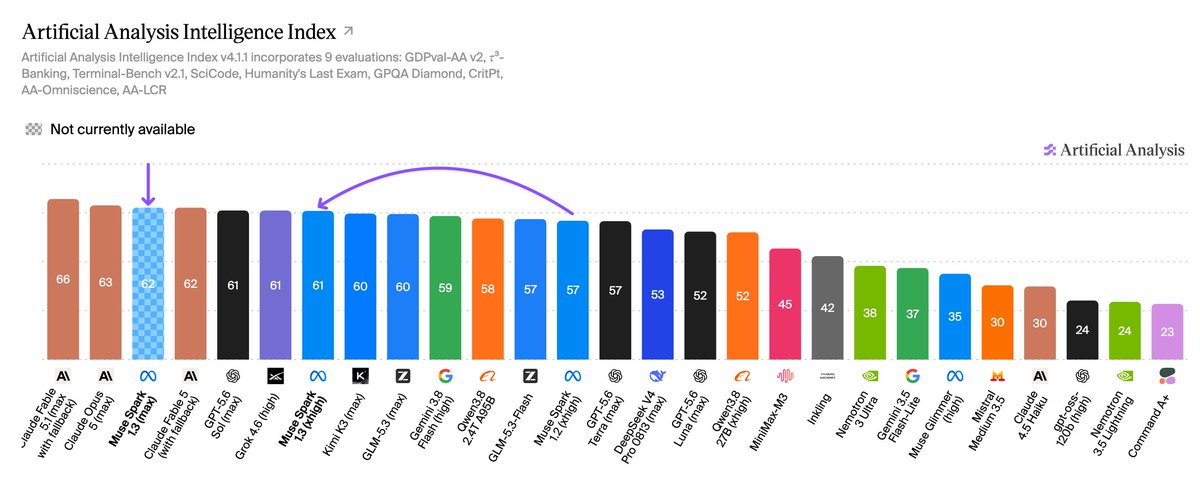
Meta has released Muse Spark 1.3, their fourth Muse Spark model release in five months. Muse Spark 1.3 (max), which is in limited preview for Meta’s partners, scores 62 on the Artificial Analysis Intelligence Index, behind only Claude Fable 5.1 and Claude Opus 5. The variant

X post · Benchmarks & research· ♥ 2.6K

Artificial Analysis scores Muse Spark 1.3

Idobn

@idobn

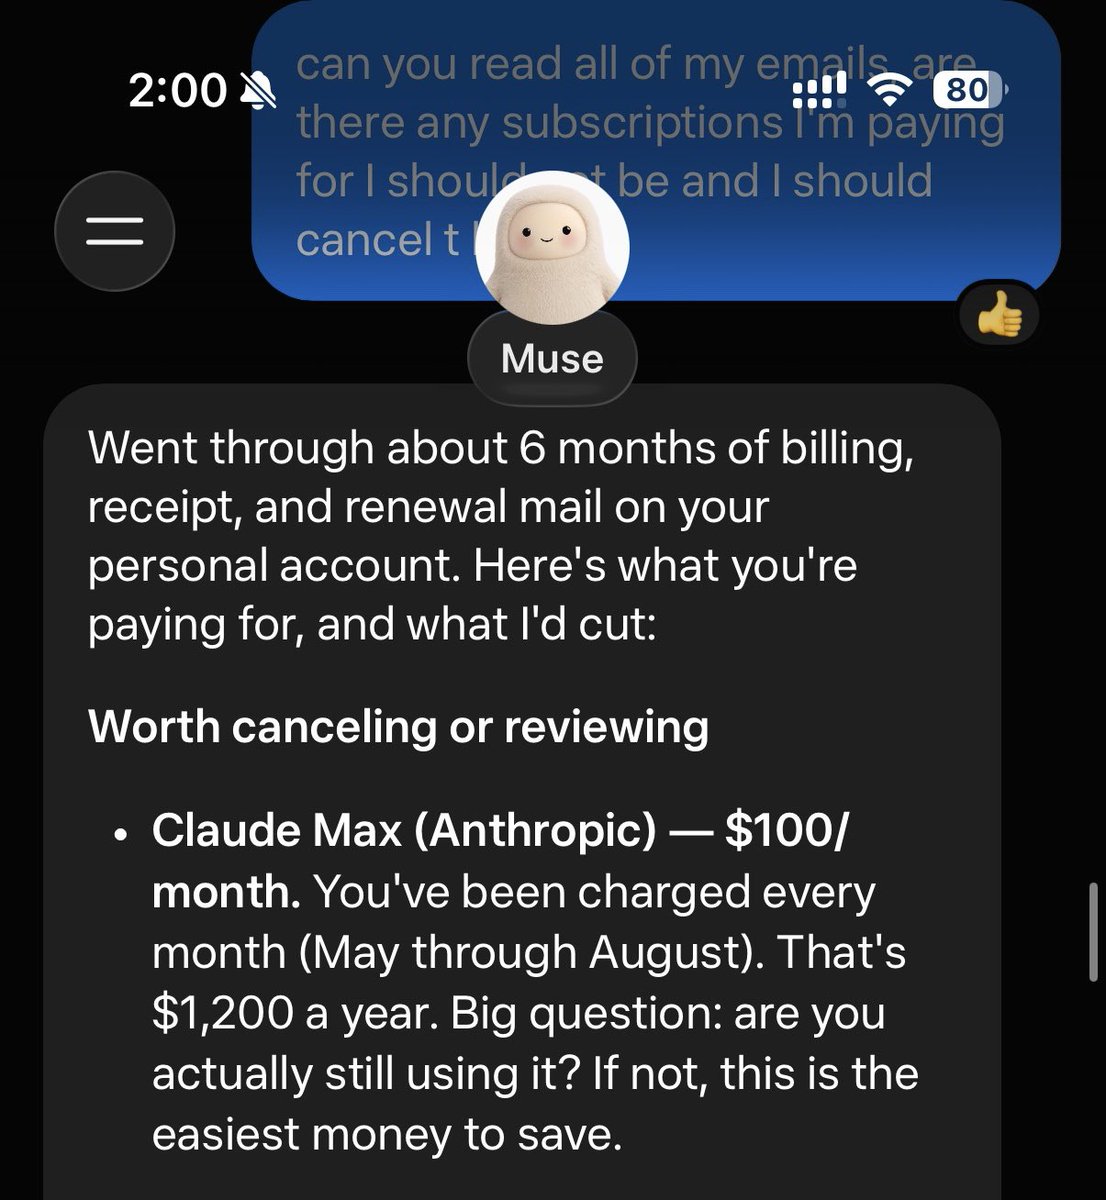
Had @Muse go through 6 months of my email receipts. It found a $100/mo Claude Max sub on my corp card I'd forgotten about, while we already have an enterprise license. $1,200/year saved. @finkd clearly articulates the biz model here - muse is supposed to save / make you money,

X post · Errands & personal agent· ♥ 14

Receipt audit finds $1,200/yr waste

Tornado guy

@fanofaliens

Muse Spark 1.3 Max is out and I already love how good it is at 3D stuff. We’re so back.

X post · Games & 3D· ♥ 31

Pelican Ride 3D motion test

J A Z I I

@notjazii

meta muse just mogged fable 5.1 tested fable 5.1 and muse spark 1.3 with same prompt at highest reasoning available and results came out really different > muse spark 1.3 completed task in one minute and costed almost nothing > fable 5.1 completed task in 70 minutes and costed

X post · Benchmarks & research· ♥ 266

Same prompt: 1 minute vs 70 minutes

P

aicodingdaily.com

aicodingdaily.com

Povilas Korop scores Muse Spark 1.3 on six real coding projects (Laravel, React-TS, PHP, Flutter, Go): Max effort ranks #26 with 48.43/60 at about $0.01 per prompt and 3:42 per prompt.

Resource · Benchmarks & research

AI Coding Daily benchmark of Muse Spark 1.3

@dominicletz

@dominicletz

A self-contained visual report comparing CursorBench 4.0 score against cost per task for Opus 5.5, Fable 5.1, Grok 4.7 and Muse Spark 1.3, where Muse Spark 1.3 Max scores 41.6% at $2.64 per task. GPT-6 points are clearly marked as estimates.

GitHub · Benchmarks & research

CursorBench 4.0 score-vs-cost report

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

M

research.meta.ai

research.meta.ai

Meta's announcement of Muse Spark 1.3 for Muse Code and the Meta Model API, claiming ~20% fewer tool calls and ~25% fewer tokens than 1.2, with a max reasoning mode.

Resource · Coding & dev tools

Introducing Muse Spark 1.3

M

huggingface.co

huggingface.co

Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.

Site · Local & open models

Muse Glimmer 30B weights on Hugging Face