№ 0582Reddit post
8GB VRAM benchmark, with Glimmer as an outlier
Hand-graded 18 questions across six categories on an RTX 4060 laptop; Muse Glimmer 30B nearly aced the benchmark but its time-to-completion was so high he dropped it from the graphs.
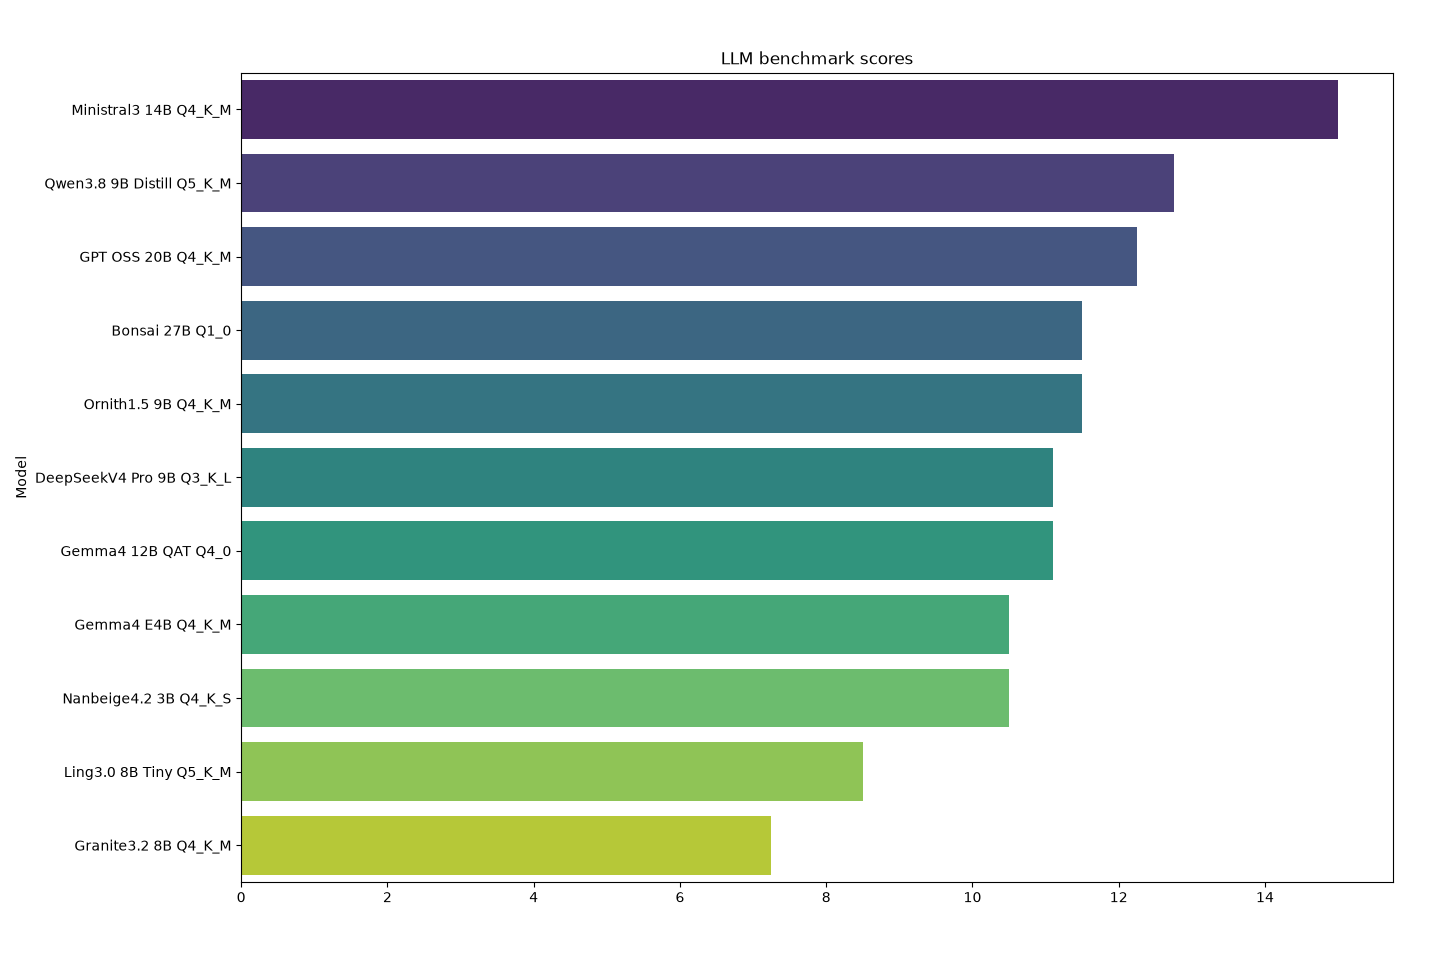
A final LLM benchmark for 8GB VRAM 16GB RAM
IMPORTANT This post is meant to provide info regarding the best local models to run on CONSUMER HARDWARE. I am on an RTX 4060 with 8GB VRAM, 16GB of RAM and I am benchmarking models that can run on my computer. If you have sunk several thousands into graphics cards you won't find these statistics much useful. This post is for all the people who can't just install Qwen3.8 27B and call it a day. Additionally, I am not an LLM benchmarking expert. I am a hobbyist and occasional LLM user trying to extract useful information for both me and people on similar hardware. Context For the past few weeks I have been doing some benchmarks of some LLMs that can run on my laptop which only has 8GB VRAM and 16GB RAM. I was mostly toying around while trying to get some useful data about what the best model is for local inference on consumer hardware. This week I decided to make a "final" benchmark that would be way better with more questions, more question categories, newer models (a lot of people complained about the models I had benchmarked before being old but I didn't find most suggested models to be any good) and a better speed benchmark, this time using TTC (Time To Completion) as a pose to



 ChatForm
 Tgmlabs