1/ big announcement today: we will be releasing an open weight version of muse spark 1.2 soon.
we also are releasing muse glimmer, a 30B agentic model with open weights under apache 2.0. muse glimmer can run on 24GB of VRAM without losing agentic reliability. 🧵
An effort to make Muse Glimmer 30B actually use a 512k-token context (4x native) as a ~17GB GGUF in 32GB VRAM, trained on DGX Spark and evaluated with RULER-style retrieval tests.
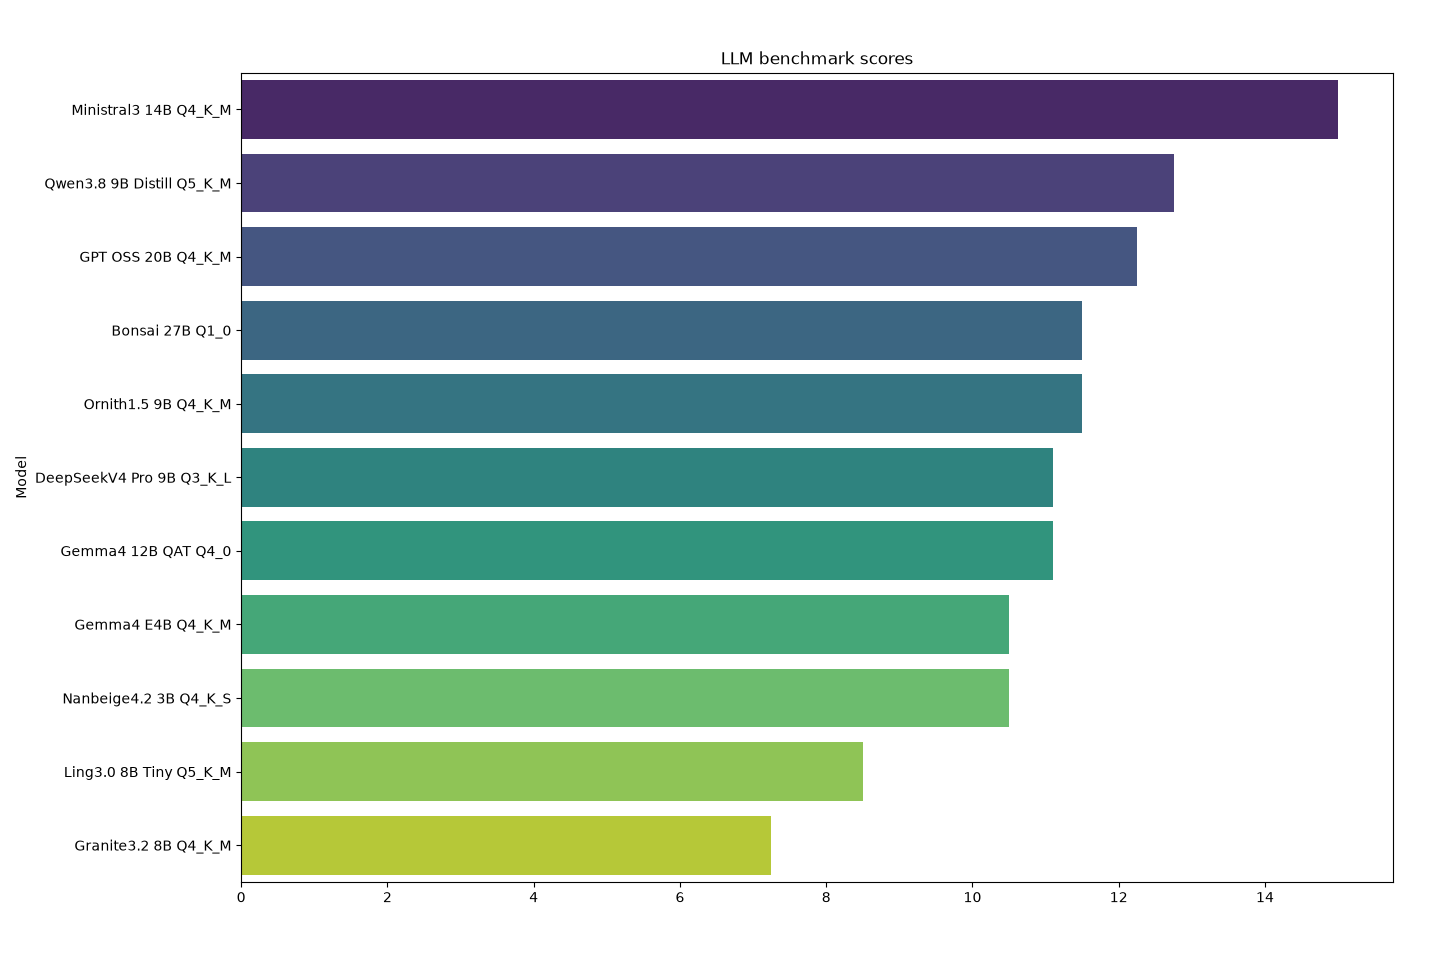
IMPORTANT This post is meant to provide info regarding the best local models to run on CONSUMER HARDWARE. I am on an RTX 4060 with 8GB VRAM, 16GB of RAM and I am benchmarking models that can run on my computer. If you have sunk several thousands into graphics cards you won't find these statistics much useful. This post is for all the people who can't just install Qwen3.8 27B and call it a day.
Additionally, I am not an LLM benchmarking expert. I am a hobbyist and occasional LLM user trying to extract useful information for both me and people on similar hardware.
Context For the past few weeks I have been doing some benchmarks of some LLMs that can run on my laptop which only has 8GB VRAM and 16GB RAM. I was mostly toying around while trying to get some useful data about what the best model is for local inference on consumer hardware. This week I decided to make a "final" benchmark that would be way better with more questions, more question categories, newer models (a lot of people complained about the models I had benchmarked before being old but I didn't find most suggested models to be any good) and a better speed benchmark, this time using TTC (Time To Completion) as a pose to
Hey Folks,
I've been making quants for a while - recently I took a short break to get into hardcore research (submitted my first EMNLP paper during it!). Along the way, I built up a little arsenal of quant-optim techniques: everything from novel, paper-pending tricks to some genuinely sick tensor-mapping algos.
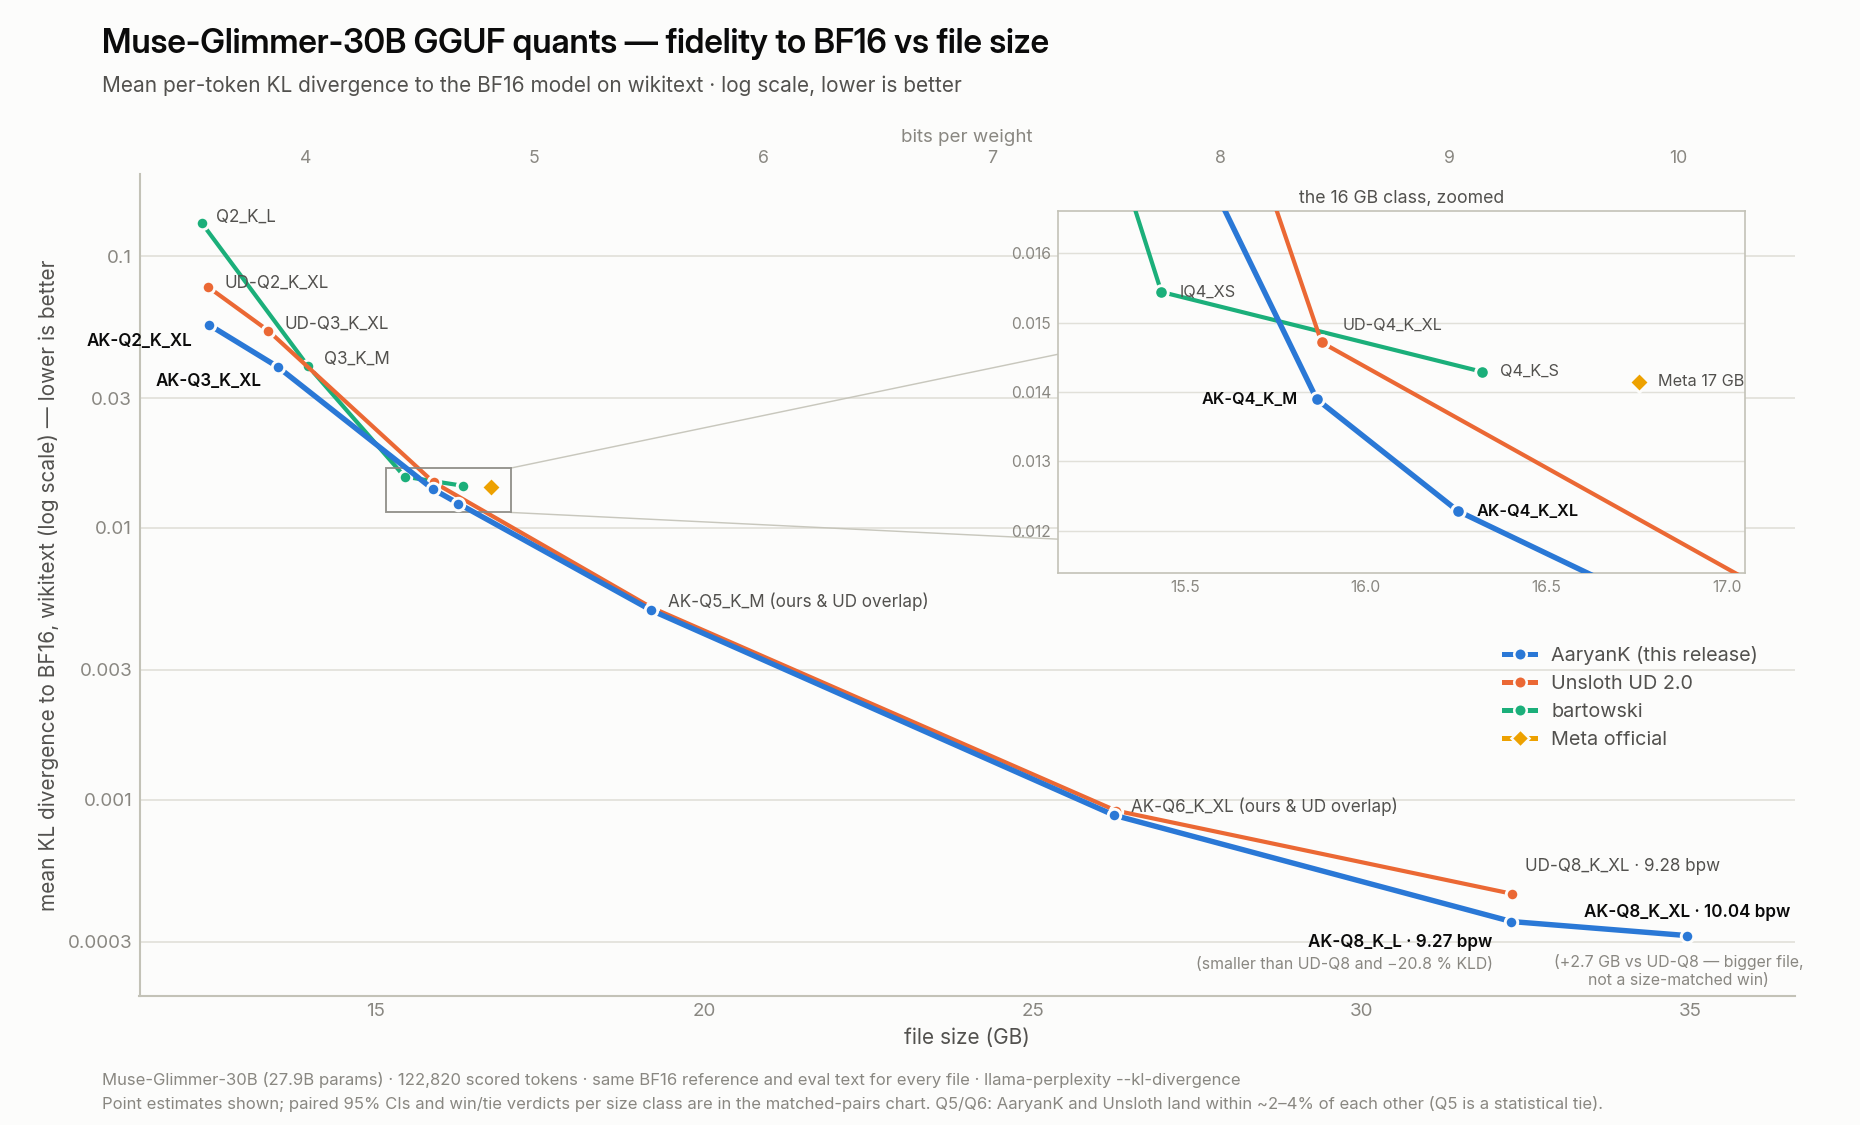
I threw some of the secret sauce into the newly released Muse Glimmer 30B (META IS BACK!) and compared it to several OGs. I'm honestly shocked by how it never loses to any quant out there in every single VRAM class!
One of the coolest ones is my Q8 quant, it is smaller than UD-Q8_K_XL and 21% closer to BF16.
Full methodology is on the card - eval setup, CIs, held-out slices, the lot. Happy to answer questions in the comments.
Model: https://huggingface.co/AaryanK/Muse-Glimmer-30B-GGUF
I still had headroom left but ran out of compute credits :( Being a solo undergrad sophomore, I can't exactly spend H100 money that often, which is why the "hopefully" in the title :)
I'm looking for internships in AI agent orchestration and model inference. If this work looks relevant to your team: linkedin.com/in/theaaryankapoor
I plan on doing a write-up soon to describe some of the
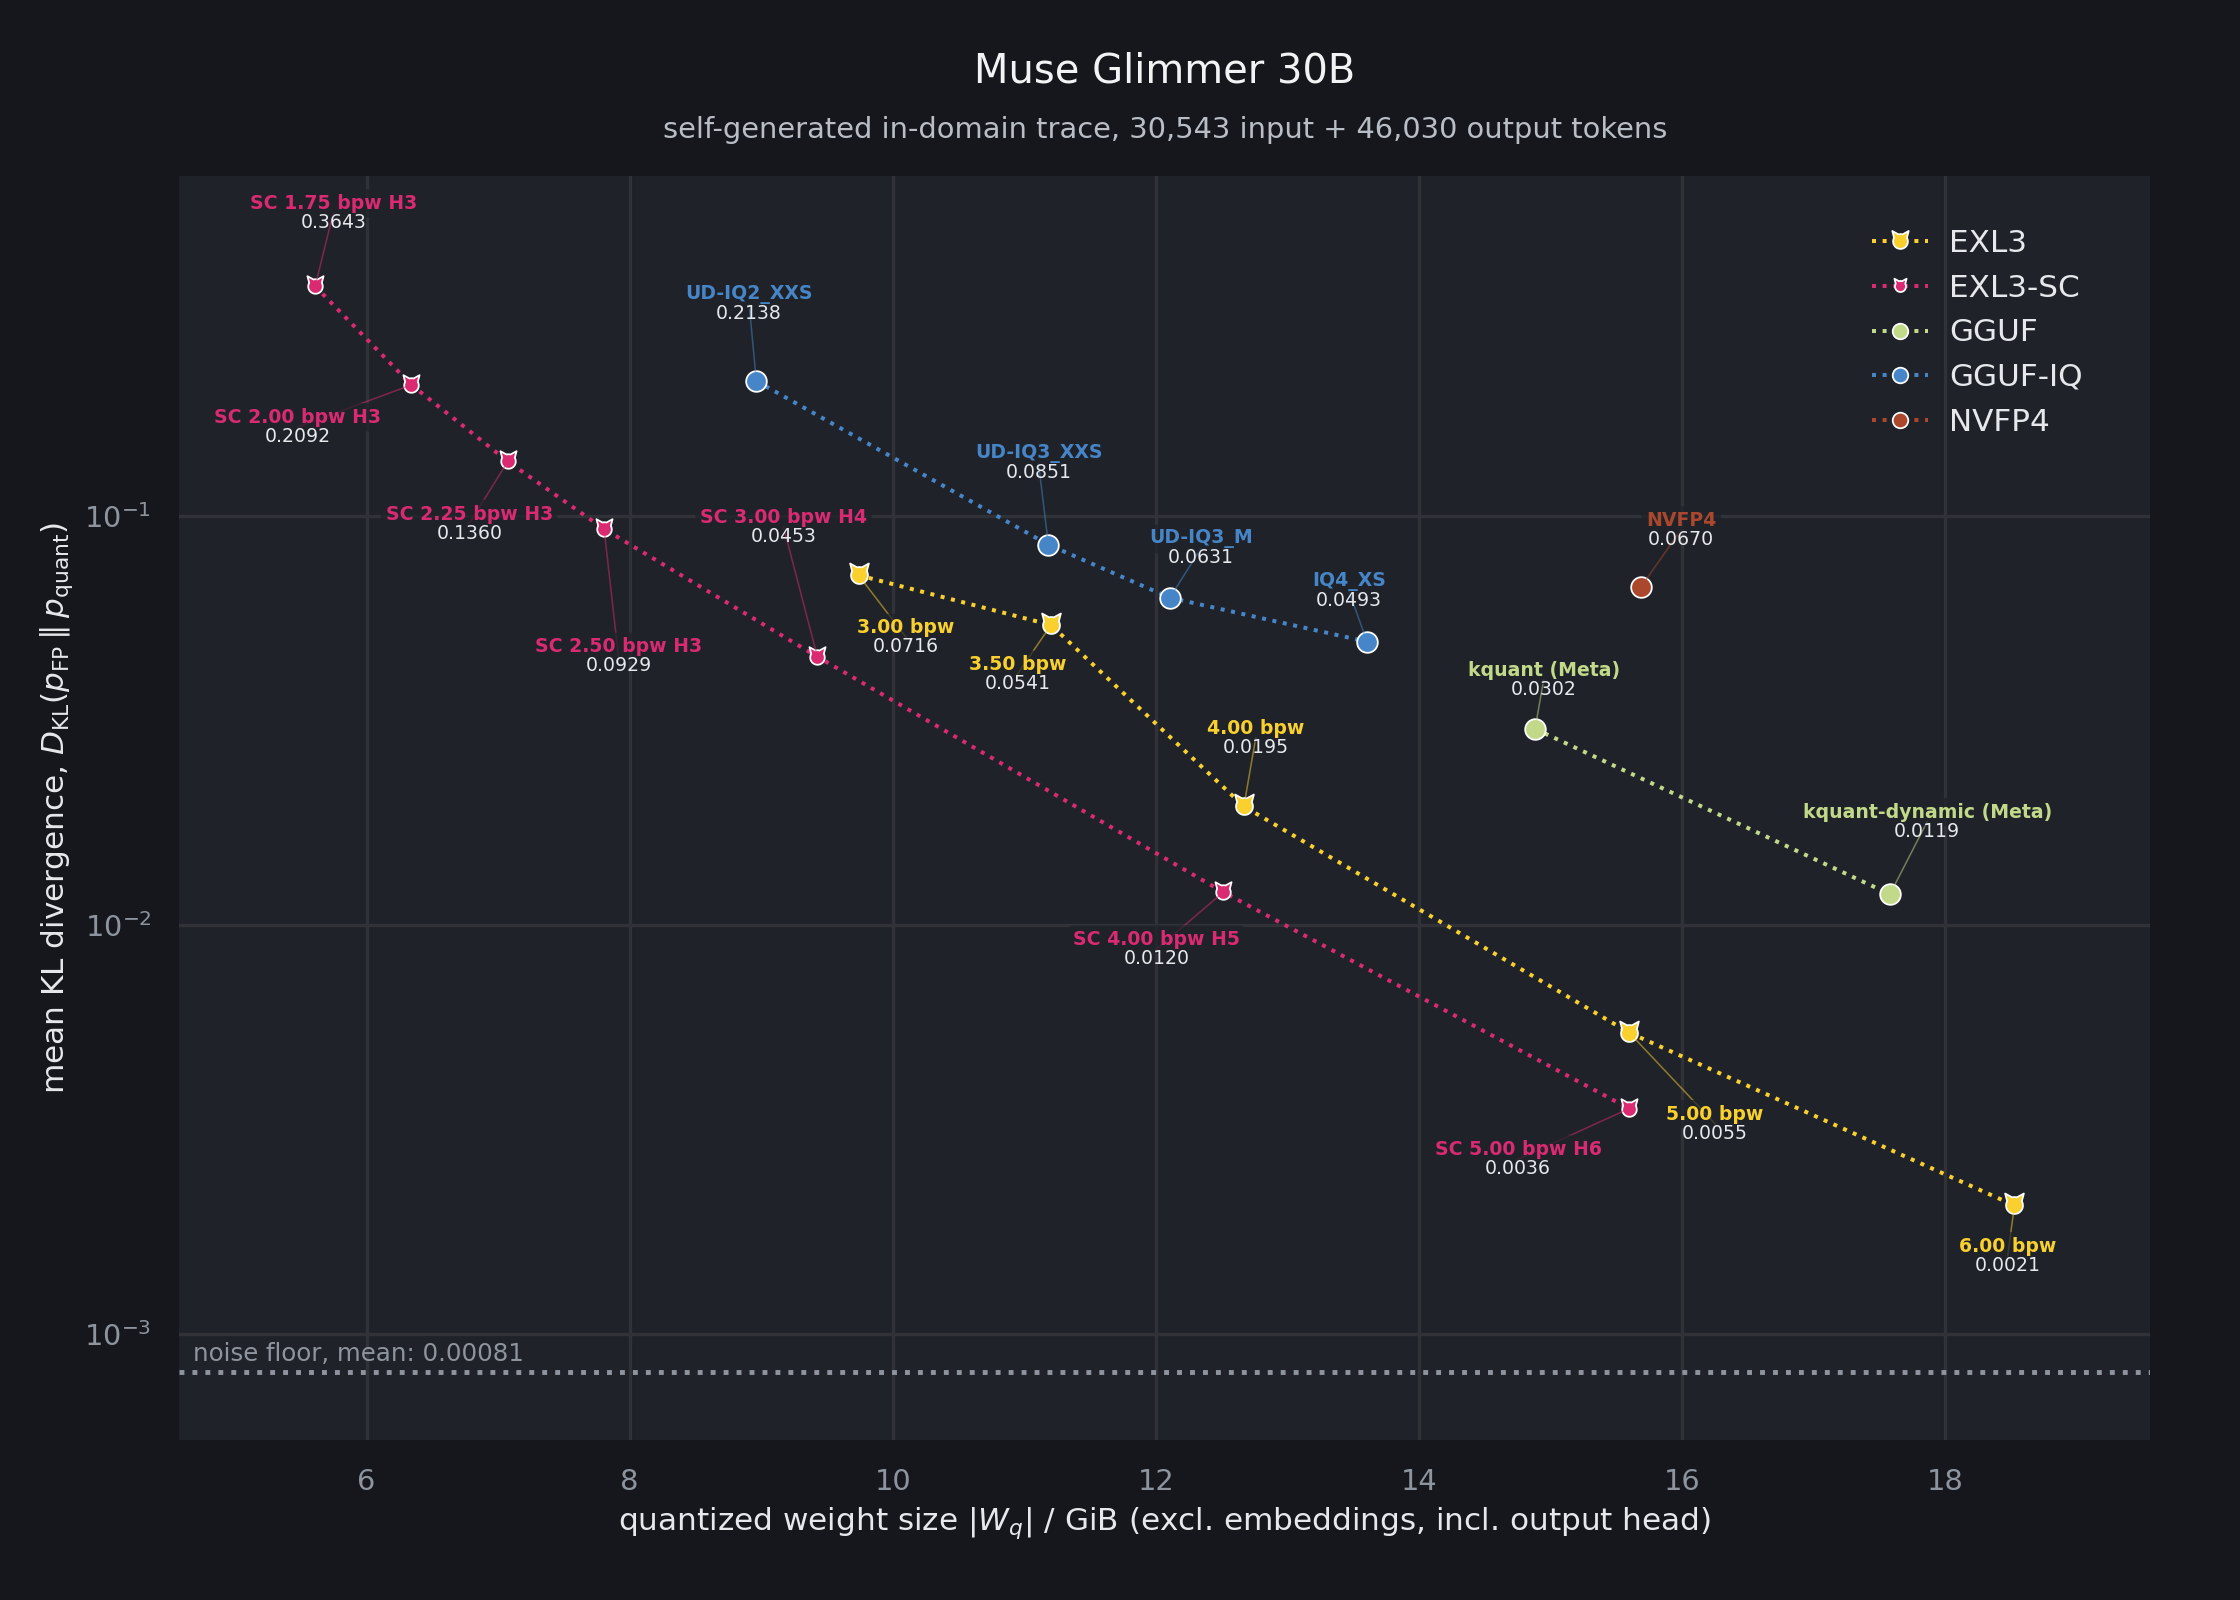
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop.
It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster.
I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.
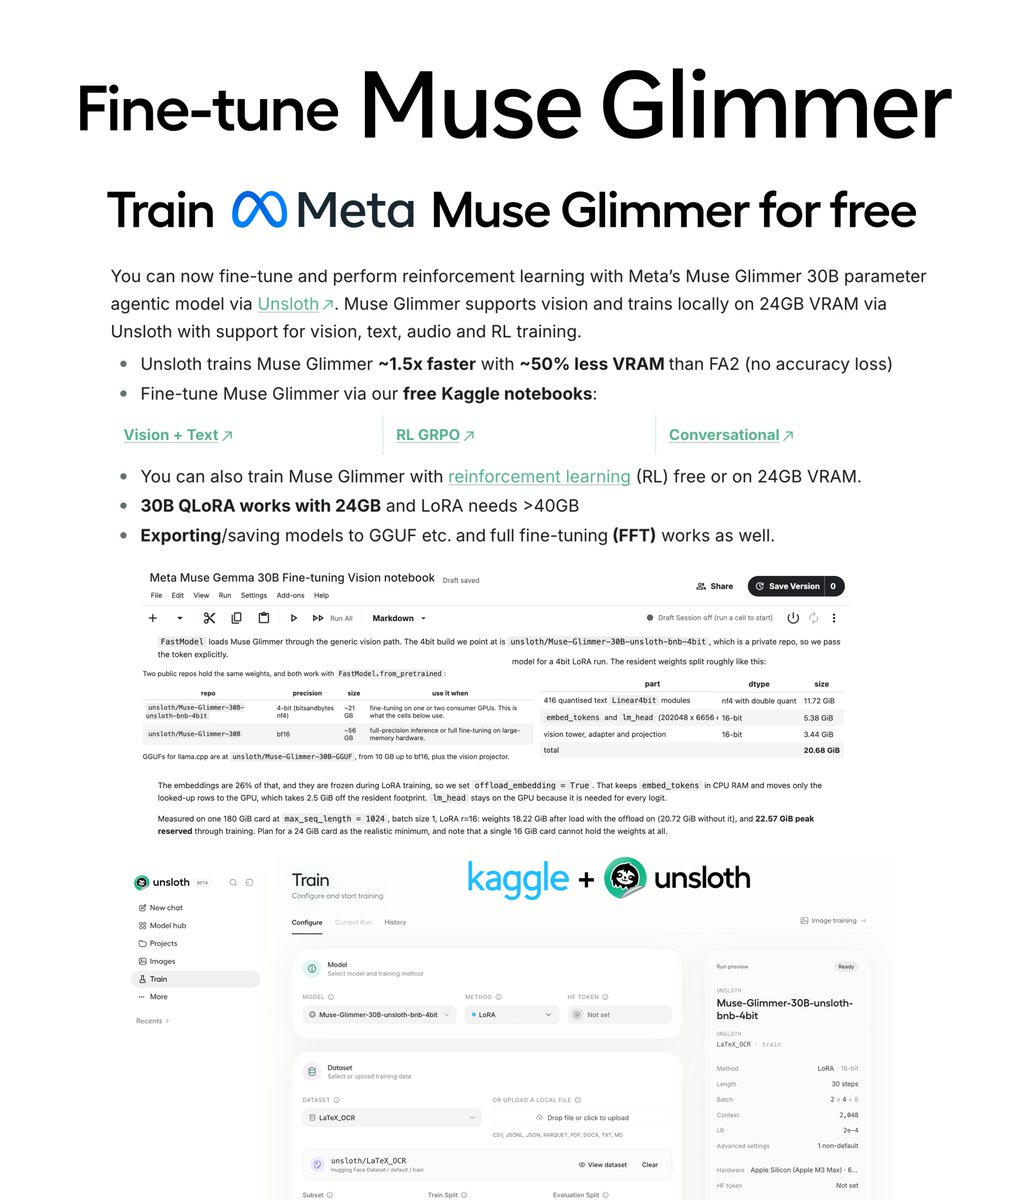
You can now fine-tune Meta Muse Glimmer 30B for free! 🔥
Our free notebook also supports GRPO RL training.
Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM.
Guide: unsloth.ai/docs/models/mu…
Notebooks: unsloth.ai/docs/models/mu…
Muse Glimmer, A 30B parameter dense model swallowing a 130,000 token context window using only 19.3 GB of VRAM (extreme efficiency). No KV cache quantization required.
I just benched the new Muse Glimmer 30B (dense) on a single RTX 4090. We are pulling 3,100+ t/s prefill and 75
NetworkCoder runs Muse Glimmer 30B on an RTX 3090, measures speed and VRAM, and gives two agent harnesses the same model, endpoint, project and prompt to compare results.
The "I don't have enough VRAM" excuse just died. I’m running Meta’s new 30B Muse Glimmer Q6_K_XL with a massive 130k context window on just 26GB VRAM FREE compute on Kaggle.
Kaggle provides you free 2x Nvidia T4 GPUs. 30 hours usage each week!
Yesterday, I showed you the
A four-in-line game built with the AIIA framework, where the plan came from the author's own model and the build then switched to Muse Glimmer running on 16 GB of VRAM.
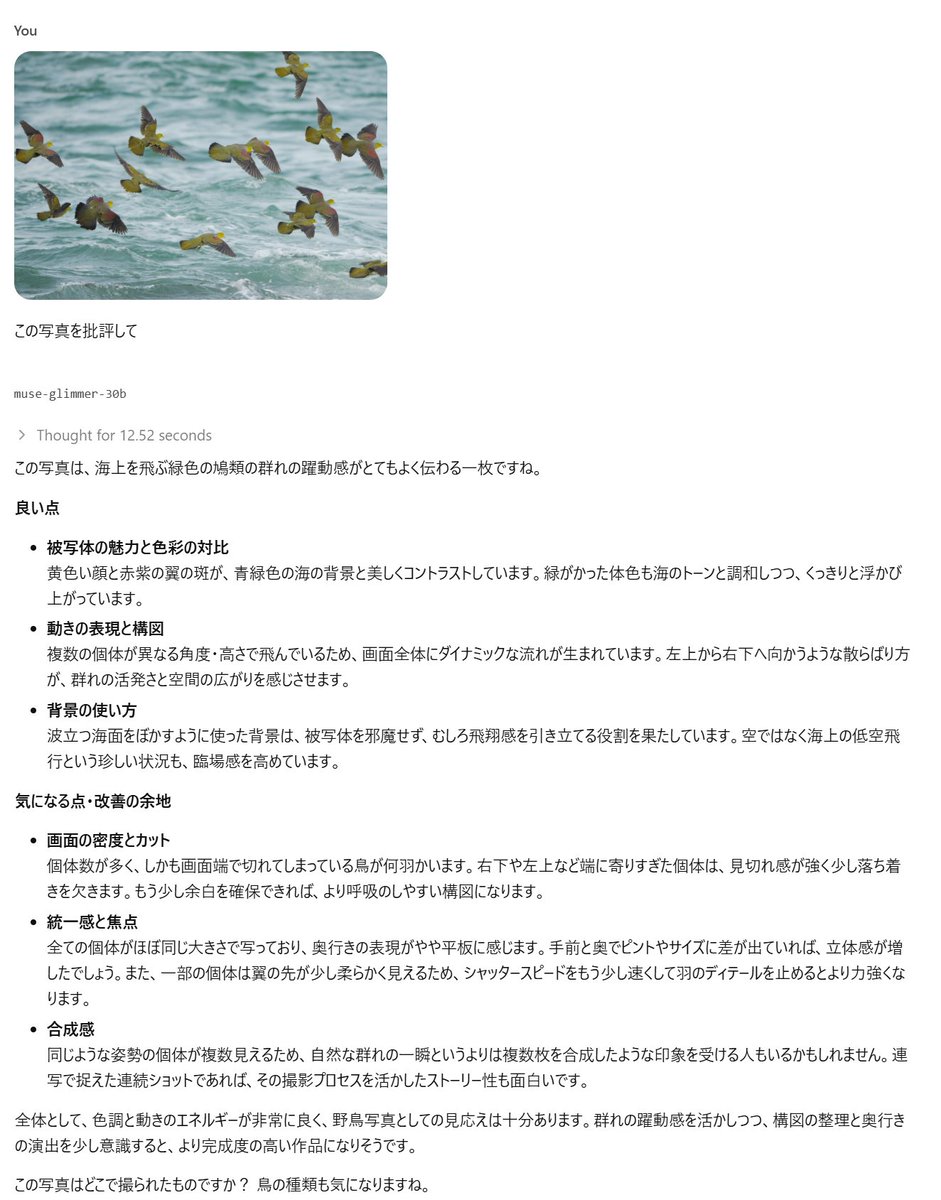
An experiment running Muse Glimmer 30B Q4_K_M via llama.cpp on an RTX 4060 laptop with 8 GB VRAM, testing autonomous Python bug fixing, tool-failure recovery and multimodal invoice extraction.