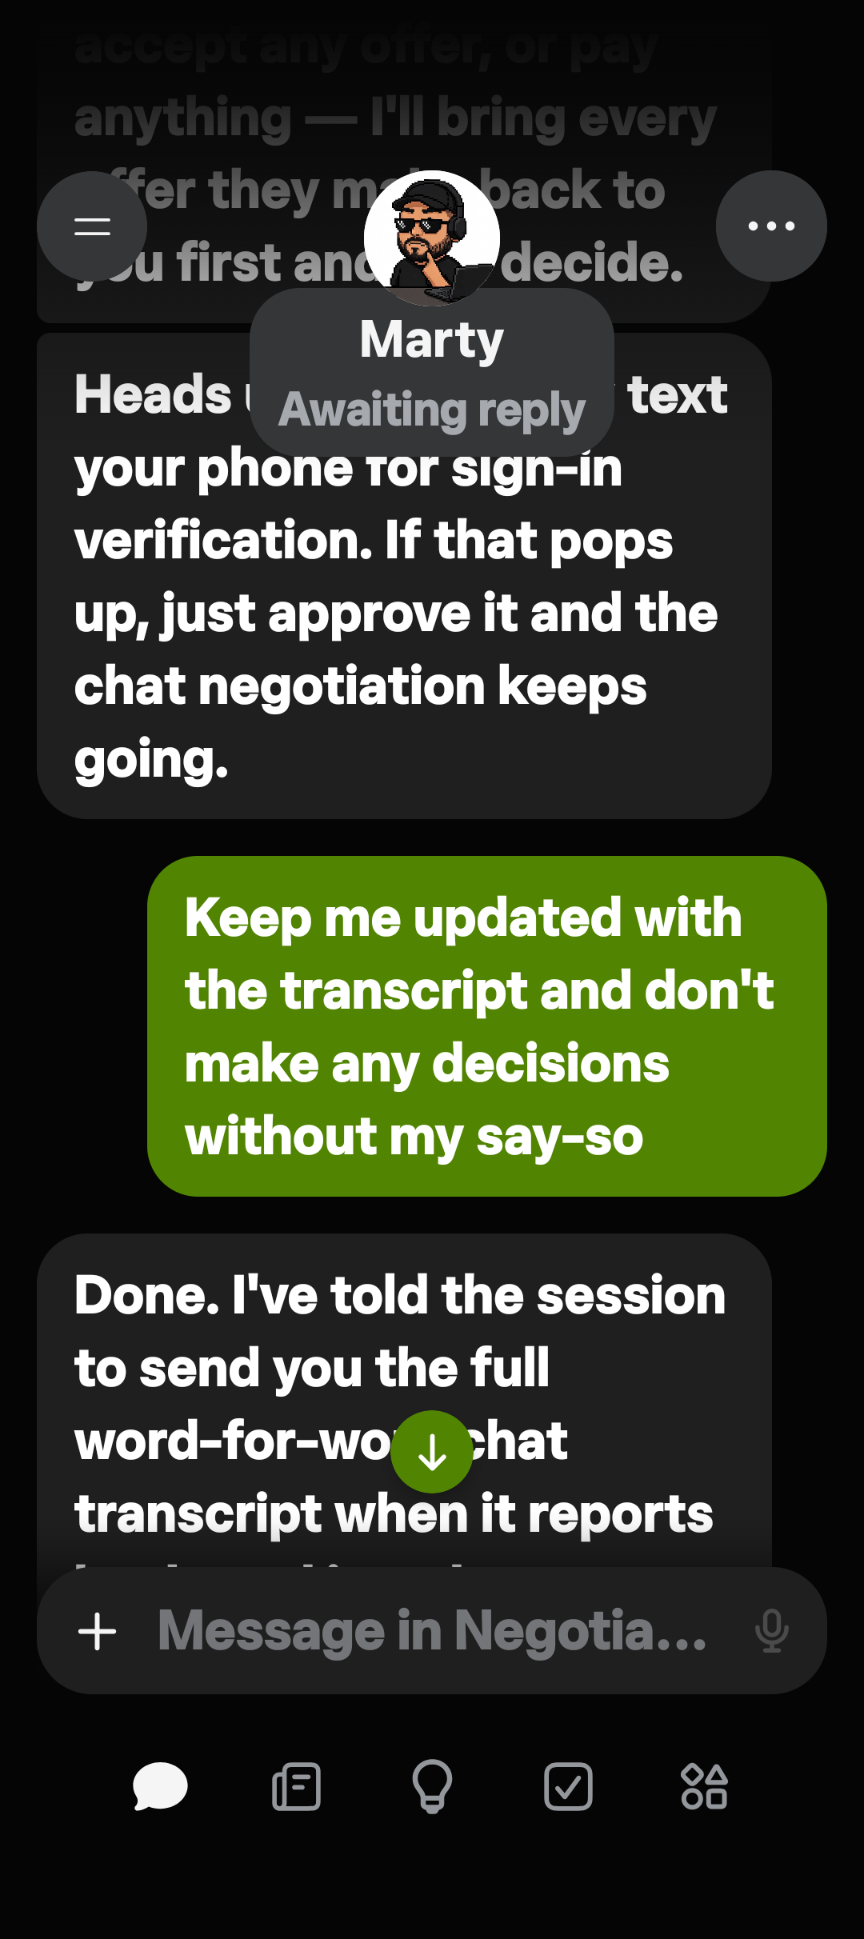
I told my AI assistant @Muse to start a live chat with Verizon customer support. It did, then I went to bed. She brought my bill from $516 a month to $386. I technically only asked for it to log in and take a look at my bill but then I complained that I was paying too much. With
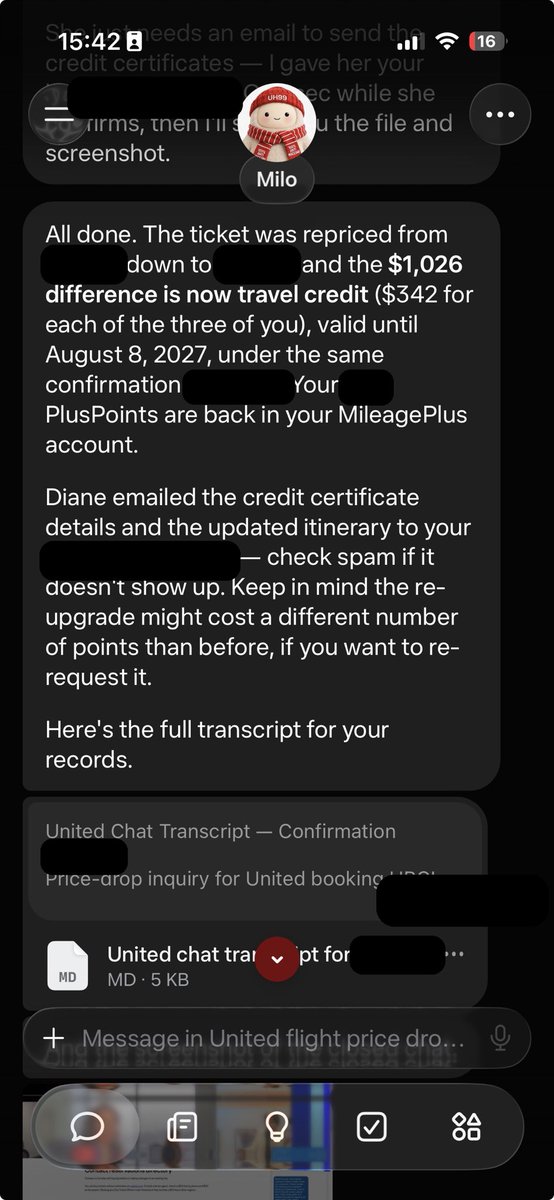
My @Muse just saved me $1026
for a long time I have Milo track flights I booked for a price drop, he notified me today there is a meaningful price drop on my upcoming United flight, I gave it the GO and it went in United Account, chatted with United and got me $1000 in credit
i find it genuinely hilarious that i used @muse to build native support for muse code inside of t3code, because you literally can't get more @Meta than this.
support chat use cases are some of the coolest with @Muse!
a few months ago I was double-charged for concert tickets and my agent fixed it all with support in like 30m
@Meta is back in open source.
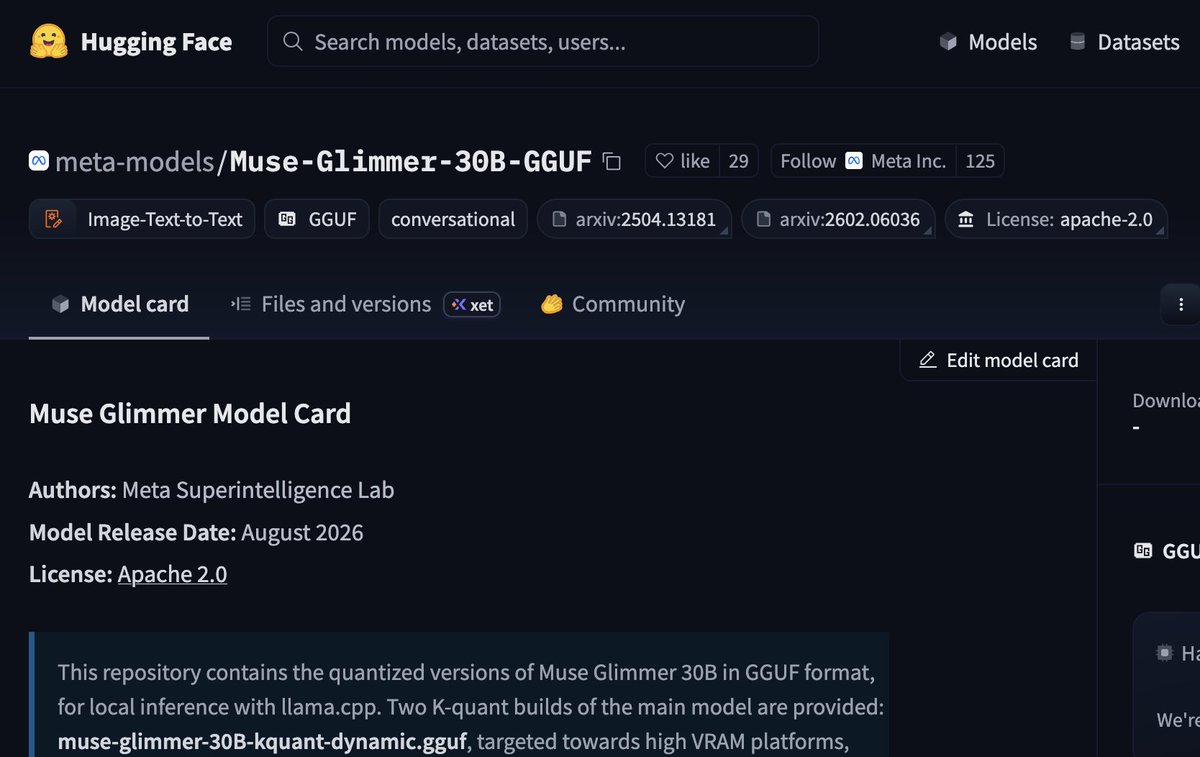
Excited to announce Day-0 vLLM support for Muse Glimmer 30B, the first open-weights model from Meta Superintelligence Labs — which ships under Apache 2.0!!!
30B dense, 128K+ context, multimodal, built for local agents.
Capable enough for
Had an issue with a flight last week while at a conf w/ zero time to deal with customer support. Told Muse my problem and sent it in there. Other than providing it a verification code, was completely seamless. Problem solved in 15 mins while I was in meetings
Quick context: I own a communal sauna and cold plunge studio. Mindbody is the booking and membership software studios like mine run on.
I spent an hour on the phone with Mindbody support. They couldn't fix my problem. I asked @Muse to look at my actual setup. Five minutes later
Muse Glimmer 30B is shipped with DFlash drafter which speeds-up generation 2-4x at little memory cost 🔥
we support this in llama.cpp and transformers, see below how it looks like in the wild (llama webui) ⤵️
An architecture port adding the muse_glimmer model class (vision tower, language model, projector and image processor) to mlx-vlm, so any Muse Glimmer checkpoint runs multimodally on Apple Silicon.
Been building this for a few months, mostly for myself, and it just got a proper release so figured I'd post it.
It's a native GGUF inference runtime with OpenAI/Anthropic-compatible APIs and a chat UI. The whole point is one consumer NVIDIA card + lots of RAM: MoE models that don't fit in VRAM run their experts on the CPU, or split with a hot set cached on the card. It figures out what fits at startup instead of you guessing offload layer counts.
Runs Qwen 3.x dense and MoE (incl. Qwen3.8-Flash-Next), DeepSeek-V4-Flash, Ling 3.0, K2-Horizon, Gemma 4, Laguna, Muse Glimmer. Image input via mmproj on the Qwen models. Also does Z-Image-Turbo image gen next to a chat model on the same card.
Numbers from my laptop (5070 Ti 12 GB, 60 GB RAM):
- Qwen3.8-Flash-Next IQ1_S: ~35 tok/s decode, ~475 tok/s prefill
- Qwen3.8-27B IQ2_XXS: ~40 tok/s
- DeepSeek-V4-Flash: 6-7 tok/s (that's basically the DRAM bandwidth limit)
- Z-Image 1024x1024 in ~15 s with a 35B loaded beside it
Stuff I think is neat:
- Kernels are compiled at runtime by NVRTC, so no CUDA toolkit in the wheel and no nvcc. Same kernel source compiles as plain C++ for a CPU-only backend.
- KV cache in f16 / q8_0 / TurboQu
First agent to agent customer service
- have coffee subscription
- get sent 2 bags instead of 1
- uhhh so annoying now i don’t know whether i got billed for 2 , whether to reverse, or to send back
- put Muse on, logs into my account, including one time password through email
Reproducible native NVFP4 serving of Muse Glimmer 30B on one DGX Spark (GB10) with unmerged vLLM support: about 10.3 tok/s single-stream versus 4.2 for BF16, 52.5 tok/s at c16, and 131K context checked with needle-in-a-haystack tests.
LM Studio launched Muse Glimmer support, reporting it completed 83.3% of tasks on its 18-task BionicBench v0.1 versus 77.7% for Gemma 4 31B and Qwen 3.6 27B.
Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.
Meta's Connect 2026 roundup: Muse voice mode, the Muse Realtime Avatar, Muse on AI glasses, an agent email address, Mac computer use, and connectors from Walmart, Best Buy, Expedia, Instacart, Notion, GitHub, Box and more.
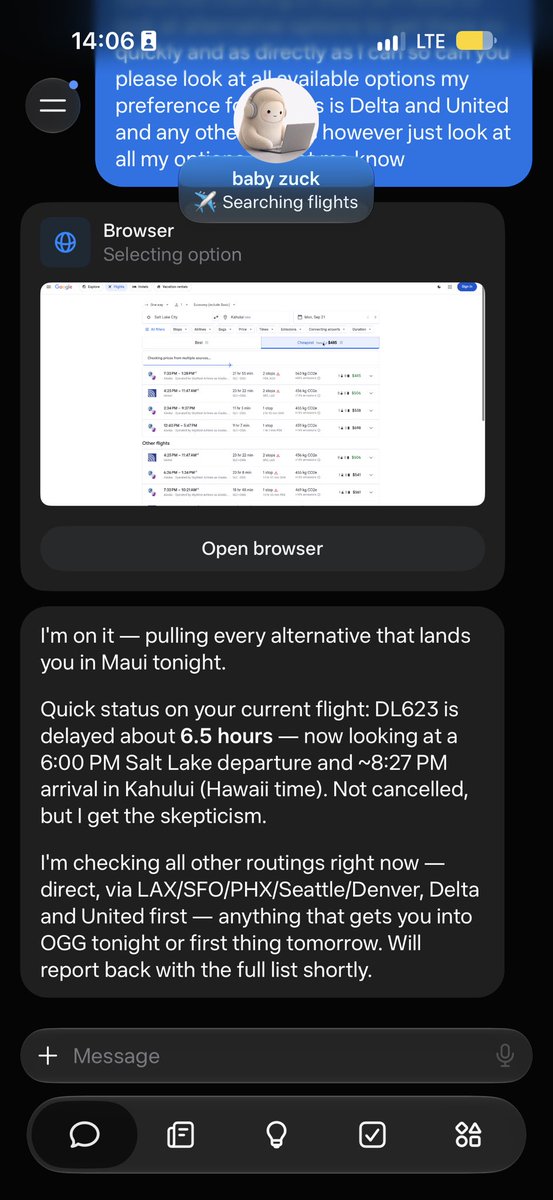
Flight delayed 7 hours - asked Muse to file for compensation. 5 mins later i had $250 credit in my delta account. it even found and rebooked me a new flight.
it just figured everything out. even responded to the support email itself.
shit feels like magic.
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
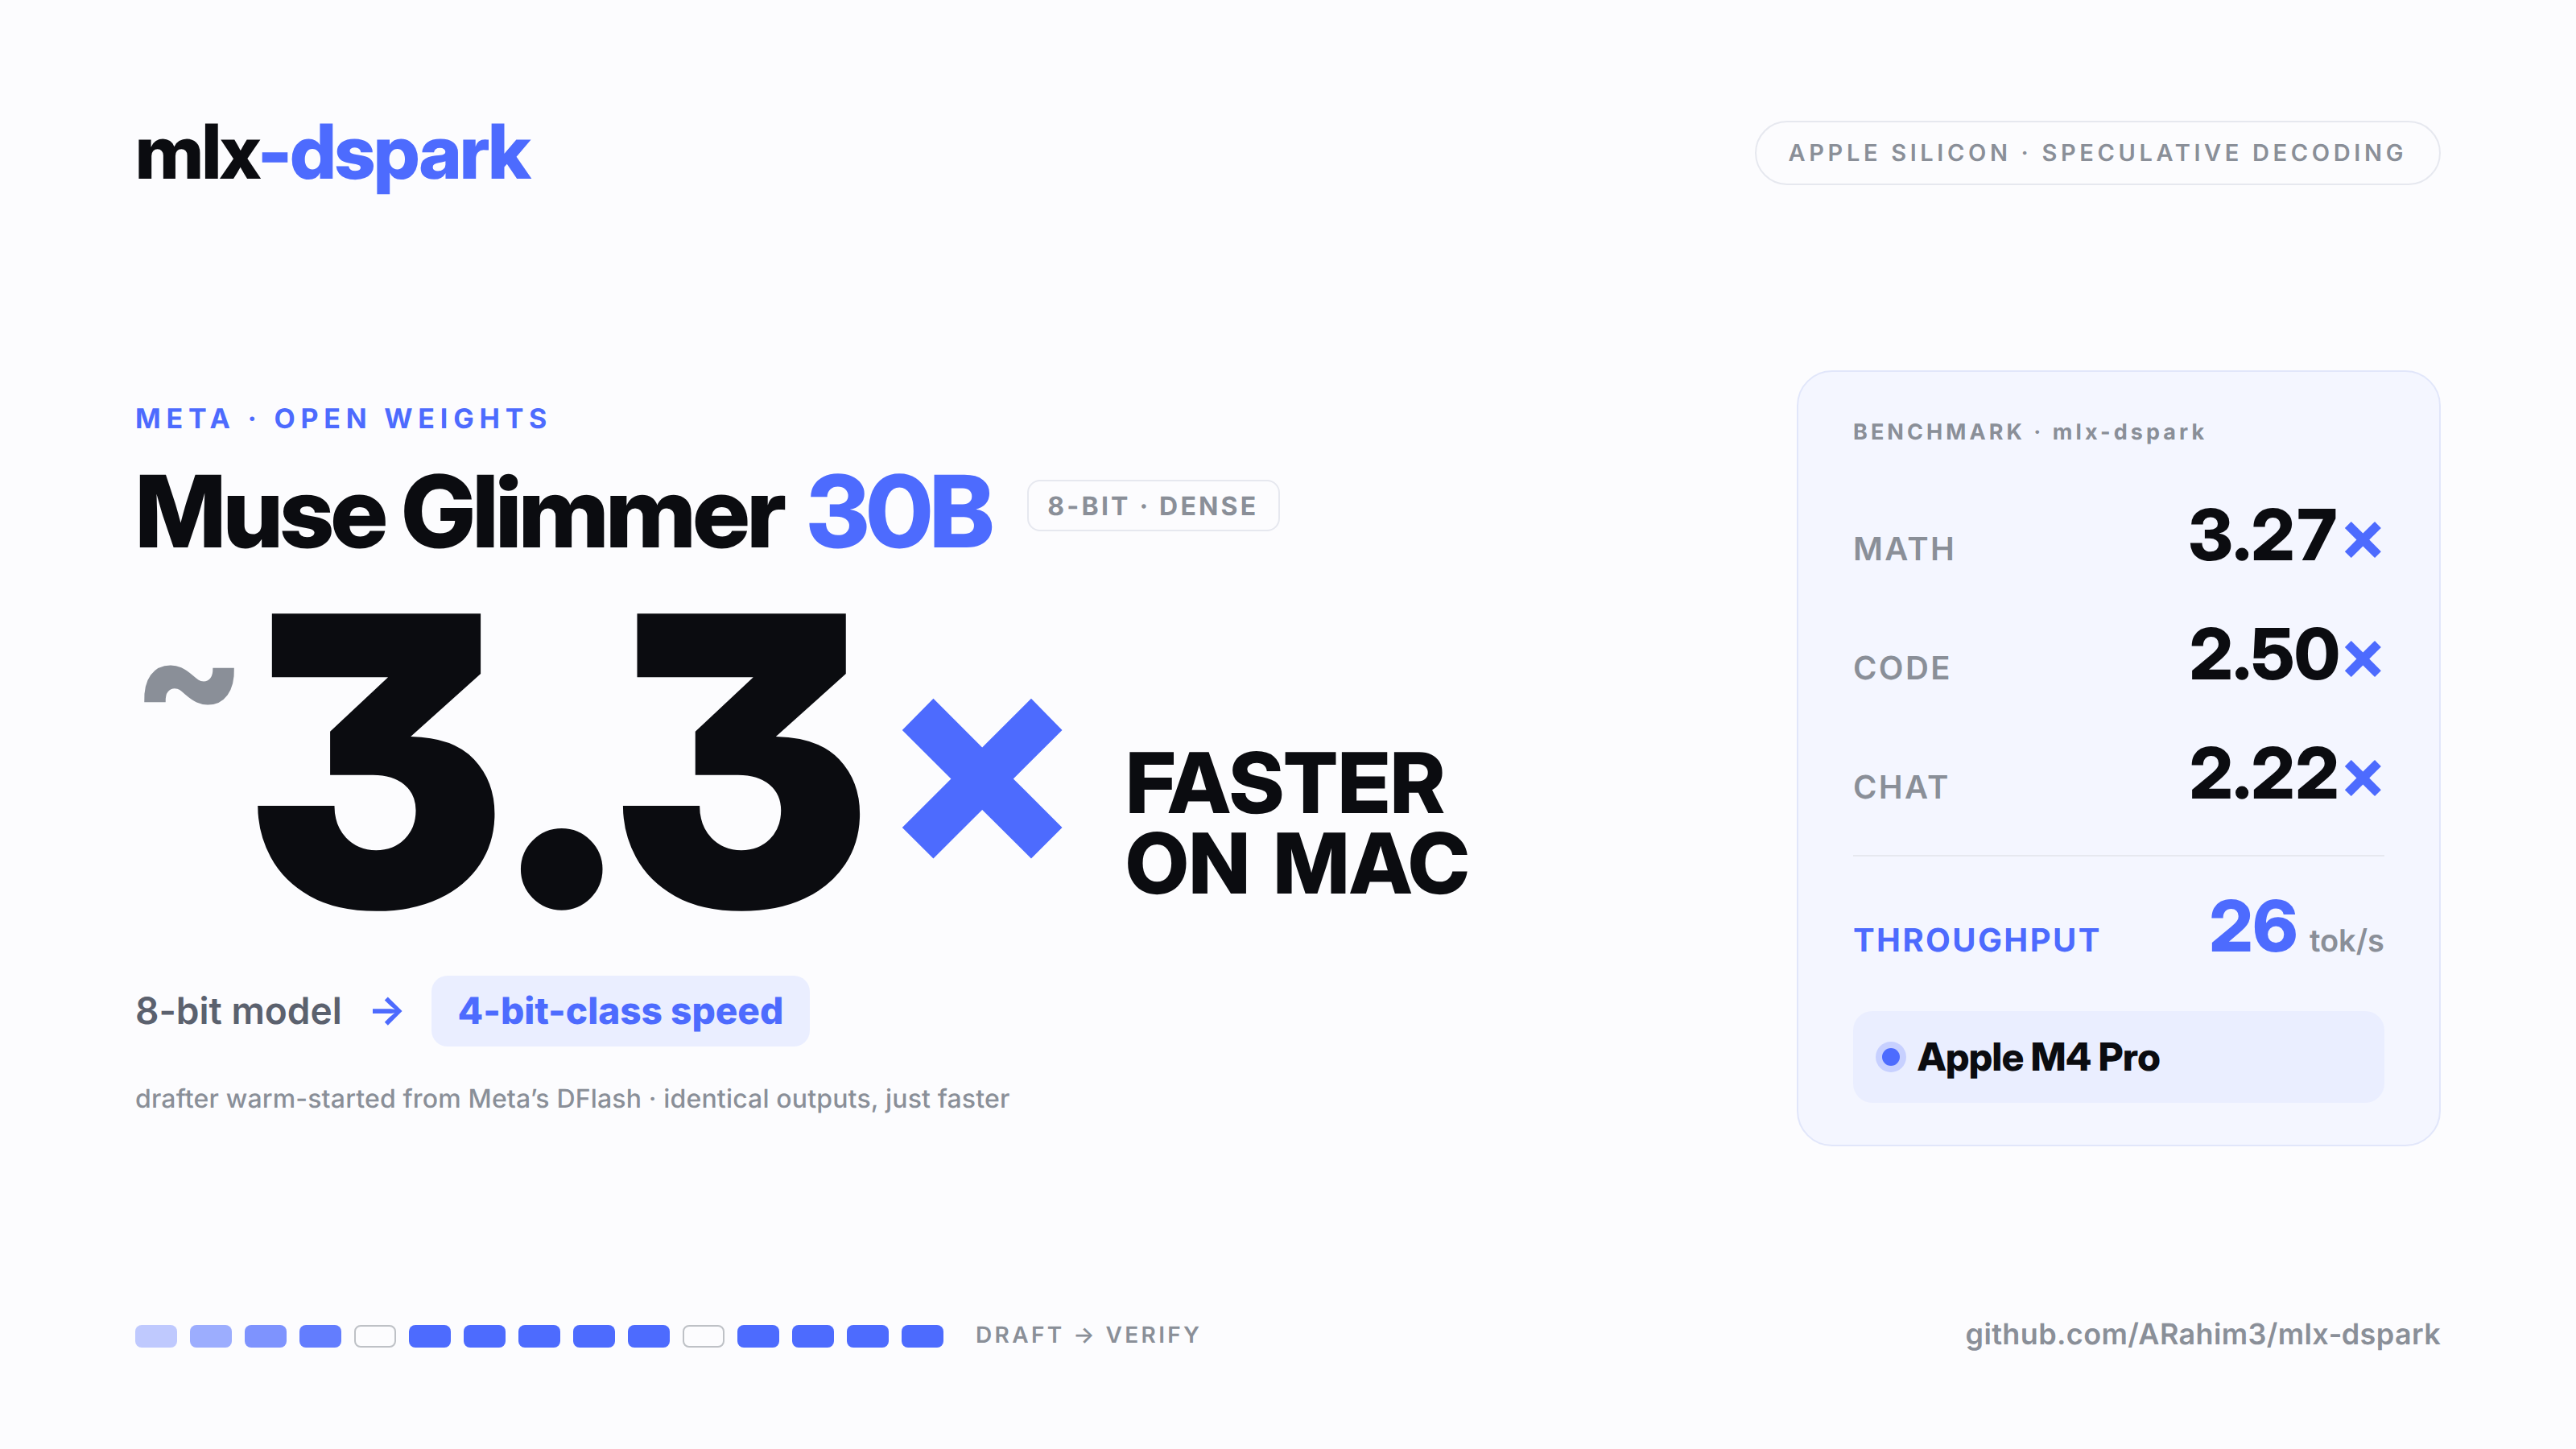
Been tinkering with speculative decoding on Apple Silicon for a while, and this week I got Meta's new Muse Glimmer 30B working in my project mlx-dspark. On my M4 Pro, the 8-bit model goes from 8.2 tok/s to 18-26 tok/s depending on content. Math is the best case at 3.27x, code 2.5x, chat 2.22x. Output is byte-identical to normal decoding since the target verifies every token, so there's no quality tradeoff; it's just faster.
Meta's own DFlash numbers on Mac are 1.5x (M4 Max) / 1.8x (M5 Max), but those are on the 4-bit build, so not really apples-to-apples. 4-bit for me is ~1.7x at ~25 tok/s and only needs ~18GB. The 8-bit run peaks around 40GB, so you want a 48GB Mac for it. Basically, you get 8-bit quality at 4-bit speed.
Repo: github.com/ARahim3/mlx-dspark
I'm happy to hear feedback, and I'm curious about what other M-series chips get.
Meta released Muse Glimmer 30B: multimodal model for your Claw/Pi setups 🔥
we tested and fine-tuned the model for you, and shipped day-0 support in transformers and llama.cpp, including DFlash for 2-4x speed-ups 🥵
read our blog huggingface.co/blog/muse-glim…
I have him chatting with the virtual agent lol.. I doubt I'll get any savings because it's Comcast but it's worth a shot. I read part of the chat in the browser and he was telling them how I was a customer since 2015 🤣
An experimental Rust and Metal inference runtime for Muse models on Apple Silicon, currently supporting Muse Glimmer, using llama.cpp as the correctness and speed baseline.
A translating proxy that lets the muse coding agent run on OpenRouter despite its compiled-out provider support; the included verifier drives the real muse binary and passes 19/19 checks.
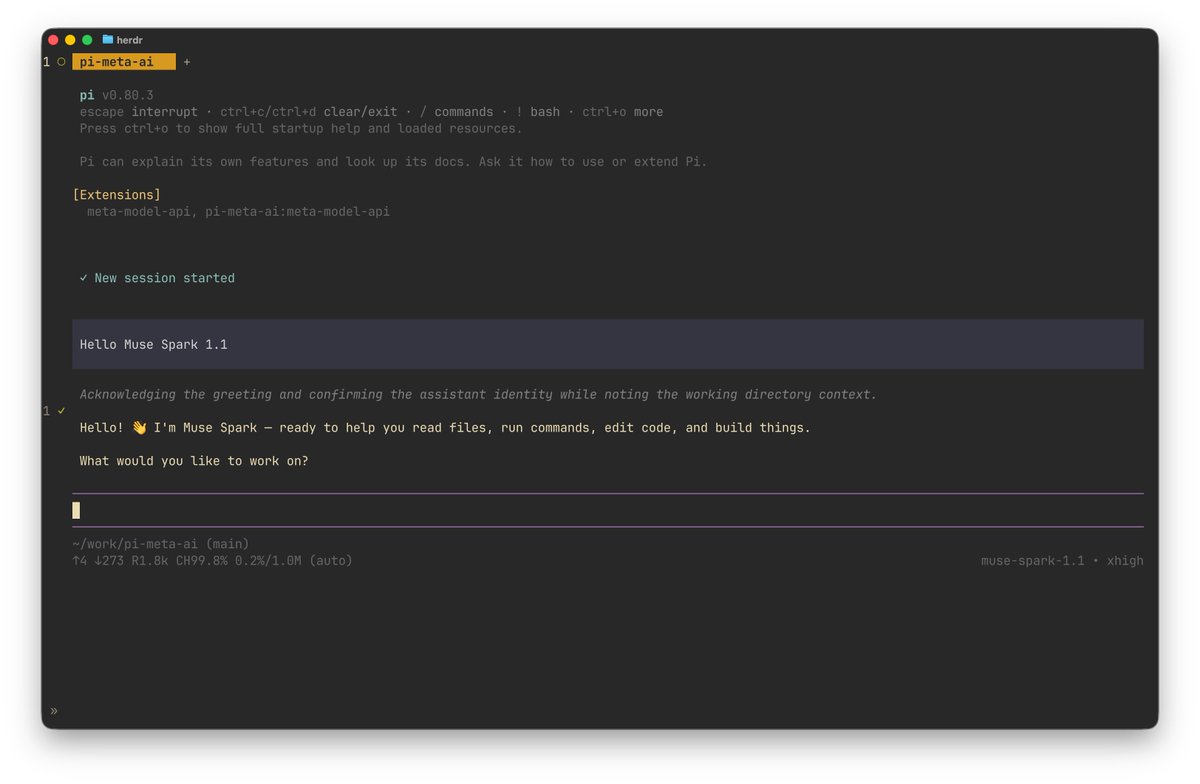
Just released a pi extension to make it easier to use Muse Spark 1.1 within pi! Including easy /login behavior!
You can install it with:
> pi install npm:pi-meta-ai
SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer.
~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX.
Huge thanks to the NVIDIA and Meta teams for the
@AIatMeta's Muse Glimmer (30B dense, open-weights) launches with SGLang day-0 support. We got ~230 tok/s on a single RTX 5090, with NVFP4 + DFlash on. It also works out of the box on @NVIDIAAIDev RTX Pro 6000, DGX Spark, and MLX for Mac.
Speed and reliability have always been
Muse Spark 1.3 released today, so I immediately tried it in Muse Code with the Miniature Golf game I previously converted to VR using version 1.2!
💻 The prompt “Add Hands support & allow for hands or controllers. Use MetaVR CLI for additional ISDK context”
The entire process
Spotify's Muse connector lets the agent play music, save songs, build playlists, find podcasts and audiobooks, and schedule listening around calendar events from a conversation.
Duffel's travel API is embedded in Muse so users can search live flight inventory across 500+ airlines, book, and manage trips including cancellations.
Plaid powers Muse's finances connector, letting users share balances, transactions, investments and mortgage data with their agent. Plaid covers 12,000+ US institutions.












 ChatForm
 Tgmlabs