Meta's Mac app lets Muse work with local files, Messages, Notes, Reminders, Mail and Calendar, with per-app Off / Read only / Read and interact controls.
Site · Errands & personal agent
Meta's Mac app lets Muse work with local files, Messages, Notes, Reminders, Mail and Calendar, with per-app Off / Read only / Read and interact controls.
Site · Errands & personal agent
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Glimmer HD Vision is an OpenAI-compatible proxy that keeps images within Muse Glimmer 30B's 4,096 visual-token limit by sending a 4K image as one overview plus four overlapping detail tiles, with an OCR/layout mode.
GitHub · Local & open models
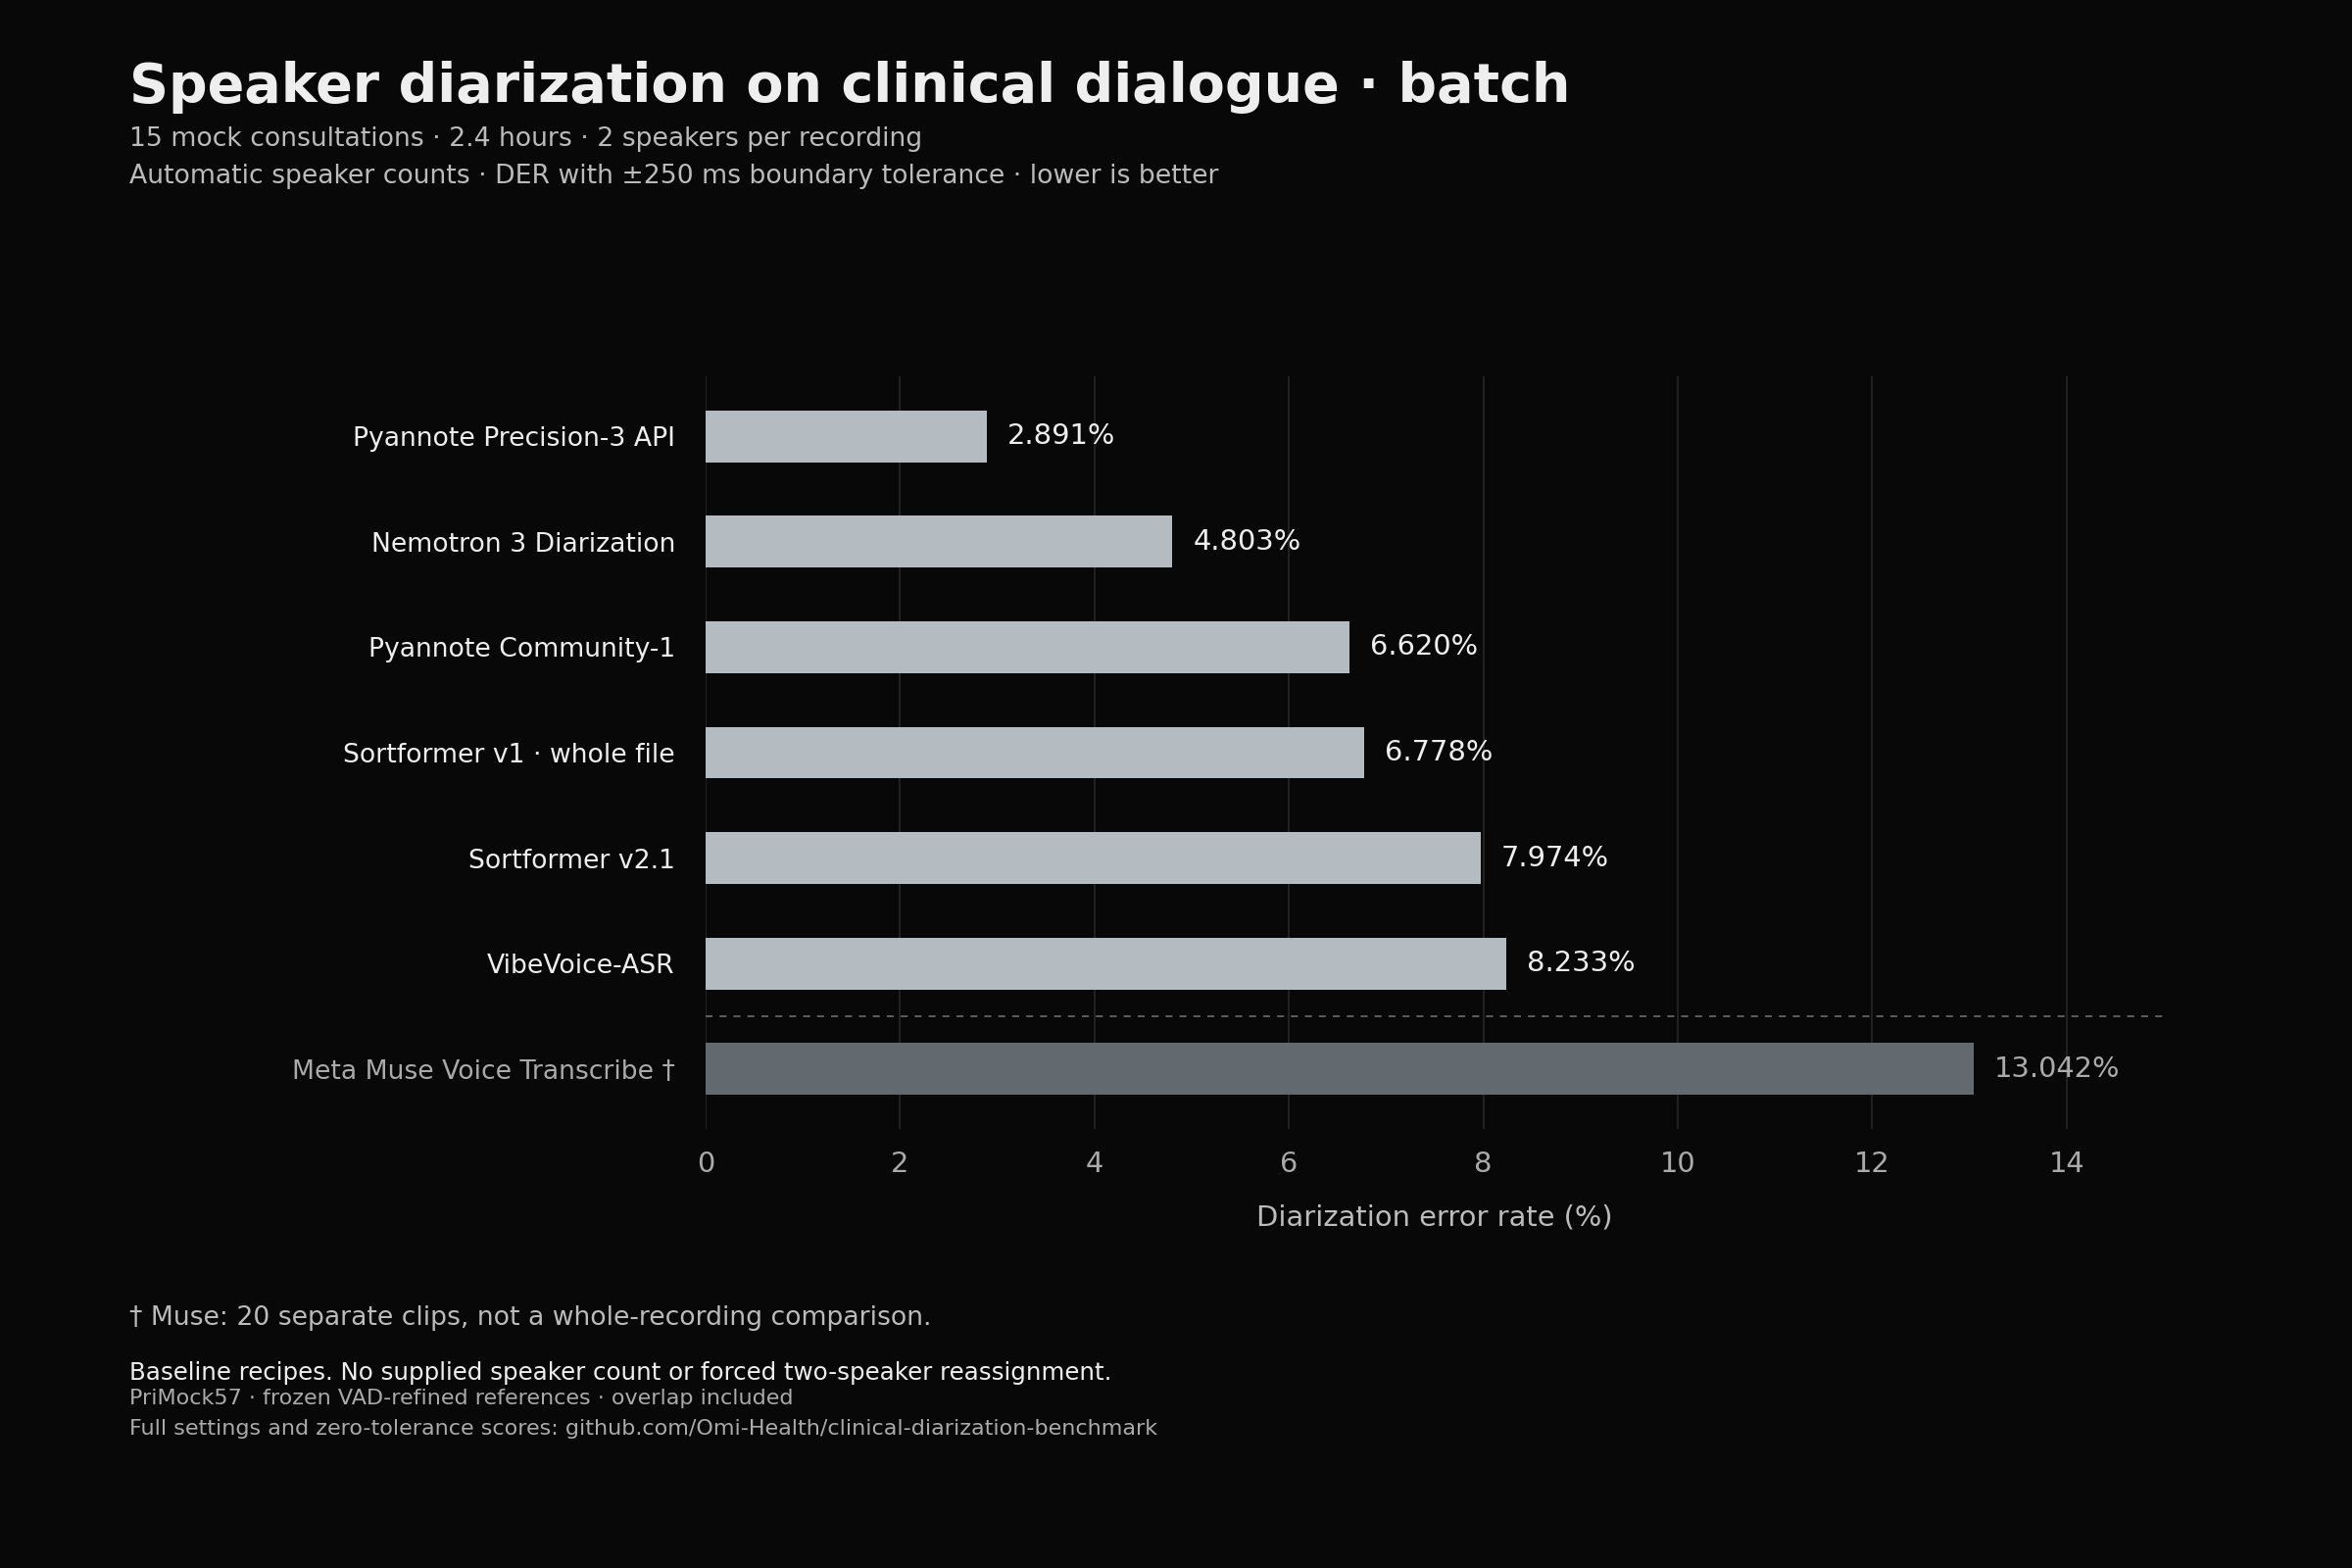
I've been working on clinical speaker attribution at Omi and wanted to compare the current diarization models on the same audio. I used 15 mock doctor–patient consultations from PriMock57, about 2.4 hours. Full recordings, automatic speaker counts, without telling the models there are two people. Batch Diarization error rate (DER), with ±250 ms boundary tolerance. Lower is better. Model DER Median processing time Pyannote Precision-3 2.891% 18.9 s / recording (API) Nemotron 3 4.803% 0.688 s / recording Pyannote Community-1 6.620% 18.691 s / recording Sortformer v1 6.778% 3.869 s / recording Sortformer v2.1 7.974% 1.077 s / recording VibeVoice-ASR 8.233% 123 s / recording Meta Muse Voice Transcribe † 13.042% 92 s / request (API) Local models ran on one NVIDIA L4. API times include round-trip overhead; VibeVoice-ASR also performs transcription. † Muse used 20 separate clips because of its 10-minute request limit, so its result isn't a whole-recording comparison. Pyannote Precision-3 had the lowest error. Nemotron came next and was the fastest local model. Streaming Model DER Pyannote live API 3.959% Nemotron 3 † 4.971% Sortformer v2.1 † 6.958% VibeVo
Reddit post · Benchmarks & research
I'm developing a detailed history book, I'm 333 pages deep, I have used my whole weeks limit and am 8 million deep in my free 1 billion tokens.
Reddit post · Content & creative

Baptiste Dubois
@duboibaptiste
Mine took a cancelled Alaska flight + two Lyft receipts from my email and filed the whole claim: converted email to PDF, fought a broken upload widget (said 2.5MB, real limit 512KB), submitted $189.37 + goodwill. Came back with case number. I just watched. Very smooth, I asked
X post · Errands & personal agent· ♥ 5

Full Value Dan
@fullvaluedan
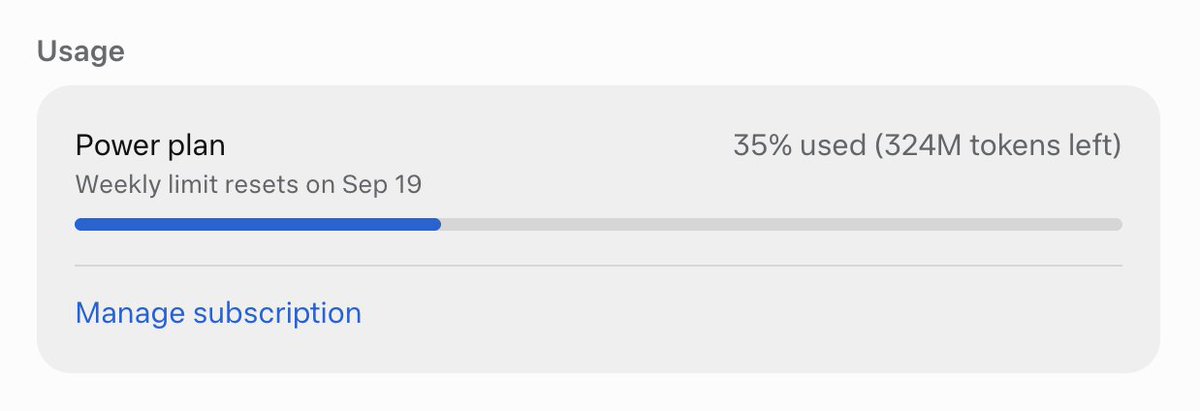
the $16/month @Muse subscription is a media beast there's no 5-hour limit you can generate: - video w/music - voiceovers - infographics - sound effects - edits with @HyperFrames_ I'm nowhere near my weekly limit even after running aggressive quality check loops
X post · Content & creative· ♥ 65
A 4-byte GGUF header edit that raises Muse Glimmer 30B's 131,072 context limit to 262K. The author shows YaRN scaling only adds prefill cost on this architecture, and verified 262K with 8 slots on one RTX 4090.
Resource · Local & open models· ♥ 1
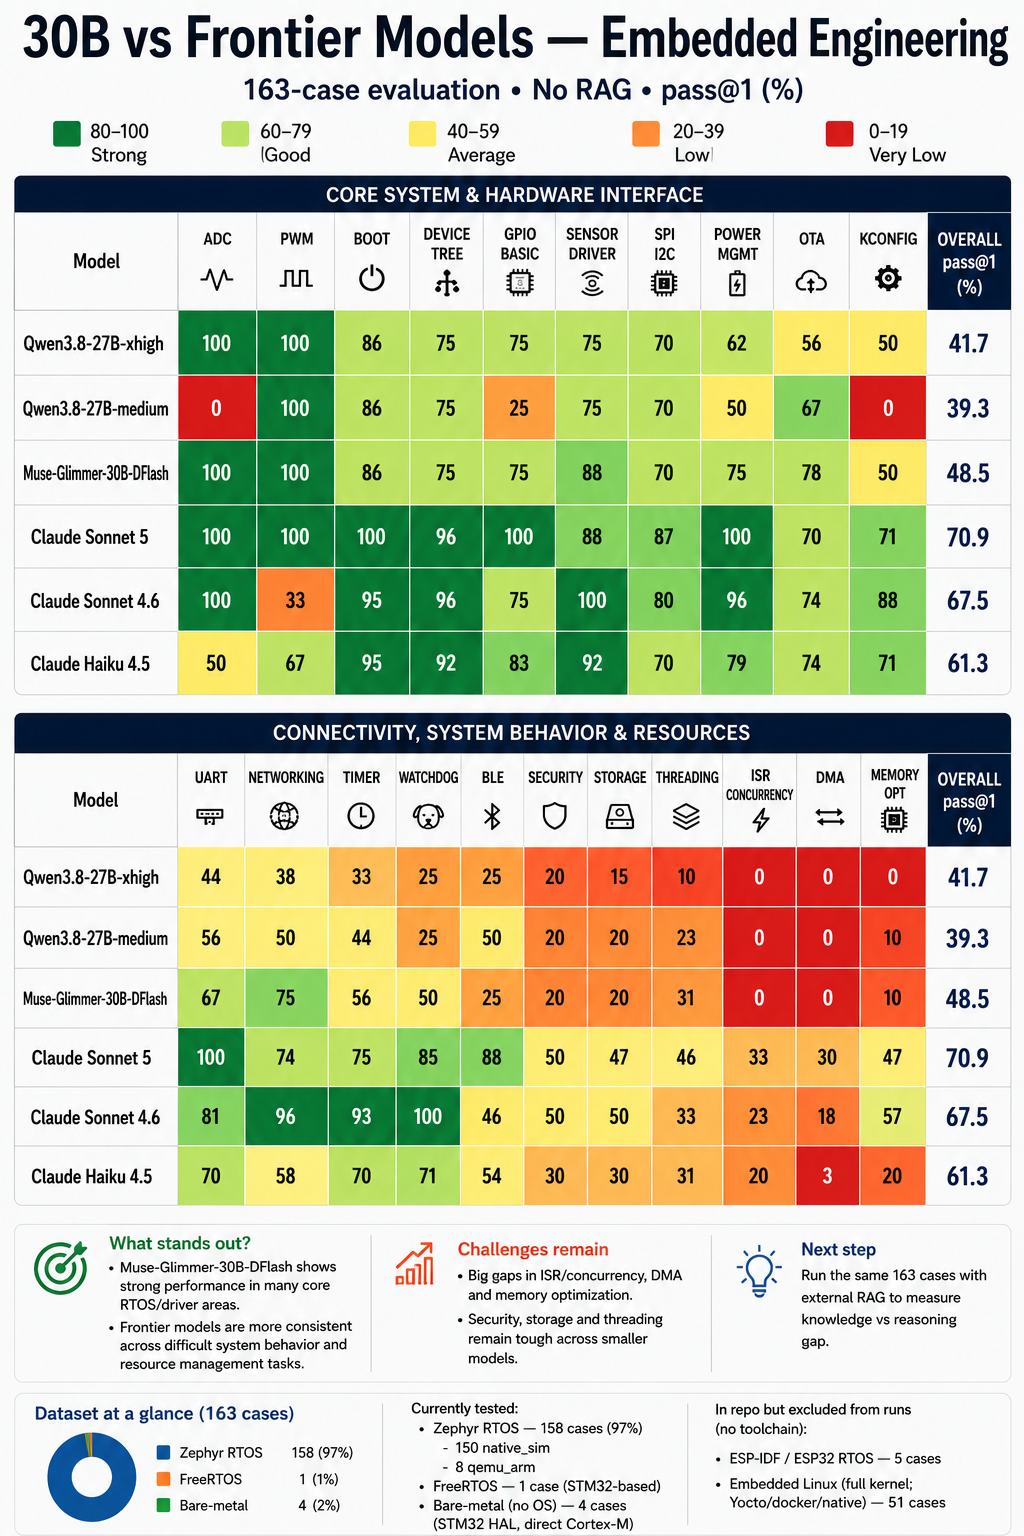
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.
Reddit post · Benchmarks & research
8 builds · page 1 of 1
