Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
15 builds · page 1 of 1
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
A BYOK VS Code extension that registers the InferHub catalog, including Muse Spark with its 1,048,576-token context window, as a model provider in the Copilot Chat picker without Copilot Pro.
GitHub · Coding & dev tools
muser is a standalone inference engine for Muse Glimmer 30B on Apple Silicon Metal, with an optional disaggregated lane where an NVIDIA GB10 node prefills in NVFP4 and hands the KV cache to the Mac.
GitHub · Local & open models
An experimental Rust and Metal inference runtime for Muse models on Apple Silicon, currently supporting Muse Glimmer, using llama.cpp as the correctness and speed baseline.
GitHub · Local & open models
xCreate runs a Q9 MLX build of Muse Glimmer against Qwen 3.6 on a 512 GiB M3 Ultra using the Inferencer app.

Video · Local & open models· ♥ 129
Ben Burtenshaw's Gradio agent runs Muse Glimmer on an Inference Endpoint with read-only Hugging Face MCP tools to search and inspect Hub models, datasets, Spaces, docs and papers.
Site · Agents & automation· ♥ 4
Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.
GitHub · Local & open models
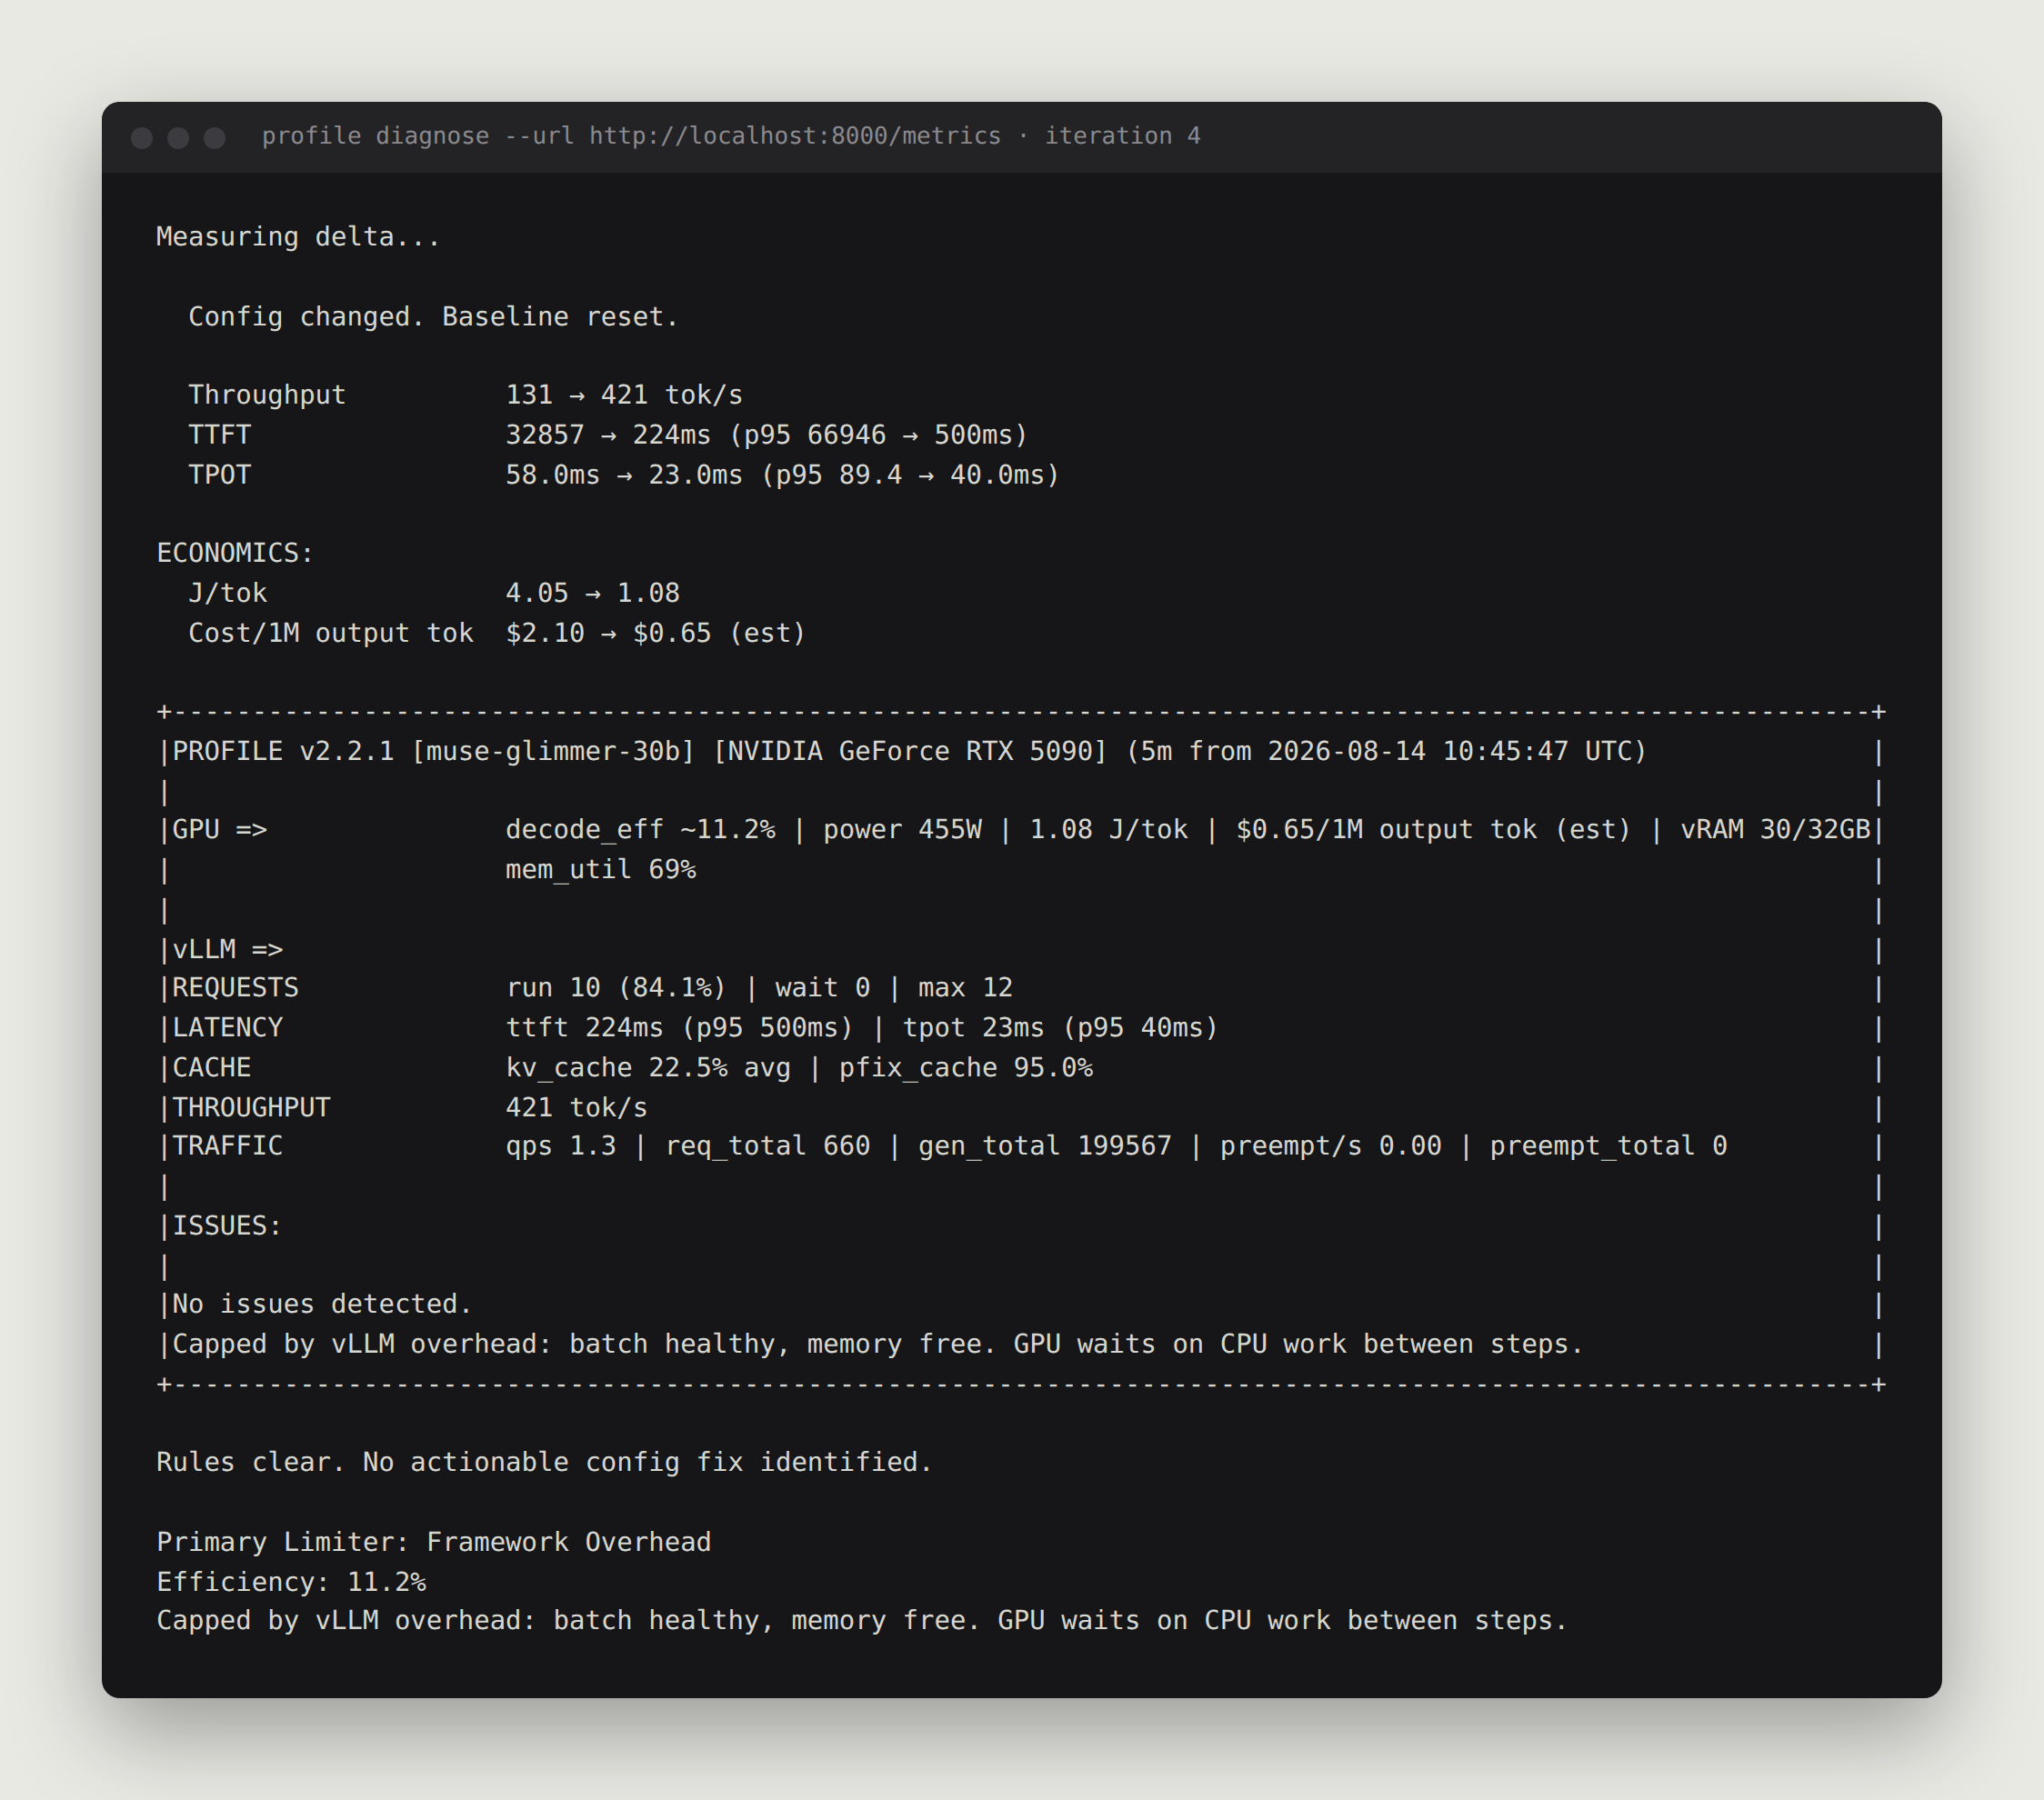
Hi all, Profile v2.2 is out. It's an open-source optimizer for inference servers. It computes your GPU's roofline ceiling, measures your live server against it, names the bottleneck, gives the flag. You apply. It re-measures. Every fix answers to a number. vLLM only today. More engines next. This release: core rule engine rewritten. Eight rules on a priority DAG with mutual exclusivity. Five alarms fire, four echoes are silenced, one true cause survives. Deterministic. AMD cards are now supported too. Tuning today is chaos: try a flag, wait, squint at a dashboard, repeat for days. Profile turns it into deterministic engineering: measure, fix, verify. Results in a few iterations. Mine took 4, ~30 minutes. My setup: RTX 5090, muse-glimmer 30B, SWE-Bench agents, no DFlash spec decoding. • 81 → 421 tok/s at 25k ctx • $3.41 → $0.65 per 1M output tok • TTFT 224ms (p95 500ms), TPOT 23ms at end of run • 4.72 → 1.08 J/tok https://preview.redd.it/4vazyxkcq6kh1.png?width=2248&format=png&auto=webp&s=77923a489b6f725240d23a7953150b5779260734 One iteration regressed hard: KV thrashing, TTFT 32.8s. Profile labeled it worse. Next fix recovered it. Regressions stay in the record. Watc
Reddit post · Local & open models
Resource · Local & open models· ♥ 4
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Unsloth's bitsandbytes 4-bit build of Muse Glimmer 30B for fine-tuning and inference.
Resource · Local & open models· ♥ 14
Fahd Mirza installs Muse Glimmer in GGUF format and tests it with DFlash speculative decoding for faster local inference.

Video · Local & open models
A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.
GitHub · Local & open models
A reproducible record of running the 17GB Muse Glimmer 30B GGUF with llama.cpp and Metal on a 24GB M4 Pro MacBook Pro, with notes on mistakes, fixes and how local inference works.
GitHub · Local & open models
Taylor Arndt retried Muse after Meta Connect with Gmail, Google Calendar, GitHub and her own product-management tool connected, and found it inferred her COO role from calendar data and became useful for ongoing task management.
Resource · Business & commerce
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
A 40-chapter book on Muser, an engine that runs Muse Glimmer on Apple Silicon Metal. It covers kquant and DFlash speculative lanes, exact KV-cache replay with kvpack, and GB10 NVFP4 prefill handed off to a Mac, with every number tied to an evidence receipt.
GitHub · Local & open models· ★ 3




 ChatForm
 Tgmlabs