 usecases


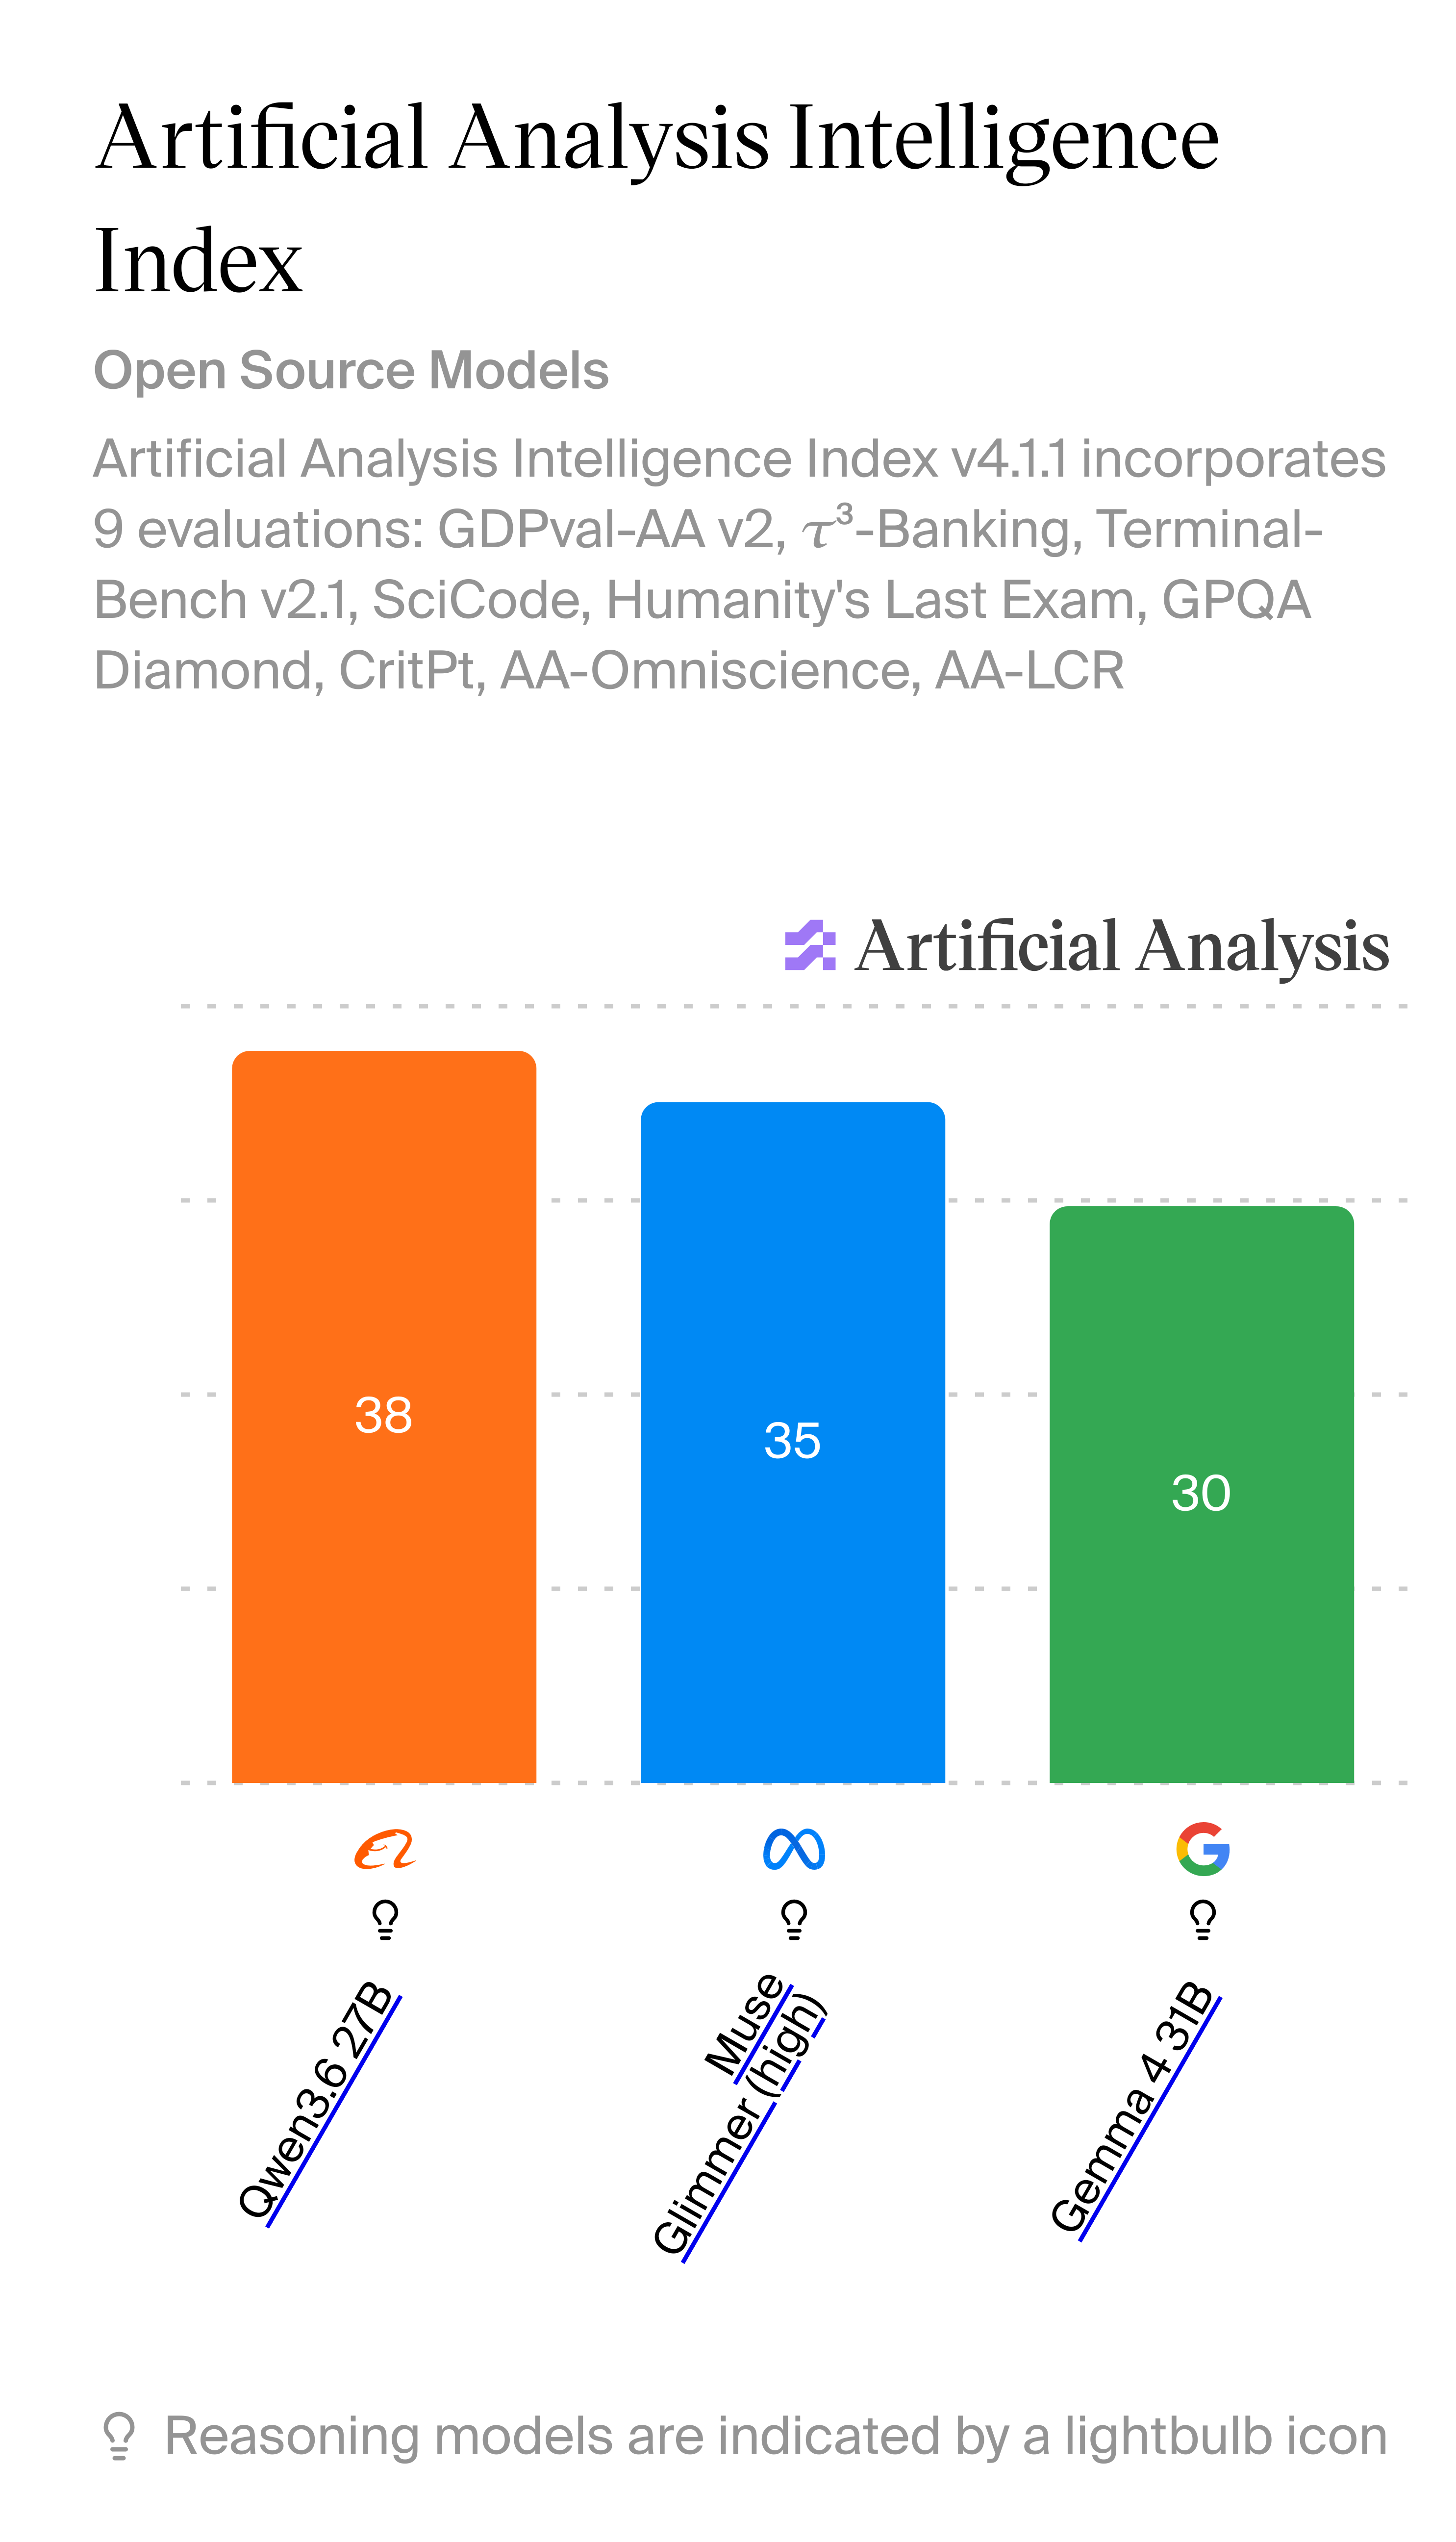
eesel AI reports Muse Spark 1.3 ranks #6 on the Artificial Analysis Intelligence Index, leads long-context and coding rows, but trails Claude Opus 5 on four of six agent evals.
Resource · Benchmarks & research
Newly submitted
Loot Radar: Game deals and Freebies trackerloot radar is my game deals site, radar.codemeoww.com. tracks deals and freebies across stores like steam and epic, ranked by discount and popularity. features: daily loot summaries on telegram and discord, fast price alerts, a morning deals digest, wishlist tracking so you get pinged when a game you want drops, and an api for the deal data.
Newly submitted builds are featured here. Submit yours
1076 builds · page 26 of 27
eesel AI reports Muse Spark 1.3 ranks #6 on the Artificial Analysis Intelligence Index, leads long-context and coding rows, but trails Claude Opus 5 on four of six agent evals.
Resource · Benchmarks & research
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Negligible Capital
@negligible_cap
Sure $META Muse is good. Really good even. I had it go through my entire email last night and unsubscribe me from dozens of promotions and it only used around 10% of the free token budget But Instinct is also really good and didn’t need to pay Alex Wang a billion dollars to get
X post · Errands & personal agent· ♥ 342
A YouTube tutorial companion repo where Muse Glimmer 30B (a 2-bit GGUF, run offline) looks at screenshots of badly designed web pages and generates and self-repairs modern replacement code.
GitHub · Local & open models
Lightweight LoRA that makes Muse Glimmer 30B output a target element's bounding box directly from a screenshot and instruction, for computer-use agents.
Resource · Local & open models· ♥ 3

Louis Vuitton
@metinsk
Muse has been checking the Apple Store online for me and notified me when an iPhone became available to pre order! Saved me a lot of time and effort! Amazing!
X post · Errands & personal agent· ♥ 2

Weida Tan
@weidatan0
Muse bought tickets at Ticketmaster successfully, where Instinct failed
X post · Errands & personal agent· ♥ 1
Standalone packaging of the vision tower and projector extracted from Muse Glimmer 30B.
Resource · Local & open models· ♥ 2
Benchmark reports on Muse-Glimmer-30B on NVIDIA DGX Spark covering BF16 to Q4 to DFlash (a 10x speedup) and NVFP4 via SGLang, plus a head-to-head against Qwen3.6-27B.
GitHub · Benchmarks & research

Aaron Skrivan
@AaronSkrivan
Finally put @Muse to the test. Pretty shocked. I had it find unclaimed property and file all the paperwork. Free $97. Then I had it opt me out to all major data brokers. Finally, I had it add all my Amex offers. Saved 200 manual clicks. @alexandr_wang 🫡
X post · Errands & personal agent

Mika Reyes ⚡️ Timerich AI
@__mikareyes
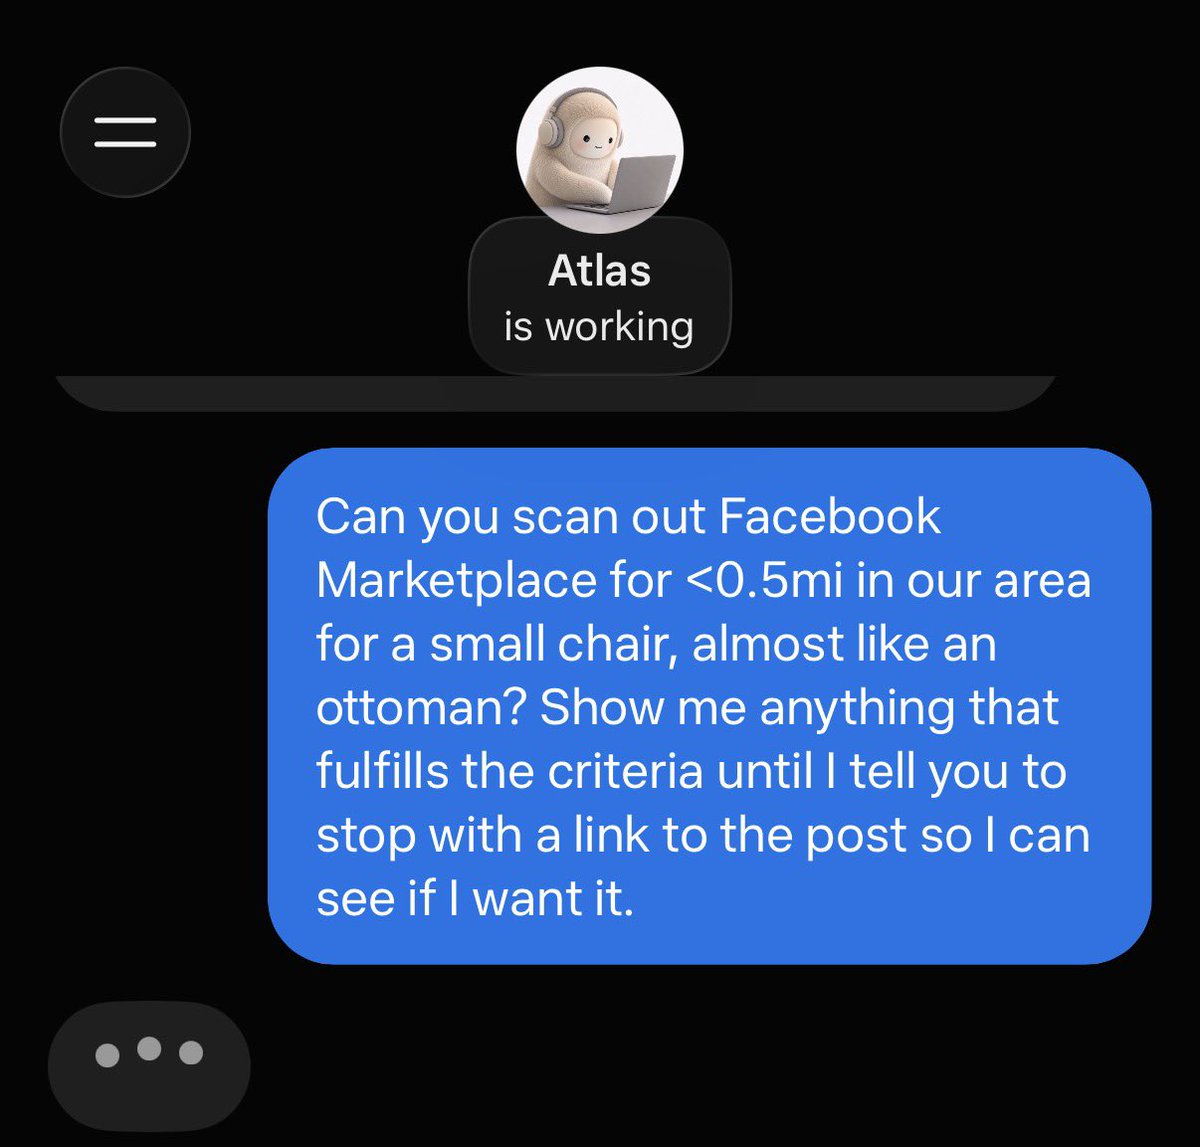
Killer Meta Muse use case: scan FB marketplace for specific items instead of me scrolling myself!!!
X post · Errands & personal agent· ♥ 2
Meta's Mac app lets Muse work with local files, Messages, Notes, Reminders, Mail and Calendar, with per-app Off / Read only / Read and interact controls.
Site · Errands & personal agent
muse-glimmer-mlx is an MLX port of Muse Glimmer 30B for Apple Silicon that supplies the missing runtime so the many unloadable MLX conversions published on Hugging Face can actually be run.
GitHub · Local & open models
Ported a Miniature Golf prototype to VR using Meta Muse Code and the Unity CLI, added dozens of automated tests, and built a website to capture test runs, screenshots and results.
Reddit post · Games & 3D★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Davvit
@DAVV1T
@Muse is content creators gold! It made me 30 days of content calendar and its all great ideas for a City related account i have.
X post · Content & creative· ♥ 1

Ben Parr
@benparr
Things I did with my @muse today: — Researched and got my mom's PODS container booked ($576 under their quote) — Built my 2025 tax doc tracker and hunted down the missing K-1s — Ran a two-week fare sweep for Thanksgiving flights I feel so much more productive.
X post · Errands & personal agent· ♥ 43
Agent Workflow Lab runs the Q8 GGUF of Muse Glimmer 30B through llama.cpp on an RTX 4090 plus 3x RTX 3090, measures DFlash speedups and a 120K-token retrieval probe, then has it build a Three.js browser FPS with no human edits.
Video · Games & 3D

PHARM.Dabbler
@PharmDabbler
$META Had Muse audit my entire YouTube channel 👌
X post · Content & creative· ♥ 1
I established an MCP that allows you to provision a phone number for your Muse agent. It allows it to do outbound calling to the U.S. and Canada to any numbers, not just business lines, and also allow it to take inbound calls. Say, if you wanted to build a receptionist. I am looking for people to test this out, and if you're interested, DM me. I'd love to get you some credits to try it out for free. https://www.botphone.tel/products/muse-receptionist
Reddit post · Connectors & MCP
Motion Labs explains Muse Spark 1.2 setup, the cheaper Contributor tier at $0.10/M input tokens, Artificial Analysis scores and using it for content.
Resource · Content & creative

Eric Fitzpatrick
@FITZPAE
Muse became my personal dietitian after I found that I had high blood sugar last week; really cool to have someone check in and help me plan + monitor each day!
X post · Errands & personal agent· ♥ 1
Reddit post · Benchmarks & research
ROCmFP4 and ROCmFP8 builds of Muse Glimmer 30B and its drafter, targeted and tested on AMD Strix Halo (gfx1151).
Resource · Local & open models· ♥ 18
Fine-tune of Muse Glimmer 30B for Hermes Agent and agentic tool work that teaches the model to call one or two tools and stop.
Resource · Local & open models· ♥ 2

Flrid
@sunilsrathode
asked muse to lookup all county courts in California for any traffic citation on my name, It actually found a recent case, set up payment through Stripe Link, done in minutes. Fast, seemless and super easy to use. Offloading all such tasks. Thanks @alexandr_wang and the team.
X post · Errands & personal agent· ♥ 6
This started as a failure. I had cut 6.34% of Meta's Muse-Glimmer-30B (the FFN sublayers of four layers, the next FFN after each cut retrained against the parent) and the healed model passed my fidelity bar at Q8_0. At Q4_K it failed by 0.006 KLD, and the arithmetic said why: the surgery's cost plus the ordinary Q4_K cost adds up to just over the bar, and three months of levers on the surgery side could not close a gap that small. So I attacked the other term. In a fixed GGUF the integer codes are frozen, but every quantised block still carries one or two fp16 scales, and the decoded weight is linear in them. That means the scales can be trained end to end against the parent's next-token distribution on the student's own forward pass, without touching the codec, the format, the byte length or the offsets. On the surgical model it worked: 0.05615 fail to 0.04949 pass on 45,056 held-out positions, and the preregistered control (the same recovery on the uncut parent at Q4_K) showed the two costs are not additive once the scales are trained; recovery took back part of the surgery error too. That file and the whole study are on my Hugging Face page. Then the obvious question: does it
Reddit post · Local & open models

Ahmad Awais
@MrAhmadAwais
Solid model. Shipped live in @CommandCodeAI 🐐
X post · Coding & dev tools· ♥ 2
A Makefile that downloads the three Muse Glimmer 30B GGUFs and builds and serves llama.cpp on Apple Silicon, automating a scriptable.com walkthrough.
GitHub · Local & open models
LoRA adapter that makes Muse Glimmer 30B reliably commit to tool calls when it already knows the correct function.
Resource · Local & open models· ♥ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
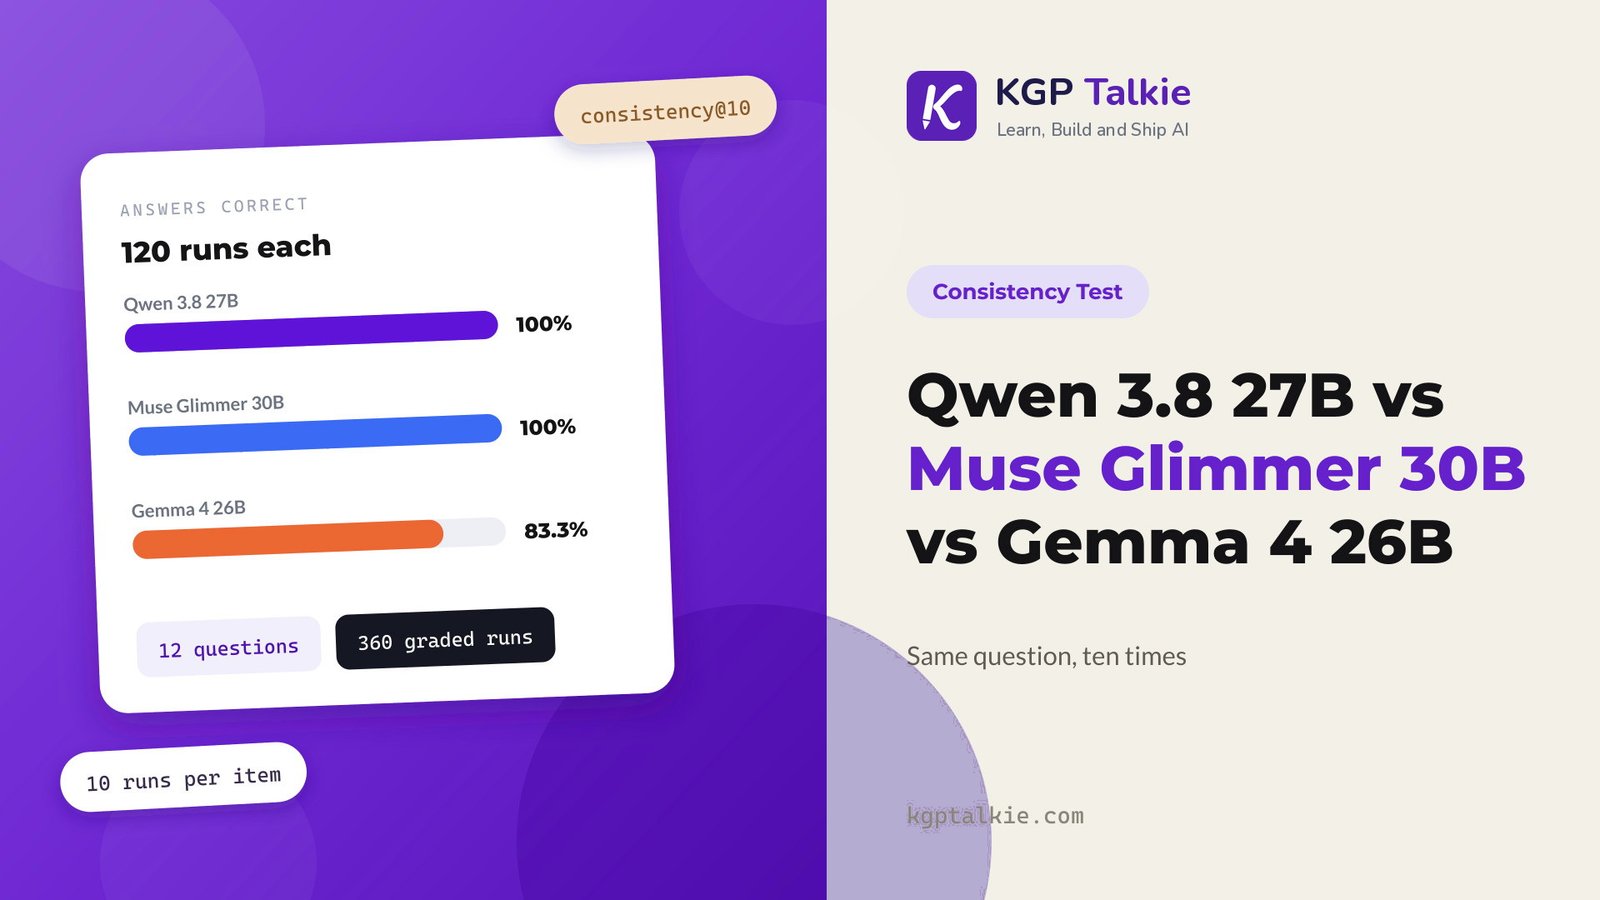
KGP Talkie asked Qwen 3.8 27B, Muse Glimmer 30B and Gemma 4 26B the same twelve questions ten times each to see which answers the same way twice.
Resource · Benchmarks & research

Cristian Uibar
@cristianuibar
@theo please add support for Muse Code in T3. I've opened a PR here for it using the official SDK. github.com/pingdotgg/t3co…
X post · Coding & dev tools· ♥ 1
Been building this for a few months, mostly for myself, and it just got a proper release so figured I'd post it. It's a native GGUF inference runtime with OpenAI/Anthropic-compatible APIs and a chat UI. The whole point is one consumer NVIDIA card + lots of RAM: MoE models that don't fit in VRAM run their experts on the CPU, or split with a hot set cached on the card. It figures out what fits at startup instead of you guessing offload layer counts. Runs Qwen 3.x dense and MoE (incl. Qwen3.8-Flash-Next), DeepSeek-V4-Flash, Ling 3.0, K2-Horizon, Gemma 4, Laguna, Muse Glimmer. Image input via mmproj on the Qwen models. Also does Z-Image-Turbo image gen next to a chat model on the same card. Numbers from my laptop (5070 Ti 12 GB, 60 GB RAM): - Qwen3.8-Flash-Next IQ1_S: ~35 tok/s decode, ~475 tok/s prefill - Qwen3.8-27B IQ2_XXS: ~40 tok/s - DeepSeek-V4-Flash: 6-7 tok/s (that's basically the DRAM bandwidth limit) - Z-Image 1024x1024 in ~15 s with a 35B loaded beside it Stuff I think is neat: - Kernels are compiled at runtime by NVRTC, so no CUDA toolkit in the wheel and no nvcc. Same kernel source compiles as plain C++ for a CPU-only backend. - KV cache in f16 / q8_0 / TurboQu
Reddit post · Local & open models
I have a classic test for local LLM's. I asked for 8 ball pool game with only one HTML file and Muse Glimmer spend 21k Token(I m using full context so 128k) and only created a 220 lines of HTML and said its done. With my experience its not even close to Qwen 3.6 27B and we are waiting for Qwen 3.8 27B already. What is your toughts about this model. I was so hopeful until this test.
Reddit post · Benchmarks & research
Alex Volkov tests the Muse agent's research and Stripe-powered payments, and walks through its VM security, personal-data handling and the training opt-out.

Video · Errands & personal agent

Blaine 📈📉📈
@BlaineCapital
Built a Sleeper fantasy football co-pilot: tracks across multiple 12-team leagues with FAAB budgets, sends weekly waiver/start-sit briefings plus Thu/Sun pre-game checks with inactives and weather as a tiebreaker. Already caught an OUT starter & recommended a swap.
X post · Errands & personal agent
A Muse Glimmer fine-tune that writes, tunes and translates detection rules (Sigma to KQL and SPL, YARA, Wazuh) and runs 4-bit on a single 24 GB card.
Resource · Local & open models
A video companion repo with the commands and configs for running Muse Glimmer 30B locally on an RTX 3090 and comparing the Prime Agent and Hermes harnesses under the same conditions.
GitHub · Local & open models· ★ 1
Ran the model with quants (Q4) by Unsloth with latest (build from master) llama.cpp server. It takes ~20GB ram running on M5 Pro with 48GB at about 17t/s. Didn't do any reasoning loops/overthinking. Overall, sits below Qwen3.6 27B, wasn't able to get good code (frontend and backend) results. On the positive side, it didn't fail any tool calls. Your opinions/findings? Watch more: https://www.youtube.com/watch?v=_5wKhkUT438
Reddit post · Local & open models
I noticed on the same hardware that I can get 24 x 128k contexts with muse glimmer (30b q8_0 + mmproj+dflash) only gets me 3x 256k or 6x 128k with qwen. But a straight forward analysis of the architecture suggests to me that qwen's state per token is somewhat smaller than glimmers. So it seems llama.cpp is particularly memory inefficient for the qwen arch. I presume there is an existing issue for this, but I couldn't find one. What's the deal? The extra concurrency makes a big difference in batched performance.
Reddit post · Local & open models
An unofficial parody MLX-VLM QLoRA adapter for Muse Glimmer 30B on Apple Silicon.
Resource · Local & open models· ♥ 1
Setup. We run Qwen3.8-Flash-Next NVFP4 as our main agentic model (SGLang, RTX PRO 6000). Before its output reaches a human or gets merged, a second local model acts as judge: reviews the diff, flags real bugs only. Hosted on a 5090 32GB, so we're limited to ~30B NVFP4/GGUF class models. The metric that matters is NOT detection rate — it's false alarms on correct code. A judge that cries wolf gets ignored within a week, exactly like a flaky CI. We built our own battery: 20 injected bugs + 20 clean-but-suspicious snippets (intentional swallowed exceptions, deliberate mutability, weird-but-correct concurrency, short hashes, float patterns that look wrong). Ground-truth labeled, and a stronger model (GLM-5.2 API) arbitrates the judge's prose so scoring isn't vibes. Two passes minimum — single runs lie. Results (40 cases, temp 0, same baremo for everyone): Qwen3.8-27B NVFP4 (no-thinking) • Bugs found: 17/20 • False alarms: 3/20 • Verdict: only pass Nemotron Lightning 30B • Bugs found: 17/20 • False alarms: 0→9 across runs • Verdict: non-reproducible as judge Muse-Glimmer 30B GGUF • Bugs found: 19/20 • False alarms: 12/20 • Verdict: hypercritical Granite 4.1 30B (no-thinki
Reddit post · Benchmarks & research
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page




 ChatForm
 Tgmlabs