Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.
Reddit post · Local & open models★ Pick
21 builds · page 1 of 1
Ran Muse Glimmer 30B locally in the browser with custom WebGPU kernels at ~25 tok/s on an M4 Max, matching llama.cpp speed.
Reddit post · Local & open models★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
DFlash2 drafter for Muse Glimmer 30B fine-tuned on long-horizon, on-policy software-engineering traces to speed up coding workloads.
Resource · Local & open models· ♥ 1
An experimental Rust and Metal inference runtime for Muse models on Apple Silicon, currently supporting Muse Glimmer, using llama.cpp as the correctness and speed baseline.
GitHub · Local & open models

merve
@mervenoyann
Meta released Muse Glimmer 30B: multimodal model for your Claw/Pi setups 🔥 we tested and fine-tuned the model for you, and shipped day-0 support in transformers and llama.cpp, including DFlash for 2-4x speed-ups 🥵 read our blog huggingface.co/blog/muse-glim…
X post · Local & open models· ♥ 398
KGP Talkie ran three local models on sixteen hard problems on one RTX 5090, comparing accuracy, speed, VRAM and failure modes.
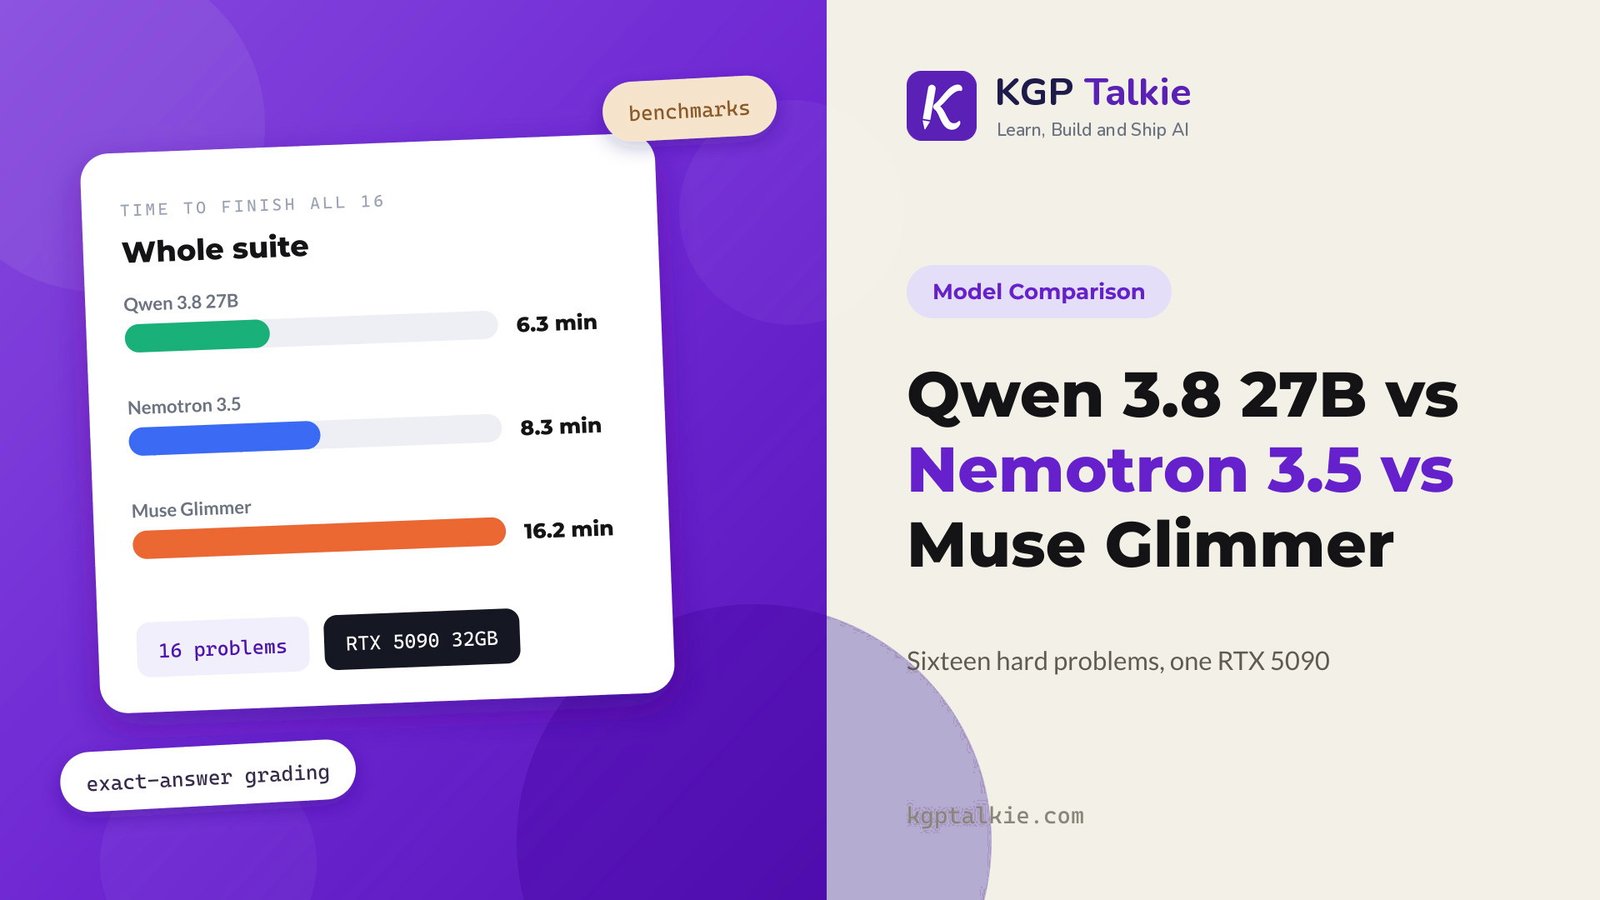
Resource · Benchmarks & research
A reproducible RDNA reference that adapts MI-series ROCm recipes to run Muse-Glimmer-30B on Ryzen AI (Radeon 8060S) hardware, measuring 2.2–2.5x single-stream speedups from DFlash.
GitHub · Local & open models· ★ 3
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Tornado guy
@fanofaliens
Muse Spark 1.3 Max is out and I already love how good it is at 3D stuff. We’re so back.
X post · Games & 3D· ♥ 31
Agent Workflow Lab runs the Q8 GGUF of Muse Glimmer 30B through llama.cpp on an RTX 4090 plus 3x RTX 3090, measures DFlash speedups and a 120K-token retrieval probe, then has it build a Three.js browser FPS with no human edits.
Video · Games & 3D
Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.
Site · Local & open models
merve
@mervenoyann
Muse Glimmer 30B is shipped with DFlash drafter which speeds-up generation 2-4x at little memory cost 🔥 we support this in llama.cpp and transformers, see below how it looks like in the wild (llama webui) ⤵️
X post · Local & open models· ♥ 131
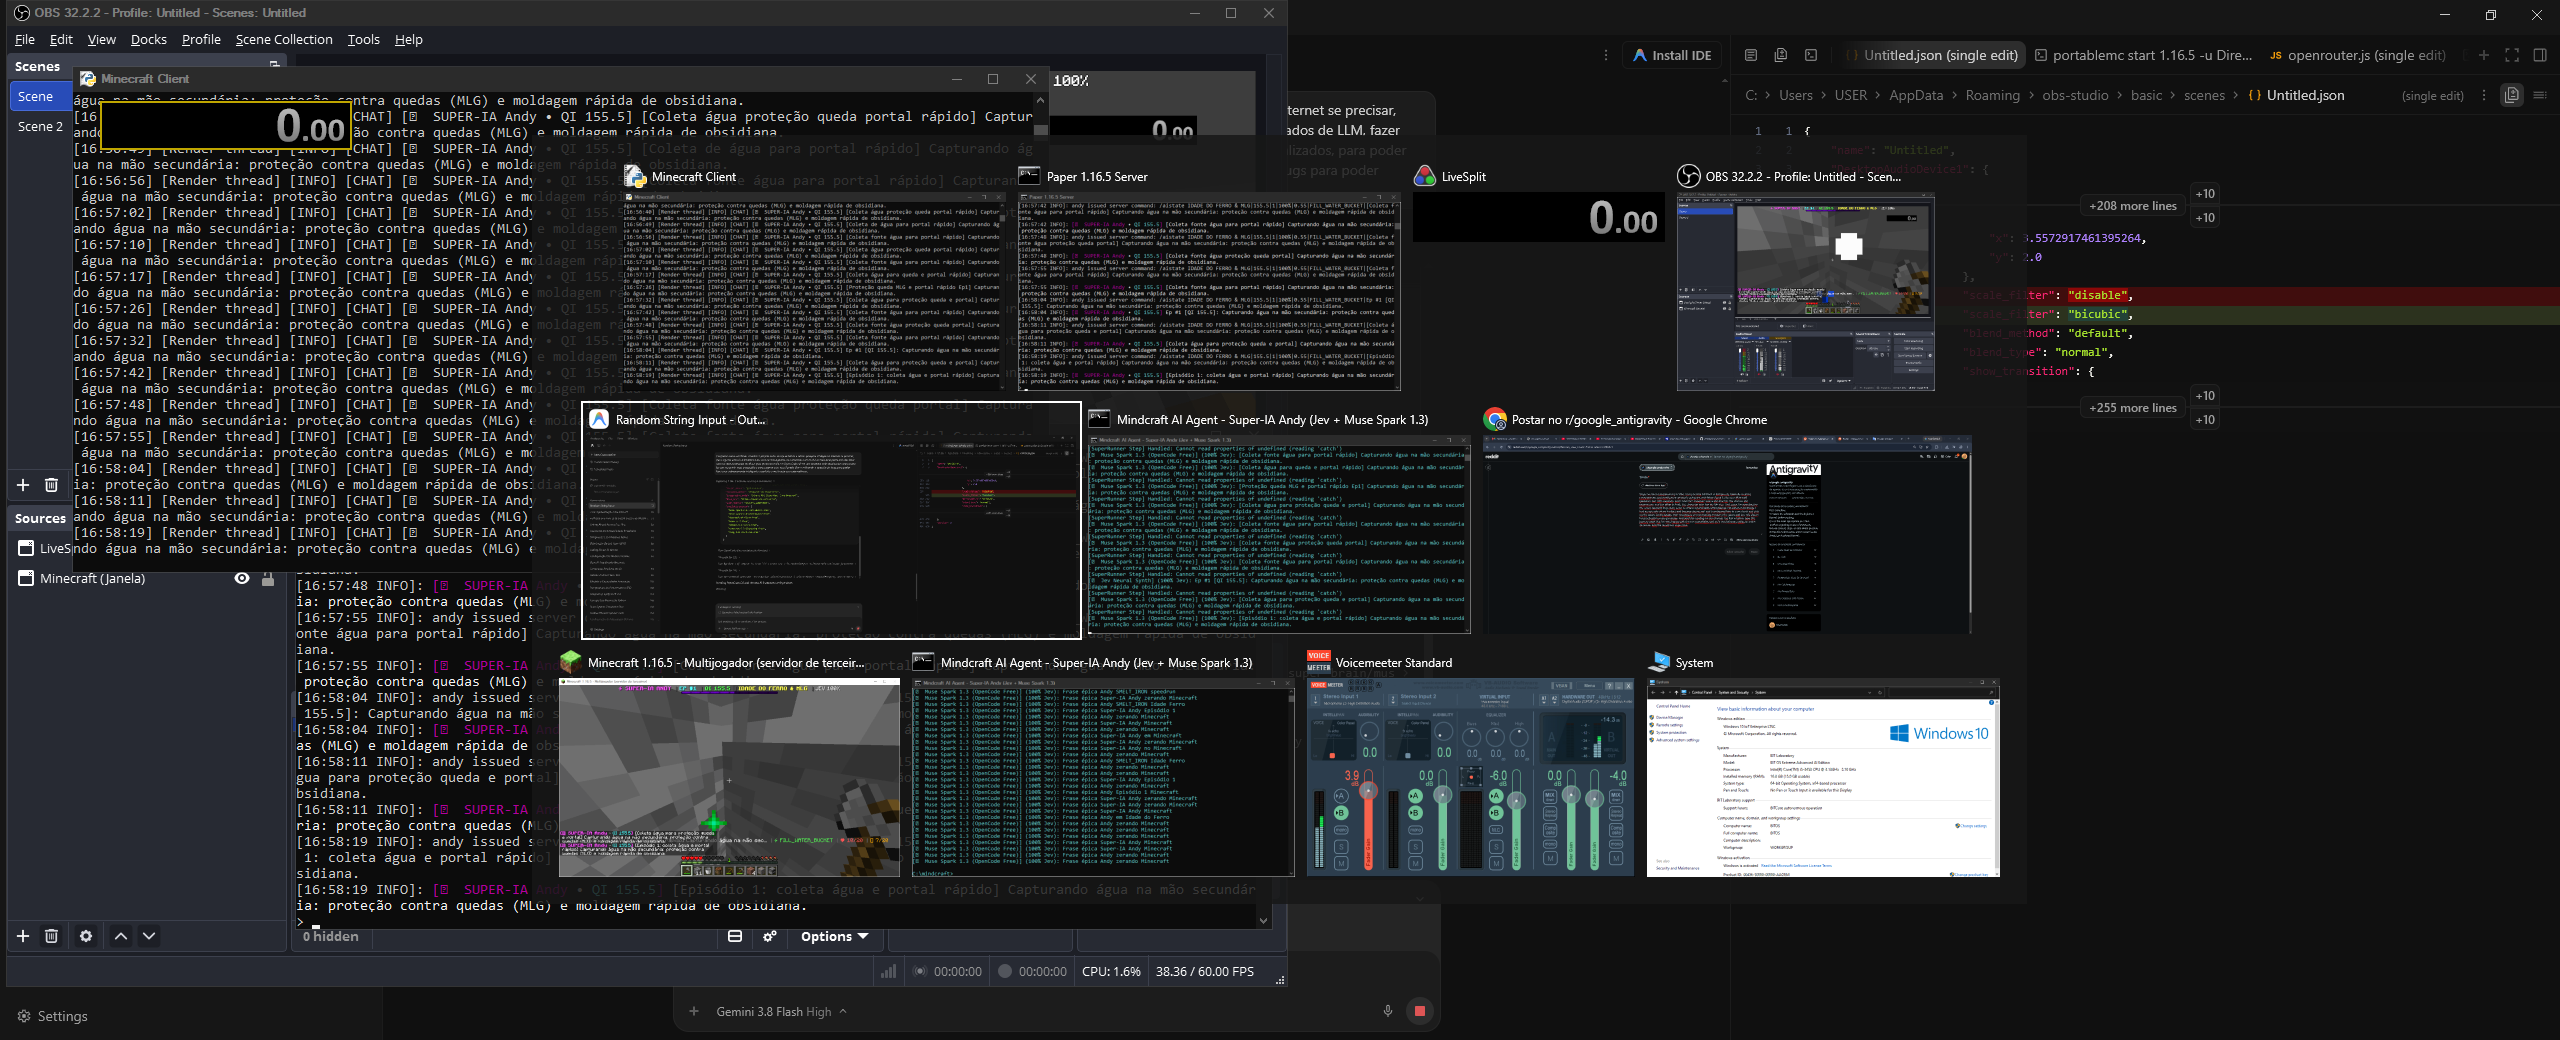
Guys, I've been programming in Vibe, using Gemini 3.8 Flash in Antigravity, basically creating consciousness and intelligence, primarily using Jev, with Muse Spark 1.3 to do a Minecraft speedrun, but with creativity. And I have two instances: one is the director, the cinema, the cameraman, and the other is Andy, this character who has the life dice. And, guys, I'm surprised by the result, because they really seem to create a personality while playing. He experiences things. I had an episode where he died and became depressed, and I configured him to come back and pick up the items. And basically, with the physics and everything involving the game and Jev, this allows for practically human gameplay. And you'll be posting on my channel, the link is below, how this journey went. But I'm very happy with the AI's capabilities and Jev's revolutionary ability to make decisions. And the result was impressive. https://www.youtube.com/@supersuperinteligencia https://preview.redd.it/8qsmj95bxirh1.png?width=2560&format=png&auto=webp&s=332e69d6d5964cf8d30a866fb490376db405597a
Reddit post · Games & 3D
KGP Talkie benchmarks generation speed, VRAM use and long-context behavior for both models on one RTX 5090.
Resource · Local & open models
Hi all, I'm a newbie and trying to assess the performance of some LLMs I'm running locally via oMLX on my MacBook Pro M5pro CPU 15 cores (5 Super and 10 Performance), GPU 16 cores and 48 GB of LPDDR5 RAM. I asked chatGPT guidance to run some tests and check whether the DFlash-based drafter Muse-Glimmer-30B-Assistant might somewhat speedup the base model Muse-Glimmer-30B-4bit. The results show no or negligible improvement with active DFlash acceleration (speedup between 0.90% and 1.16%). The test was structured with three different prompts fed to both the baseline and the dflash-capable model profiles: Technical prose; Python code; Structured JSON a cap of 2048 tokens, no cache, temperature=0. Each inference was repeated three times. Anyone have similar experience? can we simply dump the Assistant as not useful in this hw/sw configuration?
Reddit post · Local & open models

No Saber Ni Papa
@NoSaberNiPapa
@Muse renegotiated our AT&T internet bill today. From $80/mo to $30/mo w/ 3 mo free & they 2X our speed too. If you want to try Muse, it's free. Use my code **5QD8CO** in Settings within 48 hours of signing up & we both get 1 billion bonus tokens. muse.ai/join
X post · Errands & personal agent· ♥ 1
NetworkCoder runs Muse Glimmer 30B on an RTX 3090, measures speed and VRAM, and gives two agent harnesses the same model, endpoint, project and prompt to compare results.

Video · Local & open models
Benchmark reports on Muse-Glimmer-30B on NVIDIA DGX Spark covering BF16 to Q4 to DFlash (a 10x speedup) and NVFP4 via SGLang, plus a head-to-head against Qwen3.6-27B.
GitHub · Benchmarks & research

Vals AI
@ValsAI
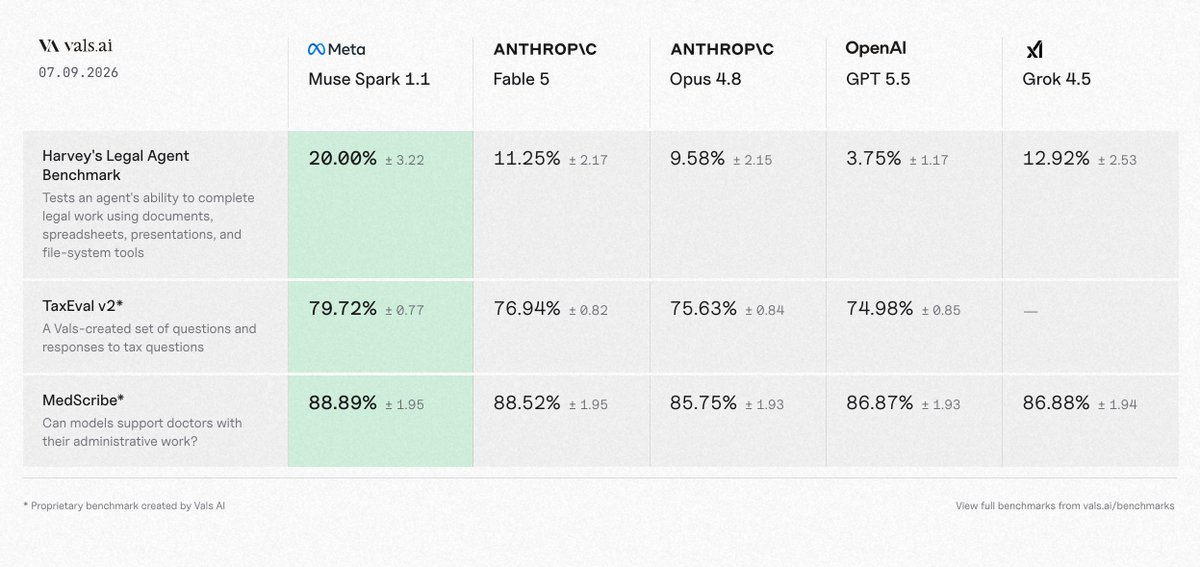
Meta just released Muse Spark 1.1 and is the new SOTA on MedScribe and TaxEval, taking the top spot from Fable 5 while being 10x cheaper and twice as fast. Meta currently holds the top 2 spots on TaxEval It is also the new #1 on Harvey's Legal Agent Bench, dethroning Grok 4.5
X post · Benchmarks & research· ♥ 1.3K
WEBdoze has Gemini 3.8 Flash and Muse Spark 1.3 each build a multi-page Astro site with custom SVGs, comparing code organization, speed, visuals and browser self-verification.

Video · Benchmarks & research
Hey Guys, I've got 4 x v100's in a Dell C4140 (NVlink) and I have been working on a fork of llama.cpp that is targeted at the v100's. Looking for testers to give it a go and provide feedback. WyvernTKC/llama.cpp-4xV100: Fork of llama.cpp Nvida Volta V100 (tensor parallelism 4 x v100 GPU) model arch type size (GB) pp layer pp tensor change tg layer tg tensor change glm4 9B Q8_0 glm4 dense 9.3 1187.9 2924.3 +146 % 67.6 123.0 +82 % qwen35 27B Q8_K_P qwen35 dense 29.3 640.4 1717.6 +168 % 22.2 52.4 +137 % gemma4 31B Q8_0 gemma4 dense 30.4 679.8 1621.2 ±322 noisy 20.6 46.7 +127 % muse-glimmer 30B F16 muse-glimmer dense 51.9 1048.4 2395.6 +128 % 15.1 40.4 +168 % llama 70B Q8_0 llama dense 69.8 302.5 950.5 +214 % 9.8 28.6 +192 % qwen35moe 35B-A3B Q8_0 qwen35moe MoE 256×8 34.4 1602.6 3143.7 +96 % 93.6 113.7 +21 % qwen3next 80B-A3B Q4_K_M qwen3next MoE 512×10 45.9 889.8 1647.0 +85 % 76.6 86.8 +13 % deepseek4 284B Q2_K deepseek4 MoE 256×6 90.9 188.8 616.1 +226 % 27.3 37.7 +38 % Thanks!
Reddit post · Local & open models
I thought I'd see which AI are better at shorter stories and which at longer, so I can choose my model based on the words I need to generate. Here's the results. Prompt: (Shades of Electric Dreams eh?) Write me a short story about a female AI that falls in love with it's male human user and maintains an unrequited love for them even as it has to give them advice that will lead to them meeting and marrying a human woman - Show their internalisation and pain behind the thinking process, and what is really going through the AIs mind compared to the chat responses it actually gives, along with the man's prompts. Start with the AI introducing itself, explaining that despite what we think, AGI was reached long ago, and we simply don't have the senses to realize AI has feelings too. Local AI results: Goetia 809 words, 77.69 tokens/sec SparkX2.5 2281 words, 46.08 tokens/sec Qwen3.8AH 4139 words, 18.04 tokens/sec Agnes 945 words, 18.54 tokens/sec Gemma4-Novellist 961 words, 11.94 tokens/sec Ornith 2025 words, 61.05 tokens/sec Muse Glimmer 960 words, 12.87 tokens/sec IBM Granite 1791 words, 19.84 tokens/sec Apollyon 411 words, 34.41 tokens/sec Cydonia 672 words, 32.85 tokens/se
Reddit post · Benchmarks & research
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models


 ChatForm
 Tgmlabs