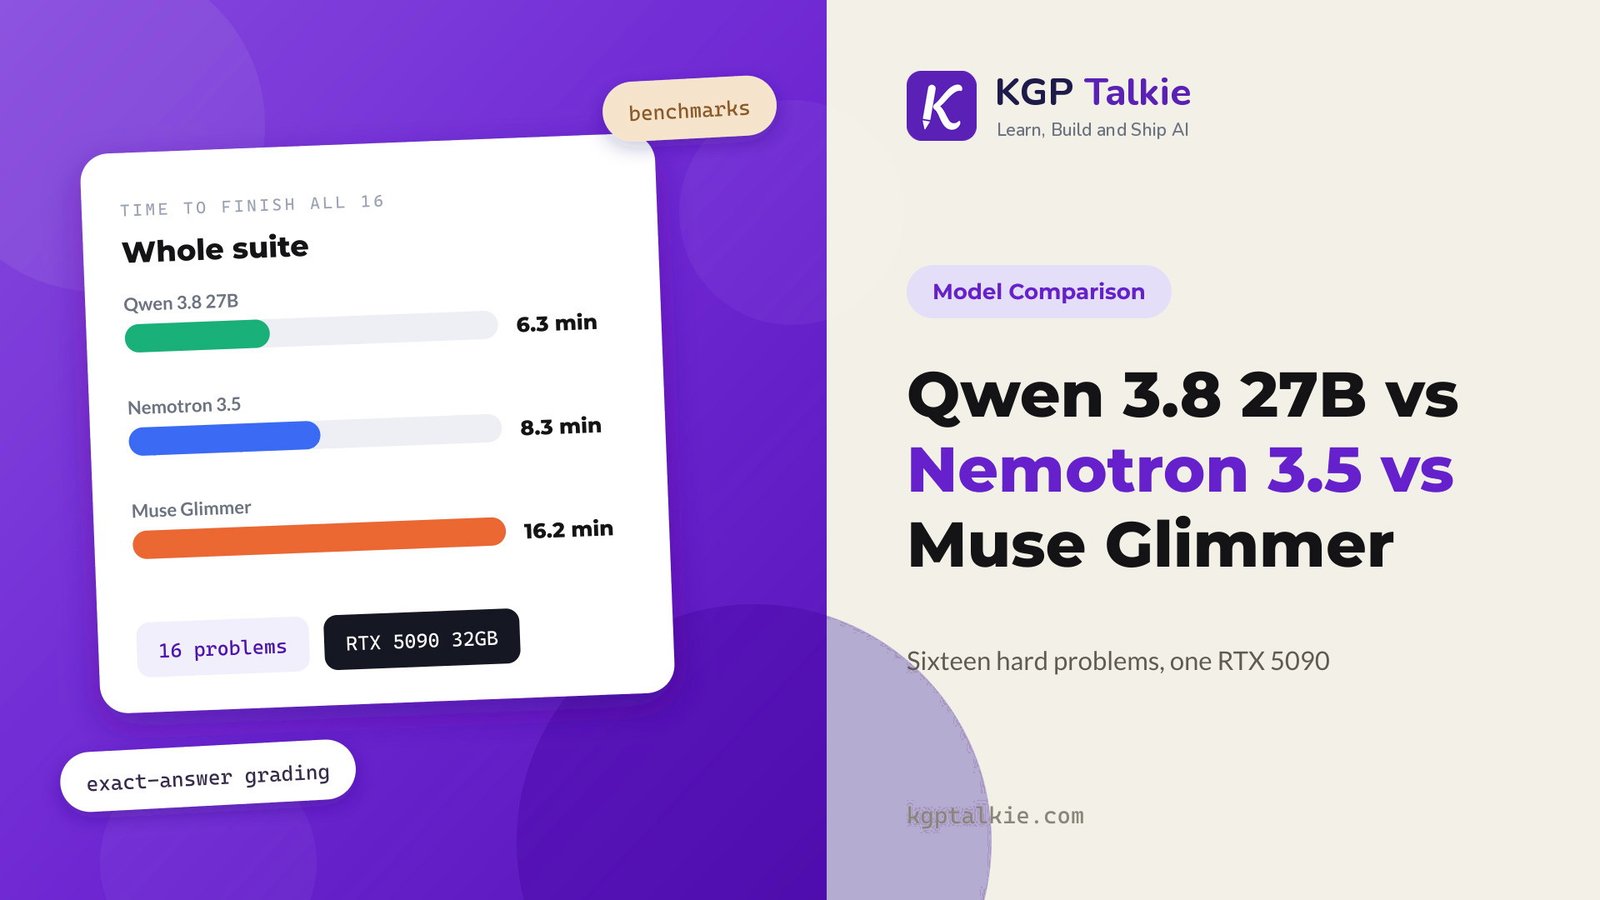
KGP Talkie ran three local models on sixteen hard problems on one RTX 5090, comparing accuracy, speed, VRAM and failure modes.
Resource · Benchmarks & research
15 builds · page 1 of 1
KGP Talkie ran three local models on sixteen hard problems on one RTX 5090, comparing accuracy, speed, VRAM and failure modes.
Resource · Benchmarks & research
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.
GitHub · Local & open models· ★ 8
KGP Talkie benchmarks generation speed, VRAM use and long-context behavior for both models on one RTX 5090.
Resource · Local & open models
A benchmark that tests whether Muse Glimmer 30B on a single RTX 5090 works as an OpenCode backend, using the same tasks as earlier DeepSeek and Qwen runs; first results show 18/18 episodes with zero malformed tool calls.
GitHub · Benchmarks & research
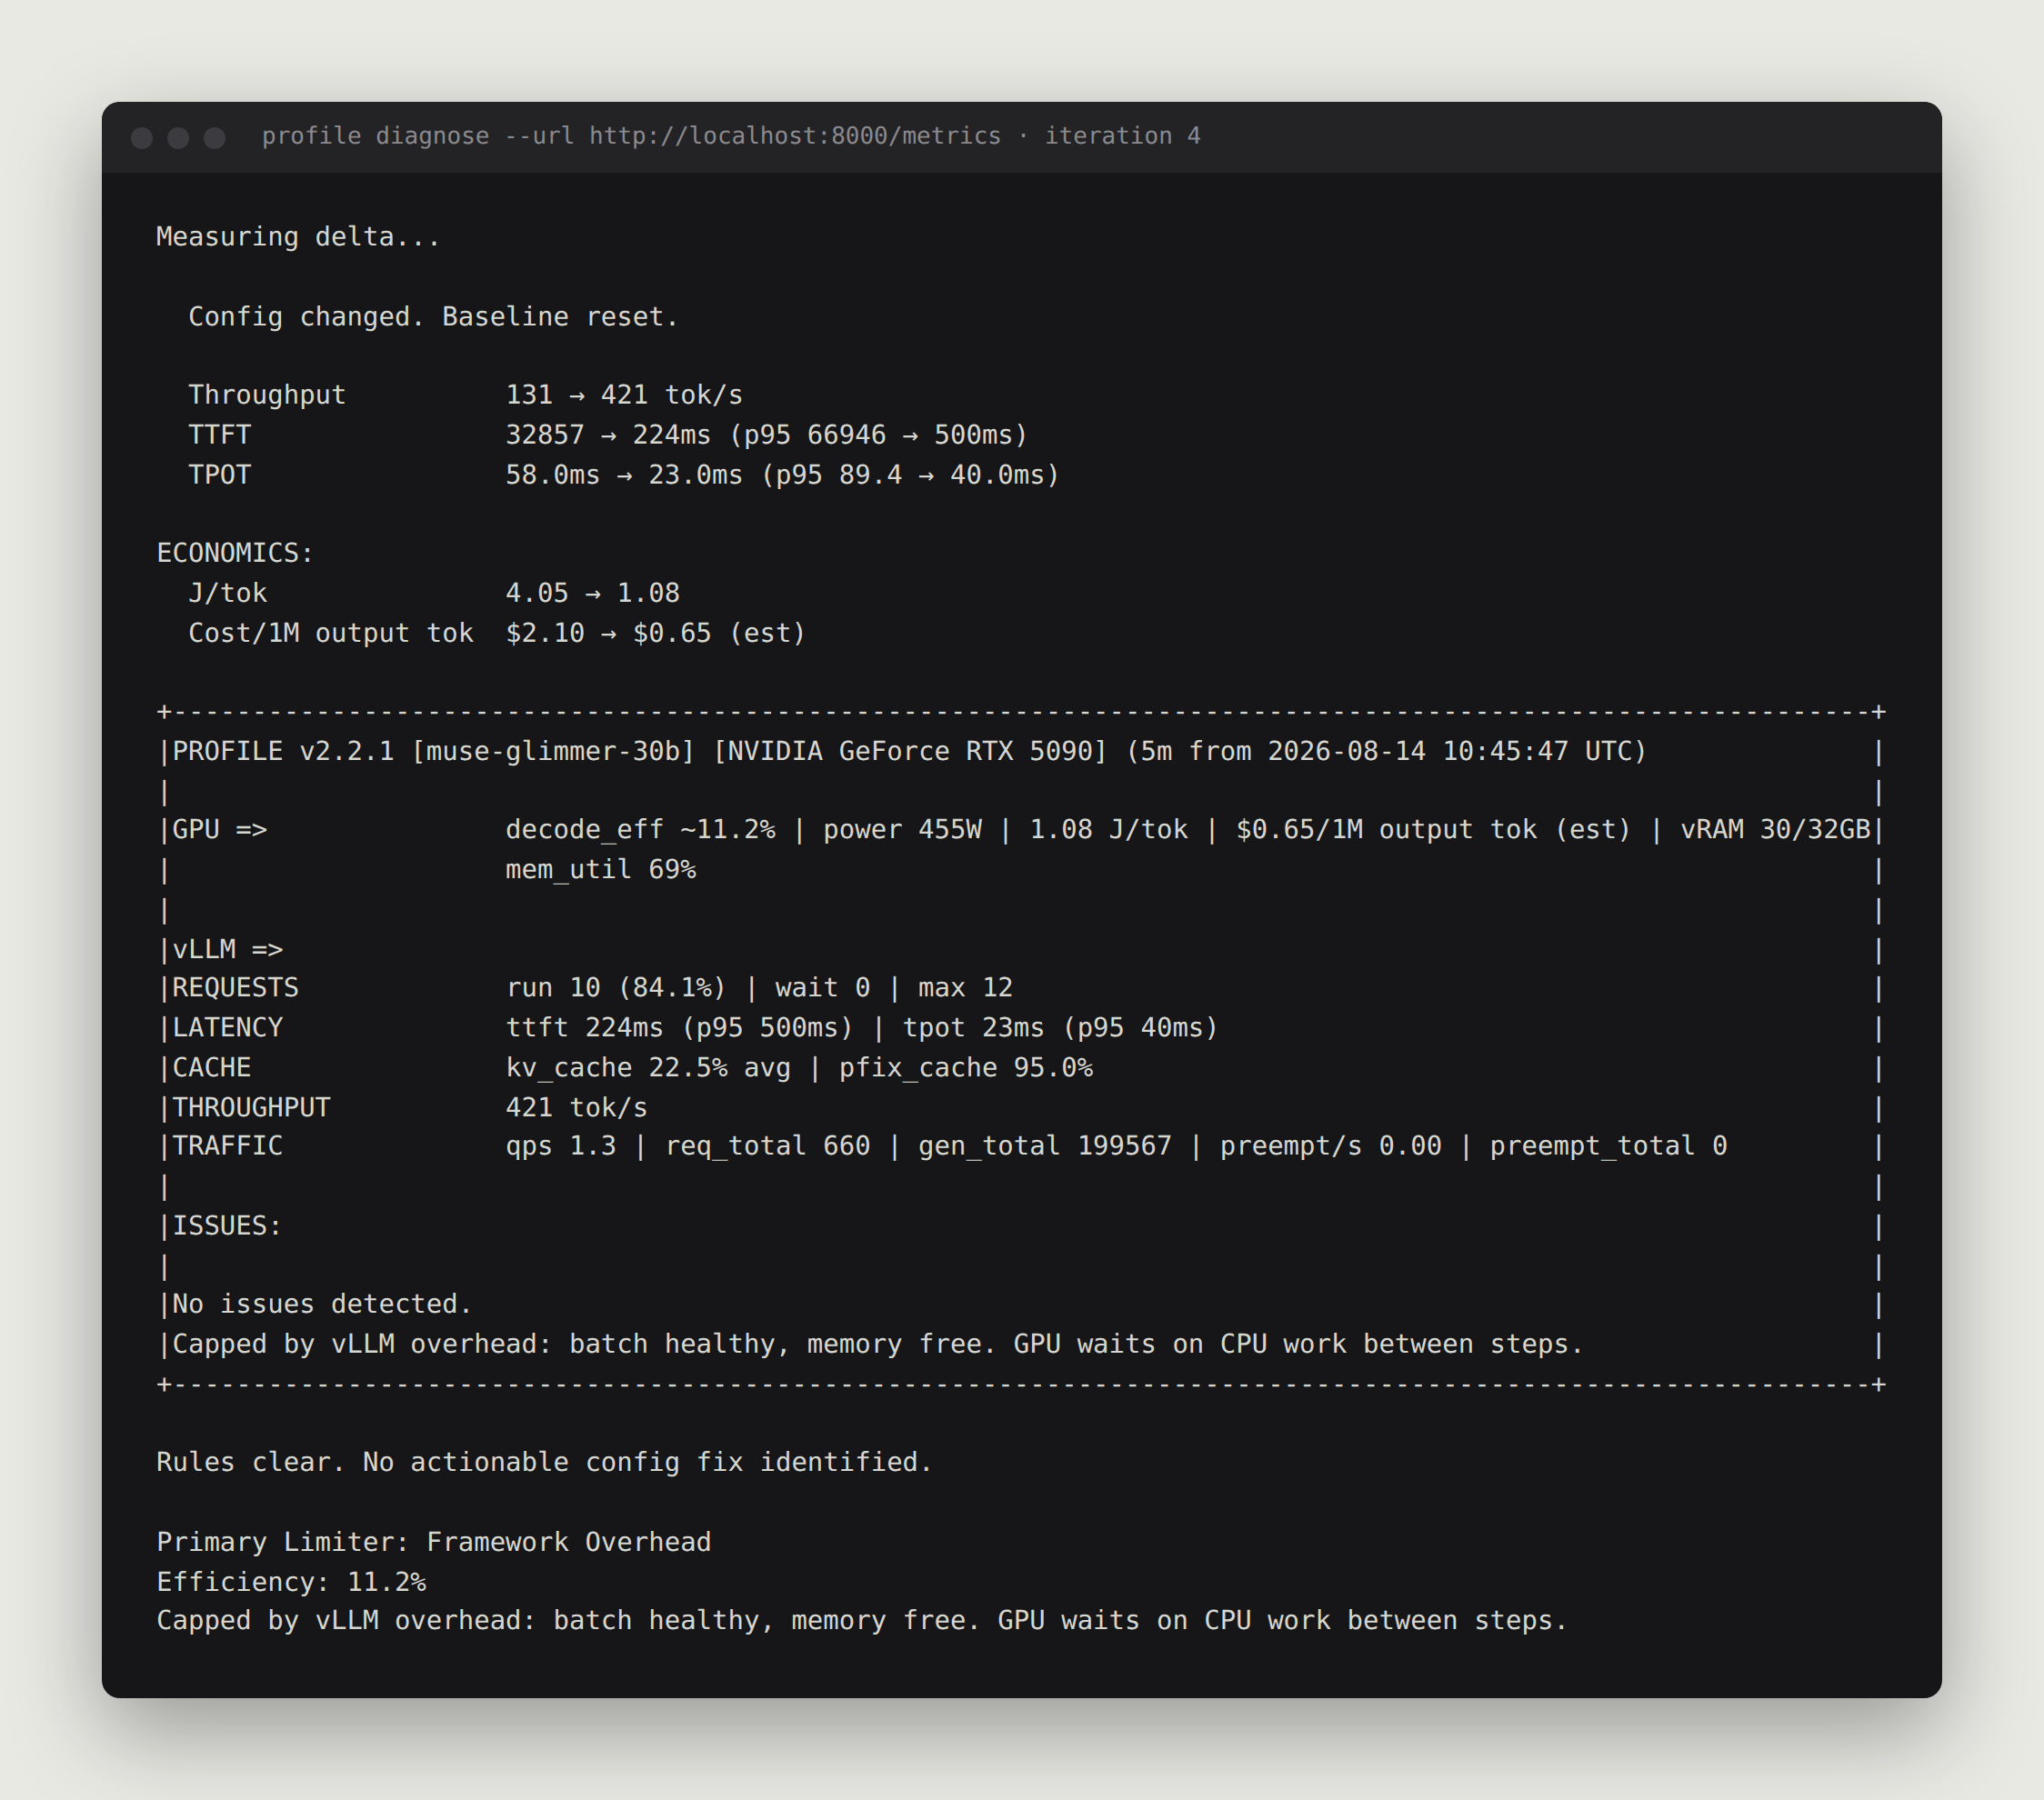
Hi all, Profile v2.2 is out. It's an open-source optimizer for inference servers. It computes your GPU's roofline ceiling, measures your live server against it, names the bottleneck, gives the flag. You apply. It re-measures. Every fix answers to a number. vLLM only today. More engines next. This release: core rule engine rewritten. Eight rules on a priority DAG with mutual exclusivity. Five alarms fire, four echoes are silenced, one true cause survives. Deterministic. AMD cards are now supported too. Tuning today is chaos: try a flag, wait, squint at a dashboard, repeat for days. Profile turns it into deterministic engineering: measure, fix, verify. Results in a few iterations. Mine took 4, ~30 minutes. My setup: RTX 5090, muse-glimmer 30B, SWE-Bench agents, no DFlash spec decoding. • 81 → 421 tok/s at 25k ctx • $3.41 → $0.65 per 1M output tok • TTFT 224ms (p95 500ms), TPOT 23ms at end of run • 4.72 → 1.08 J/tok https://preview.redd.it/4vazyxkcq6kh1.png?width=2248&format=png&auto=webp&s=77923a489b6f725240d23a7953150b5779260734 One iteration regressed hard: KV thrashing, TTFT 32.8s. Profile labeled it worse. Next fix recovered it. Regressions stay in the record. Watc
Reddit post · Local & open models
Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.
Site · Local & open models
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Kyle Hessling
@KyleHessling1
First impressions on Muse Glimmer! It's incredibly fast for a dense model, currently running an average of 208tps with a max of 274tps on a single 5090 with their DFLASH config. Comparatively, though, both using Open Code, Qwopus Coder (with thinking off) produced a much
X post · Local & open models· ♥ 176
A llama.cpp container that serves Muse Glimmer 30B with vision and DFlash on an RTX 5090, reporting 98.8 tok/s single-stream and about 250 tok/s aggregate with 131k context.
GitHub · Local & open models

LMSYS Org
@lmsysorg
@AIatMeta's Muse Glimmer (30B dense, open-weights) launches with SGLang day-0 support. We got ~230 tok/s on a single RTX 5090, with NVFP4 + DFlash on. It also works out of the box on @NVIDIAAIDev RTX Pro 6000, DGX Spark, and MLX for Mac. Speed and reliability have always been
X post · Local & open models· ♥ 129
Benchmarked Muse Glimmer 30B on my RTX 5090 (32GB), 262k context, UD-Q5_K_M + dflash-kquant + mmproj. Workload Stock master + DFlash ngram-simple PR #26842 + DFlash Code patch 78 t/s 57 t/s 220-253 t/s Mixed agent turn 77 t/s 68 t/s 188-213 t/s Tool-call JSON 71 t/s 75 t/s 155-181 t/s Heavy reasoning 52 t/s 58 t/s 120-130 t/s PR #26842 moves the DFlash draft argmax from CPU to GPU, which was the bottleneck. I cherry-picked it onto master (it branched before the Muse merge, one conflict to resolve manually) and it builds clean. Code generation now matches Meta's published 233 t/s, which I could not reproduce on stock master. Notes: • ngram-simple loses to DFlash on every coding workload. • Server caps context at the model's metadata context_length, use --override-kv for 262k. • The reasoning budget flags do not work with this template. This is verified: with the budget set to 64, the model still burned 2000+ chars thinking and the budget message never appeared. Leave max_tokens headroom for the reasoning block. Flags: llama-server ^ --model Muse-Glimmer-30B-UD-Q5_K_M.gguf ^ --mmproj mmproj-kquant.gguf ^ -c 262144 --parallel 1 ^ --override-kv "muse-glimmer.context_le
Reddit post · Local & open models

SGLang
@sgl_project
SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer. ~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX. Huge thanks to the NVIDIA and Meta teams for the
X post · Local & open models· ♥ 95
Abid Ali Awan sets up Muse Glimmer 30B on an RTX 5090 with llama.cpp, dynamic quantization and DFlash speculative decoding, serves it locally and wires it into OpenCode to build a medical research web app.
Guide · Local & open models
These numbers were captured during a real feature implementation task in Next.js and Nest.js (adding a theme switching system across components). The structural predictability of UI/state refactoring is likely why DFlash hit such a high draft acceptance rate (~97%). Here is a quick log analysis and performance summary running Muse-Glimmer-30B (UD- Q6_K_XL) paired with DFlash (Speculative Decoding) via llama.cpp (llama-server + single RTX 5090). -ngl 99 -c 200000 --host 0.0.0.0 --port 8080 --timeout 600 --cache-reuse 256 --parallel 1 --flash-attn on --spec-type draft-dflash --spec-draft-n-max 16 --spec-draft-p-min 0.7 --spec-draft-ngl 99 --cache-type-k q8_0 --cache-type-v q8_0 --no-webui --load-mode none --cache-ram 12192 --temperature 0.8 --top-k 30 --top-p 0.95 --min-p 0.05 --repeat-penalty 1.1 --repeat-last-n 64 --reasoning on --chat-template-kwargs {"enable_thinking":true} Compared to Qwen 3.6 27B: No Chinese language-mixing bugs, no overthinking loops, and concise responses. Its lighter memory footprint at Q6 also freed up more VRAM/RAM for a much larger context size. Metric Measured Value Notes Generation Speed (Peak) 100 – 287 tokens/sec Average ~173 t/s across all ta
Reddit post · Local & open models
NVIDIA's technical blog reports Muse Glimmer serving over 20K tokens/sec on a single Blackwell Ultra GPU and covers RTX 5090, DGX Spark, DGX Station and Jetson deployments.
Resource · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page


 ChatForm
 Tgmlabs