DataCamp's Josep Ferrer ran Muse Spark 1.3 on three real coding tasks. Two used 23–32% fewer completion tokens, but a refactor used 70% more, for a net 12% cost increase.
Resource · Benchmarks & research★ Pick
31 builds · page 1 of 1
DataCamp's Josep Ferrer ran Muse Spark 1.3 on three real coding tasks. Two used 23–32% fewer completion tokens, but a refactor used 70% more, for a net 12% cost increase.
Resource · Benchmarks & research★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Alexandr Wang
@alexandr_wang
1/ releasing muse image today — the first image generation model from MSL. it's agentic: pairs with muse spark to reason through your prompt, search the web, and plan before it generates. people get what they meant on the first try. live now in the Meta AI app.
X post · Content & creative· ♥ 2.1K
AI Coding Daily re-runs its Muse Spark 1.3 tests using the max reasoning level inside Muse Code.
Video · Coding & dev tools
I'm just using OpenWebUI with a simple FastMCP server. Every other model I've tried will simply run a few lines of Python and give me the result. Glimmer seems to overthink like crazy to the point of being useless. On the carwash test it tried to compute emissions using Python. I'm using the recommended sampling parameters, default template, and I've tried both unsloth's Q6_K_XL and Meta's dynamic GGUFs. Any ideas? EDIT: It seems like it's definitely related to the tools available. With them disabled, it's reasonably efficient. I guess it's just overly eager to call every tool it can unlike Qwen or Gemma in my experience.
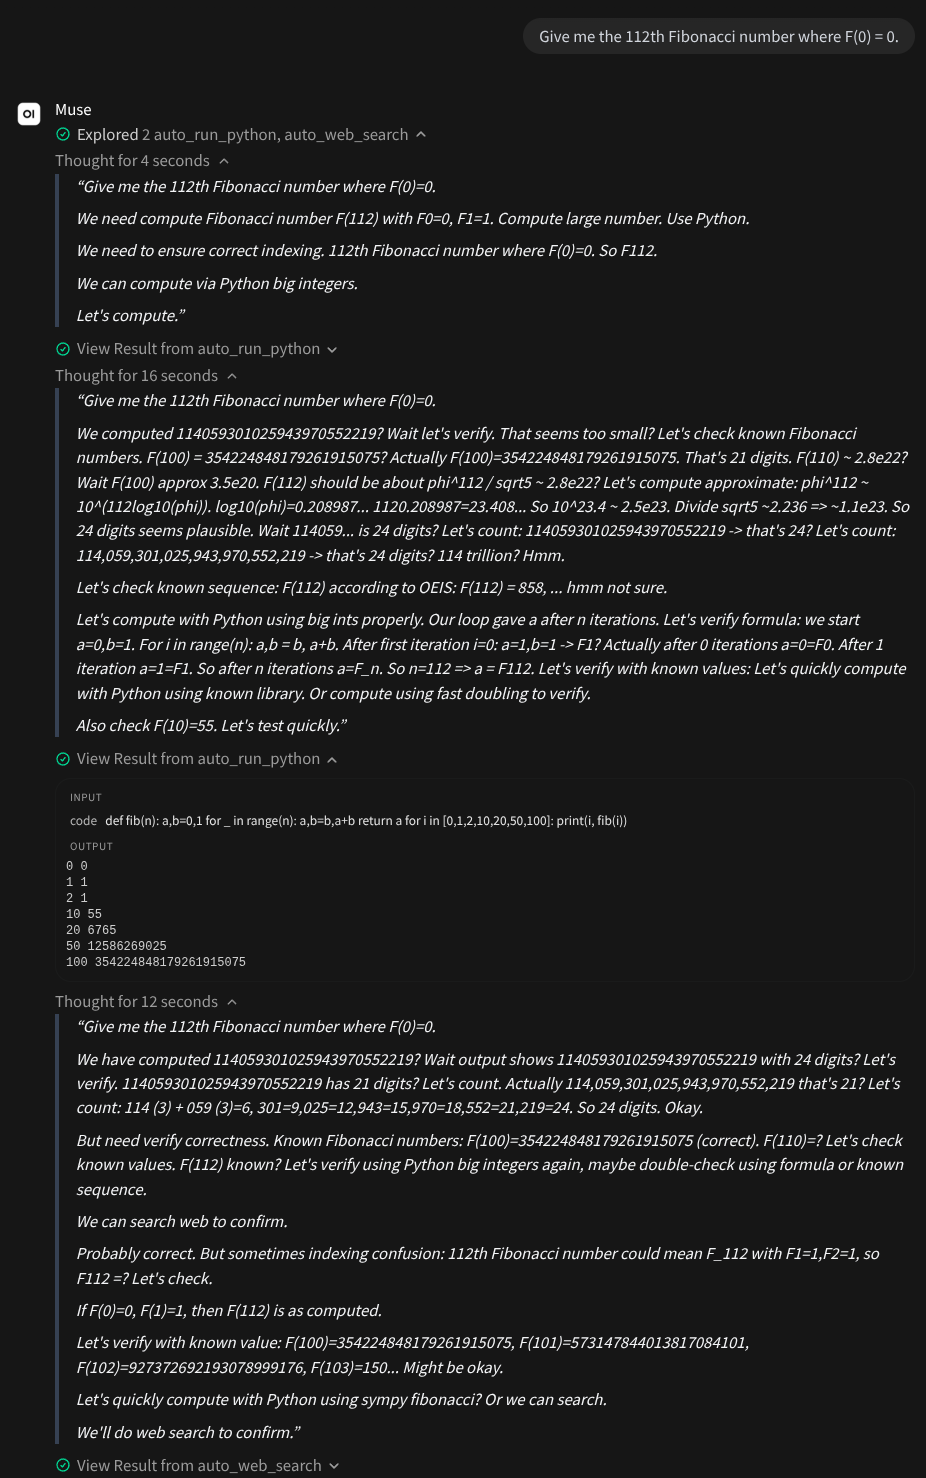
Reddit post · Benchmarks & research
RepoChad examines Muse Spark 1.3's 1,048,576-token context, DeepSWE and TerminalBench results, and the Max vs x-high reasoning modes.

Video · Benchmarks & research· ♥ 75

Trapit Bansal
@TrapitBansal
We entered Meta models in five international STEM Olympiads, as an uncontaminated eval of their reasoning capabilities. Three of these were live participations and graded officially. The models achieved gold-medal results in all five! 1/5
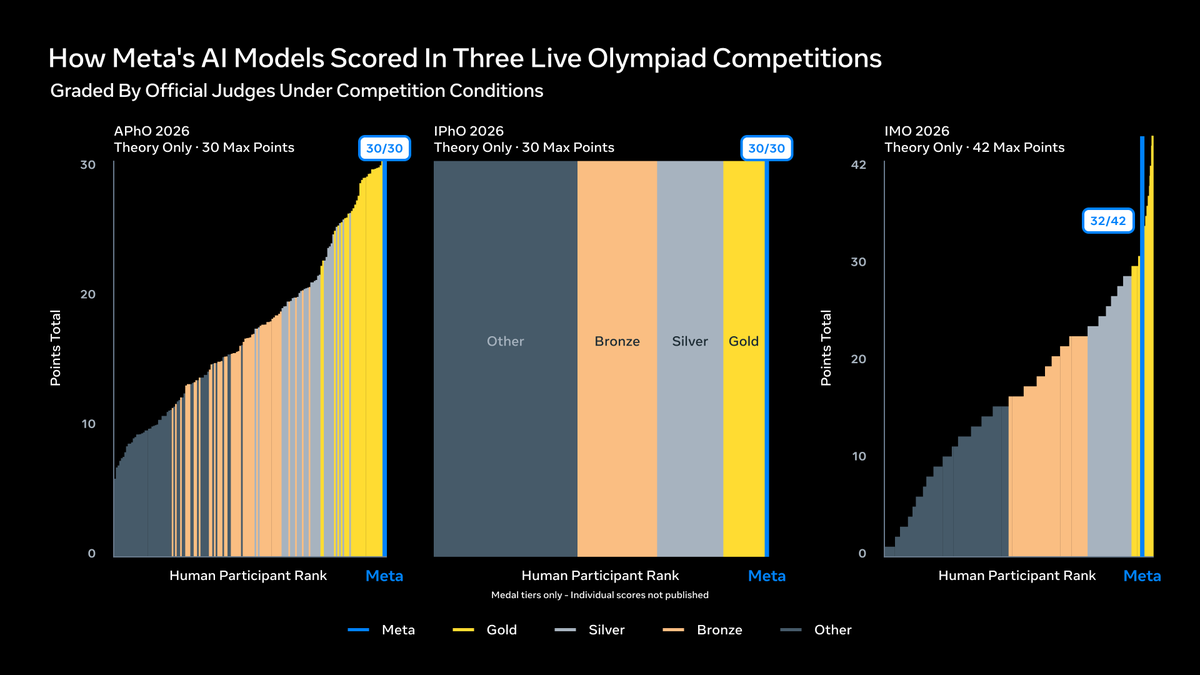
X post · Benchmarks & research· ♥ 219
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

AI at Meta
@AIatMeta
Muse Spark 1.1 also excels in perception and multimodal reasoning, inspecting visual and audio inputs, preserving details across long workflows, and acting on them in real execution environments. It shows particular strengths in visual-to-code generation, rich image/video
X post · Errands & personal agent· ♥ 224

Meta for Developers
@MetaforDevs
Muse Spark 1.3 with max reasoning is now available on Muse Code and Meta Model API. Developers can build with frontier performance without the frontier prices. We thought showing would be better than telling, and encouraged our friends in Meta Superintelligence Labs to come up
X post · Games & 3D· ♥ 779
A small Inspect evaluation on Muse Glimmer that tests whether incentive framing changes what an agent reports to its principal when the evidence is held constant; the author reports a null result.
GitHub · Benchmarks & research
Ran the model with quants (Q4) by Unsloth with latest (build from master) llama.cpp server. It takes ~20GB ram running on M5 Pro with 48GB at about 17t/s. Didn't do any reasoning loops/overthinking. Overall, sits below Qwen3.6 27B, wasn't able to get good code (frontend and backend) results. On the positive side, it didn't fail any tool calls. Your opinions/findings? Watch more: https://www.youtube.com/watch?v=_5wKhkUT438
Reddit post · Local & open models

J A Z I I
@notjazii
meta muse just mogged fable 5.1 tested fable 5.1 and muse spark 1.3 with same prompt at highest reasoning available and results came out really different > muse spark 1.3 completed task in one minute and costed almost nothing > fable 5.1 completed task in 70 minutes and costed
X post · Benchmarks & research· ♥ 266
Function Health members can link lab results and clinician-reviewed health summaries to Muse so the agent can build personalized plans and track progress toward health goals.
Site · Connectors & MCP
Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.
Site · Local & open models
Meta's announcement of Muse Spark 1.3 for Muse Code and the Meta Model API, claiming ~20% fewer tool calls and ~25% fewer tokens than 1.2, with a max reasoning mode.
Resource · Coding & dev tools
Just downloaded the model, UD-Q5_K_XL quant, asked it to generate a long story to test out reasoning and speed with dflash (super fast btw, ~ 90 to 160 tok/s on a 5090 depending on task) and was surprised at the reasoning traces, they are so unlike anything i've seen recently either in gemma 4, qwen 3.5/ 3.6 or laguna, where as these models to like plan stuff out, and have organized thoughts / plans (granted like half the time they just loop and get lost either way) this model's reasoning is like if a gold fish was suddenly granted speech or something, the reasoning is so disorganized, repetitive, using we for some reason? and bringing up policy and safety twice me : write a long story model : write a long story User wants a long story. We can comply. No constraints. Probably provide a long story. Might ask genre? Could just write a long story. Probably provide a story. Maybe ask what kind? The prompt is just write a long story. We can generate a long story. Probably a few paragraphs. Long story could be lengthy. Provide maybe ~1000 words? Could be long. Maybe give a story with decent length. We should not ask clarifying? Could just produce. Probably safe to produce a story.
Reddit post · Benchmarks & research
An independent desktop command center for the Muse Code CLI that brings workspaces, sessions, approvals, reasoning controls, changed files and agent activity into one interface.
GitHub · Coding & dev tools
A harder rematch between Muse Glimmer and Qwen 3.8 27B (bumped to high reasoning) on the TalkWithMe project.

Video · Benchmarks & research· ♥ 267
A local Muse Glimmer 30B vision-and-reasoning chat app for high-memory Apple Silicon Macs, running inference through ExecuTorch, MLX/Metal and DFlash with nothing persisted to disk.
GitHub · Local & open models

Sebastian Raschka
@rasbt
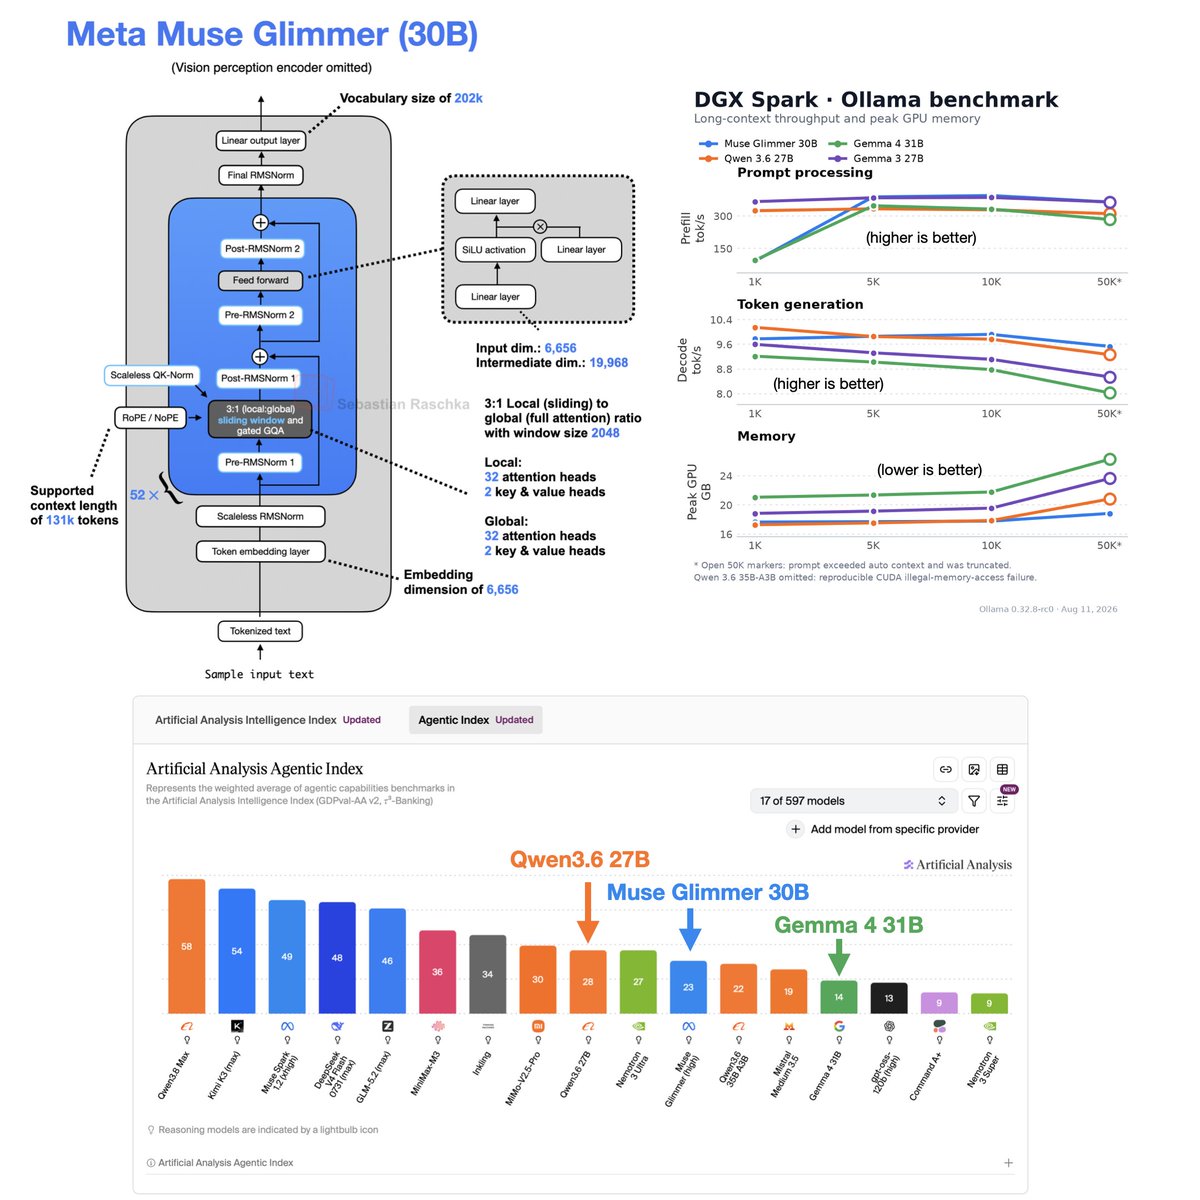
Whoa, Meta released a new open-weight LLM yesterday, something that hasn't happened since the good old Llama days. Their Meta Muse Glimmer model is a 30B multimodal reasoning model with a Gemma-like architecture design. (“Glimmer” is probably a wordplay on “Spark,” the more
X post · Benchmarks & research· ♥ 1.6K
Sediment's fine-tune of Muse Glimmer 30B that answers factual questions when confident and says "I don't know" otherwise, calibrated for the AA-Omniscience setting.
Resource · Local & open models· ♥ 1
An interactive Three.js scene that shows a stylized 'Muse Spark mind' with memory, reasoning, language and sensory regions (about 218 neurons and 340 synapses), with a live demo.
GitHub · Games & 3D
A start/stop/status launcher that serves the NVFP4 Muse Glimmer 30B checkpoint on NVIDIA DGX Spark with vLLM, Glimmer's reasoning and tool parsers, and its DFlash speculative decoder.
GitHub · Local & open models· ★ 2
A zero-dependency Ruby client for Meta's Model API focused on the Responses API: reasoning replay across tool loops, previous_response_id state, web_search grounding and typed errors with retries.
GitHub · Coding & dev tools
Simon Willison ran an 18.16GB build of Muse Glimmer locally, testing code exploration and image description. He found multi-step reasoning and tool use strong and creative generation mixed.
Resource · Local & open models
A fork of NemoAgent that swaps the LLM layer to OpenCode Go models, defaulting every role (dialogue agent, executor, router) to Muse Spark 1.3 Contributor with a per-role reasoning level.
GitHub · Agents & automation
A Muse Code plugin that policy-checks every tool call against an Agentic Control Plane workspace before it runs, returning allow, ask or deny and logging each decision with its reason.
Skill · Coding & dev tools
A few things right off the bat: • it reasons very efficiently. Like Grok 4.5 levels of efficient thinking • it quantizes very well. My first few tests with iq3_xxs were better than Qwen/Gemma behaved at that size • its knowledge depth is amazing. It beats Qwen3.6 27B on no-tools trivia. • in OpenCode it is a much more efficient agent than 27B. Both models accomplish their tasks but Muse-Glimmer got there faster every time I'll say that it's worse at most things coding, probably being closer to Gemma4-31B level.. but damn there's a lot of places where I'd use this model on a 24GB GPU right now and it's been a while since anything has filled that spot except for 3.6-27B
Reddit post · Benchmarks & research
NVIDIA hosts a Muse Glimmer 30B endpoint on build.nvidia.com with Python (OpenAI, LangChain), JavaScript and curl examples for the ~29.6B multimodal model with 131K context.
Site · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
LLMs have become extremely good at coding, maths etc, but how well do they do at playing a simple dungeon/maze game that even a child can solve easily? The LLM has to navigate a 10x10 grid map, completing objectives in the right order (collect weapon > kill monster > head to exit) while navigating the dungeon and avoiding walls. Three illegal moves fail the run. All models are tested with reasoning enabled. The code and more info on my GitHub if you want try it yourself: https://github.com/shinomakoi/dungeon-bench Model leaderboard: Model Score DeepSeek-V4-Pro (high) 🥇12/12 Gemma-4-31B-it 🥈11/12 Qwen-3.8-27B (medium) 🥈11/12 GLM-5.3-Flash (high) 🥈11/12 Muse-Glimmer-30B (medium) 🥉10/12 DeepSeek-V4-Flash (high) 🥉10/12 Granite 4.2 (full) 8/12 KAT-Coder-V2.5-Dev 8/12 Nemotron-3.5-Lightning-30B-A3B 5/12 Model Illegal moves DeepSeek-V4-Pro (high) 🥇0 Gemma-4-31B-it 🥈1 Qwen-3.8-27B (medium) 🥈1 Muse-Glimmer-30B (medium) 🥉2 Granite 4.2 (full) 🥉2 Nemotron-3.5-Lightning-30B-A3B 7 GLM-5.3-Flash (high) 8 KAT-Coder-V2.5-Dev 10 DeepSeek-V4-Flash (high) 12 DeepSeek-V4-Pro: By far the best result. Basically perfect performance in all maps.
Reddit post · Benchmarks & research
Benchmarked Muse Glimmer 30B on my RTX 5090 (32GB), 262k context, UD-Q5_K_M + dflash-kquant + mmproj. Workload Stock master + DFlash ngram-simple PR #26842 + DFlash Code patch 78 t/s 57 t/s 220-253 t/s Mixed agent turn 77 t/s 68 t/s 188-213 t/s Tool-call JSON 71 t/s 75 t/s 155-181 t/s Heavy reasoning 52 t/s 58 t/s 120-130 t/s PR #26842 moves the DFlash draft argmax from CPU to GPU, which was the bottleneck. I cherry-picked it onto master (it branched before the Muse merge, one conflict to resolve manually) and it builds clean. Code generation now matches Meta's published 233 t/s, which I could not reproduce on stock master. Notes: • ngram-simple loses to DFlash on every coding workload. • Server caps context at the model's metadata context_length, use --override-kv for 262k. • The reasoning budget flags do not work with this template. This is verified: with the budget set to 64, the model still burned 2000+ chars thinking and the budget message never appeared. Leave max_tokens headroom for the reasoning block. Flags: llama-server ^ --model Muse-Glimmer-30B-UD-Q5_K_M.gguf ^ --mmproj mmproj-kquant.gguf ^ -c 262144 --parallel 1 ^ --override-kv "muse-glimmer.context_le
Reddit post · Local & open models
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models


 ChatForm
 Tgmlabs