shipwithmuse

Entries matching “laptop”

7 builds · page 1 of 1

U

PyaesoneP

u/PyaesoneP

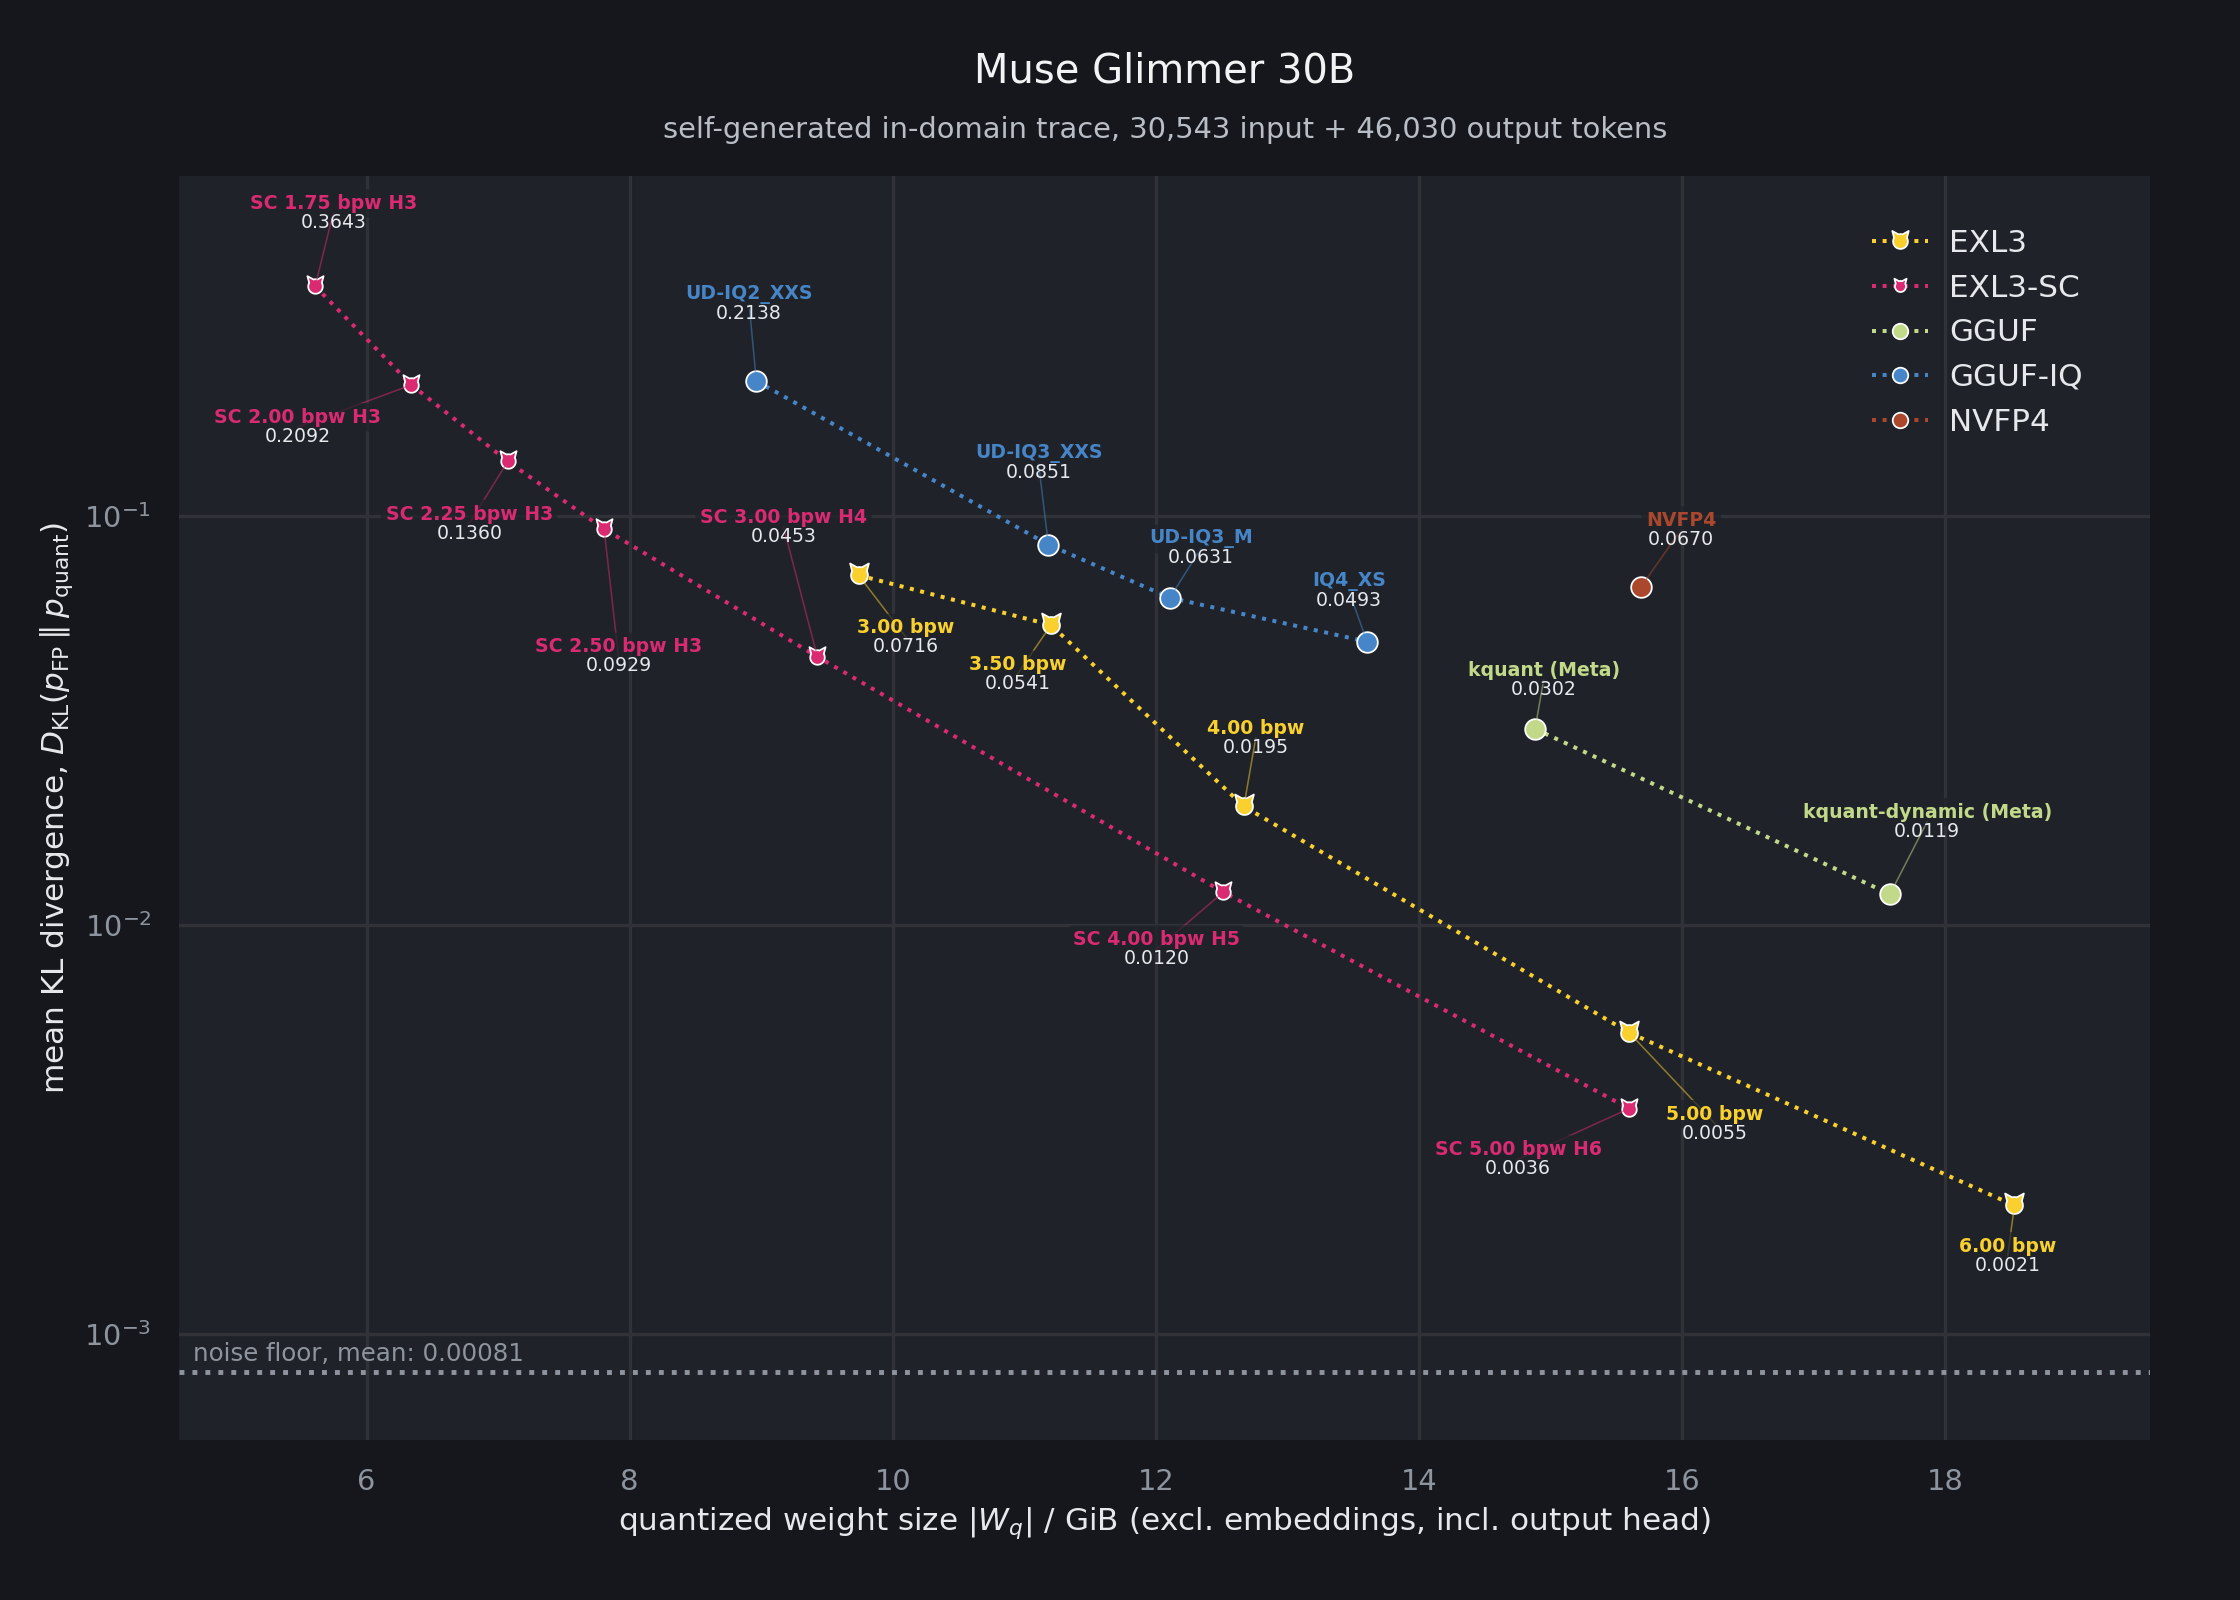
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop. It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster. I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.
Reddit post · Local & open models★ Pick

Muse Glimmer 30B on a 12GB laptop GPU

@TanayYadavDev

@TanayYadavDev

An always-on laptop voice companion: local Porcupine wake word, local Whisper speech-to-text in Hindi and English, Muse Spark via the Meta Model API as the brain, offline TTS and local conversation memory.

GitHub · Agents & automation

Ziggy, a 24/7 voice assistant on Muse Spark

boymanrobshit

@boymanrobshit

Getting a ton of utility out of Muse. This may take a minute to catch on because it’s truly a modality shift but here is what I used it for so far. - optimized my credit card rewards. No less than 1000 bucks saved so far. I have five expensive credit cards. I have no idea

X post · Errands & personal agent· ♥ 113

Credit card rewards optimized across five cards

@krtarunsingh

@krtarunsingh

An experiment running Muse Glimmer 30B Q4_K_M via llama.cpp on an RTX 4060 laptop with 8 GB VRAM, testing autonomous Python bug fixing, tool-failure recovery and multimodal invoice extraction.

GitHub · Local & open models

Muse Glimmer on an 8 GB RTX 4060 laptop

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

U

37Scorpions

u/37Scorpions

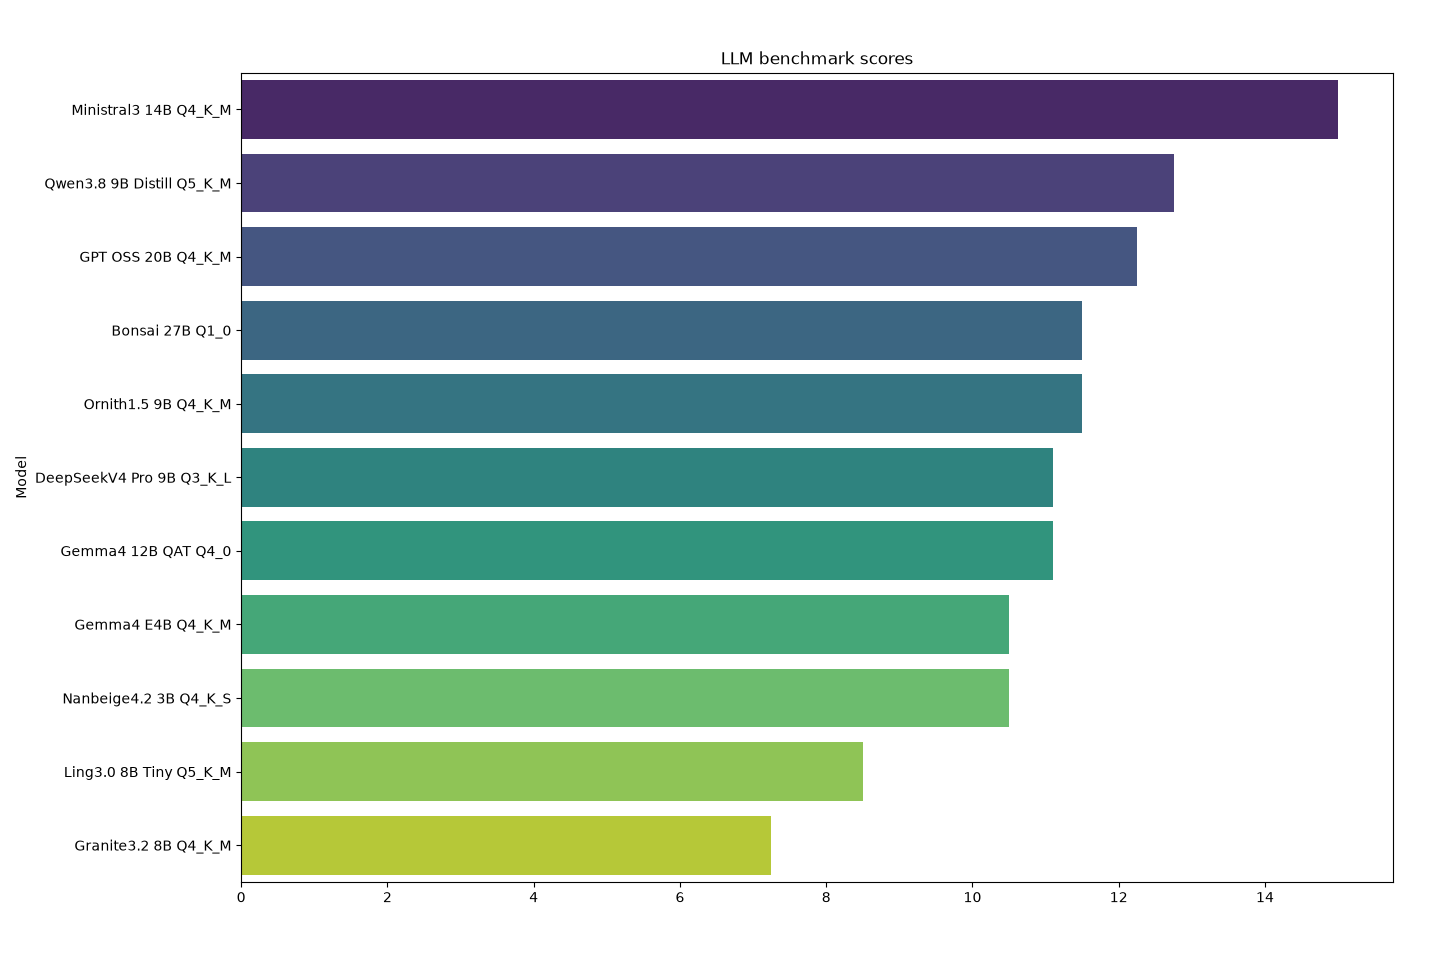
IMPORTANT This post is meant to provide info regarding the best local models to run on CONSUMER HARDWARE. I am on an RTX 4060 with 8GB VRAM, 16GB of RAM and I am benchmarking models that can run on my computer. If you have sunk several thousands into graphics cards you won't find these statistics much useful. This post is for all the people who can't just install Qwen3.8 27B and call it a day. Additionally, I am not an LLM benchmarking expert. I am a hobbyist and occasional LLM user trying to extract useful information for both me and people on similar hardware. Context For the past few weeks I have been doing some benchmarks of some LLMs that can run on my laptop which only has 8GB VRAM and 16GB RAM. I was mostly toying around while trying to get some useful data about what the best model is for local inference on consumer hardware. This week I decided to make a "final" benchmark that would be way better with more questions, more question categories, newer models (a lot of people complained about the models I had benchmarked before being old but I didn't find most suggested models to be any good) and a better speed benchmark, this time using TTC (Time To Completion) as a pose to

Reddit post · Local & open models

8GB VRAM benchmark, with Glimmer as an outlier

L

lmstudio.ai

lmstudio.ai

LM Studio launched Muse Glimmer support, reporting it completed 83.3% of tasks on its 18-task BionicBench v0.1 versus 77.7% for Gemma 4 31B and Qwen 3.6 27B.

Resource · Local & open models

LM Studio: Run Muse Glimmer locally