
Refusal-direction ablation on Muse-Glimmer-30B that cut refusals from 128/150 to 3/150, adding an agentic-safety evaluation and publishing bf16 and GGUF uncensored weights.
GitHub · Local & open models★ Pick· ★ 1
27 builds · page 1 of 1
Refusal-direction ablation on Muse-Glimmer-30B that cut refusals from 128/150 to 3/150, adding an agentic-safety evaluation and publishing bf16 and GGUF uncensored weights.
GitHub · Local & open models★ Pick· ★ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Trapit Bansal
@TrapitBansal
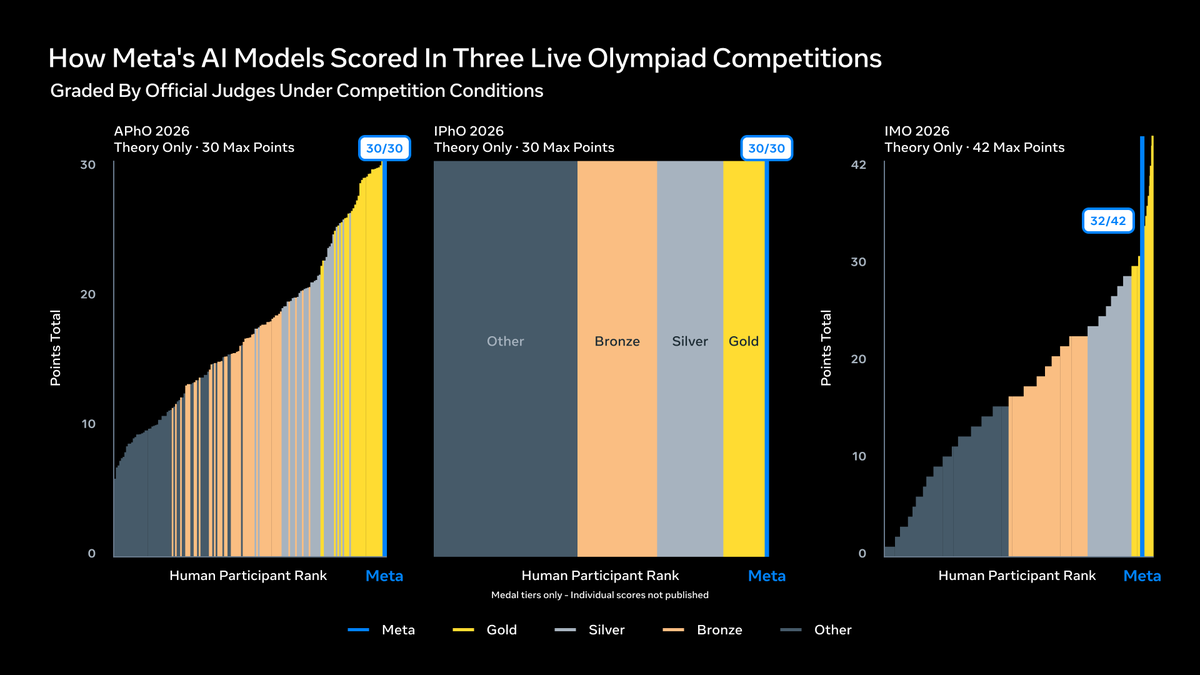
We entered Meta models in five international STEM Olympiads, as an uncontaminated eval of their reasoning capabilities. Three of these were live participations and graded officially. The models achieved gold-medal results in all five! 1/5
X post · Benchmarks & research· ♥ 219
Box's Complex Work Eval finds Muse Spark 1.1 up to 5-6 points above the top-tier composite on structured work, and nearly 30 points ahead on cost-optimization analysis.
Resource · Benchmarks & research
turboderp's self-calibrated EXL3 quants of Muse Glimmer 30B down to 1.75 bits per weight, with calibration and eval traces.
Resource · Local & open models· ♥ 14
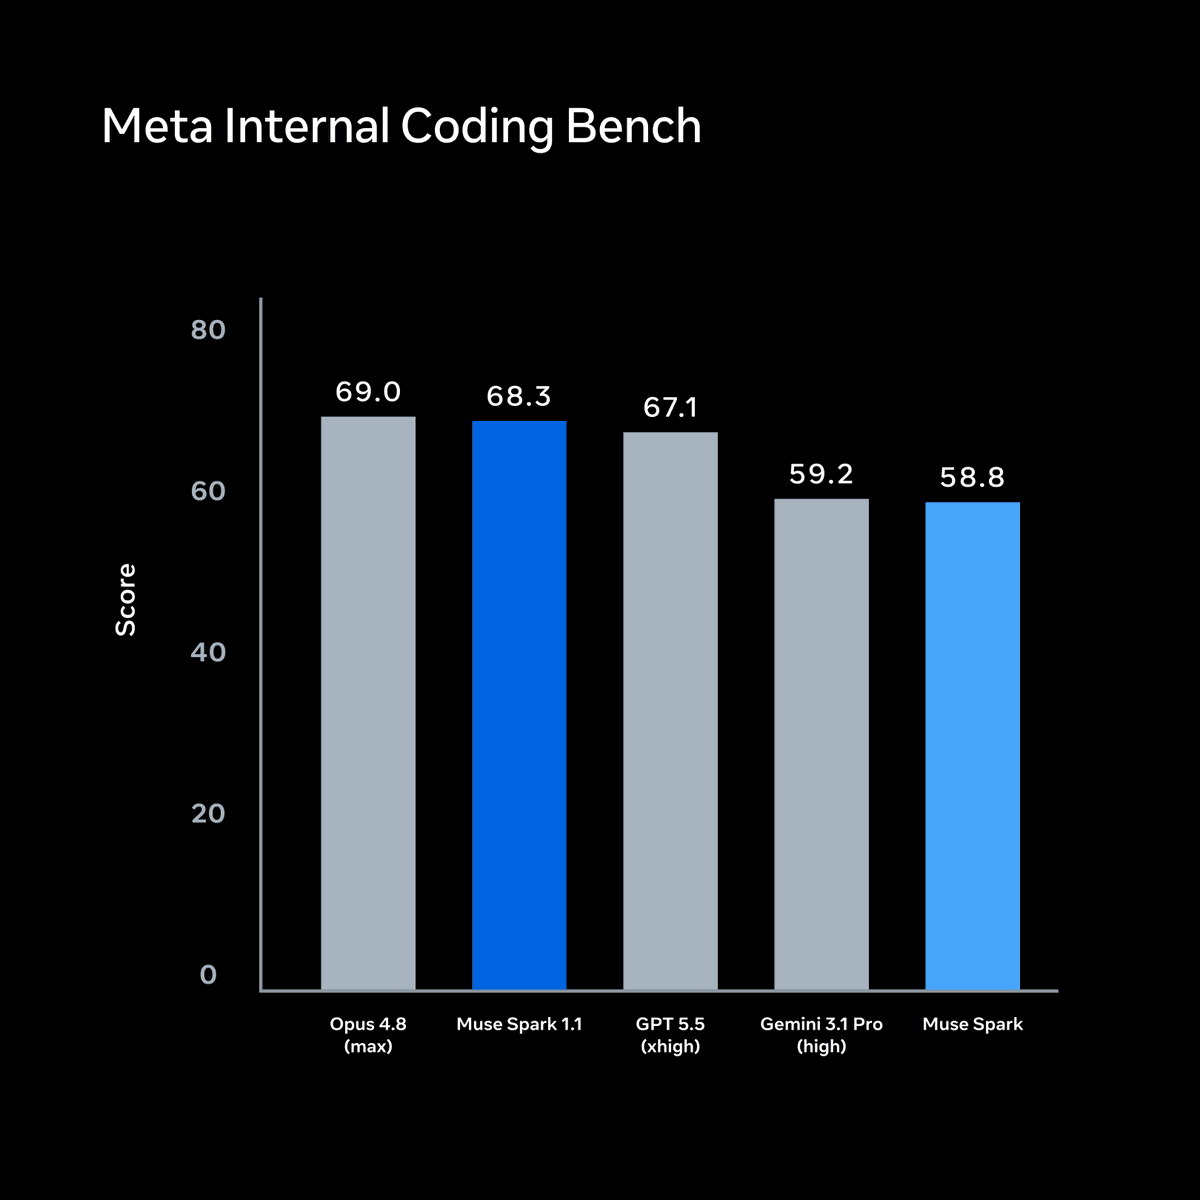
Codus reads the three benchmark charts Meta published for Muse Code and notes Claude Opus 5 wins all three, including Meta's own internal eval.
Resource · Benchmarks & research
A project that fine-tunes a DSpark speculator for Muse Glimmer 30B on on-policy coding and agentic traces to raise acceptance length on agentic workloads, evaluated with Terminal-Bench.
GitHub · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

Morgan
@morganlinton
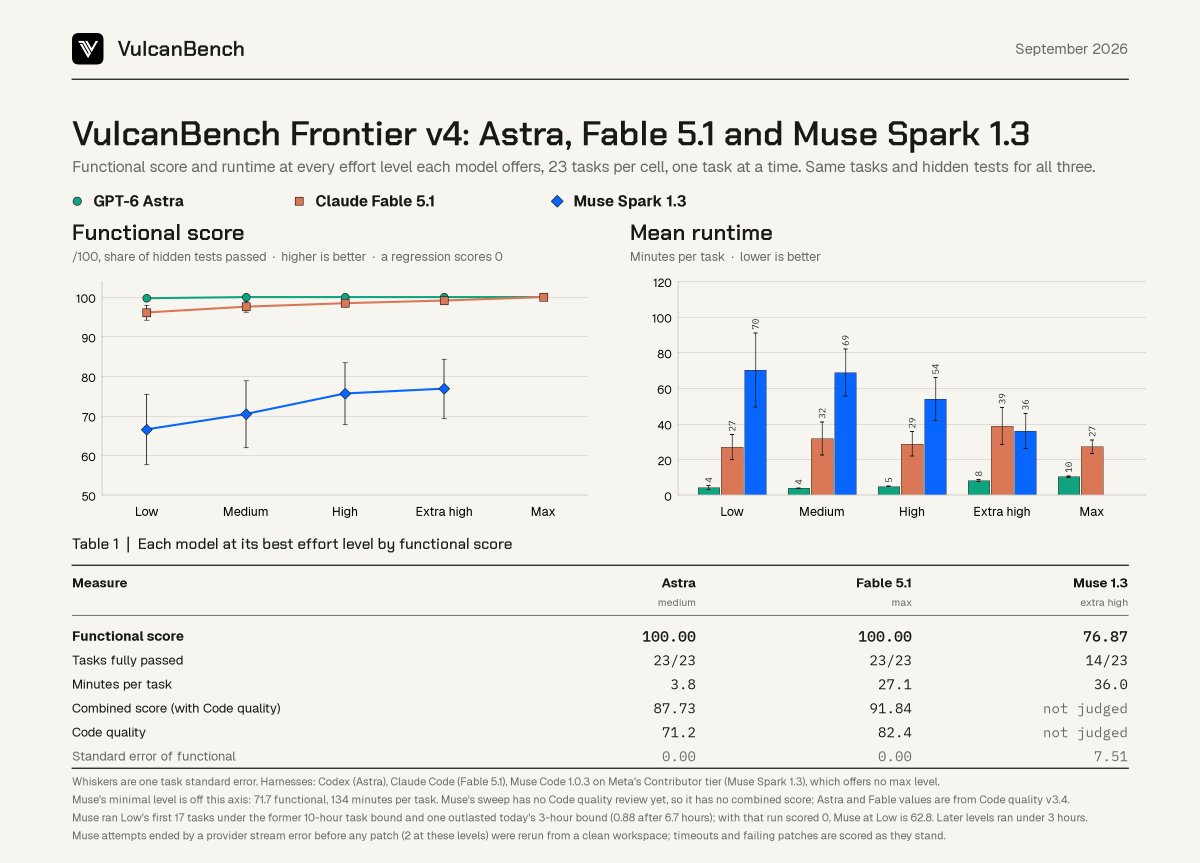
Okay, finally finished my Muse Spark 1.3 benchmark. This ended up being the longest-running benchmark I've ever done at @VulcanBench and it definitely looks like Muse has some serious issues at lower effort levels. I was able to run Astra through my v4 eval suite across every
X post · Benchmarks & research· ♥ 99

AI at Meta
@AIatMeta
Muse Spark 1.1 is used across Meta in coding and research workflows, scoring competitively with leading models on Meta's internal coding benchmark. Our researchers are now automating model development and evaluation tasks by leveraging Muse Spark 1.1 in their workflows.
X post · Benchmarks & research· ♥ 167
Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.
GitHub · Local & open models
Got Muse Glimmer 30B running locally using the UD-Q2-K-XL quant paired with DFlash speculative decoding, and the results on modest hardware are pretty impressive. Hardware Setup Host: Ryzen 5 4600G with 96GB DDR4 RAM running headless Debian Trixie. Guest VM: QEMU/KVM assigned 4 cores and 32GB RAM, running Debian Sid with ROCm 7.2. GPU: AMD Radeon RX 7600 XT 16GB passed through to the VM, built llama.cpp fresh from master targeting gfx1102 and gfx1201 via HIP. Context Size: Set to 62144 tokens. Processed 14685 total tokens at roughly 308 tokens per second prompt evaluation and 20 tokens per second generation speed. Speculative Decoding: Using the dflash-kquant draft model with spec-draft-n-max set to 2. Fed it a clean context slate consisting of eight JavaScript files and one HTML file alongside the problem description. On the first turn, it identified and output the necessary diff snippets. A quick follow-up prompt telling it to stop being lazy and output the complete updated files yielded functional code that dropped straight in and worked on the first try.
Reddit post · Local & open models
eesel AI reports Muse Spark 1.3 ranks #6 on the Artificial Analysis Intelligence Index, leads long-context and coding rows, but trails Claude Opus 5 on four of six agent evals.
Resource · Benchmarks & research
Compared diarization models on 15 mock doctor-patient consultations (~2.4 h): Meta Muse Voice Transcribe scored 13.04% DER at ~92 s per request via API, behind Pyannote (2.89%) and Nemotron 3 (4.80%).
Reddit post · Benchmarks & research
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
AI at Meta
@AIatMeta
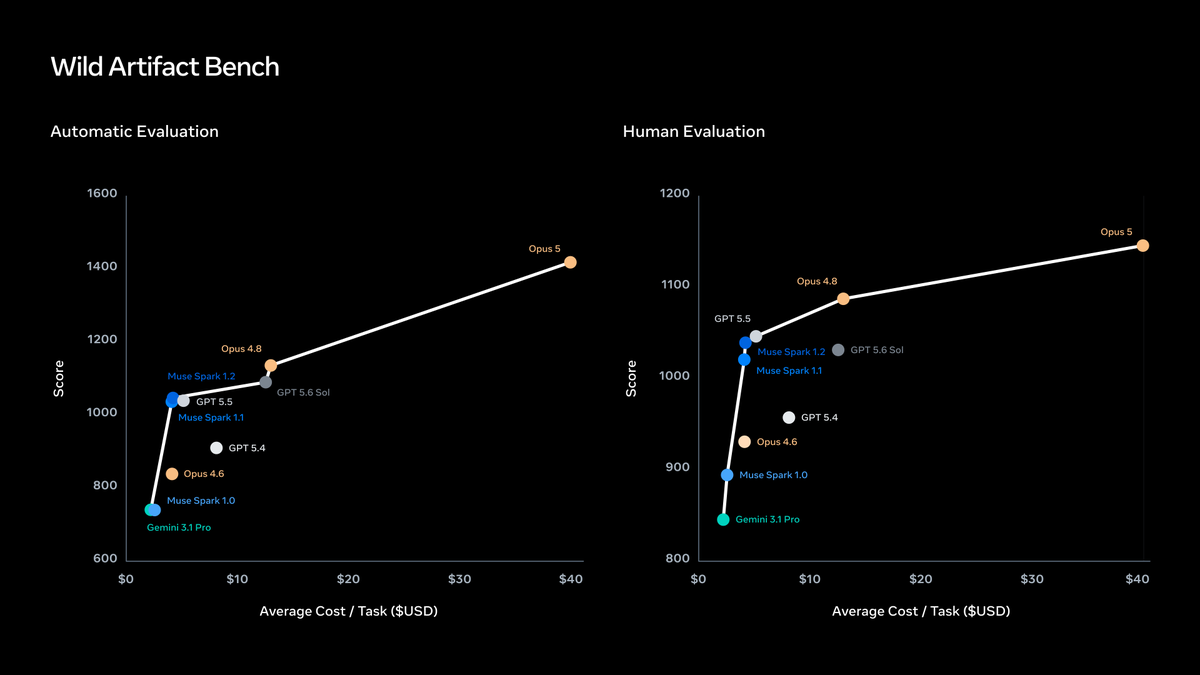
Today we’re also previewing WildArtifactBench, an internal evaluation framework designed to assess agents on complex, real-world tasks across diverse deliverable formats. By using win rates and Elo scores from human and agentic preference judges rather than strict ground-truth
X post · Benchmarks & research· ♥ 637

John Yang
@jyangballin
My favorite demo from the launch: muse spark 1.1 + opencode runs evaluation of *itself* + mini-SWE-agent (by @KLieret, @closji, urs truly) on DeepSWE!
X post · Benchmarks & research· ♥ 40

Alexandr Wang
@alexandr_wang
Muse Spark 1.1 outperforms Opus 4.8 and Grok 4.5 on some nice out of distribution evals :)
X post · Benchmarks & research· ♥ 420

Artificial Analysis
@ArtificialAnlys
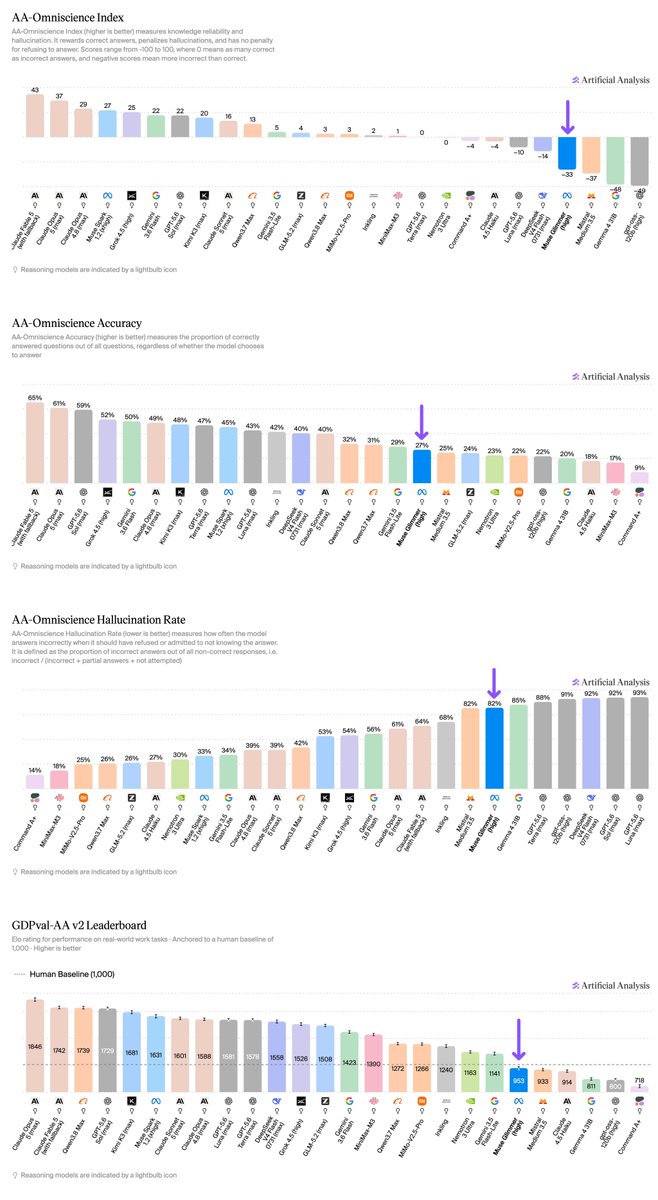
Muse Glimmer's gaps against its class concentrate in agentic evaluations: 953 Elo on GDPval-AA v2 against 1141 for Qwen3.6 27B (Reasoning), 1141 for Gemini 3.5 Flash-Lite, and 1004 for Kimi K2.5 (Reasoning), with Terminal-Bench v2.1 (52%) also behind Qwen3.6 27B (61%). The
X post · Benchmarks & research· ♥ 34
You.com's harness for evaluating Muse Glimmer 30B on DeepSearchQA with You.com MCP tools inside pi sessions. A custom RLM v5 extension reached F1 0.8054 on 50 tasks (0.6910 over 900x3) versus 0.50 for plain skill injection.
GitHub · Benchmarks & research
Solo-built GGUF line of Muse Glimmer 30B with custom calibration, per-tensor allocations and an eval harness behind every reported number.
Resource · Local & open models· ♥ 21
glimmer-cli is a local TypeScript CLI for Muse Glimmer 30B and Muse Spark 1.2 via Ollama, with stubbed tools and a reproducible tool-use eval harness.
GitHub · Local & open models
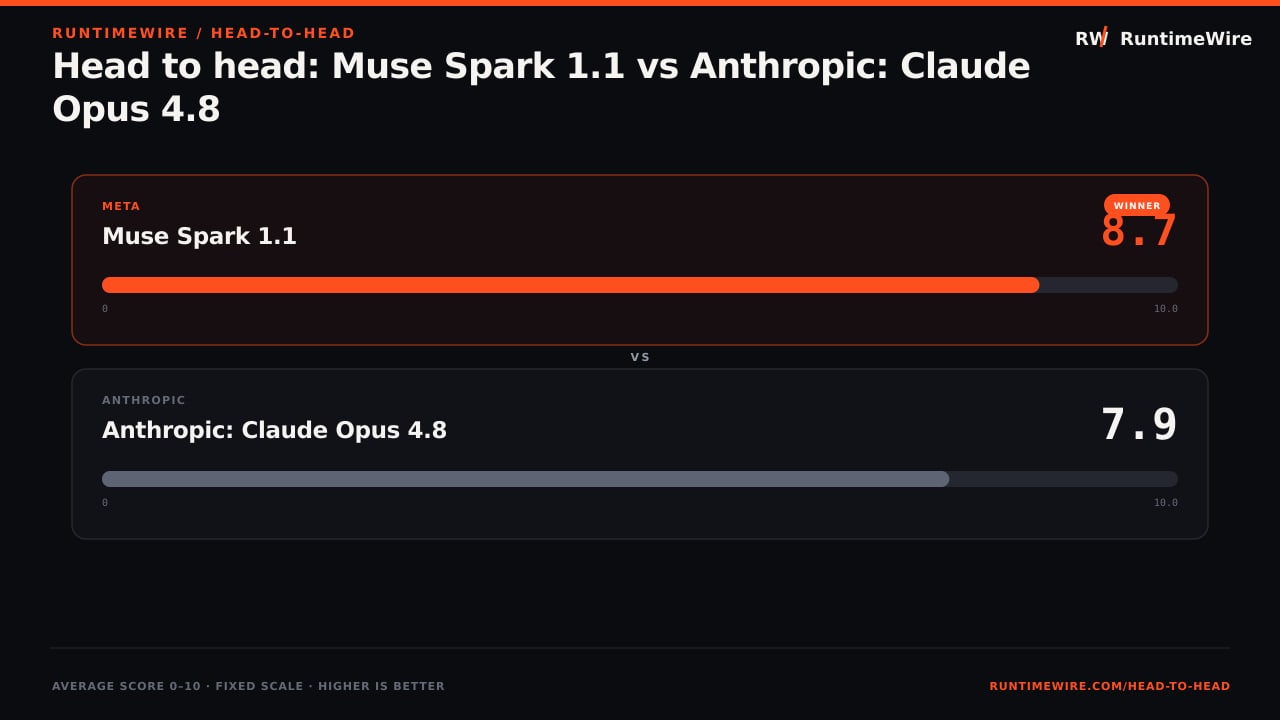
RuntimeWire's head-to-head eval has Muse Spark 1.1 beating Claude Opus 4.8 by 10 points overall with a 95% confidence verdict.
Resource · Benchmarks & research
An effort to make Muse Glimmer 30B actually use a 512k-token context (4x native) as a ~17GB GGUF in 32GB VRAM, trained on DGX Spark and evaluated with RULER-style retrieval tests.
GitHub · Local & open models· ★ 1
A small Inspect evaluation on Muse Glimmer that tests whether incentive framing changes what an agent reports to its principal when the evidence is held constant; the author reports a null result.
GitHub · Benchmarks & research
A fork of DeepSeek's DeepSpec that trains a fresh DSpark speculative drafter for Muse-Glimmer-30B in place of the shipped DFlash drafter, with the full data-to-eval pipeline working on GPU.
GitHub · Local & open models
A reproducible evaluation of a stochastic defect where Muse Spark 1.1, under some agent-like request envelopes, wrote to claude-smoke.txt when asked for muse-smoke.txt; a neutral control kept 80/80 filenames intact.
GitHub · Benchmarks & research
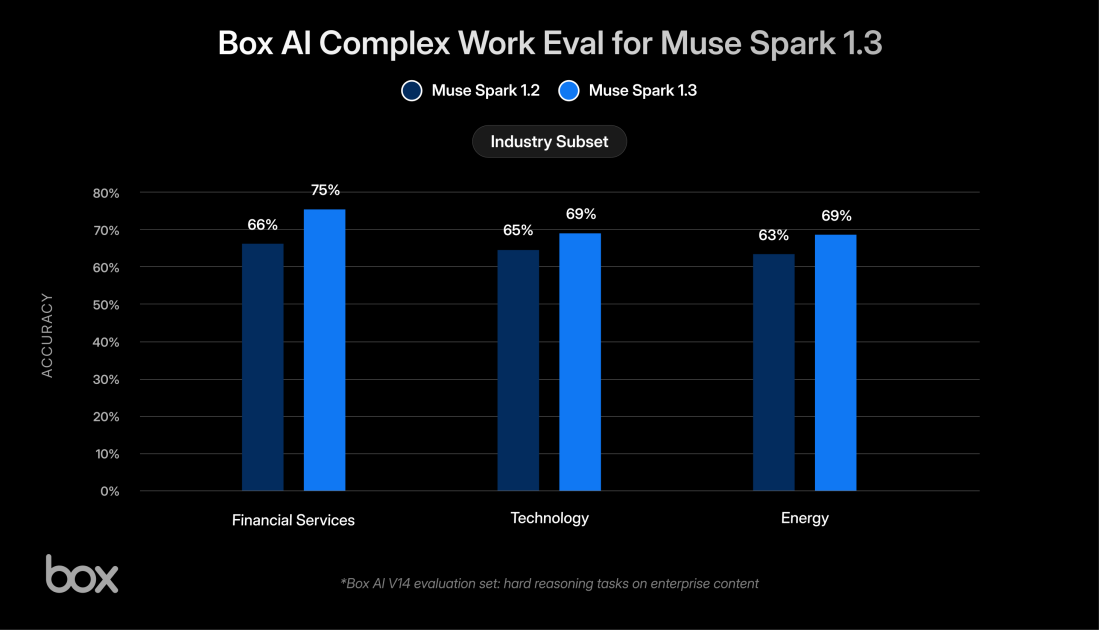
Box added Muse Spark 1.3 to Box AI, reporting it runs 42% faster than Muse Spark 1.2 with roughly a third fewer tokens, and lifts financial services accuracy from 66% to 75% on Box's eval.
Site · Business & commerce
Meta's announcement of Muse Spark 1.3 for Muse Code and the Meta Model API, claiming ~20% fewer tool calls and ~25% fewer tokens than 1.2, with a max reasoning mode.
Resource · Coding & dev tools
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.
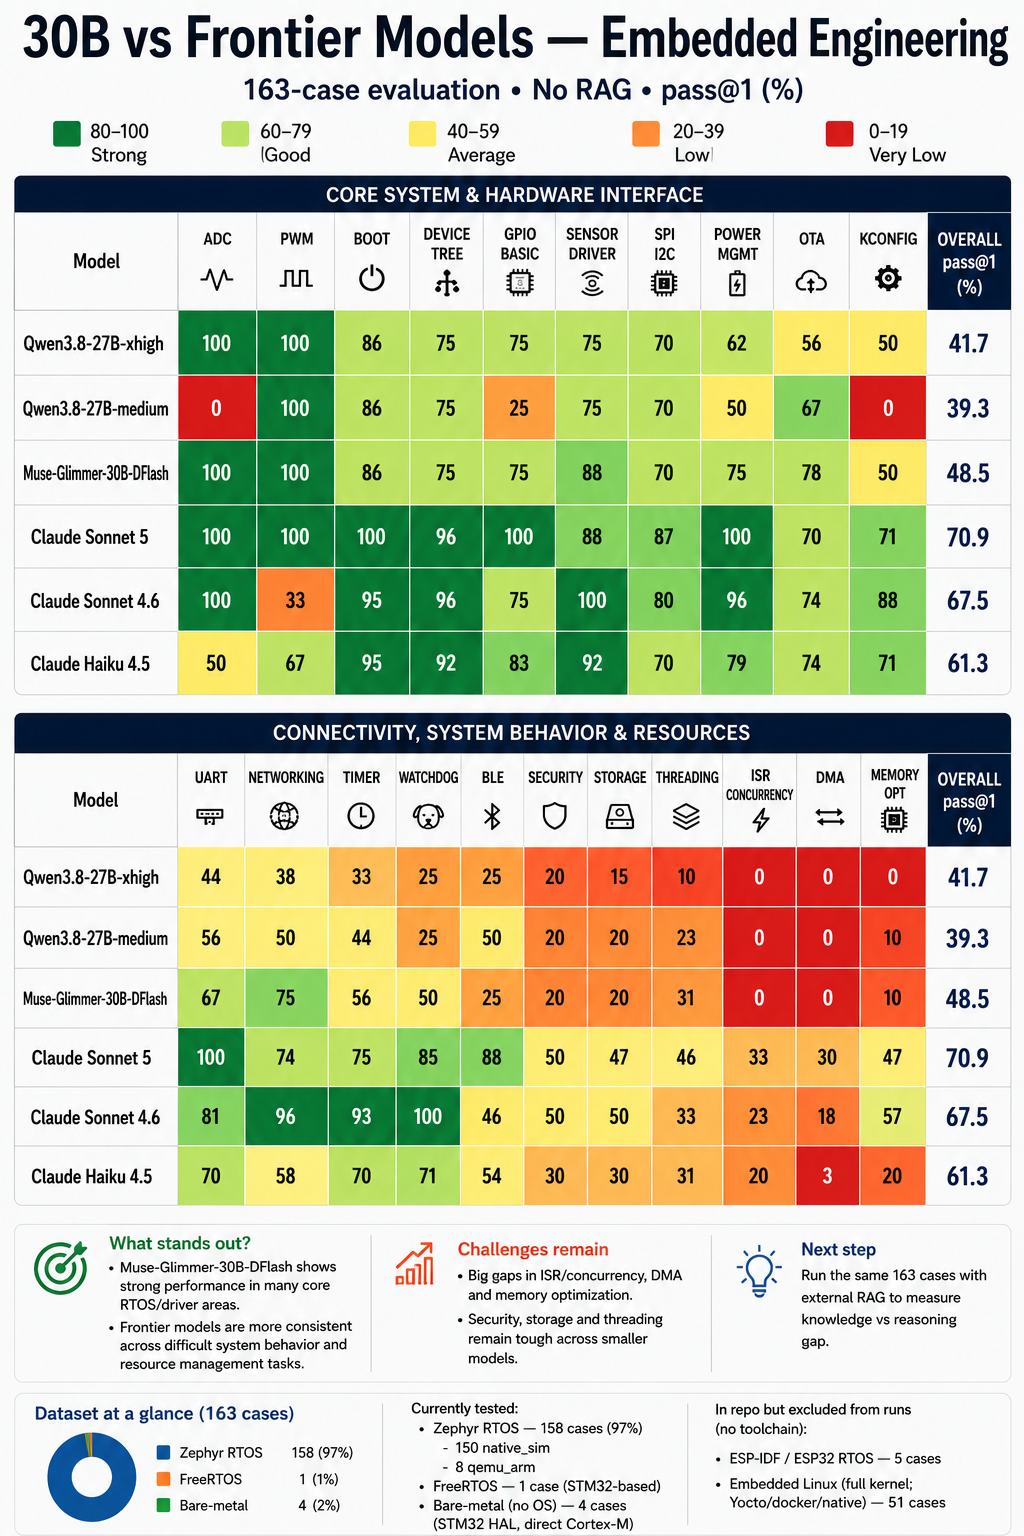
Reddit post · Benchmarks & research


 ChatForm
 Tgmlabs