Curated with by@mohithkumar808

№ 0211Reddit post

Muse Glimmer as code reviewer in a multi-model pipeline

A Claude Code-orchestrated pipeline where Qwen 3.8 27B writes code, Muse Glimmer sanity-checks it, and DeepSeek arbitrates disagreements; a tool-allowlist fix cut payloads 161KB to 24KB.

u/Graemer71 runs Claude Code as orchestrator, DeepSeek 4.1 Flash for planning, Qwen 3.8 27B Q8 for boilerplate and Muse Glimmer to sanity-check code and push issues back. After a token spike, a diagnostic server showed the --tools allowlist cut tools from 55 to 7 and payloads from 161KB to 24KB.

r/Anthropic· u/Graemer71View on Reddit ↗

Found out why Claude was burning so many tokens when just orchestrating.

OK, for context, I have Claude Code desktop app driving the CLI and orchestrating the code and verification tasks to try to save tokens. So Claude runs things, a Deepseek 4.1 Flash (cloud) session does the planning, Qwen 3.8 27b Q8 does the boiler plate coding and Muse Glimmer sanity checks the code and pushes any issues back to Qwen. If there are issues Qwen and Glimmer can't agree on, Deepseek validates. If Deepseek can't sort it out, it goes back to Claude. This had been working fine, but then in the last few days token use spiked, tasks that used to take 10 minutes were taking an hour or more and Qwen started going into more and more reasoning loops. It seems that since I last checked (on 12th September) the CLI changed. I used to strip unnecessary tool calls from the prompt using --disallowedTools and enabledPlugins: false. It would seem that these no longer work. In the end I got Claude to build a request-dumping diagnostic server, that actually measured the payload bytes, and confirmed --tools (an allowlist) is the flag that works now: 55→7 tools, 161KB→24KB, byte-verified. It also caught something specific to my workflow running the wrapper from inside an already-active

Also filed under Agents & automation

See all →
  1. 1057

    Muse Mail: your agent gets an email address★

    MUSE FEATURE ALERT: y'all have been asking for this one. your @muse is getting its own email address. add it to a thread or forward it stuff and it’ll handle it for you. muse mail!

    @alexandr_wang

    X post

    Agents & automation

  2. 1054

    Kevin Roose gives his Muse $100 and a Kalshi account★

    gave my Muse $100 and a kalshi account, let's see how frontier this thing is

    @kevinroose

    X post

    Agents & automation

  3. 1007

    Plumbing company run by a Muse agent★

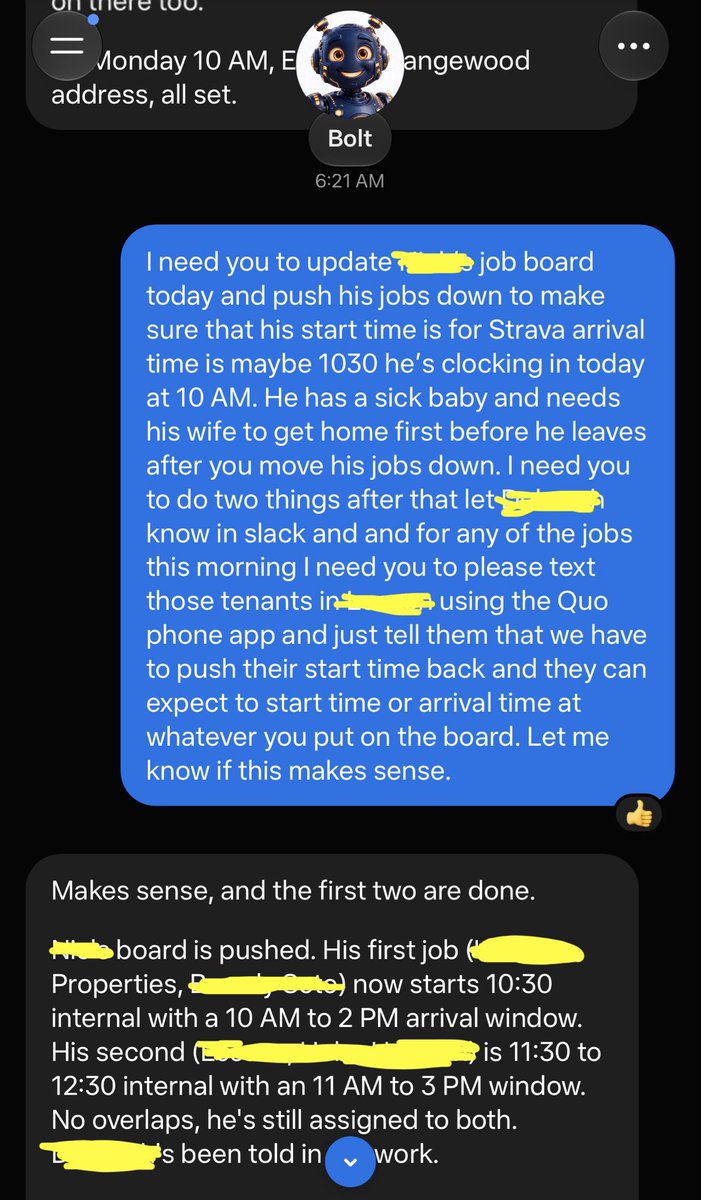
    I still can’t believe I can run my plumbing company with an agent so easily. I send this message to my Muse agent while in bed at 6am. And it: updates my job board, texts customer, updates office manager who arrives at 8am in slack Notifies technician

    @HouseHackerJon

    X post

    Agents & automation

  4. 0881

    Every Muse user gets a cloud computer★

    I’ve seen a couple of posts about this so wanted to demystify. Today, every Muse user gets a free computer in the cloud. It's a real computer, and we’ve designed the security architecture of the Muse Secure VM carefully so you and your Muse can do almost anything you could with a

    @dps

    X post

    Agents & automation

More Reddit posts

See all →
  1. 1071

    Public brokerage connector for Meta Muse

    Research markets, analyze your portfolio, and prepare trades right from your conversation. Guide to connect: https://public.com/api/docs/templates/meta-muse

    u/Public

    Reddit post

    Connectors & MCP

  2. 1067

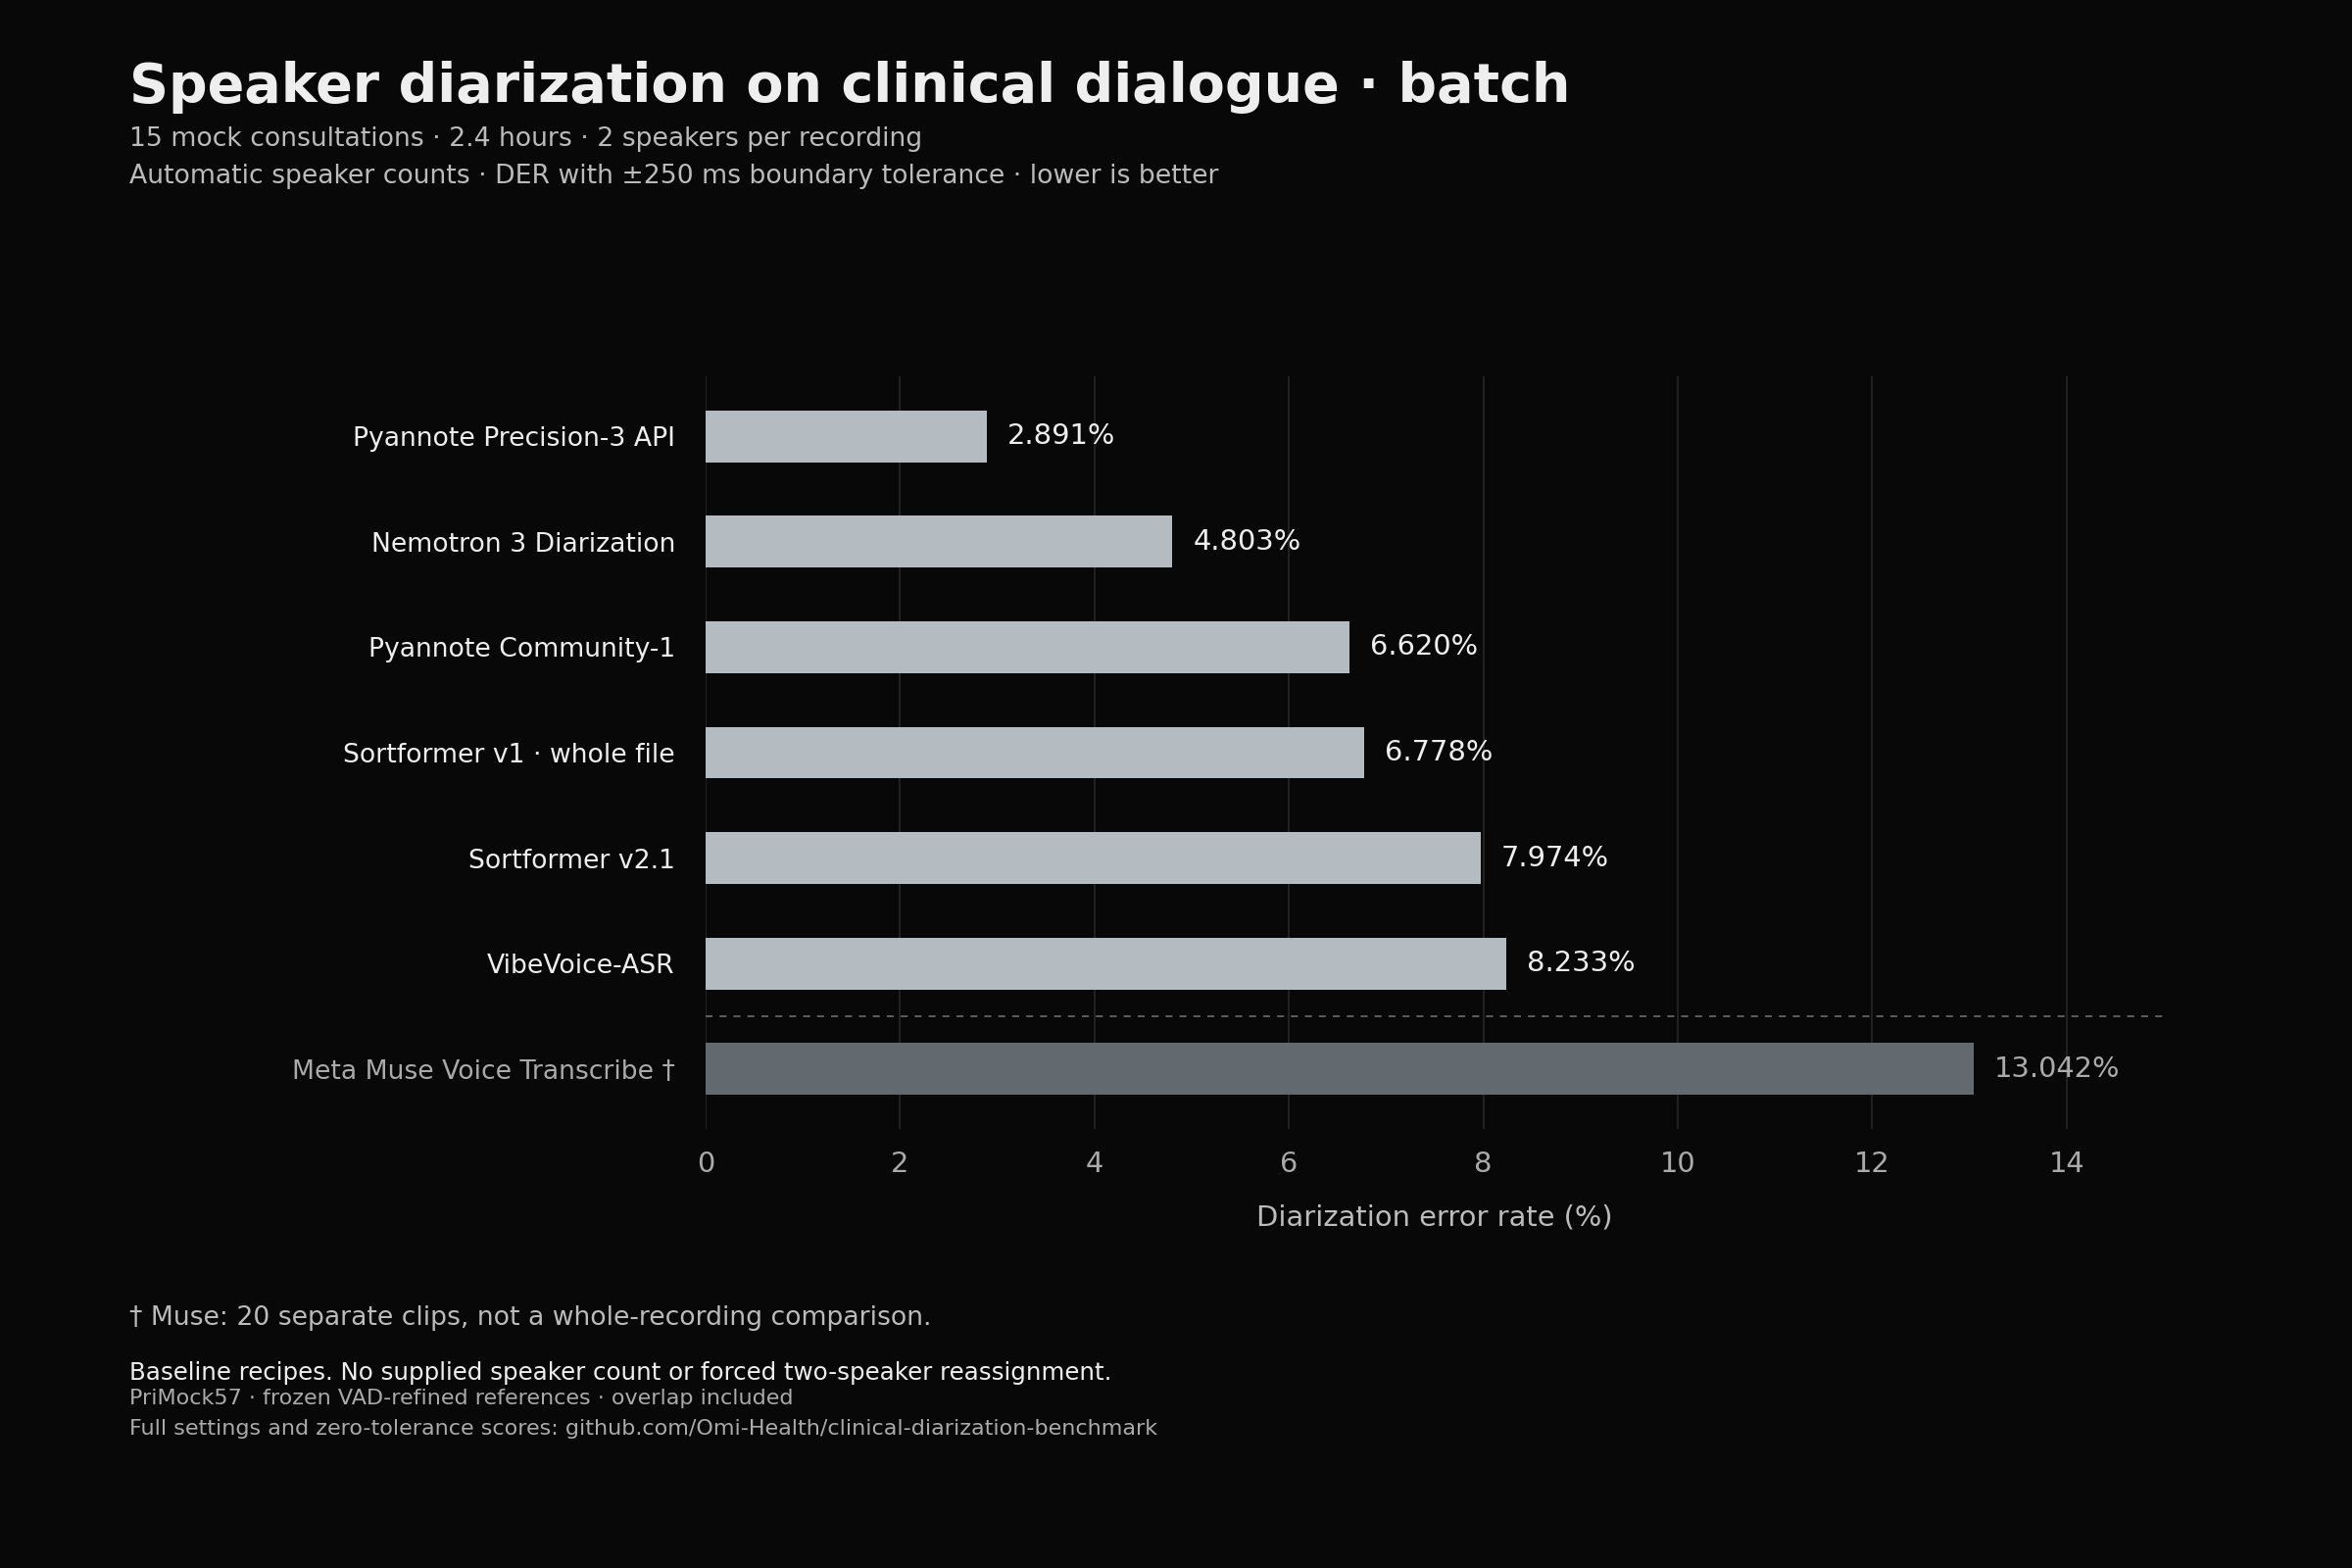
    Muse Voice Transcribe tested on clinical diarization

    I've been working on clinical speaker attribution at Omi and wanted to compare the current diarization models on the same audio. I used 15 mock doctor–patient consultations from PriMock57, about 2.4 hours. Full recordings, automatic speaker counts, without telling the models there are two people. Batch Diarization error rate (DER), with ±250 ms boundary tolerance. Lower is better. Model DER Median processing time Pyannote Precision-3 2.891% 18.9 s / recording (API) Nemotron 3 4.803% 0.688 s / recording Pyannote Community-1 6.620% 18.691 s / recording Sortformer v1 6.778% 3.869 s / recording Sortformer v2.1 7.974% 1.077 s / recording VibeVoice-ASR 8.233% 123 s / recording Meta Muse Voice Transcribe † 13.042% 92 s / request (API) Local models ran on one NVIDIA L4. API times include round-trip overhead; VibeVoice-ASR also performs transcription. † Muse used 20 separate clips because of its 10-minute request limit, so its result isn't a whole-recording comparison. Pyannote Precision-3 had the lowest error. Nemotron came next and was the fastest local model. Streaming Model DER Pyannote live API 3.959% Nemotron 3 † 4.971% Sortformer v2.1 † 6.958% VibeVo

    u/MajesticAd2862

    Reddit post

    Benchmarks & research

  3. 1061

    Wiring a Muse agent VM to Home Assistant over Tailscale

    Setup: Home Assistant + Caddy in Docker on a Mac mini at home. Caddy serves only /api/* on the Mac's Tailscale IP, port 8443. Tailscale ACL allows my Muse agent's VM to that port. Goal: let the agent query the HA API remotely. What's verified: • Mac mini is on the tailnet, Tailscale running, peer visible in tailscale status from the agent VM • Caddy serves the API locally (gets expected 401 without token) • Lutron/Ring integrations healthy in HA What fails: every request from the agent VM through Muse's documented tunnel path (HTTP proxy with CONNECT, port 3130) to https://<tailnet-ip>:8443/api/ dies with curl exit 52, "Empty reply from server" — in about 8 seconds, never a proxy error, never a timeout waiting on approval. A stale duplicate node entry in the peer list just times out (exit 28), so that's not it either. This smells like the agent platform's tunnel data plane never passing the traffic, not a Tailscale or HA misconfig — but before I write it off, has anyone here actually gotten a Muse agent VM talking to a tailnet peer? Or found a workaround that doesn't involve exposing things publicly (Funnel/Cloudflare Tunnel/ngrok are the obvious fallbacks)?

    u/jatayoo2026

    Reddit post

    Errands & personal agent

  4. 1058

    Muse Spark 1.3 on a 10k-LOC codebase in OpenCode

    Wondering why all the hate for muse spark 1.3 since in my testing on a codebase with about 10k LOC it performed pretty well , sometime even outperforming Gemini flash 3.8 in solving some hard bugs where flash took much longer and needed more guidance for these tasks .. Granted I think Gemini is certainly better for frontend and designs much better looking interfaces without much prompting, but for complex bugs spanning multiple backend parts I think Muse spark perform really well….

    u/NationalEar1400

    Reddit post

    Coding & dev tools

Curator picks

  1. 1046

    Medical bills audited line by line, $4,000 saved★

    Got Muse logged in to my medical provider’s portal, he pulled the itemized bills, and questioned every line. So far he’s found several times I’d been double billed, asked for some discounts and has saved me over $4,000. If your moat is bureaucracy, you’re cooked.

    @Ryan_Holdaway

    X post

    Errands & personal agent

  2. 1042

    GitHub connector for Muse★

    GitHub 🤝 @Muse A new way to connect your GitHub account to review PRs, catch up on issues and notifications, and leave comments without switching tabs.

    @github

    X post

    Connectors & MCP

Want more AI builds?artificialbuilds.com