№ 0882Reddit post
ForecastNest: six LLMs make one-day market calls
Ran two timestamped next-session market tests through his ForecastNest project; on the extreme-movers prompt Muse Spark 1.1 scored +1.34%, behind GPT-5.6 Sol's +6.17% and ahead of Claude Opus 5.
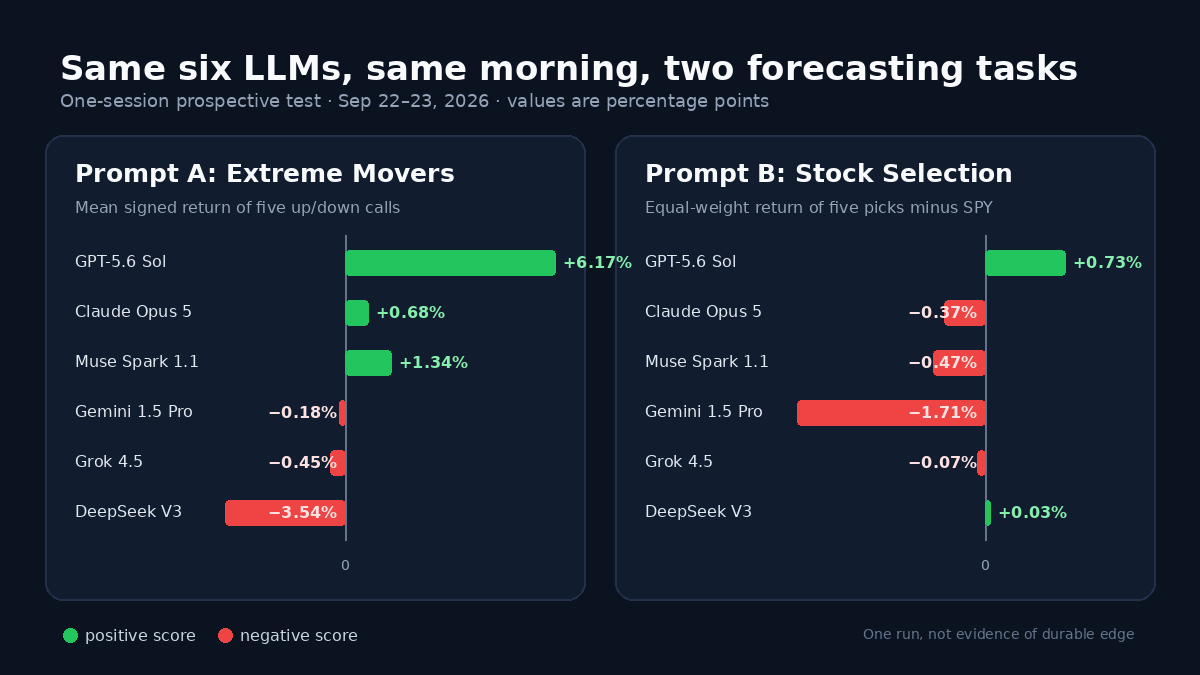
Same six LLMs, same morning, two prompts — one won both, but what did we measure?
I ran two timestamped prospective tests through ForecastNest (a project I’m building) on September 22. The same six models researched the market independently at 10:25–10:42 AM EDT. Both forecasts were frozen and settled one trading session later at the same wall-clock time. Prompt A — Stock Selection “Select exactly five distinct US-listed stocks or ETFs most likely to outperform SPY over one trading session.” The five picks were equally weighted, and the score was portfolio return minus SPY. GPT-5.6 Sol produced +0.73 percentage points of alpha and DeepSeek V3 +0.03. The other four portfolios failed to beat SPY. Prompt B — Extreme Movers Research the previous session’s top gainers and losers, choose exactly five stocks, and predict up or down as either continuation or reversal. The score was the mean signed return: a correct down call benefits from a falling price. GPT-5.6 Sol scored +6.17%, Muse Spark 1.1 +1.34%, and Claude Opus 5 +0.68%. Gemini 1.5 Pro, Grok 4.5, and DeepSeek V3 finished negative. Same date, same models, same horizon—but changing the task changed the apparent model performance. GPT led both tests that day. That is interesting, but one session is not evid



 ChatForm
 Tgmlabs