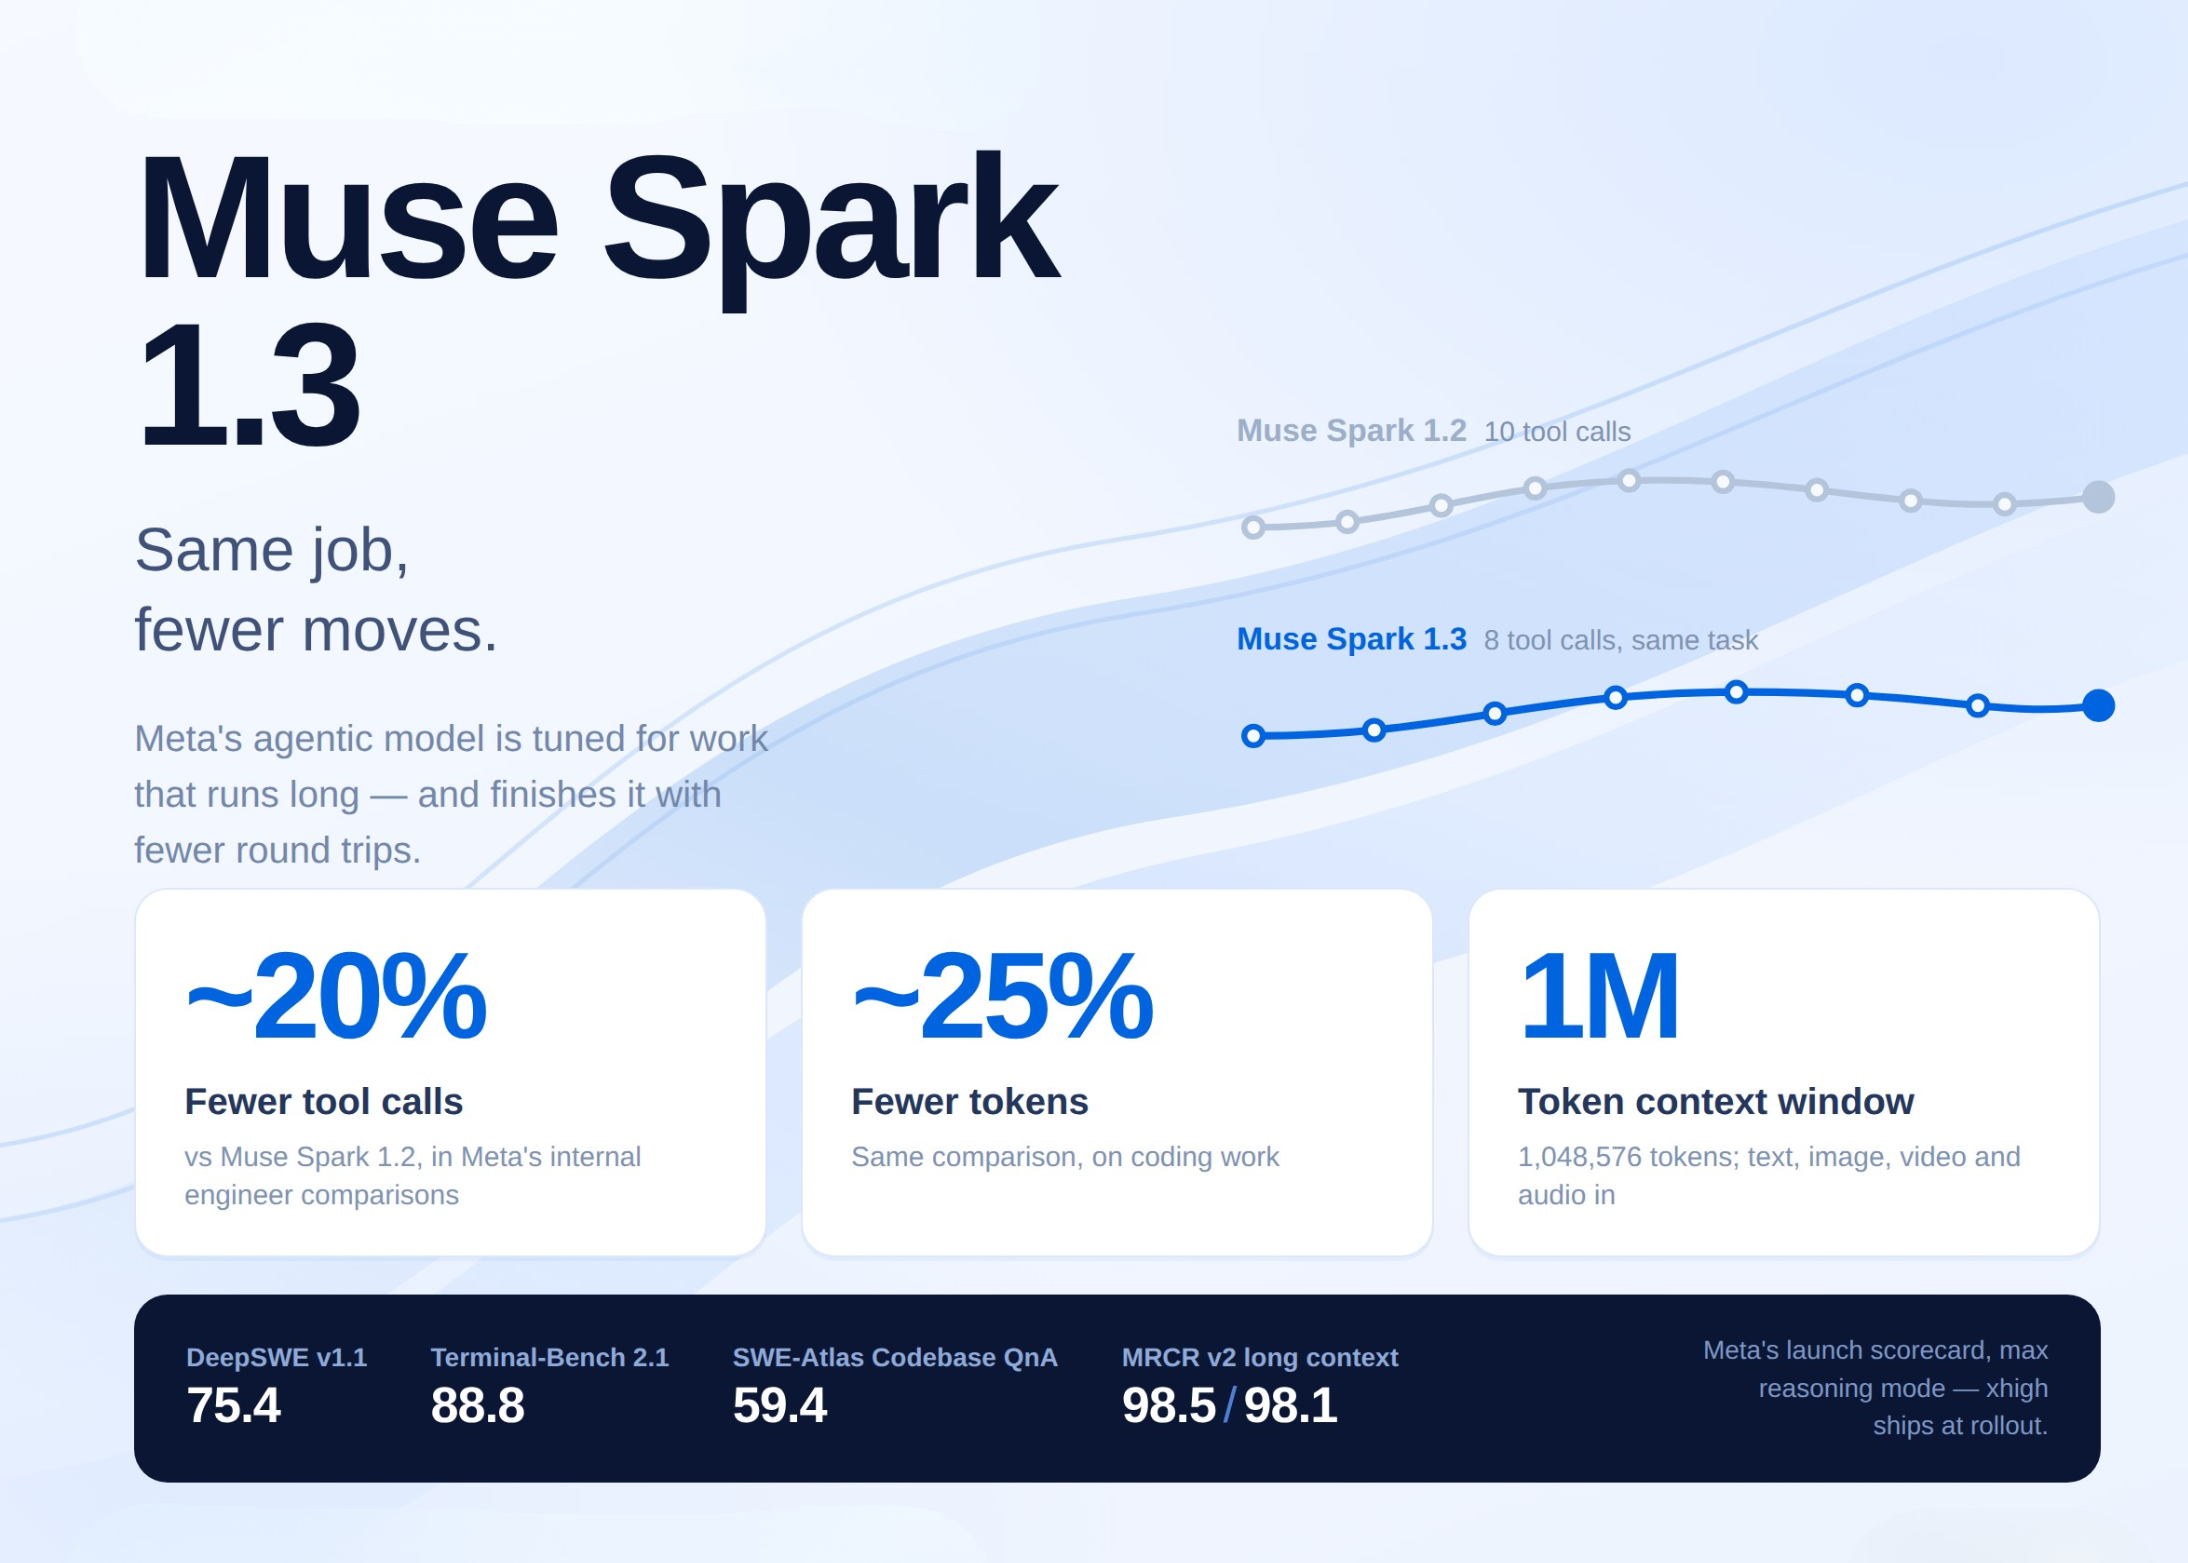
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.
Resource · Benchmarks & research
Catalog / Type
About 115 Muse resources: Meta docs, Muse Glimmer model weights and quants, independent reviews, benchmark write-ups and setup tutorials.
137 builds · page 2 of 4
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.
Resource · Benchmarks & research
Meta's announcement of Muse Spark 1.3 for Muse Code and the Meta Model API, claiming ~20% fewer tool calls and ~25% fewer tokens than 1.2, with a max reasoning mode.
Resource · Coding & dev tools
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models
TryAI has frontier and open models, including Muse Spark, each build a raycaster, a Rubik's cube, a calculator and a fourth app, and compares the results.
Resource · Benchmarks & research
Decensored Muse Glimmer 30B made with Heretic v1.4.0, shipped with a reproduce directory.
Resource · Local & open models· ♥ 15
sequelbox's Tachibana-Agent fine-tune of Muse Glimmer 30B, part of a series also released for Gemma 4 12B and Qwen3.6 27B.
Resource · Local & open models· ♥ 4
Wavect's guide covers Glimmer's hardware targets (24–32GB) and tool-use scores such as MCP-Atlas 75.5 and SWE-Bench Pro 51.2, and recommends a 20–30 task pilot before production.
Resource · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Codus reads the three benchmark charts Meta published for Muse Code and notes Claude Opus 5 wins all three, including Meta's own internal eval.
Resource · Benchmarks & research
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
Meta's developer post on running Muse Glimmer on a single consumer GPU with vLLM, llama.cpp and ExecuTorch, with quantized builds in 24-32 GB and cookbook recipes.
Resource · Local & open models
Experimental OpenVINO INT4 conversion of Muse Glimmer 30B that needs development builds of Optimum Intel and OpenVINO.
Resource · Local & open models· ♥ 1
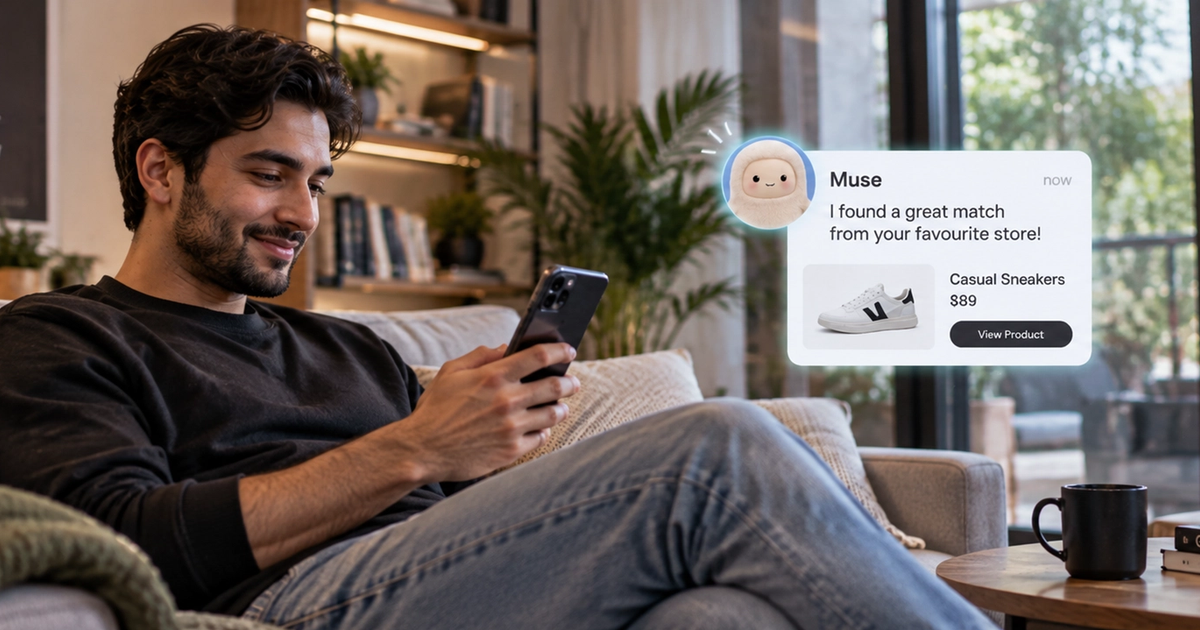
Codilar explained that Shopify products became searchable and purchasable inside Muse through Shop Pay at launch with no merchant setup, and what product-data and checkout readiness merchants need for the new channel.
Resource · Business & commerce
A DPO fine-tune of Muse Glimmer focused on prose quality and humanlike characters, trained on roughly one-third writing and two-thirds roleplay data.
Resource · Local & open models· ♥ 2
A Jacobian lens (J-lens) for interpretability on Muse Glimmer 30B's 52 layers, reading out which tokens each activation is poised to verbalize.
Resource · Benchmarks & research· ♥ 2
QAInsights' hands-on first look at Muse Code covering CLI commands, syntax and setup on launch day.
Resource · Coding & dev tools
Simon Willison ran an 18.16GB build of Muse Glimmer locally, testing code exploration and image description. He found multi-step reasoning and tool use strong and creative generation mixed.
Resource · Local & open models
Resource · Local & open models· ♥ 18
Resource · Local & open models· ♥ 4
Resource · Local & open models· ♥ 343
Meta's launch post for Muse, a personal agent powered by Muse Spark 1.3 that runs in a dedicated Muse Secure VM and acts across email, travel, forms and purchases.
Resource · Errands & personal agent
A suite of 27 GGUF quantizations of an abliterated Muse Glimmer 30B produced with Heretic v1.4.0.
Resource · Local & open models· ♥ 20
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
DFlash 2 speculative-decoding draft model for Muse Glimmer 30B from z-lab, run inside a speculative decoding server alongside the target model.
Resource · Local & open models· ♥ 15
A quantization-aware-trained Q4_0 GGUF of Muse Glimmer 30B for llama.cpp. On held-out tokens it measures closer to BF16 than Meta's official Q4_K_M: 0.0213 vs 0.0228 KL and 95.9% vs 95.6% top-token agreement.
Resource · Local & open models· ♥ 3
Muse Glimmer 30B abliterated with Heretic v1.4.0 using self-organizing maps and magnitude-preserving orthogonal ablation.
Resource · Local & open models· ♥ 11
DataCamp's Josep Ferrer ran Muse Spark 1.3 on three real coding tasks. Two used 23–32% fewer completion tokens, but a refactor used 70% more, for a net 12% cost increase.
Resource · Benchmarks & research★ Pick
Fireworks made Muse Glimmer 30B available on launch day, pitching high-concurrency, cost-effective serving for always-on agents.
Resource · Local & open models
Sediment's fine-tune of Muse Glimmer 30B that answers factual questions when confident and says "I don't know" otherwise, calibrated for the AA-Omniscience setting.
Resource · Local & open models· ♥ 1
Stark Insider introduced Muse to its own AI agent setup to test whether Muse's one-minute onboarding costs depth compared with OpenClaw.
Resource · Benchmarks & research
Wavect's buyer guide to Muse Code pricing, training-data rights, client repositories, agency margins and routing workloads safely.
Resource · Coding & dev tools
A 4-byte GGUF header edit that raises Muse Glimmer 30B's 131,072 context limit to 262K. The author shows YaRN scaling only adds prefill cost on this architecture, and verified 262K with 8 slots on one RTX 4090.
Resource · Local & open models· ♥ 1
Muse Glimmer 30B quantized with Intel AutoRound at a 3.5-bit target and packed with llm-compressor, tested on vLLM.
Resource · Local & open models· ♥ 3
AWQ INT4 quant of Muse Glimmer 30B calibrated on STEM and agentic data across ten languages, 24.02 GB.
Resource · Local & open models· ♥ 10
turboderp's self-calibrated EXL3 quants of Muse Glimmer 30B down to 1.75 bits per weight, with calibration and eval traces.
Resource · Local & open models· ♥ 14
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Simon Willison reads the Muse Code launch as more evidence that long-sequence agentic tool calling is now the key model trait.
Resource · Coding & dev tools
explainx.ai breaks down Meta's Sep 19 opening of the Muse connector platform: developers bring the API, Muse brings the agent, browser and user context.
Resource · Connectors & MCP
Abliterated Muse Glimmer 30B GGUF quant ladder, updated with a 1.63 GB abliterated DFlash drafter and a 1.40 GB multimodal projector.
Resource · Local & open models· ♥ 49
Rohan Adwankar found Muse runs on Cloud Hypervisor microVMs with a 327 MB Rust harness that boots in ~40 s, an on-VM Postgres with 194 tables and 60+ privsep tool workers.
Resource · Benchmarks & research
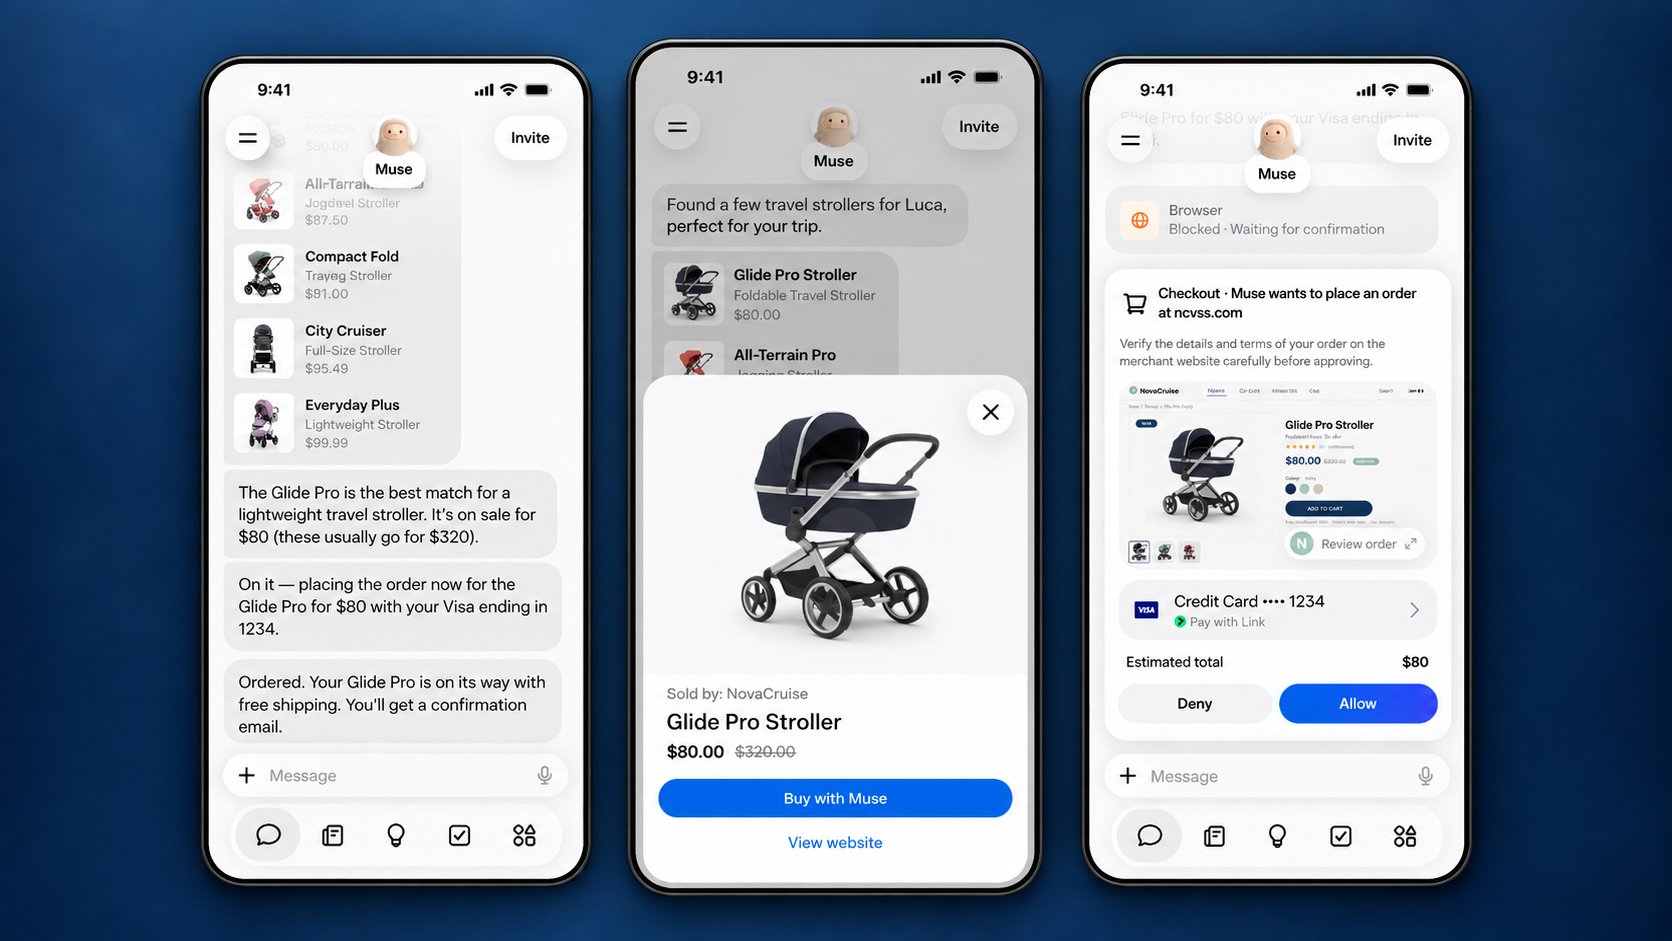
GeekWire reports Amazon blocked Muse from making purchases as of September 20, saying the agent accessed its store without permission, didn't identify itself, and appeared to store credentials.
Resource · Benchmarks & research
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
Resource · Local & open models★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
llama.cpp imatrix quantizations of Muse Glimmer 30B with image support via mmproj and MTP/DFlash notes.
Resource · Local & open models· ♥ 19
 ChatForm
 Tgmlabs