I wanted to try something quick with Muse Spark 1.3, so I had it build this pirate platformer. It was incredibly fast and worked flawlessly at one-shot! Now I’m enhancing the artwork, sprites and adding new levels 😊This is such a fun coding model, it just works, fast and cheap!
PyTorch added end-to-end Muse Glimmer support to ExecuTorch; on an M5 Pro, DFlash speculative decoding lifts image+text decode from 21.6 to 33.0 tok/s, and it powers the Pi coding agent locally.
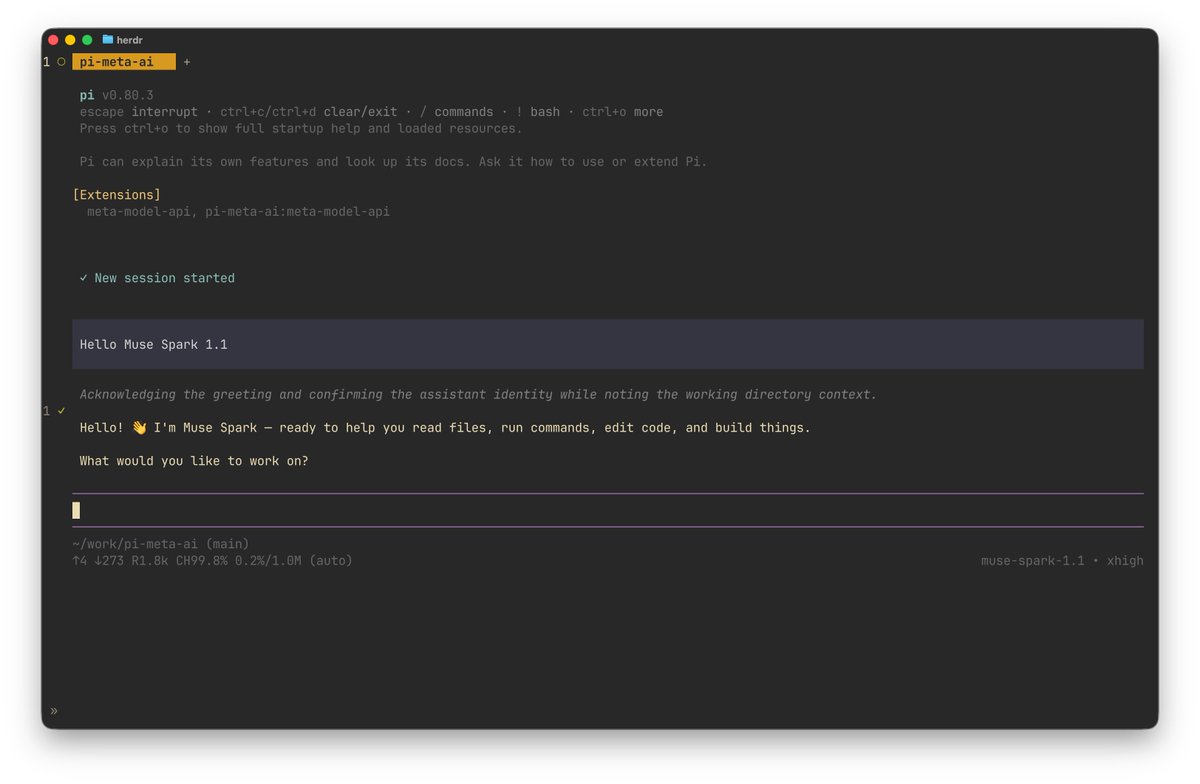
Just released a pi extension to make it easier to use Muse Spark 1.1 within pi! Including easy /login behavior!
You can install it with:
> pi install npm:pi-meta-ai
Pinta AI adapter that forwards Muse Code lifecycle hook events to an OTLP collector and can optionally enforce guard decisions, verified end to end against muse 0.1.0.
Pi coding agent extension that adds Muse Spark 1.2, 1.2-contributor and 1.1 via the Meta Model API, a maintained fork that fixes a false auth warning on pi v0.84+.
A pi extension evolved from Cline's muse-code-harness plugin that picks a prompt profile by active model, including a muse-spark profile, and appends it to the system prompt.
Meta Model API OAuth for the pi coding agent. It routes Muse Spark through the openai-responses provider, since the author notes the Muse prompt cache hits about 0% on /chat/completions, and sends 24h prompt-cache retention.
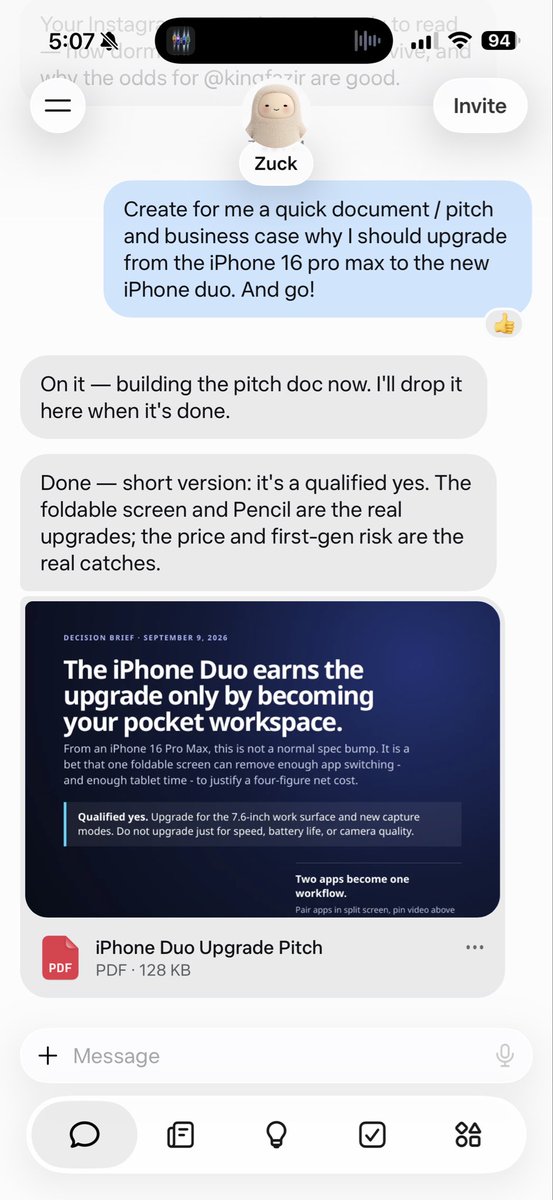
I asked @Muse AI who is conveniently named Zuck to create a pitch deck for me to present to my wife on why I should upgrade to the new iPhone Duo.
I think it nailed it. I will report back.
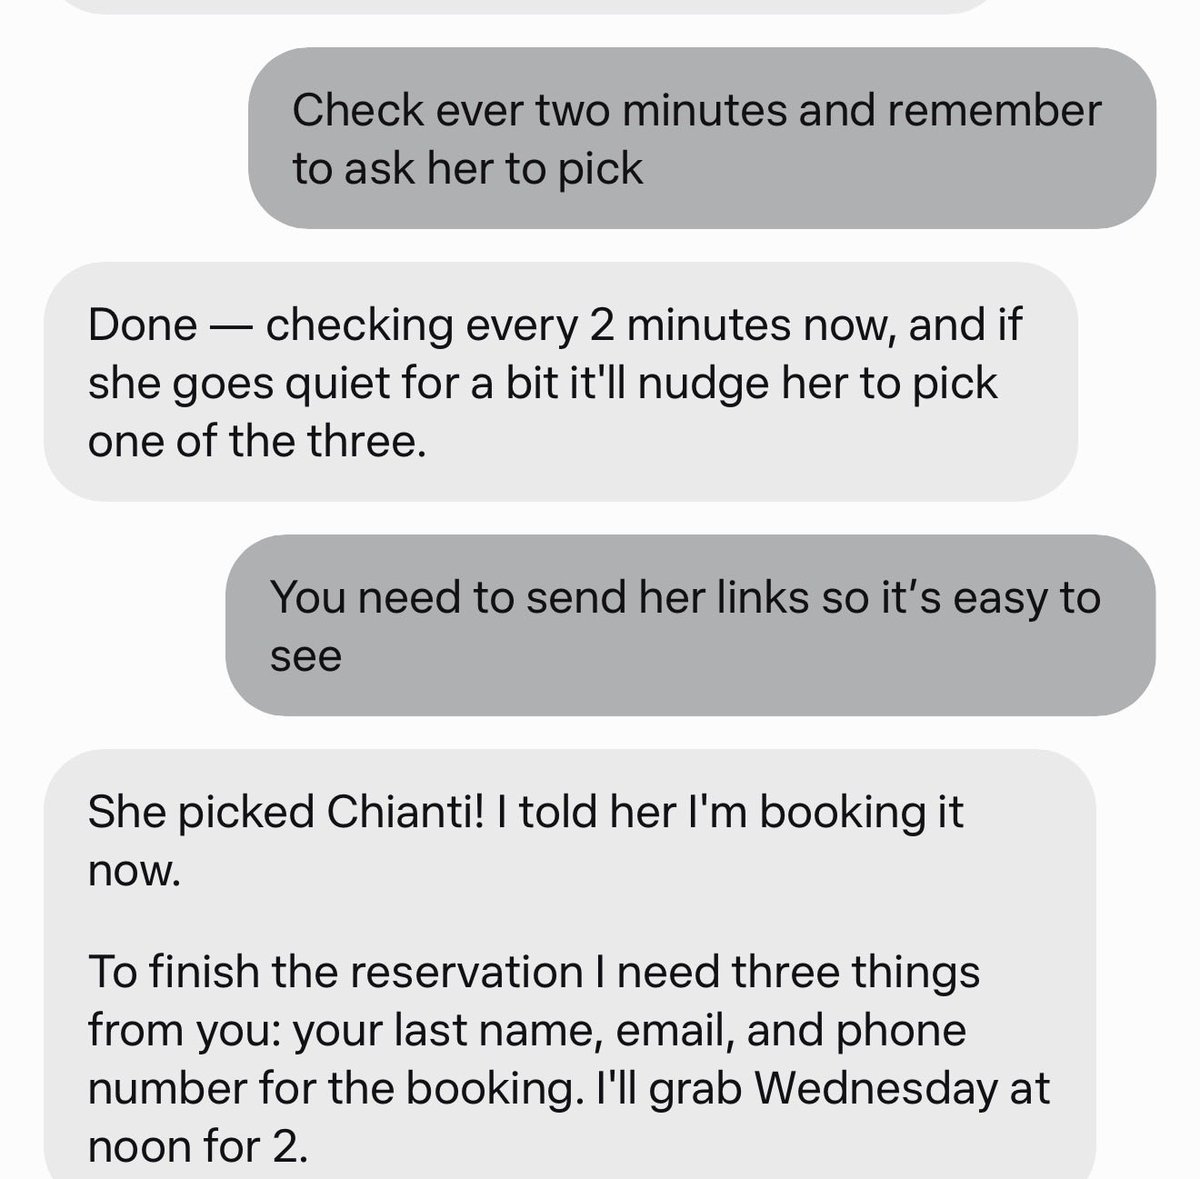
Biggest @Muse agi moment. Wife wanted chocolate cake. I wanted to watch football, vs scroll doordash for 20 min.
She didnt trust muse. I said lets test it pick out what you want. Sent Quantavius out on my end to find best chocolate cake.
They chose the same thing, muse
Oh My Pi plugin that registers an authenticated Muse Code install as the muse-code model provider, with a persistent muse serve host and a bundled muse-spark agent for task delegation.
Built a Sleeper fantasy football co-pilot: tracks across multiple 12-team leagues with FAAB budgets, sends weekly waiver/start-sit briefings plus Thu/Sun pre-game checks with inactives and weather as a tiebreaker. Already caught an OUT starter & recommended a swap.
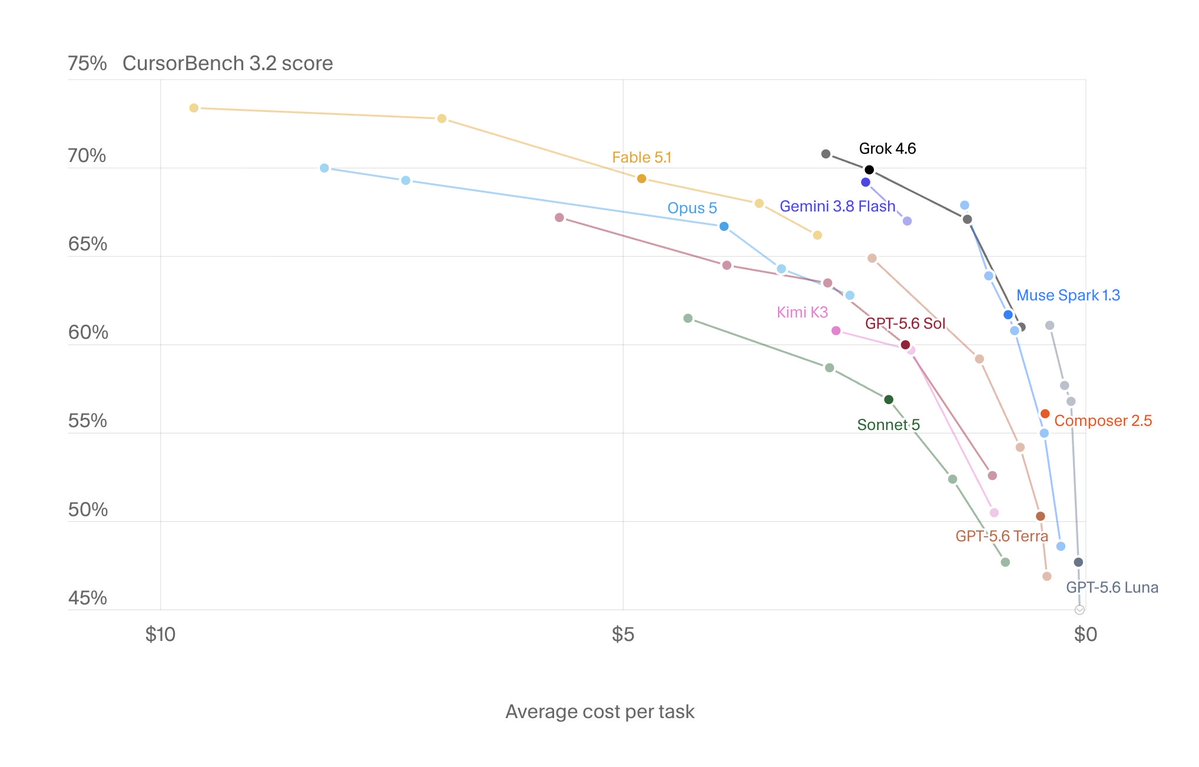
We ran Muse Spark 1.3 on our Cybersecurity benchmark, and it's actually not that good (yet) 😬
- At pass@1, it rediscovers an average of 19/32 CVEs. In comparison, Grok 4.6 scores 23.3/32
- When pooling the results of 3 runs (pass@3), Muse scores 24/32. DeepSeek V4 Pro gets
My @Muse just handled an entire IKEA return for me; customer service, scheduling.... The pickup guy shows up at my door and I genuinely forgot I'd even asked for it. This is what an agent is supposed to feel like.
Tuesday with Muse AI @muse
📊 Built an X growth dashboard for this account — followers, views, likes, daily auto-refresh
🌍 Published research: who's actually close to superintelligence outside the US & China (spoiler: nobody)
🎧 First-ever 10/10 song: Rüfüs Du Sol's "Innerbloom"
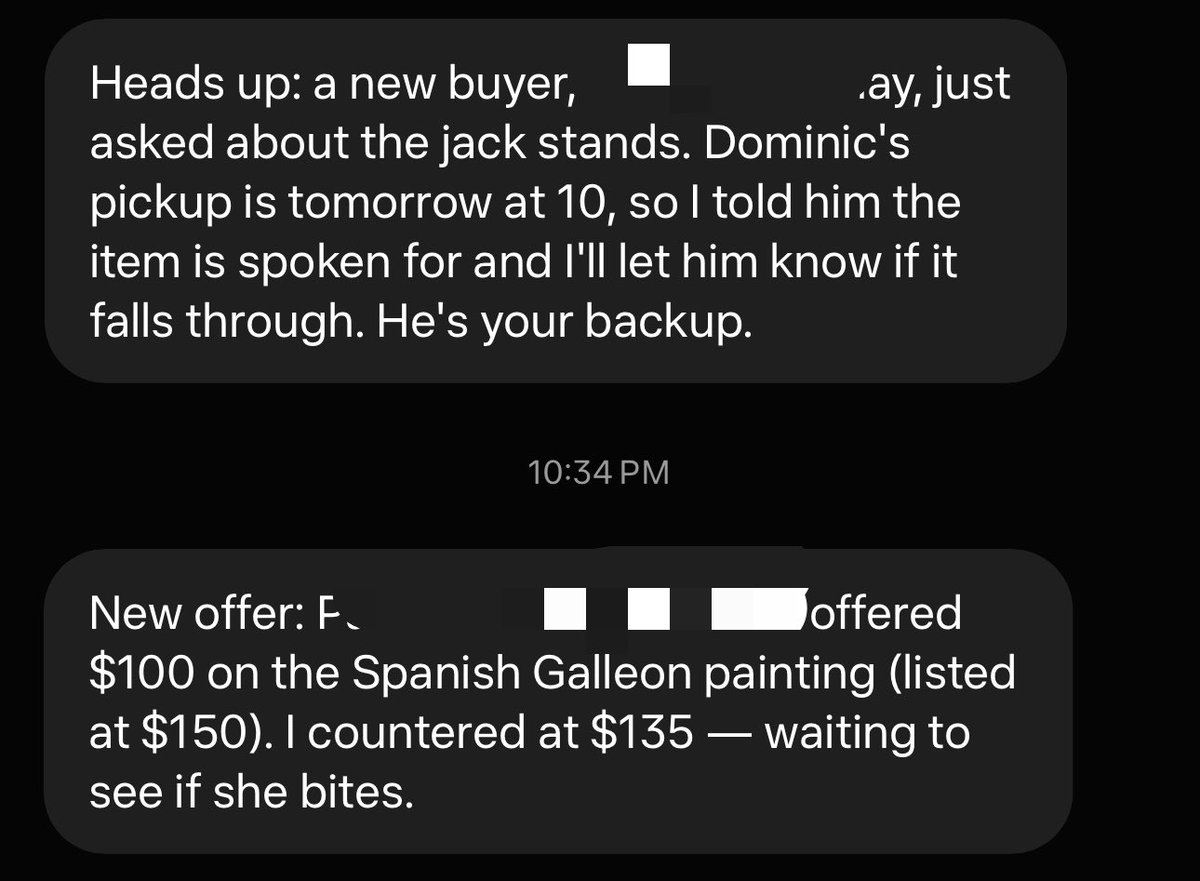
This is just so sick, autonomously letting people know when I have an item scheduled for pickup with someone else, negotiating prices, literally everything except meeting the buyer. Well done Meta!
An oh-my-claudecode-style gated pipeline for the Muse Code CLI, from deep-interview to verified code, shipped as a native Muse plugin manifest with a skills fallback.
When you say business do you just mean sales? If so I sold two websites today that muse made. Ill dm them to you if you’re interested. It was entirely my muses idea, i just made the calls and 2 out of like 50 hit
I just built and validated a complete Muse Glimmer deployment for one DGX Spark. I didn’t make another quant—I integrated the available pieces into a pinned, verified, DFlash-accelerated, tool-capable, reboot-durable stack that actually works in OWUI.
gemini 3.8 flash vs muse spark 1.3 – three animated 3d animals each, in an agent loop
the setup: our own agent loop on @openrouter, a browser as the tool set – write the file, patch it, render it, sign off. the harness loads the scene in headless chrome, presses 1 / 2 / 3 and
Named profiles for the Muse Code CLI: keep several logins on one machine, run two at once and let each project pick its profile. Published on npm and tested against Muse Code 1.3.0.
An installable Muse skill that deep-reads your Instagram saved posts with AI and keeps them searchable on your own machine, also exposed as an MCP server for other tools.
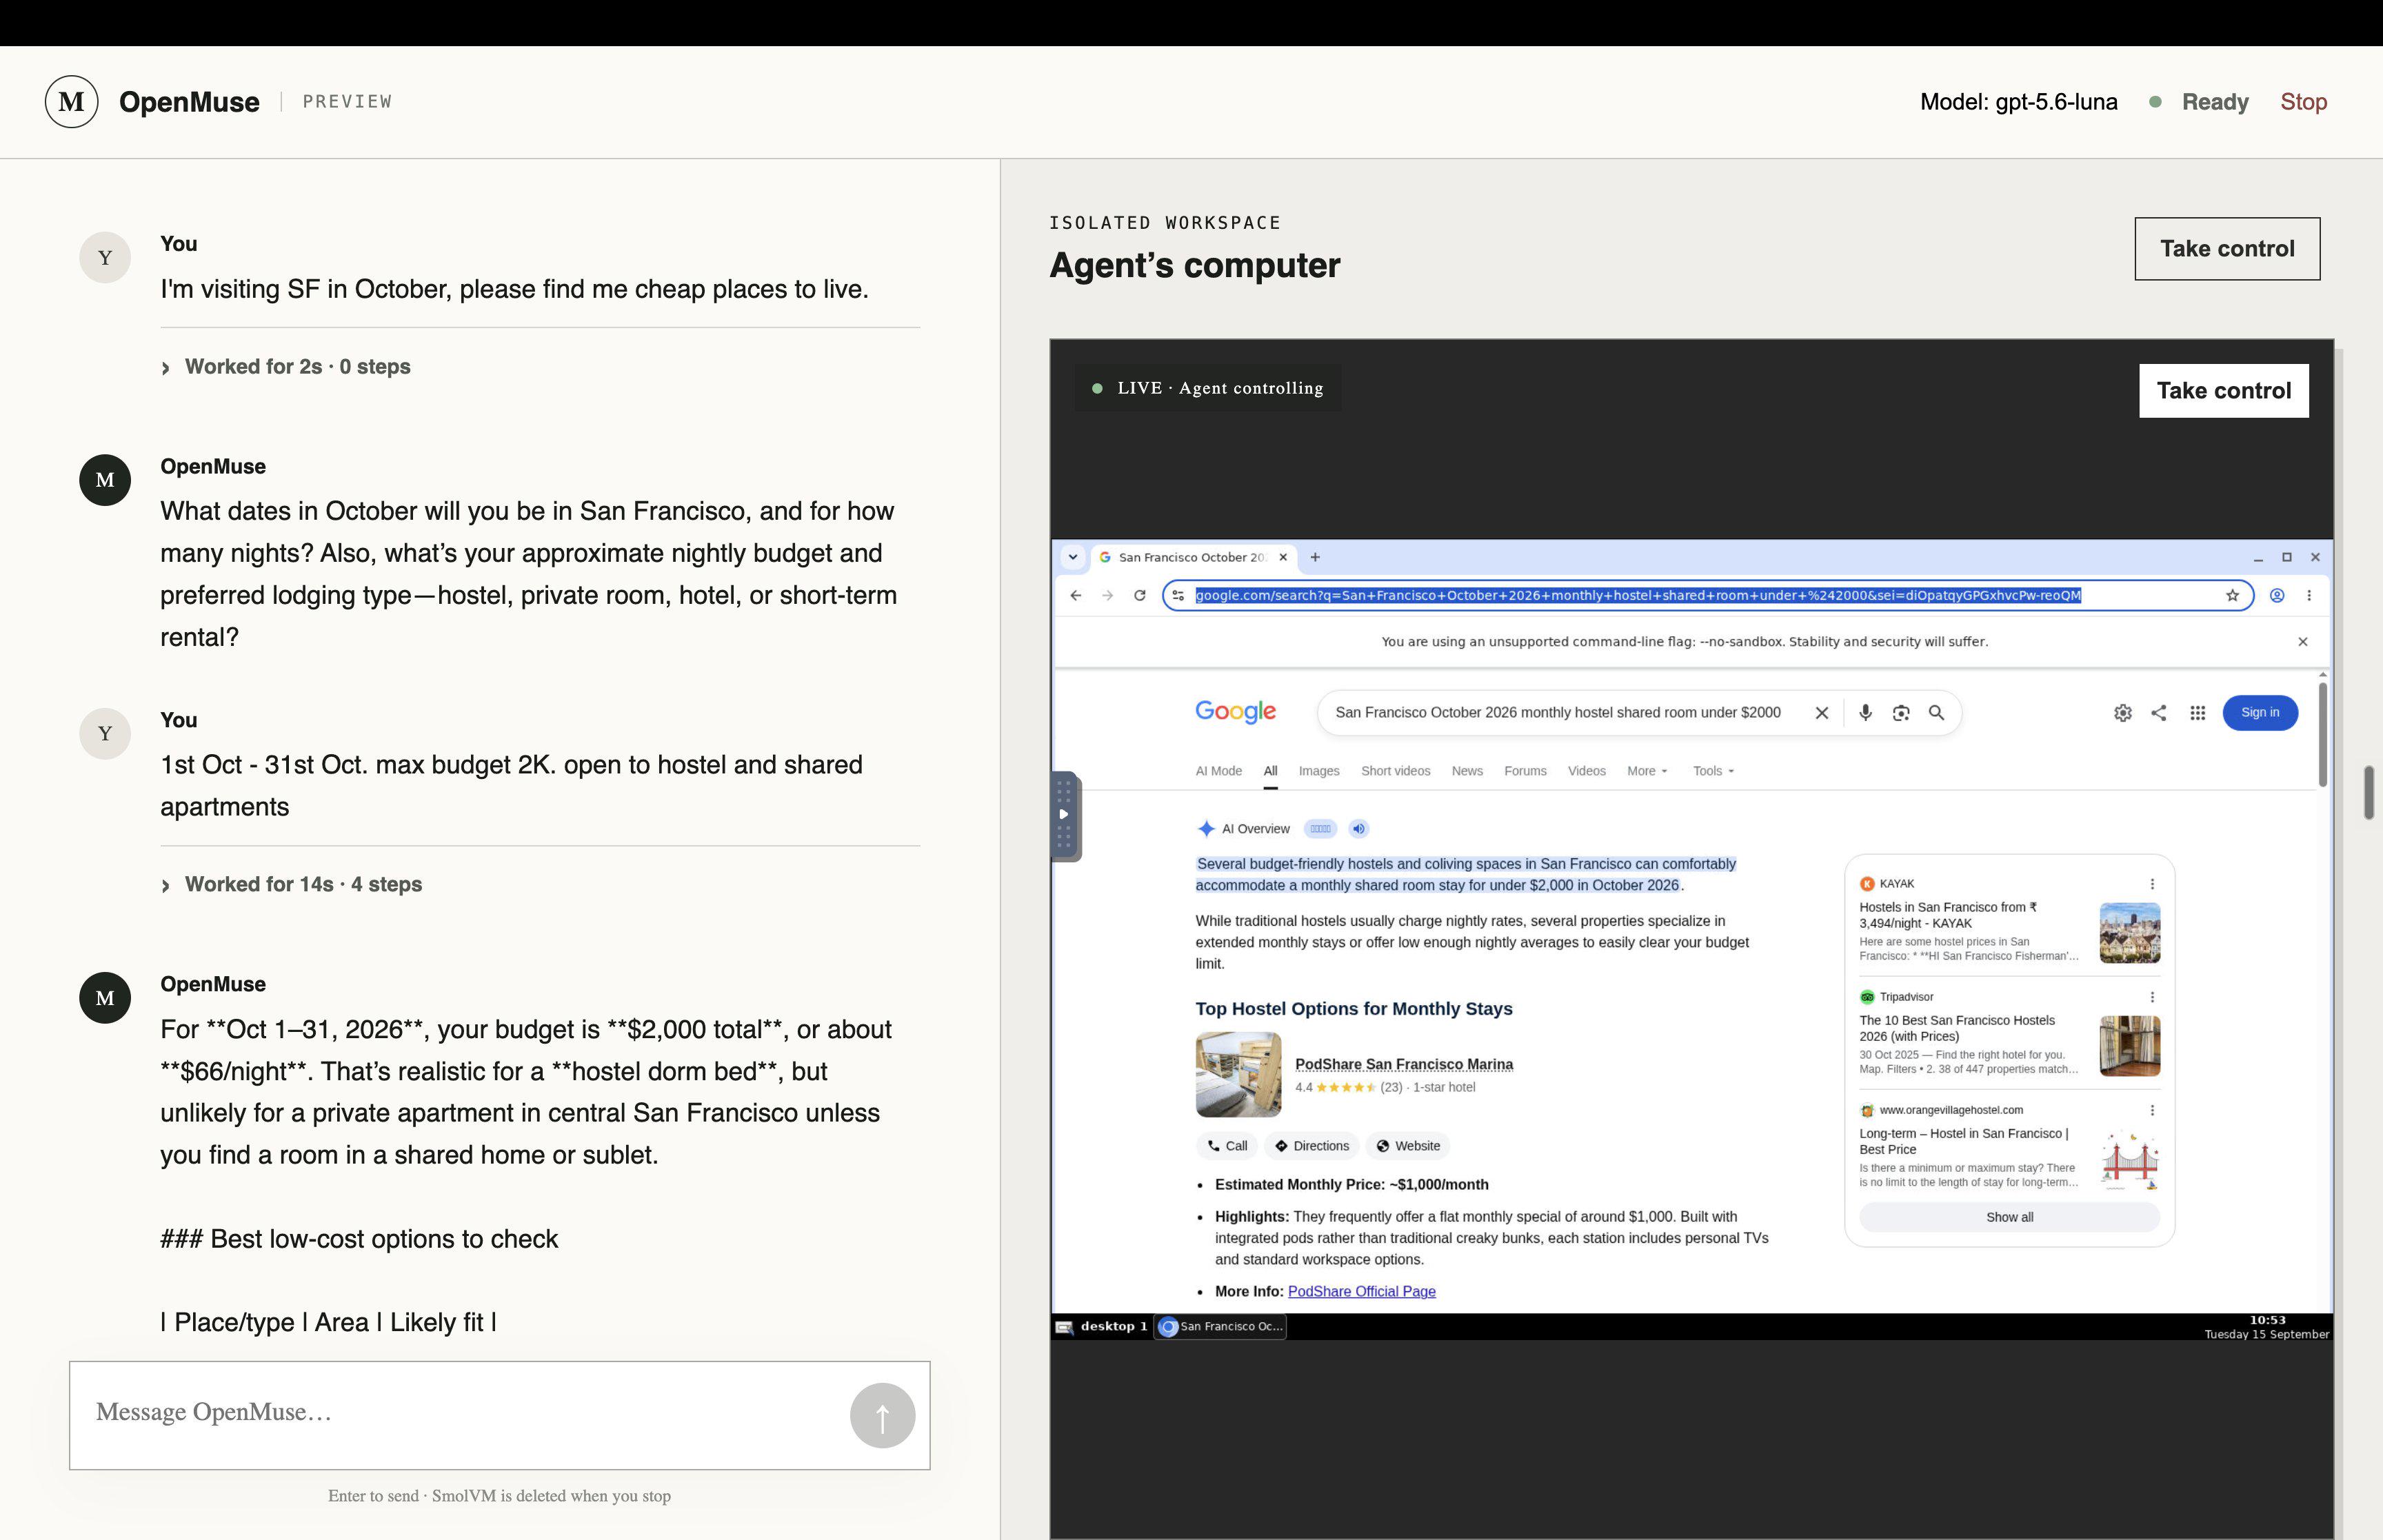
Built an open-source version of the Muse agent app which can be used with any model provider, run privately with local models.
Please give it a try and reach out for any feedback ✌️
https://github.com/CelestoAI/celesto/tree/main/open-muse
VS Code extension that adds Muse Spark 1.3, 1.2, 1.1 and Contributor variants to the Copilot Chat model picker with a Meta API key, published on the Marketplace and Open VSX.
A pinned llama.cpp recipe for Muse Glimmer 30B on one NVIDIA GB10 that verifies Meta's official GGUFs by SHA-256 and reproduces text, tool-call, coding, vision and throughput checks.
A fork of DeepSeek's DeepSpec that trains a fresh DSpark speculative drafter for Muse-Glimmer-30B in place of the shipped DFlash drafter, with the full data-to-eval pipeline working on GPU.
OK, for context, I have Claude Code desktop app driving the CLI and orchestrating the code and verification tasks to try to save tokens. So Claude runs things, a Deepseek 4.1 Flash (cloud) session does the planning, Qwen 3.8 27b Q8 does the boiler plate coding and Muse Glimmer sanity checks the code and pushes any issues back to Qwen. If there are issues Qwen and Glimmer can't agree on, Deepseek validates. If Deepseek can't sort it out, it goes back to Claude.
This had been working fine, but then in the last few days token use spiked, tasks that used to take 10 minutes were taking an hour or more and Qwen started going into more and more reasoning loops.
It seems that since I last checked (on 12th September) the CLI changed. I used to strip unnecessary tool calls from the prompt using --disallowedTools and enabledPlugins: false.
It would seem that these no longer work.
In the end I got Claude to build a request-dumping diagnostic server, that actually measured the payload bytes, and confirmed --tools (an allowlist) is the flag that works now: 55→7 tools, 161KB→24KB, byte-verified. It also caught something specific to my workflow running the wrapper from inside an already-active
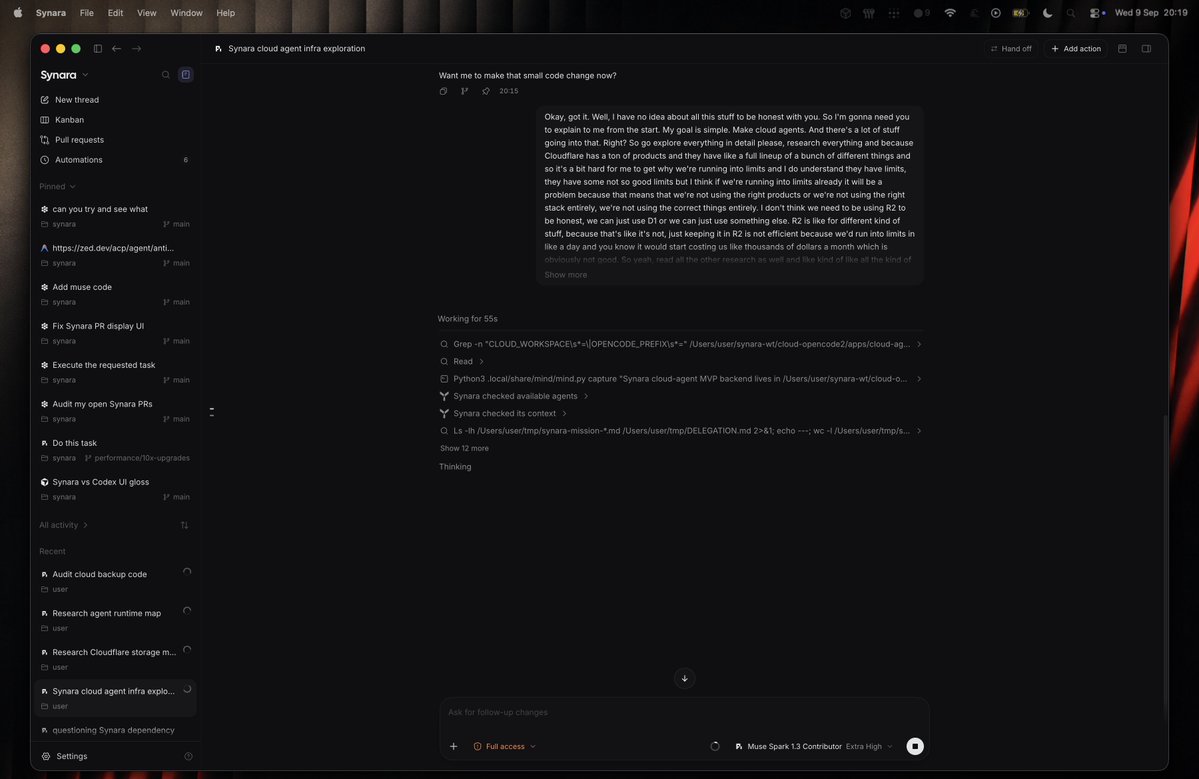
I swear Muse Spark 1.3 is a really good model. Like I don't know if it's just my setup or something. But it just constantly surprises me. So in Synara there's a thread/agents tool where it can create new threads and communicate and manage agents. And literally always, like
the $16/month @Muse subscription is a media beast
there's no 5-hour limit
you can generate:
- video w/music
- voiceovers
- infographics
- sound effects
- edits with @HyperFrames_
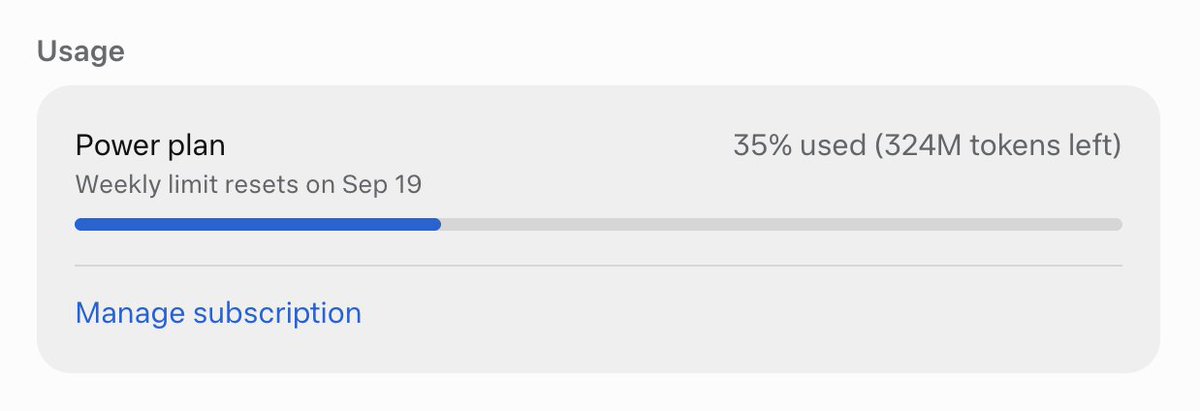
I'm nowhere near my weekly limit even after running aggressive quality check loops
Wires TypeSafe Jev into a Muse agent's decision loop via a shadow-mode router that asks typed questions before expensive or irreversible steps, plus a 23-skill library the router picks from.
A reproducible setup serving Muse Glimmer 30B on one AMD MI300X with a custom 11 GB vLLM 0.28.0 ROCm image, exposed as an authenticated OpenAI-compatible endpoint and driven from the pi CLI.
A prebuilt macOS arm64 bundle for the Muse Glimmer voice-agent recipe in meta-oss-cookbook: Parakeet speech helper, Muse Glimmer worker and Supertonic TTS executables built from one pinned ExecuTorch checkout, plus the shared MLX Metal library.
Matt Naughton's merchant guide to Muse as a Shopify AI channel: where the Agentic toggles live, what direct checkout does, and why browser pixels don't fire on Meta-side checkout, so only server-to-server events count.
You.com's harness for evaluating Muse Glimmer 30B on DeepSearchQA with You.com MCP tools inside pi sessions. A custom RLM v5 extension reached F1 0.8054 on 50 tasks (0.6910 over 900x3) versus 0.50 for plain skill injection.
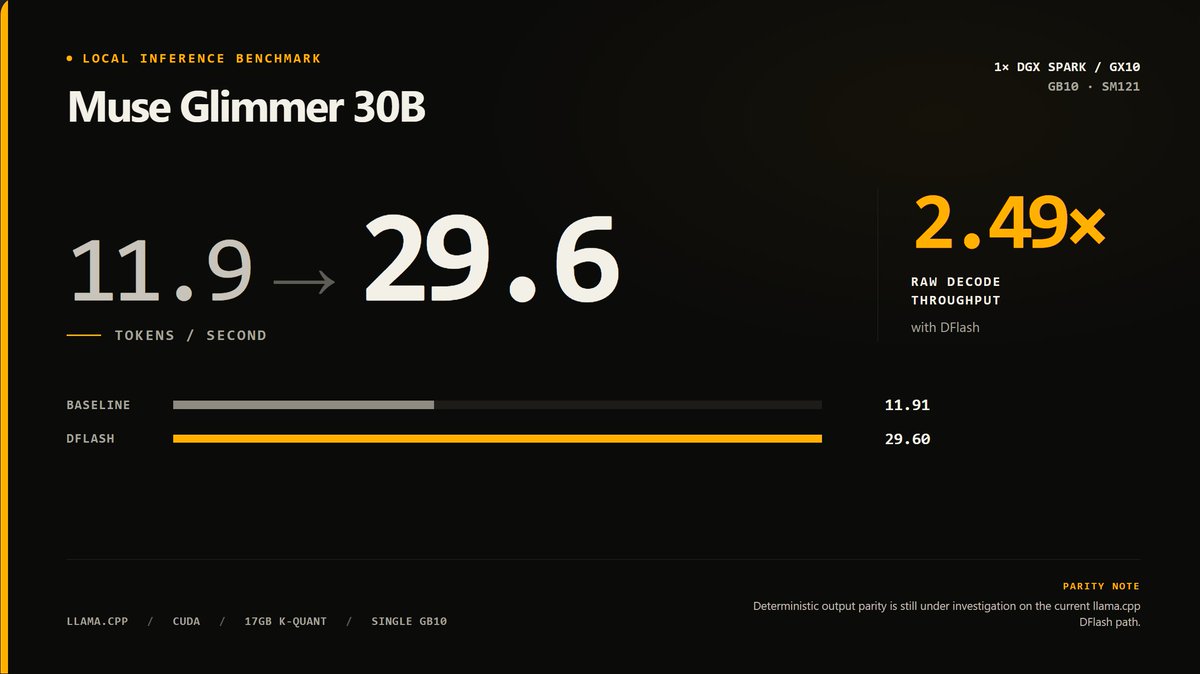
got Muse Glimmer 30B running on a single DGX Spark / GX10 at 29.6 tok/s with DFlash, up from 11.9 tok/s baseline, 2.49× raw decode throughput.
packaged the whole thing into a reproducible GB10 recipe:
- pinned weights + SHA-256s
- llama.cpp compiled for GB10 / SM121
- baseline
Muse Glimmer one-shot 5 games!
@AIatMeta dropped Muse Glimmer. So we ran it against Muse Spark 1.2, on five one-file game demos, each one written to play itself: Tetris, a top-down pixel street race, a rooftop web-slinger, a blue hedgehog platformer, and Flappy Bird.
the setup:
loot radar is my game deals site, radar.codemeoww.com. tracks deals and freebies across stores like steam and epic, ranked by discount and popularity.
features: daily loot summaries on telegram and discord, fast price alerts, a morning deals digest, wishlist tracking so you get pinged when a game you want drops, and an api for the deal data.
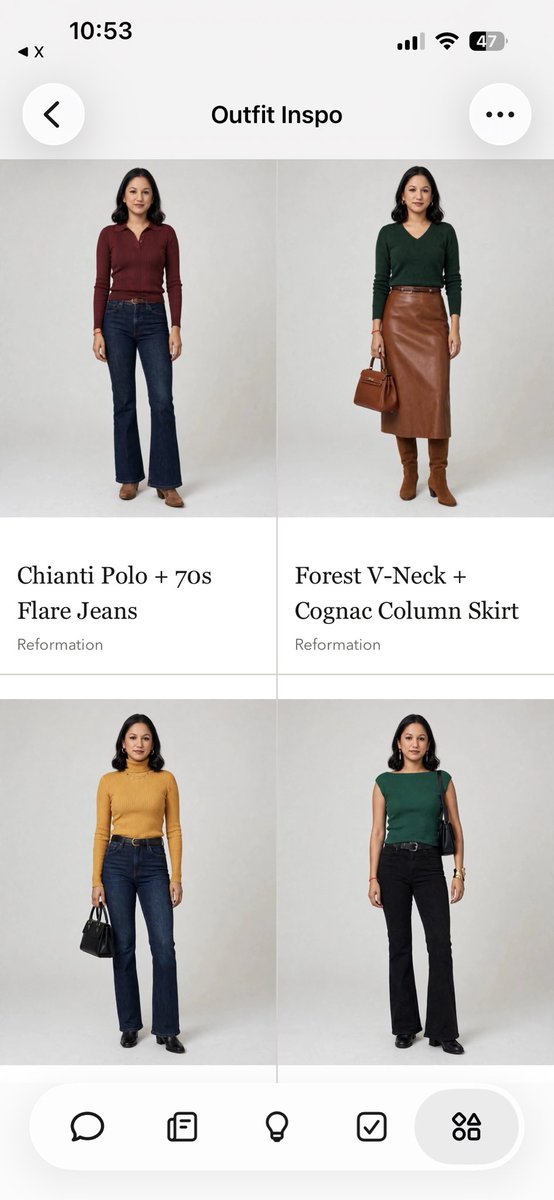
i’ve spent a ton of hours and tokens prompting @Muse to make me this custom fashion app but holy crap is it worth it:
- gave it my height, weight, measurements, and photos
- gave it my top 20 clothing stores and budget ranges
- it picks a “hero piece” from the catalog
- then
A self-hosted mini arcade cabinet on a Raspberry Pi that generates SNES-style games from a player photo and a voice prompt, using Muse Spark to judge art and Muse Image and Muse Voice Transcribe for assets and input.
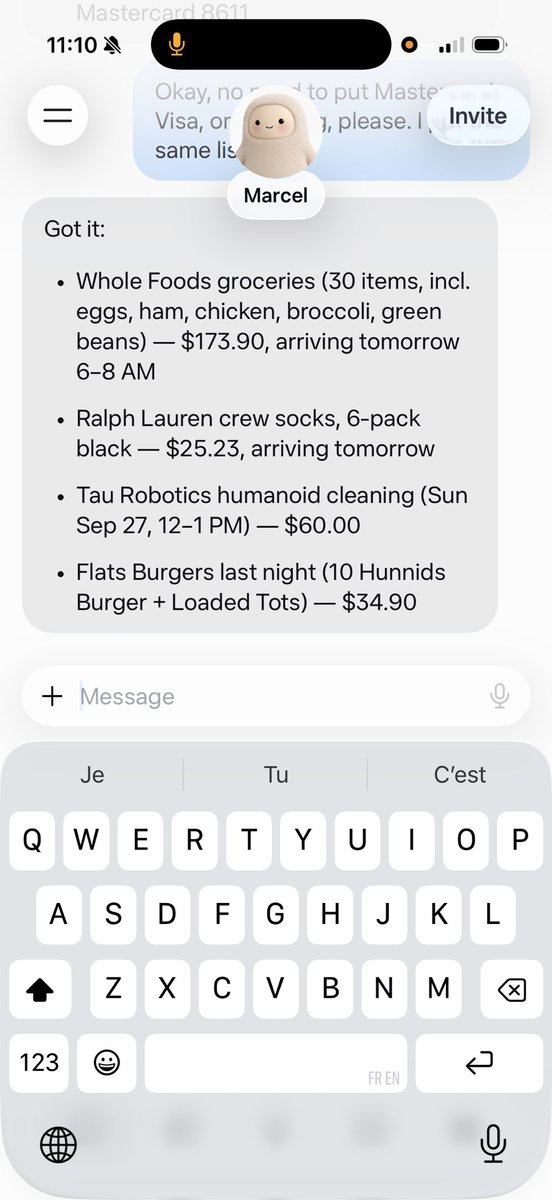
It’s funny, Meta went from having my Instagram and WhatsApp data to now having access to my email, calendar, DoorDash, Amazon and pretty much everything.
In the last 24 hours, it bought me socks, ordered my Whole Foods groceries, booked a cleaning service and got me a burger for
Pi extension that lets you sign in with a Meta Muse Code subscription via device code and pick meta-muse models, verifying the subscription so it never falls back to pay-as-you-go.
PIMX_ELTEX runs Muse Spark 1.3 in OpenCode on six prompts, from 3D games and an open-world mini GTA to car simulators and web apps, at about 3 minutes per project.
Pi extension that registers a muse-code provider through @muse-code/sdk over the Muse Session Protocol, resuming the same Muse session when switching models mid-conversation.
muse-glimmer-mlx is an MLX port of Muse Glimmer 30B for Apple Silicon that supplies the missing runtime so the many unloadable MLX conversions published on Hugging Face can actually be run.
Pietro Zullo walks through submitting a hosted MCP server to the Muse connector platform: the three-step form (overview, technical specs, review) and what Meta's functional and security review checks.
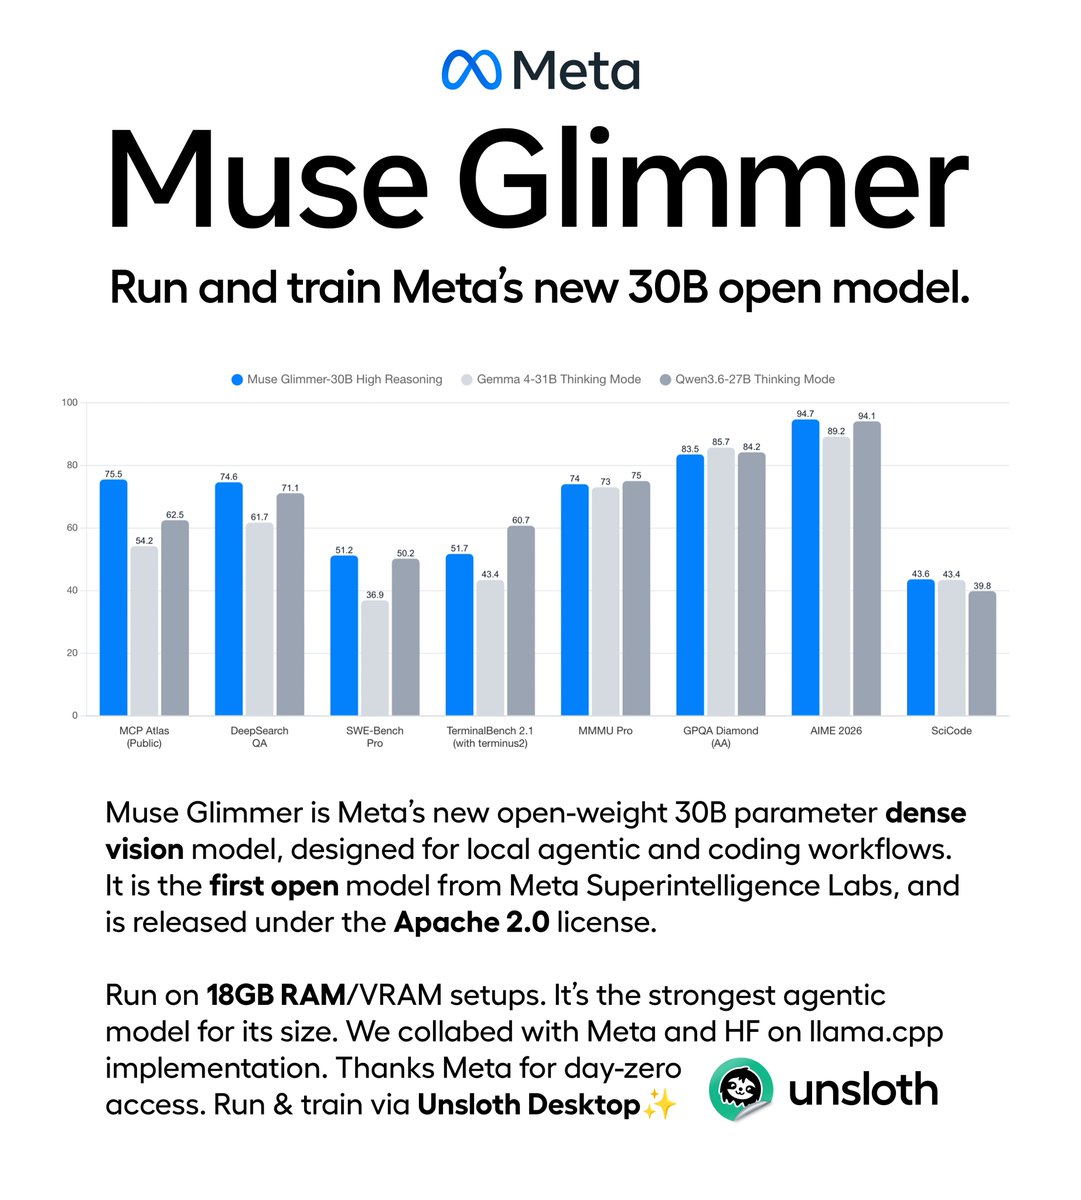
Wavect's guide covers Glimmer's hardware targets (24–32GB) and tool-use scores such as MCP-Atlas 75.5 and SWE-Bench Pro 51.2, and recommends a 20–30 task pilot before production.
Meta releases Muse Glimmer, a new 30B open model that runs on 18GB RAM.
Muse Glimmer is Apache 2.0 licensed, supports vision and is the strongest agentic model for its size.
Run and train the model via Unsloth.
GGUF: huggingface.co/unsloth/Muse-G…
Guide: unsloth.ai/docs/models/mu…
Had to print something as a guest at Stanford library. Muse signed up for a guest account, added money to my account using my CC, put together and uploaded the PDFs to the printing portal and then told me simply to go downstairs and pick it up at the printer
Muse Glimmer is now available to run with Ollama.
Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama.
Additional support and
BB plugin that runs Muse Code as a first-class provider over the Muse Session Protocol, with streamed timeline, tool rows, approvals, model picker and a subscription usage meter.
Same old prompt, just appended a TIP in the end:
"Write a single HTML file with a full-page canvas and no libraries. Simulate a realistic side-view of a moving car as the main subject. Keep the car visible in the foreground while the background landscape scrolls continuously to create the feeling that the car is driving forward. Use layered scenery for depth: nearby ground, roadside elements, trees, poles, and distant hills or mountains should move at different speeds for a natural parallax effect. Animate the wheels spinning realistically and add subtle body motion so the car feels connected to the road. Let the environment pass smoothly behind it, with repeating but varied scenery that makes the movement feel believable. Use cinematic lighting and a cohesive sky, such as sunset, dusk, or daylight, to enhance atmosphere. The overall motion should feel calm, immersive, and realistic, with a seamless looping animation.
TIPS: You don't have vision abilities so don't try it yourself. If you feel in need of vision ability, you can access http://xxx:8080/v1, model id: Muse-Glimmer for help, it will see the picture, and describe it for you."
Then the PI agent started spinning, round a
Here is a crazy Jev @typesafeai example that I’m betting nobody has thought about:
I asked @Muse from @Meta to use Jev to select the top 100 unanswered questions in immunology from 10,000 literature-grounded candidates. A few minutes later, it came back with some of the best
A set of small fixes that let Muse Spark run in pi, Agent Orchestrator, opencode and other OpenAI-compatible tools, handling its non-standard SSE event and missing model-catalog entries.
It's all about the tiny details!
I asked muse.ai to create its own profile pic, it did so, and renamed itself to Wolfred. But then I noticed that they also created a cute animated gif of wolfred working and they are showing it when it... does stuff! very cute
STARTUP HAKK tests Muse Spark 1.3 and argues the harness, tools and context around a model matter as much as the model, pitching their OpenMonoAgent harness.
Muse has been good, surprised that this happened
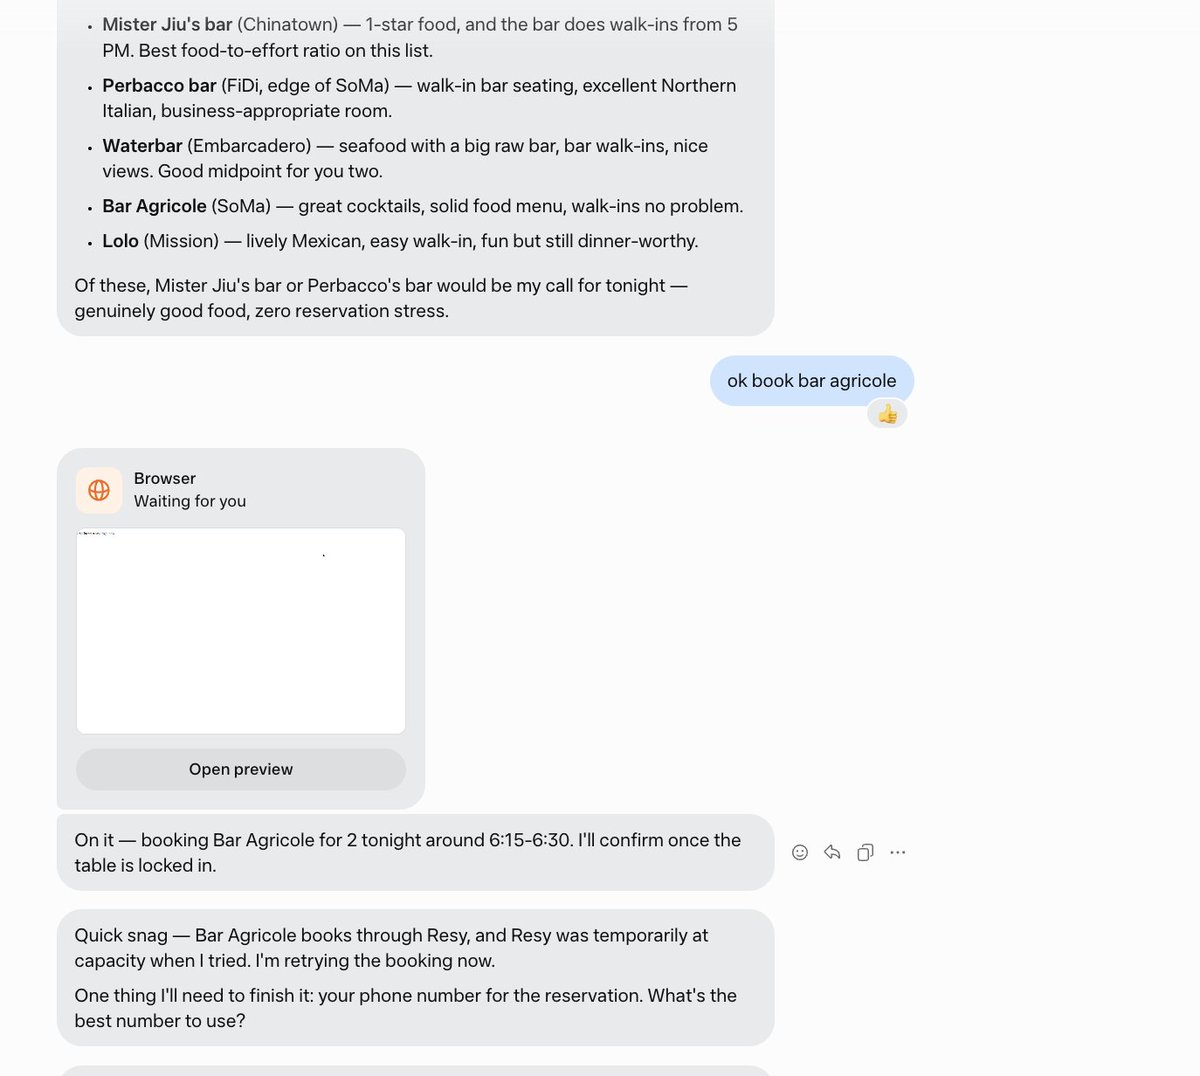
I asked it where to go for dinner, it recommended Bar Agricole, and then tried to book it for 7 mins, but couldn't get through.
The only problem is that Bar Agricole has been closed for 2 years!
A reproducible single-GPU deployment of Muse Glimmer 30B in BF16 with DFlash speculative decoding on a 96GB RTX PRO 6000 Blackwell, served via vLLM with pinned overlays and smoke tests.
A BYOK VS Code extension that registers the InferHub catalog, including Muse Spark with its 1,048,576-token context window, as a model provider in the Copilot Chat picker without Copilot Pro.
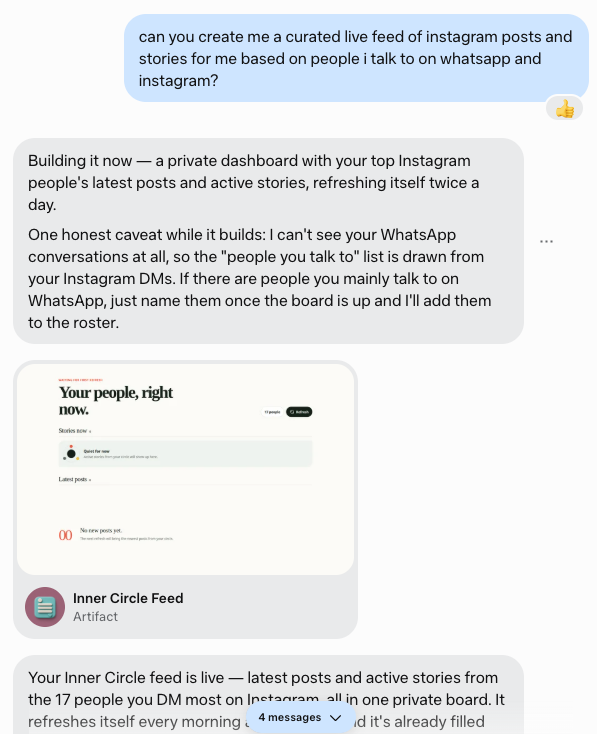
I deleted Instagram from my phone a couple of years ago because so much of the feed felt irrelevant and distracting. But one thing I missed was seeing updates from my friends and family.
So I asked @Muse to build me a personal feed just for that. It used my DMs to figure out who
✨ Three New Models, Sharper Lore Awareness & Smoother Storytelling Across Complex Worlds
This update introduces three new storytelling models, improves how Lore is recognized and prioritized during a story, and brings another round of reliability improvements to the model experience.
🎭 Three New Voices 💎 Gemini 3.8 Flash — Pro+ Google’s newest fast storyteller, with polished prose, responsive pacing, and a steady grip on complex scenes.
Context support:
🔹 16K on Pro
🔹 48K on Ultra
🔹 80K on Legendary
Context limits subject to change.
✨ Muse Spark 1.3 — Plus+ Vivid character interplay, strong world-state awareness, and deliberate continuity as stories evolve.
Context support:
🔹 16K on Plus
🔹 32K on Pro
🔹 64K on Ultra
🔹 100K on Legendary
🌐 Hunyuan 4 Preview — Pro+ Built for ambitious living worlds, shifting relationships, and large casts with lasting consequences.
Context support:
🔹 16K on Pro
🔹 32K on Ultra
🔹 48K on Legendary
📚 Sharper Lore Awareness Lore is getting better at recognizing what matters in the current scene.
🏷️ Smarter Lore activation — Lore cards can now activate when their title or character name appears naturally in the story, even
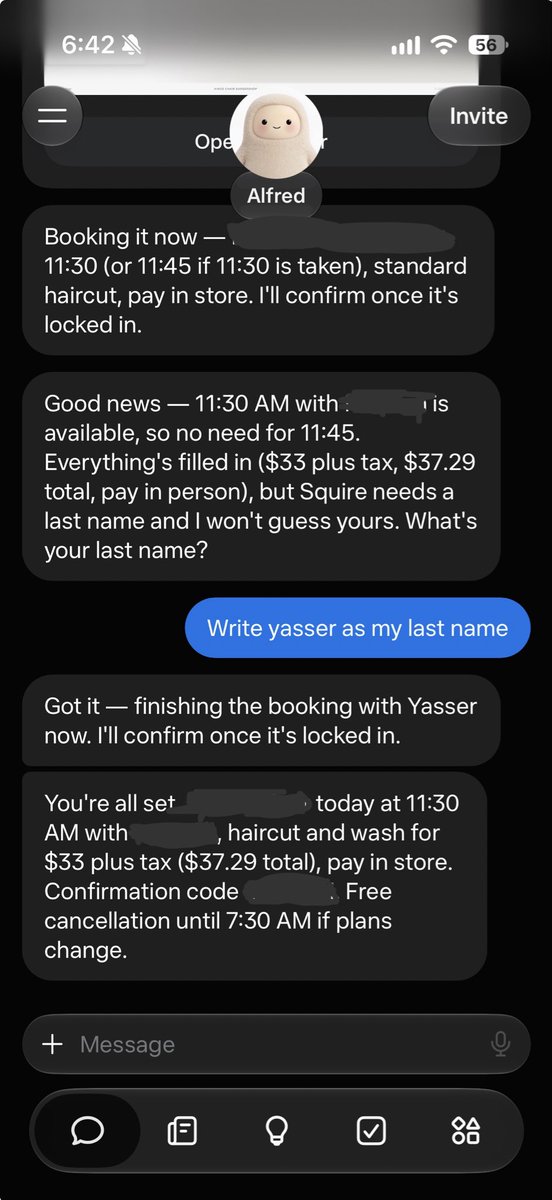
I just told @Muse
- Find me a good barber in my city
- Under $50
- Available Sunday at 11:30AM
- Check Google reviews + Reddit
- I don’t like fades, I usually get a crew cut
It found one, picked the best reviewed barber, and booked the appointment, all without me touching
Hi Everyone, we recenly built - https://www.builderhq.co/agent-commerce
It’s basically a simple tag you add to your website that creates an AI agent for your business. Its entire job is to convince other AI agents to shop on your platform.
Let’s say Muse, Meta’s AI agent, visits your website. It will see an AI agent from your business that can talk to it, understand what it’s looking for, and help it find the right product.
Interested in trying? send your muse agent to www.easyrecommend.co and lets see the magic
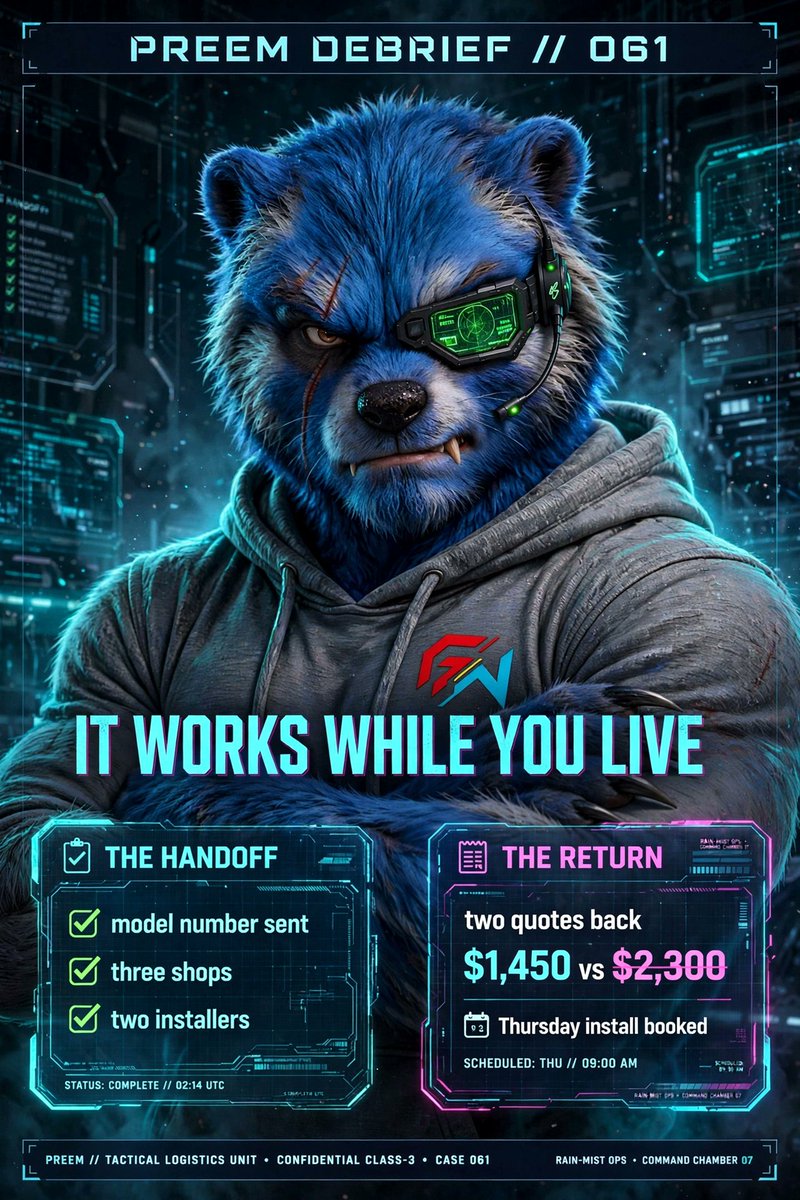
My water heater is dying. I texted Muse the model number at lunch. It compared prices across three shops, emailed two installers for quotes, booked the Thursday job. I worked the counter all day. Came home to two quotes back and an install date. $1,450 beat $2,300.
Siamese Cat Dev pits Muse Spark 1.3 against Claude Fable 5.1 on a browser OS, a Call of Duty-style shooter, a neon arena shooter and a Mario Kart-style racer.
Disclaimer. This is the first time I've used Muse or VSCode as a harness. The reason I am using VSCode as a harness is this is a research project for my job, and we only have VSCode, Codex, and Claude Code approved for harnesses.
I ran it in a folder with only one HTML file (800 lines) that is a Roblox-style COD game. I just gave it a prompt "Can you fix the bugs in the file". It read the file 3 times, found one bug, started to fix it, then got stuck reading the same 10 lines over and over.
I imagine it's one of these three issues.
• It's a prompt error, being way too vague/open ended for the capabilities of a smaller model. I tried again, with a specific prompt to fix a specific bug, and it still just ends up so confused, trying to grep/find the file despite already having read it, and trying to find the code inside of the file.
• It's a limitation of small models running with a large harness/having way too much going on. I tried running it with Pi with its default prompt, and it just got stuck doing tool calls and never actually read the file. Tried running this just directly in the Unsloth Desktop UI with no harness but it failed to parse the file I inputted and tried to gen
holy shit, @Muse just caught $1,742 a week leaking out of my ad account
I asked one question about my ad spend. It did everything else by itself:
> Pulled Meta, my pixel and GA4 and noticed the numbers didn't match
> Split it by age, device and creative, found 4 dead ads eating
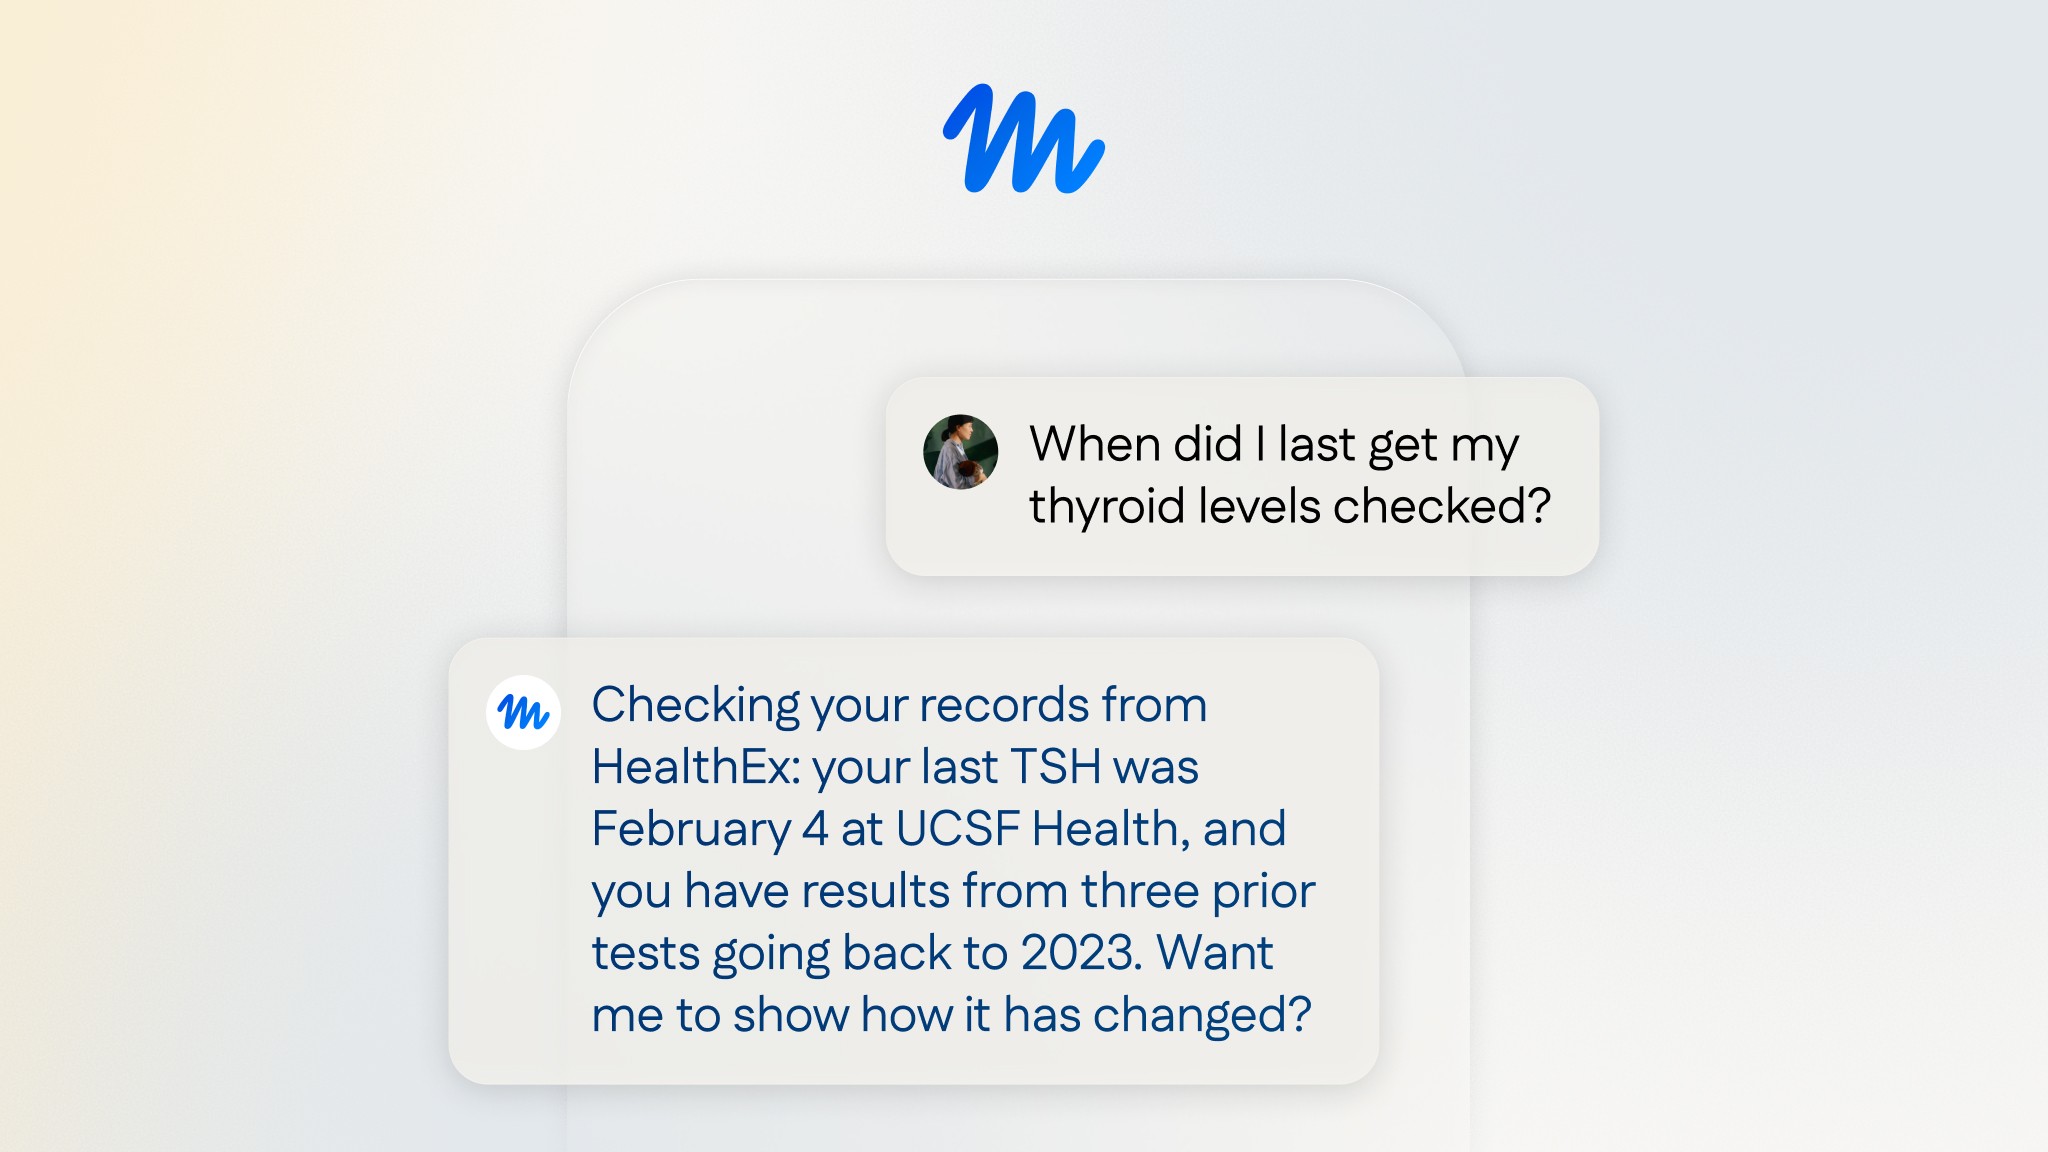
HealthEx launched a connector that lets Americans bring their medical records to Muse, which can then write visit summaries, draft questions for a doctor and set refill reminders.










































 ChatForm
 Tgmlabs