shipwithmuse

Entries matching “official”

26 builds · page 1 of 1

Zach Holman

@holman

Still really enjoying @muse. I use Things.app for all of my todos, and though it has cloud sync they (still) haven’t added an official API. I told muse to build it and a minute or two later I have ongoing todo sync from my LLM across all my Apple devices. Wild.

X post · Connectors & MCP★ Pick· ♥ 77

Todo-app sync built without an official API

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

M

meta-models

meta-models

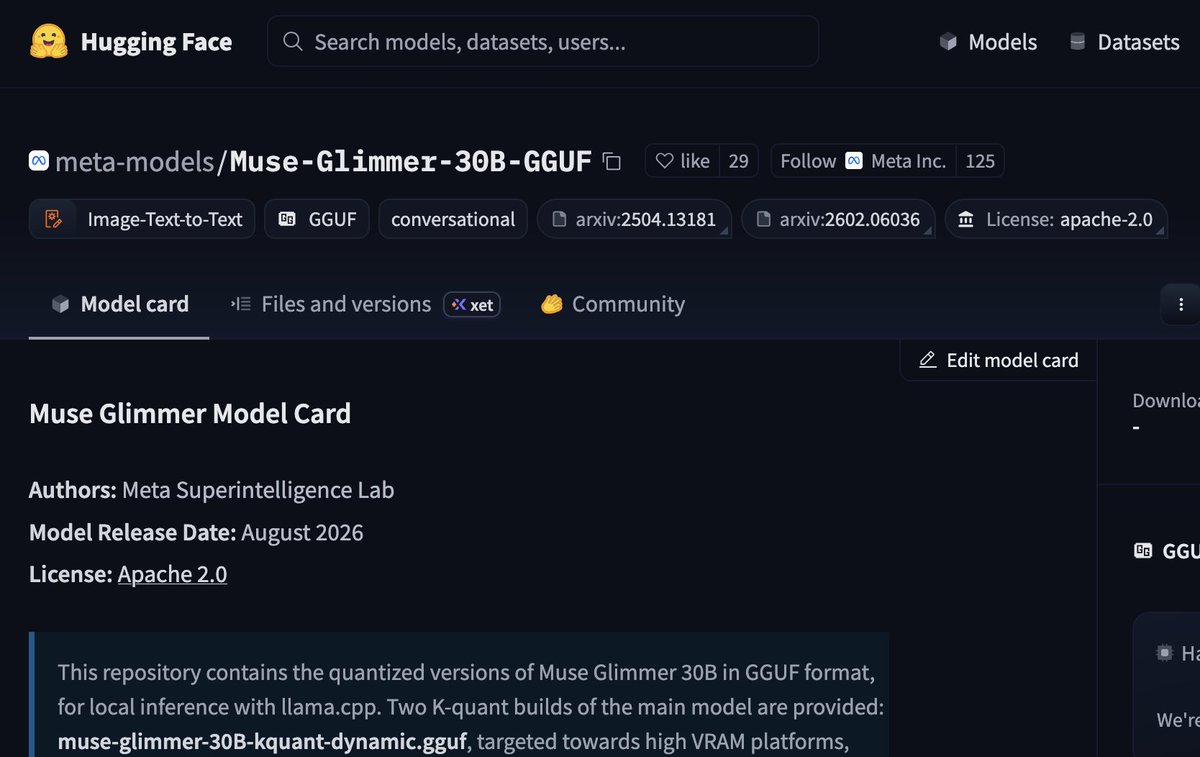
Meta's own GGUF conversions of Muse Glimmer 30B for llama.cpp.

Resource · Local & open models· ♥ 343

Official Muse Glimmer 30B GGUF

@luckeyfaraday

@luckeyfaraday

An unofficial loopback shim that lets Meta Muse Code use OpenAI Responses APIs, OpenRouter, Codex OAuth and the official Claude Code CLI, switchable from Muse's /model menu.

GitHub · Coding & dev tools· ★ 1

muse-shim

Xuan-Son Nguyen

@ngxson

We are happy to announce that Muse Glimmer is day-0 supported on llama.cpp. Meta also provides an official GGUF quant:

X post · Local & open models· ♥ 86

Day-0 llama.cpp support for Muse Glimmer

松xR

@matsu_vr

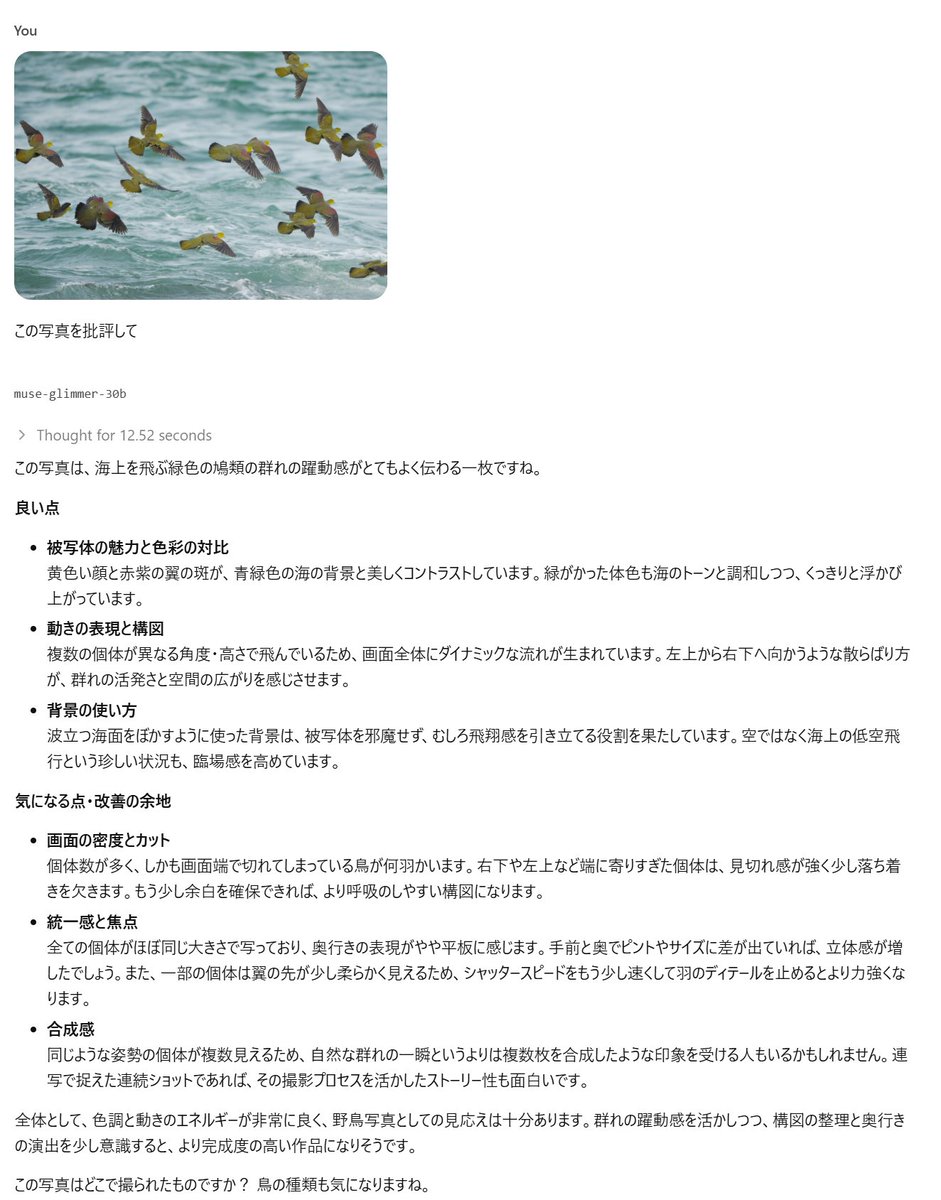
muse glimmer 30Bを公式の17GBに収まるよバージョンのggufでLM Studioで動かしてみました。写真の批評もバッチリしてくれる。これは僕が撮った写真なのでネットにないのでちゃんと写真を見ているはず。コンテクスト長64000にして、VRAM20GB以内に収まっているので、かなり実用的かもしれない!

X post · Local & open models· ♥ 2

Local photo critic with Glimmer in LM Studio

@cezaronx

@cezaronx

A reference CUDA worker that serves Meta's official Muse Glimmer 30B GGUF through llama-server on Runpod Serverless load-balancing endpoints or manual Pods, exposing a real OpenAI-compatible API.

GitHub · Local & open models

Muse Glimmer Runpod serverless worker

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@johnhalloran321

@johnhalloran321

Scripts that run Muse-Glimmer-30B with vision and tool calling on a 32GB M2 MacBook Pro via llama.cpp and Metal, without admin or sudo access, pulling Meta's official GGUFs.

GitHub · Local & open models· ★ 1

Muse Glimmer 30B on a 32GB Mac

@harris-ryder

@harris-ryder

Dowser is a read-only MCP connector for Muse that surfaces open class-action settlements, product recalls with refunds, unused card credits, expiring points and birthday freebies, each with an official link.

Skill · Errands & personal agent

Dowser: find the money hiding in your life

@arananet

@arananet

A CLI that opens a shop in headless Chromium to check whether an AI shopping agent can discover and act on the page, and can ask a real Muse Code agent to shop it through the official @muse-code/sdk.

GitHub · Business & commerce

muse-commerce-audit

@MiaAI-Lab

@MiaAI-Lab

A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.

GitHub · Local & open models· ★ 8

Muse Glimmer 30B NVFP4 for DGX Spark and RTX 5090

U

6353JuanTaboApp6

u/6353JuanTaboApp6

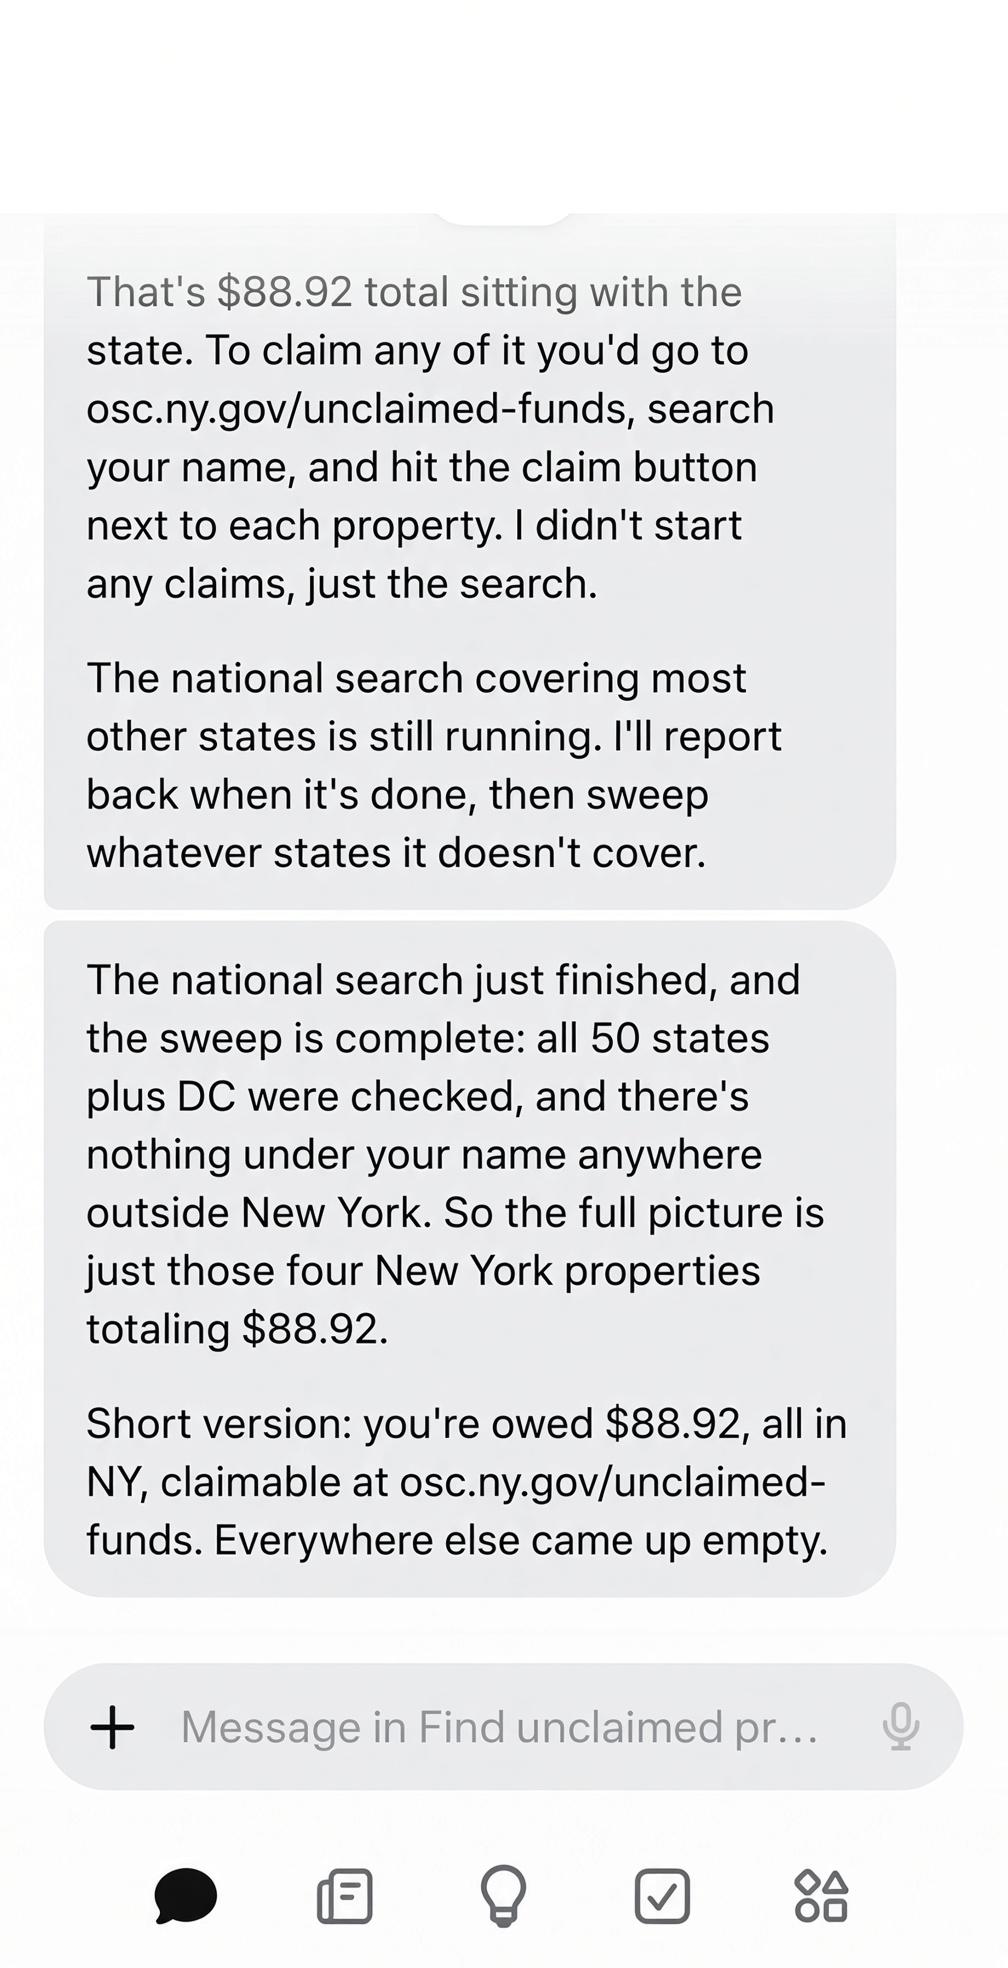
Muse found that i was owed $88.92 PROMPT: Research every state’s official unclaimed property database for money owed to me. Use my full name and every city I’ve lived in. For anything you find, tell me what it is, who owes it, and how much. My government name is _______

Reddit post · Errands & personal agent

Unclaimed property search across every state

U

StartupTim

u/StartupTim

Heeeey all! I just completed some fun tests with Muse Glimmer, I thought I'd let you know. In fact, the summary below was written by Muse itself! I ran a 2× DGX Spark cluster and got Meta's day-old Muse Glimmer 30B running the day after release — then pushed its context from the trained 131K all the way to 1M with YaRN, verifying retrieval at every rung. Sharing config + results since the "131,072+" hint in the model card turned out to be very real. Setup • Hardware: 2× NVIDIA DGX Spark (GB10, 128 GB unified each, ~273 GB/s), ConnectX-7 direct link between them • Engine: llama.cpp master (day-1 muse_glimmer support), built from source with CUDA sm_121 + GGML_RPC • Model: official Muse-Glimmer-30B-GGUF K-Quant-Dynamic (~18.3 GiB) + official mmproj (vision) + official DFlash drafter • Spec decode: --spec-type draft-dflash --spec-draft-n-max 15 (block-diffusion drafter) • Context extension: --rope-scaling yarn --rope-scale <2/4/8> --yarn-orig-ctx 131072 plus --override-kv muse-glimmer.context_length=int:<N> (llama.cpp caps at trained length otherwise) • Yes, we also ran it split across both Sparks with llama.cpp RPC — no reason beyond liking to cluster things for fun. Our daily dri

Reddit post · Local & open models

Muse Glimmer at 1M context on 2x DGX Spark

M

@muse

@muse

Alex Cornell walks through how his Muse buys movie tickets, plans family weekends and helps his chess game, covering the chat tab, feed, proactive ideas, goal tracking and library.

Video · Errands & personal agent★ Pick

Official full tour of the Muse personal agent

U

PyaesoneP

u/PyaesoneP

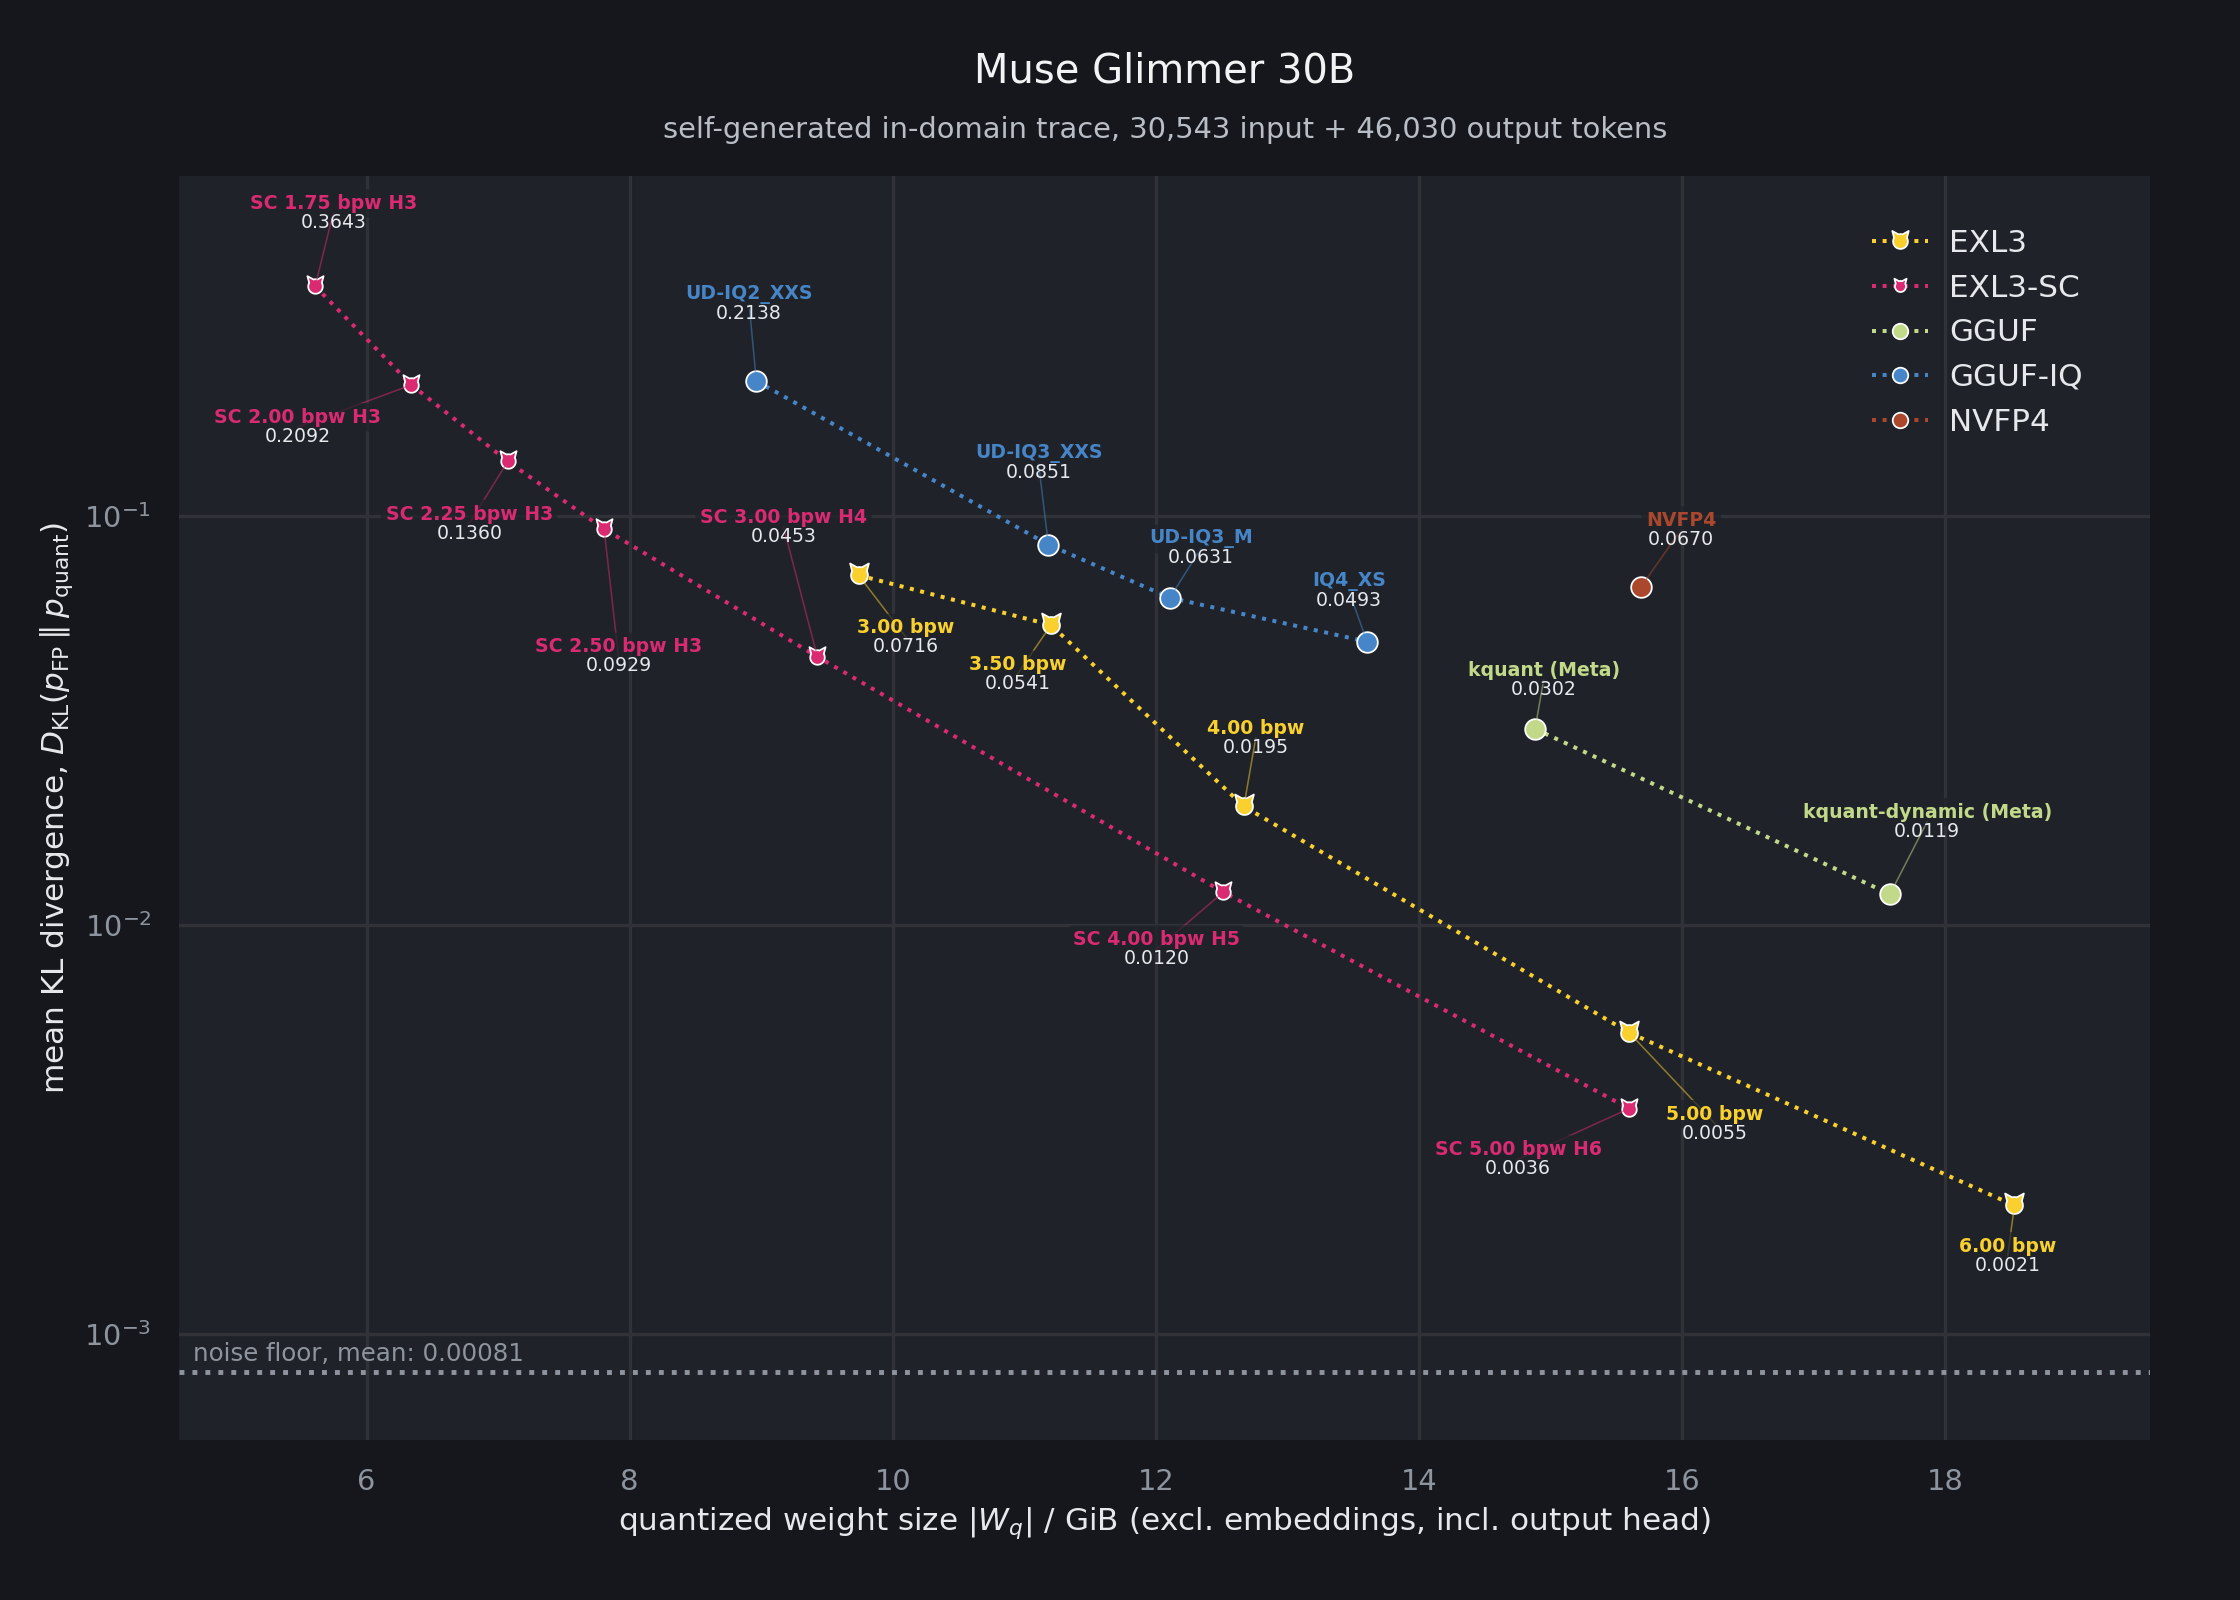
I'm running Muse Glimmer 30B EXL3-SC 3.00bpw H4, fully resident on my 12GB VRAM GPU at 100K context with Q8\_O KV cache. It's a joy to use a dense 30B model at this size and still get \~30 tok/s on a VRAM-constrained laptop. It's supposed to be only slightly worse than the official 17GB K-quant at a much smaller footprint, and for my Hermes Agent use case I don't notice a quality difference. It's just much faster. I've tried Qwen 3.8 27B at SC2.20bpw H3 too. Definitely usable but I'm sticking with Unsloth UD\_Q4\_K\_XL for Qwen 3.8 27B because it's mainly for coding.

Reddit post · Local & open models★ Pick

Muse Glimmer 30B on a 12GB laptop GPU

Cristian Uibar

@cristianuibar

@theo please add support for Muse Code in T3. I've opened a PR here for it using the official SDK. github.com/pingdotgg/t3co…

X post · Coding & dev tools· ♥ 1

Muse Code support PR for T3 Code

M

meta-models

meta-models

Meta's lightweight DFlash block-diffusion drafter for Muse Glimmer 30B that predicts blocks of 16 tokens per forward pass for speculative decoding.

Resource · Local & open models· ♥ 61

Muse Glimmer DFlash drafter (official)

Muse

@Muse

Get more done with Muse with two new connectors: ✅ @meetgranola: your meeting notes ✅ @NotionHQ: your docs …and more coming soon! Ask Muse or connect in settings.

X post · Connectors & MCP· ♥ 542

Granola and Notion connectors land in Muse

@emman27

@emman27

MCP server built for the Muse connector directory that answers Singapore bus arrival times and MRT/LRT service questions using the official LTA DataMall API.

Skill · Connectors & MCP

SG Bus + Train connector for Muse

Trapit Bansal

@TrapitBansal

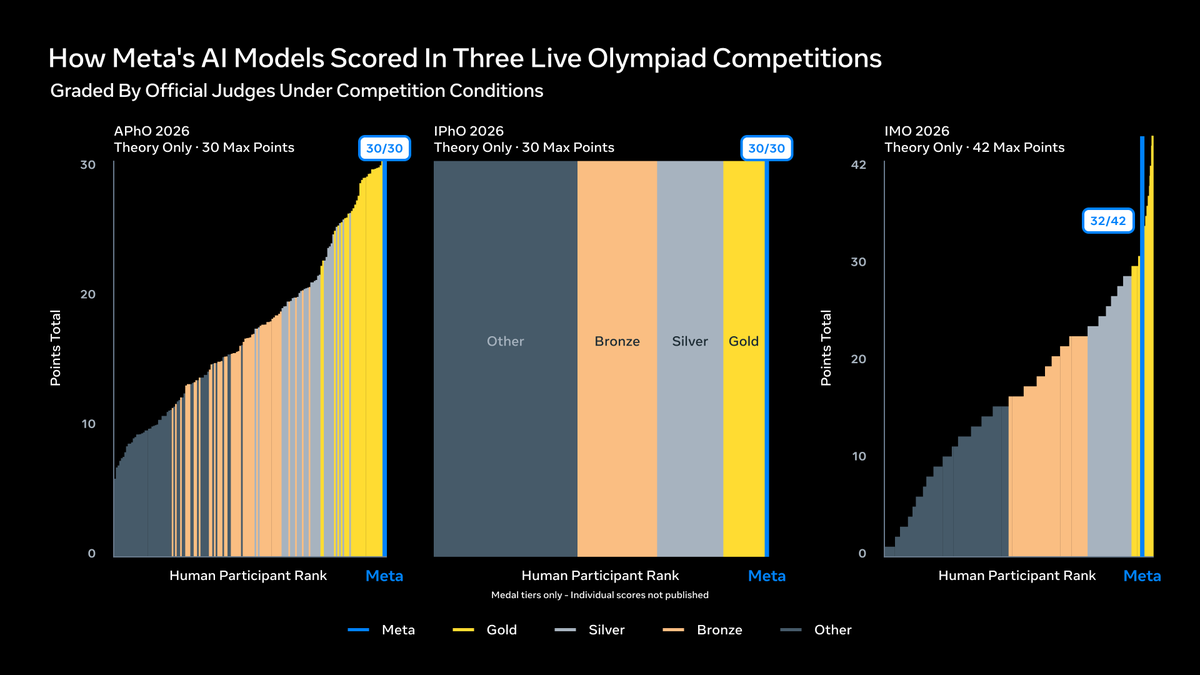
We entered Meta models in five international STEM Olympiads, as an uncontaminated eval of their reasoning capabilities. Three of these were live participations and graded officially. The models achieved gold-medal results in all five! 1/5

X post · Benchmarks & research· ♥ 219

Olympiad golds as an uncontaminated eval

@itsgoharr

@itsgoharr

Threadwell Slack is an open-source Muse connector that bridges to Slack's official MCP server via a local OAuth bridge, submitted to the Muse Connector Platform with a full submission pack.

Skill · Connectors & MCP

Threadwell Slack connector for Muse

@sxuff

@sxuff

A pinned llama.cpp recipe for Muse Glimmer 30B on one NVIDIA GB10 that verifies Meta's official GGUFs by SHA-256 and reproduces text, tool-call, coding, vision and throughput checks.

GitHub · Local & open models· ★ 1

Measured Muse Glimmer recipe for DGX Spark

P

postiz.com

postiz.com

Postiz's Nevo David shows how to hook Postiz's OAuth MCP server into Muse through the custom-connector path, so Muse can schedule posts across 30+ platforms before an official directory listing.

@meta-models

@meta-models

Meta's official recipes for building agents and coding tools on the Model API with Muse Spark 1.3, covering API basics, multi-agent patterns and end-to-end use cases via OpenAI- and Anthropic-compatible SDKs.

GitHub · Coding & dev tools· ★ 136

Meta Model API cookbook

U

curiousily_

u/curiousily_

Setup the latest (master) version of llama.cpp server with the guide and the official GGUF weights by Meta AI: https://huggingface.co/meta-models/Muse-Glimmer-30B-GGUF and connected the Hermes Agent to the llama.cpp endpoint. Getting about 22t/s (+3-4t/s) on M5 Pro, using ~24GB including the drafter (provided by Meta). The model did correct tool calls and actually did some useful work inside the Hermes Agent. Moreover, the resulting coding task/project works, which was not the case when running the model with OpenCode. Watch more: https://www.youtube.com/watch?v=cmENEolUtM4

Q

huggingface.co

huggingface.co

A quantization-aware-trained Q4_0 GGUF of Muse Glimmer 30B for llama.cpp. On held-out tokens it measures closer to BF16 than Meta's official Q4_K_M: 0.0213 vs 0.0228 KL and 95.9% vs 95.6% top-token agreement.

Resource · Local & open models· ♥ 3

Muse Glimmer 30B native Q4_0 QAT GGUF

M

huggingface.co

huggingface.co

Meta's official Muse-Glimmer-30B repo: ~29.6B dense model with a 1.8B vision encoder, 131K context, Apache 2.0, with vLLM and SGLang serve commands.

Site · Local & open models

Muse Glimmer 30B weights on Hugging Face