KGP Talkie benchmarks generation speed, VRAM use and long-context behavior for both models on one RTX 5090.
Resource · Local & open models
6 builds · page 1 of 1
KGP Talkie benchmarks generation speed, VRAM use and long-context behavior for both models on one RTX 5090.
Resource · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Meta's announcement of Muse Spark 1.3 for Muse Code and the Meta Model API, claiming ~20% fewer tool calls and ~25% fewer tokens than 1.2, with a max reasoning mode.
Resource · Coding & dev tools

Meta for Developers
@MetaforDevs
AI developers - we’ve published a technical guide covering how to get started with Muse Spark on Meta Model API. Muse Spark is a multimodal reasoning model built for agentic tasks, coding, computer use and long-context workflows. See what you can build 👉 bit.ly/4vWMkZx
X post · Coding & dev tools· ♥ 150
A 4-byte GGUF header edit that raises Muse Glimmer 30B's 131,072 context limit to 262K. The author shows YaRN scaling only adds prefill cost on this architecture, and verified 262K with 8 slots on one RTX 4090.
Resource · Local & open models· ♥ 1
eesel AI reports Muse Spark 1.3 ranks #6 on the Artificial Analysis Intelligence Index, leads long-context and coding rows, but trails Claude Opus 5 on four of six agent evals.
Resource · Benchmarks & research
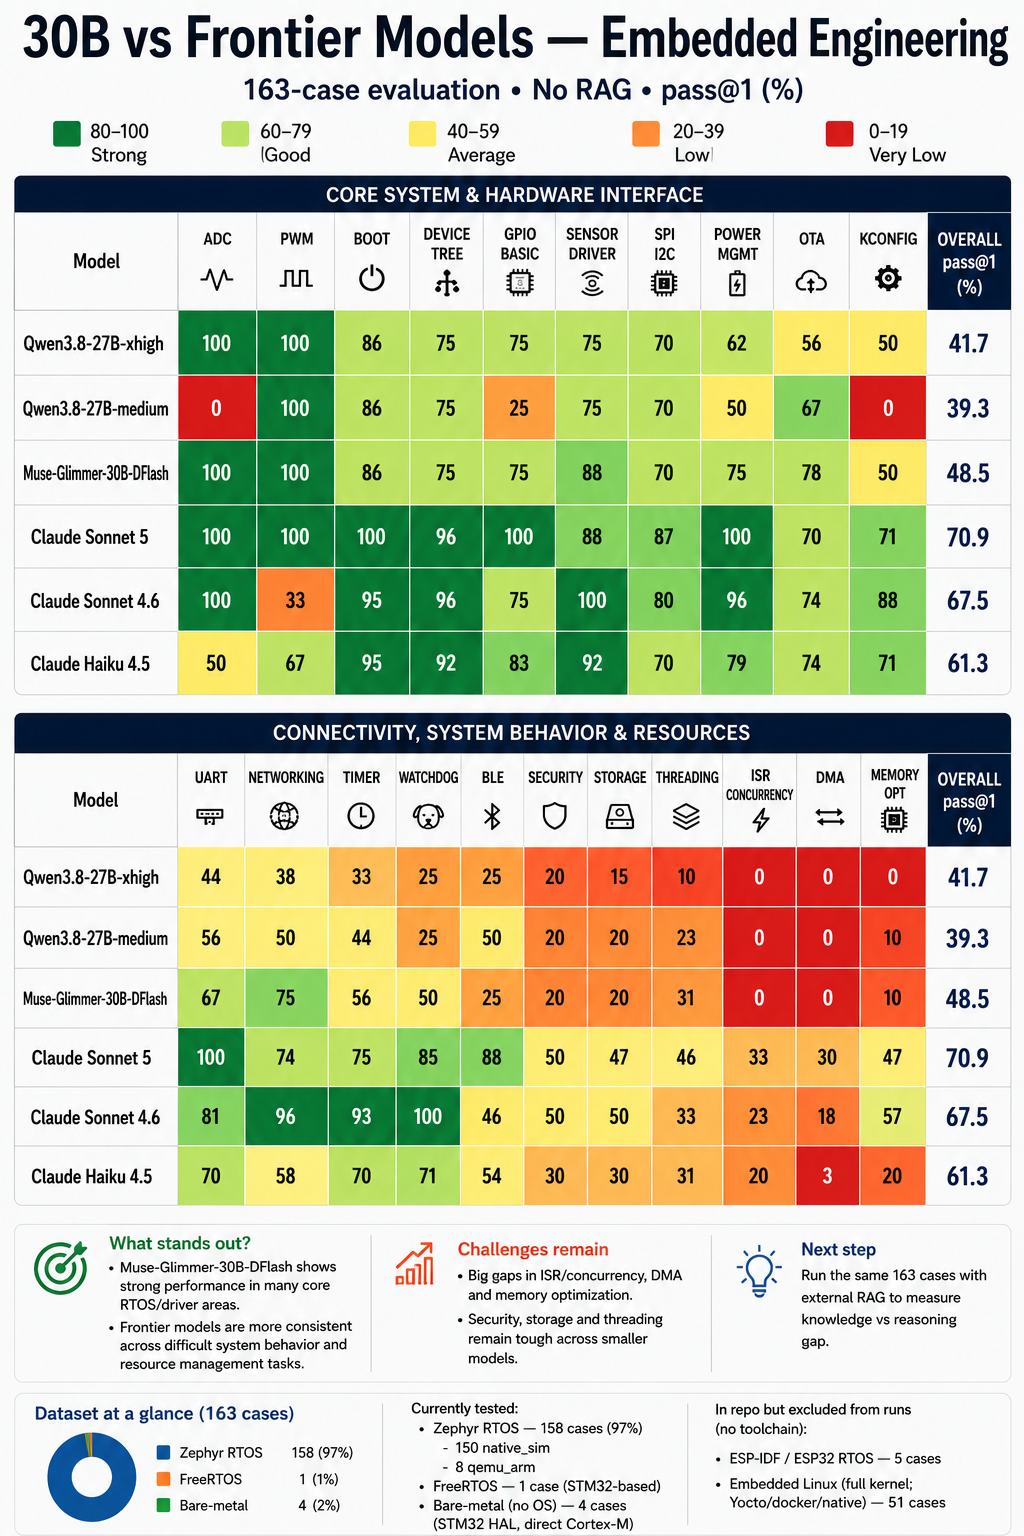
Benchmarked qwen3.8 xhigh, medium and muse glimmer. Xhigh effort mode with qwen3.8 took almost 30hrs. (And still failed on 16 cases because of the 32K output token limit) Medium effort mode and muse glimmer were 3-4 hours each. But I'm actually surprised by the muse glimmer results, they came better than the qwen. These benchmarks are on implicit knowledge of the model, which is a bit unfair to smaller models, but throw in a RAG and I'm sure they get on par with frontier models. I have taken the result of claude models directly from embedeval repo by ecro. I'm not pushing qwen down here, I like how qwen thinks and gives better results. I know with more context and RAG qwen will do better. I'm just appreciating muse here, cause i feel it is underrated. The advantage is efficient kv cache due to sliding window, which can give you more context window.
Reddit post · Benchmarks & research
 ChatForm
 Tgmlabs