Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
12 builds · page 1 of 1
Hugging Face's launch post covers day-0 transformers, llama.cpp and vLLM support, Inference Endpoints, speculative decoding, TRL fine-tuning and agent demos for Muse Glimmer.
Resource · Local & open models★ Pick
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
Cobus Greyling's companion repo for Muse Glimmer 30B pairs a long-form intro with an offline-first interactive lab for exploring agent loops, benchmarks and memory envelopes before downloading the weights.
GitHub · Local & open models
Meta's developer post on running Muse Glimmer on a single consumer GPU with vLLM, llama.cpp and ExecuTorch, with quantized builds in 24-32 GB and cookbook recipes.
Resource · Local & open models
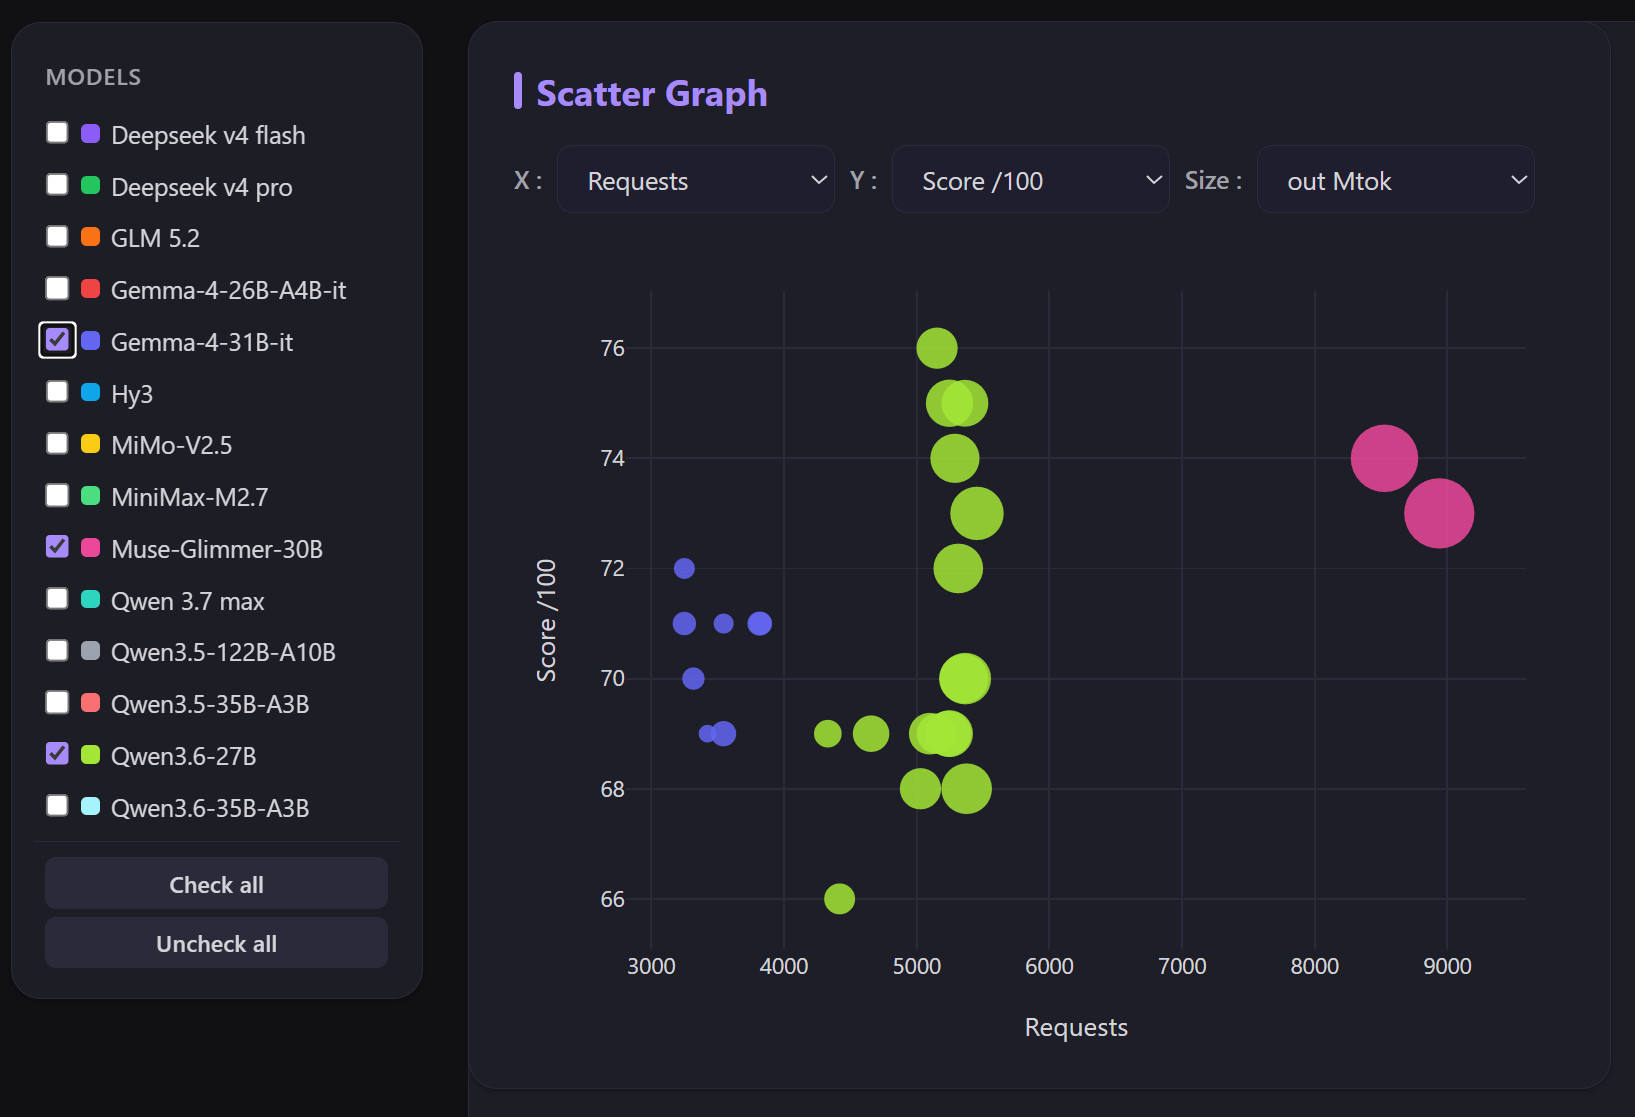
Needs a lot of requests compared to Qwen (almost twice) and Gemma (almost x3). Final score is fine, even though it is "not a coding model" https://wonderrico.github.io/local_llm_benchmark/benchmark-main.html more details on https://wonderrico.github.io/local_llm_benchmark/benchmark-detail.html let see Qwen 3.8 tomorrow...
Reddit post · Benchmarks & research
NVIDIA's technical blog reports Muse Glimmer serving over 20K tokens/sec on a single Blackwell Ultra GPU and covers RTX 5090, DGX Spark, DGX Station and Jetson deployments.
Resource · Local & open models

Cline
@cline
The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now!
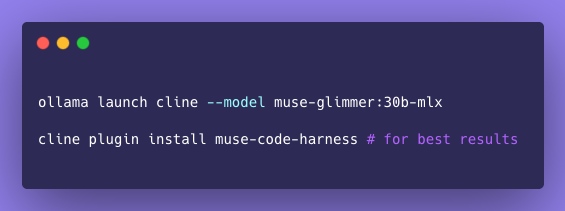
X post · Local & open models· ♥ 157
AICodeKing reviews Muse Glimmer for local agent setups, finding it strong at tool calling, multi-step tasks and failure recovery but weaker on general benchmarks.

Video · Local & open models
Venelin Valkov pairs Muse Glimmer with Hermes Agent on llama.cpp for a fully free local agent, testing whether a better harness fixes the model's mixed early reviews.
Video · Local & open models
I've had Qwen3.6:27b (and Qwen 3 coder next before it) running along side gpt-oss:20b for a while now as my two main models (qwen for coding, gpt-oss for agentic stuff). Qwen is pretty self-explanatory, while I had been using gpt-oss because of how good it was at producing json and instruction following, despite the size and age. https://preview.redd.it/lr61tb02lejh1.png?width=1920&format=png&auto=webp&s=cef1f0bbfb43c8462162ec675d52c5896d174118 The "upgrade" to 3.8 is pretty evident, especially because of the SWE bench score improvement, but I was more reticent with Muse-Glimmer as I had some trouble when I tried Gemma4, which was far too opinionated when given a task, but Muse-Glimmer seems great - low memory footprint at 128K context, fairly fast and seems to follow instructions well. What models are you using locally and for what? did you have a similar experience with these latest models?
Reddit post · Local & open models
A controlled local benchmark on an M1 Max comparing Muse Glimmer 30B with Qwen 3.6 35B and Qwen 3.8 27B on tool calling and data-science tasks; Glimmer passed 24/30 versus Qwen 3.8's 30/30.
GitHub · Benchmarks & research
NVIDIA hosts a Muse Glimmer 30B endpoint on build.nvidia.com with Python (OpenAI, LangChain), JavaScript and curl examples for the ~29.6B multimodal model with 131K context.
Site · Local & open models
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models


 ChatForm
 Tgmlabs