shipwithmuse

Entries matching “hardware”

12 builds · page 1 of 1

U

ogbrien

u/ogbrien

I think a lot of people are boxing Muse in as “Hermes for normies.” My guess is Meta intentionally keeps the deeper capabilities out of sight because the target audience does not want a complicated Hermes/Grok Bot-style setup. They aren't trying to capture the nerdy Hermes using market, they want this to be an AI agent for normies but they don't limit it as such. What it advertises its for is far from what it actually can do with very little work. But Muse gets much more interesting once you stop thinking of its VM as the whole system. I joined the Muse VM to my Tailscale network, gave it SSH access to a restricted user on my home Ubuntu box, and now it can run commands and browser automation through hardware I already own. I figured out Muse can do this because I asked it if it had a Tailscale skill and it said it did, then after a series of "proceed" replies, it set it up for me outside of the parts where I had to join it. At that point, Muse stops being a “shopping assistant” and starts looking more like a control plane for your own infrastructure. With Tailscale + SSH/API access, it can potentially: • Manage Docker, VMs, NAS, Proxmox, and homelab services • Pull repos,

Reddit post · Agents & automation★ Pick
Muse as a control plane for a homelab via Tailscale

@amoeba-farm

@amoeba-farm

Muse connector application for public hardware-market research over Amoeba Farm's existing HTTPS API, exposing RAM and NAND market catalogs and options books as Raw API operations.

AI at Meta

@AIatMeta

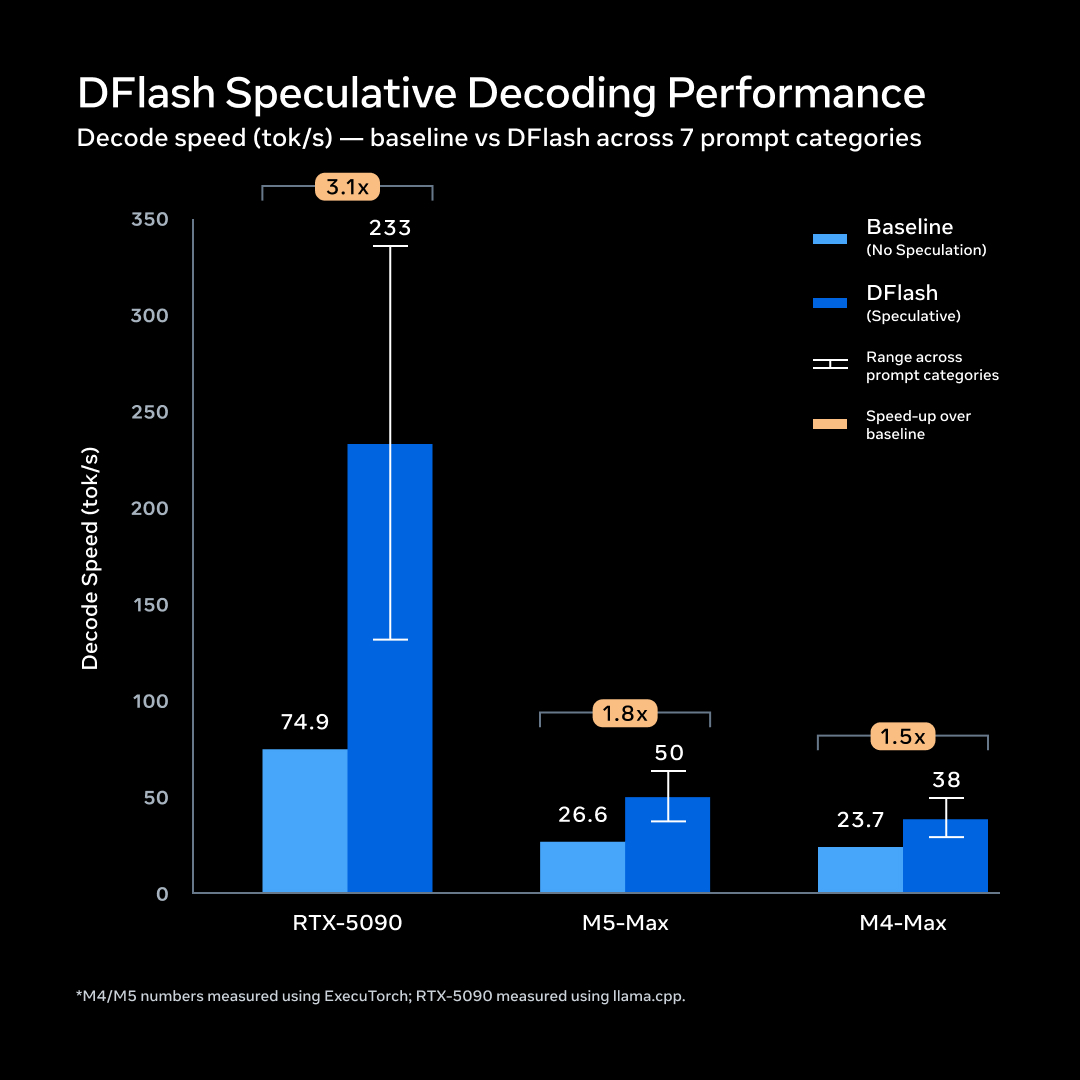
For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to

X post · Local & open models· ♥ 456

How Glimmer fits on consumer hardware

@AIwork4me

@AIwork4me

A reproducible RDNA reference that adapts MI-series ROCm recipes to run Muse-Glimmer-30B on Ryzen AI (Radeon 8060S) hardware, measuring 2.2–2.5x single-stream speedups from DFlash.

GitHub · Local & open models· ★ 3

Muse Glimmer 30B on Ryzen AI and Radeon

M

research.meta.ai

research.meta.ai

Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Introducing Muse Glimmer

Bojo.io

@justinbojarski

I’m working on a hardware prototype for something that required me to source a LOT of components from different suppliers. I decided to take @Meta ‘s Muse agent for a spin and automate the procurement process. It seamlessly researched and procured line items across 14 different

X post · Business & commerce· ♥ 3

Hardware component procurement across 14 suppliers

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

H

holaclaw.ai

holaclaw.ai

HolaClaw's tutorial for running Muse Glimmer 30B behind OpenClaw on a Mac, with hardware requirements and llama.cpp and Ollama setup.

Resource · Local & open models

Run OpenClaw with Muse Glimmer locally

W

@intheworldofai

@intheworldofai

WorldofAI benchmarks Muse Glimmer 30B on consumer hardware with a self-built test harness and compares it against Qwen 3.6 27B.

Video · Benchmarks & research

Muse Glimmer 30B vs Qwen 3.6 27B, fully tested

U

nullc

u/nullc

I noticed on the same hardware that I can get 24 x 128k contexts with muse glimmer (30b q8_0 + mmproj+dflash) only gets me 3x 256k or 6x 128k with qwen. But a straight forward analysis of the architecture suggests to me that qwen's state per token is somewhat smaller than glimmers. So it seems llama.cpp is particularly memory inefficient for the qwen arch. I presume there is an existing issue for this, but I couldn't find one. What's the deal? The extra concurrency makes a big difference in batched performance.

Reddit post · Local & open models

24 parallel 128K contexts with Muse Glimmer

Sayer Martin

@SayerPM

Today @muse: -booked and paid for airport parking, after recommending the best location for charging a @Tesla -advised on flights for an upcoming trip during my kids’ fall break timeframe (which it found) -read a receipt from @AceHardware and found that the prices were better

X post · Errands & personal agent· ♥ 1

Tesla-friendly airport parking and receipt check

W

wavect.io

wavect.io

Wavect's guide covers Glimmer's hardware targets (24–32GB) and tool-use scores such as MCP-Atlas 75.5 and SWE-Bench Pro 51.2, and recommends a 20–30 task pilot before production.

Resource · Local & open models

Muse Glimmer 30B: is it production-ready?