2-bit Muse Glimmer GGUF managed to call 100+ tools on just 14GB RAM. 🔥
Muse Glimmer did a complete repo bug hunt for 5 mins nonstop with: evidence, repro, fix, tests and a PR writeup.
Run and train it in Unsloth.
GitHub repo: github.com/unslothai/unsl…
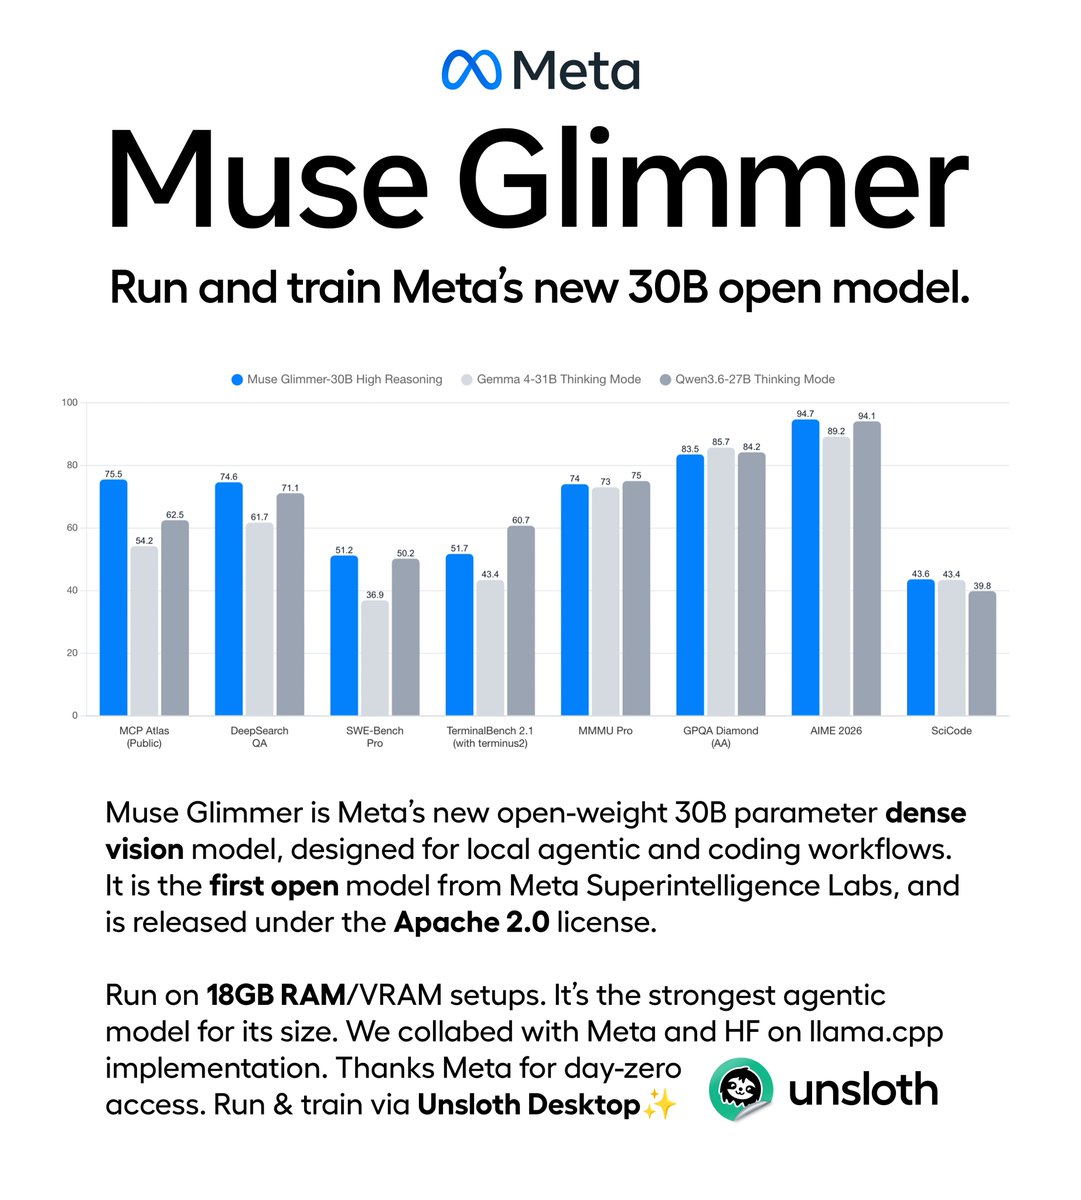
Meta releases Muse Glimmer, a new 30B open model that runs on 18GB RAM.
Muse Glimmer is Apache 2.0 licensed, supports vision and is the strongest agentic model for its size.
Run and train the model via Unsloth.
GGUF: huggingface.co/unsloth/Muse-G…
Guide: unsloth.ai/docs/models/mu…
Disclaimer. This is the first time I've used Muse or VSCode as a harness. The reason I am using VSCode as a harness is this is a research project for my job, and we only have VSCode, Codex, and Claude Code approved for harnesses.
I ran it in a folder with only one HTML file (800 lines) that is a Roblox-style COD game. I just gave it a prompt "Can you fix the bugs in the file". It read the file 3 times, found one bug, started to fix it, then got stuck reading the same 10 lines over and over.
I imagine it's one of these three issues.
• It's a prompt error, being way too vague/open ended for the capabilities of a smaller model. I tried again, with a specific prompt to fix a specific bug, and it still just ends up so confused, trying to grep/find the file despite already having read it, and trying to find the code inside of the file.
• It's a limitation of small models running with a large harness/having way too much going on. I tried running it with Pi with its default prompt, and it just got stuck doing tool calls and never actually read the file. Tried running this just directly in the Unsloth Desktop UI with no harness but it failed to parse the file I inputted and tried to gen
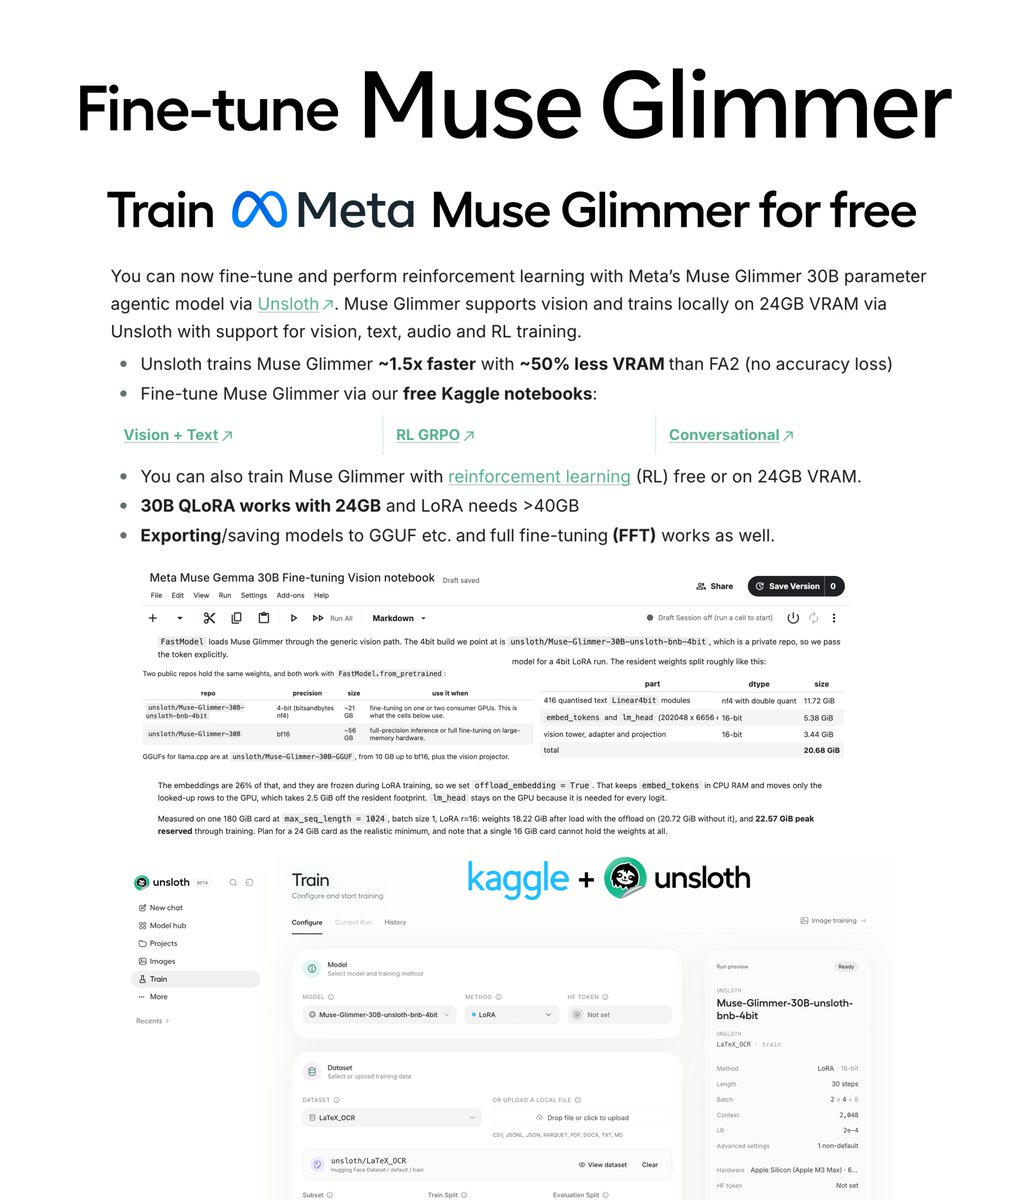
You can now fine-tune Meta Muse Glimmer 30B for free! 🔥
Our free notebook also supports GRPO RL training.
Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM.
Guide: unsloth.ai/docs/models/mu…
Notebooks: unsloth.ai/docs/models/mu…
Ran the model with quants (Q4) by Unsloth with latest (build from master) llama.cpp server.
It takes ~20GB ram running on M5 Pro with 48GB at about 17t/s. Didn't do any reasoning loops/overthinking.
Overall, sits below Qwen3.6 27B, wasn't able to get good code (frontend and backend) results. On the positive side, it didn't fail any tool calls.
Your opinions/findings?
Watch more: https://www.youtube.com/watch?v=_5wKhkUT438
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.



 ChatForm
 Tgmlabs