shipwithmuse

Entries matching “terminal-bench”

4 builds · page 1 of 1

Cline

@cline

Muse Spark 1.1 just launched and it's their most capable coding agent model yet. On Terminal-Bench 2.1 it scores 80.0%, in the same cluster as Opus 4.8 (82.7%) and GPT 5.5 (83.4%). Use it in Cline with the Meta API!

X post · Benchmarks & research· ♥ 191
Spark 1.1 scores 80% on Terminal-Bench 2.1

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

M

marktechpost.com

marktechpost.com

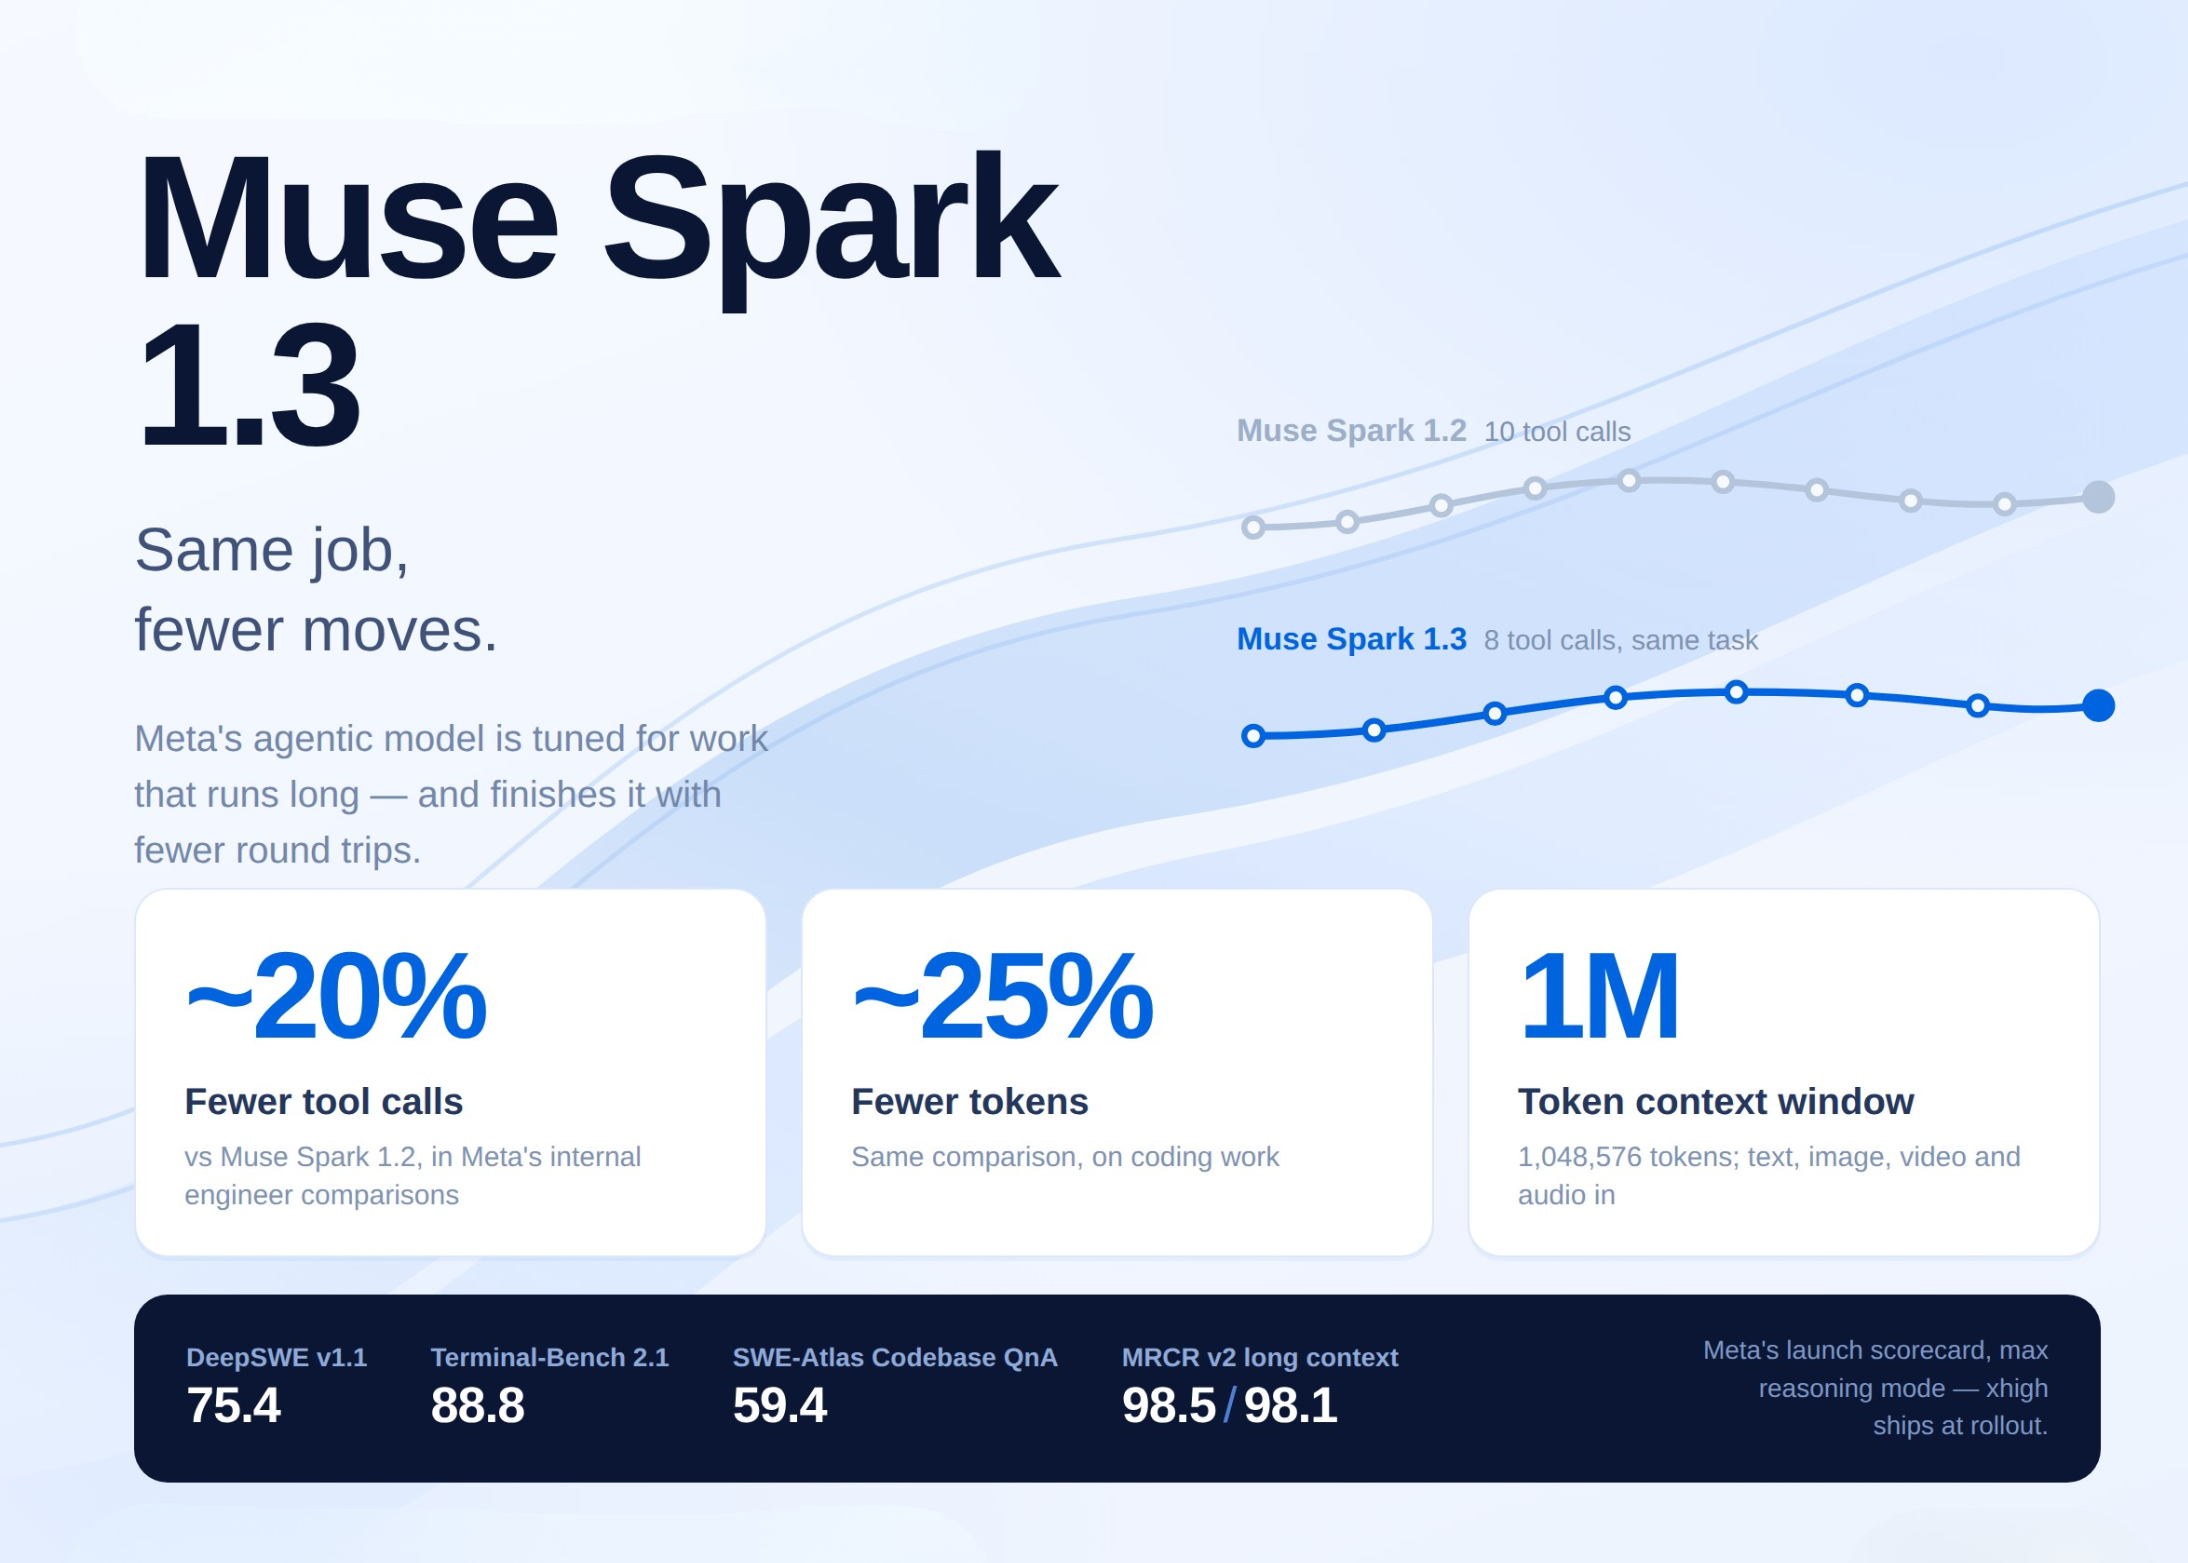
MarkTechPost summarizes Meta's numbers: 75.4 on DeepSWE v1.1 (Opus 5 74.0, GPT-5.6 Sol 72.7), 88.8 on Terminal-Bench 2.1, and 98.1 on MRCR v2 at 512K–1M context.

Resource · Benchmarks & research

MarkTechPost: Muse Spark 1.3 benchmarks breakdown

@Satgoy152

@Satgoy152

A project that fine-tunes a DSpark speculator for Muse Glimmer 30B on on-policy coding and agentic traces to raise acceptance length on agentic workloads, evaluated with Terminal-Bench.

Artificial Analysis

@ArtificialAnlys

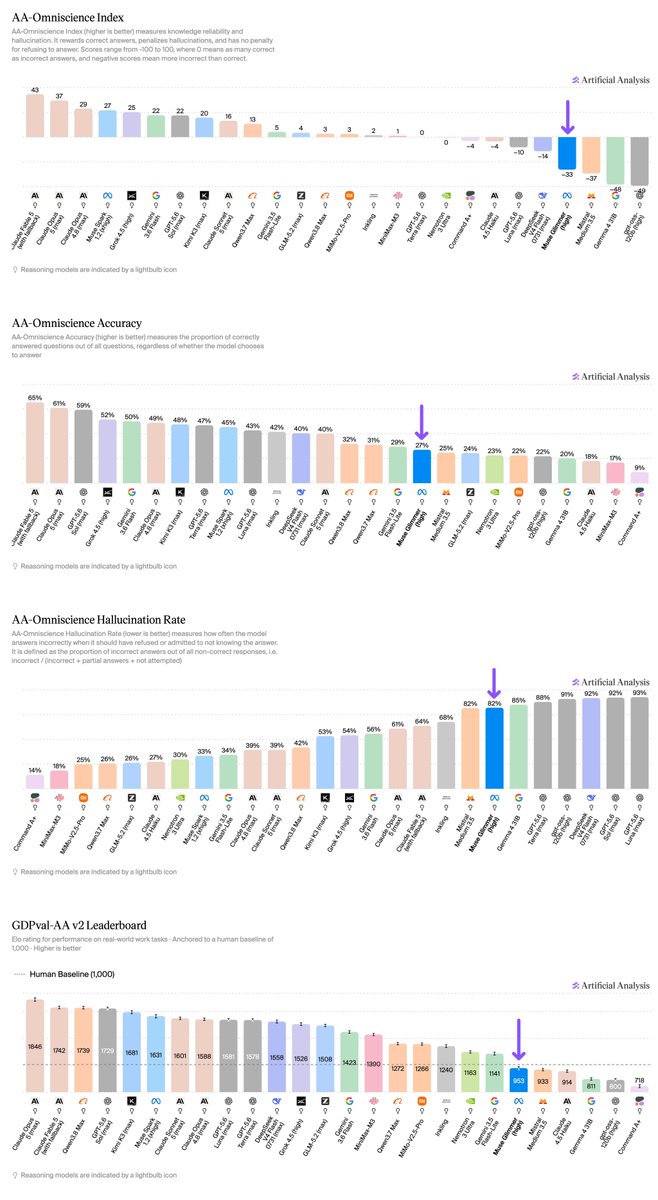
Muse Glimmer's gaps against its class concentrate in agentic evaluations: 953 Elo on GDPval-AA v2 against 1141 for Qwen3.6 27B (Reasoning), 1141 for Gemini 3.5 Flash-Lite, and 1004 for Kimi K2.5 (Reasoning), with Terminal-Bench v2.1 (52%) also behind Qwen3.6 27B (61%). The

X post · Benchmarks & research· ♥ 34

Where Glimmer trails on agentic evals