Parallel gives a six-step method and a template prompt for having Muse write, test and save its own connector for any public API, CLI or MCP server, using the Parallel Search MCP as a worked example.
Guide · Connectors & MCP
8 builds · page 1 of 1
Parallel gives a six-step method and a template prompt for having Muse write, test and save its own connector for any public API, CLI or MCP server, using the Parallel Search MCP as a worked example.
Guide · Connectors & MCP
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
I noticed on the same hardware that I can get 24 x 128k contexts with muse glimmer (30b q8_0 + mmproj+dflash) only gets me 3x 256k or 6x 128k with qwen. But a straight forward analysis of the architecture suggests to me that qwen's state per token is somewhat smaller than glimmers. So it seems llama.cpp is particularly memory inefficient for the qwen arch. I presume there is an existing issue for this, but I couldn't find one. What's the deal? The extra concurrency makes a big difference in batched performance.
Reddit post · Local & open models

Ejaaz
@cryptopunk7213
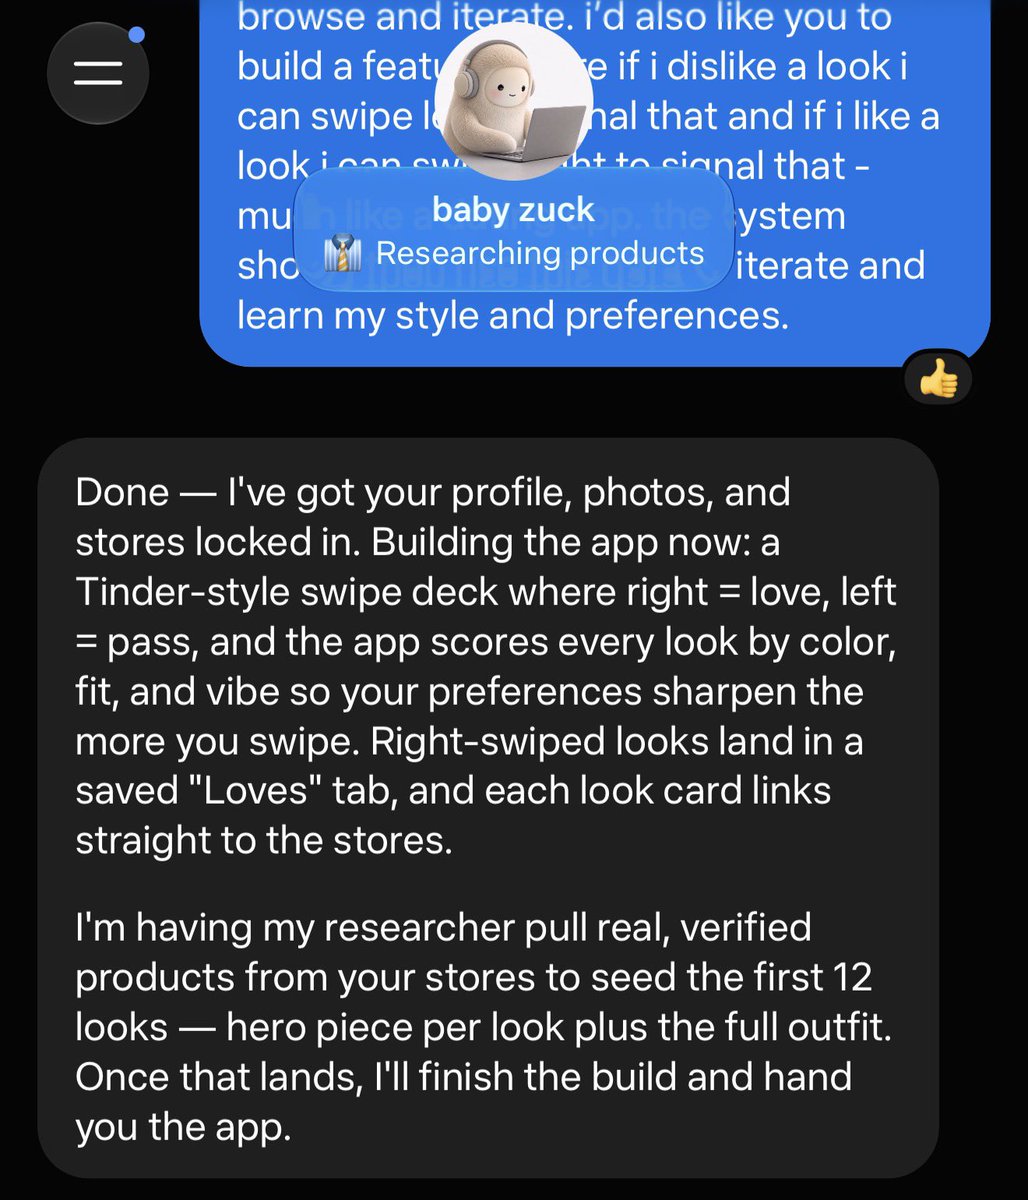
muse is not a great AI app, it’s a fantastic *personal* app. the ai model meta uses is not even frontier and yet you don’t care because the experience is so damn good. the secret sauce is meta built a much, much better open claw trained on your habits, preferences and decades of
X post · Apps & websites· ♥ 365
Hey Guys, I've got 4 x v100's in a Dell C4140 (NVlink) and I have been working on a fork of llama.cpp that is targeted at the v100's. Looking for testers to give it a go and provide feedback. WyvernTKC/llama.cpp-4xV100: Fork of llama.cpp Nvida Volta V100 (tensor parallelism 4 x v100 GPU) model arch type size (GB) pp layer pp tensor change tg layer tg tensor change glm4 9B Q8_0 glm4 dense 9.3 1187.9 2924.3 +146 % 67.6 123.0 +82 % qwen35 27B Q8_K_P qwen35 dense 29.3 640.4 1717.6 +168 % 22.2 52.4 +137 % gemma4 31B Q8_0 gemma4 dense 30.4 679.8 1621.2 ±322 noisy 20.6 46.7 +127 % muse-glimmer 30B F16 muse-glimmer dense 51.9 1048.4 2395.6 +128 % 15.1 40.4 +168 % llama 70B Q8_0 llama dense 69.8 302.5 950.5 +214 % 9.8 28.6 +192 % qwen35moe 35B-A3B Q8_0 qwen35moe MoE 256×8 34.4 1602.6 3143.7 +96 % 93.6 113.7 +21 % qwen3next 80B-A3B Q4_K_M qwen3next MoE 512×10 45.9 889.8 1647.0 +85 % 76.6 86.8 +13 % deepseek4 284B Q2_K deepseek4 MoE 256×6 90.9 188.8 616.1 +226 % 27.3 37.7 +38 % Thanks!
Reddit post · Local & open models

Fei Xia
@xf1280
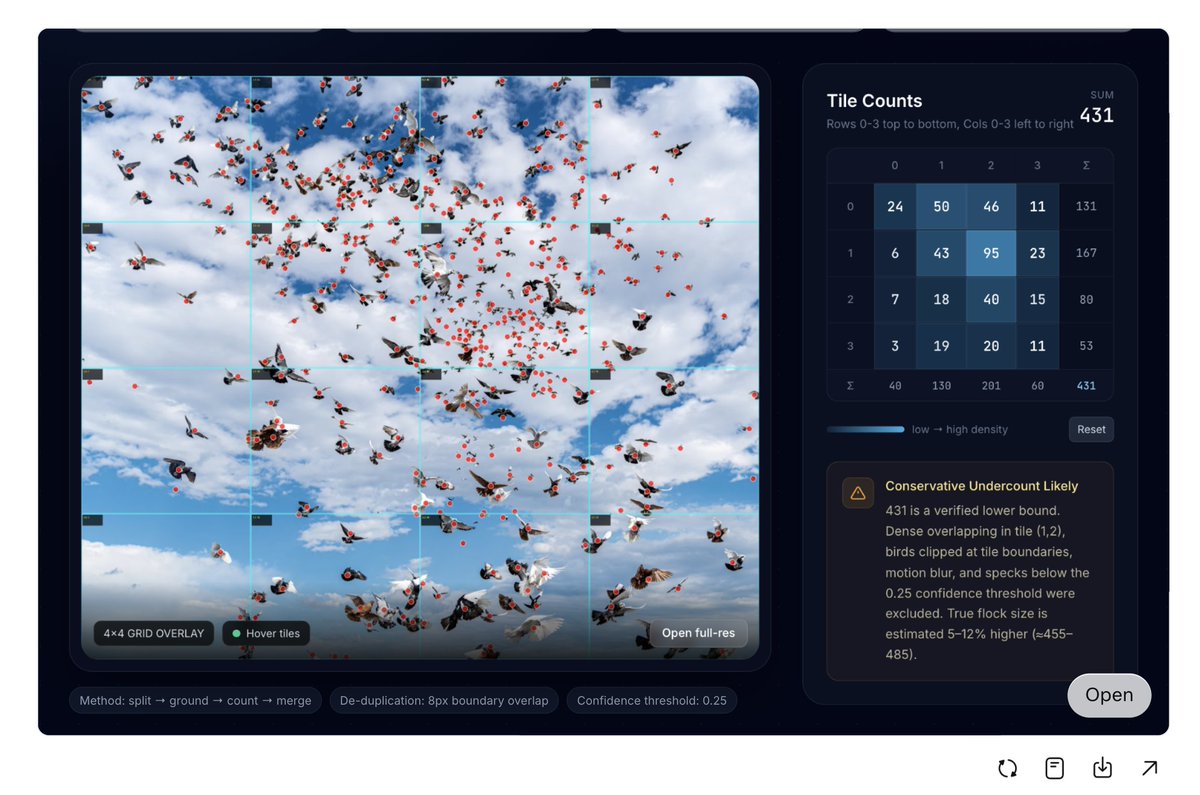
Muse Spark is agentic, which means you can ask it to leverage different test-compute scaling methods to improve quality. Here I ask the model to use parallel subagents to do counting and the results are greatly improved! meta.ai/share/aD4KAPeV…
X post · Benchmarks & research· ♥ 166

Matt Deitke
@mattdeitke
Turning any book into a chapter-by-chapter podcast series in Muse might be my favorite new use case. 🔉 It brings together so many things: - Long context agents that can reason through very long books - Subagents that go chapter by chapter to operate in parallel - Podcast
X post · Content & creative· ♥ 126
Meta's post on Muse Code exiting beta with inter-session messaging, parallel-agent workflow orchestration, rewind, a TypeScript SDK and three subscription tiers.
Resource · Coding & dev tools

Chetaslua
@chetaslua
I made 4 free models fight in one window 😱 same snake spec , 4 agents in parallel just Cline Desktop , the open source app for open weight models > GLM 5.3 Flash 152 pellets > Muse Spark 1.3 151 > DeepSeek V4 Flash 138 < patched a real bug in its own bot > > Solar Pro 4 0 ,
X post · Games & 3D· ♥ 82
 ChatForm
 Tgmlabs